Devpost
Participate in our public hackathons
Devpost for Teams
Access your company's private hackathons
Grow your developer ecosystem and promote your platform
Drive innovation, collaboration, and retention within your organization
By use case
Blog
Insights into hackathon planning and participation
Customer stories
Inspiration from peers and other industry leaders
Planning guides
Best practices for planning online and in-person hackathons
Webinars & events
Upcoming events and on-demand recordings
Help desk
Common questions and support documentation
Sort by:
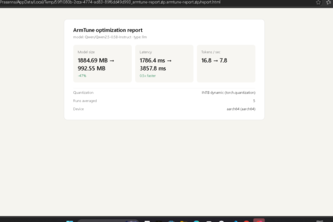
One command to quantize and benchmark any Hugging Face model for Arm CPUs — real, reproducible before/after numbers verified on genuine Arm hardware, not marketing claims.
Multi-Objective Auto-Tuner for LLM Inference on Arm CPUs
Evidence before confidence: private migration assurance with a quality-gated local model and confirmed KleidiAI speedup on native Arm64.
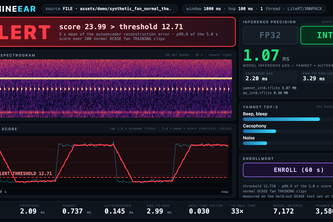
Offline acoustic machine-health monitoring on an Arm CPU. FP32 to INT8: 4.07x faster in the deployed path, 3.68x smaller, accuracy retained — and the negative results are published too.
An end-to-end NLP inference optimization and benchmarking suite evaluating DistilBERT across native Arm64 and x86_64 architectures.
An autonomous AI optimization platform for Arm that profiles, benchmarks, and continuously improves AI models and inference pipelines for faster, smaller, and more efficient deployment
Auto-tune llama.cpp for your Arm64 cloud instance — because the fastest quant format depends on the hardware, not the model.
Real-time Industrial Automation + Worker Safety powered by Arm Edge AI. 3D Digital Twin with 11.7ms inference, PLC control, and PPE detection.
FROYO: robot-made fruit yogurt, powered by a vision-language-action model — it sees the berries, plates them itself. Born yesterday, already better at portions than us. Taste it!
Analyze, optimize, benchmark, and prepare AI models for efficient deployment on Arm-based cloud infrastructure with intelligent backend recommendations and automated optimization.
One dependency-free C core turns heartbeats into a readiness state — Arm64 server, WebAssembly, or Cortex-M, unchanged. 19× faster, 5× smaller, proven identical to scikit-learn.
A 1-trillion-parameter AI engineer that reviews your PRs and fixes bugs overnight — on Arm CPUs, no GPU on Earth involved. ~$1/hour on Azure Cobalt, and your code never leaves your tenant.
NEURA AI is an cloud based Arm-optimized cognitive AI operating system that remembers, reasons, and automates workflows across devices with secure on-device intelligence.
AI-powered edge safety system that detects workplace hazards, assesses risk, and triggers real-time emergency responses using computer vision and sensor fusion.
Your Neoverse says SVE2. Your matmul runs neon_i8mm. KleidiAI gates every SVE kernel behind a 256-bit check that 128-bit N2 and Cobalt can never pass — proven on a free CI runner in two minutes.
Analyses, Bencharks and Optimize the best AI model to deploy on ARM based Edge Devices
Clusius doesn't just suggest migrating to Arm — it migrates, self-optimizes, and proves it live on real hardware: 4x the throughput, 1/4 the cost, zero mocked numbers.
Your discharge papers, decoded on your phone in airplane mode. An Arm-optimized INT4 LLM gives you a plain-language summary, a jargon glossary, and questions to ask your doctor. Full Privacy.
An Arm-powered physical AI robot using Python for local voice recognition and brain logic, connected via Wi-Fi to an ESP32 microcontroller for real-time body, servo, and audio control.
A from-scratch LiDAR 3D object detector, quantized to int8 with QAT and deployed on real Arm silicon. About 4x smaller, 4x faster on one Arm core, keeping 92% of accuracy.
A diagnostic tool that catches llama.cpp -fa auto silently picking the slower flash-attention setting on Arm CPU
Mobile AI Track: Runs within a 100 MB RAM boundary on any ARM CPU, utilizes NEON for SIMD instructions, and mmapped to operate within 60 MB peaks per layer. Fully featured+actual use Cases, not a toy.
IQ4_XS is the smallest standard 4-bit GGUF and had a tiled matmul kernel on Intel AMX, none on Arm. FastPath64 writes it: 2.12x prefill on Neoverse N2, 1.30x a whole agent turn, byte-identical output.
Real-time predictive maintenance on Arm Cortex-A9 / RTEMS 7 with 0 bytes dynamic memory allocation, NEON SIMD acceleration, and C11 memory bounds protection.