Devpost
Participate in our public hackathons
Devpost for Teams
Access your company's private hackathons
Grow your developer ecosystem and promote your platform
Drive innovation, collaboration, and retention within your organization
By use case
Blog
Insights into hackathon planning and participation
Customer stories
Inspiration from peers and other industry leaders
Planning guides
Best practices for planning online and in-person hackathons
Webinars & events
Upcoming events and on-demand recordings
Help desk
Common questions and support documentation
Sort by:
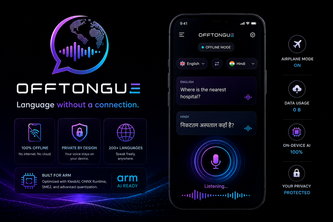
Real-time speech translation that runs entirely on your Arm-powered device. No cloud, no signal, no compromise. Speak freely, anywhere.
Sensitivity-aware mixed precision for ARM. Find the fragile tensors, spend bits there, and keep everything else small.
On-device LLM generation on Arm is bandwidth-bound. ArmForge measures what actually makes it fast on an Apple M4, and debunks what doesn't: i8mm won't speed up generation.
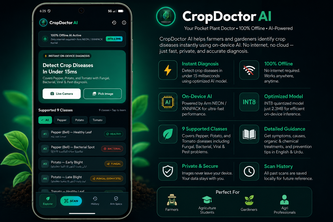
Sub-15ms on-device crop disease diagnosis using INT8 MobileNetV2 + Arm NEON SIMD. 98.3% accuracy, 9 diseases, bilingual English/Urdu guidance. Zero internet. Zero cloud. Runs entirely on Arm Cortex-A.
A reproducible Arm64 study of llama.cpp + KleidiAI on Android, measuring how Arm CPU optimizations affect prompt processing and token generation across LLM workloads.
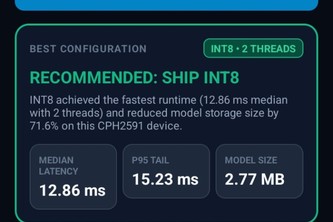
QuantForge benchmarks FP32 vs INT8 AI models on real Arm64 Android devices, auto-tunes CPU threads, and recommends the fastest deployable configuration instead of guessing.
A private AI assistant running Gemma 4 entirely on your Arm phone: voice, vision, live face recognition, and hands-free skills like directions, alarms, and reminders, with nothing sent to a server.
Run 30B AI locally on a phone by streaming only the experts it needs
ARM-Aware Scheduling and agentic harness for On-Device LLMs
An Arm64-optimized AI inference engine that delivers faster, leaner cloud LLM inference with NEON, INT4 quantization, KV-cache optimization, NUMA scheduling, and autonomous MCP agents.
Pocket Proof transcribes audio privately on Arm devices—no uploads. Its verified optimization makes Whisper 1.55× faster, 70% smaller, and use 44% less memory. Local AI, with receipts.
Which kernel path is your GGUF actually on?
An AI-driven cache optimization system that analyzes memory access patterns and intelligently selects cache configurations and replacement strategies to improve performance and reduce cache misses.
The ultimate AI routing layer. NEOVERSE leverages KleidiAI micro-kernels to run LLM workloads natively on Arm infrastructure, eliminating cloud compute waste with zero latency.
Closed-loop Physical AI on Arm — sense, plan, act — with 33× INT8 GEMM vs scalar.
InferPerf gives Arm engineers a clear view of why AI workloads slow down - using PMU‑driven microarchitectural profiling to expose bottlenecks and unlock faster, more efficient inference.
Saves 90% power & cost by routing simple prompts to an Arm-optimized local model (NEON/SVE), escalating to Fireworks Cloud only when complex reasoning is needed.
aarch64 vs x86 inference on cloud compute to test which is better
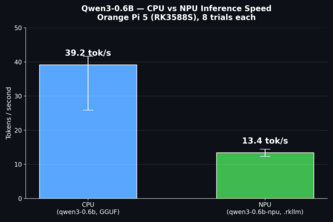
A real grow-cabinet monitors soil moisture and narrates plant health using a local LLM on the Orange Pi 5's NPU — with a measured CPU vs. NPU benchmark showing exactly where NPU inference pays off.
Verify whether llama.cpp on Arm actually uses KleidiAI kernels—and measure what that costs on Google Axion.
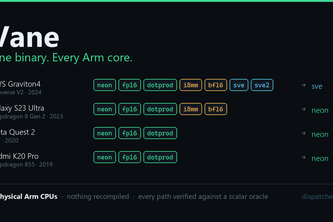
Arm isn't one target. A NEON kernel that flies on one chip can lose to scalar on the next. Vane picks the right kernel at runtime and can't print a number it didn't measure.
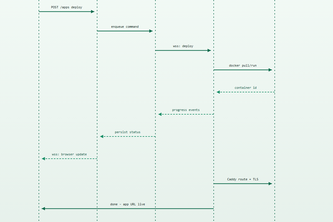
Anchor is an automated Arm64 deployment pipeline that detects your hardware, benchmarks generic vs KleidiAI optimized builds across model and tells you exactly which configurations get faster.
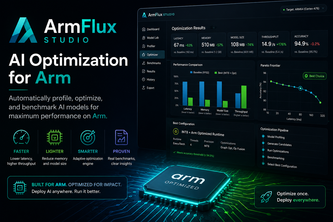
ArmFlux Studio automatically profiles, optimizes, and benchmarks AI models for Arm—finding the best configuration for speed, efficiency, and accuracy.
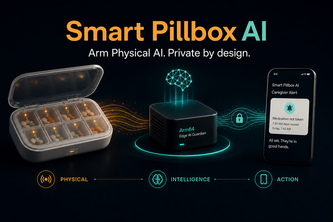
Smart Pillbox AI turns pillbox sensor events into private, offline safety actions using an INT8 Arm64/NEON inference kernel—34× faster with 75% less model memory.