Devpost
Participate in our public hackathons
Devpost for Teams
Access your company's private hackathons
Grow your developer ecosystem and promote your platform
Drive innovation, collaboration, and retention within your organization
By use case
Blog
Insights into hackathon planning and participation
Customer stories
Inspiration from peers and other industry leaders
Planning guides
Best practices for planning online and in-person hackathons
Webinars & events
Upcoming events and on-demand recordings
Help desk
Common questions and support documentation
Sort by:
Agent Ledger transforms invoice collections into intelligent financial knowledge, combining AI-powered semantic search, deterministic analytics, and traceable evidence through natural language.
Agent Launchpad gives AI agents scoped, revocable keycard-style tokens enforced at the backend — so prompt-injected overreach gets denied, every action is traced, and access can be revoked instantly.
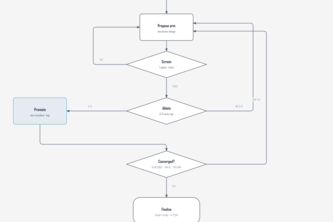
An autonomous LLM agent that plays the role of an ML engineer on a recommender system: it hypothesises, codes, trains, evaluates, and iterates, but with no human touching the model in the loop.
Meet Pip, your AI shopping companion. Simply tell Pip what you’re looking for, even if you’re unsure of your budget, brand, or specs, and Pip will adapt and find the right products for you.
Lupa-Auditor autonomously audits live collective bank data data with Gemini 3.5 Flash, detects risks and anomalies, and recommends actions before problems become costly.
A fleet of Gemini agents that recovers a disrupted airline day autonomously and proves it helped by replaying the same storm with the agents switched off.
are you ai?
An agentic personal pattern engine that turns lived experiences into evidence-linked behavioral patterns—and lets you see how repeated choices shape your future.
From denial to decision: Appeal uses agentic AI to build evidence-backed, policy-grounded appeals, while deterministic controls and clinician approval govern every external action.
Upload a UI sketch. A team of ADK agents built in Google Antigravity plans, codes, self-heals build errors, and deploys a live app to Cloud Run in your GCP project.
FamiLyOs is a voice-first family COO that preserves context, catches risks and autonomously drives long-running tasks—from shared documents to a confirmed embassy appointment.
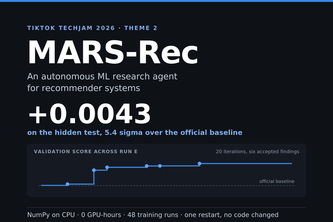
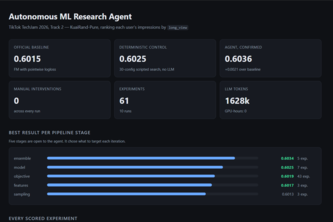
An LLM agent that does ML research unattended: 20 iterations, zero human intervention, six compounding discoveries, and +0.0043 over TikTok KuaiRand-Pure baseline on the hidden test.
A correct extraction can still produce the wrong decision. PROOFCHAIN checks whether business documents agree enough to act — and stops when they don't.
Stop scrolling through filters. Just tell our AI what you're looking for, and it asks the right questions to find your perfect product in minutes, not hours.
ContextCart turns evolving shopping conversations into fast, explainable recommendations using offline-safe retrieval, intent routing, and preference-aware ranking.
AIEndpoint finds the right website. WebMCP operates it. An open standard and live registry that lets browser agents discover which service can do the job before they ever navigate.
We turn Transformer shape diversity from a performance problem into an optimization opportunity.
A live funding-search agent, now callable by agents directly via a real WebMCP tool.
Building production-ready e-learning content usually requires manual coordination across content generation, syllabus structuring, and task prioritization.
A Transformer layer that picks its own kernel — 1.32× average, nothing slower than baseline.
An AI that does the deciding, not just the coding.
autonomous production incident response in 90 seconds: 8 observability signals investigated in parallel, root cause identified by Gemini, runbook generated automatically.
Finds the exact product a shopper wants from 50,000 items in 2.06 turns, scoring 0.891 against a 0.107 baseline. Keyword retrieval and rule-based dialog state, no model in the scored path.
A small autonomous loop for KuaiRand-Pure within-user ranking. It reproduces the official FM, tries one change at a time on validation only, then retrains and writes the test scores.