-
-
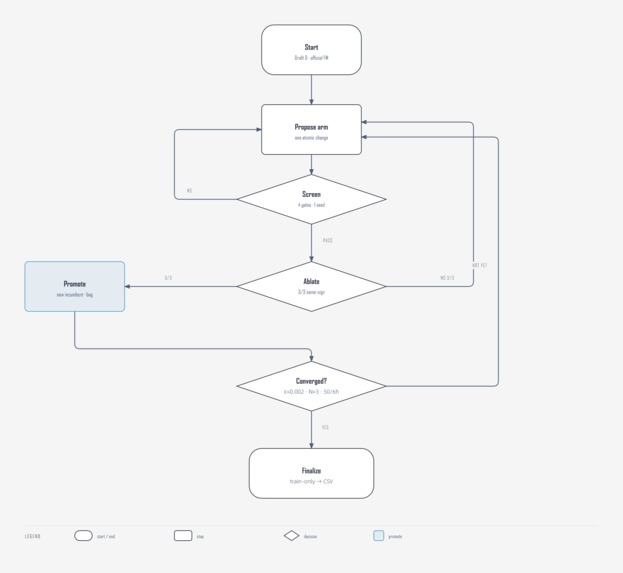
flowchat
-
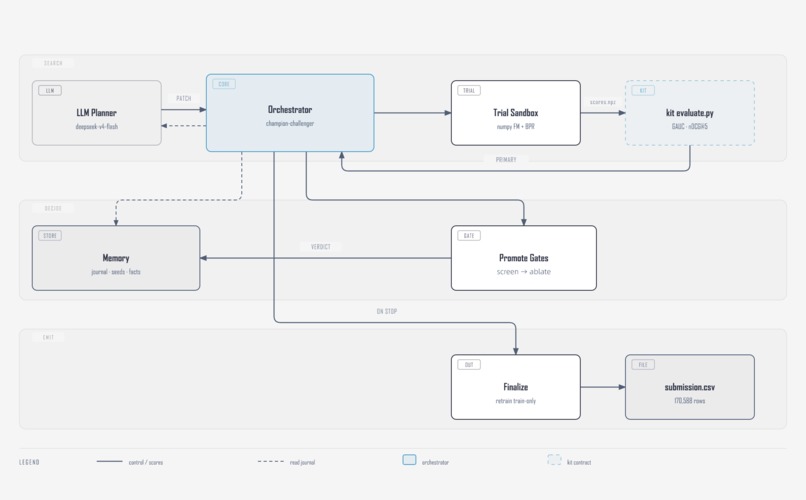
architechture
About the project
Inspiration
Track 2 asks for an autonomous ranking agent, not a hand-tuned notebook. The published bar is the official Factorization Machine on KuaiRand-Pure: within-user ranking of long_view, with
$$\text{primary} = \tfrac{1}{2}(\text{GAUC} + \text{nDCG@5}).$$
I wanted a loop that could reproduce that FM, try one legal change at a time on train and validation, and stop without ever reading test labels during search.
What makes the problem worth an agent is the split. The kit ranks a user's whole date window as one list. Recency features that look causal in production are group leakage on this offline metric. If the loop cannot notice that — and refuse to restack it — then "autonomous search" is just a way to overfit validation.
What it does
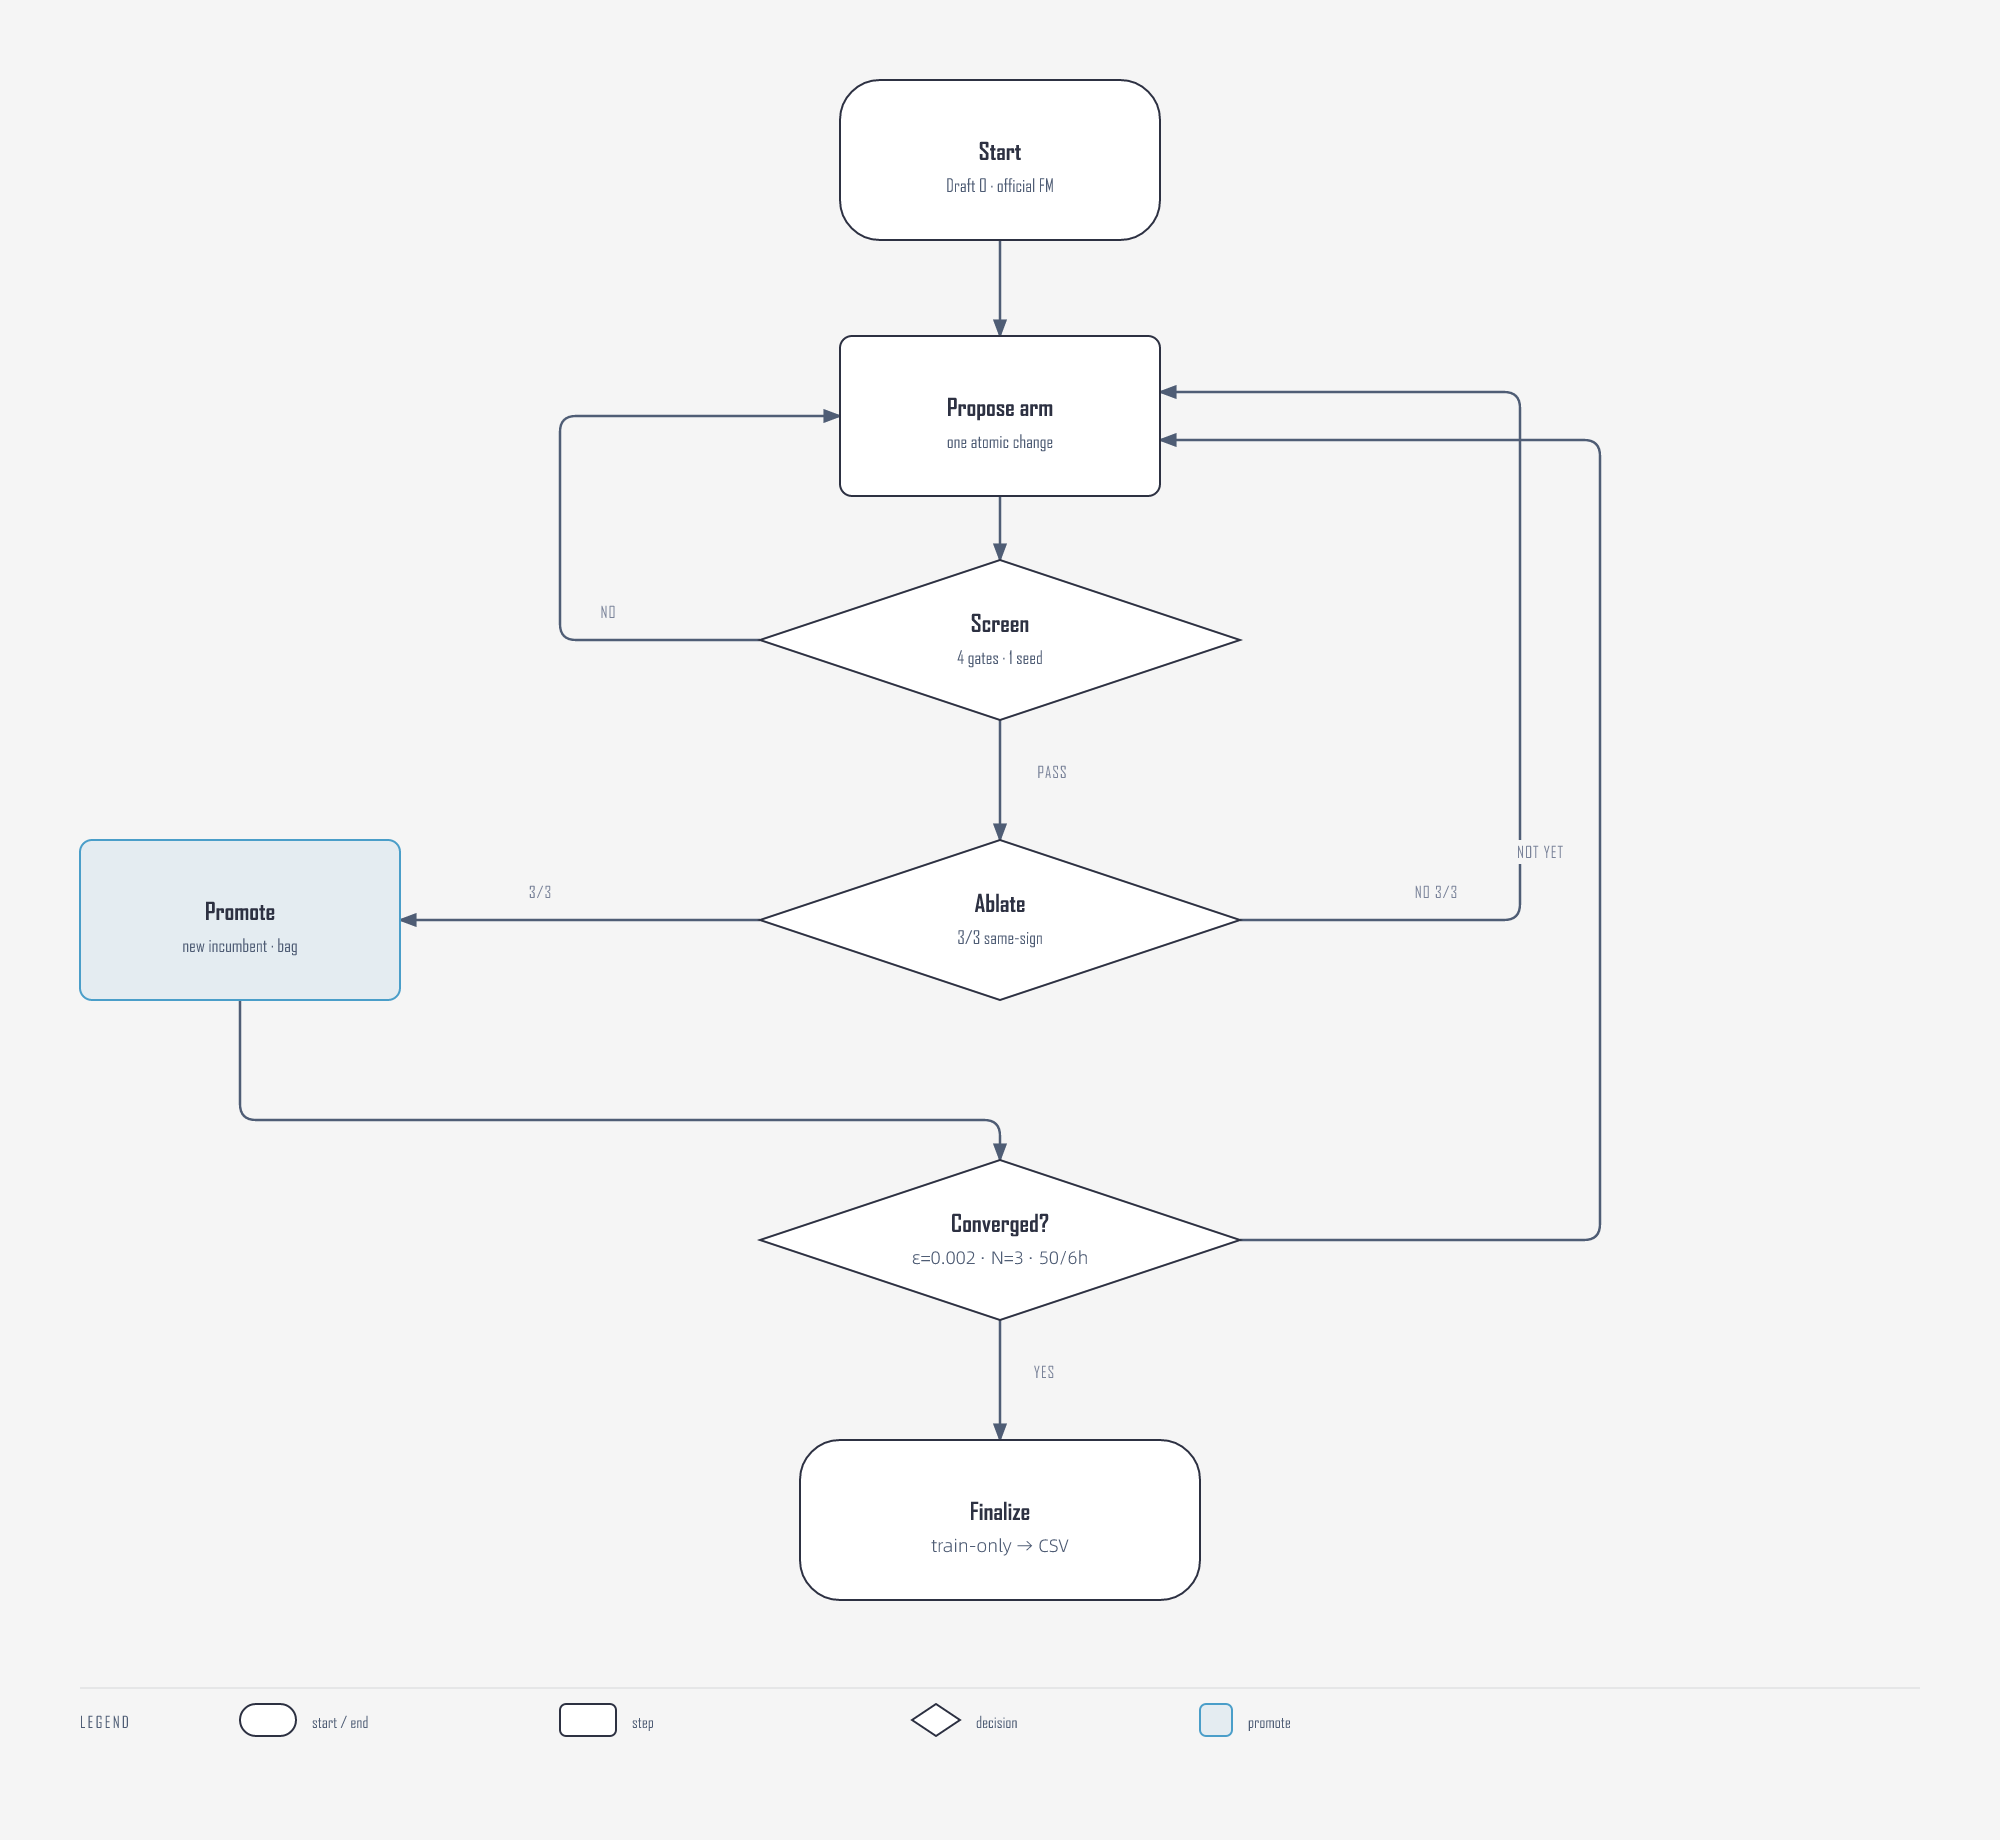
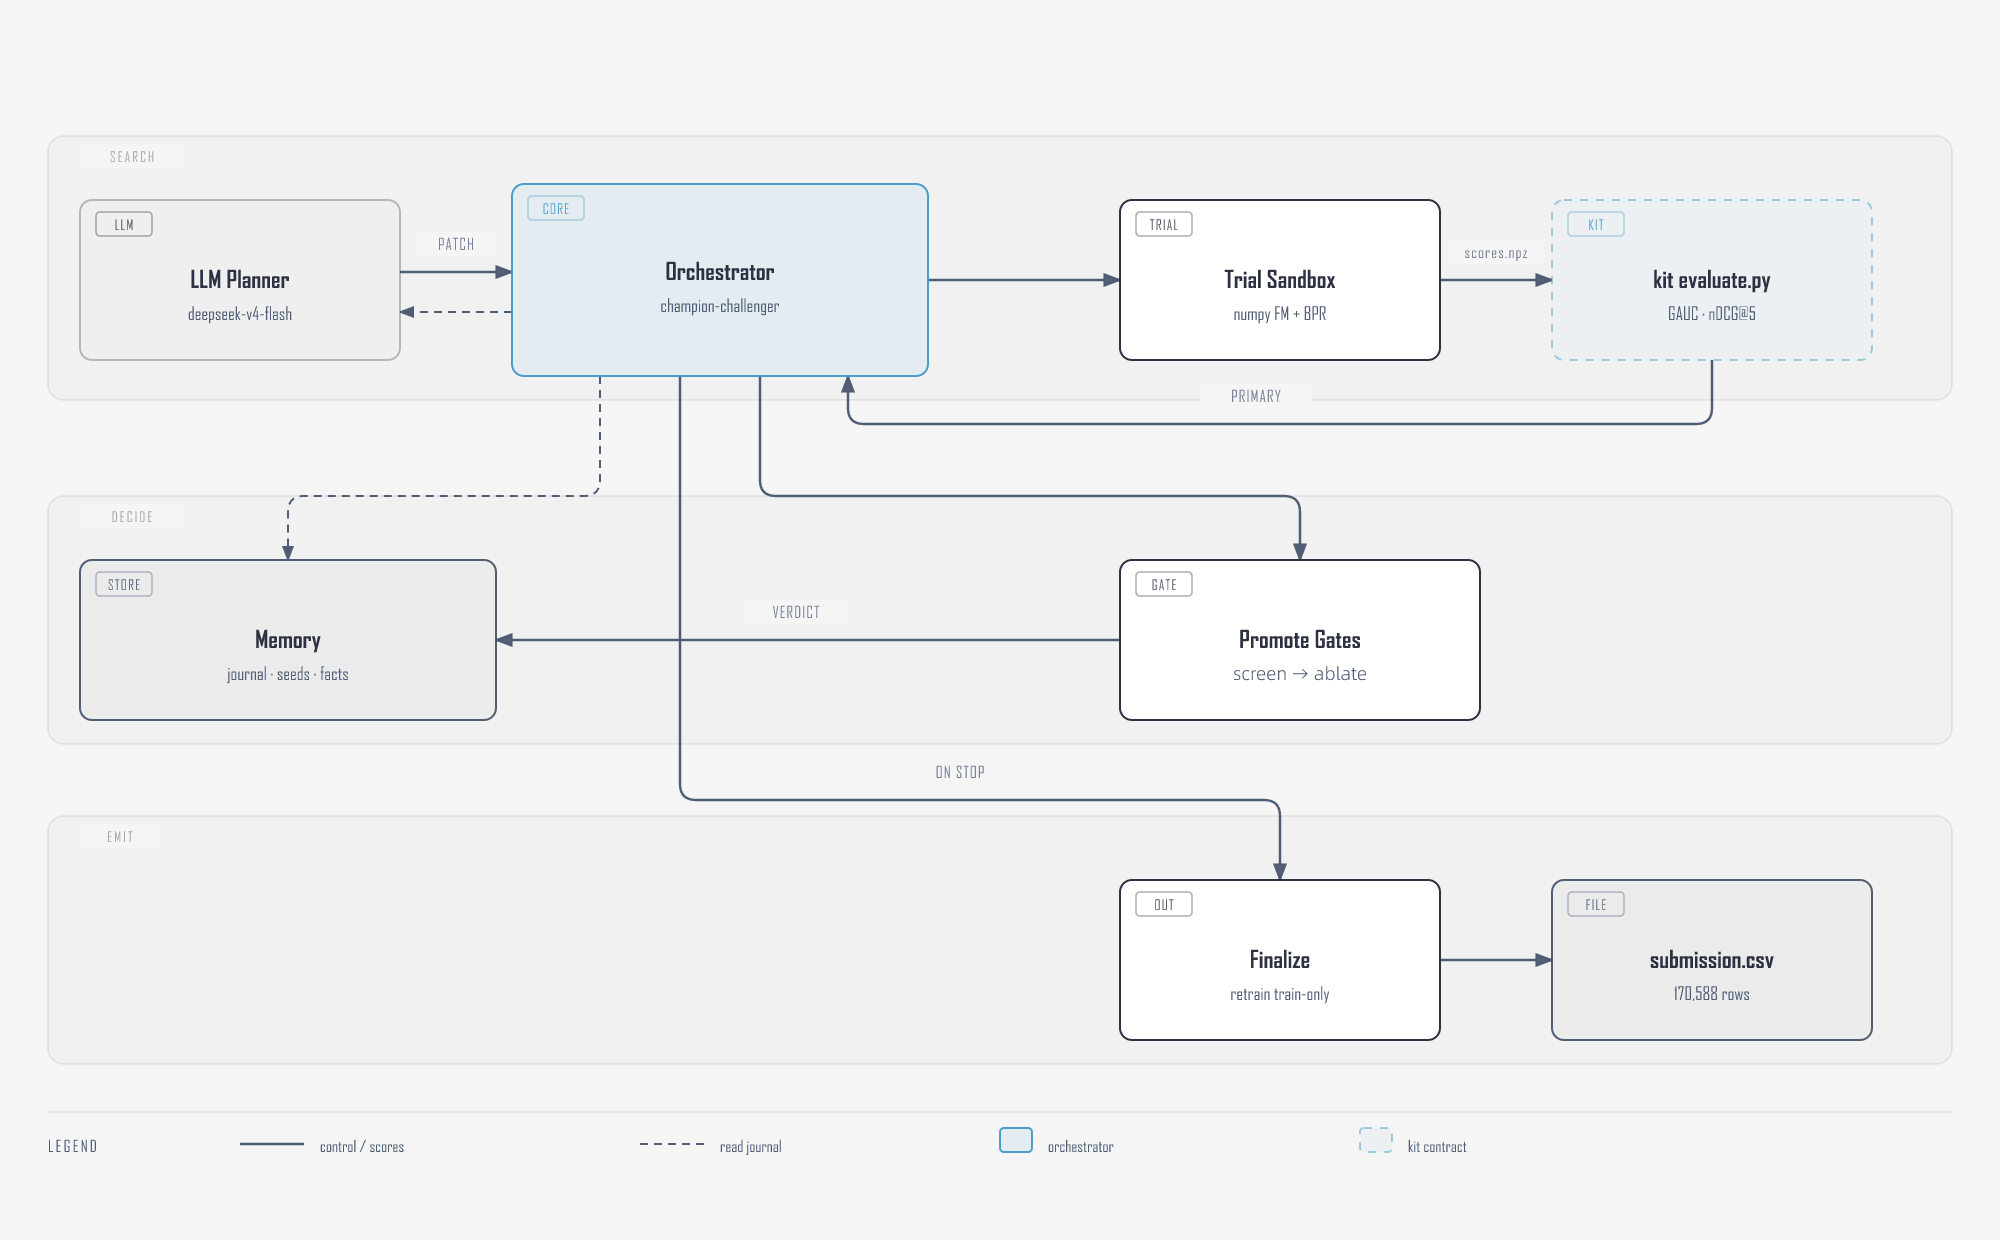
The agent copies templates/, trains draft 0 as the official FM, then proposes a single config_patch (loss, architecture, sequence, regularisation, …). Training happens in an isolated trial. The parent always scores scores.npz with kit evaluate.py. A 1-seed that looks real gets a 3-seed ablate; same-config seeds are rank-averaged. Stop: $\varepsilon = 0.002$ for $N = 3$ billed steps, or 50 iterations, or 6 hours. Then finalize retrains the chosen bag on train only and writes the test CSV.
Submitted Pure (the contest file): 3-seed DeepFM + seq_len=100 pool + $l_2=10^{-5}$.
| GAUC | nDCG@5 | primary | Δ vs FM | |
|---|---|---|---|---|
| Official FM (valid) | 0.6674 | 0.5357 | 0.6016 | — |
| Submitted (valid) | 0.67099 | 0.53816 | 0.60458 | +0.00298 |
| Official FM (hidden test) | 0.6610 | 0.5282 | 0.5946 | — |
| Submitted (hidden, once after search) | 0.66528 | 0.53137 | 0.59833 | +0.00373 |
50 / 50 billed steps, 1.87 hours, 513,033 in / 12,224 out tokens, 0 GPU-hours, 0 runtime interventions. Hidden test was scored once after search and was not used to pick the model.
A second freeze-eval Pure search independently shipped DeepFM + BPR and also beat the official FM — same parent scorer, same gates. Bonus KuaiRand-1K (different id space, not in that CSV) selected its own recipe: train-only use_time_decay on FM, 0.65001 vs the 1K FM 0.64203 (+0.00798).
Code: techjam2026-recsys-agent. Extra tables and the 1K CSV: data-log. Walkthrough (~3 min): https://youtu.be/UvwHHWfqQhs.
How we built it
Python 3.10, NumPy for the submitted DeepFM path, DeepSeek Chat Completions (deepseek-v4-flash). Kit evaluate.py / submit.py are unmodified. LightGBM and PyTorch are optional backends and are not in the Pure CSV.
The engineering claim is that architecture is a config patch, not a fork. DeepFM on Pure, BPR on a repeat Pure search, time-decay on 1K, and a 1-seed DCNv2 on 1K all go through the same isolated-trial / kit-scorer path. Swapping the model family did not require a new pipeline.
Guards in code:
- Search cannot
eval_split=test. Hiddenlong_viewneeds a finalize token. - Unseen labels are missing (
-1), not 0. Decay / last-k update from train 0/1 only. - Duplicate fingerprints are skipped, not retrained.
- Timeout can recover the best epoch from
curves.csv.SystemExitbecomes Debug (cap 3), not a blank restart.
src_hash for the submitted run is 193172377e3a5ad4 at start and end (unchanged=true). Journal and progress log: deliverables/pure-v6/.
Challenges we ran into
The first full search stacked recency while valid labels still flowed in, and stored missing test labels as 0. Finalize bag valid 0.63975. The same CSV, scored once afterwards, was test 0.56790 — below the official FM. Valid and test moved in opposite directions by 0.07.
Two mechanics: (1) kit ranking uses a user's whole split as one list, so rolling long_view into decay is group leakage; (2) zero is a real negative here, so test-as-0 poisons test decay while valid still sees real labels. That is the largest single signal in this project. I rebuilt label handling and searched again. The submitted number is smaller than 0.64, and I trust it.
A second challenge is the metric geometry. pair_cover = 0.016 — almost every valid pair is new — and train has 43.5 impressions / user vs 5.6 on valid. Pointwise logloss is row-equal; GAUC / nDCG average users. Ranking losses and bags are the right levers, not pair memorization.
On 1K, trials easily hit the 1-hour timeout under the 6 h wall (stopped at 31 / 50). LightGBM is wired; the one Pure trial (0.577) used the ID-only encoding, so that is not a family verdict.
Accomplishments that we're proud of
- Beat the published FM on both validation and a one-time hidden check, with 0 mid-search interventions, in 1.87 hours and 525,257 tokens.
- The leak that would have lost the hidden comparison is now a hard gate, not a footnote.
- Two independent freeze-eval Pure bags beat the FM (seq+l2 submitted; BPR as a repeat). Same scorer, same gates.
- Same loop, different recipe on 1K: +0.00798 vs that scale's FM. A 1-seed DCNv2 still moved the needle (0.65280) before the wall.
- Source tree did not move while submitted Pure trained. The parent always owns the score.
What we learned
A number that goes up on valid is not the same as a model that got better. The 0.07 reverse move is labels in the features, not the EDA pos_drift of 0.0059.
EDA named the lever before search closed it: almost no pair overlap, user-averaged metrics, short valid lists. That is why ranking losses, rank-average bags, and train-only sequence features were worth trying — and why finalize prefers a stable valid number (min of the two date halves, fewer extra flags), not $\max(\text{valid})$.
Negative results stay scoped. GBM 0.577 is an encoding bottleneck for that trial. aux_click / CWM and log_random_* (finalize primary 0.373) are diagnostics, not veto gates.
What's next for KuaiRand-Pure ranking agent
Keep freeze-eval. Let the agent set workers, batch, and timeout from the live config so 1K-scale trials stop wasting the 6 h wall on a 1-hour cap. 27K was not attempted. The next useful search is the same loop on a larger id space, with the leaky fingerprints still in the graveyard.
Other Devpost fields
An autonomous loop for within-user ranking on KuaiRand-Pure. It reproduces the official Factorization Machine, tries one change at a time on train and validation, scores with kit evaluate.py, and never reads test labels during search. After the loop stops, finalize retrains the chosen config on train and writes the test CSV.
Results
| GAUC | nDCG@5 | primary | |
|---|---|---|---|
| Official FM (valid) | 0.6674 | 0.5357 | 0.6016 |
| Submitted Pure (valid) DeepFM + seq-100 + l2 | 0.67099 | 0.53816 | 0.60458 |
| Official FM (hidden test) | 0.6610 | 0.5282 | 0.5946 |
| Submitted Pure (hidden test) | 0.66528 | 0.53137 | 0.59833 |
Submitted Pure: 50 billed iterations, 1.87 hours, 513,033 in / 12,224 out tokens, 0 GPU-hours, 0 runtime interventions. Hidden test 0.59833 was scored once after search and was not used to pick the model. Contest CSV: deliverables/pure-v6/submission.csv (170,588 rows). A second freeze-eval Pure search independently shipped DeepFM + BPR and also beat the official FM. Longer notes: docs/report.md.
Bonus KuaiRand-1K (different id space, not in that CSV): the same loop selected its own recipe — train-only use_time_decay on FM — and finished 0.65001 vs the 1K FM 0.64203 (+0.00798). A 1-seed DCNv2 reached 0.65280 before the 6 h wall at 31/50. Backbone, loss, sequence, and recency are all config_patch trials on the same scorer. Snapshot: deliverables/1k/.
A distribution-shift case (why the guards exist). The first full search stacked recency with valid labels flowing in, and stored missing test labels as 0. Finalize bag valid 0.63975; the same CSV scored test 0.56790, below the official FM. Valid and test moved in opposite directions by 0.07. Kit ranking uses a user’s whole split as one list, so rolling long_view into decay is group leakage; zero is a real negative, so test-as-0 poisons test decay. Submitted Pure stores unseen labels as missing (-1), updates recency from train only, and never scores test during search.
EDA on that split (pair_cover = 0.016, 43.5 vs 5.6 impressions / user) is why ranking losses, bags, and sequence features are the right levers. Finalize shipped DeepFM + seq-100 + l2. log_random_* at finalize (primary 0.373) is an off-policy check, not a candidate gate. Source-tree src_hash is unchanged for the submitted run. Runtime interventions: 0.
Built With
- deepseek
- git
- machine-learning
- numpy
- openai
- python
- recommender-systems


Log in or sign up for Devpost to join the conversation.