Devpost
Participate in our public hackathons
Devpost for Teams
Access your company's private hackathons
Grow your developer ecosystem and promote your platform
Drive innovation, collaboration, and retention within your organization
By use case
Blog
Insights into hackathon planning and participation
Customer stories
Inspiration from peers and other industry leaders
Planning guides
Best practices for planning online and in-person hackathons
Webinars & events
Upcoming events and on-demand recordings
Help desk
Common questions and support documentation
Sort by:
An Arm-optimized implementation of Qwen3-TTS focused on CPU inference efficiency, easier deployment, and real-world developer usability for cloud and edge Arm/x86 platforms.
We get rid of ai slop, normal slop, and misinformation on social media,
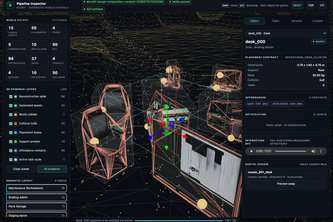
Simulation Ready Worlds for Embodied AI
Training-free, fully reproducible attention with no quadratic attention fallback: dense-equivalent retrieval at 1.03M tokens and 2.80x faster than PyTorch SDPA at 512K.
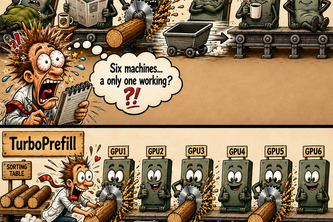
TurboPrefill accelerates multi-GPU LLM prefill by pipelining microbatches across GPUs, reducing idle time and inter-GPU communication bottlenecks.
Your idea. Your voice. Your finished video. Turn one concept into a structured script, authorized narration, animated scenes, subtitles, and an export-ready HD video.
Picotron is a hardware-adaptive, from-scratch LLM training framework that makes distributed pretraining and post-training practical on accessible GPUs like T4s.
Kenian: Trajectory-Sliced Third-Order Optimization. Bending deep learning curvature without the O(n^3) cost
LANtern turns your office's idle GPUs into a private compute pool. Submit a job from any machine; it runs on real CUDA on hardware you already own before renting cloud.
An optimA placement compiler that runs high-quality quantized MoE models faster on memory-constrained GPUs.al placement compiler for MoE models.
A placement compiler that runs high-quality quantized MoE models faster on memory-constrained GPUs.
3D AI generators can now create high-quality models, but their extreme face counts often limit them to references. What if those models could be made much lighter?
DREDGE is an AI-native platform combining GPU acceleration, intelligent agents, and advanced computation to help developers build, deploy, and scale next-generation AI systems.
Nobody has time to scrub through an eight-hour VOD for a sponsor disclosure, so we built StreamStory to automate the most tedious parts of livestream campaign reporting.
A STALKER GAMMA mod that uses a local LLM to generate faction-aware rumors, reactive world flavor, and believable player backstories—seamlessly inside the game world.
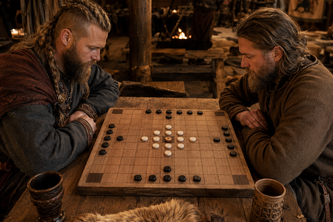
An AI powered Hnefatafl game, the Viking strategy game of raiders versus a defending king, that learns from every match, adapts to each player, and trains locally on the graphics card.
SpatialMind turns a phone walkthrough into a private PC-hosted 3D room twin, with local scene understanding, object detection, and an interactive viewer.
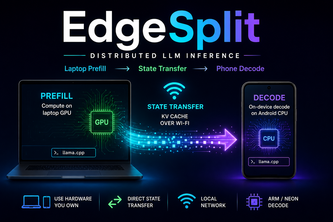
EdgeSplit runs LLM prefill on a laptop and decode on a phone, turning everyday hardware into a distributed inference system.
Step inside any image. LucidFrame transforms photographs, paintings, and panoramas into interactive 3D Gaussian worlds that can be explored in the browser.
CUDA setup is painful. Arc turns complex NVIDIA installation into one safe command by detecting your GPU, OS, and workload to create the right environment automatically.
This project uses a Multi-Agent Architecture and CT images to predict optimal radiotherapy doses for head and neck cancer, improving planning accuracy and protecting healthy tissues.
A real-time motion of deep confusion
elect a rough blockout in our Rust/Vulkan level editor, type a prompt, and a validated, textured AI-generated mesh replaces it in place three swappable model lanes TRELLIS, Hunyuan3D Tripo3D cloud
splat-fole An automatic sound-design pipeline that turns any 3D content meshes, scans, Gaussian-splat captures, a Marble-generated splat world, or a TRIPO-generated asset from a text prompt