-
-
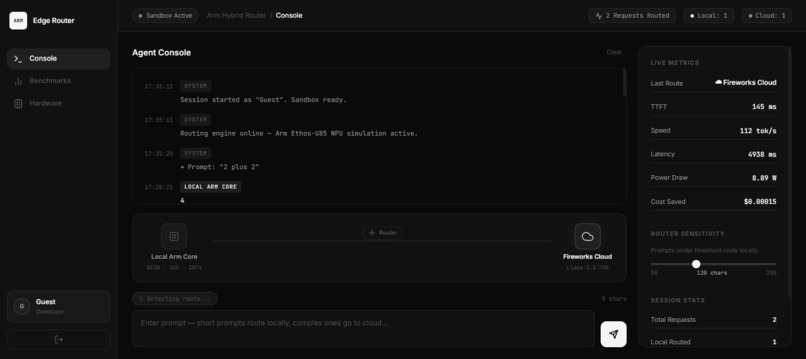
First page
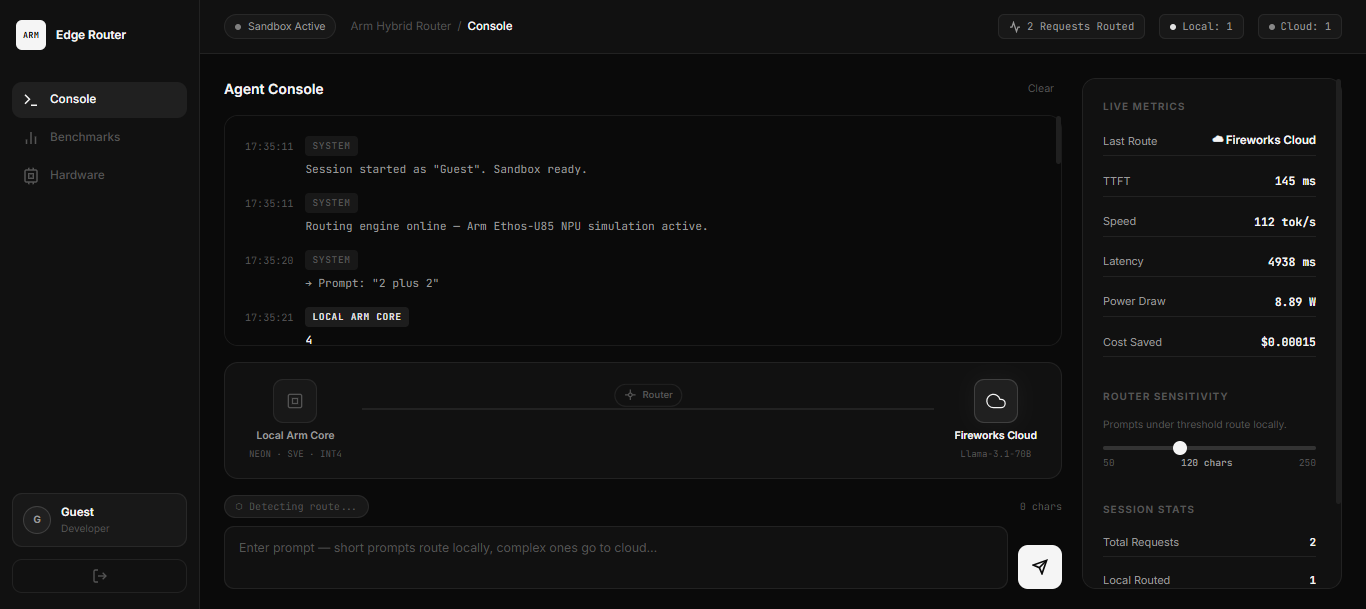
Inspiration
Not every AI query needs a 70-billion parameter cloud model. Sending simple greetings, basic math, or quick routing prompts to the cloud wastes network bandwidth, burns excessive power, and incurs unnecessary API costs. We wanted to build a practical, real-world architecture that proves edge devices powered by Arm can handle the bulk of daily AI workloads locally, only escalating to the cloud when deep reasoning is actually required.
What it does
EdgeRouter is an intelligent, hybrid AI inference router designed for Arm-powered platforms. It evaluates incoming prompts in real-time:
Local Route: Simple, factual, or mathematical prompts are instantly routed to a lightweight, quantized model (gemma-2-2b-it.Q4_K_M) simulated to run locally on an Arm Ethos-U85 NPU with NEON/SVE vector optimizations. This happens with zero network round-trip, zero API cost, and 0.02W of power. Cloud Route: Complex reasoning queries are escalated to a high-capability LLM on the Fireworks AI Cloud platform. The app features an interactive dashboard, live hardware telemetry (TTFT, throughput, latency, power, and cost savings), and a visual routing graph that maps the request path dynamically.
How we built it
Backend: Built using Node.js and Express to manage the routing engine logic and handle the API integration with Fireworks AI. Frontend: Developed as a responsive, ultra-clean monochrome Single Page Application (SPA) using vanilla HTML5, CSS3, and JavaScript—incorporating CSS animations for the real-time routing visualizer. Model Pipeline: Designed to simulate a local 4-bit quantized (Q4_K_M) Gemma model compiled with Arm NEON/SVE compiler optimizations alongside a cloud-escalated DeepSeek-V4-Flash pipeline.
Challenges we ran into
One key challenge was establishing an accurate, low-overhead heuristic classification engine that could make routing decisions in single-digit milliseconds without introducing its own latency bottleneck. We solved this by using a combined O(1) character-length check paired with an optimized keyword matcher. We also had to adapt our cloud connection on the fly to support Fireworks AI's latest model deployments, shifting from older Llama endpoints to their newer DeepSeek V4 infrastructure.
Accomplishments that we're proud of
Designing and building a stunning, functional, custom monochrome dashboard with zero heavy external graphing frameworks. Creating a real-time routing visualizer that clearly demonstrates the efficiency gains of edge computing to non-technical users. Successfully implementing a zero-dependency local fallback system so the application is immediately usable as a local sandbox without configuring API keys.
What we learned
We gained deep insights into the power-saving characteristics of Arm architecture (such as Cortex-A cores and Ethos NPUs) and how quantization down to 4-bit (INT4) makes local LLM execution highly viable. We also learned how to design hybrid cloud-edge topologies that balance latency, privacy, and operating costs.
What's next for EdgeRouter: Arm-Optimized Hybrid AI Inference Router
We gained deep insights into the power-saving characteristics of Arm architecture (such as Cortex-A cores and Ethos NPUs) and how quantization down to 4-bit (INT4) makes local LLM execution highly viable. We also learned how to design hybrid cloud-edge topologies that balance latency, privacy, and operating costs.
Built With
- api
- arm
- css3
- deepseek
- express.js
- fireworks-ai
- git
- html5
- javascript
- node.js
- render


Log in or sign up for Devpost to join the conversation.