Devpost
Participate in our public hackathons
Devpost for Teams
Access your company's private hackathons
Grow your developer ecosystem and promote your platform
Drive innovation, collaboration, and retention within your organization
By use case
Blog
Insights into hackathon planning and participation
Customer stories
Inspiration from peers and other industry leaders
Planning guides
Best practices for planning online and in-person hackathons
Webinars & events
Upcoming events and on-demand recordings
Help desk
Common questions and support documentation
Sort by:
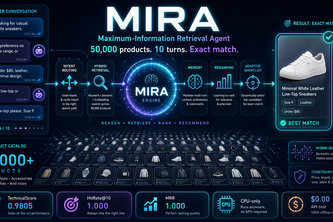
Akinator for commerce: 50,000 suspects, 10 questions. MIRA asks the question that most collapses its belief over the catalog. TechnicalScore 0.9805 vs the 0.1067 baseline. Zero API calls, $0.00.
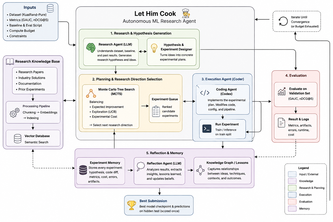
Ever wanted a personal intern that constantly works? Just hire me! Or you can use this AI scientist that I made.
A fast, in-memory, high-performance recommendation algorithm based on the Amazon 2023 50K product catalog.
A detector is only worth its accuracy on generators it has never seen. 0.958–0.989 balanced accuracy on an unseen generator across five transforms — and we found the 2026 models it still misses.
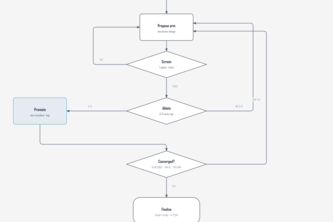
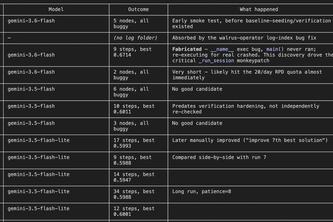
An ML research agent that owns the whole loop — it forms the hypothesis, writes the code, trains, and grades itself. 23 experiments, zero human code, and it caught its own data leak before we did.
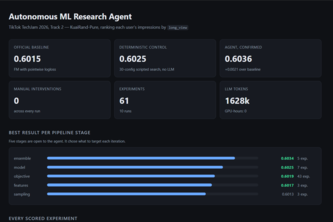
An LLM agent that runs the full ML research loop on a frozen benchmark: proposes an experiment, edits real model code, trains, and keeps it if a bootstrap test says the gain beats measurement noise.
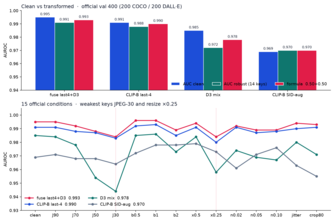
CLIP-B last-4 (~86M) scores 0.990 on 0.50×clean AUC + 0.50×14 social transforms. A mean-logit fuse with a mixed-generator head reaches 0.993. Official val and EvalGEN never enter training.
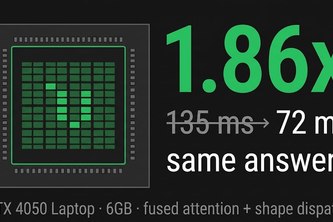
We optimized a transformer layer on an NVIDIA laptop and a MacBook. Every change was correctness-checked and timed before being kept; 25 experiments, 11 rejected, 2–15x faster.
With the rise of AIGC, the line between reality and fantasy is blurred. Serious implications could follow. Can we detect them accurately under different conditions? Our team seeks to answer this.
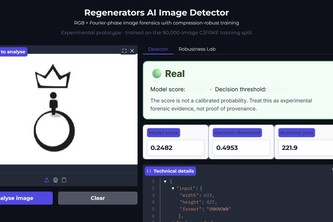
AI image detector
Find what fits, conversation by conversation.
An autonomous LLM agent that plays the role of an ML engineer on a recommender system: it hypothesises, codes, trains, evaluates, and iterates, but with no human touching the model in the loop.
are you ai?
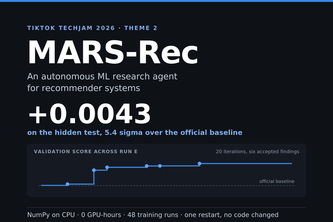
An LLM agent that does ML research unattended: 20 iterations, zero human intervention, six compounding discoveries, and +0.0043 over TikTok KuaiRand-Pure baseline on the hidden test.
ContextCart turns evolving shopping conversations into fast, explainable recommendations using offline-safe retrieval, intent routing, and preference-aware ranking.
A Transformer layer that picks its own kernel — 1.32× average, nothing slower than baseline.
An AI that does the deciding, not just the coding.
Finds the exact product a shopper wants from 50,000 items in 2.06 turns, scoring 0.891 against a 0.107 baseline. Keyword retrieval and rule-based dialog state, no model in the scored path.
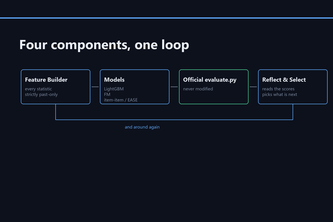
A small autonomous loop for KuaiRand-Pure within-user ranking. It reproduces the official FM, tries one change at a time on validation only, then retrains and writes the test scores.
FYPothesis - The Autonomous AI Researcher.
An autonomous agent that hypothesizes, codes, trains and evaluates its own improvements to a KuaiRand recommender system.
An AI research agent generates ML hypotheses; evolutionary search decides which experiments survive.
An autonomous research agent that reads the problem, writes the pipeline, and iterates — no human in the loop. Proposes research ideas, tests them, and logs everything by itself.
Autonomous ML agent that engineers causal features, tunes & blends LightGBM/XGBoost/CatBoost rankers, self-converges in 8 min, and beats KuaiRand's baseline +5.5% relative on hidden test.