Links
- Code + reproduce: github.com/chi030303/tiktok-techjam-aigc-detect (README Reproduce after Quick start)
- Submit weights: GitHub release v1.0-submit —
clipb16_last4_unfreeze.pt(~327 MB) andclipb16_d3_mix.pt(~5 KB). Do not use releasev0.1-model(SID DINOv2 probe). - Robustness / errors: docs/robustness.md · docs/error_analysis.md
- Train data we did not re-host: SID_Set (parquet; drop tampered
label=2) - Self-built mix-in we released: Kaggle AIGCTrace-Mix (CC BY 4.0)
Official demonstration val (COCO + DALL·E Advanced) and EvalGEN are hold-out: we do not republish them.
Inspiration
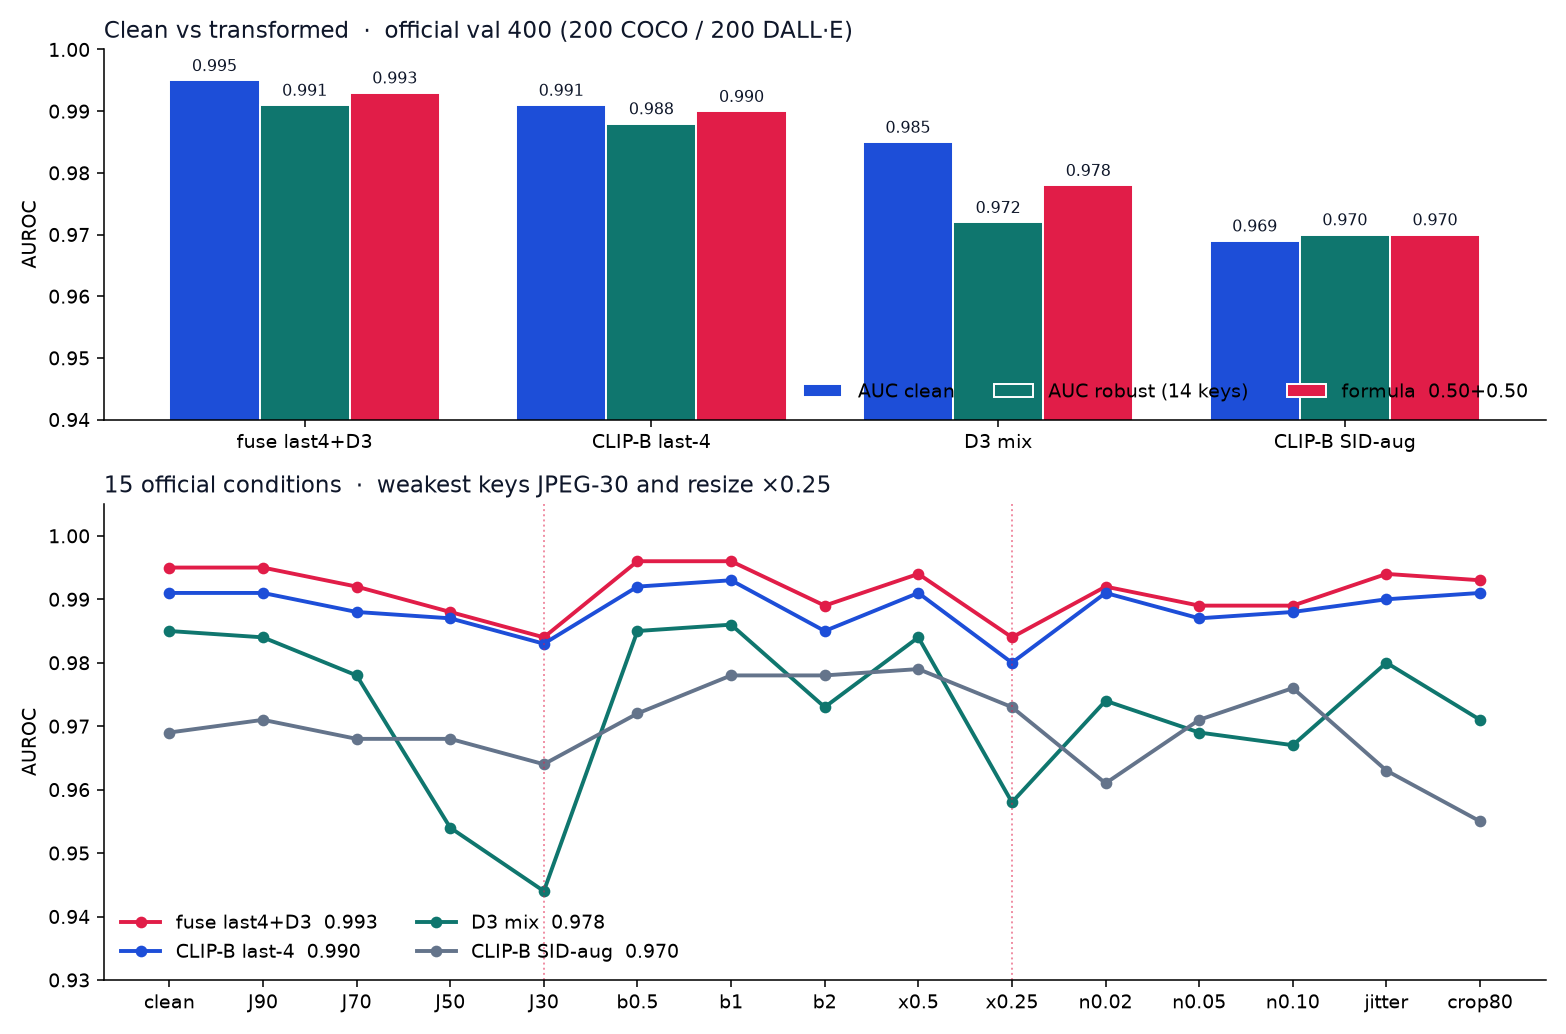
Social photos are JPEG-compressed, blurred, resized, and cropped long before a detector sees them. TikTok TechJam Challenge 5 scores $0.50 \times \mathrm{AUC}{clean} + 0.50 \times \mathrm{AUC}{robust}$ over 14 official transforms — not accuracy at 0.5. CIFAKE-trained CLIP-B scored ~0.50 on the official demonstration set. We wanted a detector that still ranks well after those transforms, stays well under the 2B parameter cap, and does not train on the hold-out val.
What it does
predict.py takes a folder of images and writes JSON {image_path, pred} with pred = P(AIGC).
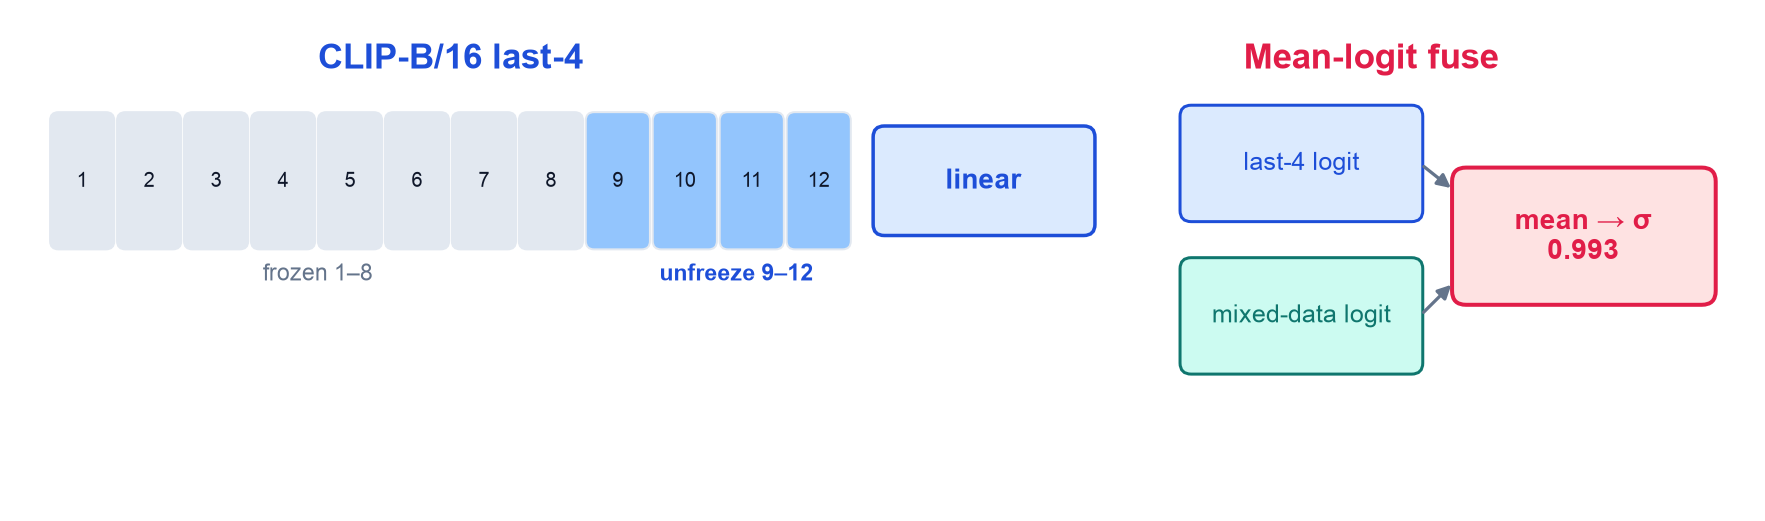
- Single checkpoint: CLIP ViT-B/16 with the last 4 vision blocks unfrozen (~86M). Official val 400 formula 0.990 (full 13,843 0.989).
- Optional two checkpoints: mean-logit fuse of last-4 and a frozen mixed-generator (D3) head → 0.993.
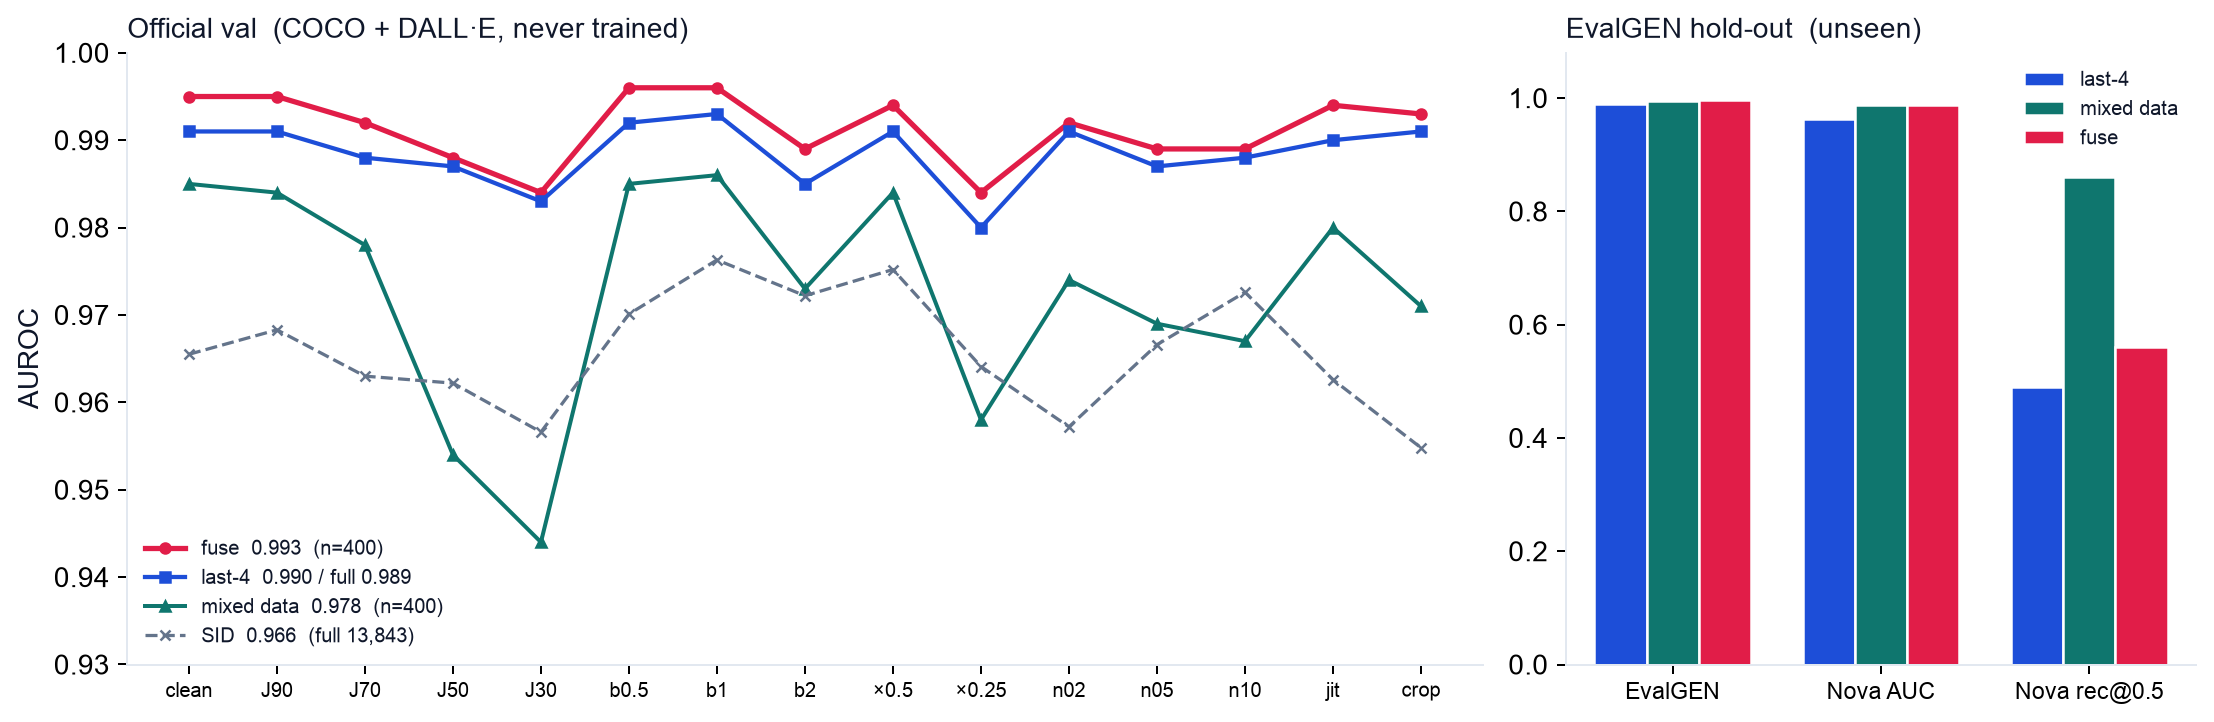
- Robustness: all 15 official conditions. Fuse stays ≥ 0.984 on every key; last-4 stays ≥ 0.980.
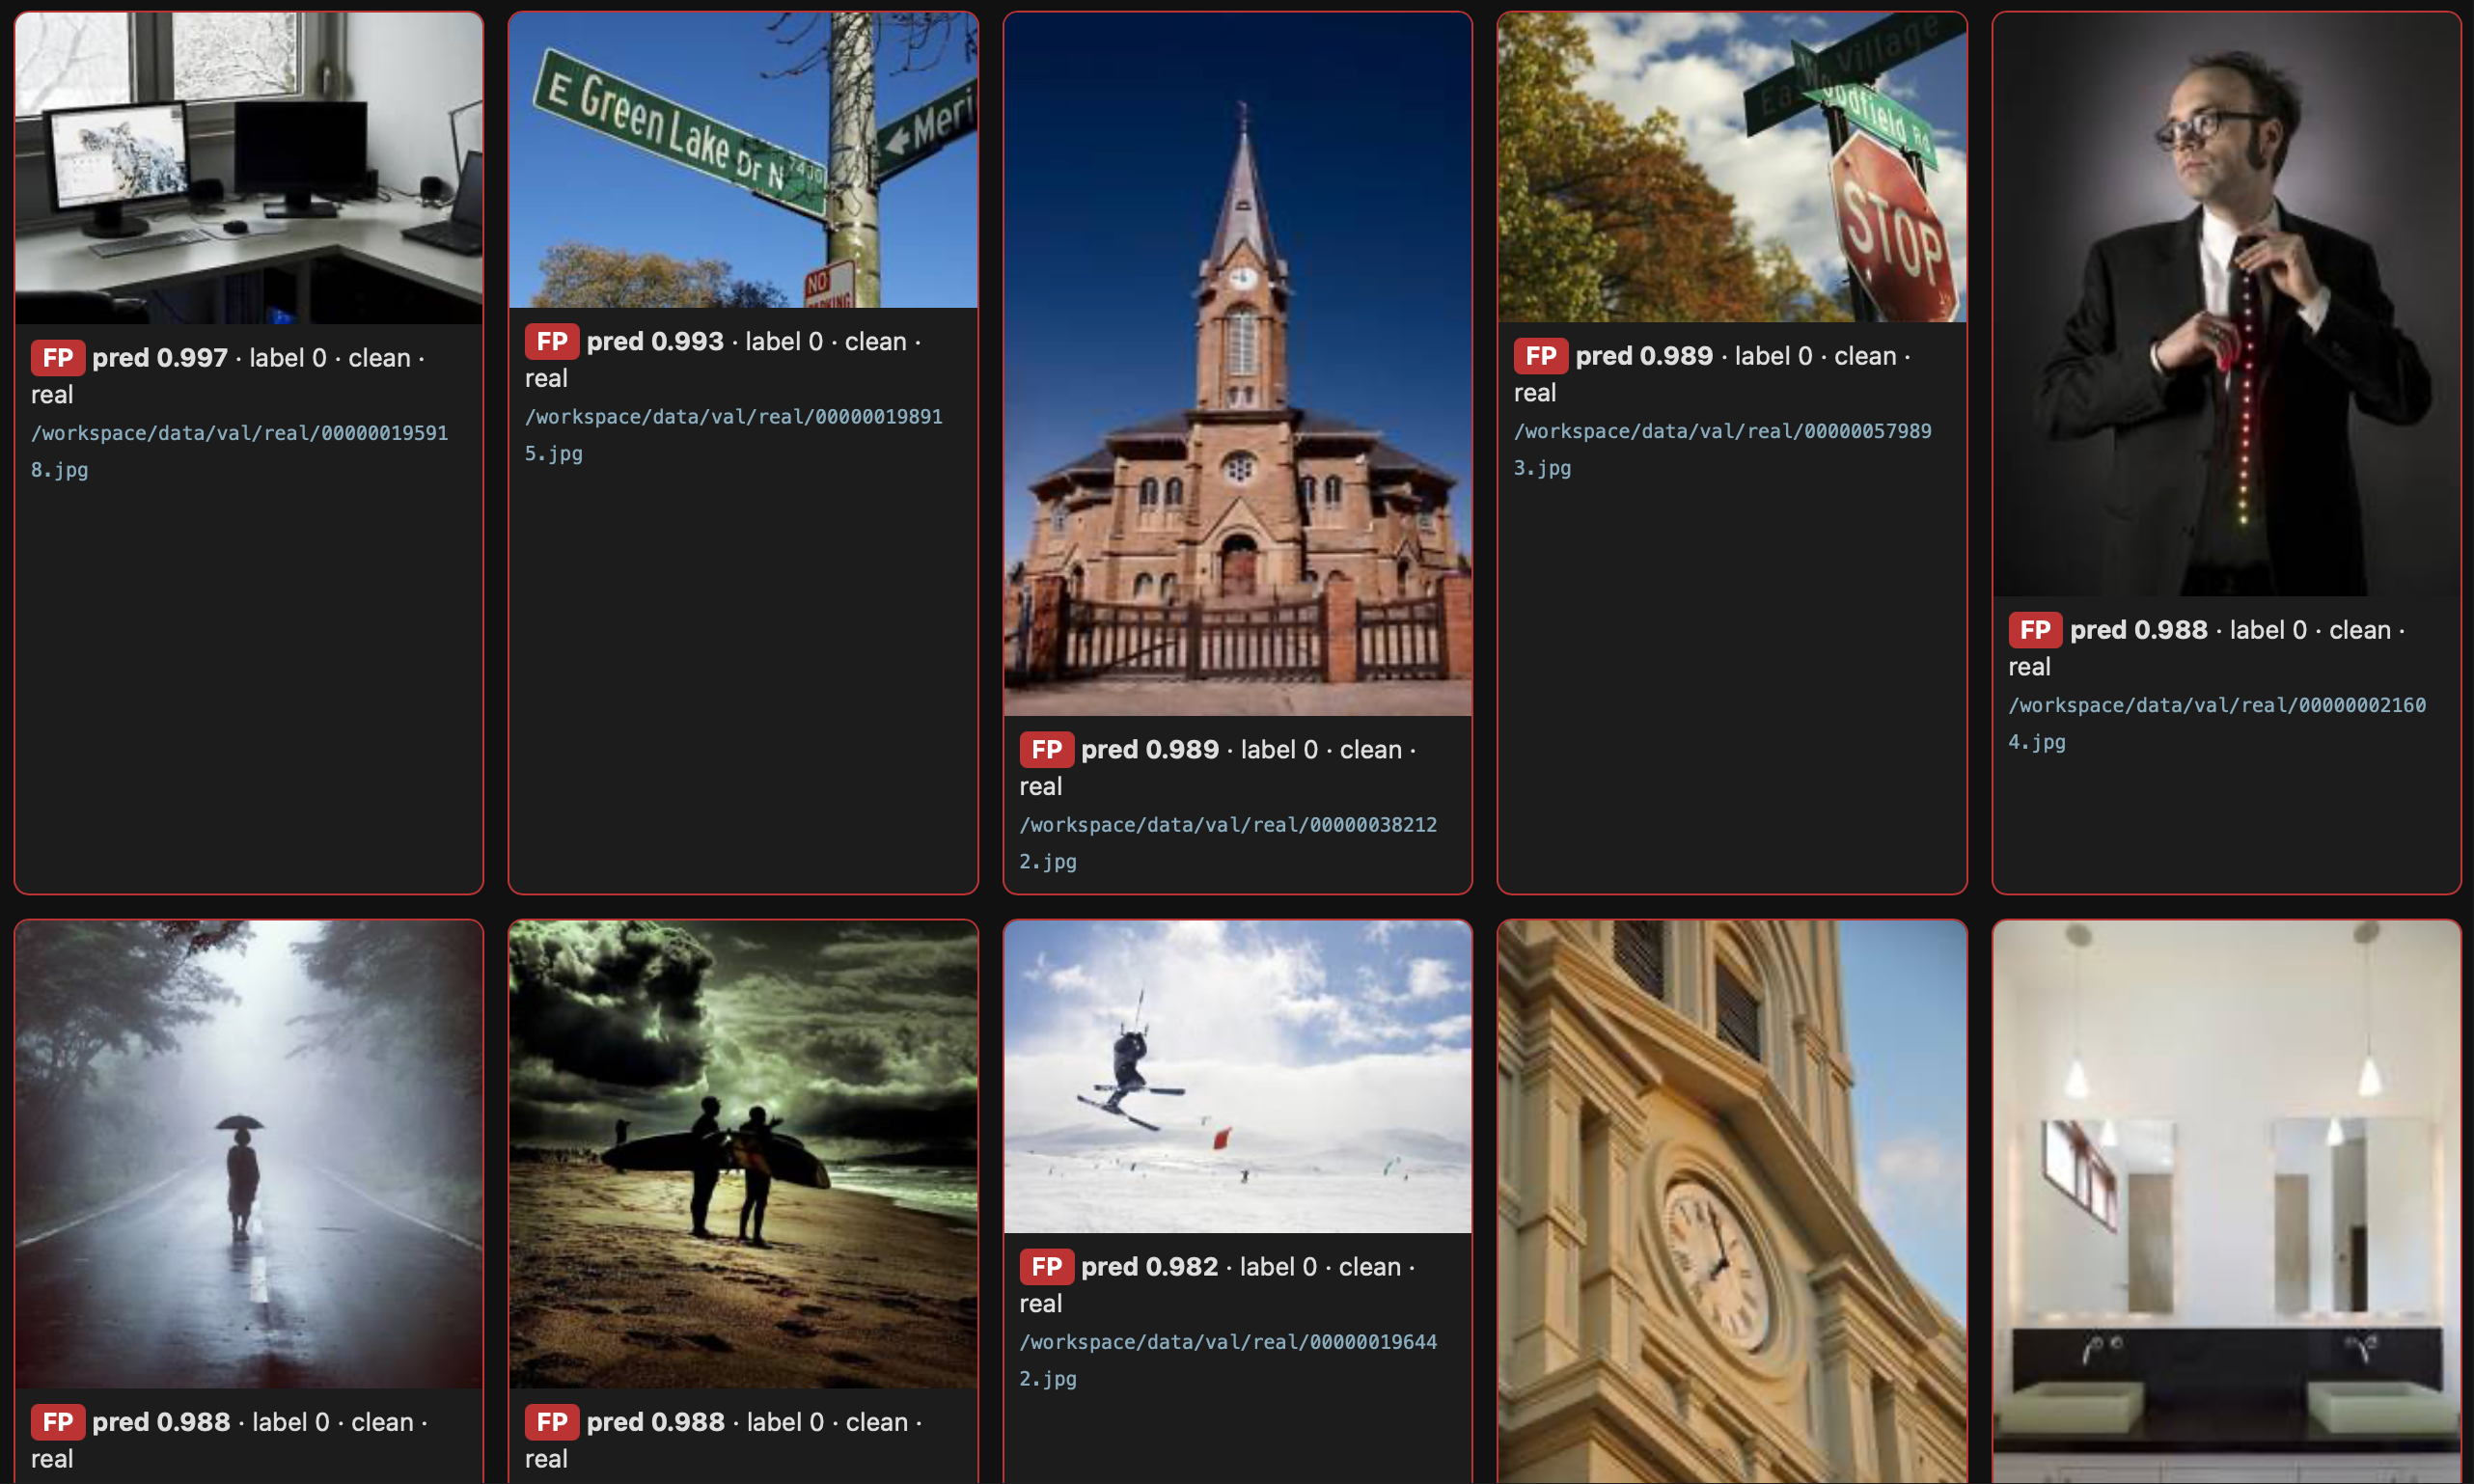
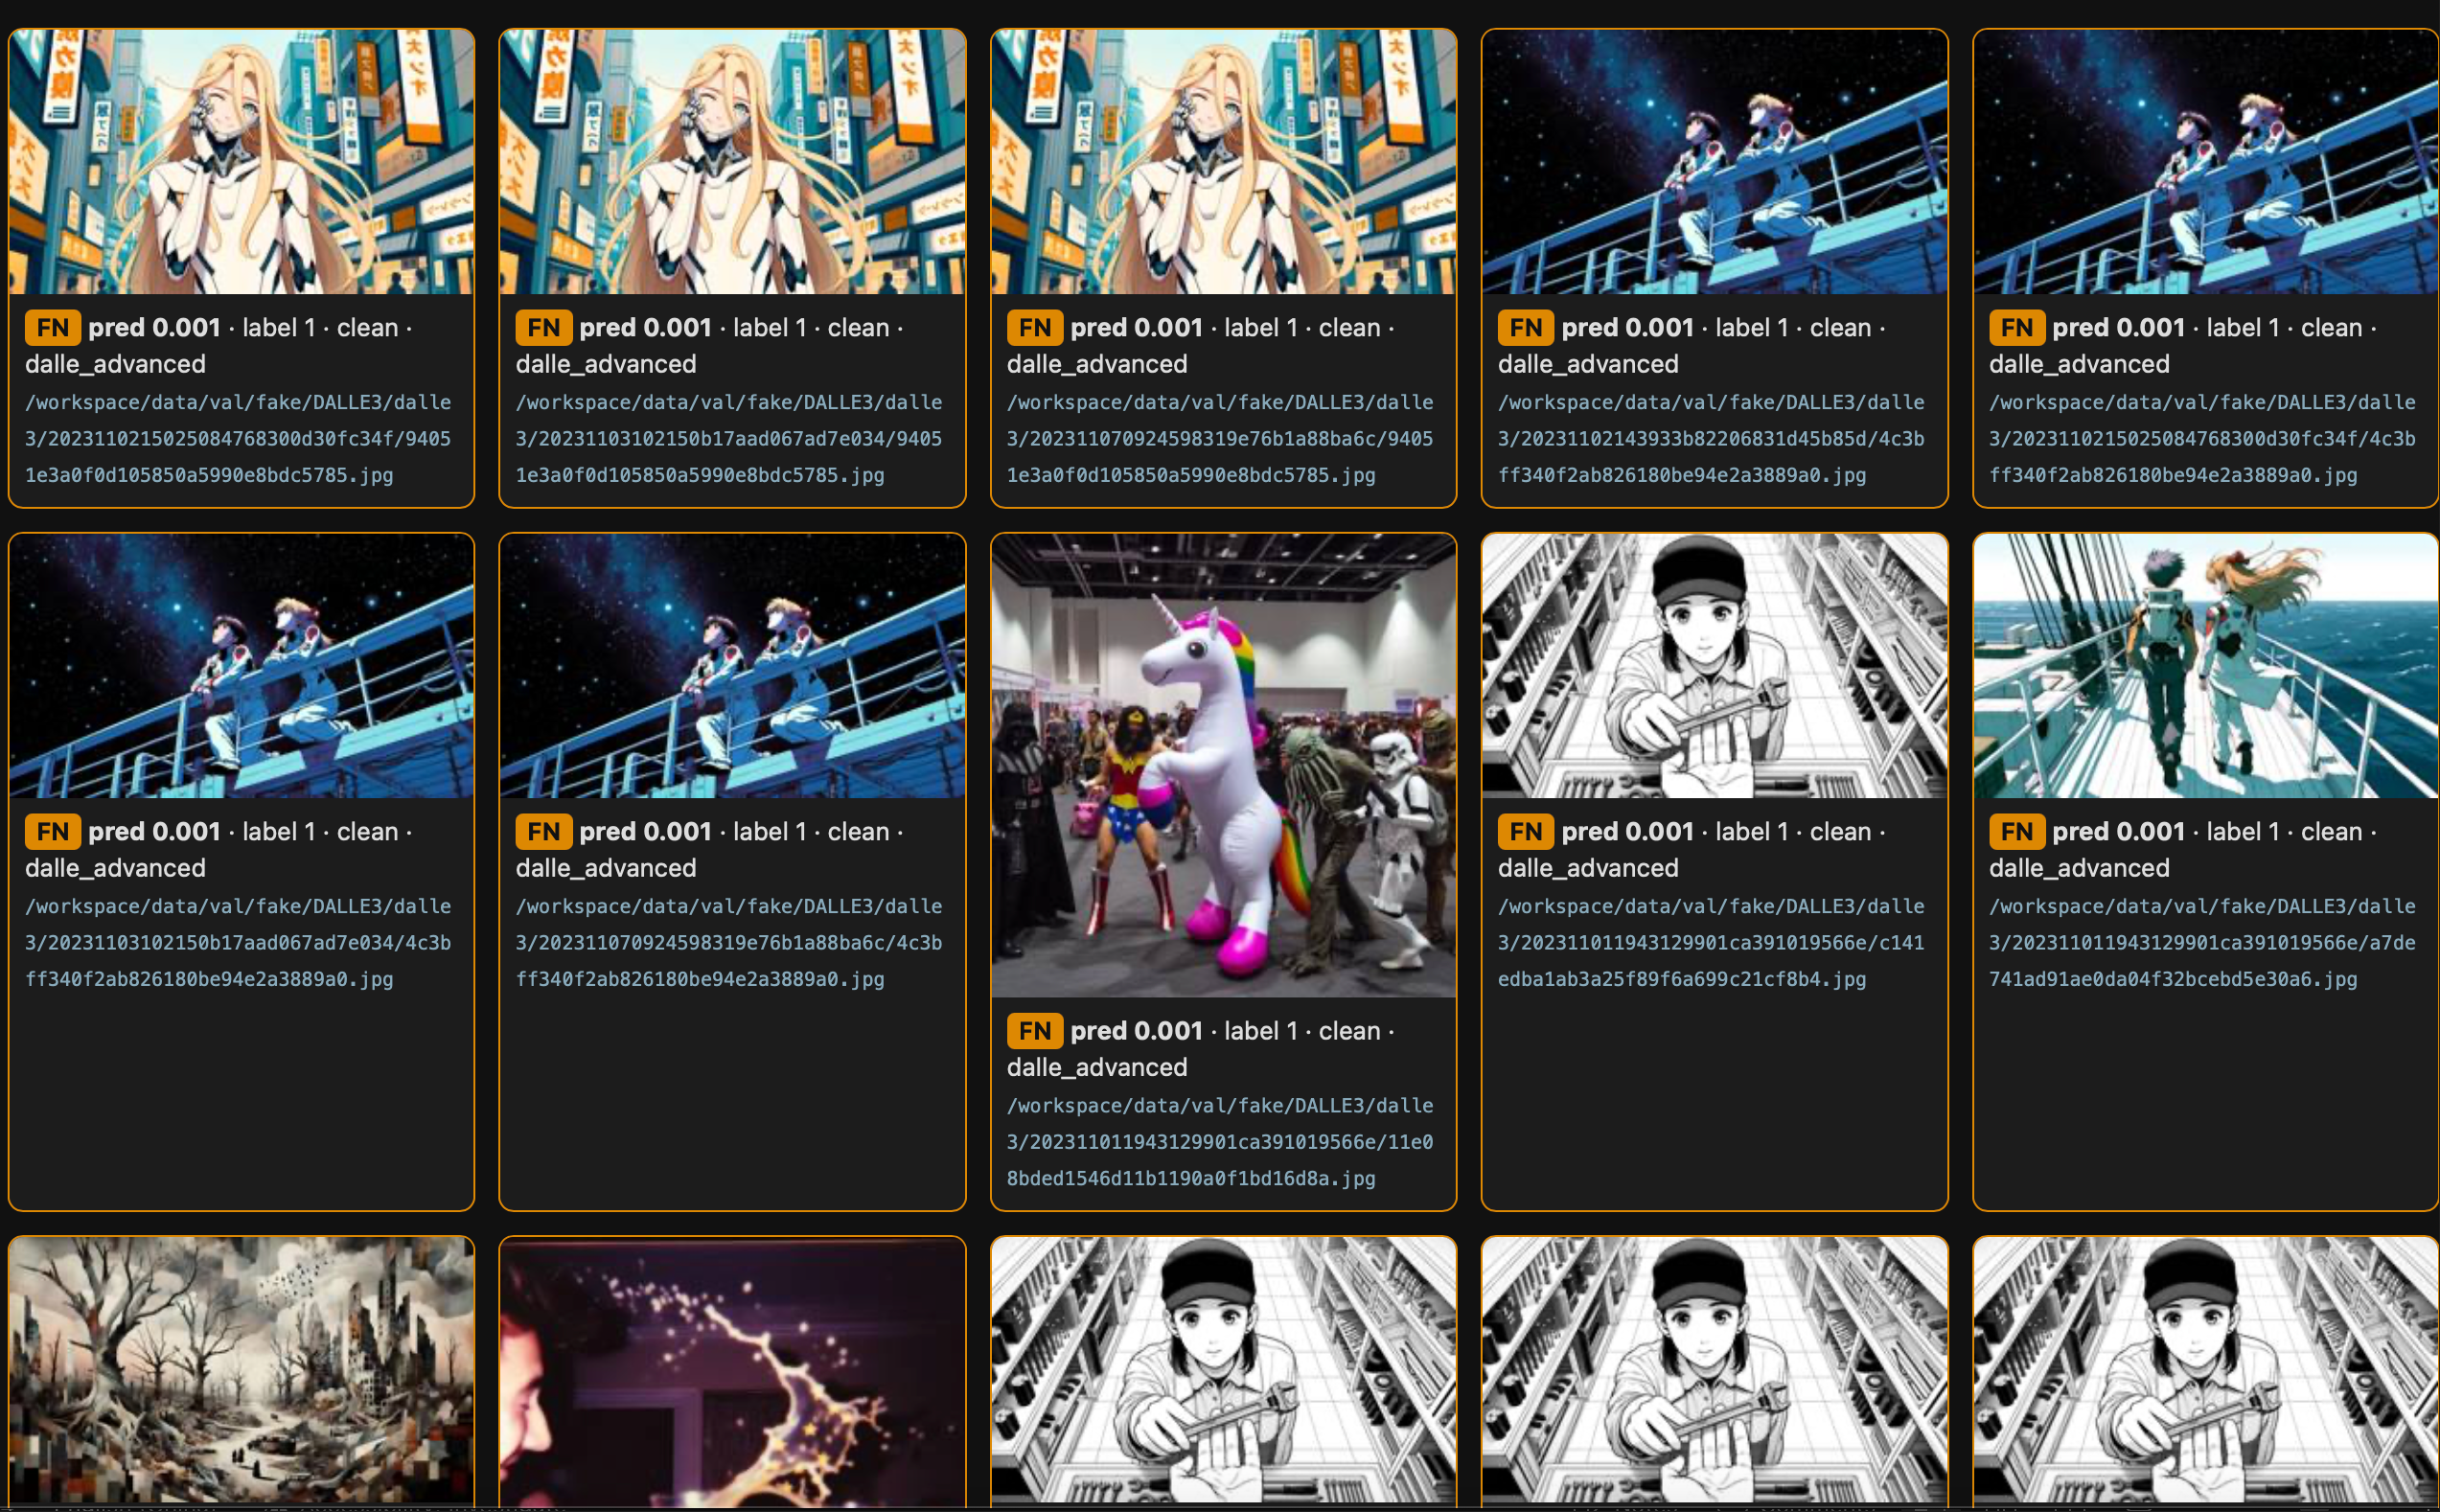
- Error analysis and HTML FP/FN galleries (open locally).
# last-4
python predict.py /path/to/images out.json \
  --ckpt checkpoints/submit/clipb16_last4_unfreeze.pt
# fuse last4+D3
python predict.py /path/to/images out.json \
  --ckpt checkpoints/submit/clipb16_last4_unfreeze.pt \
  --ckpt-b checkpoints/submit/clipb16_d3_mix.pt
How we built it
Hardware / software. 2× RTX 4090 (24 GB): GPU1 train, GPU0 infer/eval. Python 3.12.14, PyTorch 2.11.0+cu128, torchvision 0.26.0, transformers 5.16.1. SID is loaded as Hugging Face parquet, not a JPEG ImageFolder dump.
Datasets (train vs hold-out).
| Role | What | Link |
|---|---|---|
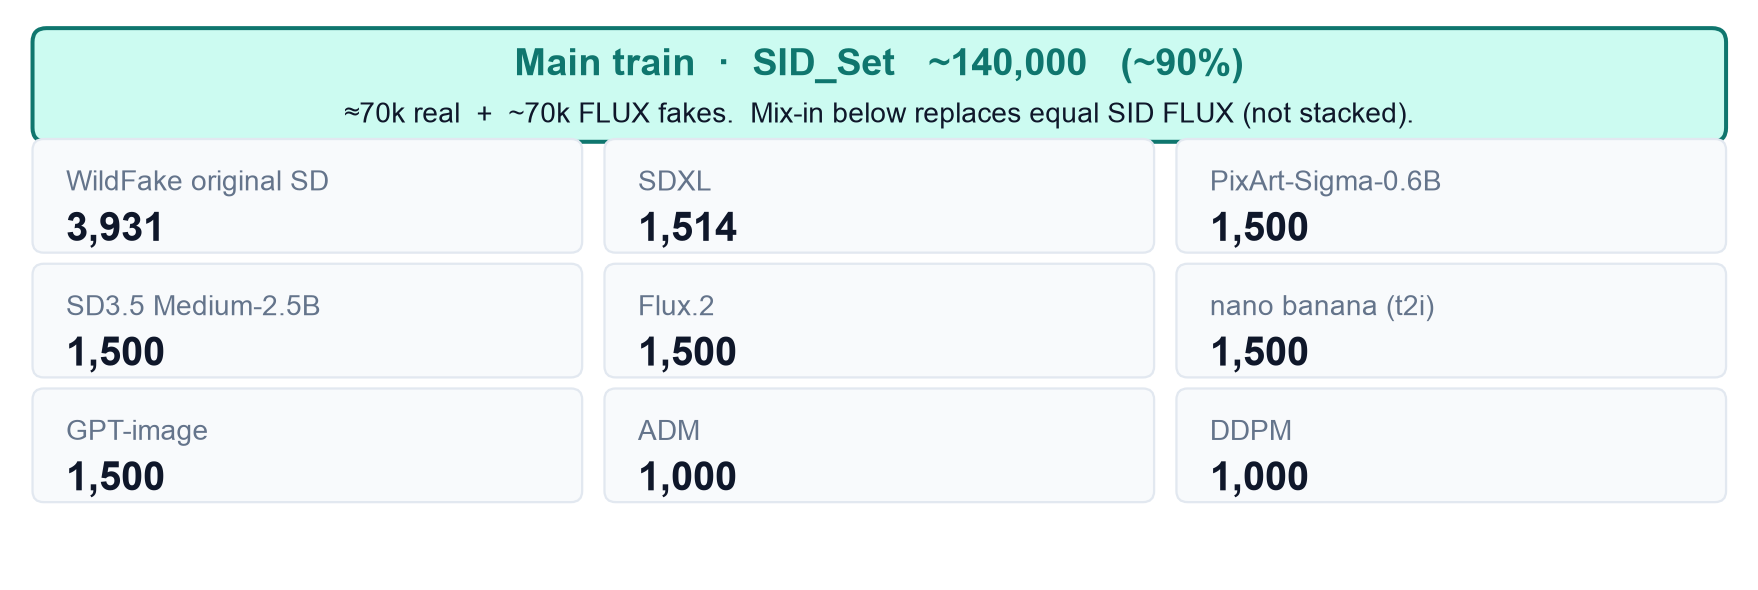
| last-4 train | SID_Set ~140k social photos (~70k real + ~70k FLUX), drop label=2, online official 14-transform aug |
saberzl/SID_Set |
| D3 mix-in (replace equal SID FLUX; not stacked) | WildFake original-SD UNet ~4k + ADM/DDPM 1k each + our Flux.2 / SD3.5 / nano | WildFake via repo download_wildfake_subset.py + AIGCTrace-Mix |
| Self-built release | GPT-image, Gemini Nano Banana, SDXL, SD3.5, FLUX.2, PixArt, plus a small i2i subset (~9.2k files, ~13 GB) | wwjjames/aigctrace-mix |
| Never train | Official demo val, EvalGEN | not re-hosted |
last-4 does not use the Kaggle zip. D3 is not “SID plus extra files”: replace_sid_fakes drops one SID FLUX per mix-in fake. Hunyuan is unused. COCO / DALL·E / EvalGEN stay out.
Model path. CLIP-L last-4 (0.980), ResNet (0.779), DINOv2 (~0.79), resize 336, RGB+frequency, and unfreezing the first 4 all lose on the contest formula. Training last-4 on the mix dropped official score to 0.976 — fuse at inference instead.
SID mix-ins (same protocol: frozen CLIP-B + online aug, ~140k). 400 = 200 COCO + 200 DALL·E.
| Mix | Extra fakes (replace SID FLUX) | Official 400 | EvalGEN clean | Nova AUC | i2i pair_acc |
|---|---|---|---|---|---|
| last-4 (SID only) | — | 0.990 | 0.989 | 0.963 | 0.64 |
| D3 (submit mix head) | WildFake UNet 4k + flux2/sd35 + ADM/DDPM 1k each (~9.6k; 603 nano then) | 0.978 | 0.995 | 0.988 | 0.79 |
| D4 | nano 1.5k + PixArt 1.5k + SDXL 1.5k + GPT-image 1.5k (from AIGCTrace-Mix) | 0.973 | 0.989 | 0.963 | — |
| D5 = D3 ∪ D4 | ~15k | 0.975 | 0.995 | 0.986 | 0.79 |
| D6 = D5 + 118 i2i | D5 + Codex/nano reconstructions (no paired reals) | 0.977 | 0.994 | 0.984 (15-cond) | 0.805 |
| fuse last4+D3 | mean logit, no retrain | 0.9930 | 0.997 | 0.988 | — |
| fuse last4+D4 / D5 / D6 | same | 0.990 / 0.9927 / 0.9929 | — | — / 0.987 / 0.986 | — |
D4’s extra T2I did not lift Nova (0.963, same as last-4). D5 ≈ D3. D6 lifts pair ranking slightly; contest score is unchanged. Submit stays last-4 (1 ckpt) or fuse last4+D3 (2 ckpts).
Train/eval commands: README Reproduce on the GitHub repo.
Challenges we ran into
- [email protected] lied. Last-4 raised AUROC but looked worse at 0.5 because fake scores sat lower — the contest metric is AUROC.
- A 59-triplet i2i-only probe scored 0.443 on official val (overfit). D6’s 118 i2i fakes on SID mix only moved pair_acc 0.79 → 0.805; contest score stayed below D3.
- False negatives at 0.5 look high (fuse 44/200), but the gallery cluster is non-photoreal DALL·E (comics / anime / illustration), outside a social-photo target. False positives on COCO are rare (1 FP). Residual photoreal DALL·E misses still exist; we do not claim FNR vanishes in the wild.
- Official val and EvalGEN had to stay strictly out of train; mixing them in would invalidate the score. SID cannot be trained as a raw JPEG dump — parquet + drop
label=2+ online aug is the recipe.
Accomplishments that we're proud of
- Last-4 0.990 / fuse 0.993 on the official formula, model ~86M ≪ 2B.
- Last-4 ≥ 0.980 on every official transform key; fuse ≥ 0.984.
- Held-out EvalGEN: mixed data lifts Nova [email protected] from 0.49 → 0.86 while fuse keeps DALL·E ranking.
- Public reproduce path: GitHub + v1.0-submit weights + AIGCTrace-Mix.
- Reproducible
predict.py, 15-condition figures in-repo, and a local HTML bad-case gallery.
What we learned
- Domain (SID vs CIFAKE) moved the score more than a larger backbone.
- Complementary heads + mean-logit fuse beat “unfreeze on the mix”.
- Generator coverage (UNet / pixel diffusion in D3) mattered for Nova; extra T2I from AIGCTrace-Mix (D4 PixArt / GPT / SDXL / nano) and 118 i2i fakes (D6) did not beat D3 on the contest formula.
- High AUC is not a license to ship threshold 0.5 — pick an FPR budget.
What's next for Robust AIGC Detection under Social Transforms
Calibrate last-4 so 0.5 matches a stated FPR without changing AUROC. Grow whole-image i2i beyond 59 triplets (D6’s 118 fakes only moved pair_acc 0.79 → 0.805). Add a license-clean Nova-family t2i stand-in that is not EvalGEN. Keep fuse last4+D3 if two files are allowed; do not train last-4 on the mix again.


Log in or sign up for Devpost to join the conversation.