Inspiration
During Hurricane Harvey, civilians took their own fishing boats out to pull neighbours off roofs. They rescued thousands of people. Some of them drowned doing it.
One detail kept pulling us back. When a volunteer self-deploys, nobody writes down that they went. No dispatcher, no roster, no log. If they don't come back, there is no moment where a system notices — someone eventually realises they haven't heard from a person in a while.
A dispatcher who was there put it better than we could. Interviewed afterwards by researchers at ISCRAM, he described trying to keep track of "who was going out who was coming back who was out on a boat, can we account for everyone, and who's in their house and it was a mess." The same study found at least twenty separate volunteer groups operating with, between them, "no way to seamlessly share information and coordinate activity."
The detail that decided the design is smaller than either. The rescuers in that study described their phones constantly blowing up with relatives asking "are you okay, are you okay, are you okay." Somebody was always going to ask the question. The question simply had nowhere to be answered.
Every disaster app we looked at maps the incident. We couldn't find one that keeps a list of the people walking into it.
What it does
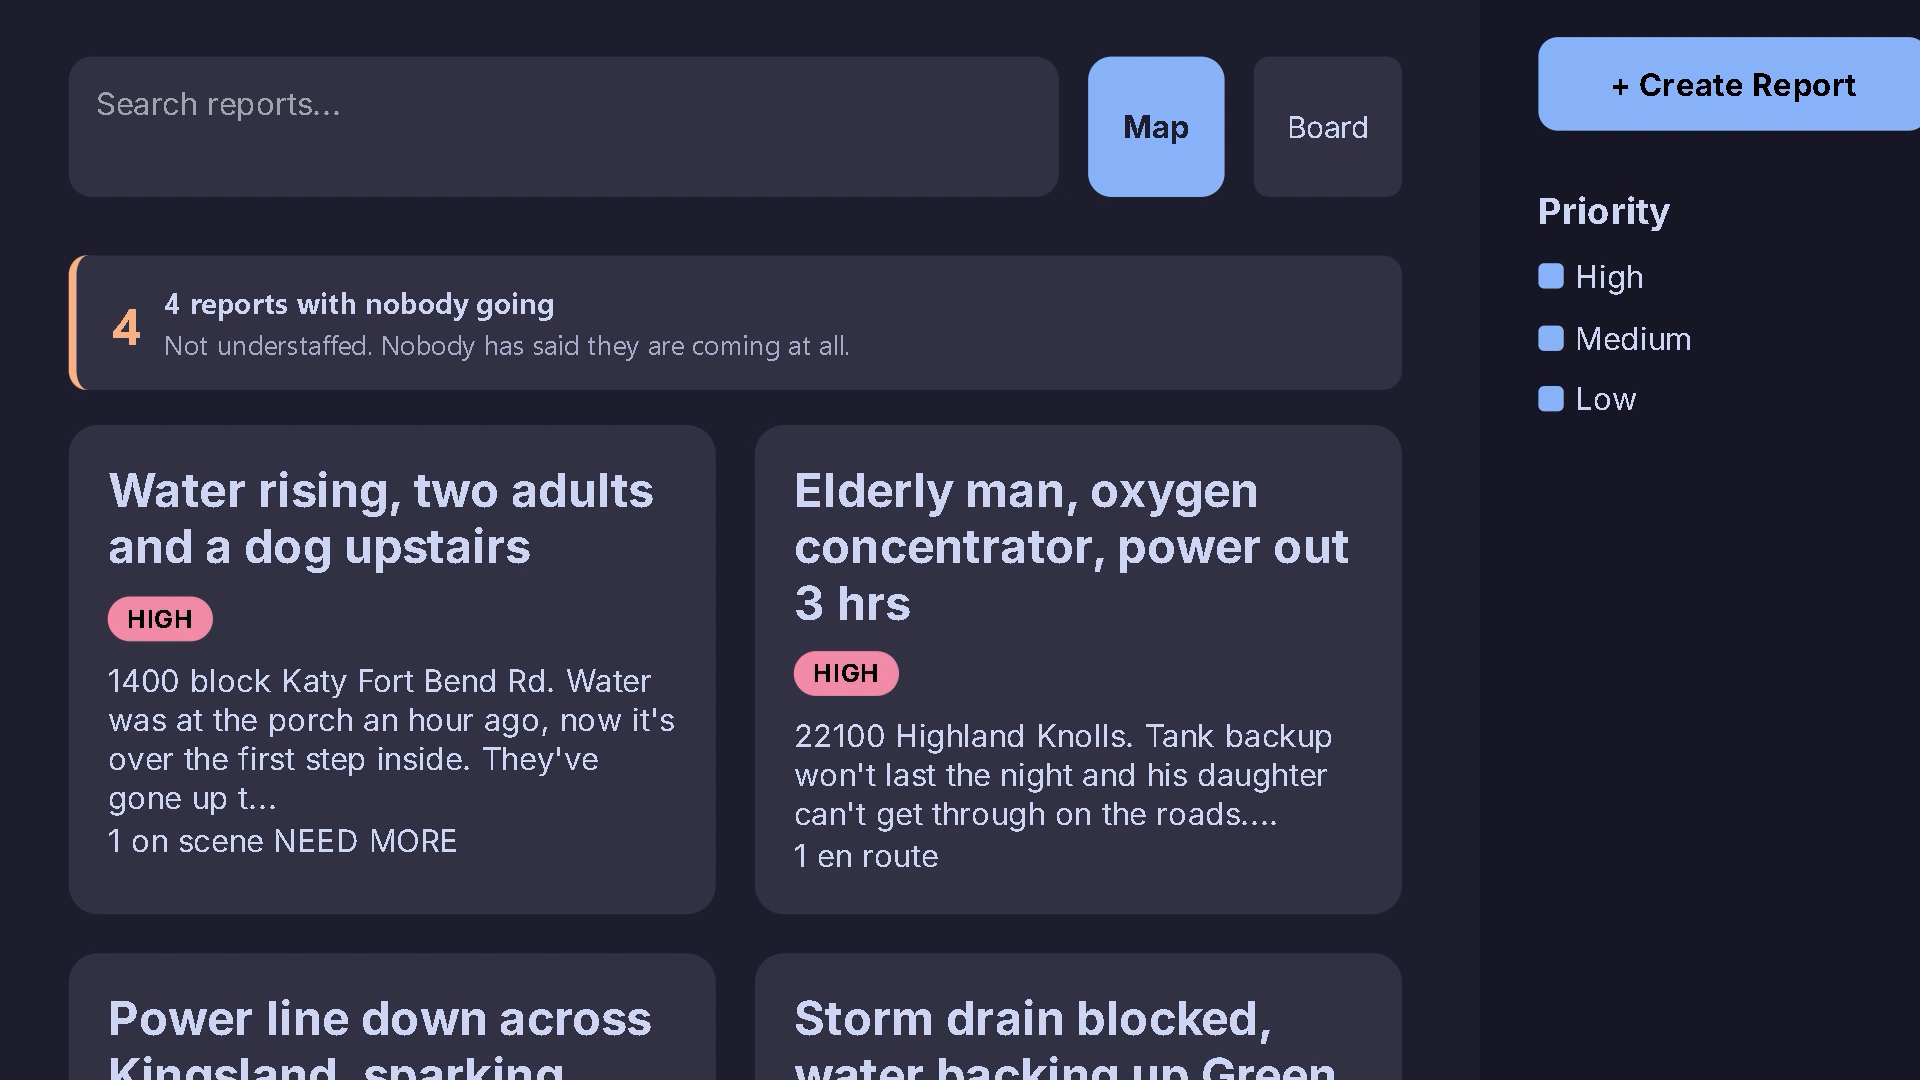
You file a report: what's happening, how bad, and where — pinned on a map or pulled from your phone's GPS. If you can't judge how bad it is, four questions run START, the triage protocol used at real multiple-casualty scenes, and pick for you.
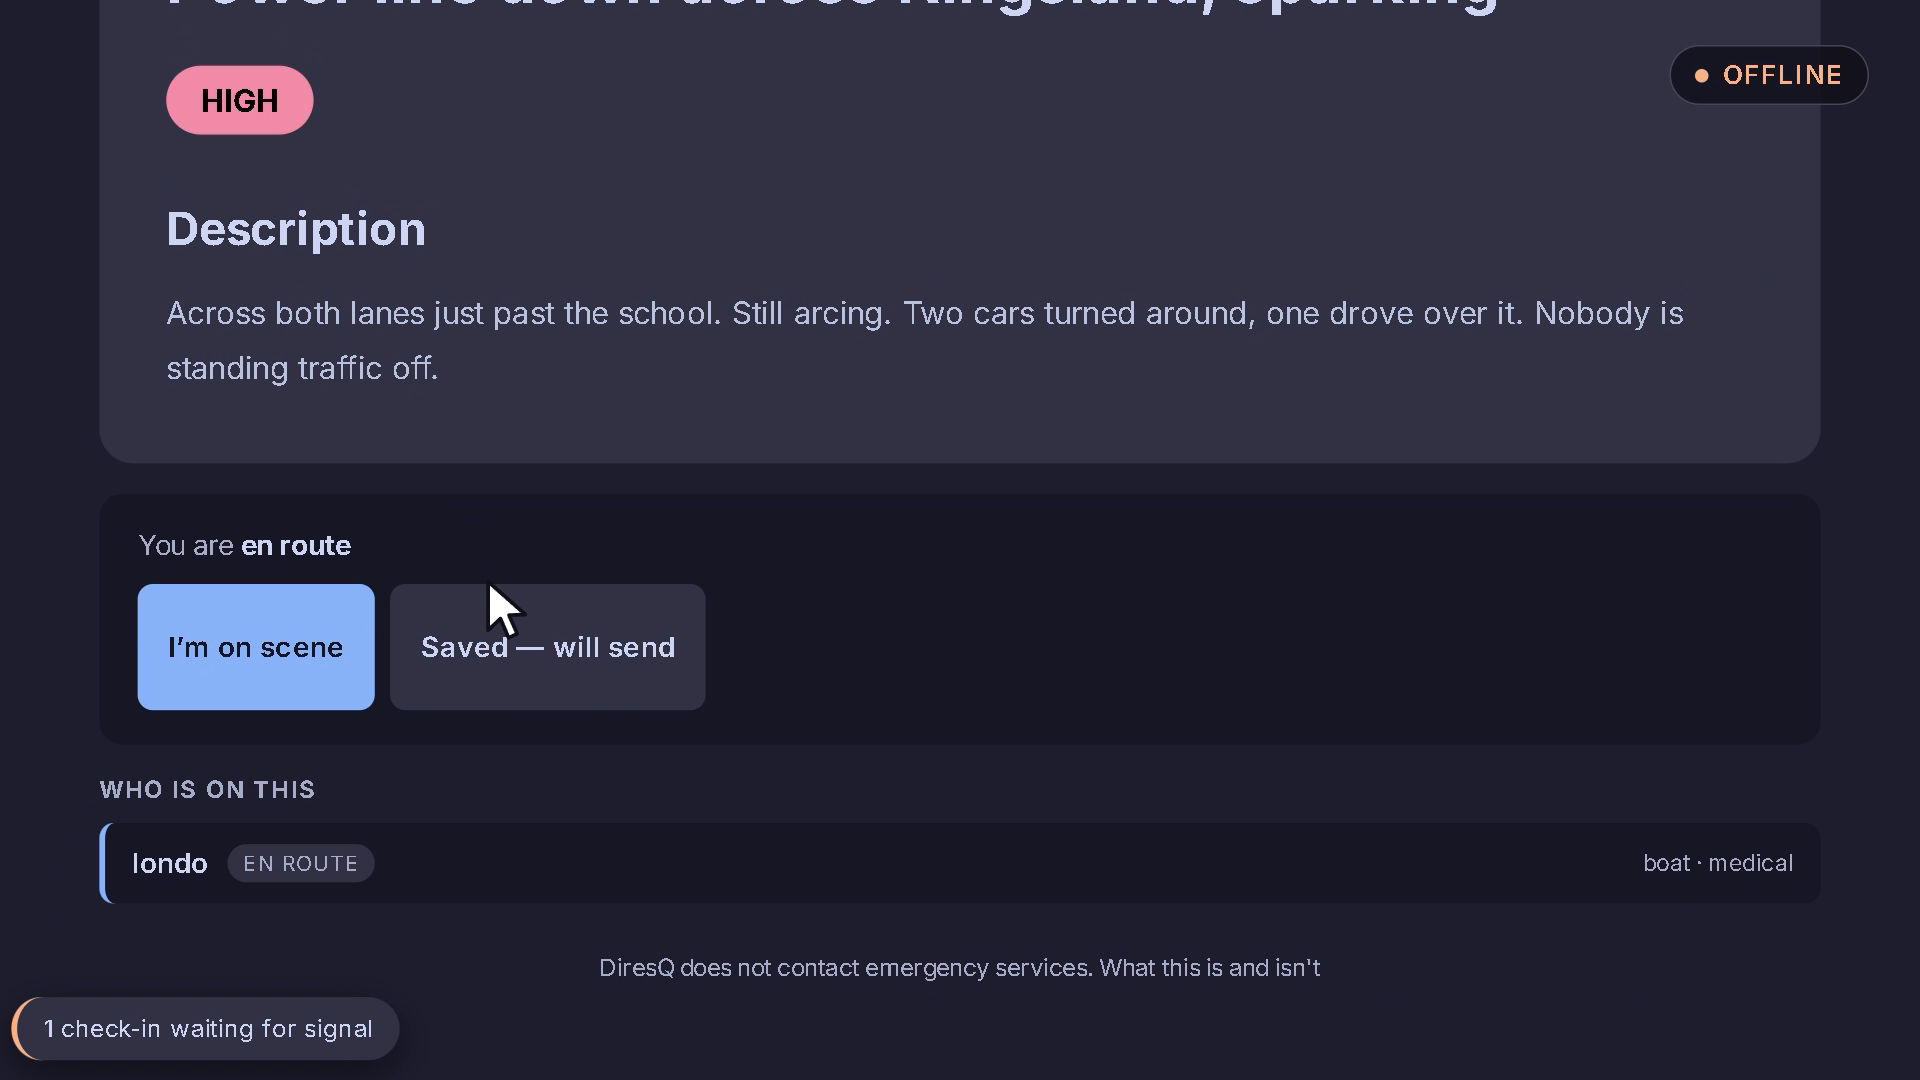
Responders join and give a rough ETA in plain English — "30 min", "back in a couple hours". That becomes a check-in deadline.
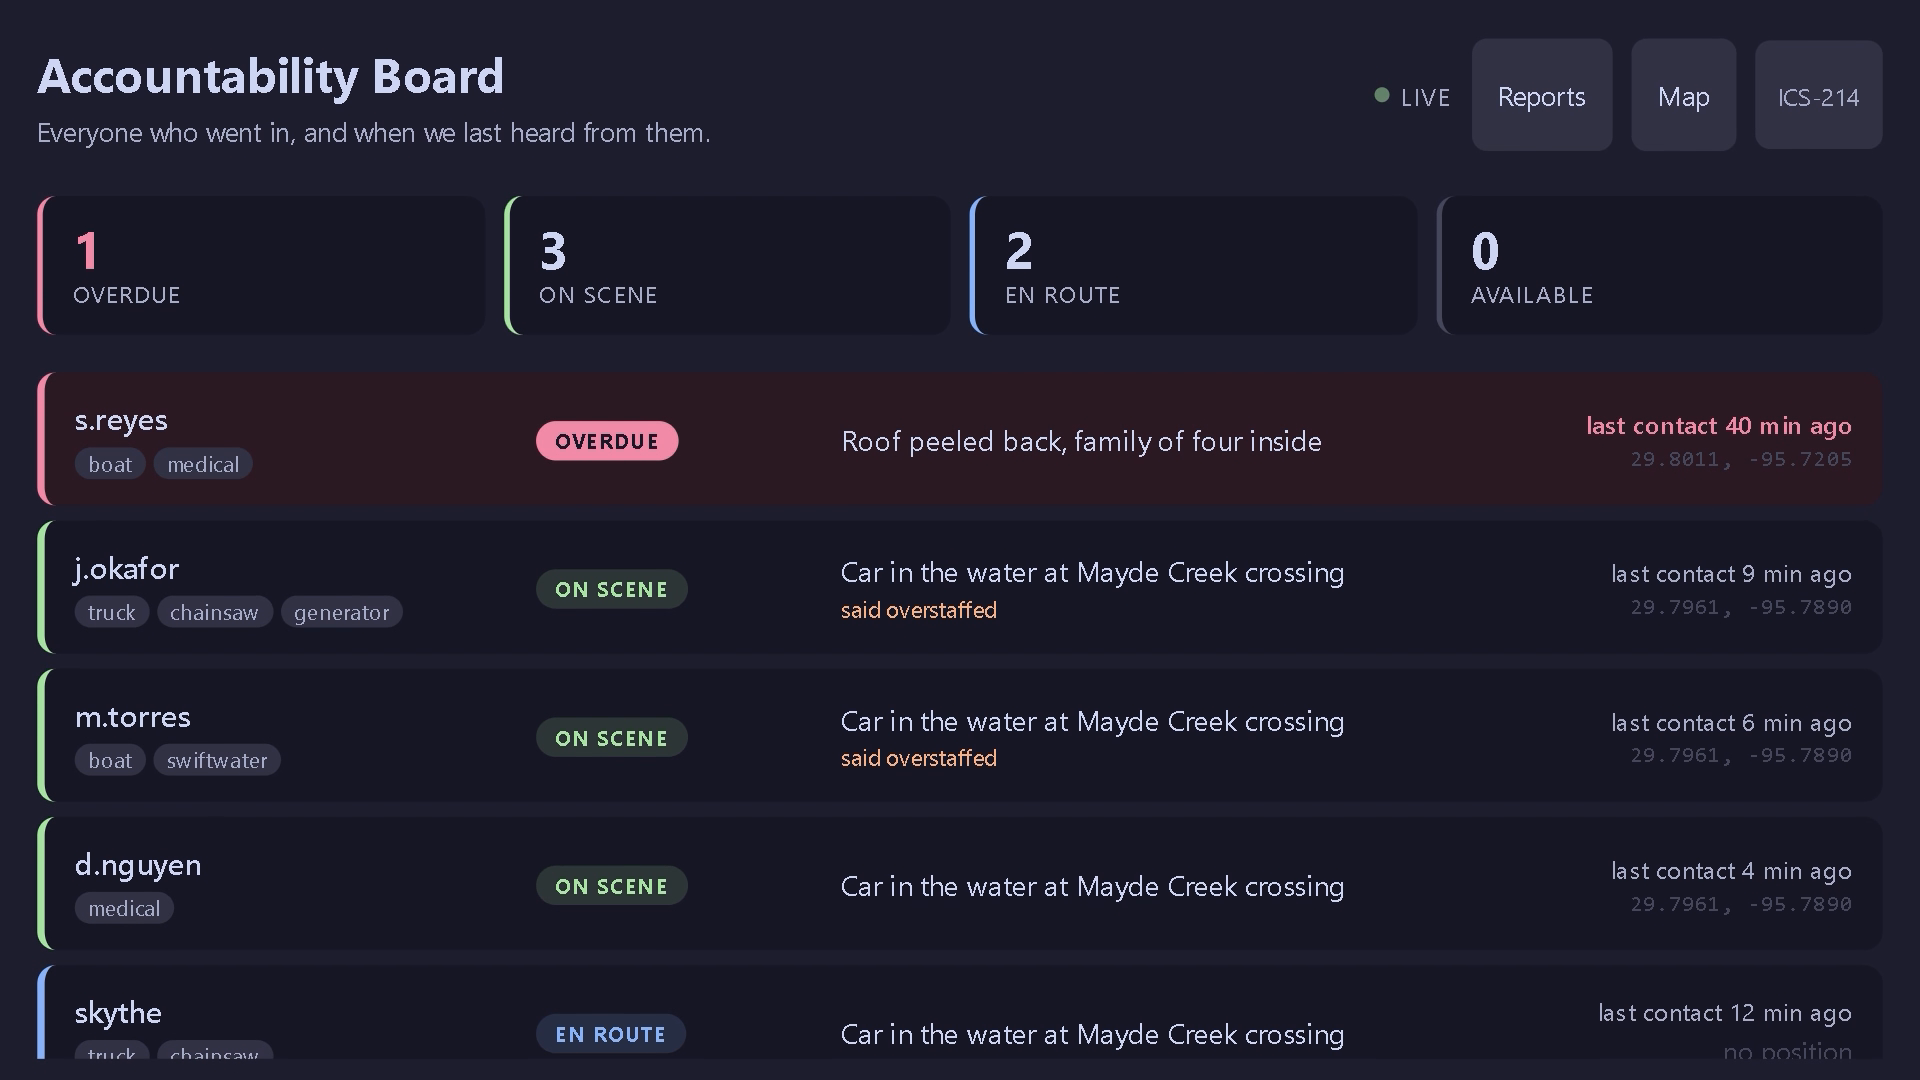
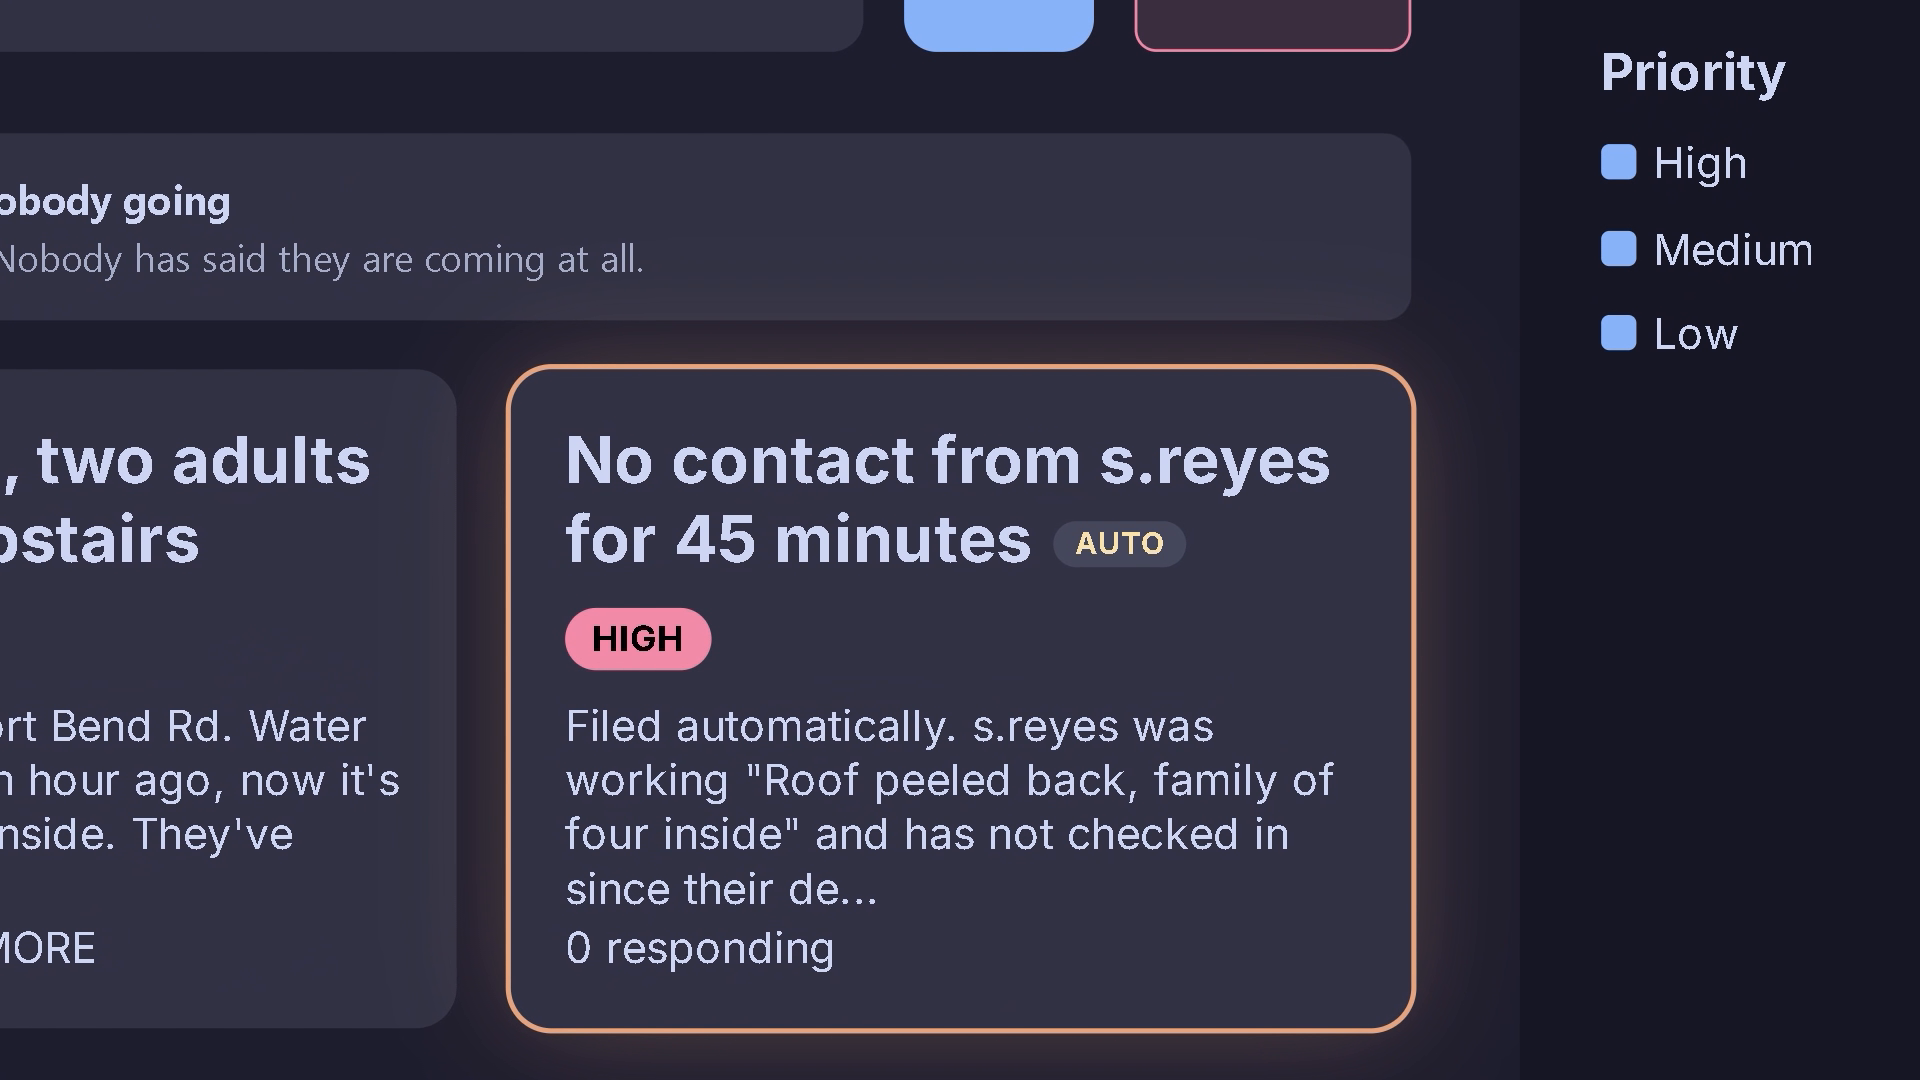
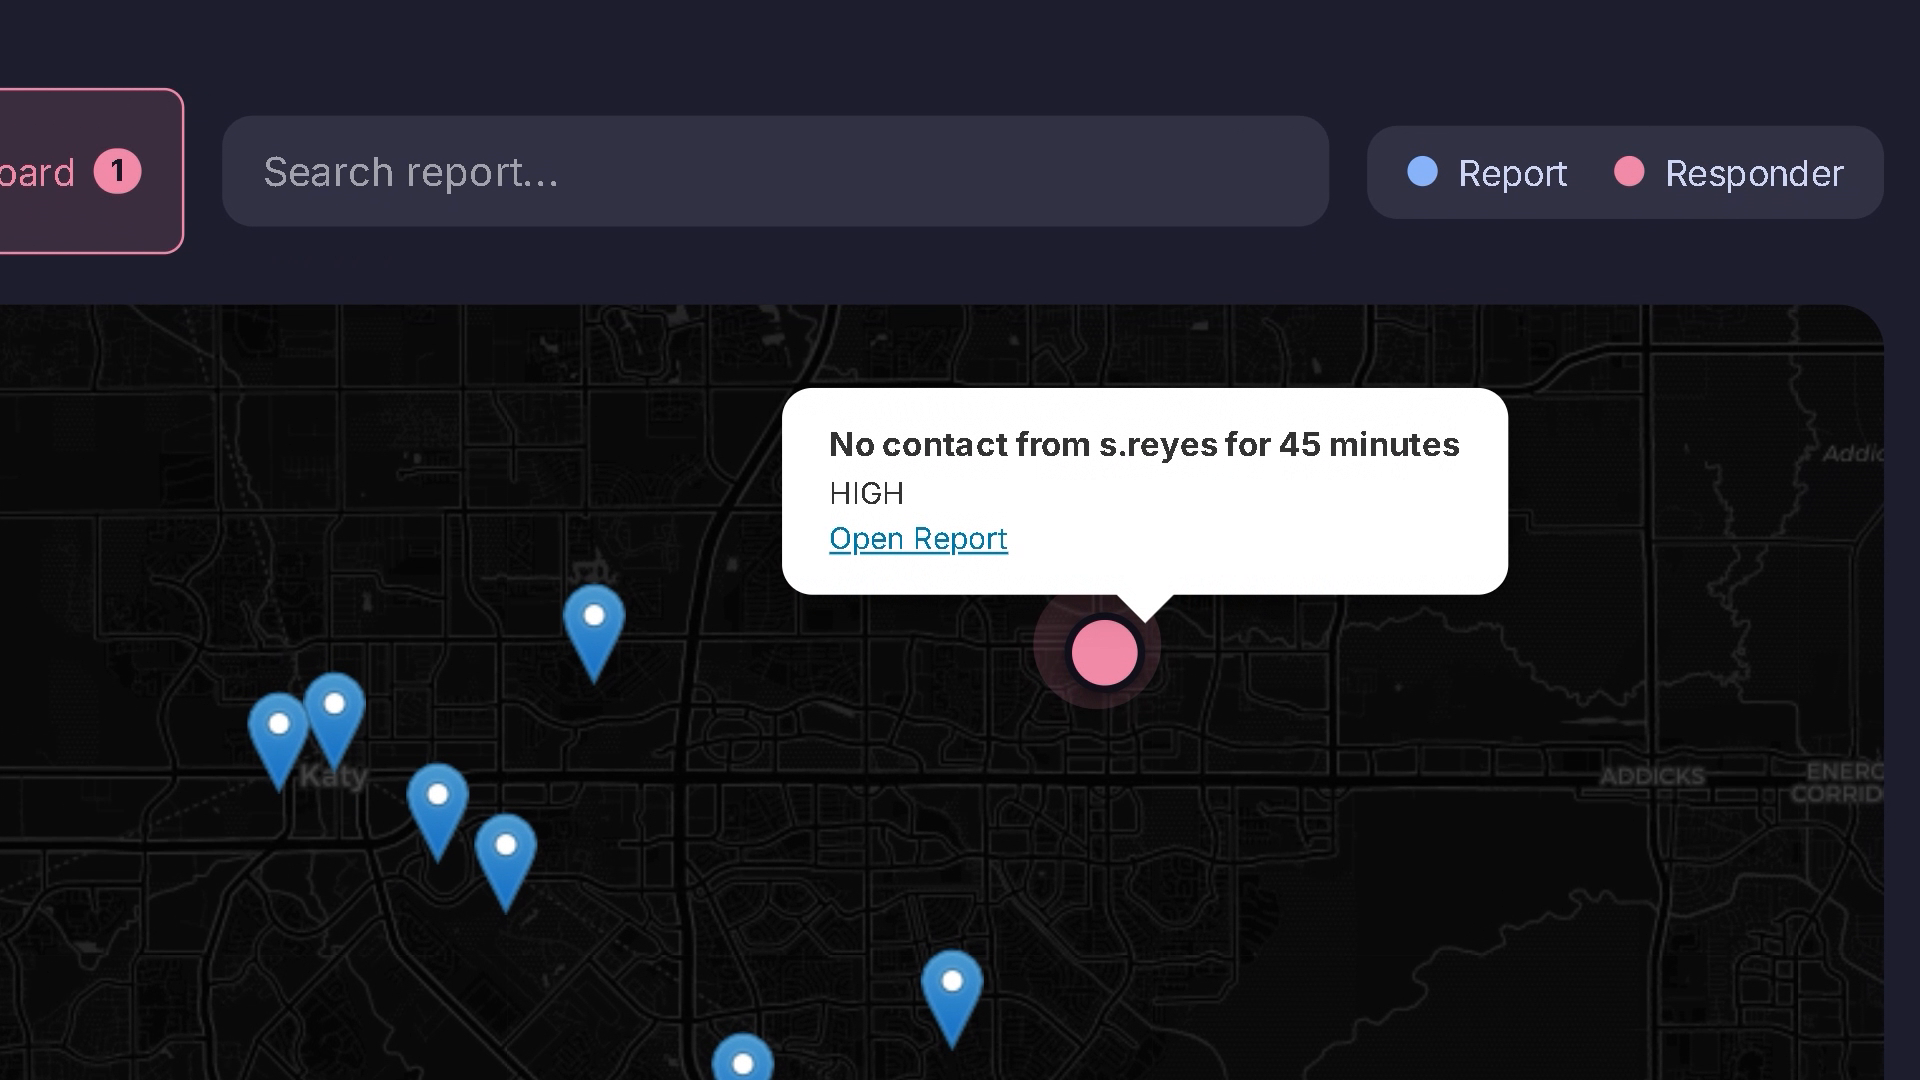
Then the part the whole thing exists for: if nobody hears from you by your deadline, the board turns red. Your name, your last known position, how long since anyone heard from you. Nobody has to notice. Nobody has to remember you went out.
Stay quiet fifteen minutes past that and the server stops waiting to be noticed. It files a report about you, at your last known position. It joins the feed like any other job, so somebody can go and find you.
You can watch this happen rather than take our word for it. The mechanism is the absence of an event over fifteen minutes, which is the hardest thing in software to show anybody. So the clock is injectable: with DIRESQ_DEMO_SPEED=60 a minute of incident time passes every second, a responder goes overdue five seconds after the page loads, and the report about them arrives fifteen seconds after that. Nothing is staged for the camera — there is one now(), and every deadline, comparison and query downstream is the production code untouched. Only the rate at which time enters the system changes, and the page says so while it does, because a screen showing accelerated time has to admit it.
Any number of responders can join the same report — there's no claim lock, deliberately. Once you're physically on scene you can signal how staffed the site is, and that reorders the feed, so the next person who opens the app goes where the help isn't.
How we built it
Flask and SQLite, server-rendered pages with a JSON API layered on top, Leaflet for maps. The whole app works with JavaScript switched off.
Four of the libraries are ours — written from scratch, published to PyPI, then installed back into this project like anyone else's dependency:
| Package | What it does here |
|---|---|
timefuzz |
turns "back in a couple hours" into a real deadline, with a confidence score |
vitalscore |
runs the START triage decision tree |
pygeospy |
distance, bearing and bounding-box maths |
patchnotes |
validates our changelog on every push |
The machine learning, and why it isn't a language model
Somebody filing a report at 2am from a flooded house is being asked to pick a severity from a dropdown. They don't know. They aren't trained, they're frightened, and the honest answer to "how bad is this on a three-point scale" is you tell me.
So we hand-wrote a multinomial naive Bayes classifier. One file, no dependencies, no model file, no network, 0.1 ms per call, trained on 55 hand-labelled reports. The whole decision is one line of maths:
$$\hat{y} = \arg\max_{c} \left[ \log P(c) + \sum_{i} n_i \log P(w_i \mid c) \right]$$
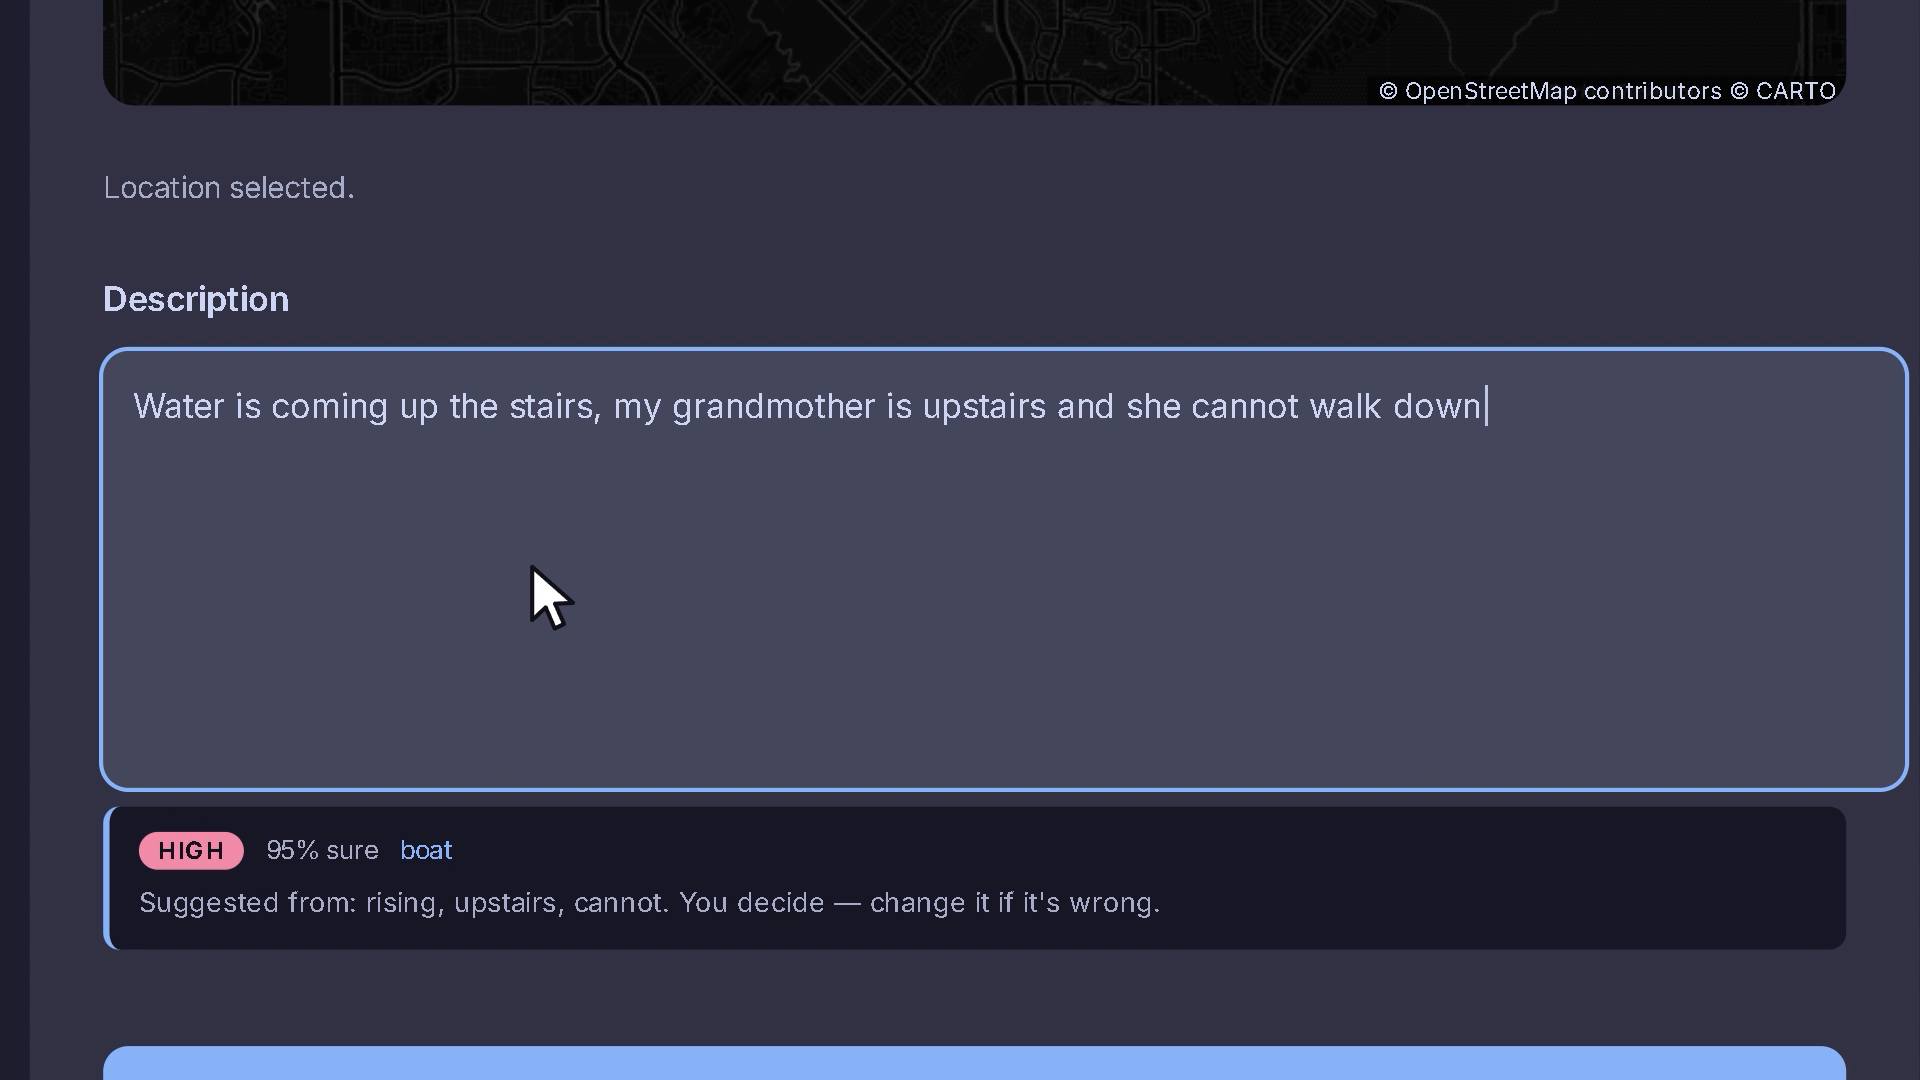
Type "water rising fast, grandmother upstairs and cannot walk down" and it answers HIGH, and tells you it decided that from rising, upstairs, cannot — those are the top terms of that same sum, not a separate explanation. Touch the dropdown yourself and it stops adjusting it, permanently.
The same maths spots when your description matches a report somebody has already filed, by cosine similarity over stemmed term counts:
$$\text{sim}(a, b) = \frac{\mathbf{a} \cdot \mathbf{b}}{\lVert \mathbf{a} \rVert \, \lVert \mathbf{b} \rVert}$$
Duplicate reports are exactly how six people end up at one address while a street nearby has nobody. That threshold was measured, not guessed:
| Similarity | |
|---|---|
| Two genuinely different reports | at most 0.157 |
| A restatement of the same incident | 0.409 |
| A reworded restatement using synonyms | 0.241 |
We set it at 0.30 — nearly double the margin over the worst false positive. Note the third row: it misses the synonym case, and we left that in the table because it's the honest limit of counting words. "Flooding, couple on the second floor" and "water rising, two adults upstairs" share almost no vocabulary and describe the same house. Catching that needs embeddings, and embeddings need a model file, a download, and a machine to run it on.
We deliberately did not use an LLM, for three reasons in the order they mattered:
- It has to explain itself. The words shown are the decision — the ranked log-odds — not a separately generated rationalisation that can disagree with it. "Trust me" isn't available when somebody is deciding where to send a boat.
- It has to be honest about being wrong. Below 45% confidence it says nothing at all. A confident paragraph from a language model is much harder to disbelieve, and this is a domain where confidently wrong sends people to the wrong street.
- It has to run. No download, no API key, no network, no GPU. Our check-ins already queue offline; a classifier that needed somebody else's datacentre would be the one part of the system that fails exactly when it's needed.
How we used AI
Two different things get called AI here, and the paragraphs above are only about one of them, so to be unambiguous:
In the shipped product — none. No LLM, no API, no model file. The classifier is the naive Bayes described above, and that is the only machine learning DiresQ contains.
In building it — yes. We used AI for code, documentation, and literature search. It was a working tool for fourteen hours, not a footnote.
What that did and didn't cover. Every design decision reported here is ours, including the one we reversed — the claim lock came out because we read about Kathmandu and Mexico City and concluded it was wrong. Every number on this page was produced by running the code and reading the output, not by asking a model what it thought the answer was; the held-out 75%, the 0.30 threshold and the 0.157/0.409 margins are all measurements, and the test suite fails the build if any of them drift. The commit history is public if you want to see how it was actually built.
Challenges we ran into
Our first design was wrong, and we threw it out. We built the dispatch model: one responder claims one report, it's locked, nobody else can take it. It felt obviously right. Then we read about Kathmandu in 2015 and Mexico City in 1985 — hundreds of neighbours converging on single collapse sites — and about Harvey, where whoever owned a boat went to whatever address they saw online. A claim lock would have fought the exact thing that saves people. The real failure mode isn't two people colliding on one job; it's fifty people on one street while the next one over has nobody.
The plan didn't survive contact. We'd agreed the backend would push stub JSON endpoints in the first hour so the frontend could build against them — and then we put the one hard dependency in the whole plan on a single task and didn't treat it as one. It sat in the doc looking like a step rather than a blocker. The stubs never got written, and the frontend rightly kept moving instead of waiting, building five complete pages as server-rendered templates that ignore JSON entirely.
The plan failing produced a better app — the whole thing works without JavaScript now. What it cost was the contract: with no stubs and no conversation instead of them, both sides assumed one, and three field names came out different. The lesson isn't "somebody should have waited." It's that a plan with a dependency in it needs that dependency named as one, out loud, with a time on it.
Deciding what not to build was harder than building. LoRa mesh is roadmap-only. We don't have radios, so we couldn't test it, and untested code isn't a feature — it's a file that looks like one.
Accomplishments that we're proud of
We caught our own classifier lying, and published the number.
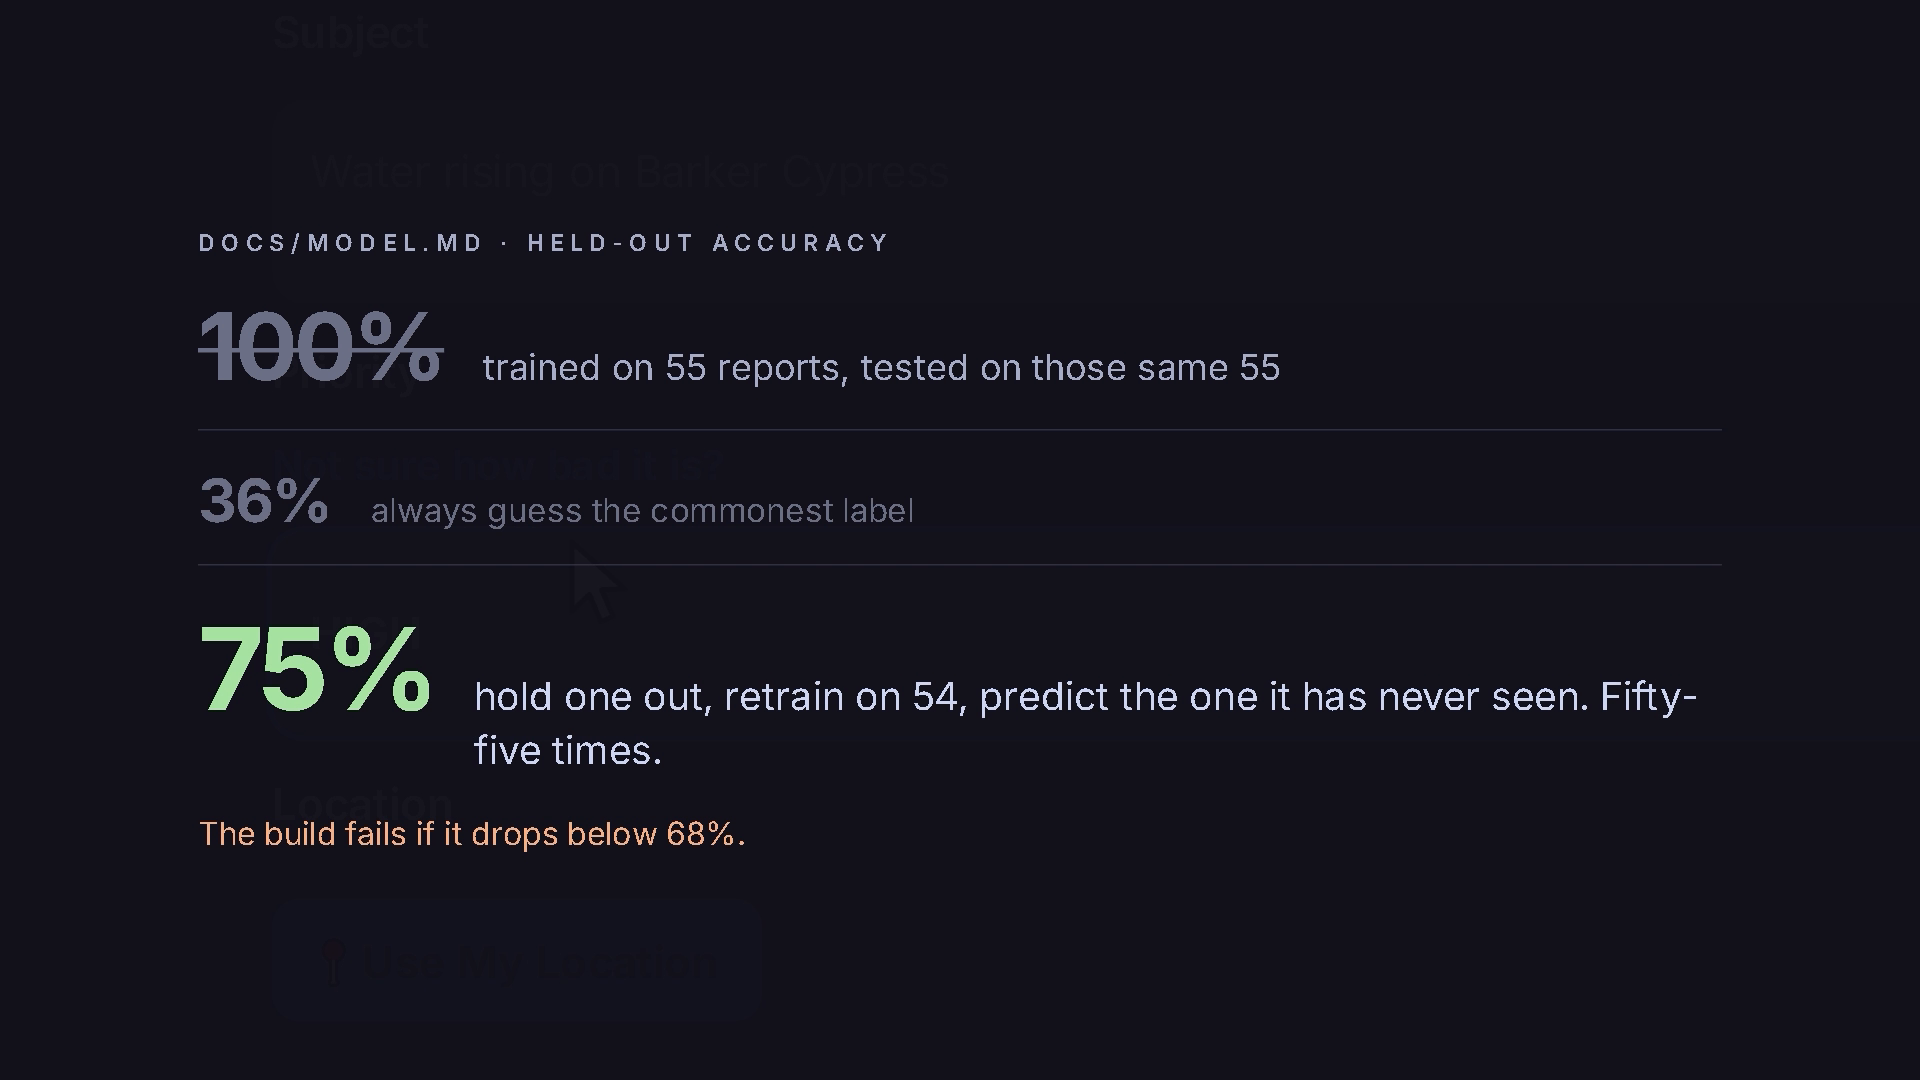
We checked it the obvious way first — run it over the corpus it was trained on. It scored 100%. That number is worthless: it had memorised its 55 examples. Measured properly, holding one report out and retraining on the other 54, fifty-five times over:
| Held out | |
|---|---|
| Always guess the commonest label | 36% |
| Naive Bayes alone | 45% |
| Naive Bayes + severity lexicon | 75% |
Nine points above guessing, and wrong in the worst possible direction — "child not breathing properly" came back MEDIUM, "gas smell, whole street evacuating" came back LOW.
The fix was a lexicon of the categories a triage protocol calls immediate, written from the START protocol rather than from our own failures, with a test asserting no phrase ever fires on a report labelled something else. That measurement runs in CI and fails the build if it regresses below 68%.
It still gets one report in four wrong. That's survivable because it lands in a dropdown you control, next to the words that caused it — and it would be unacceptable if it were deciding anything.
600 tests, 745 cases with parameters — including a WCAG 2.1 AA audit, adversarial input tests, and a suite that reads our own documentation and fails the build when the numbers in it go stale. That last one caught us mid-project: it went red because we'd added the research write-up to the repo and the README's line count silently became a lie.
We wrote the paper. Somewhere around hour forty we realised the interesting claim wasn't the app, it was the gap — so we went and read the literature to find out whether the gap was real. It mostly wasn't the way we'd assumed: convergence has been documented since 1957, and the field's answer is credentialing. But credentialing presupposes an authority who has arrived, and FEMA's own guidance answers the 2am boat owner by saying they should have affiliated months earlier. There's an eleven-page preprint on that interval, with a real bibliography, and it says plainly that DiresQ has no users, no deployment and no evaluation.
What we learned
Tests found bugs that looked like working features. Five of them. The backend was calling flash() in five places to report errors — no template rendered them, so every rejected form just sat there looking frozen. Nobody would have found that by clicking around, because the page looks fine.
The report form marked its hidden latitude and longitude fields required. Hidden inputs are exempt from browser validation — so an untouched map submitted anyway and the report saved with no coordinates, invisible on the map, forever.
A safety check that fails silently is worse than no check. Our CI greps for hardcoded secrets. The pattern needed both quote characters, and escaping that inside a YAML block scalar produced an unterminated string. The job went red having searched nothing. We rewrote it in Python and tested it against a deliberately broken file, to prove it still catches a real one.
This turned out to be the project's actual theme. The dead man's switch started life as a background timer inside the app, and we deleted it for the same reason: a timer that dies takes the alarm with it and leaves the screen showing green, and a green screen reads as a positive result rather than an absent one. The check now runs whenever anybody loads the board, and the board displays how long since it last ran.
Test on a database that already has something in it. A table added late to our schema got its CREATE and not its DROP, so rebuilding an existing database stopped halfway and left it in pieces. Every test passed, because tests build from empty and empty is the one case that works.
Measure the clever version before you keep it. We learned this twice — once on equipment detection, where five binary classifiers confidently demanded a chainsaw for a downed power line, and once on priority, hidden behind a 100% accuracy figure measured on the training data.
What's next for DiresQ
The radio. A check-in already packs into 22 signed bytes — small enough for a LoRa payload — and there's a gateway script that forwards them to the API. What's missing is hardware. That's a purchase and a weekend, not a rewrite.
Five conversations. The one thing that would move this from a plausible design to a tested one is talking to people who have run a volunteer reception centre, or turned volunteers away, or gone in unaffiliated themselves. That would tell us whether the interval we designed for is a real operational gap or an artefact of how we read the literature.
Real data. 55 training examples is a demonstration, not a dataset. Real deployment needs thousands of real reports, and real reports contain names and addresses, which is its own problem.
The things we've written down rather than hidden. There's a /limits page in the app, with eighteen of them. No identity verification — anyone can register as a responder. Location is self-reported; we detect inconsistency, not intent. The overdue timer measures contact, not safety: a dead battery flags identically to a flooded basement.
And it has never been used in a real disaster. Everything here is reasoned from published accounts of Harvey, Kathmandu and Mexico City, and from published triage protocol. We think the reasoning is sound. That is not the same as knowing it works.
Built With
- astro
- css
- flask
- html
- html5
- ics-214
- javascript
- jinja
- leaflet.js
- lora
- machine-learning
- naive-bypass
- openstreetmap
- pathcnotes
- pygeospy
- pytest
- python
- ruff
- sqlite
- start-triage
- tf-idf
- timefuzz
- vitalscore
- wcag


Log in or sign up for Devpost to join the conversation.