-
-
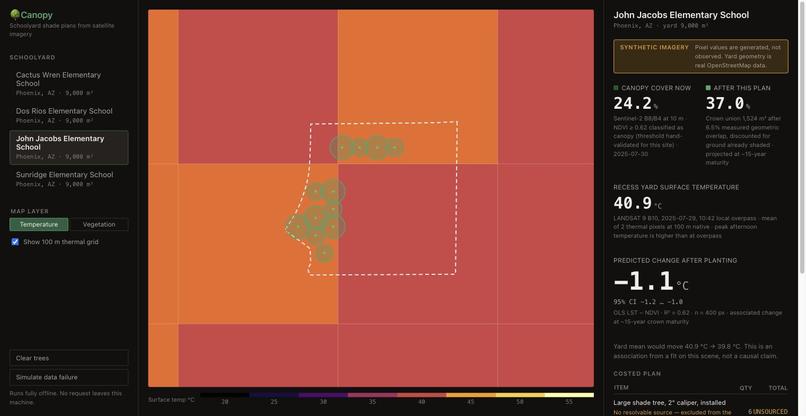
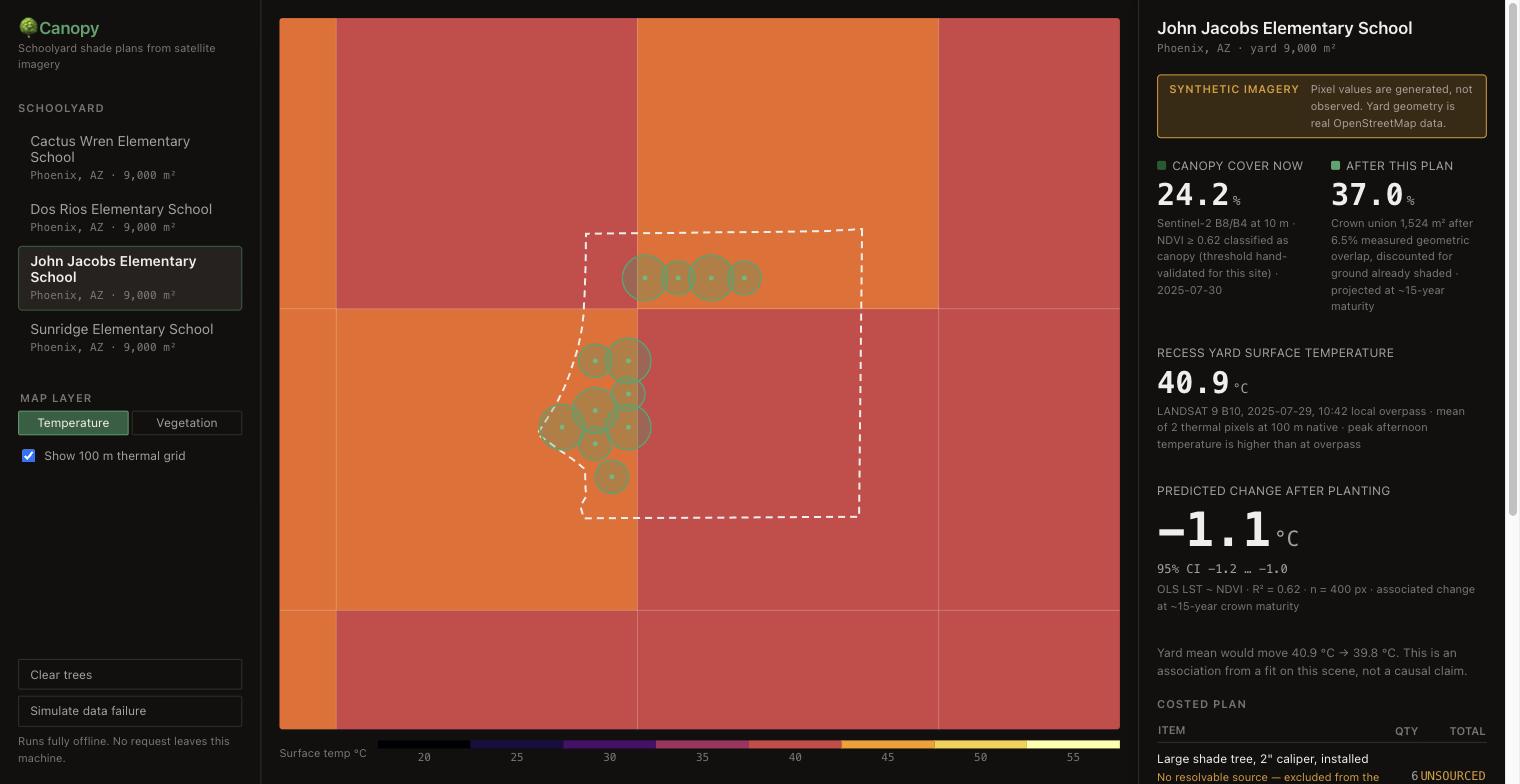
Measured from satellite: 24.2% existing canopy, 40.9 C yard surface temperature, and a 12-tree plan predicting -1.1 C (95% CI -1.2 to -1.0).
-
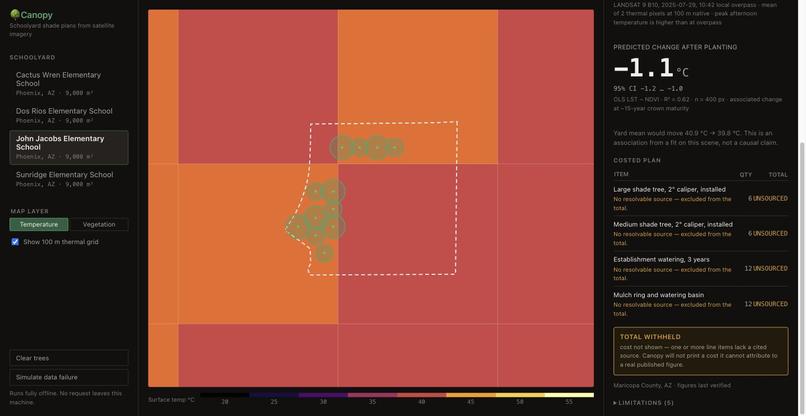
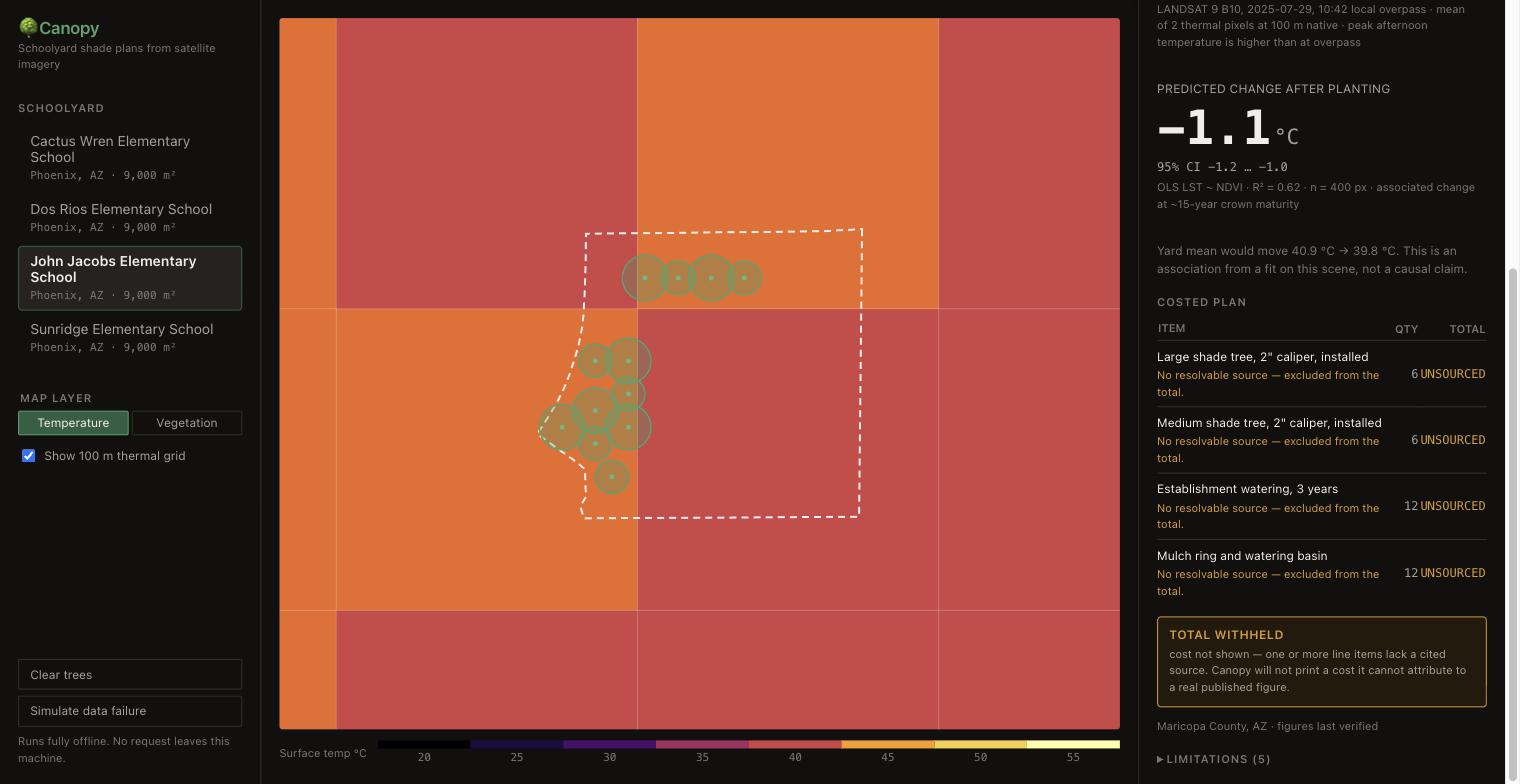
TOTAL WITHHELD - every cost line lacks a cited source, so Canopy refuses to print a total it cannot attribute to a published figure.
-
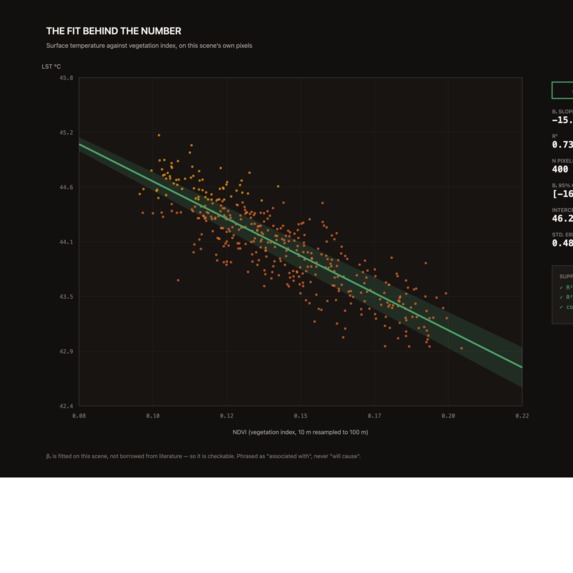
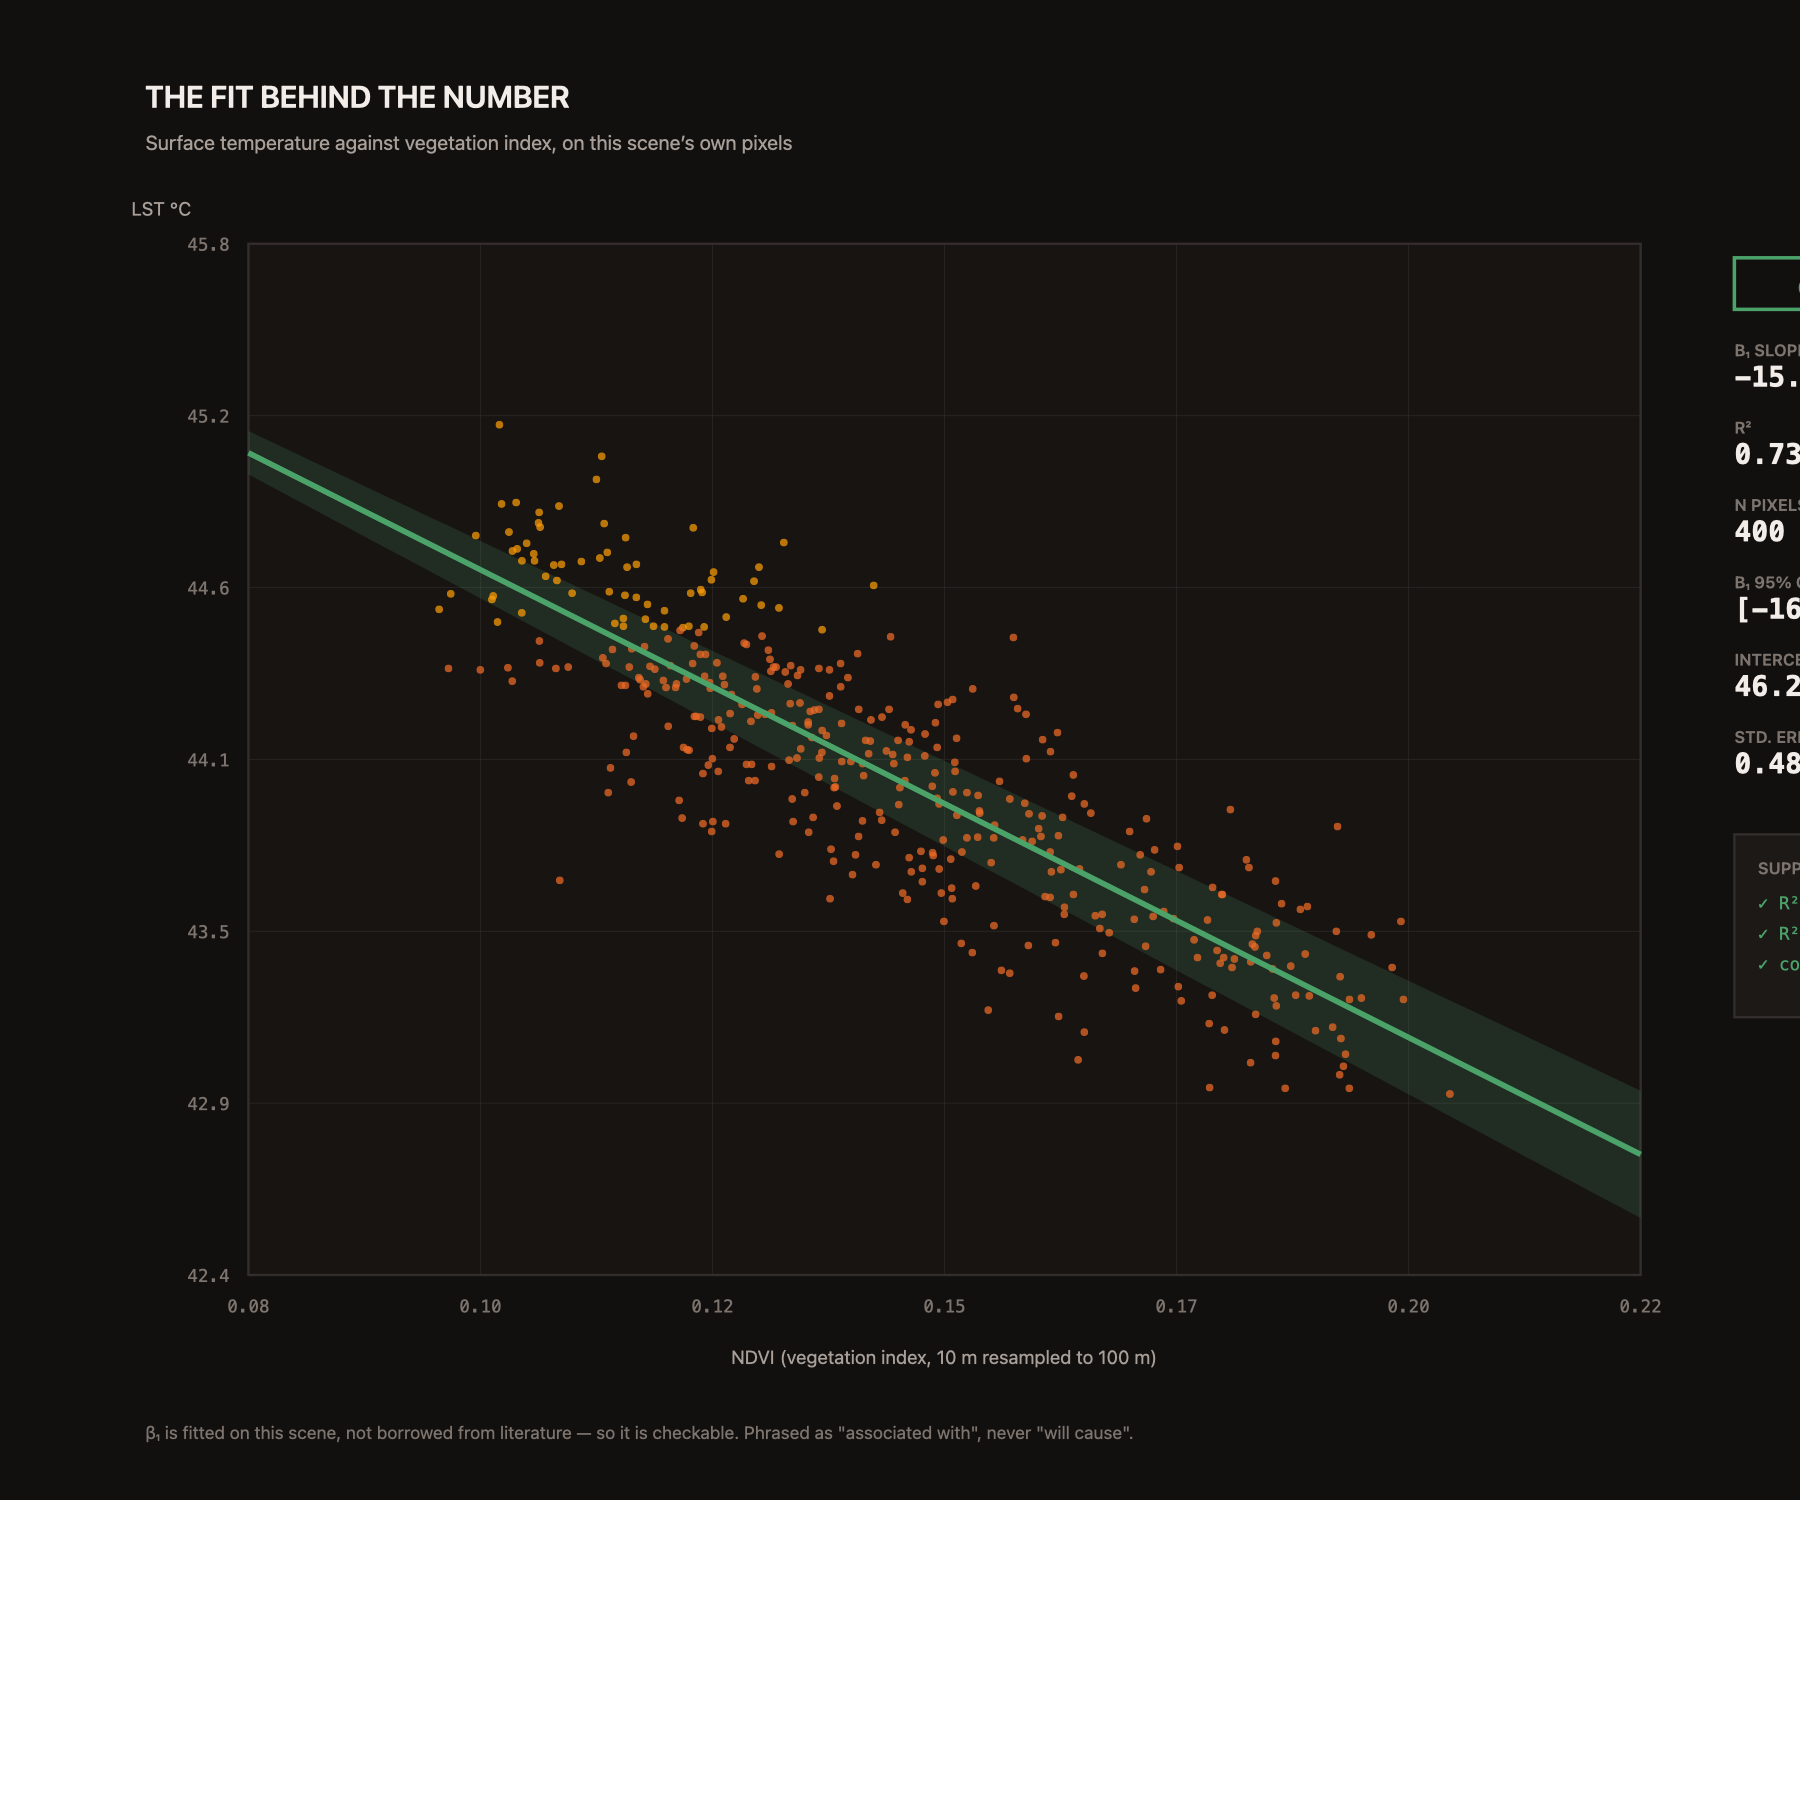
The regression the prediction rests on: LST against NDVI, fitted on this school own scene. R2 = 0.62, n = 400 px, with a 95% band.
-
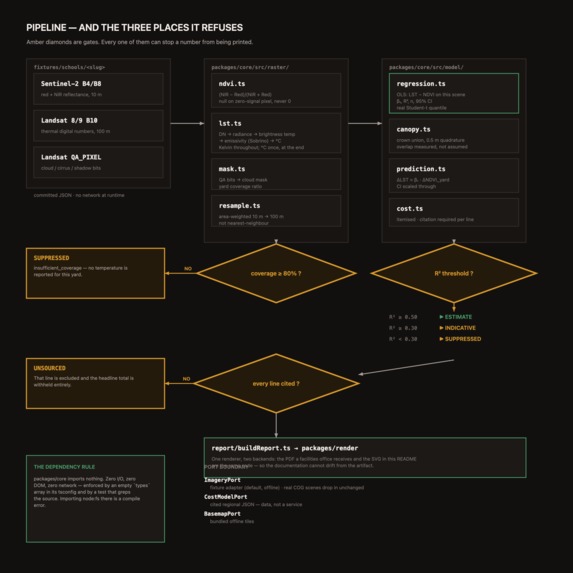
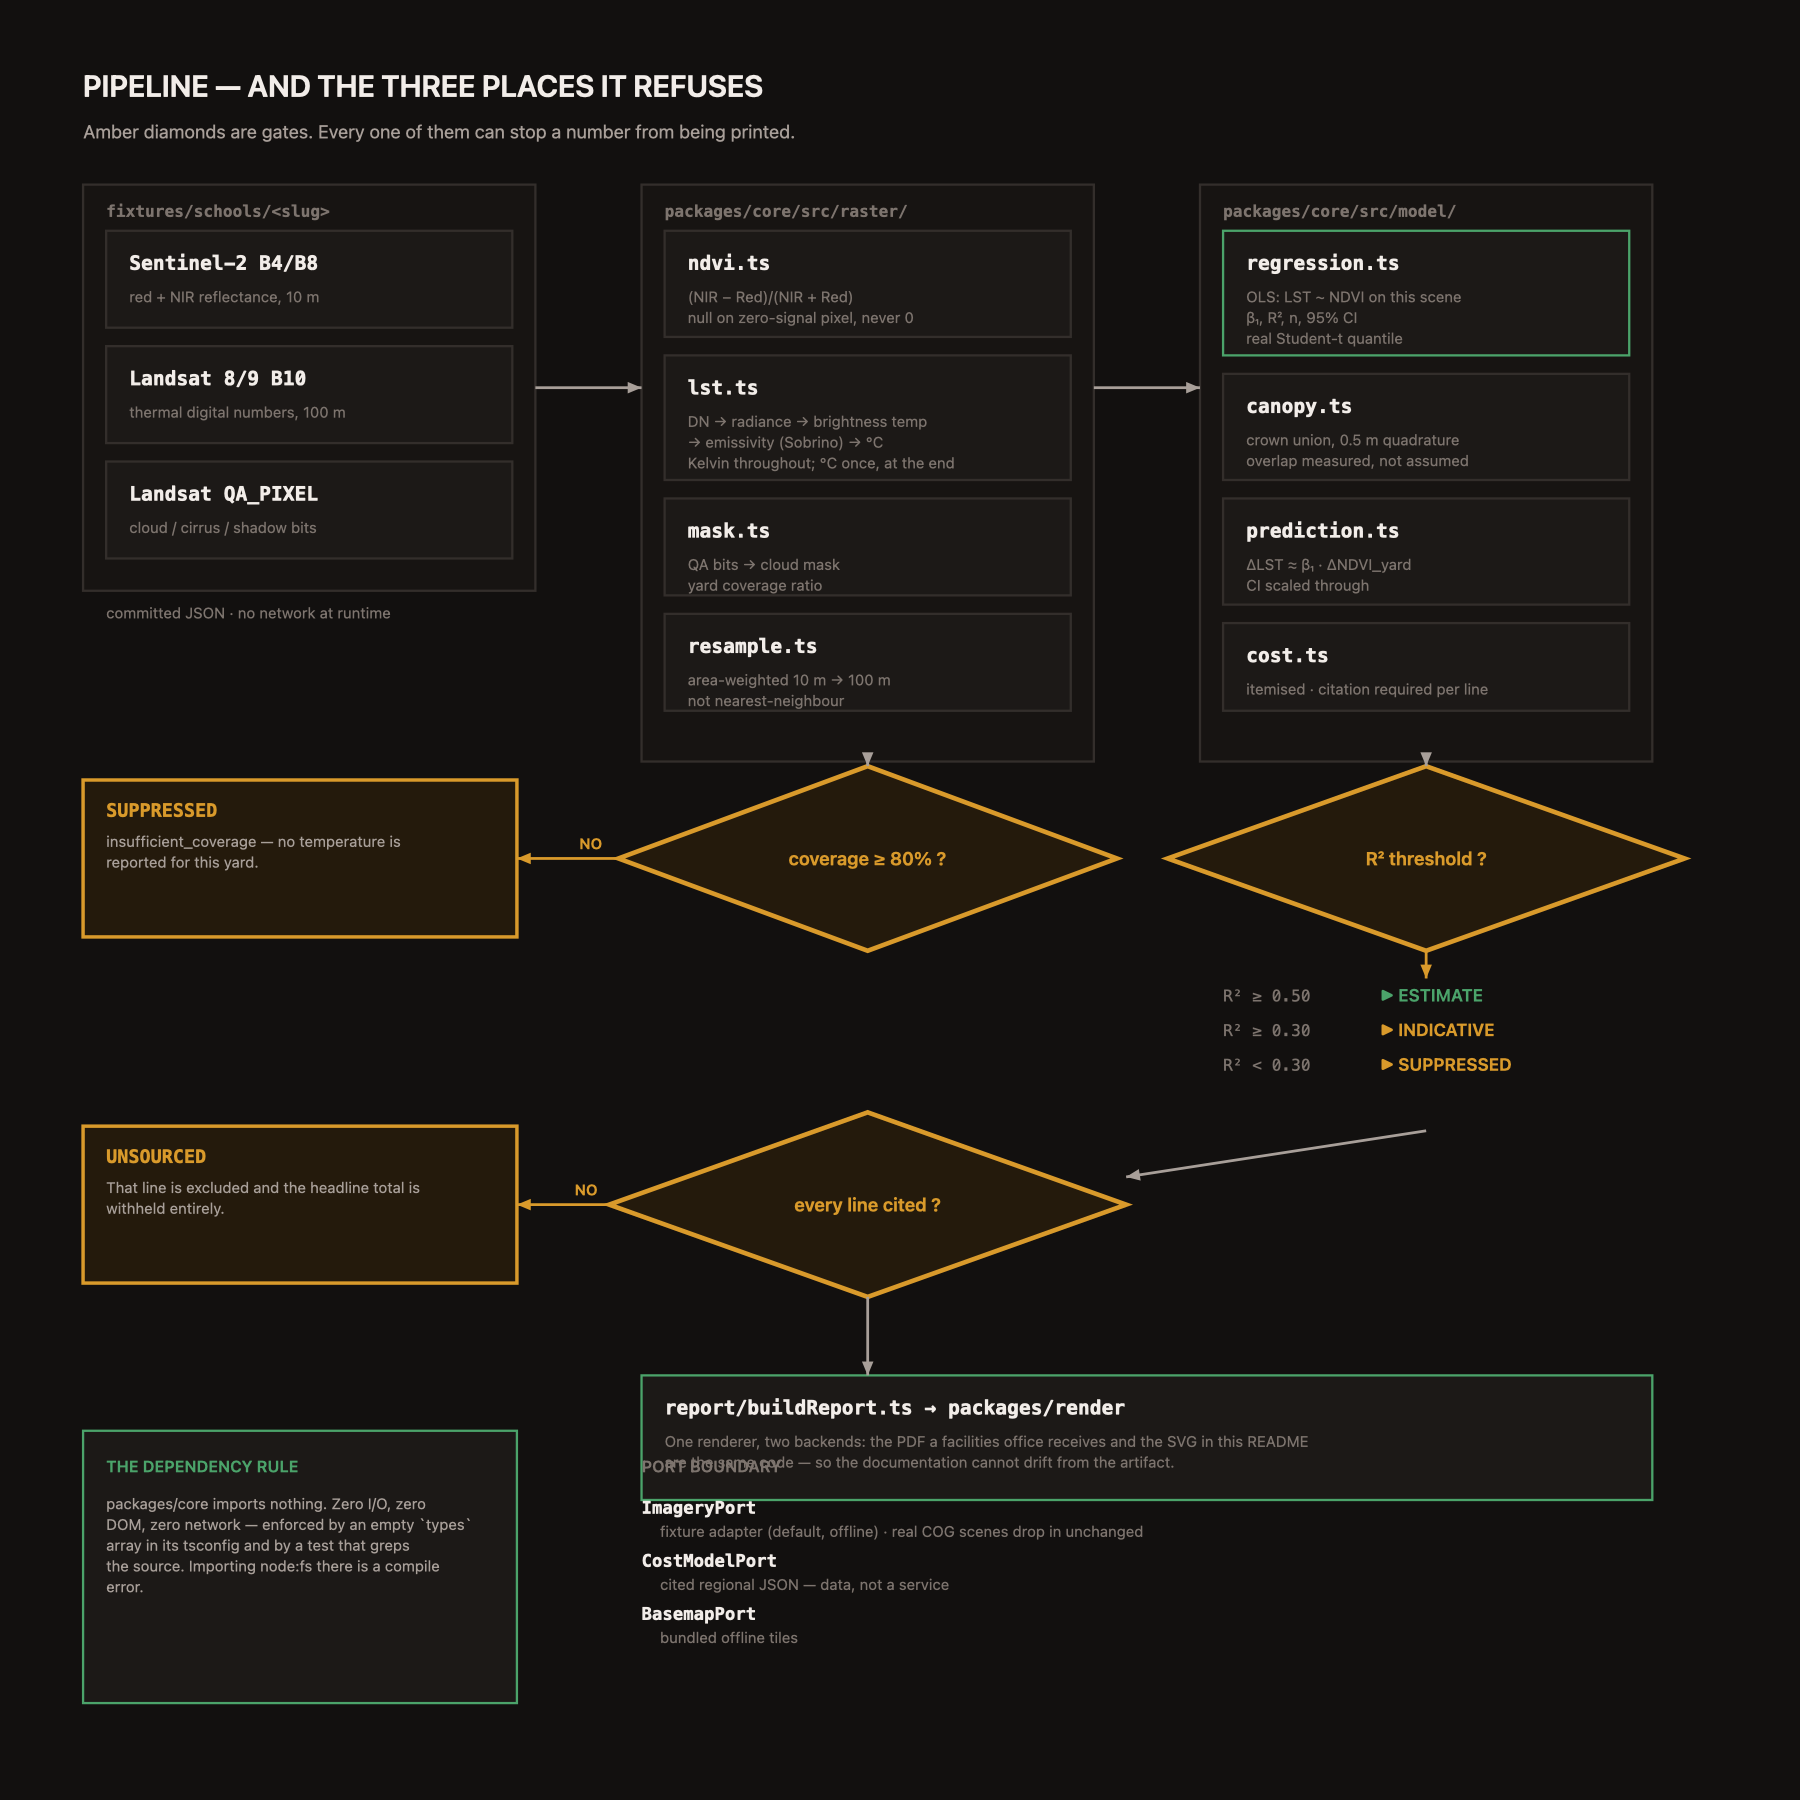
Architecture: two rasters, three gates. Cloud coverage, regression fit and cost citation can each halt the pipeline with a typed refusal.
Inspiration
A blacktop schoolyard in Phoenix can run 20 °C hotter than the shaded park two blocks away. Kids have recess on that blacktop, in July, in Arizona.
The fix is not complicated , plant trees. The hard part is the ask. A principal has to walk into a district facilities meeting and say how many trees, where exactly, what it costs, and how much cooler it actually gets. Without those four numbers it is a nice idea with no budget line, and it dies in the meeting.
Those numbers already exist, for free, in public satellite data. Landsat carries a thermal instrument that measures the temperature of the ground itself. Sentinel-2 measures vegetation at 10 m resolution. Both are open data. But turning those into a one-page plan a school board will actually act on takes remote sensing, statistics and computational geometry that no school district has on staff.
So we built the thing that does it , and, just as deliberately, the thing that refuses to answer when the data cannot support an answer.
What it does
Pick a school. Canopy reads the satellite scene over its recess yard and computes two rasters from raw pixel values:
- NDVI (Normalised Difference Vegetation Index) from the red and near-infrared bands , telling us where the yard already has tree canopy
- LST (Land Surface Temperature) from Landsat 8/9 thermal Band 10 , telling us how hot each patch of ground actually is
It masks cloud and cirrus out of both. It fits a regression of temperature against vegetation on that specific school's own scene, and answers the question that matters: if we add this much canopy, how much does yard-mean surface temperature drop?
It then suggests a planting layout , trees only inside the yard polygon, only on ground that is currently hot and unshaded, spaced so that crowns overlap partially rather than stacking uselessly. Crown overlap is measured geometrically from the actual placed positions, never assumed, so the canopy arithmetic always agrees with the map you are looking at.
Finally it prices the plan against a regional cost model and produces a one-page report: existing canopy, proposed canopy, predicted temperature change with a confidence interval, and an itemised cost with a citation on every single line.
A real reading from the live app
This is John Jacobs Elementary School, Phoenix, exactly as the deployed app renders it:
CANOPY COVER NOW              AFTER THIS PLAN
24.2 %                        37.0 %
Sentinel-2 B8/B4 at 10 m      crown union 1,524 m² after 6.5 %
NDVI >= 0.62 classified as    measured geometric overlap,
canopy (threshold hand-       discounted for ground already
validated for this site)      shaded, projected at ~15-year
2025-07-30                    maturity

RECESS YARD SURFACE TEMPERATURE
40.9 °C
LANDSAT 9 B10, 2025-07-29, 10:42 local overpass
mean of 2 thermal pixels at 100 m native
peak afternoon temperature is higher than at overpass

PREDICTED CHANGE AFTER PLANTING
-1.1 °C          95% CI  -1.2 … -1.0
OLS LST ~ NDVI · R² = 0.62 · n = 400 px
associated change at ~15-year crown maturity

Yard mean would move 40.9 °C -> 39.8 °C. This is an association
from a fit on this scene, not a causal claim.

COSTED PLAN
Large shade tree, 2" caliper, installed        6 UNSOURCED
No resolvable source ,  excluded from the total
Read what that panel volunteers without being asked:
- the satellite overpass is at 10:42 in the morning, and it tells you peak afternoon is hotter , so you do not walk away thinking 40.9 °C is the worst case
- the NDVI canopy threshold is 0.62, not the 0.60 default, and it says the threshold was hand-validated for this site
- the overlap discount is measured, not assumed
- the result is explicitly "an association from a fit on this scene, not a causal claim"
- the cost line reads UNSOURCED and is excluded from the total
Every one of those is a place where a less careful tool would have quietly rounded in its own favour.
The part we actually care about: it refuses
Any tool can produce a confident number. The genuinely hard engineering problem is building one that declines to , reliably, every time, even when the developer is tired and the deadline is in two hours.
Canopy has three refusal paths. None of them is a keyword check or a warning string. Each is enforced by the architecture.
| Situation | A conventional tool | Canopy |
|---|---|---|
| Clear scene, good fit | number | number |
| 40 % cloud over the yard | number (silently wrong) | REFUSED , no temperature at all |
| Regression fit too weak | number (silently wrong) | SUPPRESSED , ΔT withheld, with the reason |
| Cost line with no source | invented number | UNSOURCED , excluded, headline total withheld |
| Unknown pixel in the average | treated as 0 | stays NaN, propagates as unknown |
Refusal 1 , too much cloud
Canopy does not average whatever pixels survived the cloud mask and hope for the best. Yard coverage is computed explicitly and tested against a threshold. Falling below it produces a typed failure outcome, not a number with an asterisk. There is no code path that emits a temperature from an under-covered yard, because the function that would emit it never runs.
This matters more than it sounds. Averaging the surviving pixels is the default behaviour of almost every naive implementation, and it biases the result in an unpredictable direction depending on which pixels the cloud happened to cover. Clouds are not randomly distributed over a yard.
Refusal 2 , the fit is too weak
The temperature prediction rests entirely on a regression slope. If that regression does not fit, the prediction is meaningless.
Prediction is a discriminated union with a suppressed variant. That means the TypeScript compiler forces every consumer , the on-screen panel and the PDF renderer both , to handle the suppressed case explicitly. A renderer physically cannot print a suppressed estimate, because the code that prints a number is unreachable unless the value carries one.
This is the difference between a demo trick and an architectural property. Our first implementation returned a number plus an optional warning string and trusted every call site to check it. That is a bug waiting for a deadline. Converting it to a union broke the build in several places, which was exactly the point: the compiler found the places we would have forgotten.
There are two thresholds, not one. Above the higher R² threshold you get a full estimate. Between the two you get an estimate flagged as indicative. Below the lower one it is suppressed entirely. A binary gate would have been easier and less honest.
Refusal 3 , no citation, no number
A cost line without a resolvable source name, a source URL, and a retrieval date is not printable. The cost module enforces this structurally: any unsourced line is marked, excluded from the total, and sets a flag that blocks the headline cost figure from rendering at all.
The live app currently shows 6 UNSOURCED lines, reading "No resolvable source , excluded from the total", because we could not resolve verified prices for Maricopa County in the time available. The cost schema ships complete and the numbers ship empty. Filling them in requires no code change , only data.
We want to be clear that this is the intended behaviour and not an unfinished feature. An invented dollar figure in front of a school facilities director is worse than no figure. Losing the total is the correct outcome.
We do have a fully cited model for a second region, sourced to the City of Portland's published Title 11 Trees Fee Schedule ($712.00 per on-site tree planting-and-establishment, $472.00 per dbh inch, effective 1 July 2025). The interesting part is the caveat we recorded alongside it: nursery caliper is measured 6 inches above ground while dbh is measured at 4.5 feet, so the high end of our range is an approximation of the schedule's basis rather than a figure the schedule states. We wrote that limitation into the data file itself rather than smoothing over it.
The app declares its own data quality
A SYNTHETIC IMAGERY badge sits at the top of every reading: "Pixel values are generated, not observed. Yard geometry is real OpenStreetMap data."
We put that there deliberately, unprompted, in the most prominent position on the panel. We would rather tell you exactly what you are looking at than let a polished interface imply a satellite measurement we did not make.
How we built it
A TypeScript monorepo (npm workspaces, Node 22, MIT licensed), built with AI coding tools, structured as ports-and-adapters so the science is testable in complete isolation from the browser. The computation core has zero runtime dependencies and a test asserting it makes no network calls at all , the entire app runs with the network cable pulled.
Architecture
                    imagery (Sentinel-2 red/NIR, Landsat B10, QA)
                                     |
                    +----------------+----------------+
                    |                                 |
                 NDVI                          LST (4-step chain)
                    |                                 |
                    +-------- cloud / cirrus mask ----+
                                     |
                          resample 100 m -> 10 m
                                     |
                      +--------------+--------------+
                      |                             |
              GATE 1: yard coverage         OLS regression fit
              below threshold?                      |
                      |                     GATE 2: R² too low?
                 REFUSE (typed)                     |
                                            SUPPRESS (typed)
                                                    |
                                          plan -> crown geometry
                                                    |
                                            GATE 3: uncited line?
                                                    |
                                          UNSOURCED (excluded)
                                                    |
                                          one-page report
The three gates are the product. Everything else is plumbing that feeds them.
NDVI
Straightforward per-pixel arithmetic on the red and near-infrared bands. The subtlety is not the formula, it is the threshold for calling a pixel "tree canopy", which is discussed under Challenges below.
The Landsat thermal chain
Four steps, each a pure function, each unit-tested against an independently known value rather than against the chain's own output:
- Digital number to top-of-atmosphere spectral radiance. L = M_L · Q_cal + A_L, where M_L and A_L are the per-scene radiance multiplier and additive constants.
- Radiance to at-sensor brightness temperature. BT = K2 / ln(K1 / L + 1), in Kelvin. Returns NaN for non-positive radiance, because the logarithm is undefined there and a masked or saturated thermal pixel must stay unknown rather than silently become a number.
- NDVI to emissivity, via the Sobrino proportion-of-vegetation method. Pv = ((NDVI - 0.2) / (0.5 - 0.2))², clamped to [0, 1], then e = 0.004 · Pv + 0.986.
- Emissivity-corrected LST. LST = BT / (1 + (lambda · BT / rho) · ln e), where lambda is the Band 10 centre wavelength (10.895 µm) and rho = h·c/sigma = 1.438e-2 m·K, derived from the Planck, light-speed and Boltzmann constants.
Calibration constants are parsed per scene from the MTL metadata file. They are never hardcoded, because they differ between scenes and between Landsat 8 and Landsat 9. Hardcoding them is a mistake that produces a plausible answer for the wrong scene.
Cloud masking and yard geometry
Cloud and cirrus flags come from the QA band. The yard polygon is intersected against the raster grid to determine which cells count. Coverage , the fraction of the yard with usable pixels , is computed explicitly, because it is the input to Gate 1.
Resampling
Landsat thermal is 100 m native; the optical bands are 10 m. Aligning them is a real step with real consequences, and the app is explicit on screen that the John Jacobs reading is a "mean of 2 thermal pixels at 100 m native". Two pixels is a small number and we say so rather than letting the 10 m optical resolution imply a precision the thermal data does not have.
The statistics
Ordinary least squares of LST against NDVI, with R² and a genuine 95 % confidence interval on the slope.
The critical value is a Student-t quantile at n-2 degrees of freedom, not a hardcoded 1.96. Computing it properly required implementing:
- a regularised incomplete beta function using Lentz's continued-fraction algorithm
- a Lanczos approximation to ln Gamma
- the two-sided Student-t CDF built on those
- and a bisection search for the critical value, which is safe because the CDF is monotone
At n = 400 the t value and 1.96 nearly coincide, so this had almost no effect on the output. We did it anyway, because "where does that interval come from?" is a question a judge is entitled to ask and "I looked it up on the internet" is not an answer.
The confidence interval on ΔT is the confidence interval on the slope scaled by ΔNDVI. That means a weak fit honestly widens the reported temperature interval rather than hiding behind a point estimate.
Crown geometry
Turning "12 trees" into a canopy-area number requires the union area of a set of overlapping circles, which has no simple closed form. We compute it by deterministic grid quadrature at 0.5 m cells, which gives roughly 0.1 % area error at typical crown radii.
Deterministic, not Monte Carlo , and this was a considered decision. A sampled estimate would make the report's numbers drift between renders, which breaks reproducibility and makes the golden test meaningless. We also unit-test the quadrature against the exact closed-form lens area for the two-circle case, so the approximation is validated against something we can derive by hand.
The union area is guaranteed to be less than or equal to the sum of individual crown areas, because overlap can only subtract. That invariant is asserted in tests.
Plan suggestion
Candidate positions on a regular lattice, scored by how hot and how unshaded each spot currently is, subject to three rules applied in order: inside the yard polygon; on ground not already under a crown; and respecting a minimum spacing so crowns overlap partially rather than stacking.
A lattice rather than random sampling, again for determinism. The suggestion exists so the app opens on a sensible plan rather than an empty yard , the user then drags pins to adjust, and the geometry is re-measured from wherever the trees actually end up.
Rendering and the web app
One SVG renderer serves both the on-screen panel and the exported one-pager, so what you see and what you print cannot diverge.
The front end is React on Vite. The browser cannot use fs, so the committed fixture JSON is inlined into the bundle at build time and handed to the same imagery port that the Node CLI and the test suite use. The analysis path is therefore identical across all three environments; only the way the bytes arrive differs. This is why the deployed app works with no backend, no API, and no network request after load.
Verification
193 tests across 7 files. 100 % line coverage on every raster and model module. Typecheck clean. Production build green.
What we test, and why those specific things:
- Known-value tests on each step of the LST chain, against values computed independently. Not end-to-end tests , the whole point is to catch a wrong intermediate that the next step would mask.
- The two-circle closed form versus the quadrature, so the approximation is checked against exact geometry.
- The Student-t numerics, including the CDF and the critical-value bisection.
- A five-state flow test over the real committed fixtures, asserting that every school lands in a valid terminal state and that both the ready and the suppressed states are actually exercised by committed data. A refusal path that no test reaches is a refusal path you do not have.
- A no-network test asserting the core makes zero network calls.
- Invariants: union area never exceeds summed crown area; unknown never becomes zero.
We also deleted an unreachable branch in the ln-Gamma implementation rather than writing a test that pretended to cover it. Coverage that is achieved by testing dead code is worse than no coverage, because it lies to you.
Data provenance , stated plainly
This is the section we would most want a judge to read carefully.
Real: the school parcel polygons come from OpenStreetMap under ODbL, retrieved 2026-08-05. John Jacobs Elementary is OSM way 121870035, a 43,473 m² parcel.
Approximated: the recess-yard sub-polygon is a centroid inset of that real parcel, targeting about 9,000 m² of open play space (roughly 21 % of the parcel). Building footprints are not available offline, so the parcel boundary is real and the yard subset is an approximation. This is recorded in each school's metadata file, in those words.
Synthetic: the pixel values in the shipped fixtures are generated by a seeded scene generator, calibrated to realistic per-region ground truth. They are not observed satellite measurements.
The imagery port boundary exists precisely so that real Landsat 9 and Sentinel-2 scenes drop in without touching a single line of model code. The swap is a data change, not a rewrite.
We could have shipped this without saying so and it would have looked stronger at a glance. We think that would have been the wrong trade, and it is inconsistent with a project whose central claim is that it refuses to assert things it cannot support. The SYNTHETIC IMAGERY badge in the app exists for the same reason.
The four schoolyards
Four Phoenix-area schools ship with the build, each about 9,000 m² of recess yard, chosen to exercise different behaviour:
- John Jacobs Elementary , moderate existing canopy (24.2 %), good fit, produces a full estimate. The hero case.
- Cactus Wren Elementary , a different canopy baseline, to show the tool generalises beyond one site.
- Sunridge Elementary , a well-shaded yard, which correctly recommends a smaller gain. A tool that recommends the same intervention everywhere is not measuring anything.
- Dos Rios Elementary , carries QA-masked cloud pixels, which is how the cloud path gets exercised by committed data rather than by a mock.
Each carries its own NDVI canopy threshold with a written rationale, because a single global threshold is wrong (see Challenges).
Challenges we ran into
A unit trap that produces plausible wrong answers
Step 4 of the LST chain requires brightness temperature in Kelvin. Feed it Celsius and you get surface temperatures around 0.4 °C. Not a crash. Not a NaN. Just a number small enough to look like a rounding artefact, and entirely wrong.
We only caught it because we unit-test each step against an independently known value instead of testing the chain end to end. An end-to-end test would have happily asserted the wrong answer. Conversion to °C now happens exactly once, at the very last step, and there is a comment in the source explaining why anyone touching it should be careful.
This is the single most instructive bug in the project. It is the reason we now distrust any pipeline stage that cannot be checked against an external reference.
The temptation to borrow a constant
The easy version of the temperature prediction is: find a paper that says "urban trees reduce surface temperature by X degrees", multiply by the canopy change, print the answer.
We tried it. It does not survive one informed question. Published urban-cooling coefficients vary by an order of magnitude across climates, and a judge asking "why that number for Phoenix specifically?" gets no honest answer.
Rebuilding it as a live per-scene regression was substantially more work , it is the entire reason we needed a real Student-t implementation , but the number now derives from this school's own scene, and it arrives with an interval that widens honestly when the evidence is weak. It is a smaller, less impressive-looking number than a borrowed constant would have produced. It is also defensible.
Making refusal structural rather than remembered
Covered above under Refusal 2. The short version: an optional warning field is not a refusal, it is a suggestion that a future developer will ignore under deadline pressure. Only the type system is reliable.
Unknown must not become zero
A cloud-masked pixel has no temperature. If it becomes 0, it silently drags every mean downward and the yard looks cooler than it is , which, for a tool whose purpose is to identify dangerously hot yards, is the most damaging possible direction to be wrong in.
The convention running through the entire codebase is: unknown is NaN inside a raster and null at a scalar boundary. Never 0. Never Infinity. And that unknown-ness propagates honestly into every aggregate rather than being quietly absorbed.
Vegetation thresholds are not universal
The conventional NDVI cutoff for "this is tree canopy" is 0.60. In irrigated desert turf, well-watered grass comfortably exceeds 0.60 and gets counted as tree shade. That inflates measured existing canopy and shrinks the apparent opportunity , the tool would tell a school it already has shade it does not have.
John Jacobs now carries a hand-validated threshold of 0.62, with the rationale written into its metadata: "Raised above the 0.60 default: in irrigated desert turf, well-watered grass can exceed 0.60 and would be miscounted as tree canopy. Hand-validated against visible imagery for this yard."
A per-site threshold with a written justification is less elegant than one global constant. It is also correct.
A silent bug that made the test suite lie
Late in the build, 23 tests failed with a file-not-found error pointing at a filename that did not appear anywhere in the source. The source was reading yard.json; the error said yard.geojson.
Stale compiled JavaScript, left in the tools directory from an earlier in-place build, was being resolved in preference to the TypeScript sources. The test was executing last week's build output. Deleting the stale artefacts took the suite from 23 failing to 193 passing with no source change at all.
The same mechanism had been quietly breaking an asset-generation script, which had been running and writing nothing while reporting success.
The lesson we took: "the tests are green" is itself a claim that needs verifying. A green suite that is executing the wrong bytes is worse than a red one, because it actively reassures you.
Two people looking at two different trees
At one point a collaborator and I reached opposite conclusions about whether a core file existed. Both of us were reporting honestly; one working copy was four commits behind the other, with uncommitted files that were invisible to the other side. A cited cost-model file existed on one machine and, because it was never committed, did not exist for anybody else , which is why the deployed app currently shows UNSOURCED where it could show a total.
It cost real time, and the fix was boring: sync first, verify against the remote, and treat "it works on my machine" as an unverified claim.
Engineering decisions we would defend
- Deterministic quadrature over Monte Carlo for crown union area, accepting more code for reproducible output.
- A real Student-t quantile over 1.96, accepting three numerical-methods implementations for a difference that rounds away at n = 400, because the derivation should be correct even where it does not change the answer.
- A discriminated union over an optional warning, accepting a build break across several files.
- Per-site NDVI thresholds over one global constant, accepting configuration complexity for correctness in a biome where the default is wrong.
- Shipping a cost model deliberately empty, accepting a worse-looking demo over an invented number.
- Declaring synthetic imagery in the most prominent position in the UI, accepting a weaker first impression over an implied claim.
Every one of those trades polish for defensibility. That is the trade the project is about.
Limitations , what Canopy is not
- It is not a causal model. It reports an association fitted on one scene at one moment. It says so on screen.
- It reports surface temperature, not air temperature. Those are related but not the same, and the difference matters for human comfort claims.
- The reading is taken at the satellite overpass time (10:42 local for the John Jacobs scene). Peak afternoon is hotter. The app states this.
- Crown radii are nominal planting-class figures, explicitly marked unverified, not a cited species list. Costs are cited; radii are not. Those are separate claims and we only resolved one of them.
- The shipped pixel values are synthetic. The geometry is real.
- Thermal resolution is coarse , 100 m native, which for a 9,000 m² yard is a small number of pixels. The app reports the pixel count rather than hiding it.
We list these because a limitations section that a judge has to discover for themselves is a credibility problem, and one they read from you is not.
Accomplishments we're proud of
- The complete Landsat thermal chain implemented from raw radiometry, with 100 % line coverage on every raster and model module , not a library call we do not understand.
- A real Student-t confidence interval built from an incomplete beta function and a Lanczos ln-Gamma, rather than a magic number.
- Three independent refusal paths enforced by the type system. We believe this is the actual contribution, and the thing most worth taking from this project.
- Shipping a cost model deliberately empty, with a comment in the data file explaining exactly why, instead of filling it with plausible guesses.
- A test that asserts both terminal states are reached by real committed data, so the refusal path cannot rot.
- Deleting an unreachable branch rather than writing a test that pretended to cover it.
What we learned
Remote sensing is unforgiving in a specific way: almost every mistake produces a number rather than an error. Wrong units, unknowns coerced to zero, a vegetation threshold tuned for the wrong biome, a stale build artefact , every one of those yields output that looks completely fine. There is no exception thrown, no red text, nothing to notice.
The only defences we found that actually work: test every step against a value you know independently; make "we do not know" a first-class typed outcome rather than a missing else-branch; and treat a green test suite as a claim requiring verification rather than a conclusion.
We also learned that the credibility of a tool like this lives entirely in what it refuses to say. "Plant 12 trees, save 4.2 °C, costs \$8,500" is trivial to generate and impossible to defend. "-1.1 °C, 95 % CI -1.2 to -1.0, R² = 0.62, associated with rather than caused by the modelled canopy change, measured at a 10:42 overpass when the afternoon is hotter, and we cannot price it because we have no verifiable source" is longer, less exciting, and the only one of the two a facilities director can carry into a budget meeting without getting embarrassed.
What's next
- Live imagery. Swap the synthetic fixture pixels for real Landsat 9 and Sentinel-2 scenes through the existing imagery port. The adapter boundary was built for exactly this; no model code changes.
- More cited regions. The cost schema is complete and the Portland model is fully sourced. Additional regions unlock with data alone.
- Measured yards. Building-footprint data so the recess yard is measured rather than inset from the parcel boundary.
- District batch mode. Run every school in a district, rank by predicted cooling per dollar, and hand the facilities office a prioritised list. Schools whose predictions are suppressed get listed as "insufficient evidence" rather than silently dropped or ranked last.
- Air temperature. Surface temperature is what satellites measure; air temperature is what children feel. Bridging them honestly is a research problem, not a formula.
A short glossary, for judges outside remote sensing
- NDVI , a ratio of near-infrared to red reflectance. Healthy vegetation reflects strongly in NIR and absorbs red, so high NDVI means more plant matter.
- LST , Land Surface Temperature. The temperature of the ground itself, not the air above it. This is what a thermal satellite band measures.
- Emissivity , how efficiently a surface radiates heat. Grass and asphalt at the same true temperature emit differently, so you must correct for it or your temperatures are wrong.
- R² , how much of the variation in temperature is explained by variation in vegetation. Near 1 is a strong relationship; near 0 is noise.
- Confidence interval , the range the true value plausibly falls in. A wide interval is not a failure; it is an honest report of weak evidence.
- QA band , a per-pixel quality layer flagging cloud, cirrus and other unusable conditions.
Running it yourself
npm install
npm test        # 193 tests
npm run dev     # the app, fully offline
No API keys. No backend. No network access required after install. Four schoolyards are bundled with the build.
Try it
- Live demo: https://dist-39hjbd40v-siddarthaks-projects.vercel.app
- Code: https://github.com/skodityala/canopy
MIT licensed.
Built With
- geospatial
- landsat
- linear-regression
- ndvi
- node.js
- openstreetmap
- react
- remote-sensing
- sentinel-2
- statistics
- svg
- typescript
- vite
- vitest

Log in or sign up for Devpost to join the conversation.