-
-
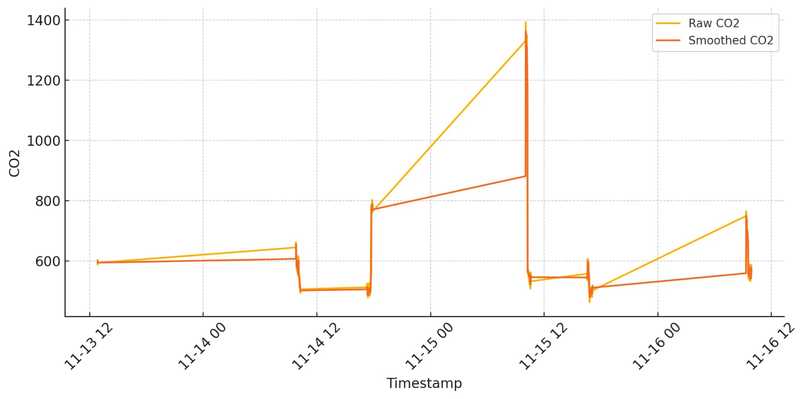
co2 graphs of three trees
-
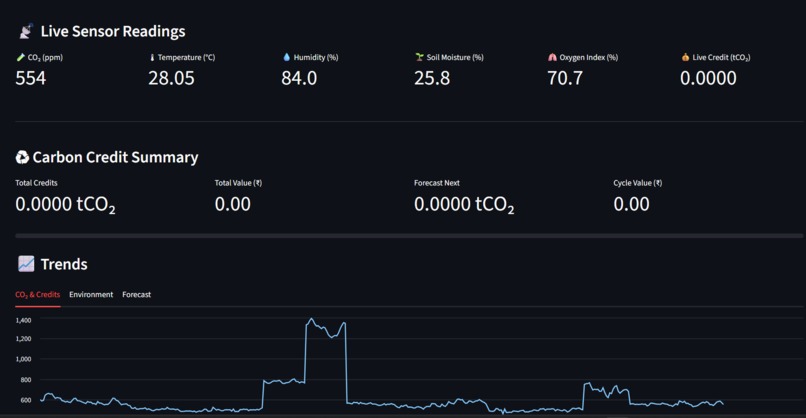
dashboard
-
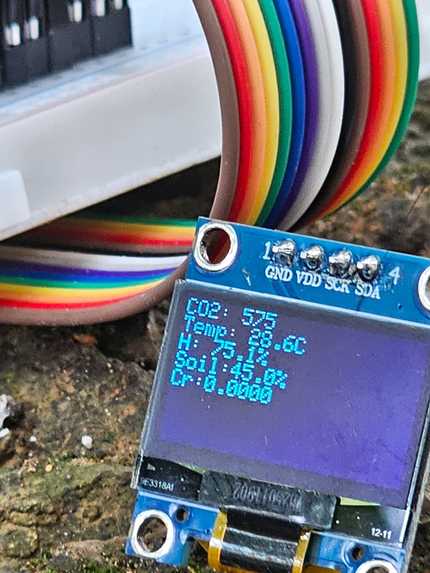
iot sensor
-
t3
-
t1
-
t2
-
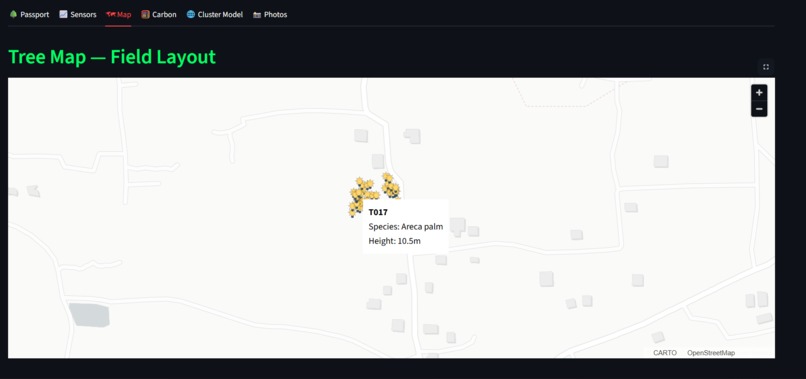
map view
-
gridbcloud


Aetherra is a climate MRV system that enables continuous, audit-ready carbon verification using real-world sensor time-series data. Current carbon MRV processes rely heavily on manual surveys, assumptions, and infrequent audits, making verification slow, non-transparent, and inaccessible to small farmers and grassroots projects.
Aetherra solves this by collecting tree-level environmental data (CO, proxies, soil moisture, temperature, humidity) through low-cost sensors, storing it in GridDB time-series containers, and visualizing it through live dashboards. This allows environmental impact to be measured continuously, reported digitally, and verified transparently.
The project demonstrates how GridDB is well-suited for climate-critical time-series workloads, where precision, reliability, and long-term data integrity are essential. Aetherra lays the foundation for scalable MRV infrastructure that can support carbon registries, agroforestry programs, and future climate finance systems. Inspiration
Carbon credit verification (MRV — Measurement, Reporting & Verification) is extremely broken. Today:
Verification is slow
Data is manual
Reporting is non-standardized
Small farmers cannot access carbon revenue
We asked: “What if MRV could be continuous, automated, and backed by real-time environmental data?”
Aetherra was born from that question — an IoT-powered MRV system that stores climate signals into GridDB, enabling transparent, timestamped evidence for carbon credits.
What Aetherra Does
Aetherra is a real-time MRV data pipeline designed for carbon credit projects and agroforestry systems.
Our system:
Collects real sensor-like climate data:
Temperature
Humidity
CO₂ ppm
Soil moisture
Pressure
Tree/plot identifiers
Accurate timestamps
Stores all records in GridDB Community Edition, using:
Time-series containers
High-frequency inserts
SQL WebAPI
Fast queries for dashboards
Generates MRV-ready time-series logs:
For issuing carbon credits
For verifying field conditions
For auditors & registries
For digital carbon passport creation
Everything is done continuously, not manually — making MRV affordable and scalable.
How We Built It Sensor Simulator (IoT Node)
A Python script simulates a real MRV sensor device sending data packets such as:
{ "tree_id": "T001", "temperature": 28.5, "humidity": 75.9, "pressure": 1012, "soil": 435, "co2": 412 }
This imitates real-world agroforestry sensor hardware.
MRV Backend (Flask)
Our backend acts as an ingestion API:
Receives sensor streams
Adds timestamps
Forwards records to GridDB
Provides APIs for dashboards:
/upload
/query
/latest
GridDB Community Edition (Time-Series DB)
We use GridDB because:
It’s optimized for high-frequency IoT data
It supports time-series containers natively
It scales for years of MRV logs
It provides SQL over REST for simple integration
We created a container:
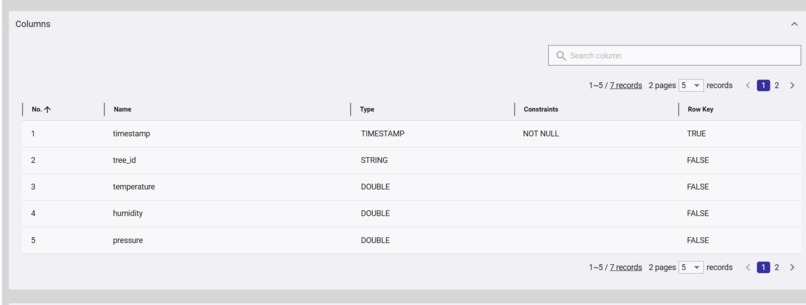
sensor_data( timestamp TIMESTAMP, tree_id STRING, temperature DOUBLE, humidity DOUBLE, pressure DOUBLE, soil_raw DOUBLE, co2_ppm DOUBLE )
Every incoming row is inserted into this container via WebAPI.
Dashboard (Web UI)
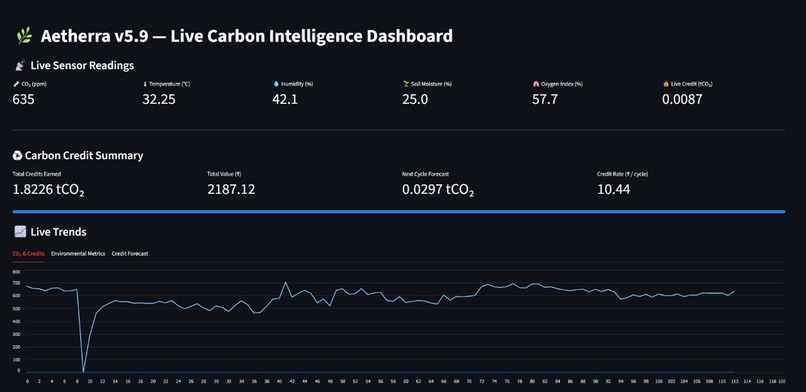
We visualize:
Live readings
Historical charts
Patterns across time
Carbon-relevant signals (CO₂ & biomass factors)
This shows how MRV data can be used for decision-making and audit trails.
Why GridDB Was Critical
MRV requires:
Fast ingestion
Low-latency queries
Compact time-series storage
High-resolution data retention
GridDB solves all of these.
It gives us:
Efficient time-series engine Super-fast SQL queries over millions of rows Easy integration via REST API Reliability for climate datasets
GridDB is literally built for MRV pipelines.
Challenges We Faced
Cloud REST API limitations → built a local GridDB setup
403 / 502 gateway failures → solved using SQL-based insert method
No hardware virtualization → couldn’t run Docker version
Needed a portable GridDB workflow for judges → created local emulator for testing
Ensuring JSON → SQL → Dashboard pipeline worked end-to-end
Despite these hurdles, we created a fully functional MRV data pipeline.
What We Learned
How to model MRV time-series datasets
How to connect IoT pipelines to GridDB
How SQL WebAPI works
How to build dashboards on top of time-series data
How climate tech requires precision + reliability
Tech Stack & Tools Database
GridDB Community Edition (Primary Requirement)
GridDB SQL WebAPI
Time-series containers
Backend
Python
Flask
Requests (GridDB REST client)
IoT Layer
Python-based sensor simulator
JSON-based data packets
Dashboard
HTML
JavaScript
Chart.js
Other Tools
VS Code
GitHub
Windows environment
Impact
This project demonstrates how MRV (Measurement, Reporting, Verification) can become:
continuous
real-time
transparent
digitally verifiable
This unlocks carbon income for:
small farmers
agroforestry projects
biodiversity regions
sustainability programs
Aetherra can evolve into a full-fledged MRV platform enabling trustworthy climate action.
What’s Next
Deploy physical sensors
Expand into biomass estimation
Integrate satellite + IoT hybrid MRV
Build carbon passport generator
Provide APIs to carbon registries
Add anomaly detection for climate alerts


Log in or sign up for Devpost to join the conversation.