-
-
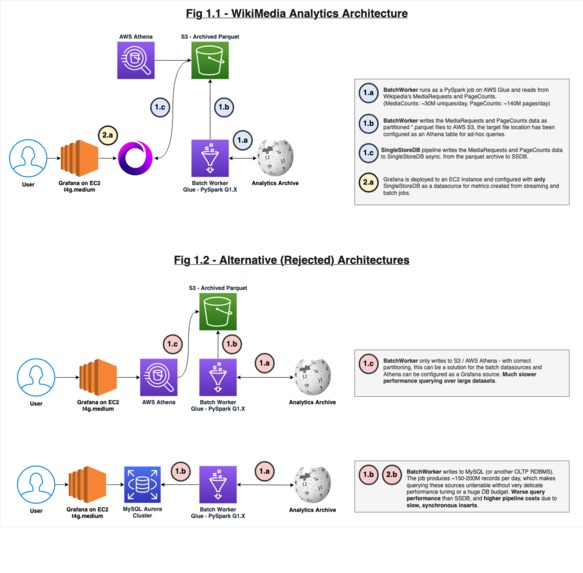
Singlestore Wikipedia Analytics Architecture

[do not review - incomplete]
This project uses SingleStore as a database for storing and calculating statistics on Wikipedia's article views and media files served. As of writing, this SingleStore instance is querying over 5 billion article-hour records (~200 GB parquet, ~900 GB raw-uncompressed). Some of these queries rely on the properties of an OLAP DB (e.g. Media Counts - Total Bytes Served, Page Counts - Total Page Views), while others depend on those of a row-based datastore (e.g. Page Counts - Total Page Views by Article) .
Batch ingestion jobs use Apache Spark running on AWS Glue to write Wikipedia's Page Views and Media Requests data to S3 as Parquet. Data is then migrated to SingleStore via an async. background pipeline.
Frontend is a Grafana instance with two dashboards provisioned, each panel comes with a detailed description of what it displays.
- Page Counts - Total Page Views [Hourly] [By Language]
- Page Counts - Total Page Views [Hourly]
- Page Counts - Total Page Views [Hourly] [By Article]
- Media Counts - Total Bytes Served [Daily]

Log in or sign up for Devpost to join the conversation.