-
-
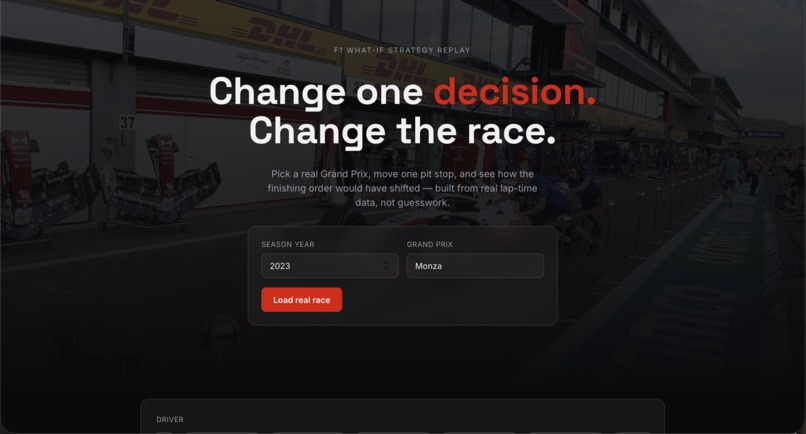
Homepage
Inspiration
Every F1 race gets decided by dozens of small decisions, and pit stop timing is one of the most consequential ones a team makes. Commentators speculate about "what if he'd pitted a lap earlier" constantly, but that speculation is always just a guess. We wanted to replace the guess with a model: pick any real race, change one driver's pit stop lap, and actually watch the projected outcome recompute against what really happened. Through this, everyone's seemingly meaningless arguments can have true meaning and a real outcome.
What it does
You pick a real Grand Prix from any recent season. The app pulls that race's actual lap-by-lap data and shows you what really happened, including every driver's real pit stops. Pick a driver, drag a slider to a different pit lap, and the app resimulates their entire race from that point forward using a tire-degradation model trained on their real in-race pace. The result is a side-by-side comparison: the position they actually finished in versus the position our model projects they would have finished in, lap by lap, with a confidence band around the projection rather than a false-precision single number.
How we built it
The backend is Python and FastAPI, pulling real timing data through FastF1, which sources directly from Formula 1's own timing archives. For each driver we fit a per-tire-compound regression on lap time versus tire age, learned from their actual laps in that race, then use it to project cumulative race time forward from a new pit lap, adding a fixed pit-stop time loss and propagating uncertainty into a confidence interval rather than pretending the model is exact. The frontend is Next.js with Recharts, rendering real position versus simulated position as a line chart, with an explicit assumption stated in the UI: only the selected driver's race is resimulated, everyone else is held at their real pace, because modeling a full field's strategic response was out of scope for four days.
We deployed the backend to Railway and the frontend to Vercel so the whole thing runs with zero cost and zero local installs, entirely from GitHub Codespaces.
The math and model behind it
Tire degradation model
For a given driver and a given tire compound, we assume lap time increases roughly linearly with tire age. For lap $i$ on a stint, with tire age $a_i$ (laps since the last pit stop):
$$ \text{LapTime}_i = \beta_0 + \beta_1 a_i + \varepsilon_i, \qquad \varepsilon_i \sim \mathcal{N}(0, \sigma^2) $$
Here $\beta_0$ is the base pace on a fresh tire of that compound, $\beta_1$ is the degradation rate (seconds lost per lap of tire age), and $\sigma^2$ is the residual variance, which we estimate directly from the fit and reuse later for uncertainty. We fit this per compound (soft, medium, hard) per driver, using only that driver's real laps from that real race, via ordinary least squares (sklearn.linear_model.LinearRegression).
Simulating a new pit strategy
To resimulate a driver's race with a new pit lap $p^*$, we walk forward lap by lap and reconstruct cumulative race time:
$$ T_n = \sum_{i=1}^{n} \text{LapTime}_i(a_i) + \mathbb{1}[\exists\, p^* \le n] \cdot L $$
where $a_i$ resets to zero the lap after a pit stop, and $L$ is a fixed pit-stop time loss (we use $L = 22.0$ seconds, a reasonable in-and-out-lap penalty). $\mathbb{1}[\cdot]$ is an indicator function that adds the loss exactly once, on the lap the new stop occurs.
Propagating uncertainty
Because each lap's prediction carries residual variance $\sigma^2$ from the regression, the uncertainty compounds as we sum laps. Assuming laps are roughly independent conditional on tire age, the variance of cumulative time through lap $n$ is:
$$ \text{Var}(T_n) \approx n \sigma^2 $$
We use this to build a 90% confidence band around the projected cumulative time:
$$ T_n \pm 1.645 \sqrt{\text{Var}(T_n)} $$
The $1.645$ comes from the standard normal distribution's 95th percentile, giving a one-sided 90% interval — we treat the band as "plausible range," not a hard guarantee, and say so explicitly in the UI rather than presenting a single confident number.
From cumulative time to race position
Real race positions aren't just about one driver's pace, they're relative to everyone else on track. To translate simulated cumulative time into a projected finishing position, we hold every other driver's real cumulative time fixed (our stated simplifying assumption) and, for each lap $n$, rank the simulated driver's $T_n$ against all other drivers' real $T_n$ values:
$$ \text{Position}n = 1 + \sum{j \ne \text{driver}} \mathbb{1}[T_n^{(j)} < T_n^{(\text{driver})}] $$
This is recomputed lap by lap, which is what produces the real-vs-simulated position line chart in the UI.
Why this design
We chose a simple linear degradation model on purpose. F1 lap time is affected by fuel load, traffic, track evolution, and driver-specific factors that a four-day hackathon model can't fully capture, so rather than overfit a complex model to a small number of laps per stint, we kept the model interpretable and leaned on explicit uncertainty bands to be honest about what it doesn't know. A model that says "P2, give or take one position" is more trustworthy than one that confidently says "P2" and is wrong.
Challenges we ran into
The biggest one had nothing to do with our own code. FastF1's pinned version in our requirements file was old enough that it was still pointed at the original Ergast API, which was deprecated in 2024, so every request was silently failing with driver lists loading but zero laps of actual timing data. We traced it by running FastF1 outside of FastAPI entirely, watching the raw HTTP calls with debug logging, and found requests were falling back to a mirror and coming back 404. Upgrading to a current FastF1 release fixed it immediately, and it turned into a good lesson in not trusting a library's error message at face value; the wrapper's generic warning hid a much more specific root cause underneath.
On the deployment side, a nested folder structure from an early zip extraction caused two separate headaches: a bloated git history where node_modules had been committed before .gitignore existed, rejecting our push for exceeding GitHub's 100 MB file limit, and later a Vercel Root Directory misconfiguration that silently built successfully but served a 404, because the frontend actually lived one folder deeper than expected. Both were solved the same way, by carefully mapping out the actual folder structure on disk instead of assuming it matched what we'd originally intended.
Accomplishments that we're proud of
We have a fully working, end-to-end pipeline running on real F1 timing data, not synthetic or mocked data, deployed live and reachable from any device. The model is honest about its own uncertainty instead of presenting a single confident number, and the UI states its modeling assumptions directly rather than hiding them. Given the time constraints, getting from an idea to a real deployed tool that correctly recomputes an actual Grand Prix from live archival data felt like the right scope to aim for and land.
What we learned
A surprising amount of this project was about data plumbing rather than modeling. Getting trustworthy real-world sports data to arrive in a clean, loadable state took far more debugging than the statistics did. We also learned to diagnose from the outside in: bypassing our own API to call FastF1 directly, bypassing the frontend to hit the backend with curl and Swagger, and bypassing Vercel's dashboard to run the build locally, each time isolating one layer at a time instead of guessing at the whole stack.
What's next for What If? F1 Strategy Sim
The clearest next step is redesigning the front end around a race and driver picker with autocomplete and a scrollable driver selection strip, replacing free-text year and Grand Prix inputs. We'd also like to visualize the actual track layout, traced from real telemetry coordinates, as a piece of UI rather than decoration. Longer term, the biggest modeling upgrade would be letting more than one driver's strategy change at once, so the sim can answer "what if the whole top three pitted differently," instead of just one driver in isolation.
Built With
- api
- codespaces
- css
- fastapi
- fastf1
- javascript
- next.js
- numpy
- pandas
- python
- railway
- react
- recharts
- rest
- scikit-learn
- tailwind
- typescript
- uvicorn
- vercel


Log in or sign up for Devpost to join the conversation.