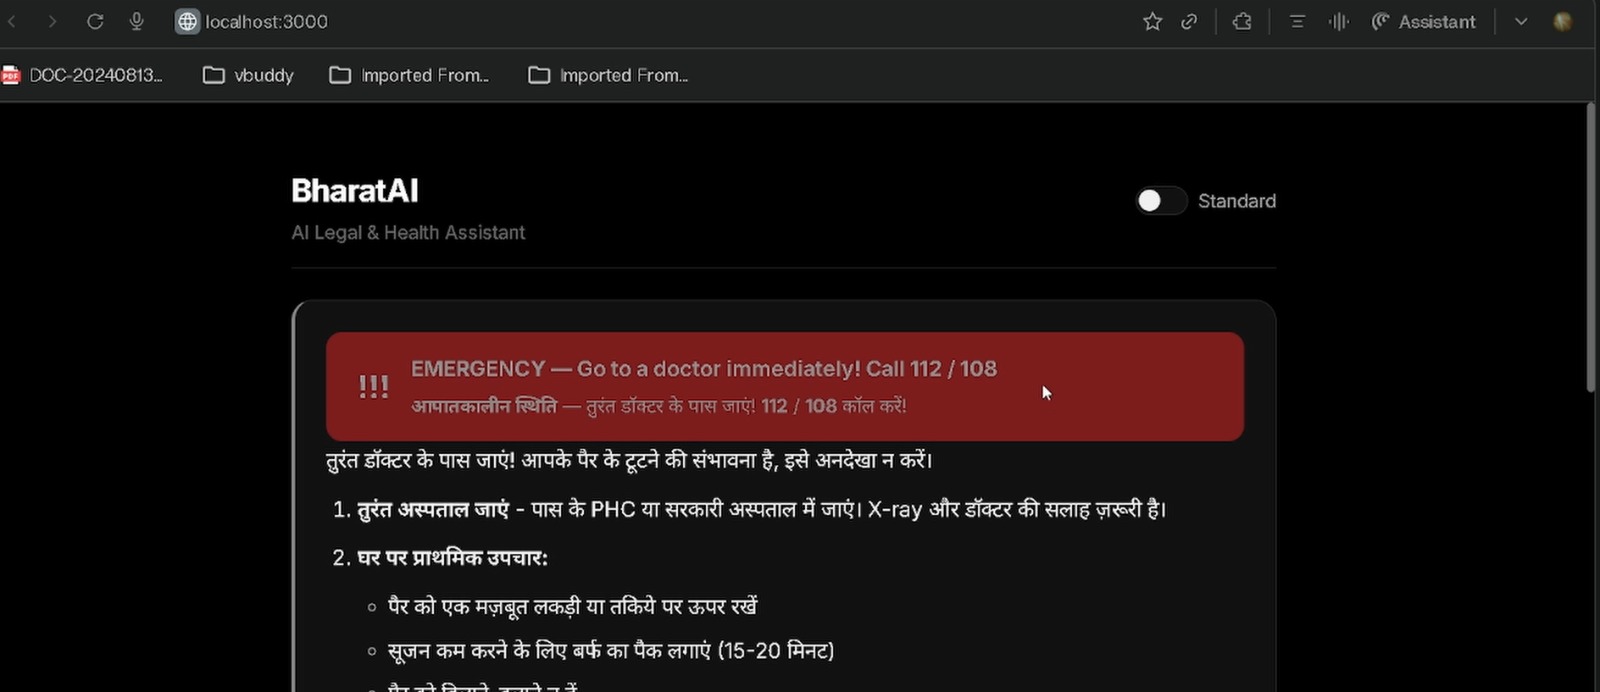
BharatAI — Unified Legal & Health AI Assistant
India has 1.4 billion people, most of whom cannot afford a lawyer or a doctor. BharatAI bridges that gap — a unified AI assistant that answers Indian criminal law questions under BNS 2023 and rural health queries, in Hindi, English, and Hinglish, with full voice support.
How It Works
Under the hood, a Qwen3-8B classifier routes every query to the right pipeline in real time.
Legal Pipeline
Legal queries hit a RAG system built on GTE-Large embeddings over $N = 448$ chunked BNS sections stored in PostgreSQL. Retrieval uses dot-product cosine similarity:
$$ \text{score}(q, c_i) = \frac{\mathbf{e}q \cdot \mathbf{e}{c_i}}{|\mathbf{e}q| |\mathbf{e}{c_i}|} $$
where $\mathbf{e}q \in \mathbb{R}^{1024}$ is the query embedding and $\mathbf{e}{c_i}$ is the chunk embedding. Top-$k$ chunks ($k = 10$) are retrieved, with co-retrieval of offense–punishment pairs. Sarvam Translate handles Hindi $\leftrightarrow$ English conversion; Qwen3-8B generates cited answers with BNS section numbers.
Health Pipeline
Health queries go through a 5-step Sarvam 30B orchestration pipeline:
$$ \text{Query} \xrightarrow{\text{Step 1}} \text{Understanding} \xrightarrow{\text{Step 2}} \text{Search Optimisation} \xrightarrow{\text{Step 3}} \text{Parallel Fetch} \xrightarrow{\text{Step 4}} \text{Synthesis} \xrightarrow{\text{Step 5}} \text{Safety Check} $$
Step 3 fans out to $M \geq 10$ sources concurrently:
| Source | Type |
|---|---|
| MedlinePlus | Health topics (XML) |
| PubMed E-utilities | Academic papers |
| OpenFDA | Drug labels |
| NHP / CDSCO / WHO | Government health (Google CSE) |
| Wikipedia | General summaries |
| Indian drug database | Local JSON |
| Government health schemes | Local JSON |
| YouTube Data API v3 | Educational videos |
Emergency keywords (chest pain, seizure, snake bite, etc.) set $\texttt{is_emergency} = \texttt{true}$, triggering an immediate red-alert banner with helpline numbers 112 / 108.
Voice Pipeline
$$ \text{Audio (16kHz WAV)} \xrightarrow{\text{Sarvam Saarika v2.5 ASR}} \text{Transcript} \xrightarrow{\text{Router}} \text{Pipeline} \xrightarrow{\text{IndicF5 / Bulbul v2 TTS}} \text{Audio response} $$
- STT: Sarvam Saarika v2.5 ASR (
hi-IN,en-IN) - TTS (Hindi, primary): IndicF5 — open-source, voice cloning via HuggingFace Space
- TTS (fallback): Sarvam Bulbul v2
Deployment & Data Architecture
The full stack — FastAPI backend + React SPA — is deployed as a single-process app on Databricks Apps. The BNS data pipeline follows the medallion architecture built in Databricks Notebooks:
$$ \underbrace{\texttt{bns_raw_sections}}{\text{Bronze: raw CSV}} \;\longrightarrow\; \underbrace{\texttt{bns_sections},\; \texttt{bns_section2_definitions}}{\text{Silver: normalised}} \;\longrightarrow\; \underbrace{\texttt{bns_chunks},\; \texttt{bns_chapter_summaries}}_{\text{Gold: embeddings } \in \mathbb{R}^{1024}} $$
Models & Open-Source Stack
| Model | Role | Source |
|---|---|---|
Qwen/Qwen3-8B |
Domain classifier + legal answer generation | HuggingFace Inference API |
thenlper/gte-large |
Embeddings $\mathbb{R}^{1024}$, RAG retrieval | HuggingFace / local |
IndicF5 |
Hindi TTS, voice cloning | HuggingFace Space |
Sarvam 30B |
Health pipeline (all 5 steps) | Sarvam AI |
Sarvam Saarika v2.5 |
Speech-to-text | Sarvam AI |
Sarvam Translate |
Hindi $\leftrightarrow$ English (12 languages) | Sarvam AI |
Built With
- aiohttp
- css3
- databricks-notebooks-databases-postgresql-15-with-pgvector-(1024-dim-hnsw-index)-ai-/-ml-models-qwen3-8b
- google-custom-search-api
- gradio-client-platforms-databricks-apps
- html5
- httpx
- huggingface-inference-api
- huggingface-spaces-cloud-services-azure-postgresql-(or-aws-rds)
- indicf5
- javascript-(es2023)
- languages-python-3.11
- medlineplus-xml-api
- numpy
- openfda-api-other-web-audio-api-(browser-side-wav-recording)
- pubmed-e-utilities
- pydantic-v2
- react-18
- react-markdown
- sarvam-30b
- sarvam-bulbul-v2-tts
- sarvam-saarika-v2.5-asr
- sarvam-translate-apis-sarvam-ai-api
- sentence-transformers
- soundfile
- sql-frameworks-&-libraries-fastapi
- tenacity
- thenlper/gte-large
- vite-5
- youtube-data-api-v3
