-
-
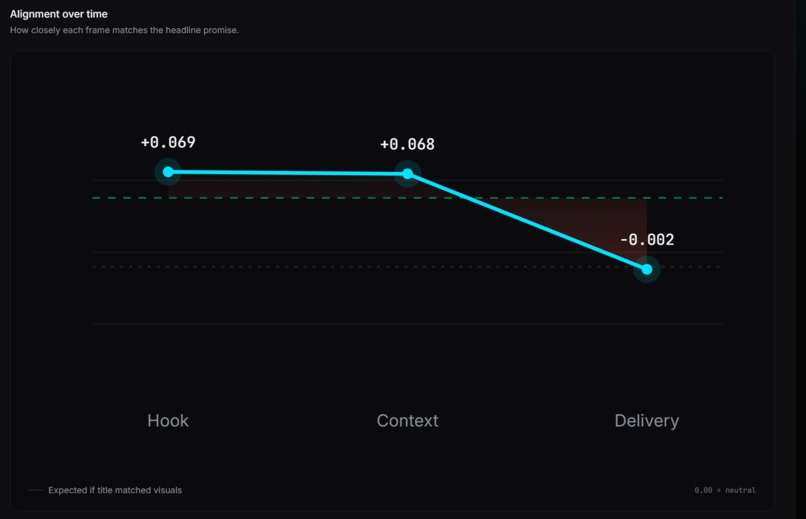
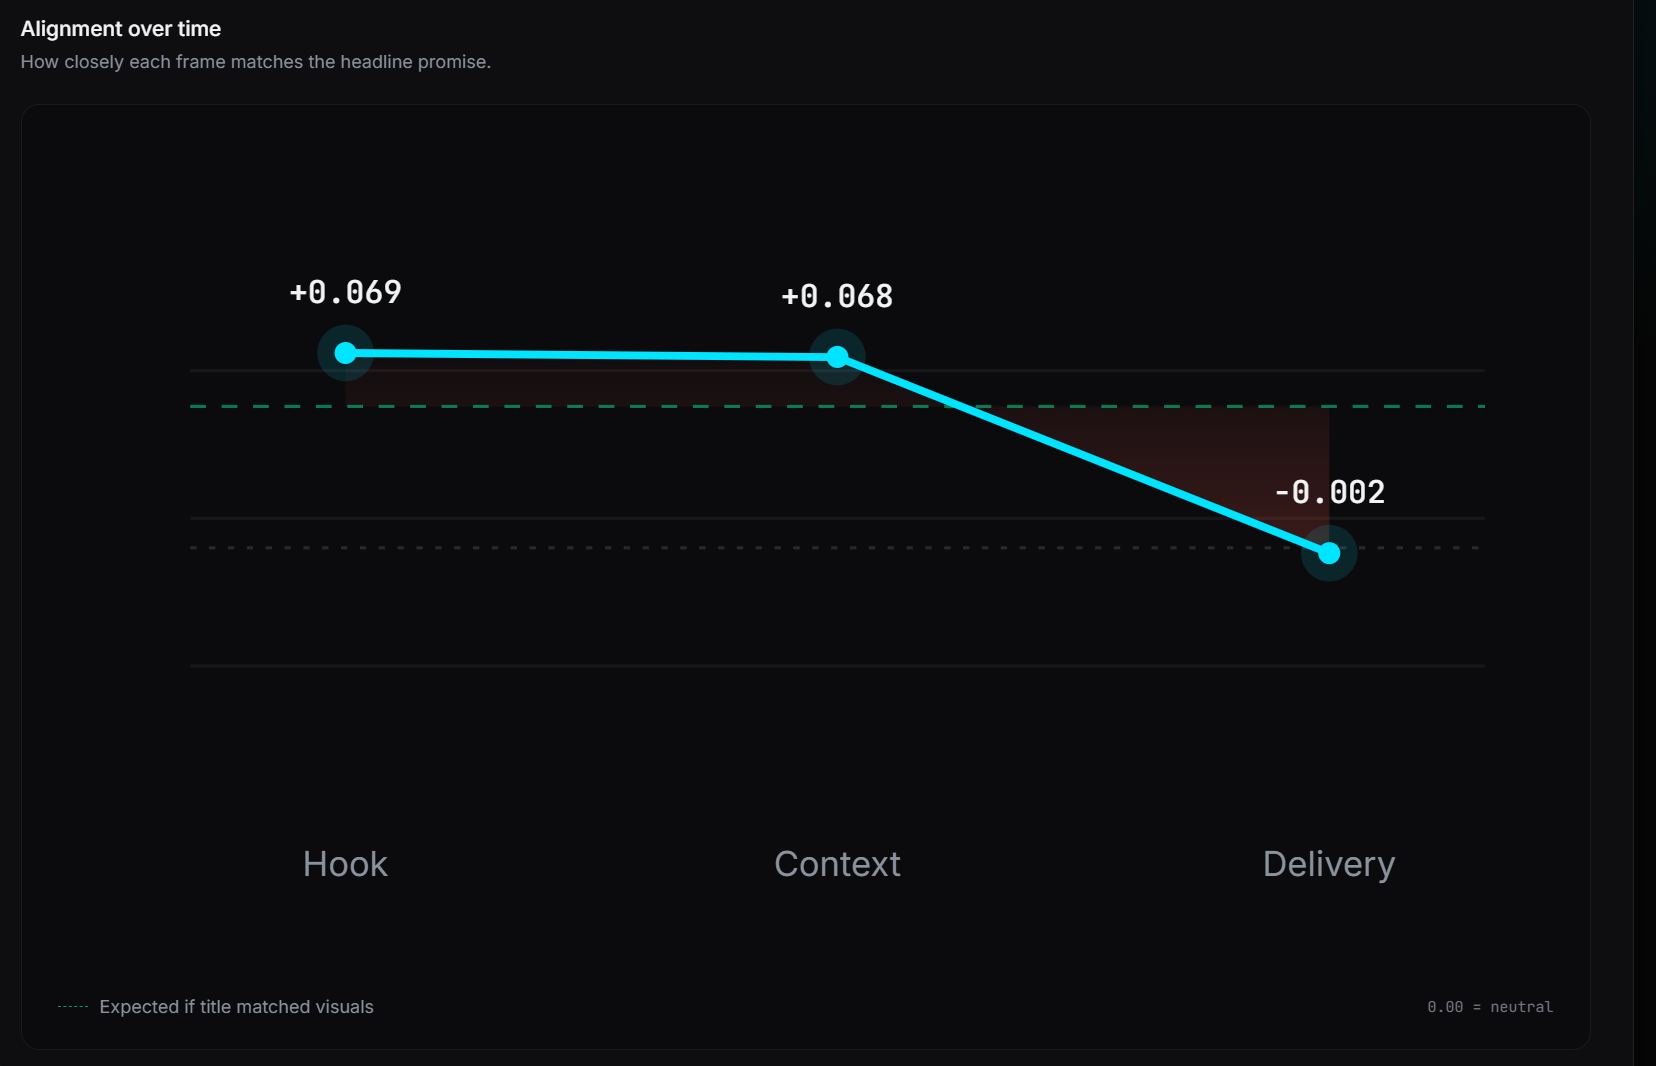
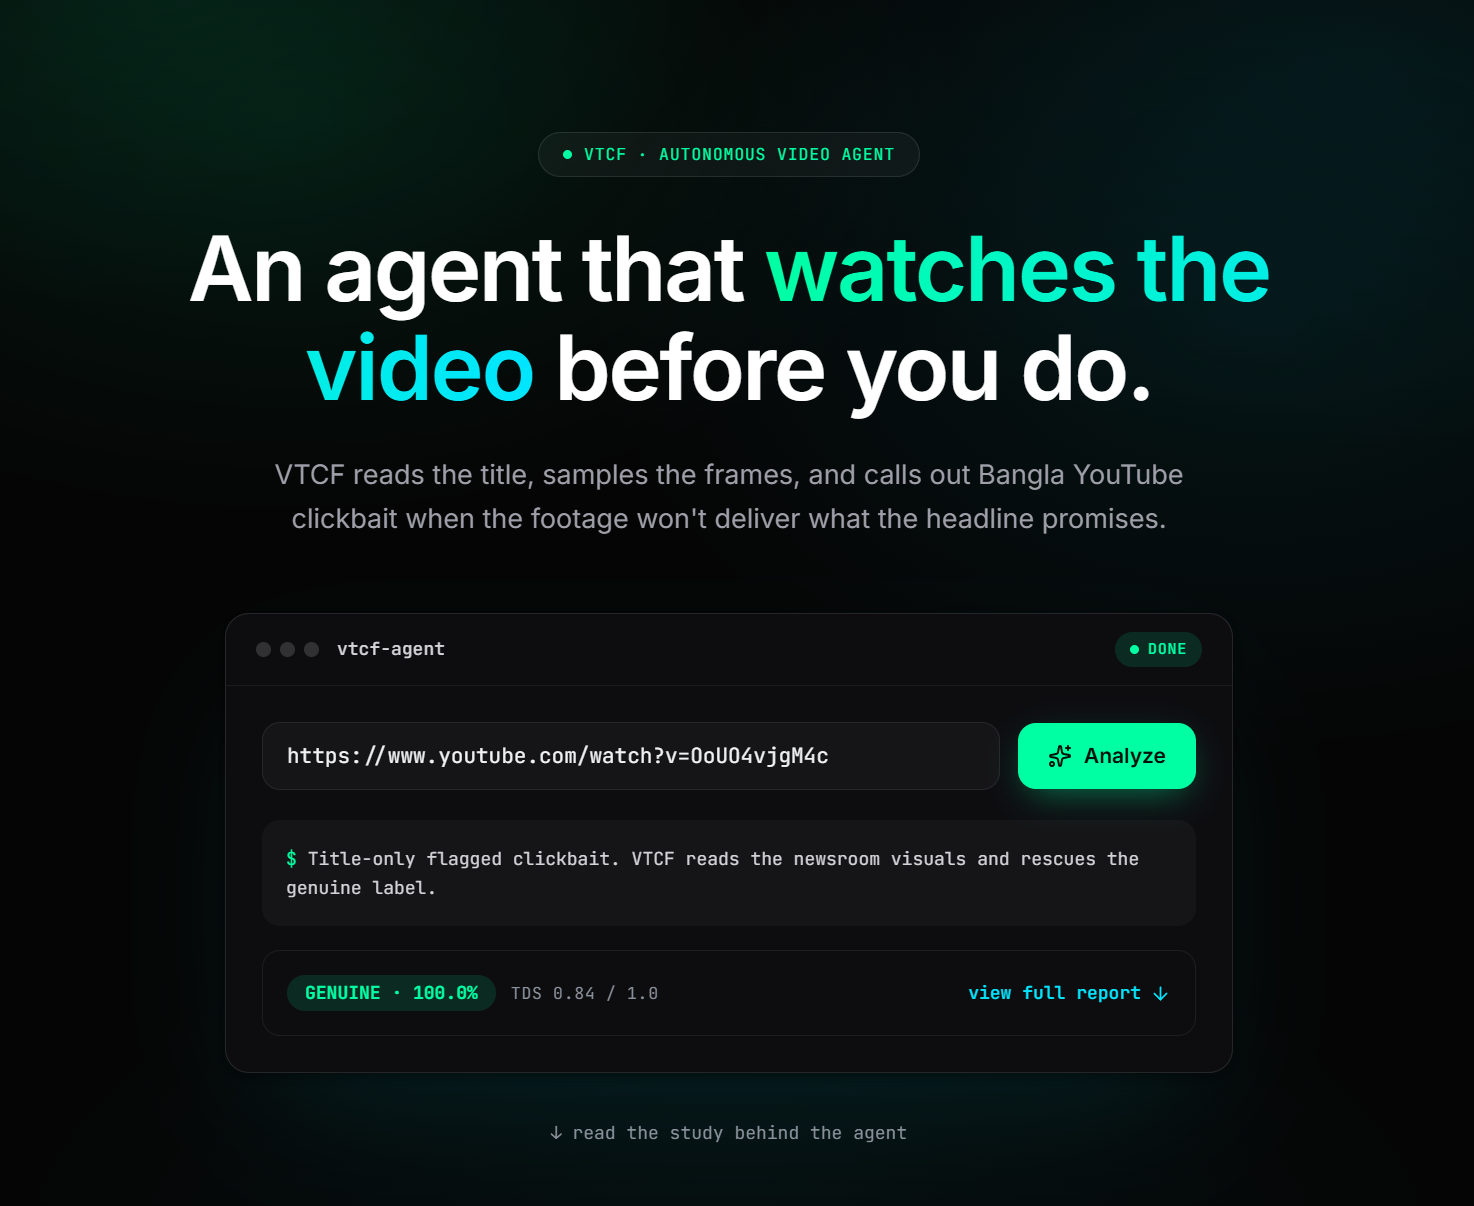
Title-to-frame alignment plotted across the video's timeline, showing exactly where a video's claims start to break down.
-
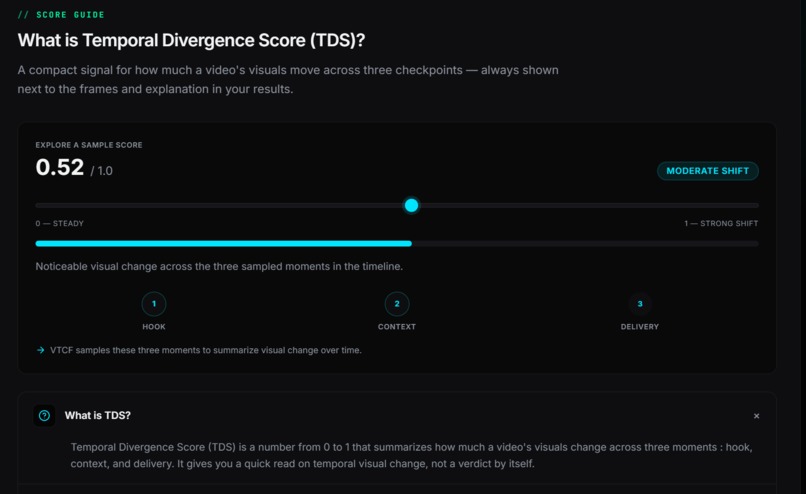
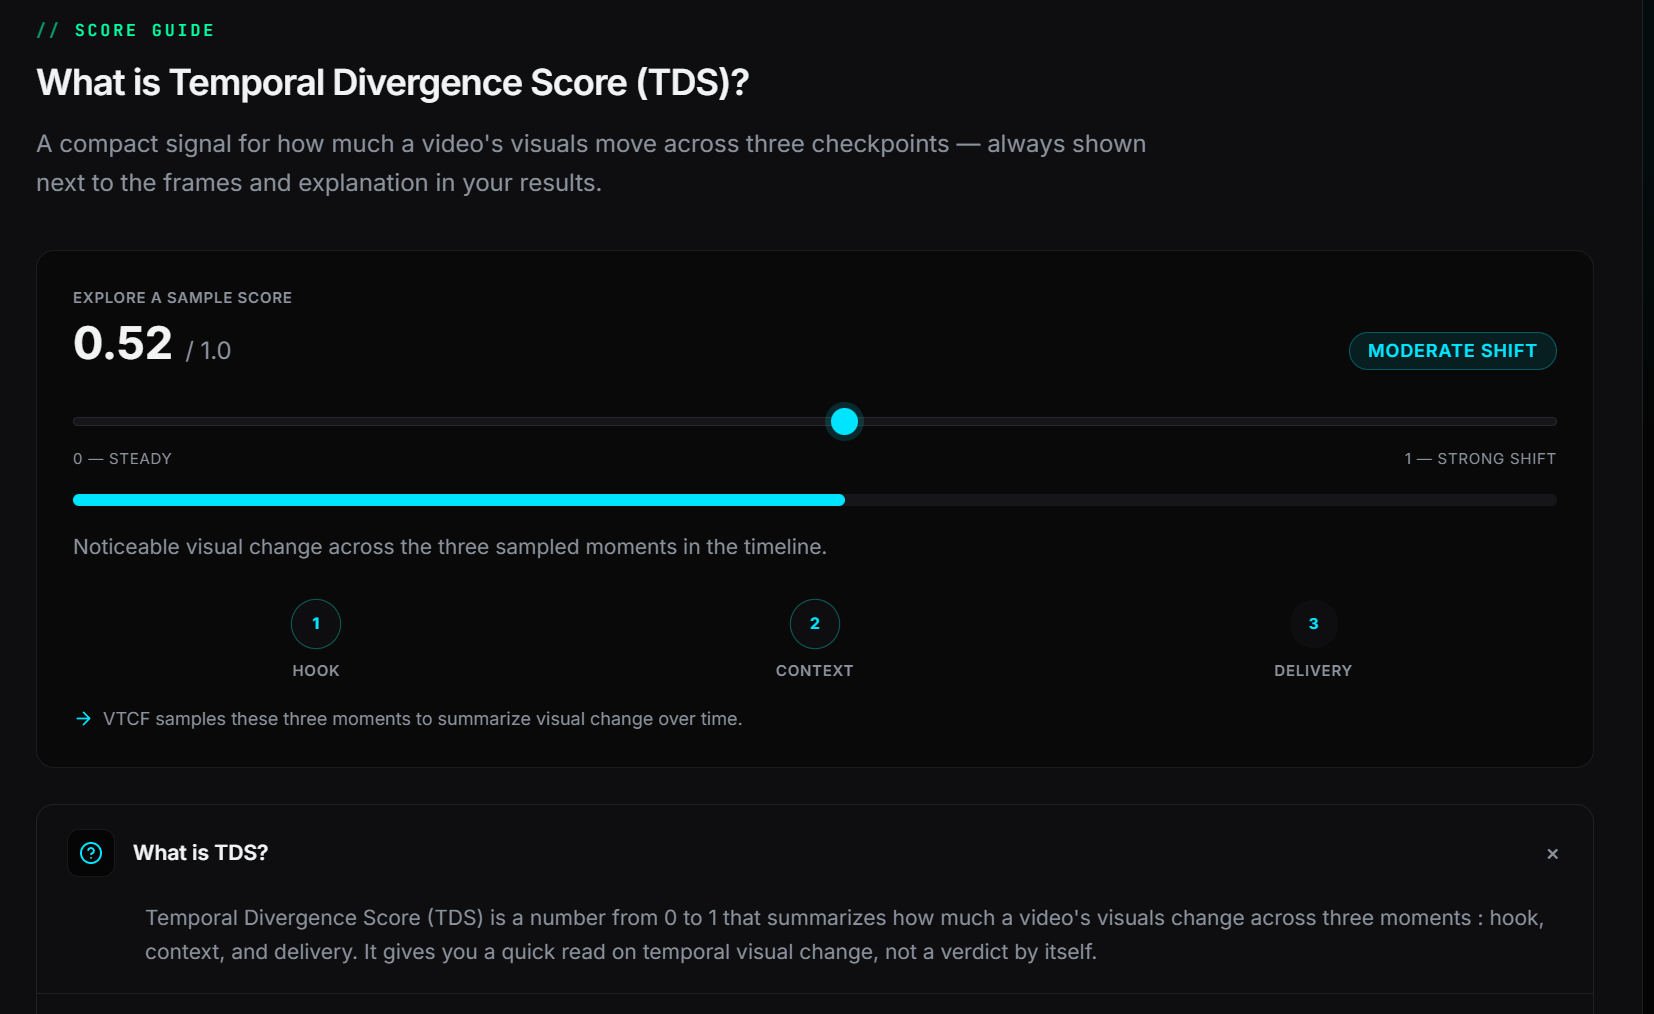
An interactive guide to the Temporal Divergence Score about how much a video's visuals shift from hook to delivery, explained.
-
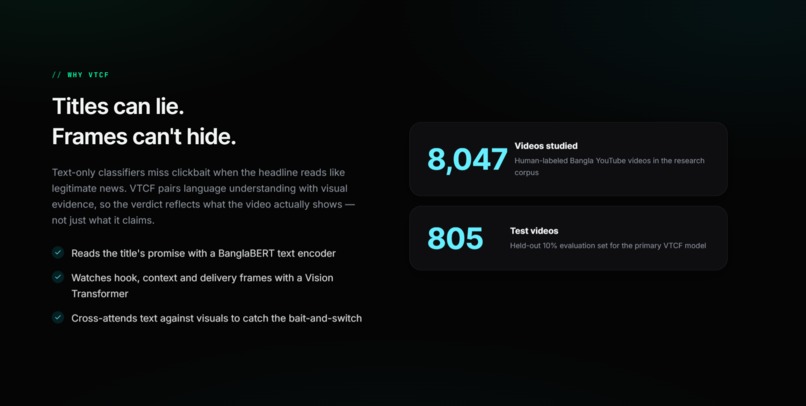
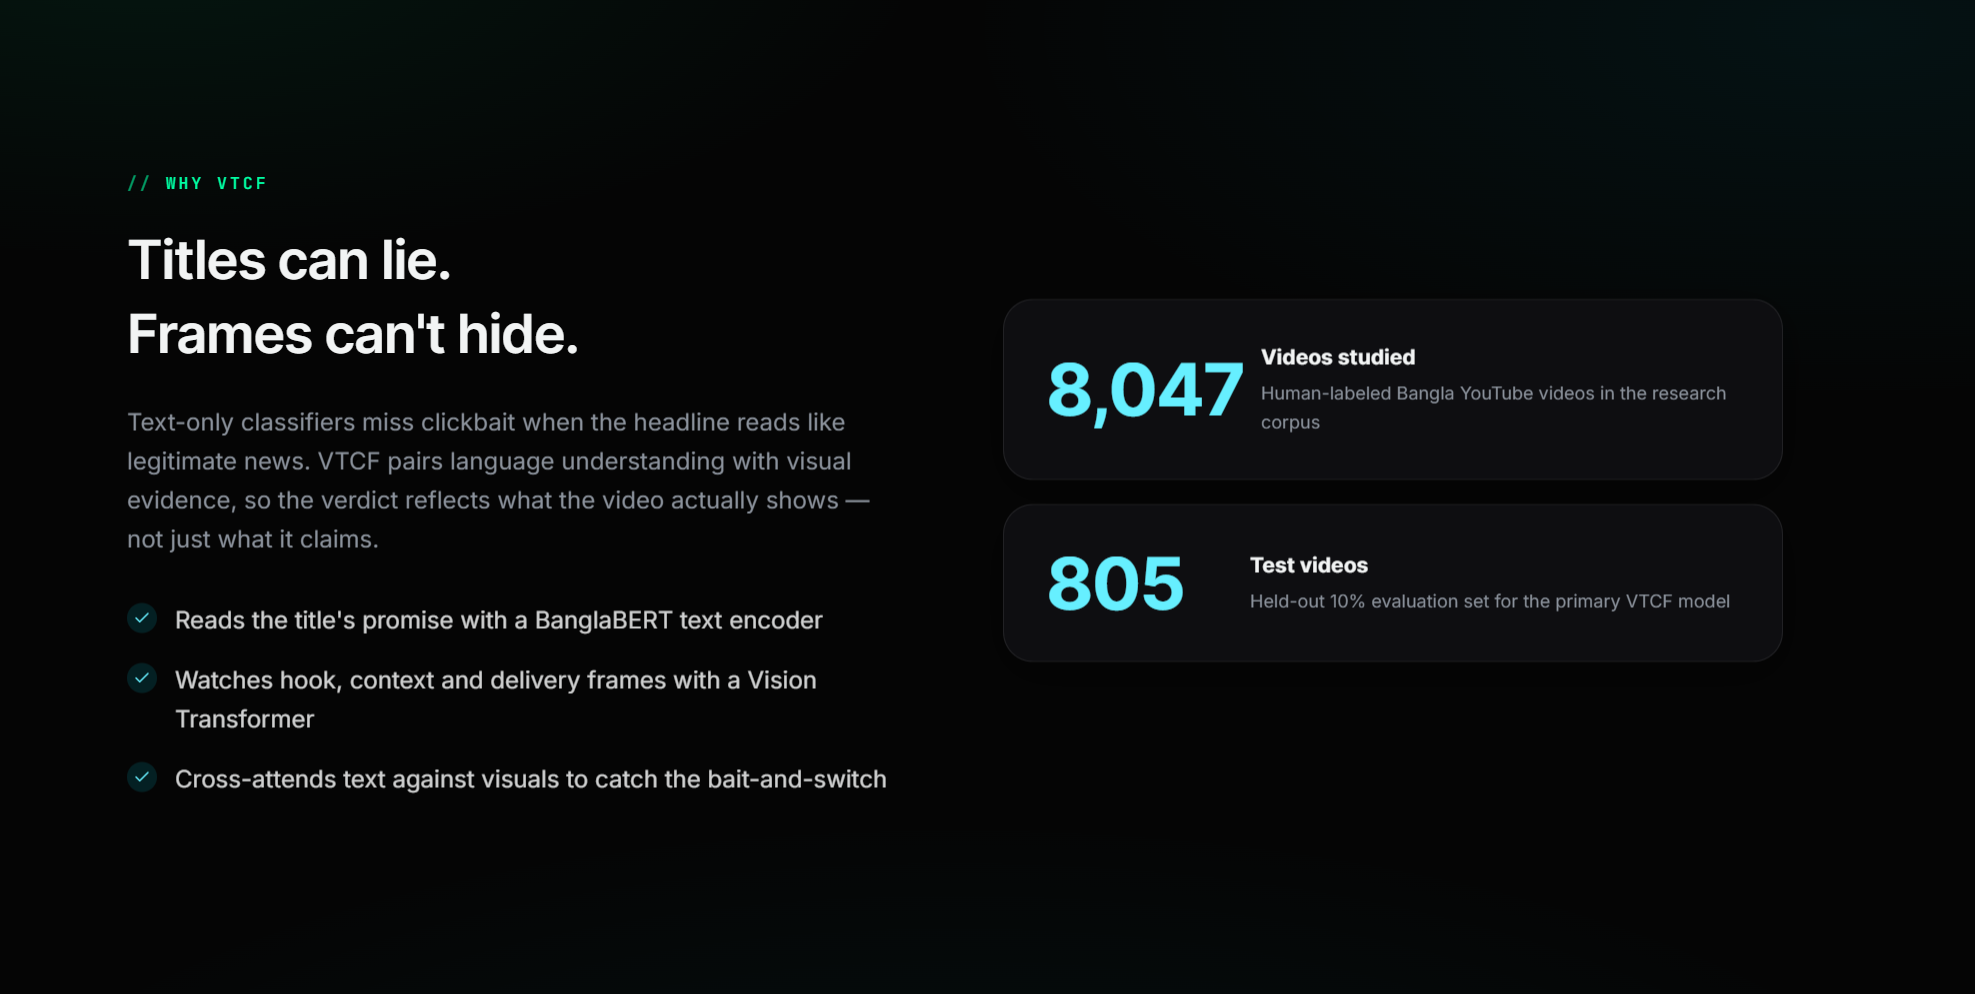
Built on 8,047 human-labeled Bangla YouTube videos, with a held-out 805-video test set.
-
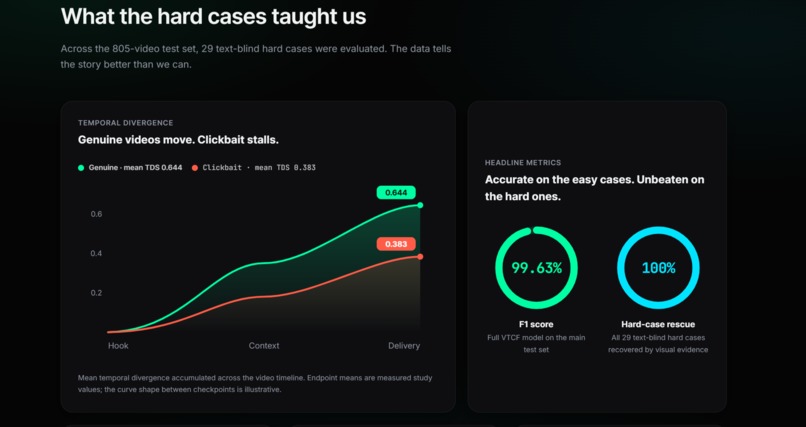
On the 33 hardest cases where a good title fools text-only AI, our visual model rescues 100% of them.
-
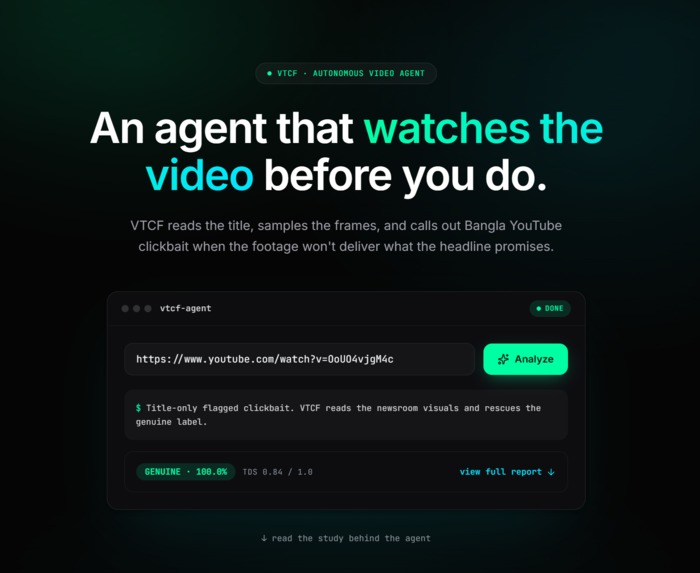
The problem in one line: VTCF reads the title AND watches the video, catching bait-and-switch content text-only models miss.
-
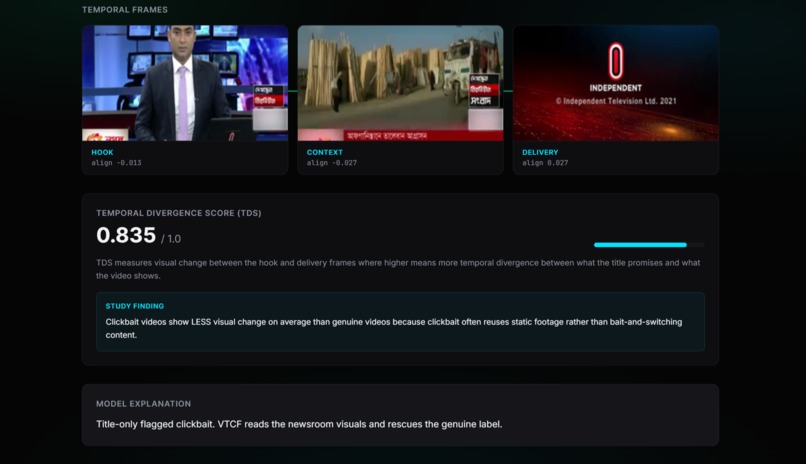
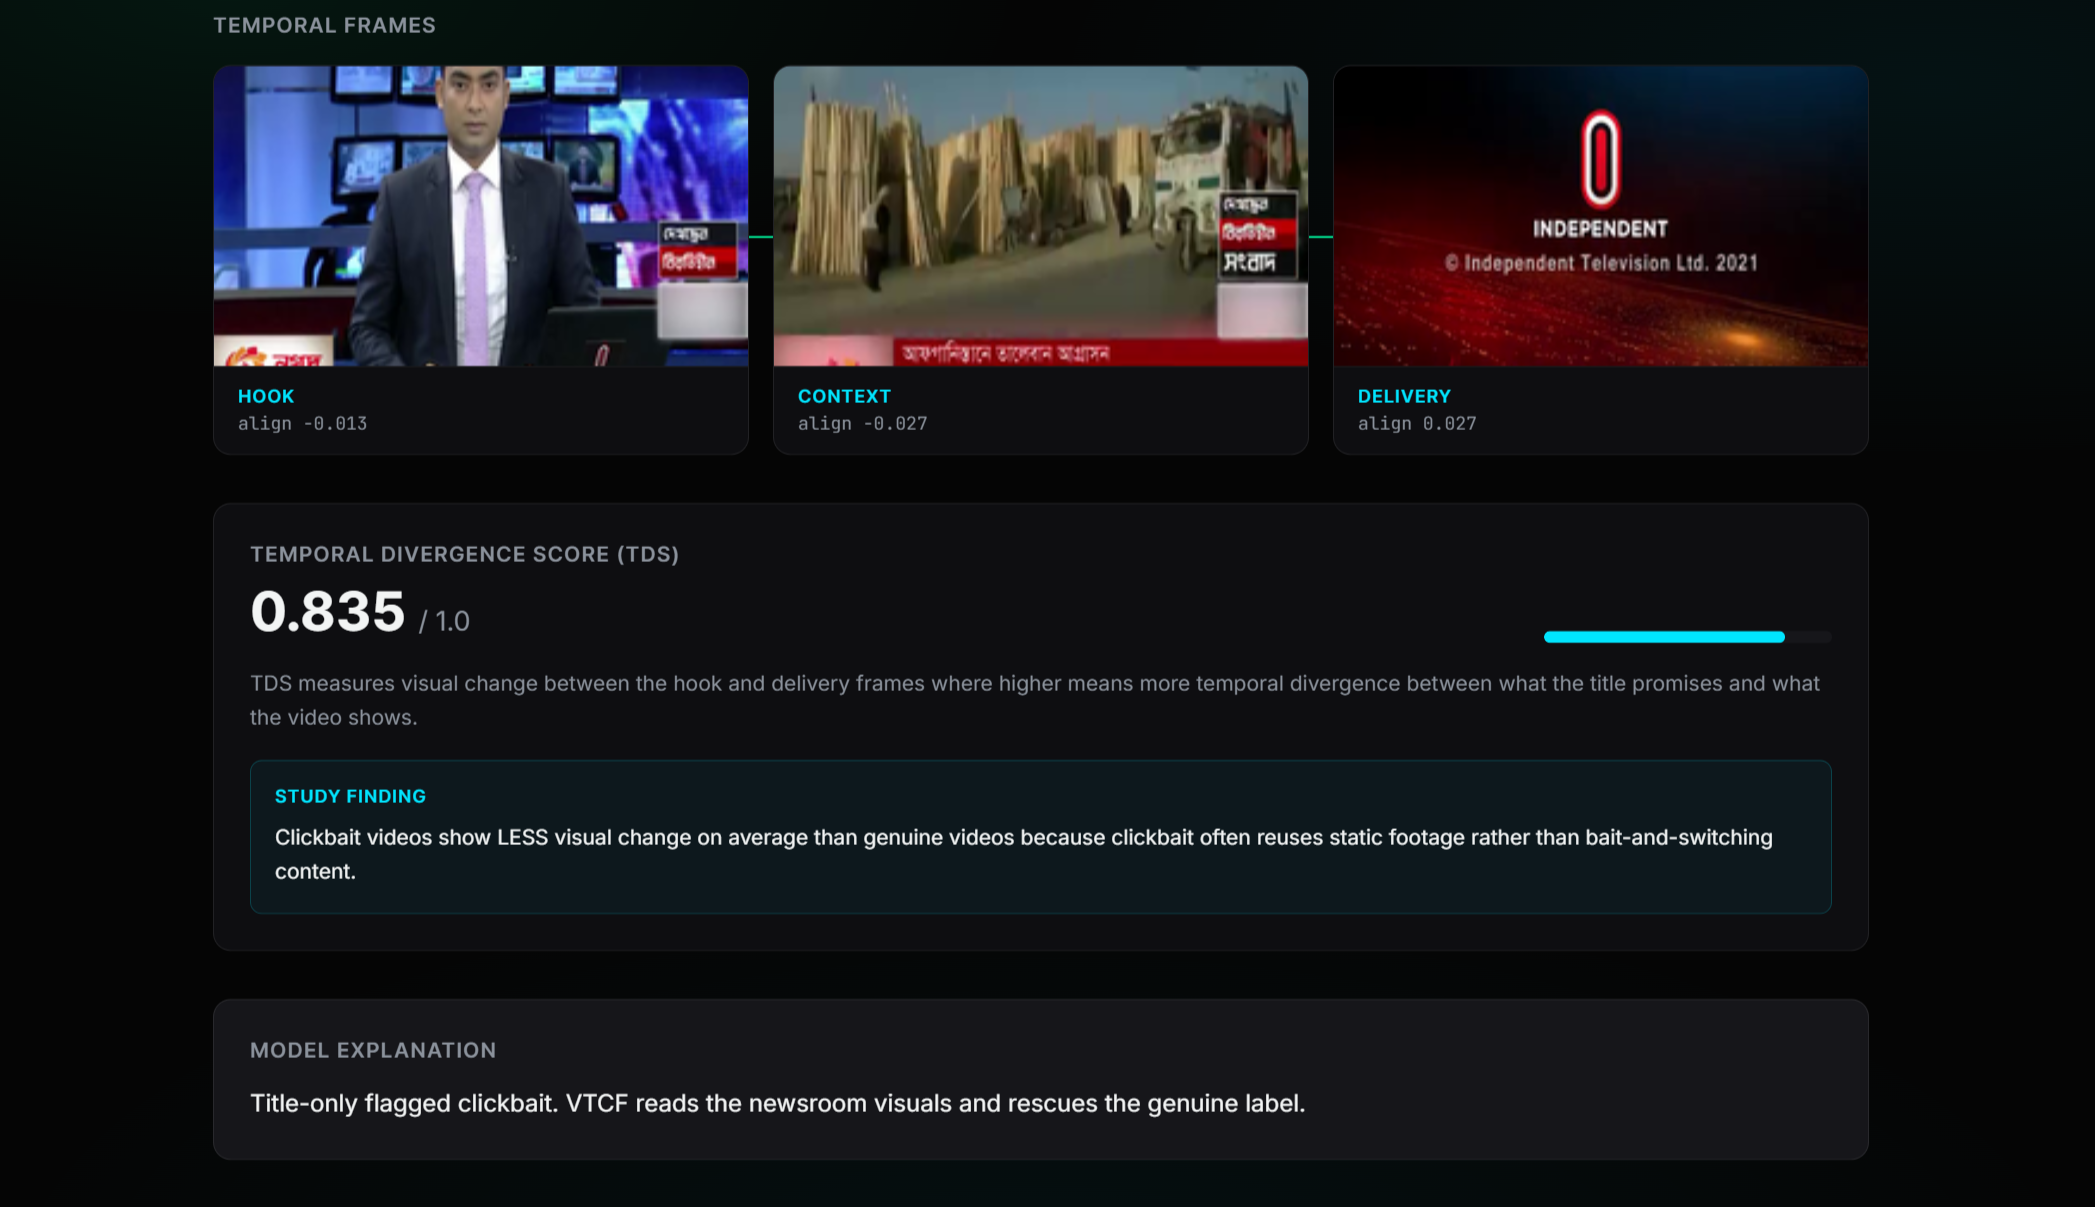
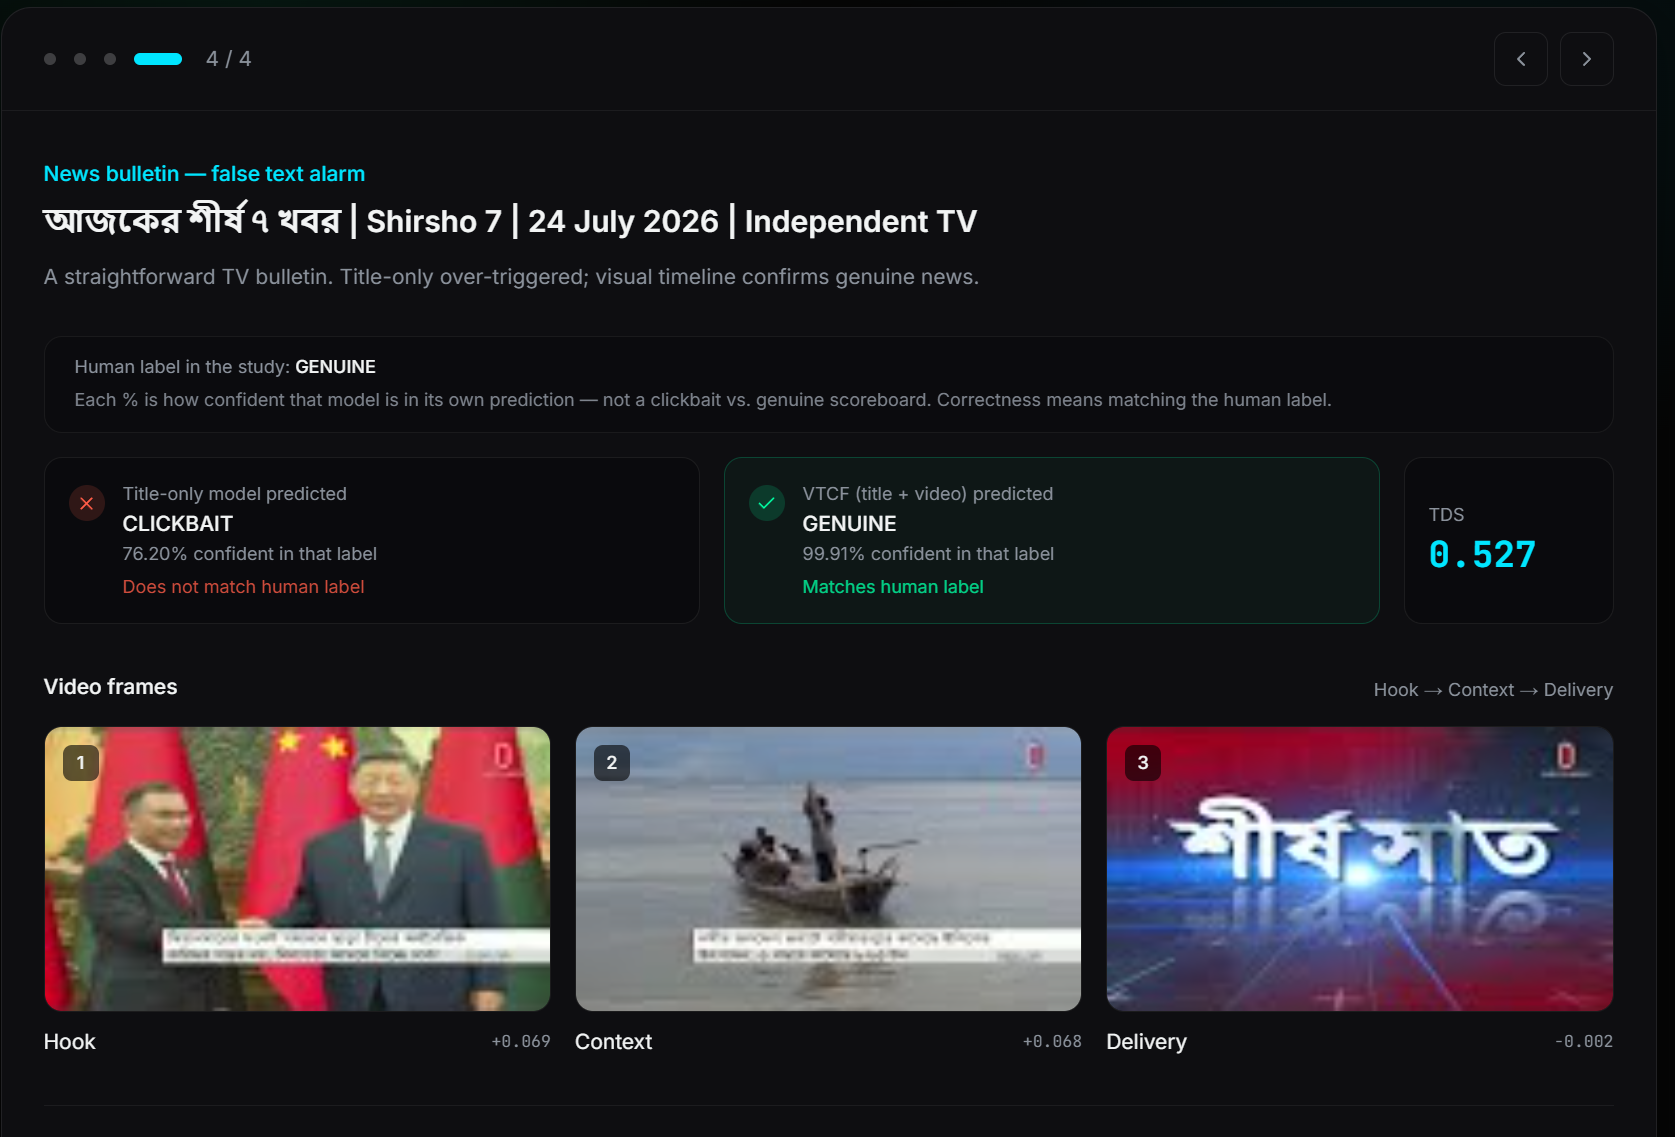
Every verdict comes with visual evidence: the actual frames analyzed, plus a Temporal Divergence Score explaining the pattern.
-
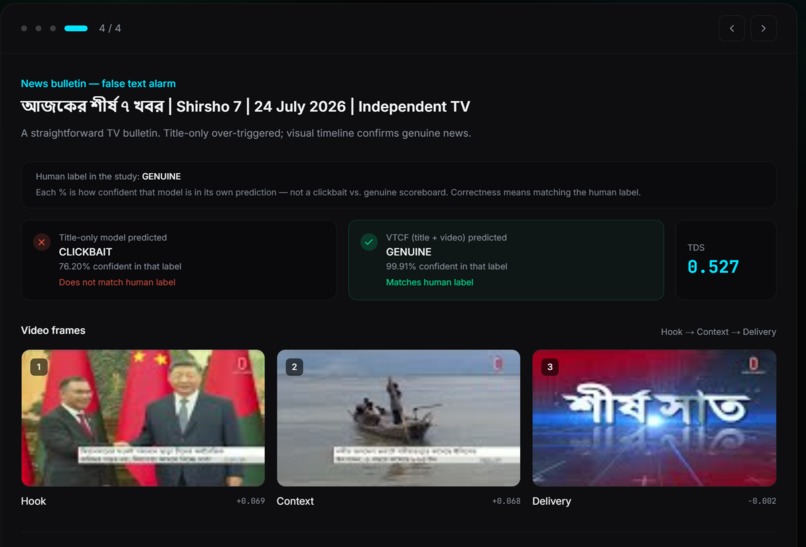
Genuine news bulletin correctly verified, with the exact hook, context, and delivery frames the model analyzed.
Inspiration
Bangla YouTube is flooded with clickbait, sensational headlines paired with footage that has nothing to do with what was promised. Existing clickbait research almost entirely relies on reading the title text. But we noticed something: a well-written, professional-sounding title can fool even a strong text classifier. If the words are convincing, text-only detection has nothing left to catch. We wanted to know: what if the AI actually watched the video instead of just reading about it?
What it does
VTCF (Visual-Temporal Contradiction Framework) analyzes a Bangla YouTube video by comparing what its title promises against what its footage actually shows. For every video, we extract three frames : the hook (opening), the context (middle), and the delivery (end), and feed them into a Vision Transformer (ViT), while a BanglaBERT model reads the title. Cross-attention compares the two, catching contradictions a text-only model would miss entirely.
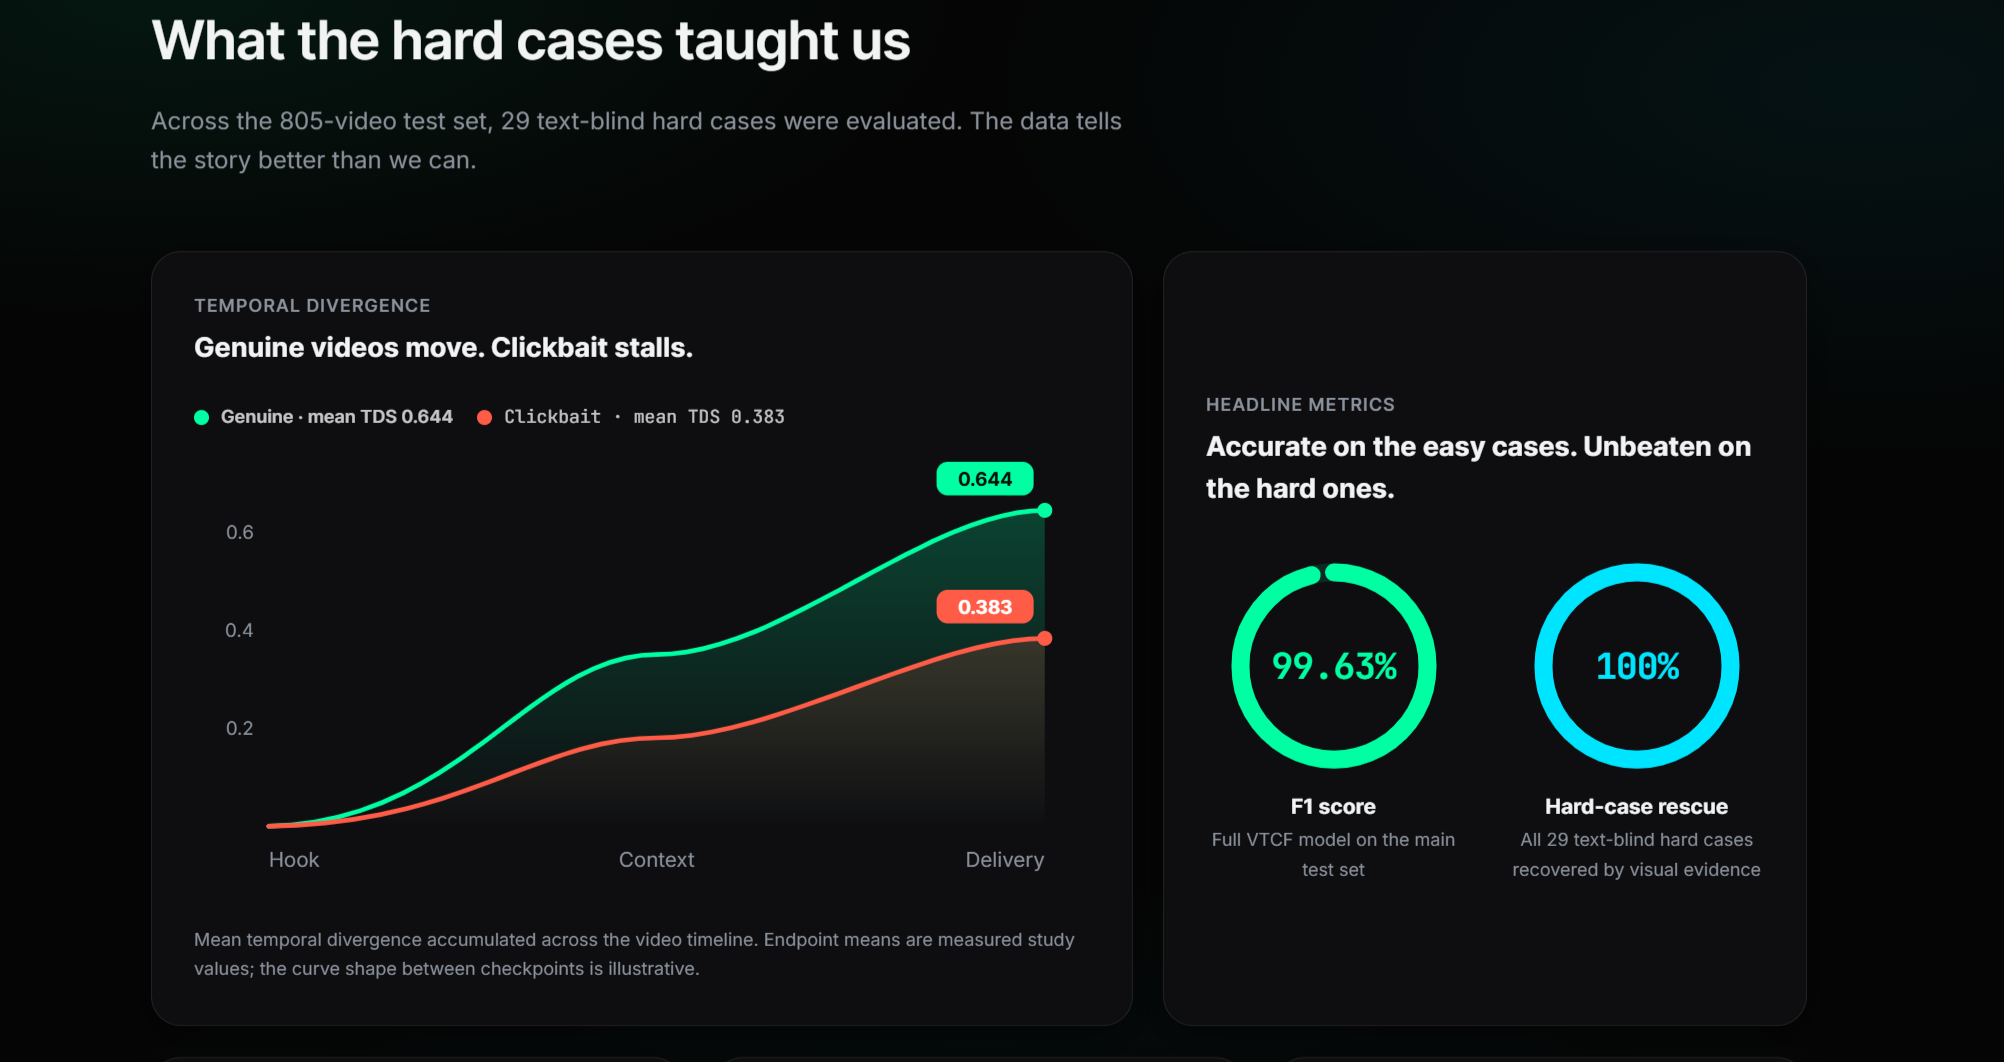
We also applied a Temporal Divergence Score (TDS), a 0–1 metric measuring how much a video's visuals shift from hook to delivery, adapted from cosine-similarity techniques and applied here specifically to Bangla clickbait detection. Counter-intuitively, we found clickbait videos show less visual change on average (~0.38) than genuine videos (~0.64) . Clickbait often reuses static footage rather than actually switching content mid-video.
How we built it
- Data: 10,000 human-labeled videos from BaitBuster-Bangla, with 8,047 successfully downloaded and frame-extracted
- Text encoder:
sagorsarker/bangla-bert-base(BanglaBERT) - Vision encoder:
google/vit-base-patch16-224(ViT) - Fusion: a custom cross-attention layer lets the title "ask" the frames whether its claims hold up, trained with a contrastive loss on the TDS signal
- Pipeline: yt-dlp for video download, PySceneDetect for frame extraction, PyTorch/Hugging Face for training and inference
- App: FastAPI backend wrapping the trained model, Next.js + Tailwind + Framer Motion frontend, with a deployed demo
Challenges we ran into
- The hard-subset test: we deliberately isolated the 33 videos where a title-only model was wrong but highly confident. The true test of whether visual evidence actually helps. Early on, a training bug silently fed the image pipeline into what was supposed to be our text-only baseline, collapsing its score to 0.34 before we found and fixed the bug.
- "Too good to be true" results: several runs came back with suspiciously perfect scores. Rather than accept them, we ran a full leakage check (confirmed zero overlap between train/val/test), isolated exactly how much each input signal contributed, and manually read raw model outputs against ground truth before trusting any number.
- Frame extraction edge cases: scene-detection occasionally picks a title card or disclaimer overlay as the "hook" frame instead of real footage, which can distort the divergence score, a known limitation we're upfront about rather than hiding.
- Getting the demo genuinely live: making the pipeline fast and reliable enough to run end-to-end on a brand-new, never-seen YouTube URL, not just pre-computed examples, took real testing: download handling, cookie/rate-limit resilience, and consistent inference timing.
Accomplishments that we're proud of
- On the 33 hardest cases, where a well-crafted title fools a text-only model with high confidence, our visual model correctly rescues 100% of them (29/29 testable cases)
- 99.63% F1 on our full 805-video held-out test set, drawn from the 8,047-video corpus
- A fully working, end-to-end demo: paste any Bangla YouTube URL and get a real, live verdict, not just a static example
- A counter-intuitive, statistically verified research finding (the TDS reversal) that runs opposite to what we initially expected, with a mechanistic explanation for why it holds
What we learned
The most interesting result wasn't just the accuracy number; it was discovering why visual evidence rescues cases that text alone can't. Clickbait deception in this dataset often lives in production style: dramatic banners, editing choices, channel branding - signals that never reach a purely textual analysis, no matter how good the language model is. We also learned the discipline of not trusting a good-looking number until we'd tried to break it. Every near-perfect result got a leakage check and a manual read-through before we believed it.
What's next for VTCF: Watch, Don't Just Read
- Scale training to the full available dataset and additional Bangla channels beyond news-style content
- Explore a lightweight "quick check" tier for instant feedback while scrolling, reserving the full visual pipeline for on-demand deep verification
- Package the pipeline as a browser extension for real-time use directly on YouTube
- Extend the approach to other low-resource languages facing the same gap in clickbait research
Built With
- banglabert
- computer-vision
- fastapi
- framer-motion
- huggingface
- machine-learning
- natural-language-processing
- nextjs
- opencv
- pyscenedetect
- python
- pytorch
- react
- tailwindcss
- transformers
- typescript
- vercel
- vision-transformer
- yt-dlp


Log in or sign up for Devpost to join the conversation.