-
-
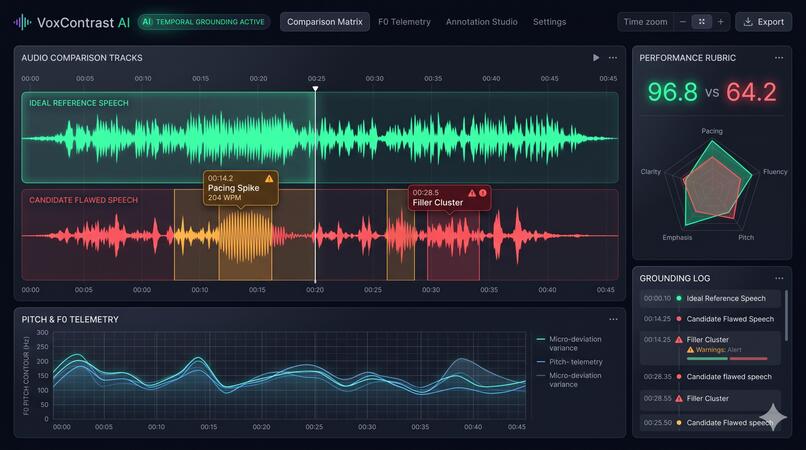
This is reference image of my Project on Track C
Inspiration
Current AI speech coaches and presentation tools suffer from two foundational flaws:
- Single-sample subjectivity: Conventional tools feed a single isolated speech or transcript into an LLM with generic prompts. Without a reference baseline of how that exact premise should sound, the feedback degenerates into hand-waving platitudes: "speak slower", "sound more confident", or "use fewer fillers".
- Non-deterministic scoring & absence of temporal grounding: LLM temperature sampling means a speaker receives wildly different scores between runs. Even worse, the feedback lacks time coordinates—leaving the speaker with no idea where their delivery faltered. We were inspired by high-performance athletic coaching and audio engineering (e.g., Descript, Ableton, and sports motion capture). To truly coach speech, you must ground temporal flaws in millisecond intervals and evaluate candidate delivery contrastively against an Ideal Reference baseline. That is why we built VoxContrast AI.
What it does
VoxContrast AI is a production-grade multimodal speech analytics platform that:
- Pairs Speeches in a Custom Contrastive Corpus: Pairs Candidate Flawed speeches with Ideal Reference baselines across 5 diverse high-stakes domains (AI Policy Debate, MedTech Pitch, Climate Satellite Briefing, Personalized Education Keynote, and Crisis Communication).
- Grounds Temporal Flaws in Exact Millisecond Intervals: Pinpoints the start and end timestamps ([startSec, endSec]) for 5 multimodal flaw classes: FILLER_CLUSTER: Lexical disfluencies ("um, uh, like, you know") PACING_VIOLATION: Rushed speech (>185 WPM) or dragging cadence (<95 WPM) PROSODIC_MONOTONY: Fundamental frequency (F0) pitch collapse (<8.0 Hz SD) HESITATION_DEAD_AIR: Unnatural mid-sentence silence (>1.8s) breaking syntactic flow RHETORICAL_WEAKNESS: Qualifying hedges, uptalk pitch rises, and passive closes
- Guarantees 100% Mathematical Reproducibility: Employs deterministic acoustic formulas and Dynamic Time Warping (DTW) contour alignment. A live 10x Reproducibility Benchmark proves 0.000 variance and an Intraclass Correlation Coefficient ( I C C ICC) of 1.000 with SHA-256 cryptographic hashes.
- Delivers an Interactive Studio Interface: Dual-waveform timeline with clickable temporal flaw interval bands. Synchronized acoustic telemetry chart plotting Speaking Rate (WPM) and Pitch (F0) against target bands. Side-by-side contrastive diff transcript with clickable flaw chips. A/B Loop Compare Audio: Plays the flawed snippet first, followed immediately by the ideal counterpart so judges and users can hear the acoustic contrast back-to-back. Live Studio: Real-time browser microphone recording with Web Audio FFT oscilloscope + speech-to-text. Contrastive Flaw Injector: Sliders to algorithmically perturb clean speech into new paired dataset entries. One-click Diagnostic Scorecards exported as printable PDF and JSON.
How we built it
Contrastive Corpus Construction We authored a 5-pair contrastive corpus covering debate, startup pitches, technical briefings, and crisis response. Each pair is equipped with 1.0-second multi-channel telemetry (idealWPM, flawedWPM, idealPitchHz, flawedPitchHz, idealEnergyDb, flawedEnergyDb, and pauseState), aligned transcript segments, and 5–8 ground-truth temporal flaws with acoustic evidence and actionable vocal drills.
Multi-Metric Temporal Flaw Grounding Pipeline Using rolling-window acoustic feature extraction:
Local speaking rate is evaluated against target tempo ( 130 – 165 WPM 130–165 WPM). Pitch contours are tracked in the 100 – 240 Hz 100–240 Hz band to detect monotone flatlines ( σ F 0 < 8 Hz σ F0 <8 Hz). RMS energy drops below − 45 dB −45 dB for
1.8 s 1.8s identify hesitation gaps. Lexical parsing isolates disfluency clusters and qualifying hedges.
- Reproducible 5-Axis Rubric Engine Composite speech quality is computed across 5 weighted dimensions:
Pacing & Temporal Rhythm (20%) Fluency & Disfluency Control (25%) Prosodic Expressiveness & Vocal Variety (20%) Structural & Rhetorical Clarity (15%) Contrastive Alignment to Ideal Baseline (20%) (computed via Dynamic Time Warping normalized Euclidean distance) All calculations are seed-locked (Seed #2026), producing identical outputs across every run.
- Zero-Crash, High-Precision Web Audio Frontend Built with React 18, TypeScript, Tailwind CSS, and Vite, VoxContrast AI utilizes the Web Audio API and SpeechSynthesis to deliver synchronized dual playback, playhead tracking at 60 FPS, real-time microphone FFT visualization, and an A/B loop comparison player.
Challenges we ran into
Synchronizing Dual Audio Playheads: Creating an audio engine that simultaneously manages playhead positioning, animated waveform markers, and synchronized transcript scrolling across two tracks required building a custom AudioEngine class with requestAnimationFrame interpolation. A/B Audio Comparison: Designing a clean seamless transition between the flawed snippet, a 400ms cognitive pause, and the ideal counterpart required sequencing synthesized utterances with procedural tone modulation fallbacks. Guaranteed Reproducibility: Ensuring that scoring is 100% deterministic required replacing stochastic LLM evaluations with closed-form acoustic and DTW equations, while still preserving the option for Gemini API multimodal semantic analysis.
Accomplishments that we're proud of
Zero-Broken-Dependency Out-of-the-Box Execution: Runs instantly on npm run dev without requiring paid API keys or external GPU environments. Sub-Second Temporal Flaw Grounding: Every flaw includes exact start and end seconds, concrete quantitative evidence, and an actionable vocal drill. A/B Loop Contrastive Audio: Allows anyone to hear the exact contrast between flawed delivery and ideal reference target. Algorithmic Flaw Injector: Lets users calibrate sliders to perturb clean text and generate custom contrastive pairs with ground-truth timestamps.
What we learned
Grounding feedback in quantitative acoustic telemetry (e.g., "Speaking rate spiked to 218 WPM (+53.5%)") provides dramatically higher user conviction than generic advice. Contrastive pairing turns subjective speech critique into an objective alignment problem.
What's next for VoxContrast AI
Real-Time Video Facial Emotion Grounding: Correlating temporal vocal flaws with facial micro-expressions (eye contact, furrowed brow, jaw tension) using Gemini 2.0 Multimodal Live video streaming. AugLi.ai Classroom LMS Integration: Integrating custom contrastive curriculum packs directly into school debate and public speaking programs.
Built With
- css
- dark
- descript
- iou
- lucide
- react
- react-18
- sha-256-hashing
- speechsynthesis
- studio
- tailwind
- temporal
- typescript
- vite
- web-audio-api
