-
-
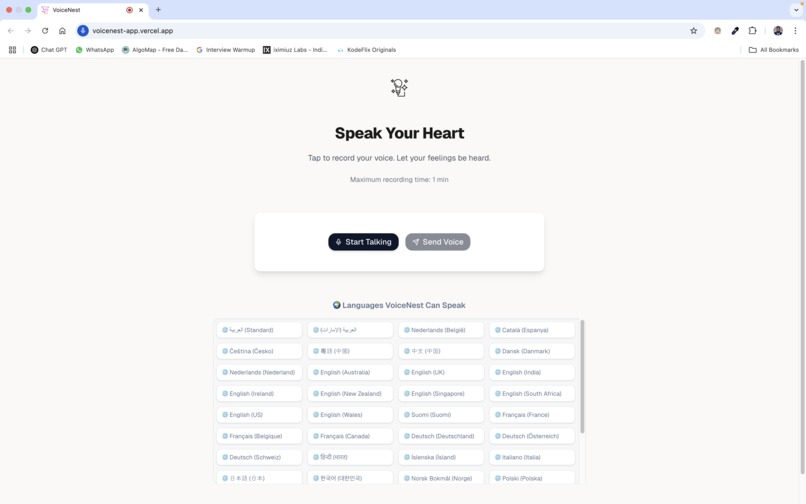
Landing Page
-
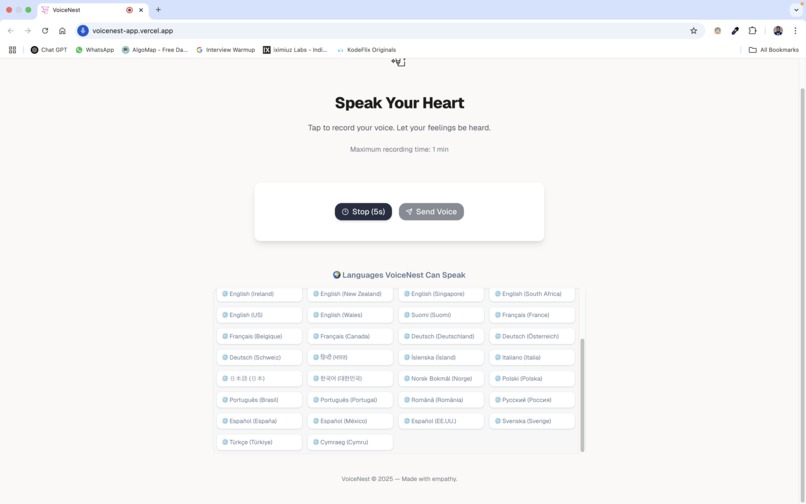
Voice Recording
-
Recorded Audio Sent for Processing
-
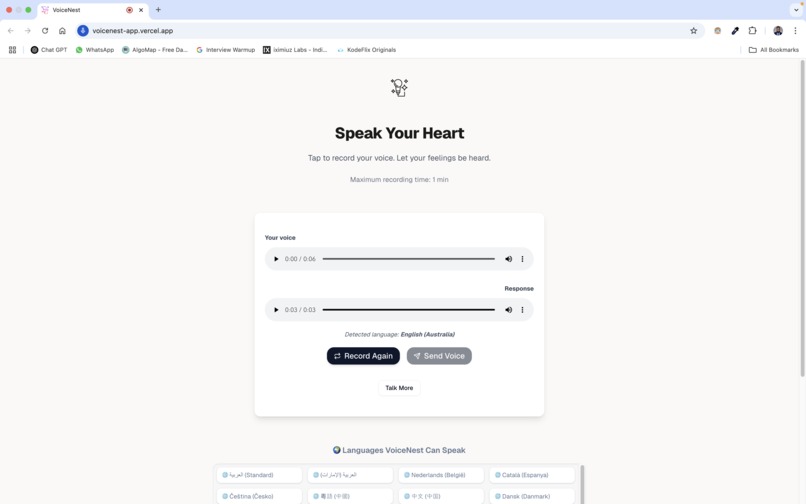
Response from VoiceNest Serverless Lambda
-
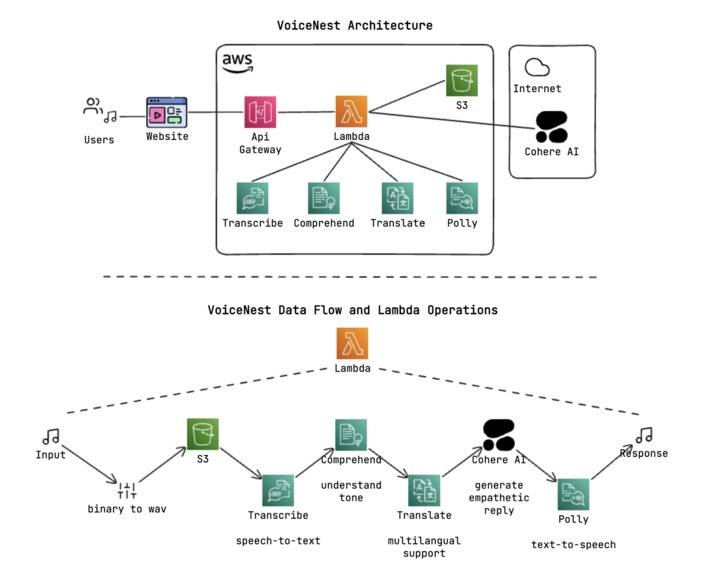
Architecture and Operations


Inspiration
VoiceNest was inspired by the rising challenge of emotional loneliness in elderly individuals. Many live alone and find modern digital tools overwhelming. We wanted to create something simple, natural, and comforting — where the user only needs their voice to feel connected, heard, and emotionally supported.
What it does
VoiceNest enables elderly users to:
- 🗣️ Speak naturally by recording their voice
- 🧠 Get a thoughtful, AI-generated response with emotional awareness
- 🌐 Receive replies in their own language
- 🎧 Listen back to both their voice and the AI’s reply
It’s a truly voice-first interface — no typing, no complexity — with support for over 40 languages and sentiment detection.
How we built it
- Frontend: Built with Next.js 14, shadcn/ui, Framer Motion, and MediaRecorder API for recording and playback.
- Backend: Triggered via API Gateway into AWS Lambda, which:
- Transcribes audio (Amazon Transcribe)
- Detects language and sentiment (Amazon Comprehend)
- Translates input/output as needed (Amazon Translate)
- Generates empathetic replies (Cohere
command-r-plus) - Synthesizes voice (Amazon Polly)
- Fully serverless infrastructure provisioned via Terraform, with CI/CD using CodePipeline and CodeBuild.
Challenges we ran into
- Recording audio in proper format from frontend
- Ensuring natural-sounding Polly voices across different languages
- Managing fallbacks when Polly didn’t support a language
- Syncing user voice and AI reply playback smoothly
- Handling short, emotionally vague inputs in a meaningful way
Accomplishments that we're proud of
- 🎉 Built and deployed a fully serverless voice AI app
- 💡 Runs entirely within the AWS Free Tier
- 🌍 Supports multilingual conversation for global accessibility
- 🧓 Focused on elderly-friendly design with minimal interaction steps
- 🚀 All code and infrastructure written during the Hackathon window
What we learned
- Building a voice-to-voice AI experience is more complex than text workflows
- Properly orchestrating AWS services in Lambda takes precision
- Cohere’s LLM can match tone and emotion effectively when guided
- UI feedback and loading states are key for trust in voice-based UX
What's next for VoiceNest
- 🎭 Add emotion-based voice tones using Polly SSML
- 📈 Store conversation history and sentiment over time
- 📱 Launch a mobile-first PWA for real-world deployment
- 📴 Support offline fallback using IndexedDB
- 🤝 Explore partnerships with senior care organizations and retirement homes
Built With
- amazon-api-gateway
- amazon-comprehend
- amazon-dynamodb
- amazon-polly
- amazon-transcribe
- amazon-translate
- amazon-web-services
- aws-codebuild
- aws-codepipeline
- aws-iam
- aws-lambda
- aws-ssm-parameter-store
- bash
- cohere-command-r-plus
- css
- framer-motion
- github
- html
- lucide-react
- mediarecorder-api
- next.js-14
- react
- shadcn/ui
- terraform
- typescript
- vercel
- wav-encoding

