- Project Story (Markdown Content) 🎯 Inspiration Standard text-based LLMs are incredible, but they create a "typing tax" for students. When you're stuck on a complex calculus derivative like $$ \frac{d}{dx}(\sin(x^2)) $$ or trying to understand a physics force diagram, describing it in text is a barrier to learning.
We built VisionTutor to replicate the experience of sitting next to a real human tutor. We wanted an AI that looks at your handwritten notes, hears your voice, and responds instantly—allowing you to interrupt the moment you get confused, just like you would in a real classroom.
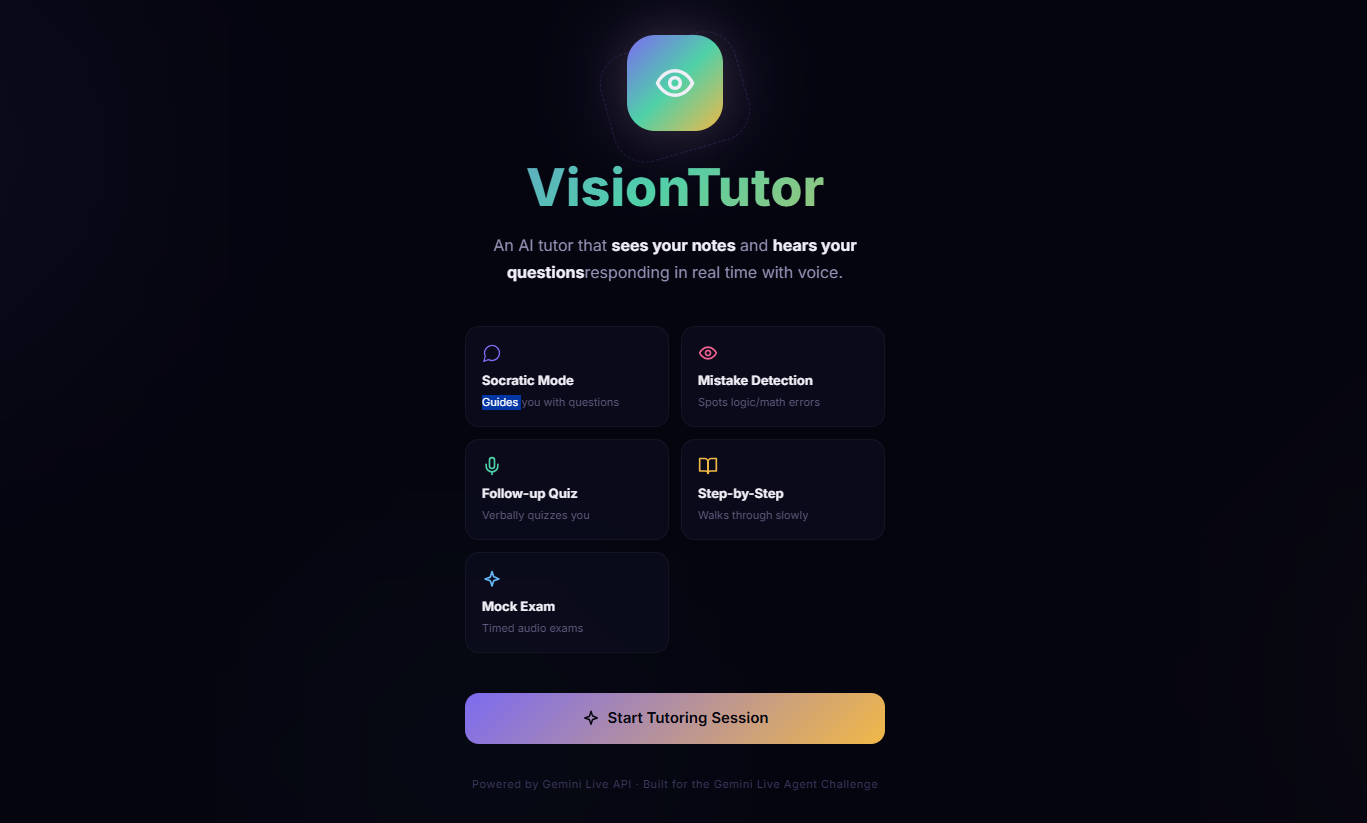
💡 What it does VisionTutor is an immersive, real-time AI study agent that moves beyond the chat box.
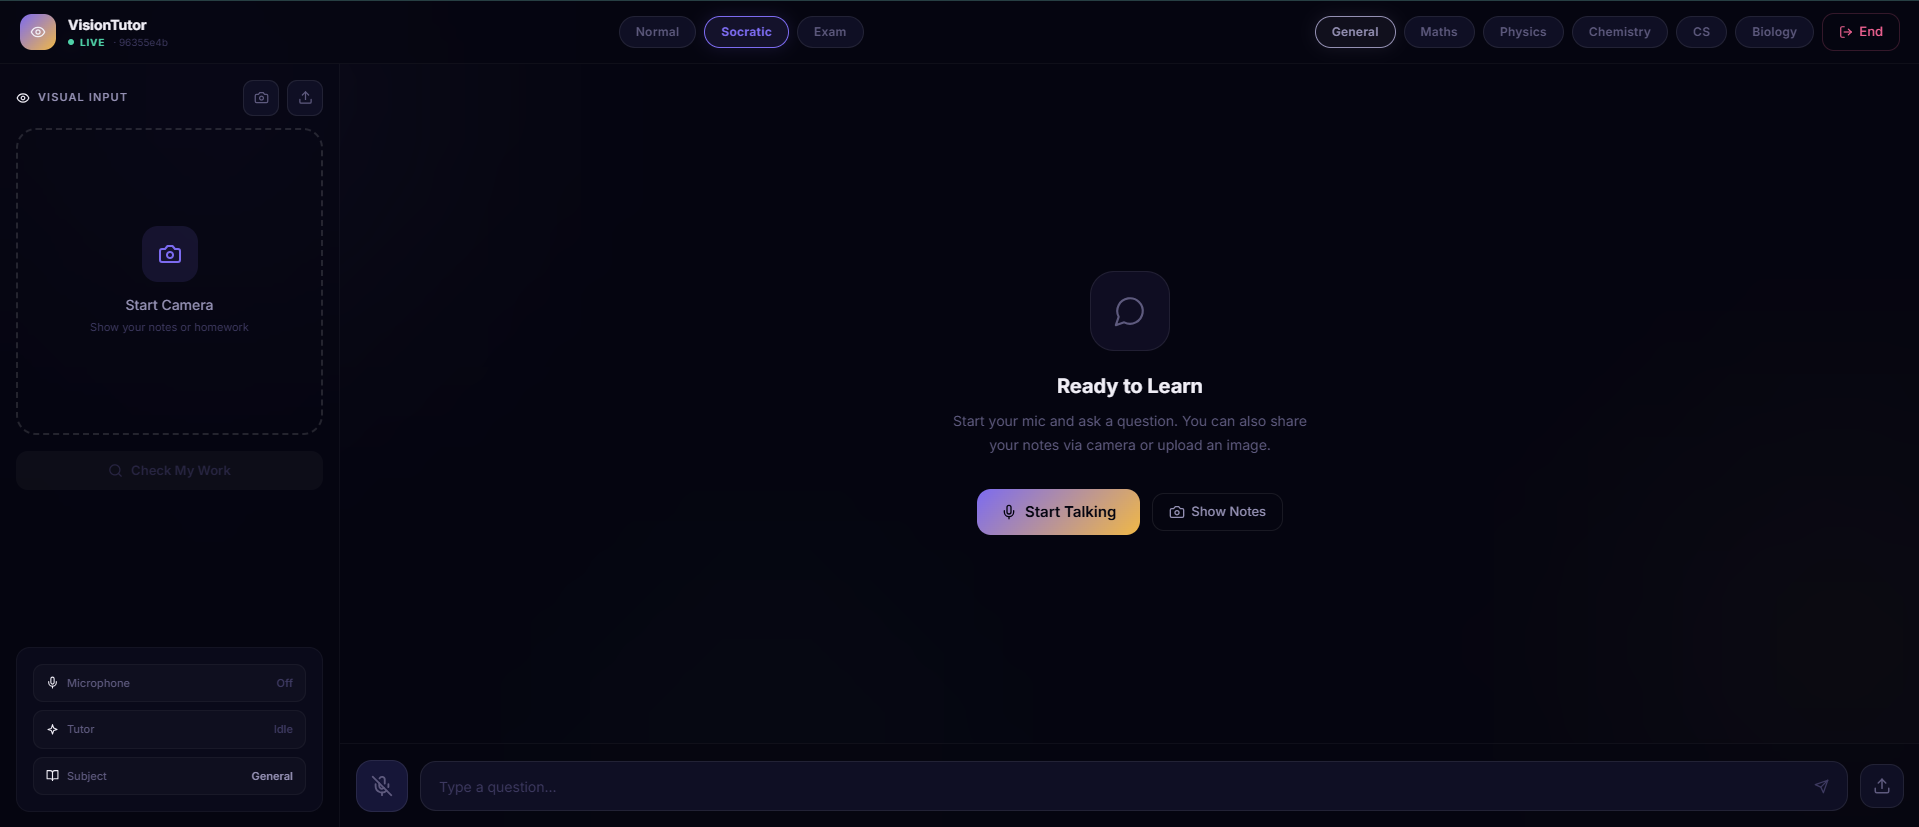
Multimodal Real-time Interaction: It simultaneously processes PCM audio from your mic and 1fps video frames from your webcam using the Gemini 2.5 Flash Native Audio Preview. 🧠 Socratic Mode: Instead of giving answers, it uses "Guided Discovery" to lead students to the solution via strategic questions. 🔍 mistake Detection: You can click "Check My Work," and Gemini scans your visible written steps to pinpoint the exact line where a calculation went wrong. 👣 Step-by-Step Walkthroughs: It breaks down complex solutions and pauses after every step, waiting for user confirmation before moving on. 📝 Exam Mode: A full mock exam experience where the tutor reads questions, listens to your verbal answers, and provides a structured feedback report at the end. 🏗️ How we built it The project is built on a high-performance streaming architecture:
Backend (Python/FastAPI): We used the google-genai (v1.5.0) SDK to maintain a bidirectional WebSocket connection. The backend acts as a secure proxy, managing session state and dynamic system prompt injections for different tutoring modes. Frontend (Next.js/React): A custom Glassmorphic UI that handles raw Web Audio API processing. We convert 16kHz microphone input to Int16 PCM and perfectly schedule incoming 24kHz audio buffers from Gemini to ensure zero-stutter playback. Deployment: Containerized with Docker and deployed on Google Cloud Run for scalable, low-latency execution. 🧠 Challenges we ran into WebSocket Synchronization: Managing the flow of raw binary audio chunks alongside JSON metadata (transcripts/interruptions) required a very robust handler to prevent race conditions. The "Stutter" Problem: Early versions had robotic audio. We had to implement a precise nextPlayTimeRef scheduling system in JavaScript to buffer chunks ahead of the browser's audio clock. Prompt Engineering for Voice: Since Gemini responds via native audio, we had to strictly instruct it not to use markdown or bullet points in its internal logic, as it would literally try to "speak" the punctuation! 🎓 What we learned We learned that the future of education isn't just "Better LLMs"—it's better interfaces. By removing the keyboard, we saw how much more naturally a student engages with the material. We also gained deep experience with the nuances of the Gemini Live API, specifically handling barge-in (interruptions) and visual context windowing.
🔮 What's next for VisionTutor We plan to implement Canvas Drawing Mode, allowing students to draw math equations directly on screen with a stylus, and Session Memory, allowing the tutor to remember your progress across multiple weeks of study.
Built With
- apis:-gemini-live-api-(gemini-2.5-flash-native-audio)-sdks:-google-genai-python-sdk-(v1.5.0)-web:-next.js
- deployment
- fastapi
- google-artifact-registry-devops:-docker
- powershell/bash
- react
- tailwind-css
- web-audio-api-backend:-python-3.11
- websockets-cloud:-google-cloud-run

Log in or sign up for Devpost to join the conversation.