Inspiration
I frequently listen to audio horror stories to help me fall asleep. However, I realized that producing these immersive audiobooks is incredibly time consuming. There is a significant gap in the market for tools that can generate a complete audiobook entirely from scratch using just plain text. Traditional production requires immense effort for voice acting, sourcing sound effects, and manually aligning tracks during editing. I wanted to build a solution that automates this entire tedious process, allowing creators to focus purely on the story.
What it does
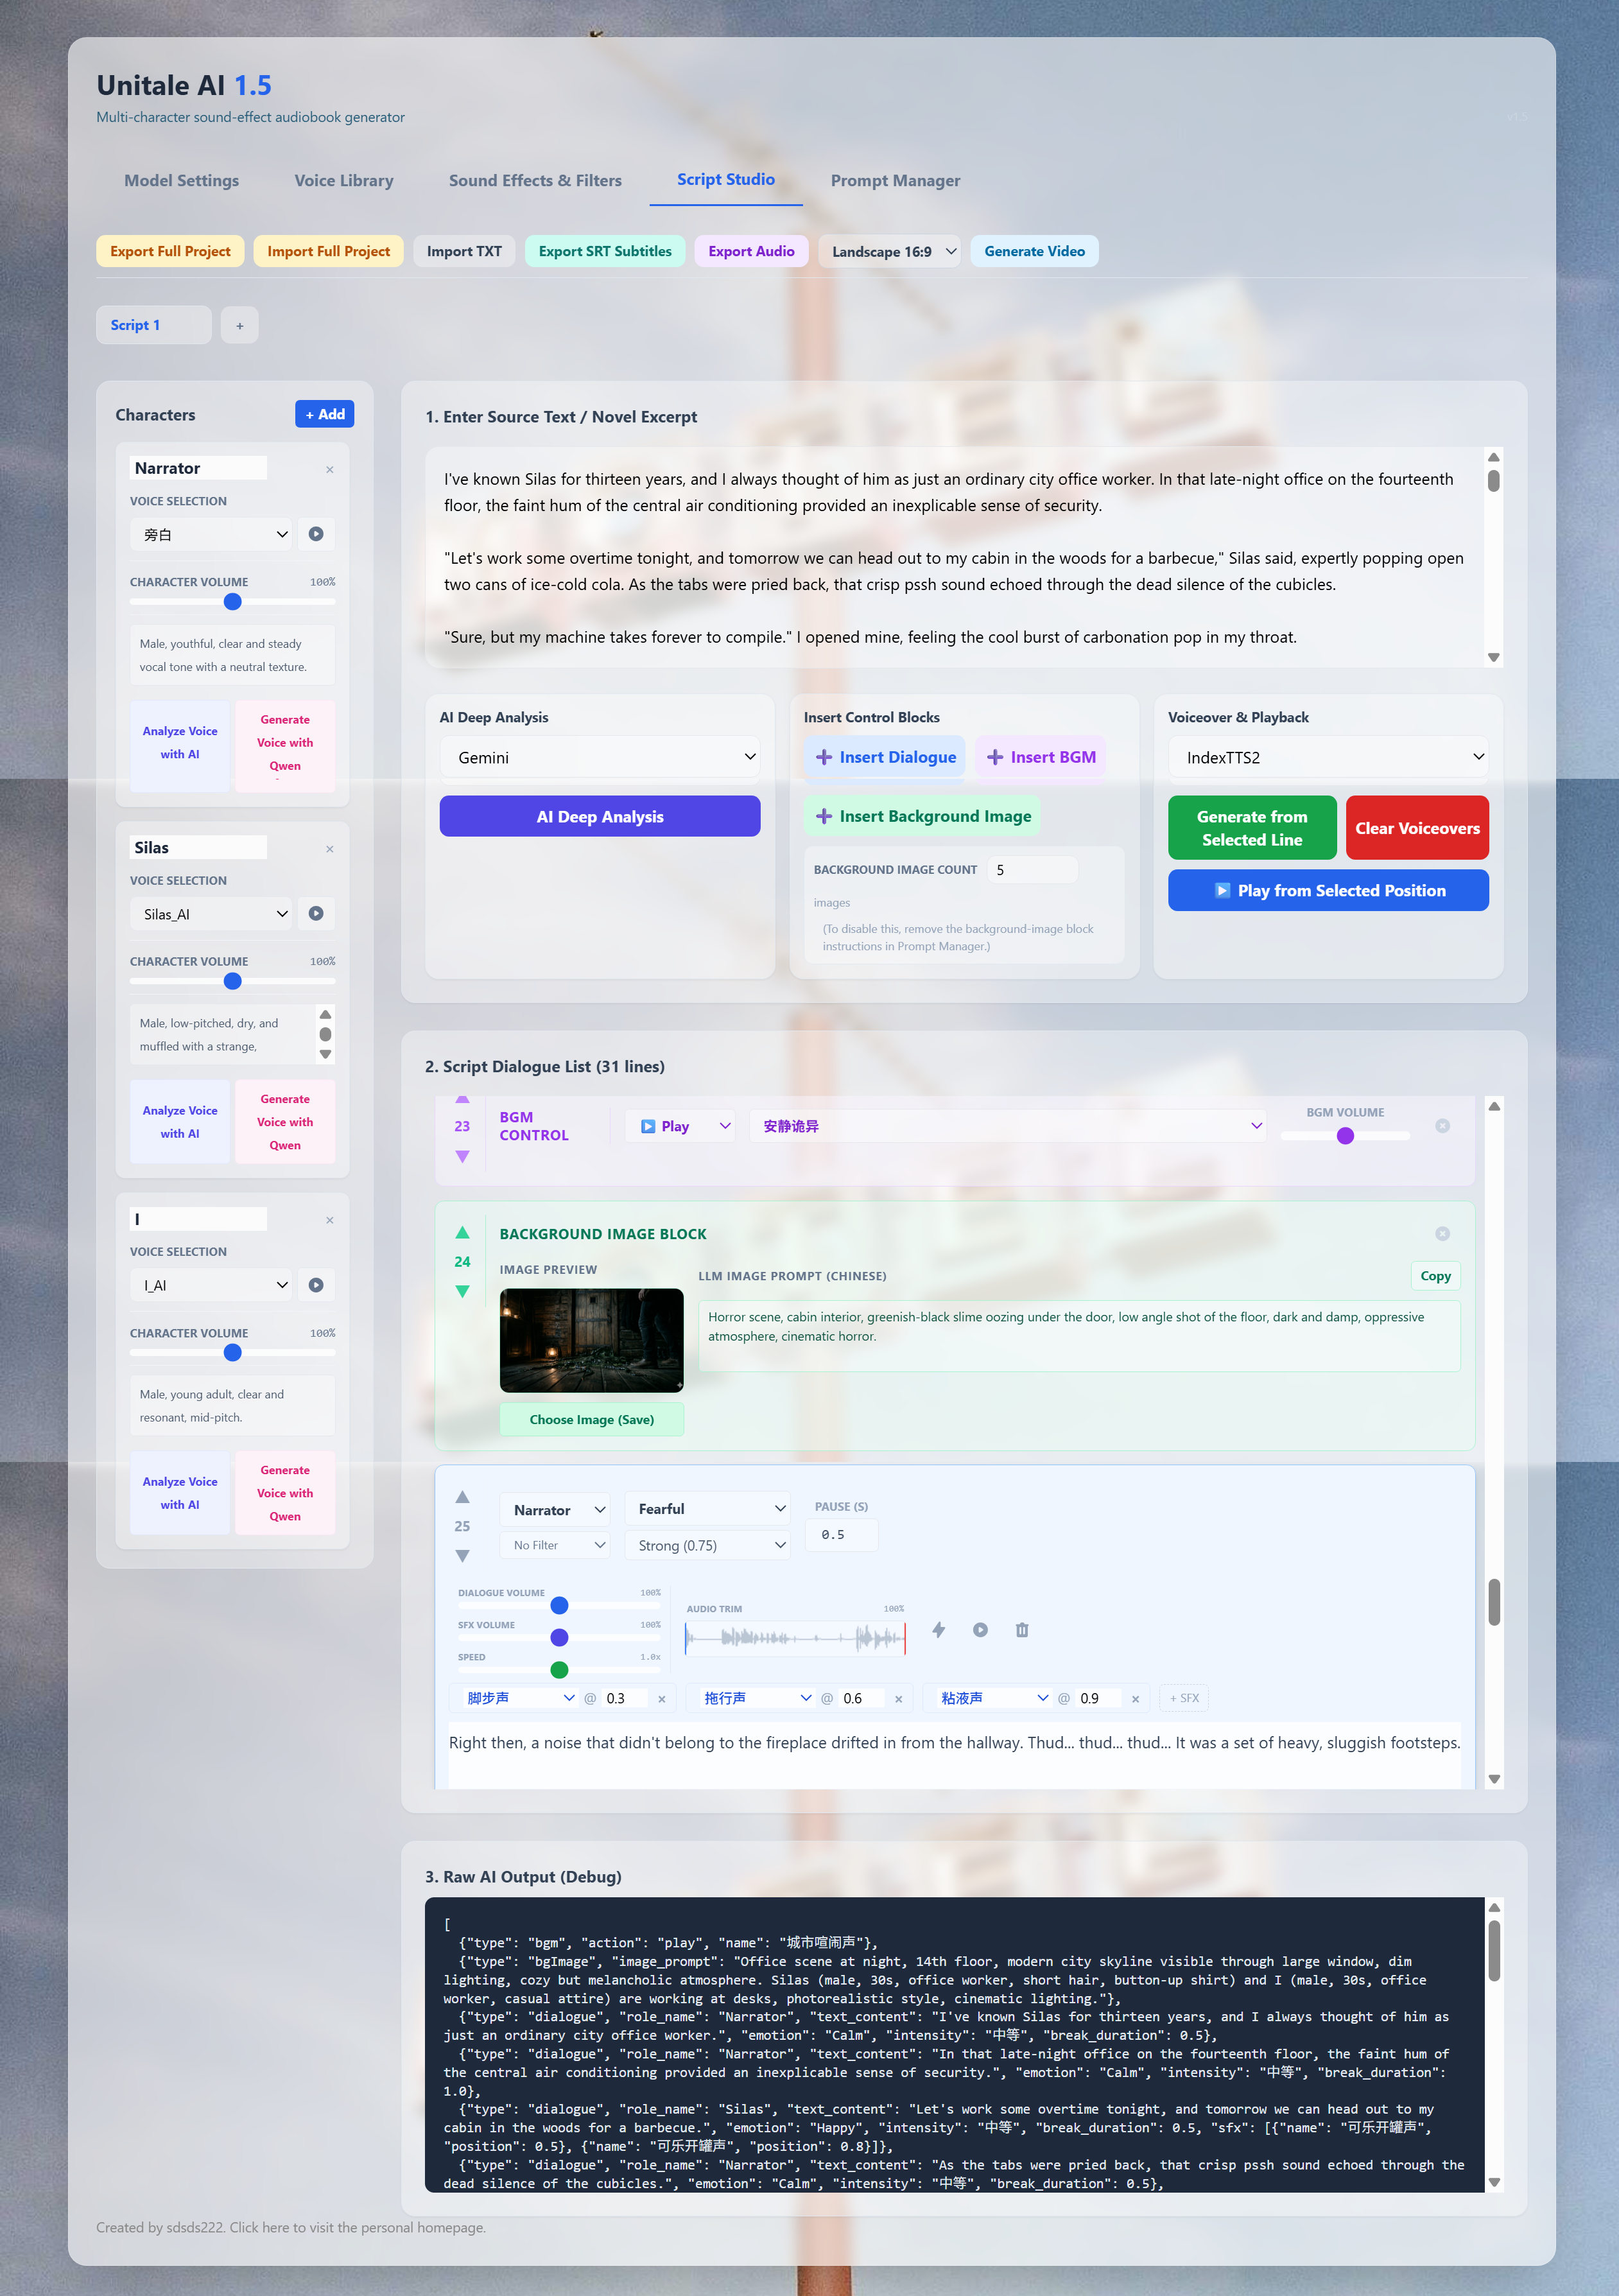
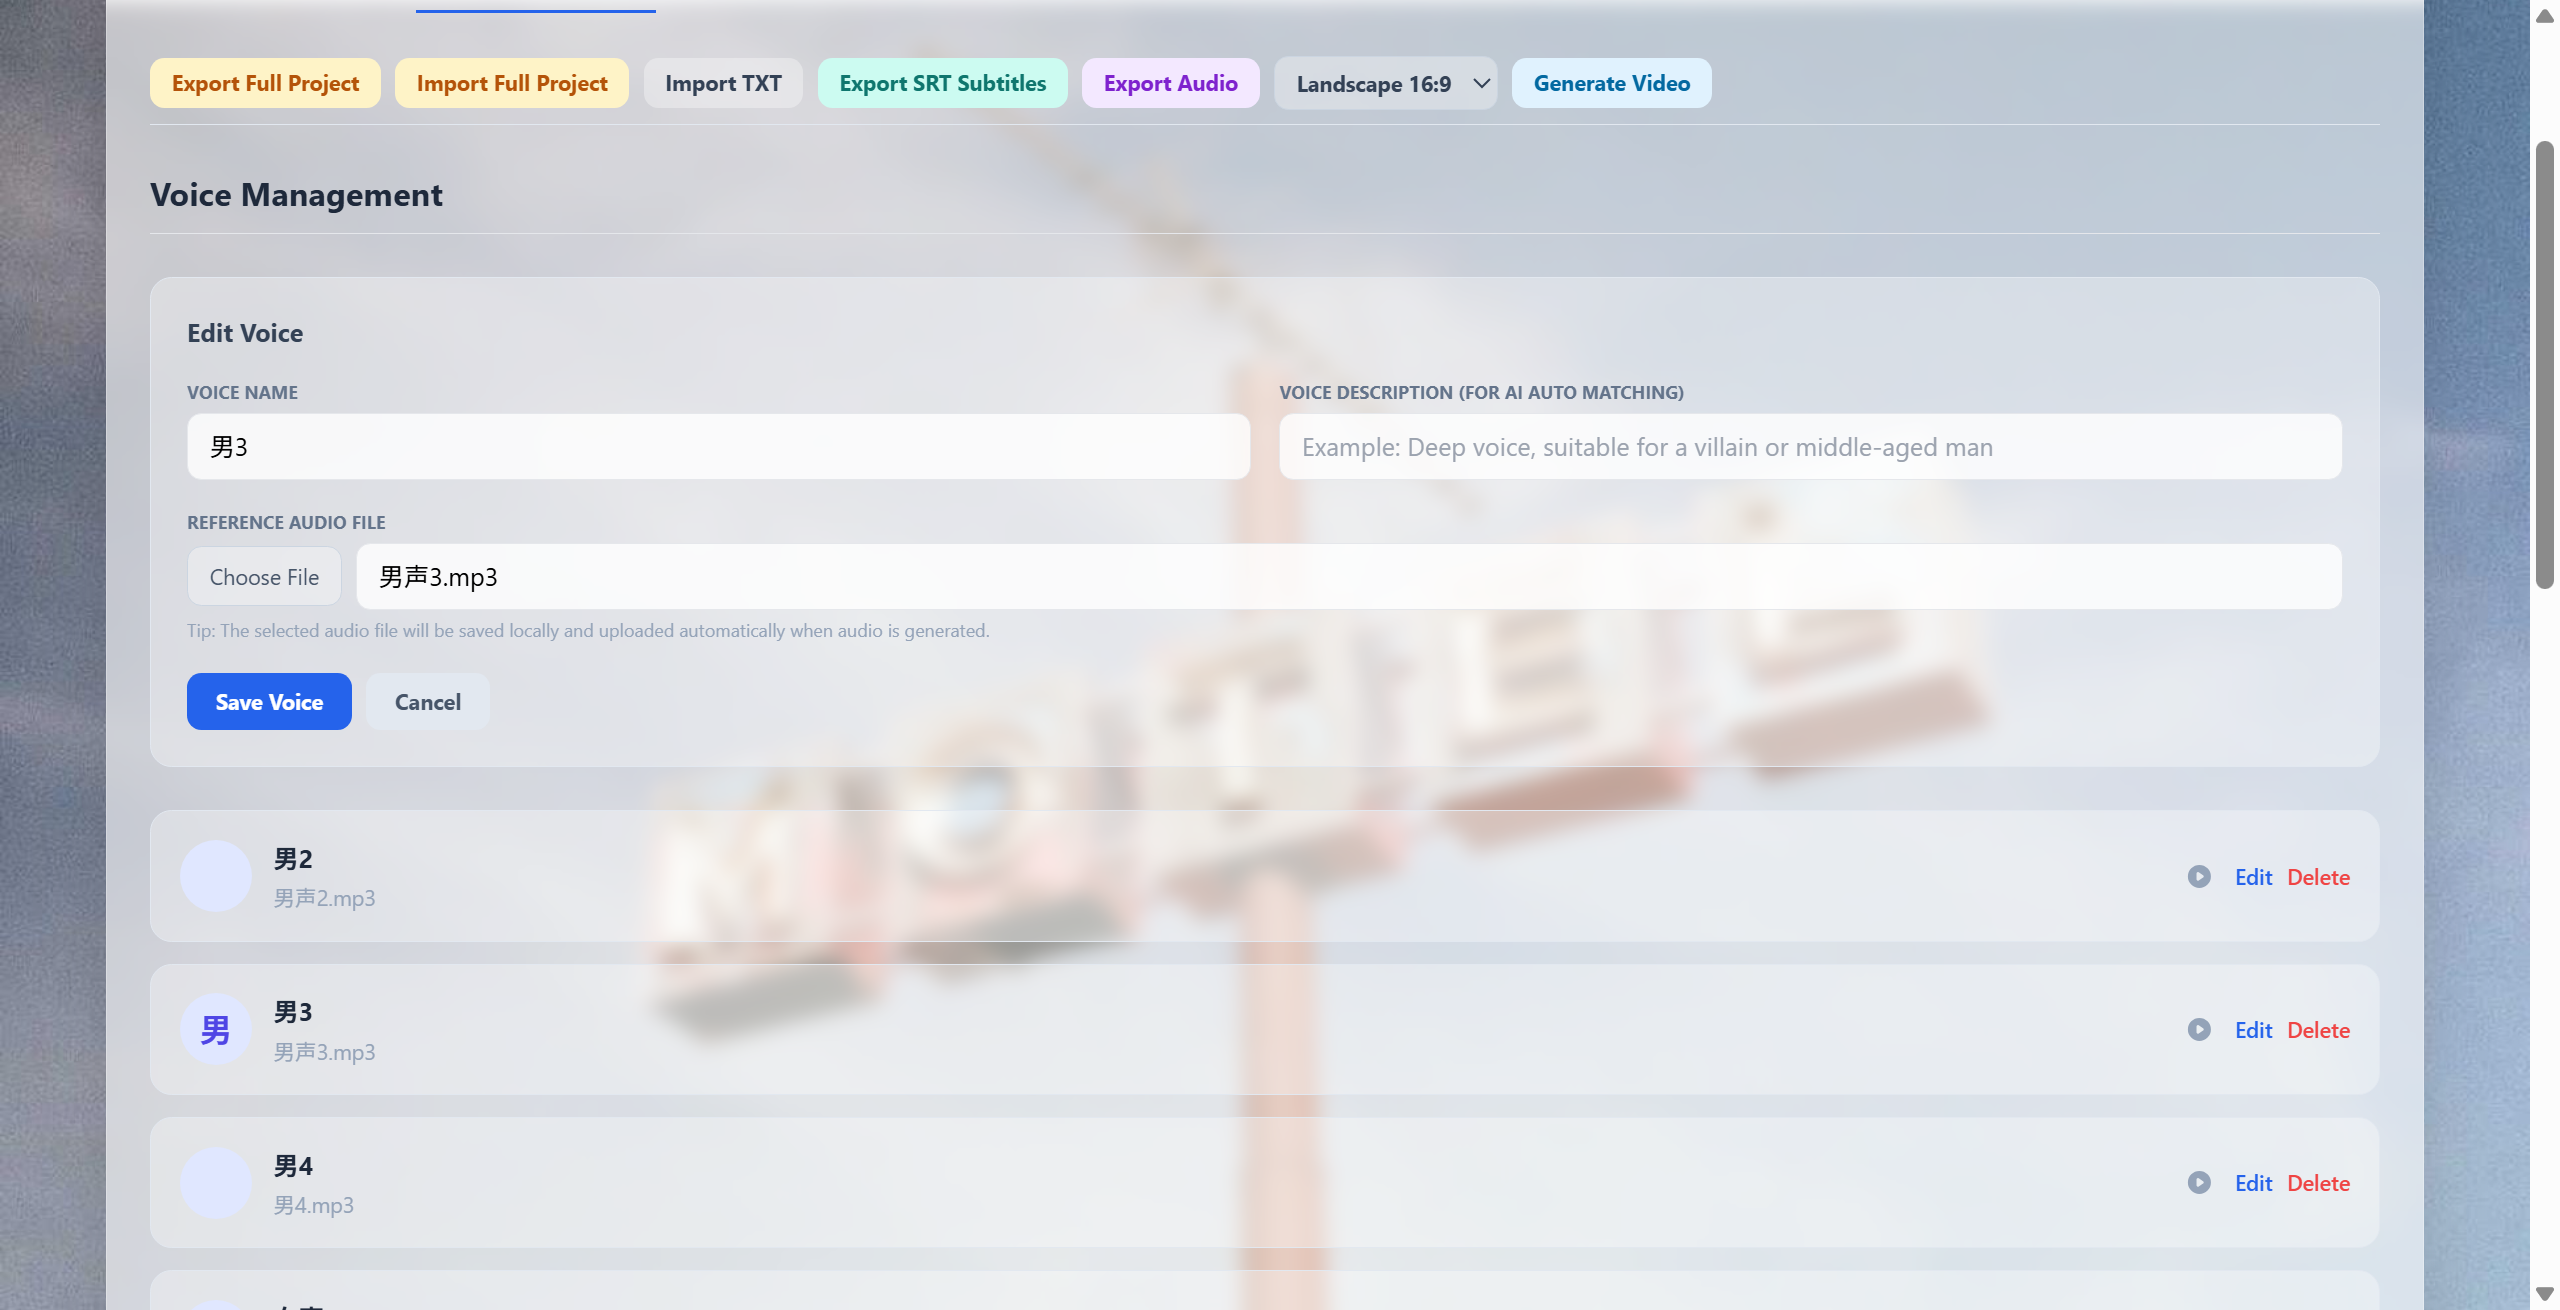
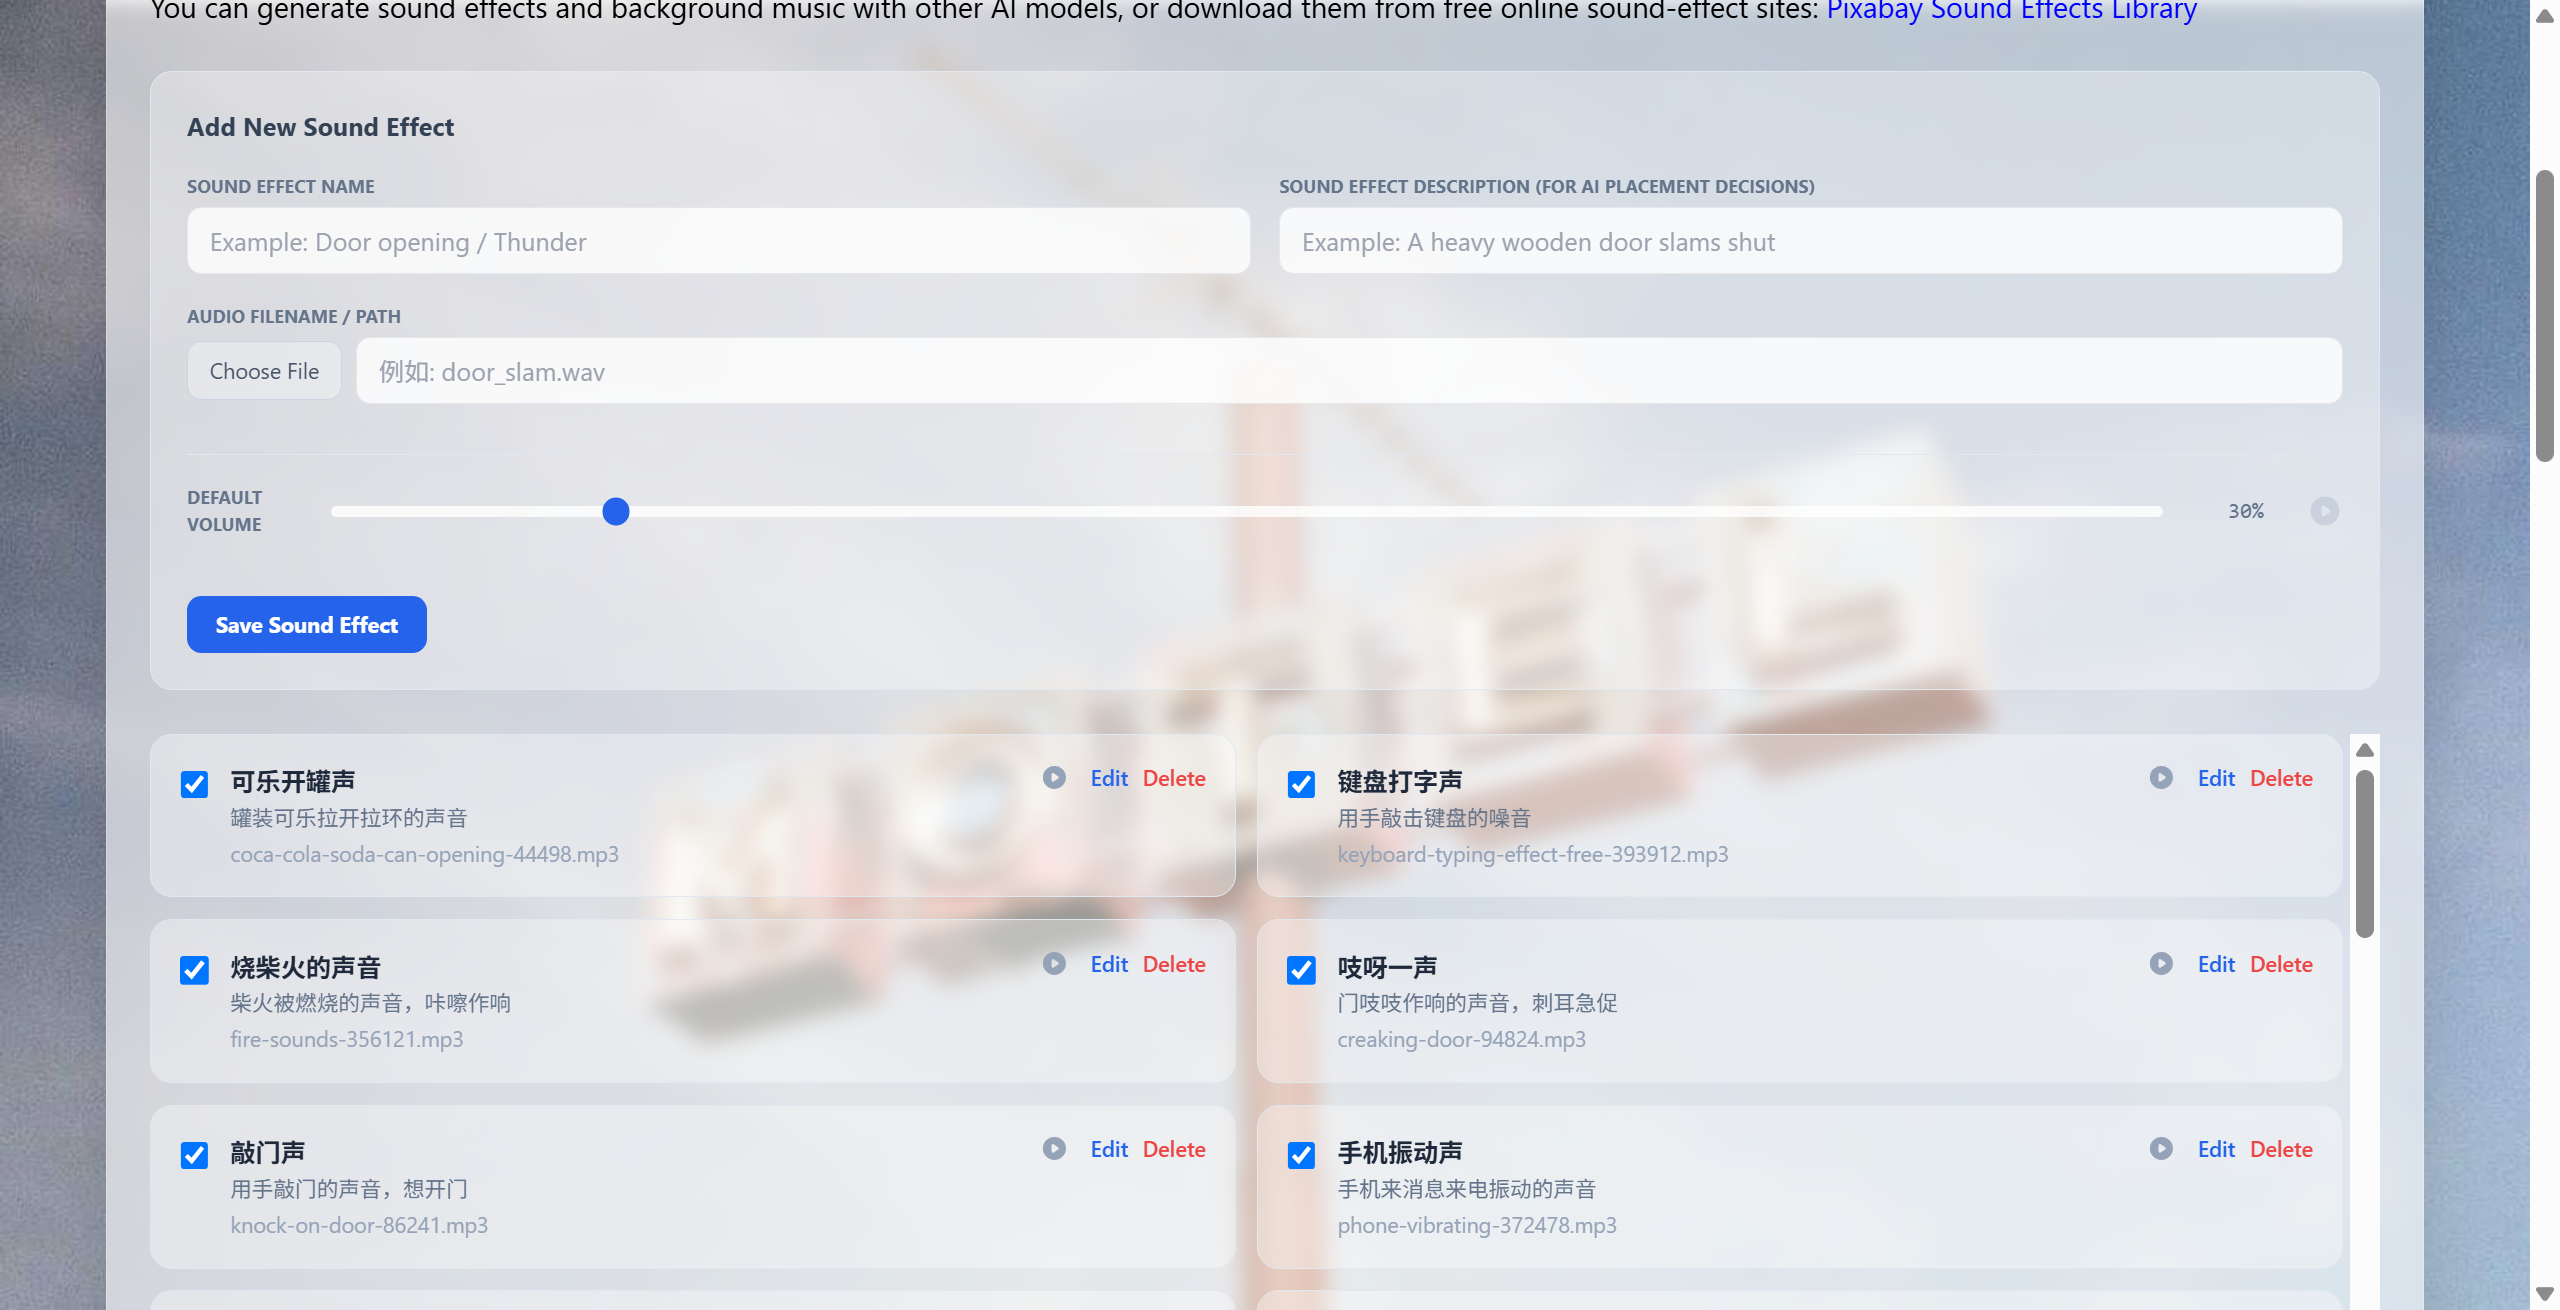
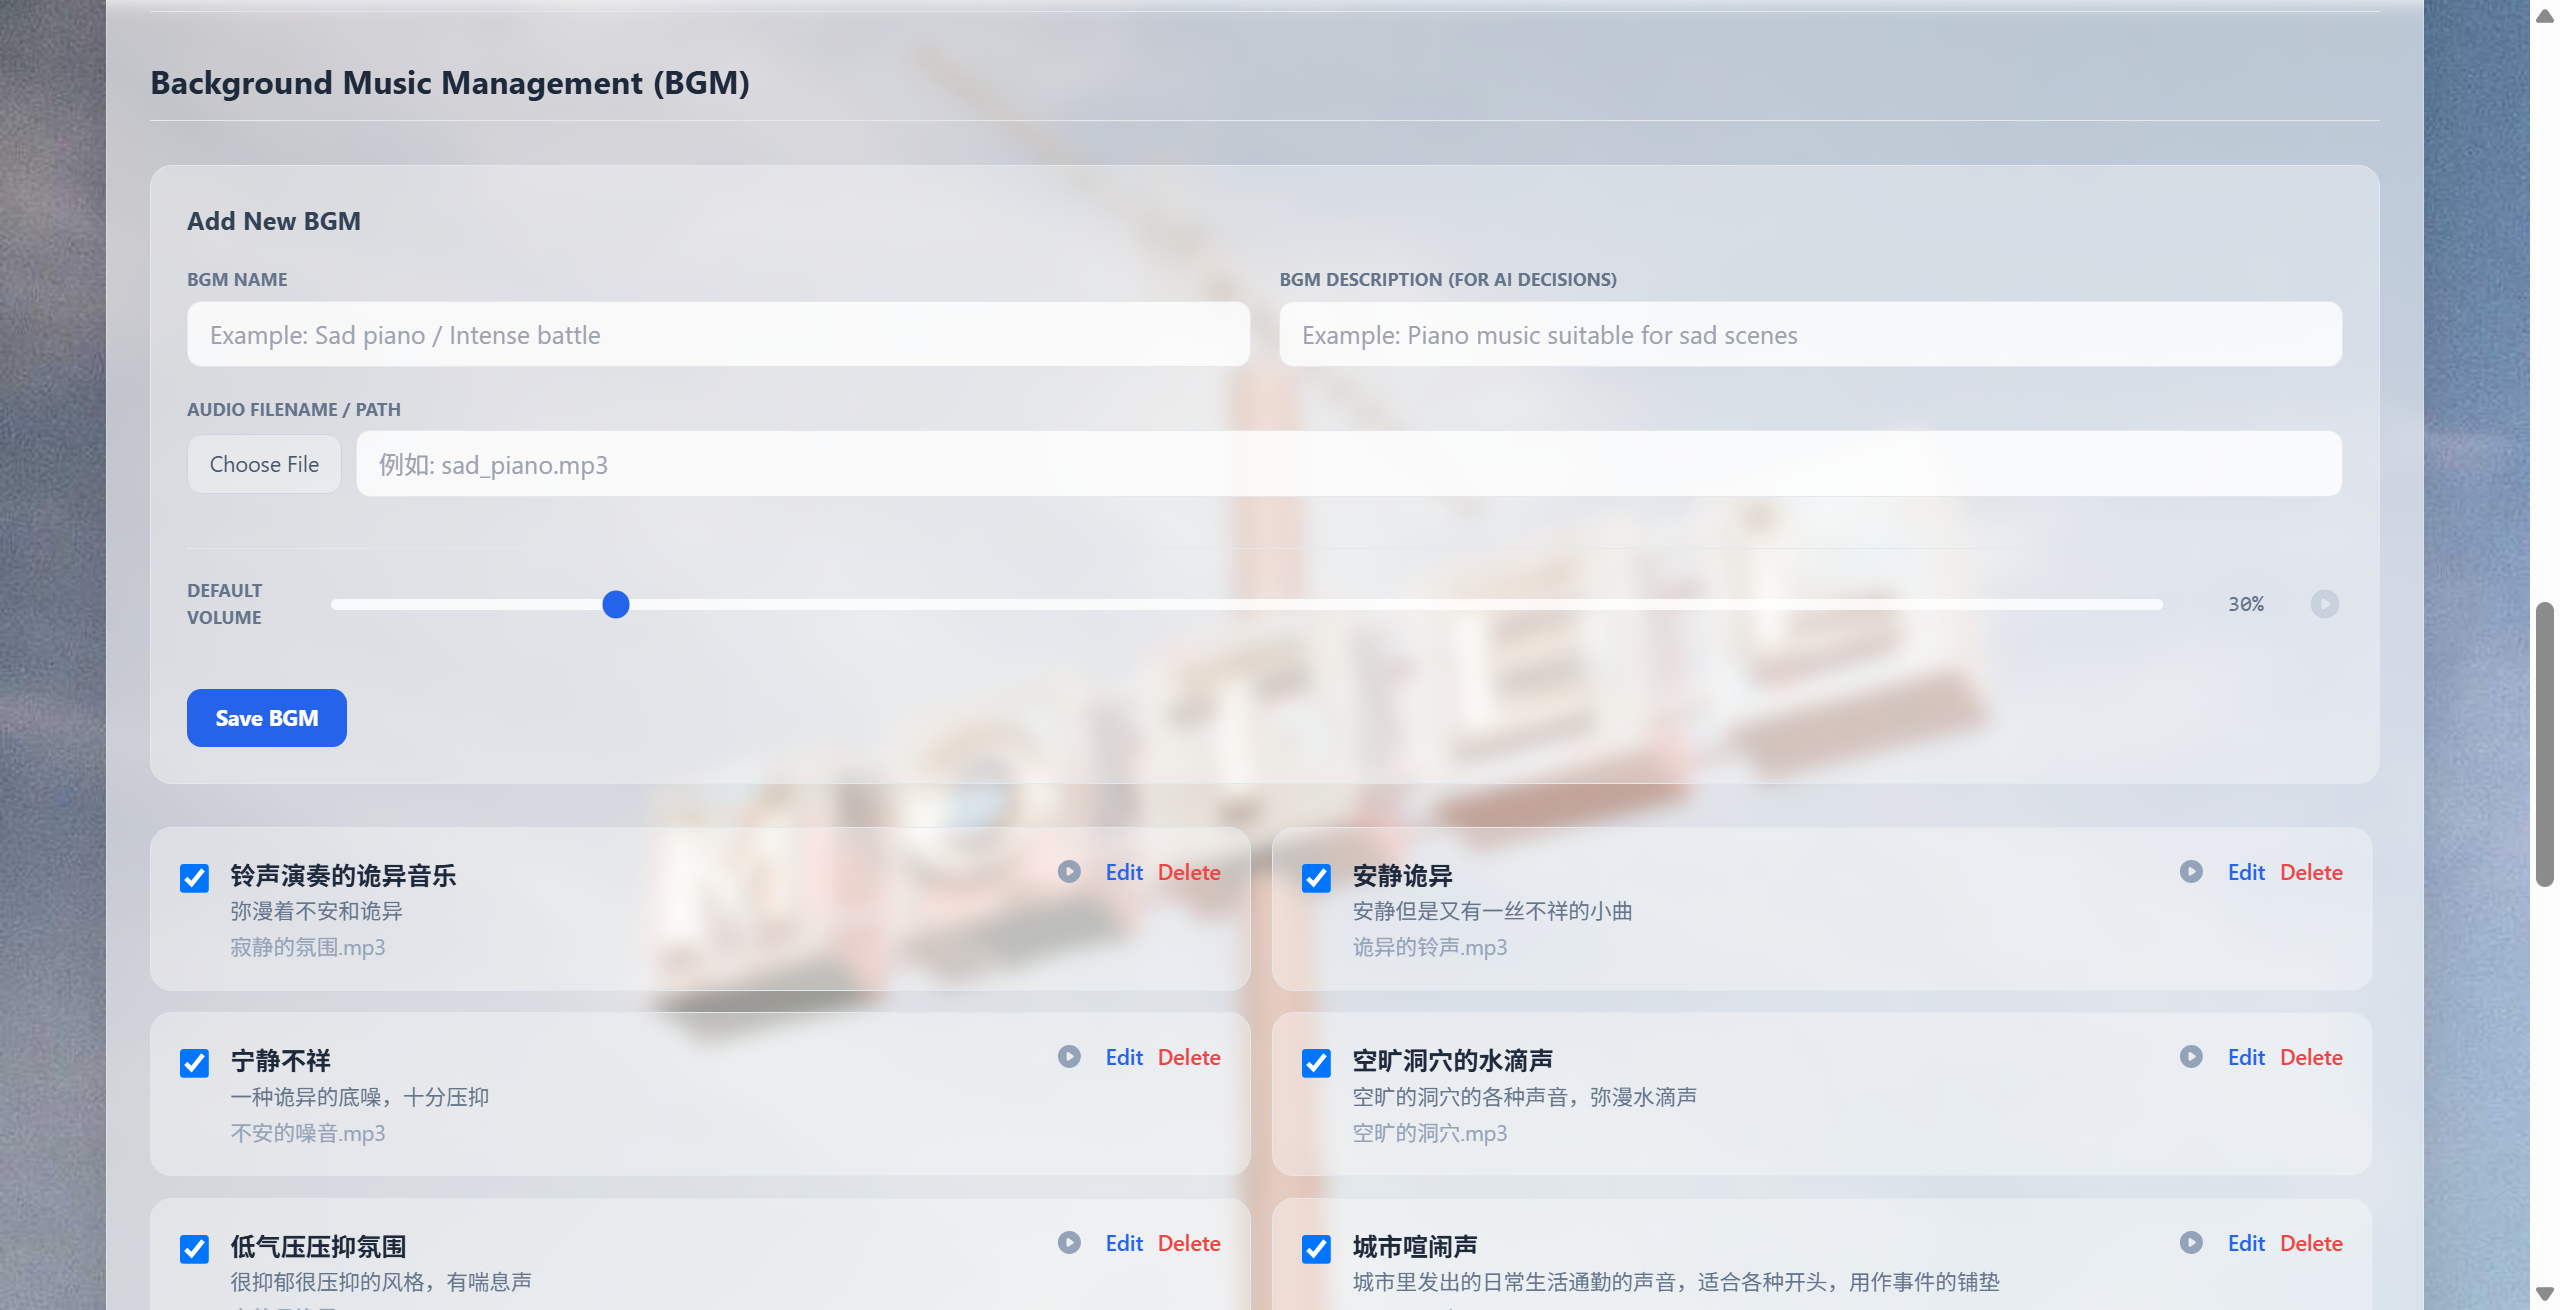
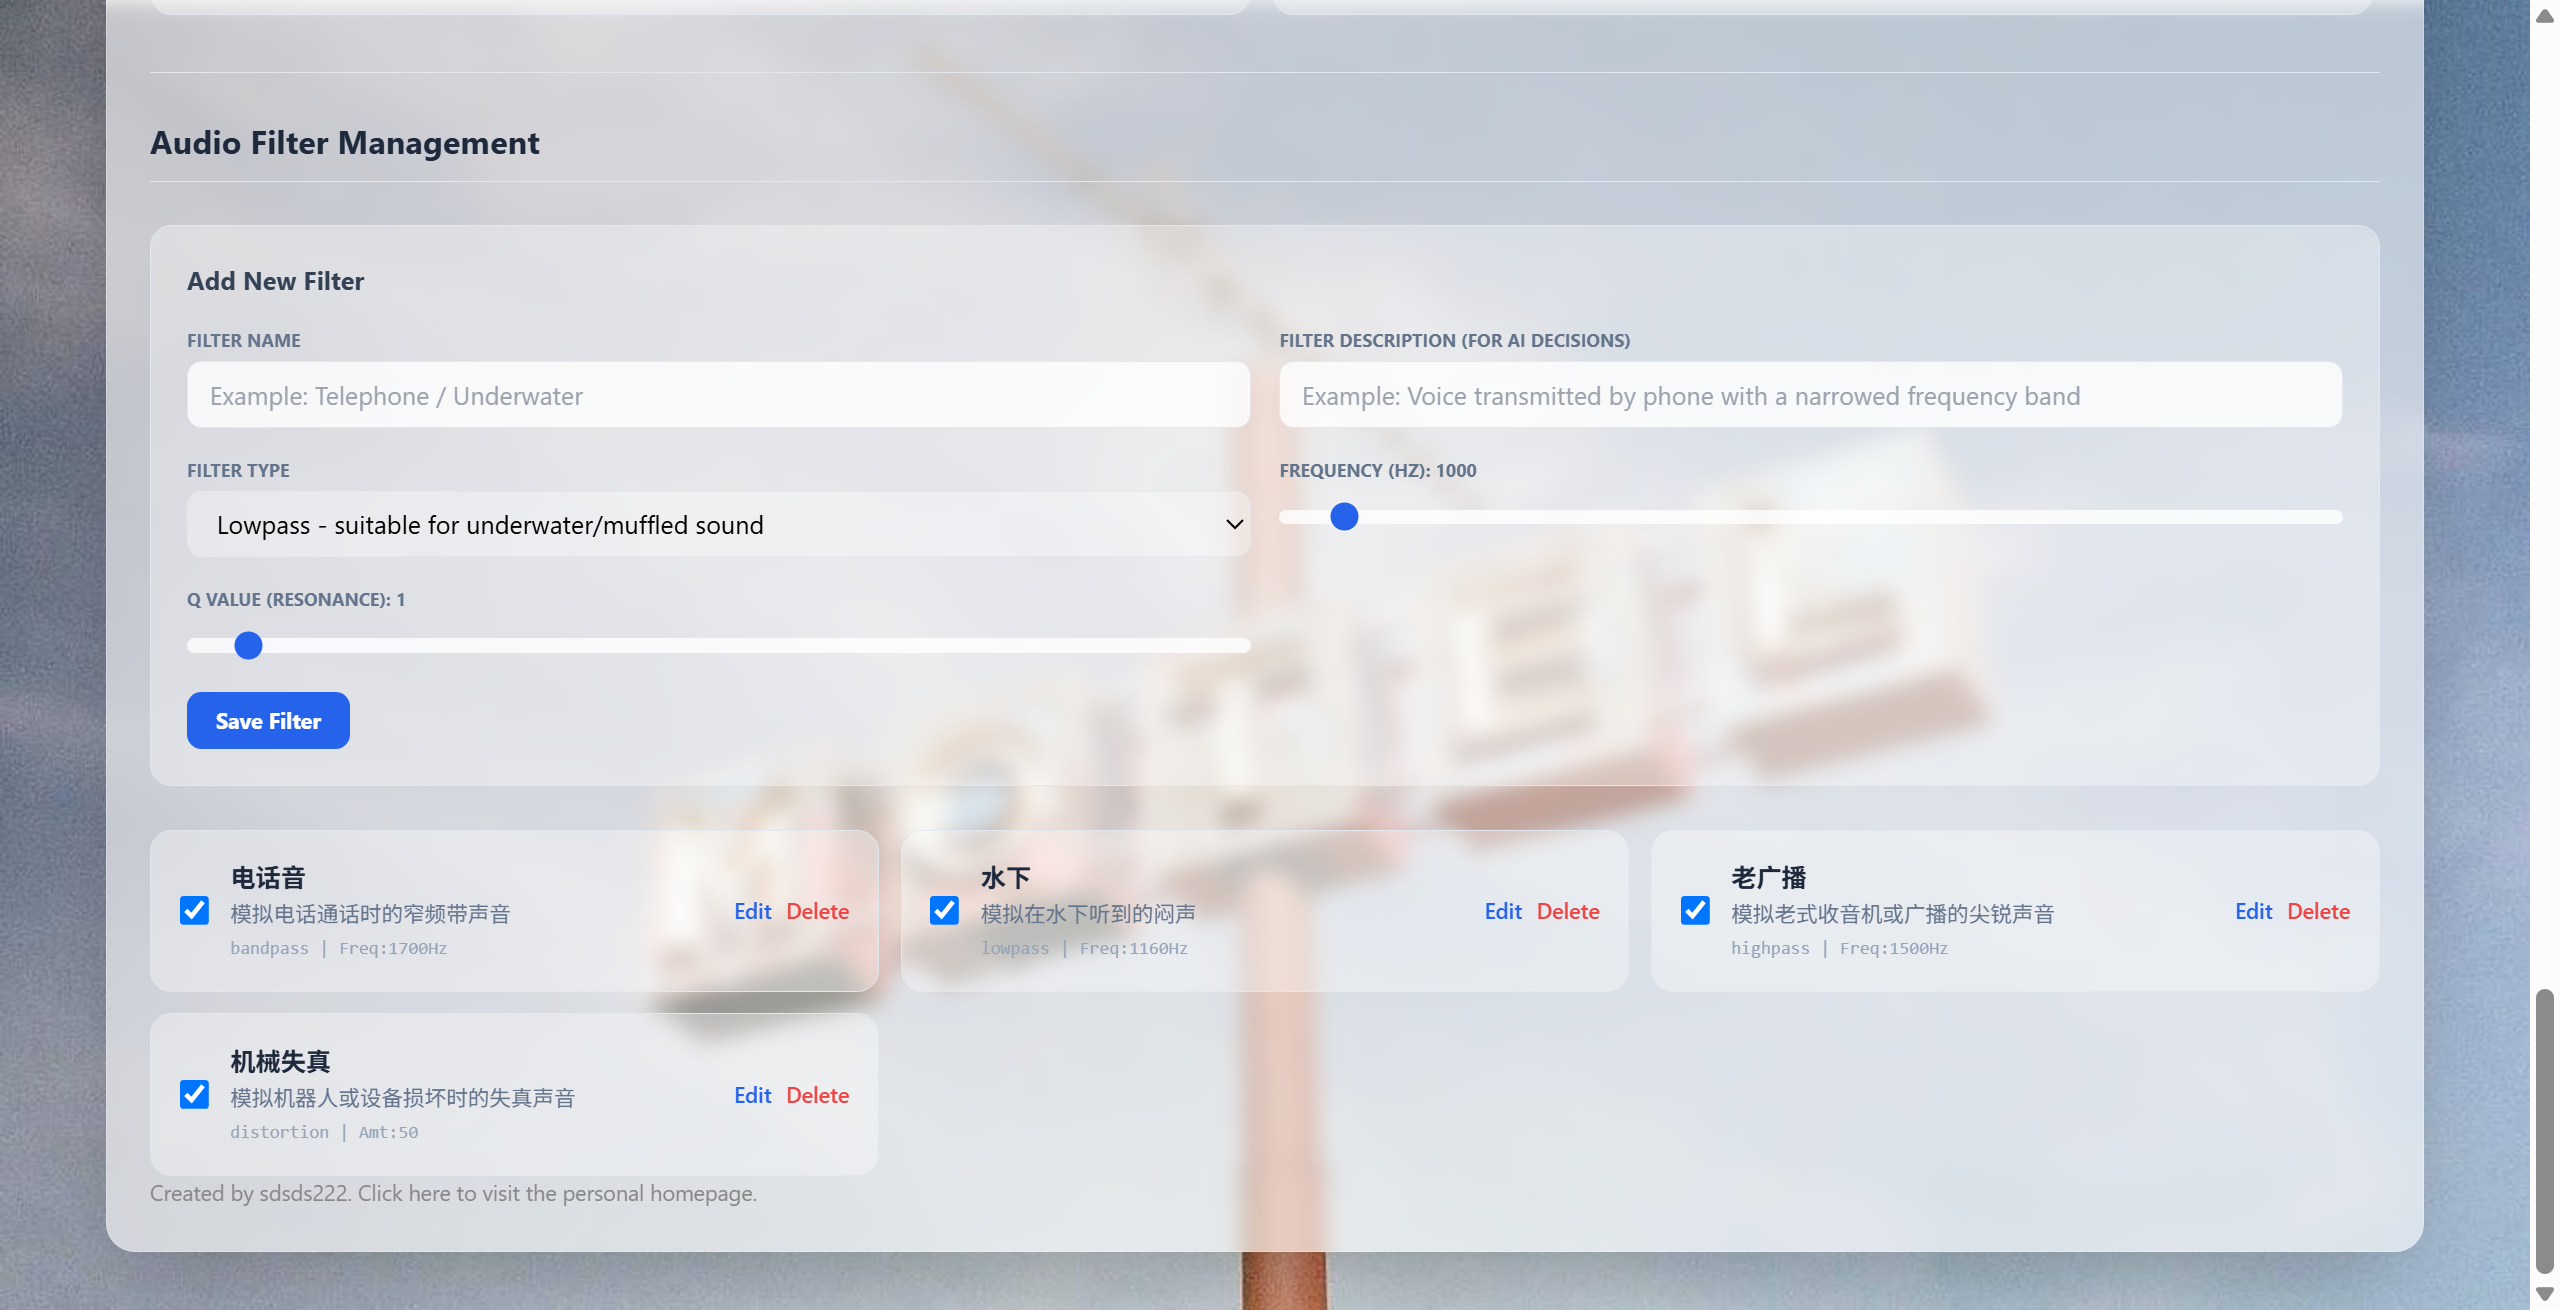
Unitale AI AudioStory Studio is an end to end, fully automated audiobook production tool. Starting from a plain text script, the system uses LLMs to automatically analyze characters and generate custom voice descriptions. It then handles the complete orchestration of dialogue, automatically matching and inserting sound effects (SFX), background music (BGM), and environmental reverb. Finally, it outputs prompt descriptions for video backgrounds, allowing users to easily create complete MP4 audiovisual stories with zero manual track alignment.
How we built it
Frontend: The user interface was built using JavaScript and the Vue framework to create a smooth, browser based experience. Backend: Powered by FastAPI for robust and fast API handling. AI Models: We integrated Qwen3TTS and IndexTTS2 for high quality audio generation. Due to local hardware limitations, the heavy backend audio generation models were deployed on the CNB cloud native platform.
Challenges we ran into
The biggest hurdle was hardware limitations. My local machine lacked the necessary Vedio RAM to run these large AI models simultaneously. To solve this, I migrated the backend to the CNB cloud native platform. However, keeping heavy models loaded concurrently still risked Out Of Memory errors. I had to engineer a custom scheduling script that dynamically loads and unloads the Qwen3TTS model from the GPU whenever it is not actively being used, successfully preventing Vedio RAM crashes.
Accomplishments that we're proud of
I am incredibly proud of achieving a truly "one click" pipeline. Successfully integrating LLM character analysis, TTS generation, and dynamic audio mixing (SFX, BGM, and reverb) into a cohesive workflow without requiring any manual editing or track alignment is a massive milestone. Overcoming the severe GPU memory constraints with a custom dynamic loading script is also a major technical win that ensures the tool runs stably.
What we learned
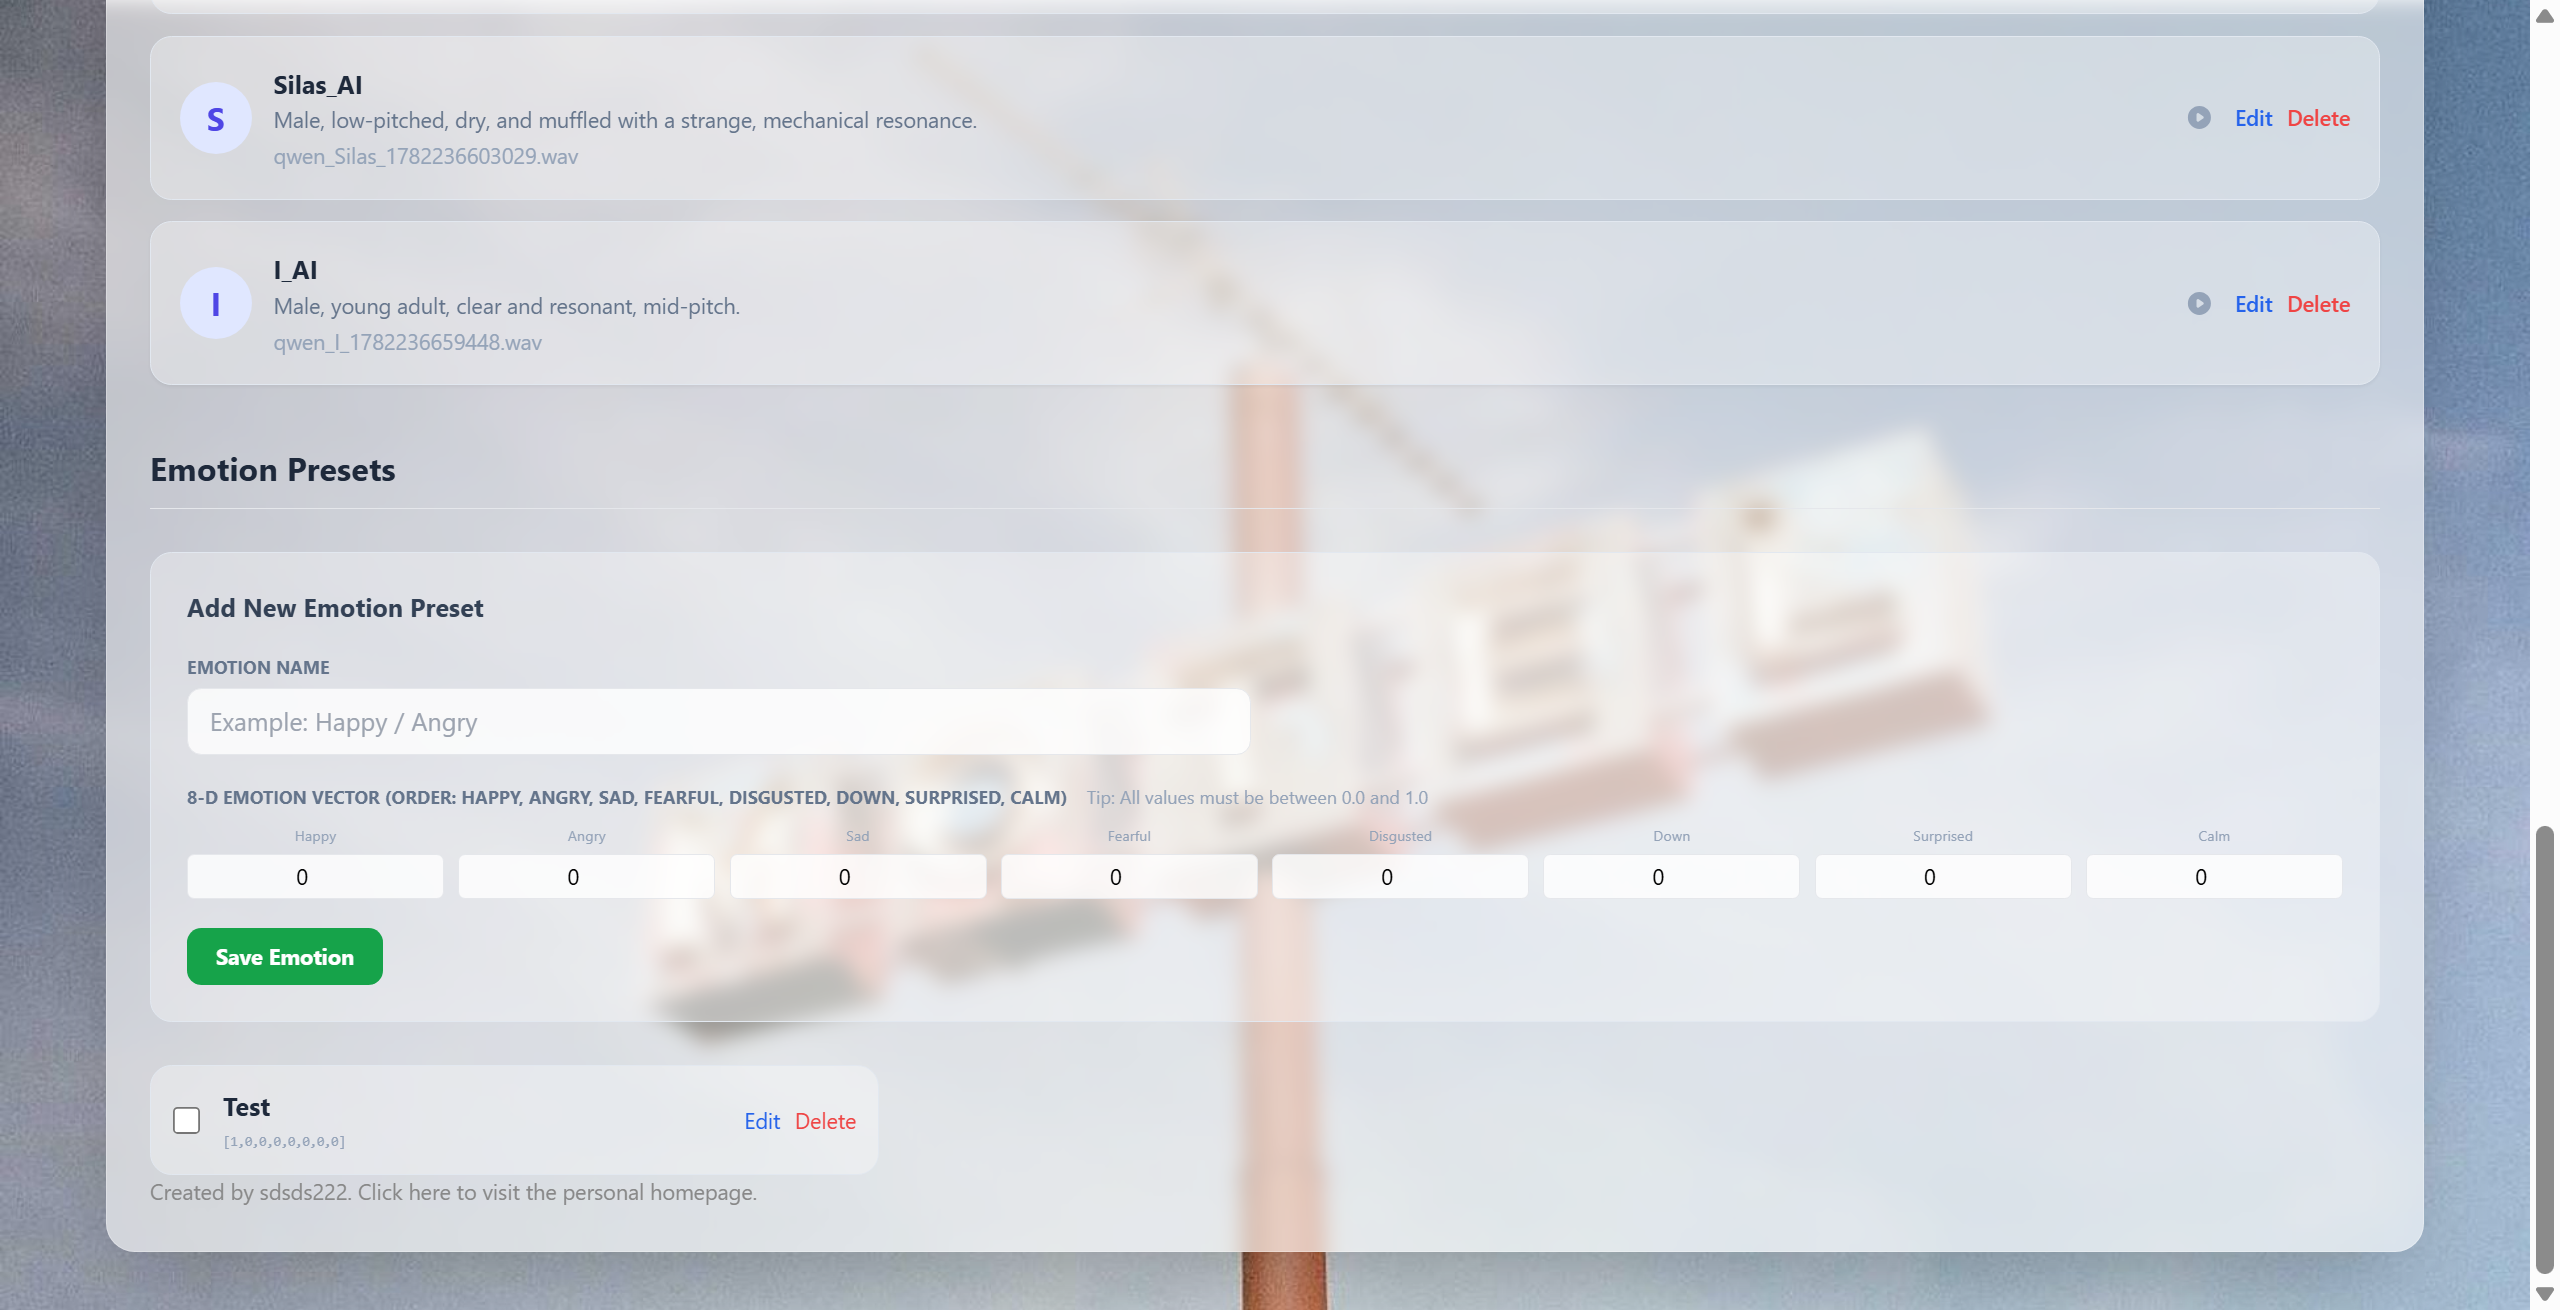
Through experimenting with multiple TTS models, I recognized the inherent limitations of current generative TTS engines, particularly regarding voice cloning and emotional control. I learned that most mature TTS models struggle to accurately perform fine tuning on emotional nuances while simultaneously maintaining a high quality cloned voice.
What's next for Unitale AI AudioStory Studio
Currently, the system relies on a user provided local library for matching SFX and BGM. The next major evolution is to integrate AI audio and music generation models directly into the pipeline. This will allow the system to dynamically synthesize completely original sound effects and background music entirely based on the situational context of the dialogue, achieving a 100% generative audio production experience without needing any external asset libraries.
Built With
- css3
- fastapi
- html5
- indextts2
- javascript
- python
- qwen3tts
- vue


