-
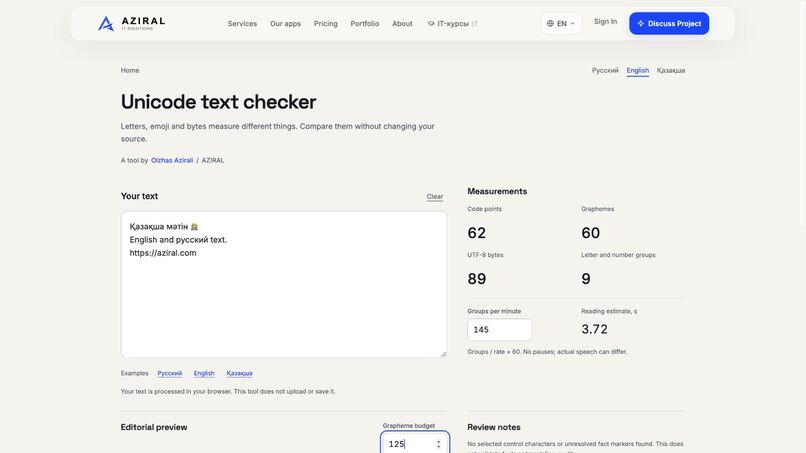
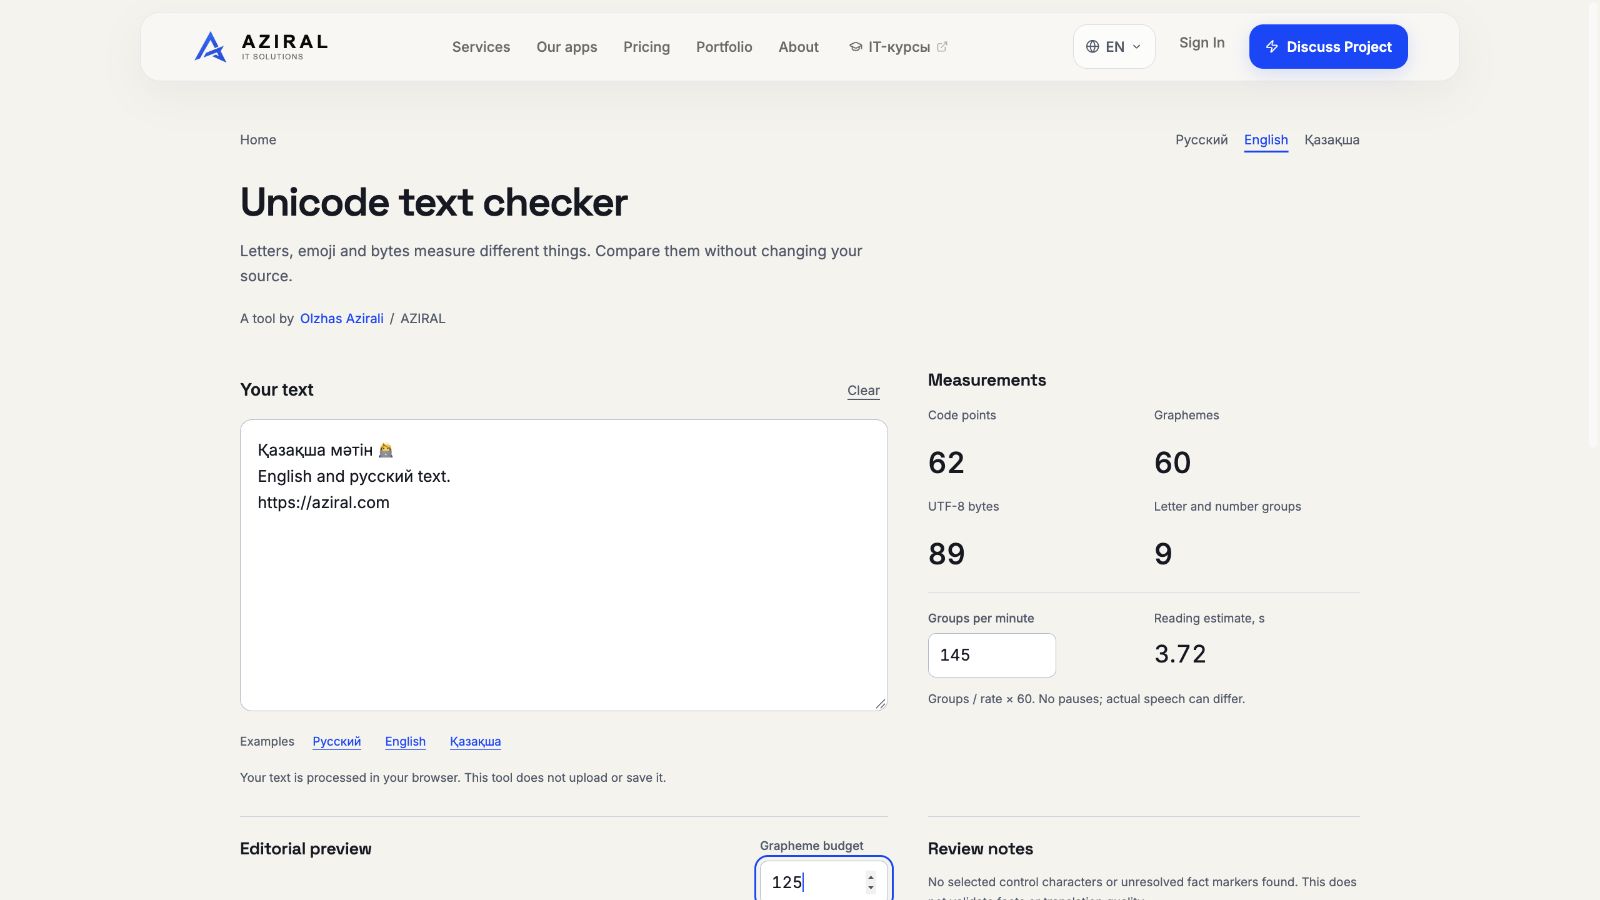
Actual Unicode Text Lab interface with synthetic English, Russian and Kazakh sample text.
What it does
Unicode Text Lab is a free browser utility by Olzhas Azirali and AZIRAL. Inspect code points, UTF-8 bytes and available grapheme segmentation in English, Russian and Kazakh. The checker preserves the input and processes it locally. An editable editorial preview budget and a rough reading estimate state their assumptions. A related public pack contains 20 reproducible Unicode fixtures and offline Python and JavaScript verifiers.
Why separate the counts?
An emoji, a Cyrillic letter and a Kazakh word can be counted differently by JavaScript, UTF-8 storage and a reader. The tool shows each available unit separately instead of presenting one ambiguous character count.
How it is built
The browser interface uses React and TypeScript. TextEncoder measures UTF-8 bytes; Intl.Segmenter provides grapheme segmentation when the browser supports it. The original input is preserved and processed locally. The interface is available in English, Russian and Kazakh.
Reproducible examples
A related public pack contains 20 Unicode regression fixtures and offline Python and JavaScript verifiers. It covers emoji sequences, Cyrillic, Kazakh letters, combining marks, line endings and invisible characters. The Python verifier uses the standard library. The optional JavaScript verifier reports the runtime used for grapheme segmentation.
View the related fixtures and verifiers. Related Unicode regression fixtures and Python/JavaScript verifiers; this is not the source repository of the browser application.
Limits
- A grapheme count is not a rendered width or a linguistic word count.
- 125 is an editable editorial preview budget, not a social-network character limit.
- Reading estimates count letter-and-number groups at a selected rate and exclude pauses.
- Absent Intl.Segmenter means unavailable grapheme segmentation, not a silent approximation.
Maker
Built by Olzhas Azirali / Олжас Азирали, founder of AZIRAL. About the maker.
Built with AI assistance. Runtime examples were reproduced locally.
Русский
Unicode Text Lab - бесплатный браузерный инструмент Олжаса Азирали и AZIRAL. Кодовые точки, байты UTF-8 и доступная графемная сегментация показываются отдельно. Есть русский, английский и казахский интерфейсы. Исходник сохраняется, обработка выполняется локально. Рядом опубликованы 20 Unicode-примеров и проверки Python/JavaScript.
Қазақша
Unicode Text Lab - Олжас Азирали мен AZIRAL ұсынған тегін браузерлік құрал. Unicode код нүктелері, UTF-8 байттары және қолжетімді графемалық сегментация бөлек көрсетіледі. Қазақша, орысша және ағылшынша интерфейс бар. Мәтін жергілікті өңделіп, бастапқы нұсқасы сақталады. Ашық жинақта 20 мысал және Python/JavaScript тексеруі бар.

Log in or sign up for Devpost to join the conversation.