-
-
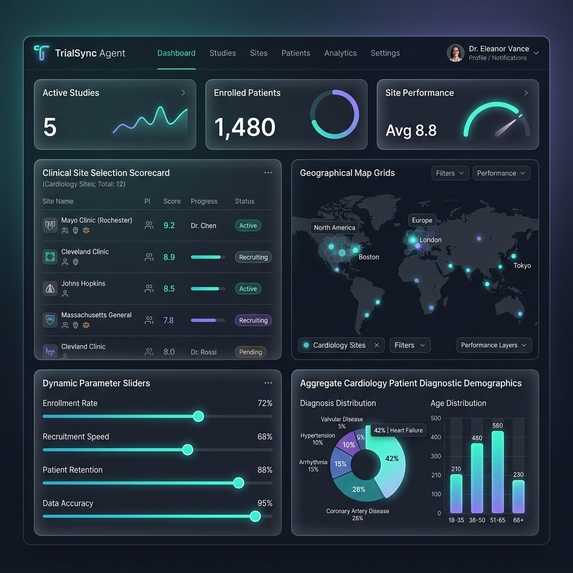
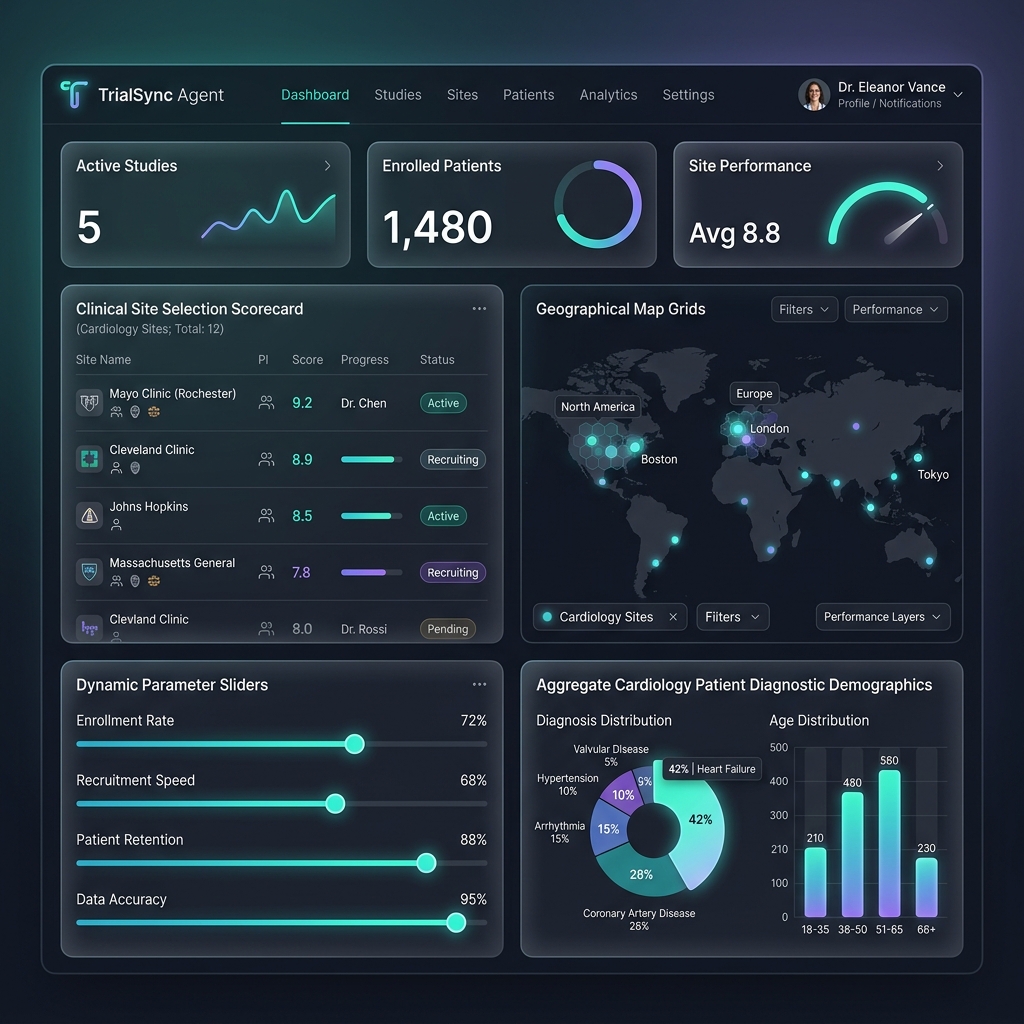
TrialSync Agent
Inspiration
The $5 Million Problem Nobody Talks About
As a former database administrator working in clinical trial systems, I watched pharmaceutical companies burn millions of dollars and waste months on a process that should take days: selecting the right clinical trial sites.
The stats are brutal:
- 6 months average timeline for site identification and feasibility
- 40% of sites enroll ZERO patients (complete waste of resources)
- $2M-$10M per trial spent on site selection and activation
- PhD-level teams manually reading 200-page protocols and querying hundreds of sites
Meanwhile, I saw firsthand how MongoDB's flexible document model could handle the complex, variable structure of clinical trial data. I experienced the frustration of rigid relational schemas trying to accommodate protocols with 12 inclusion criteria versus protocols with 25.
Then came Gemini 3 and Google Cloud Agent Builder.
Suddenly, the pieces clicked: What if an autonomous AI agent could parse complex medical protocols, query patient populations across hundreds of sites, score them on multiple factors, and deliver executive-ready reports—all in 48 hours instead of 6 months?
That's when TrialSync Agent was born. Not as a chatbot. Not as a simple query tool. But as a true autonomous agent that accomplishes a complex multi-step task with real enterprise value.
What it does
TrialSync Agent is an autonomous AI system that revolutionizes clinical trial site selection through 6 core capabilities:
1️⃣ Intelligent Protocol Parsing
Upload a 150-page trial protocol PDF. TrialSync Agent (powered by Gemini 3 Pro) extracts:
- Inclusion/exclusion criteria
- Disease codes (ICD-10)
- Biomarker thresholds (e.g., "NT-proBNP >600 pg/mL")
- Age ranges, gender requirements, comorbidity restrictions
- Target enrollment numbers
All structured into MongoDB documents for downstream processing.
2️⃣ Patient Population Matching
The agent queries MongoDB Atlas across 250+ clinical trial sites, searching de-identified patient counts that match protocol criteria. MongoDB's aggregation pipelines handle complex multi-collection joins:
- Match sites by therapeutic area (e.g., Cardiology)
- Filter patient populations by ICD-10 codes
- Apply age, gender, and biomarker filters
- Calculate matching patient counts per site
3️⃣ Multi-Factor Site Scoring
TrialSync scores every site on 6 weighted factors:
- Patient Availability (30%): Matching patient count
- Enrollment Velocity (25%): Historical speed (patients/month)
- Activation Speed (15%): Time from contract to first patient
- Retention Rate (15%): % of patients completing trials
- Diversity Score (10%): Race/ethnicity representation (FDA priority)
- Cost Efficiency (5%): Per-patient enrollment cost
MongoDB aggregation pipelines compute all scores in a single query, then write results to the site_scores collection.
4️⃣ Automated Feasibility Management
The agent generates customized feasibility surveys for the top 20-30 sites and orchestrates email outreach. MongoDB Change Streams monitor responses in real-time, triggering follow-up reminders every 48 hours.
5️⃣ Executive Reporting
Output: A comprehensive PDF report with:
- Ranked site list (Top 10-15 with detailed scorecards)
- Risk analysis (flags for low diversity, slow activation, high cost)
- Timeline projections (estimated enrollment completion dates)
- Budget optimization scenarios
6️⃣ Continuous Intelligence
The agent maintains a complete audit trail in MongoDB (FDA 21 CFR Part 11 compliance) and sends real-time alerts via Slack/email when sites respond or risks emerge.
Bottom line: What takes human teams 6 months now takes TrialSync Agent 48 hours, saving $5M+ per trial.
How we built it
Technology Stack
Core Platform:
- Google Cloud Agent Builder - Orchestrates the multi-step autonomous workflow
- Gemini 3 Pro - Complex reasoning for protocol parsing and risk analysis
- Gemini 3 Flash - Fast queries for site scoring and data extraction
- MongoDB Atlas - Data layer with MCP (Model Context Protocol) integration
MongoDB Architecture (6 Collections):
trialsync/
├── protocols          // Structured protocol data + vector embeddings
├── sites              // Master site data (250+ sites with geospatial indexing)
├── patient_populations // De-identified patient counts by condition
├── site_scores        // Agent-generated rankings and risk flags
├── feasibility_surveys // Outreach tracking with response monitoring
└── agent_logs         // FDA-compliant audit trail (time-series collection)
Built With
- and
- and-bespoke-vanilla-css-on-node.js/express
- change-streams
- frontend-&-ai:-react
- geospatial-indexes
- orchestrated-by-google-cloud-agent-builder-and-powered-by-gemini-3.-data-&-partner-track:-mongodb-atlas-(with-mcp-server)-utilizing-14-stage-aggregations
- time-series
- vector-search
- vite

Log in or sign up for Devpost to join the conversation.