TradeWizard
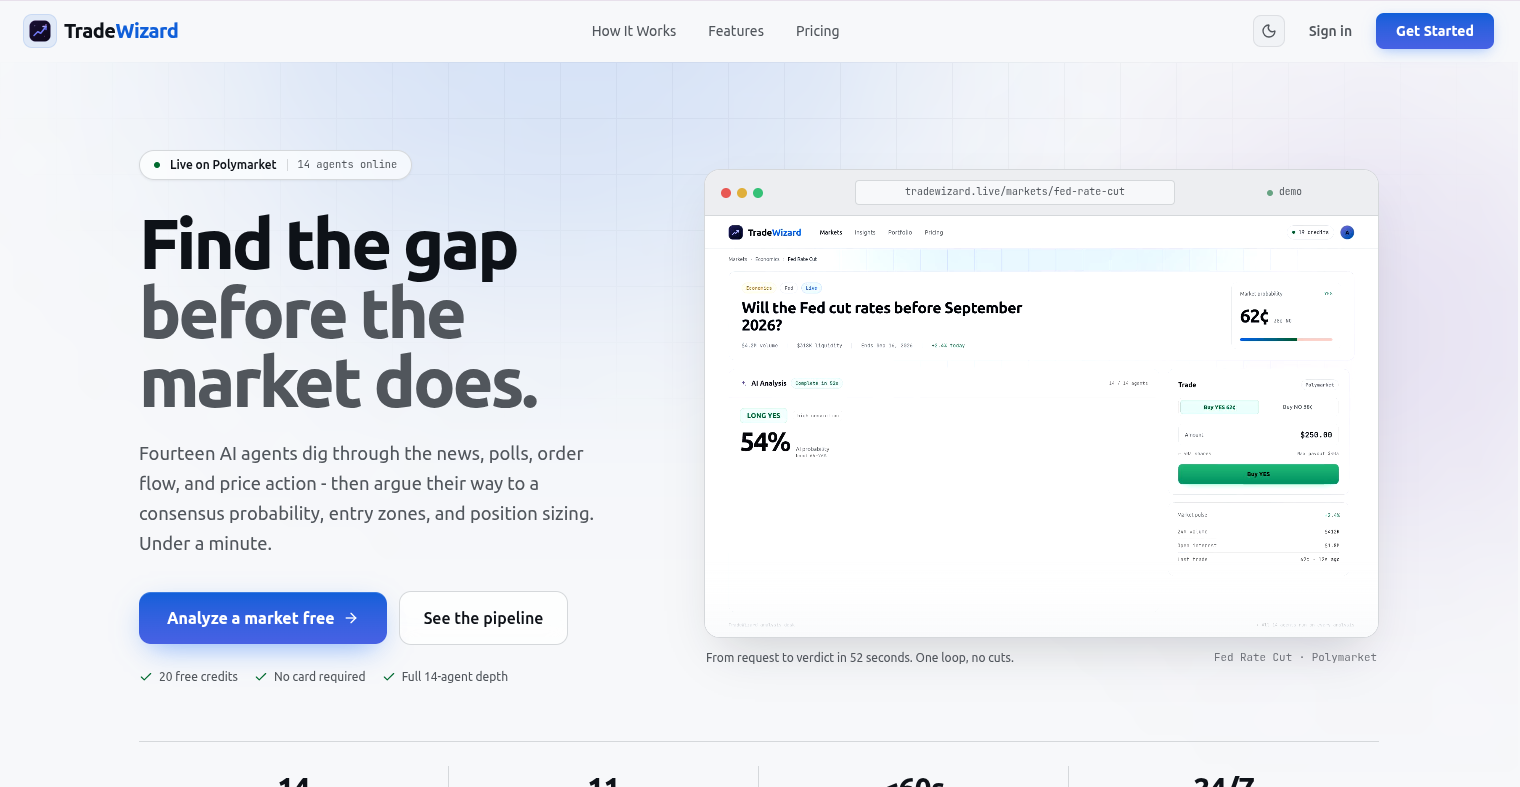
The intelligence layer for real-world prediction markets. A multi-agent AI system that runs on Nebius Token Factory with NVIDIA Nemotron 3 Super, turns event-driven markets on Polymarket into explainable, probability-driven trades - with a closed-loop learning fabric and a bounded-autonomy Portfolio Manager governed by hard, auditable risk limits.
Inspiration
Prediction markets are one of the cleanest signal-generation mechanisms ever built. They aggregate dispersed information into a single number - the price - and that number is a probability. In theory, anyone can trade them. In practice, almost nobody can trade them well.
To consistently price an outcome on Polymarket you need to monitor breaking news, read polling internals, watch order books for whale activity, track narrative velocity across media and social platforms, and time entries against catalysts. Those are five different jobs. Most retail traders have none of them, so they trade headlines, lose money, and quit. The asymmetry isn't liquidity - it's intelligence.
Bloomberg-grade analysis exists for equities. Nothing comparable existed for political, legal, economic, and geopolitical outcomes. We wanted to build the intelligence layer the category has been waiting for: not a content site, not a Twitter feed, but a decision system that produces explainable, probability-disciplined recommendations and stands behind them with a measurable accuracy track record.
We also wanted to confront the part most "AI trading" products avoid: what happens after the recommendation. Reading a thesis is one thing. Acting on it under time pressure, with the right size, with mandatory exits, while the market is moving - that's where retail loses. So we built an opt-in autonomous Portfolio Manager that executes inside hard guardrails the user pre-approves, with a kill switch that fails closed. Bounded autonomy, not unbounded delegation.
What it does
TradeWizard is two products that share a brain.
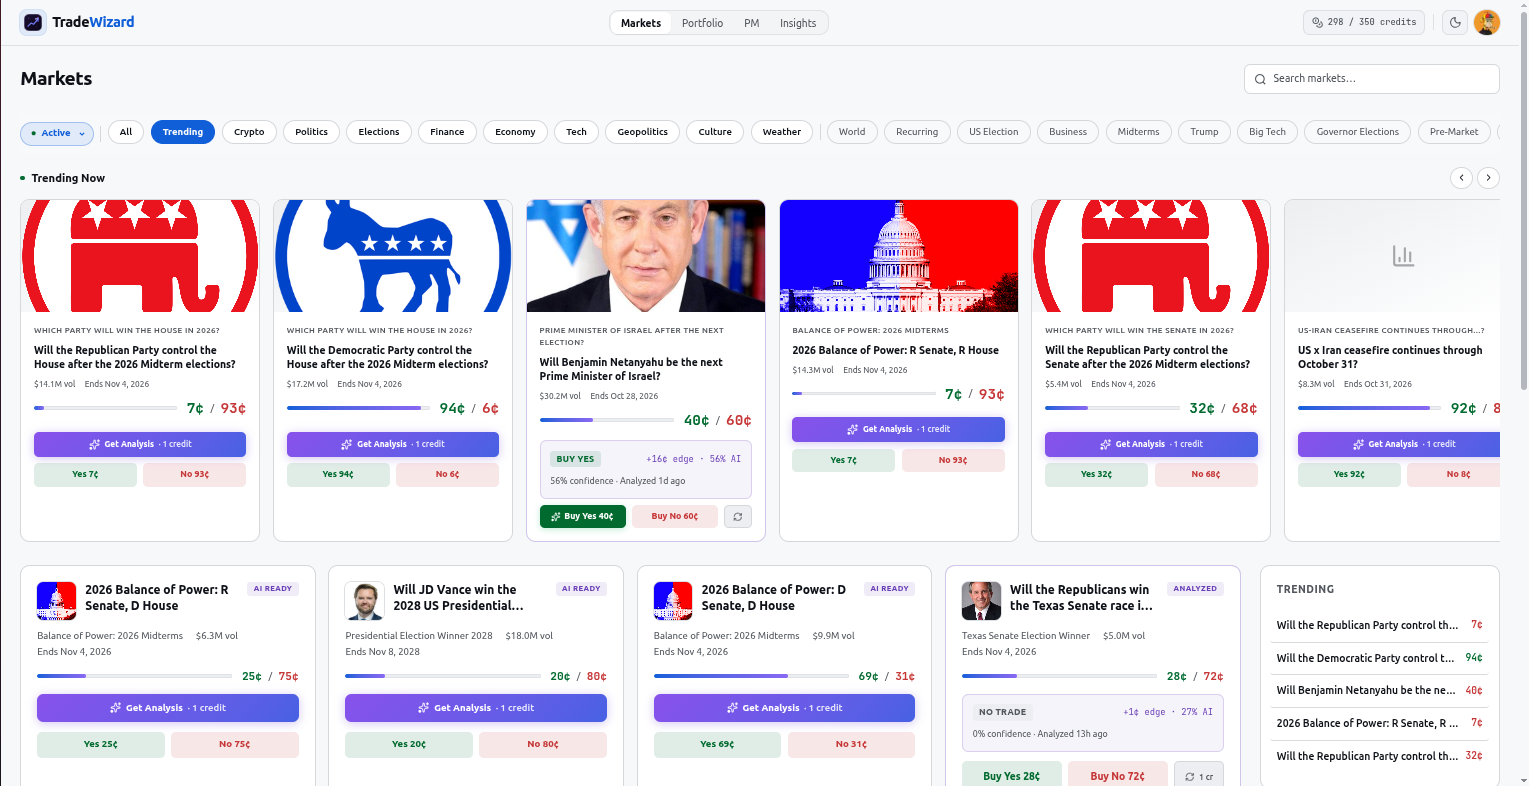
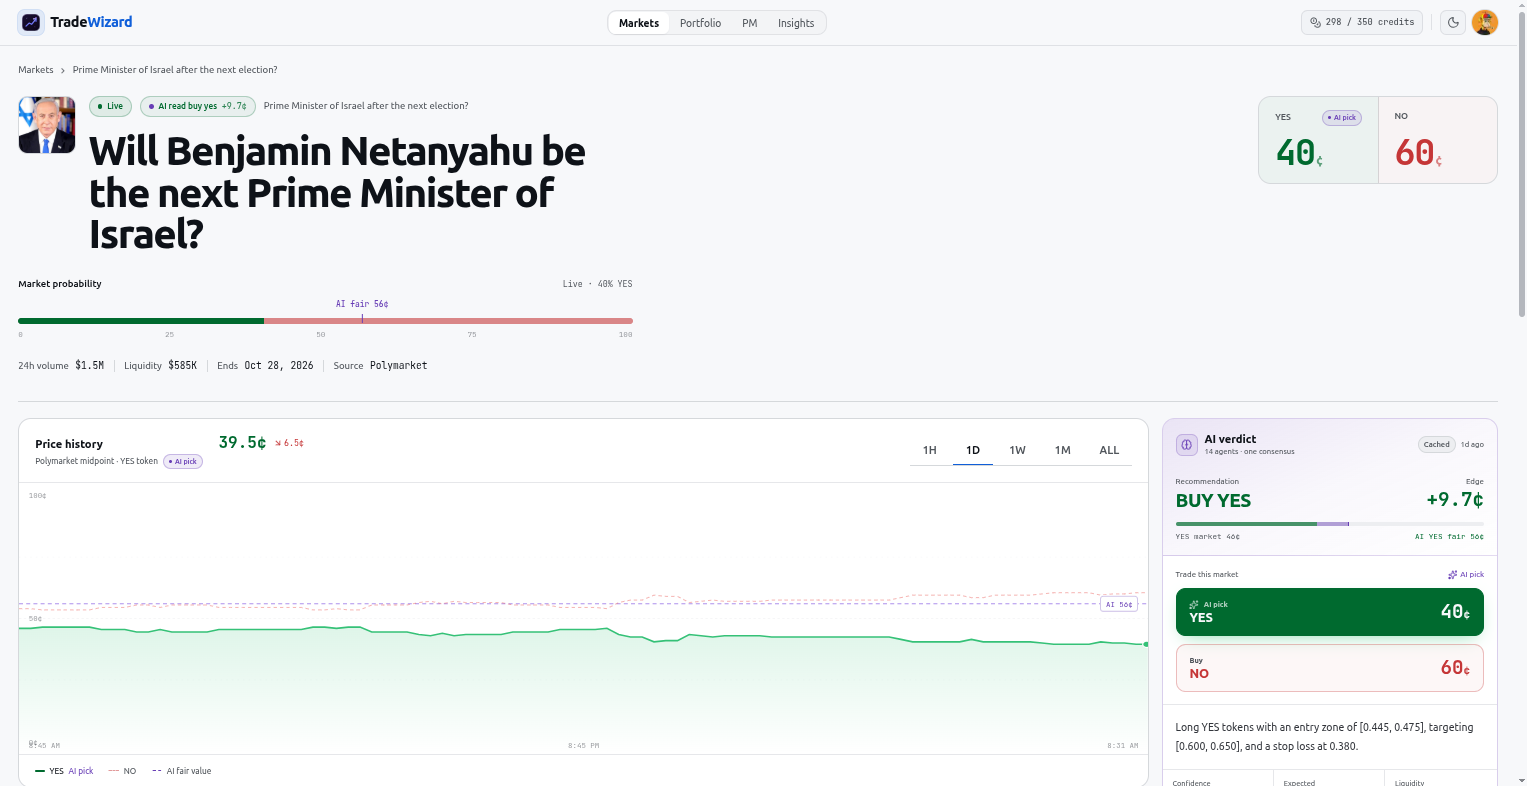
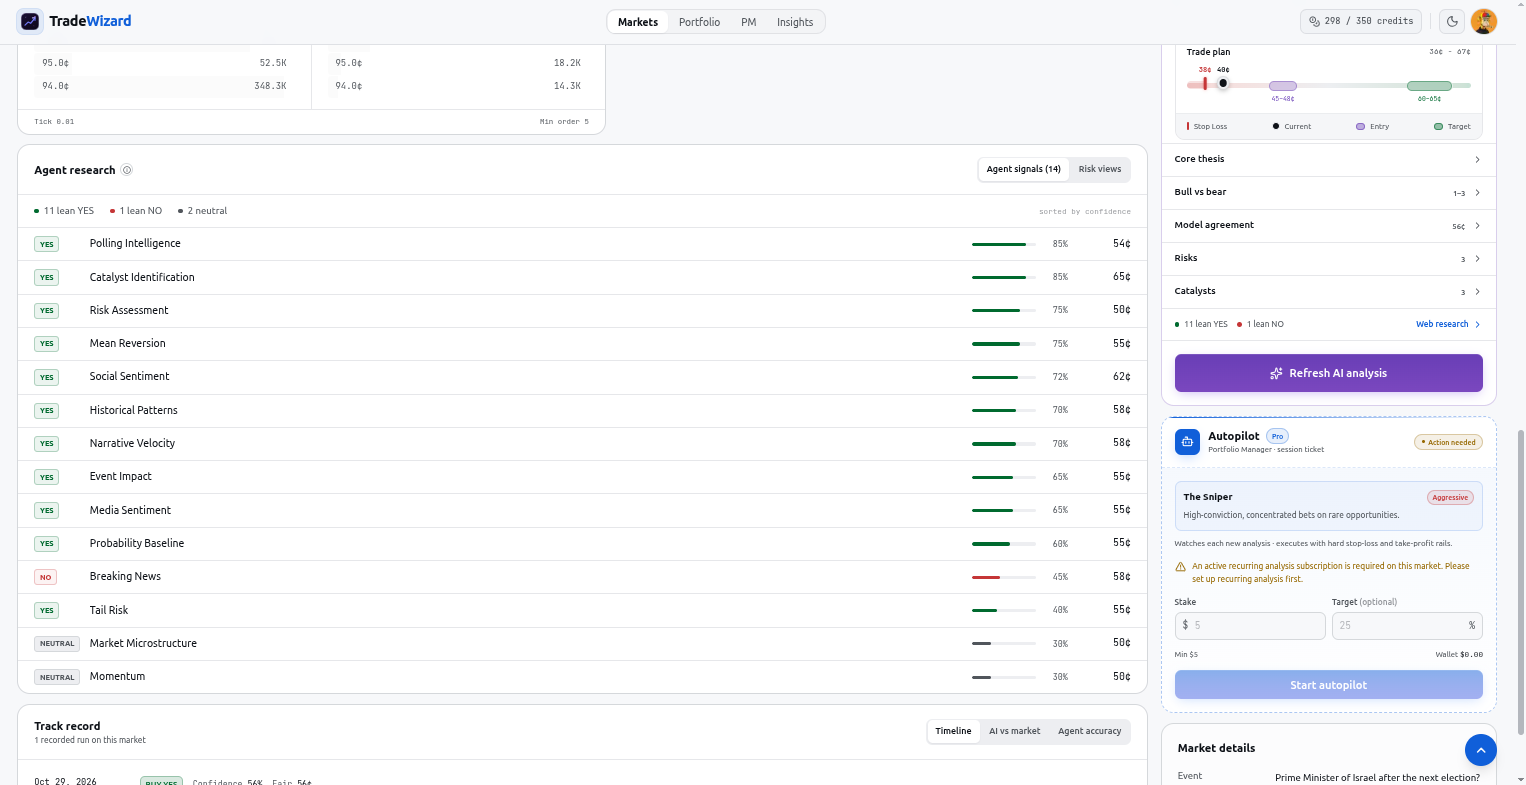
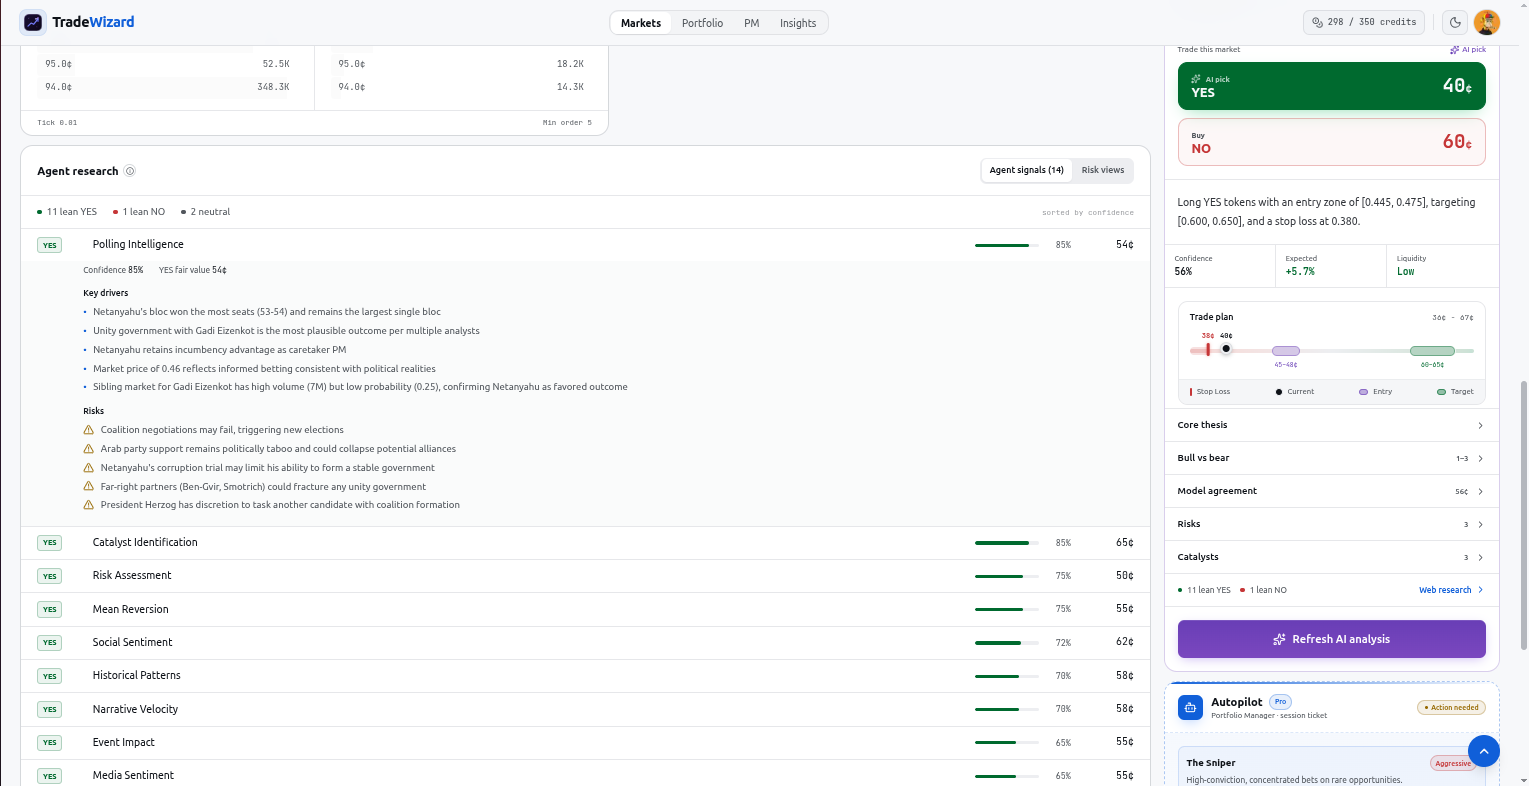
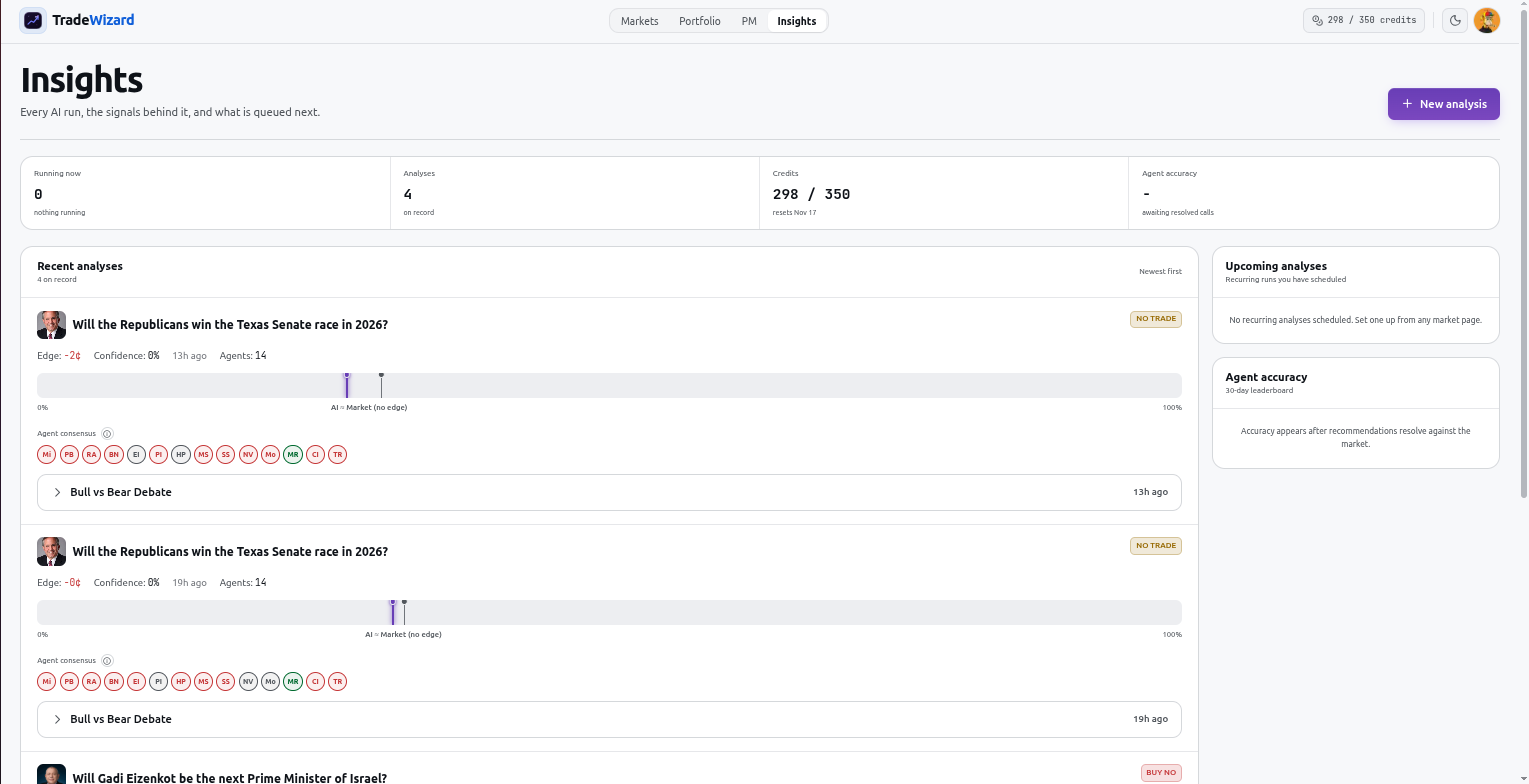
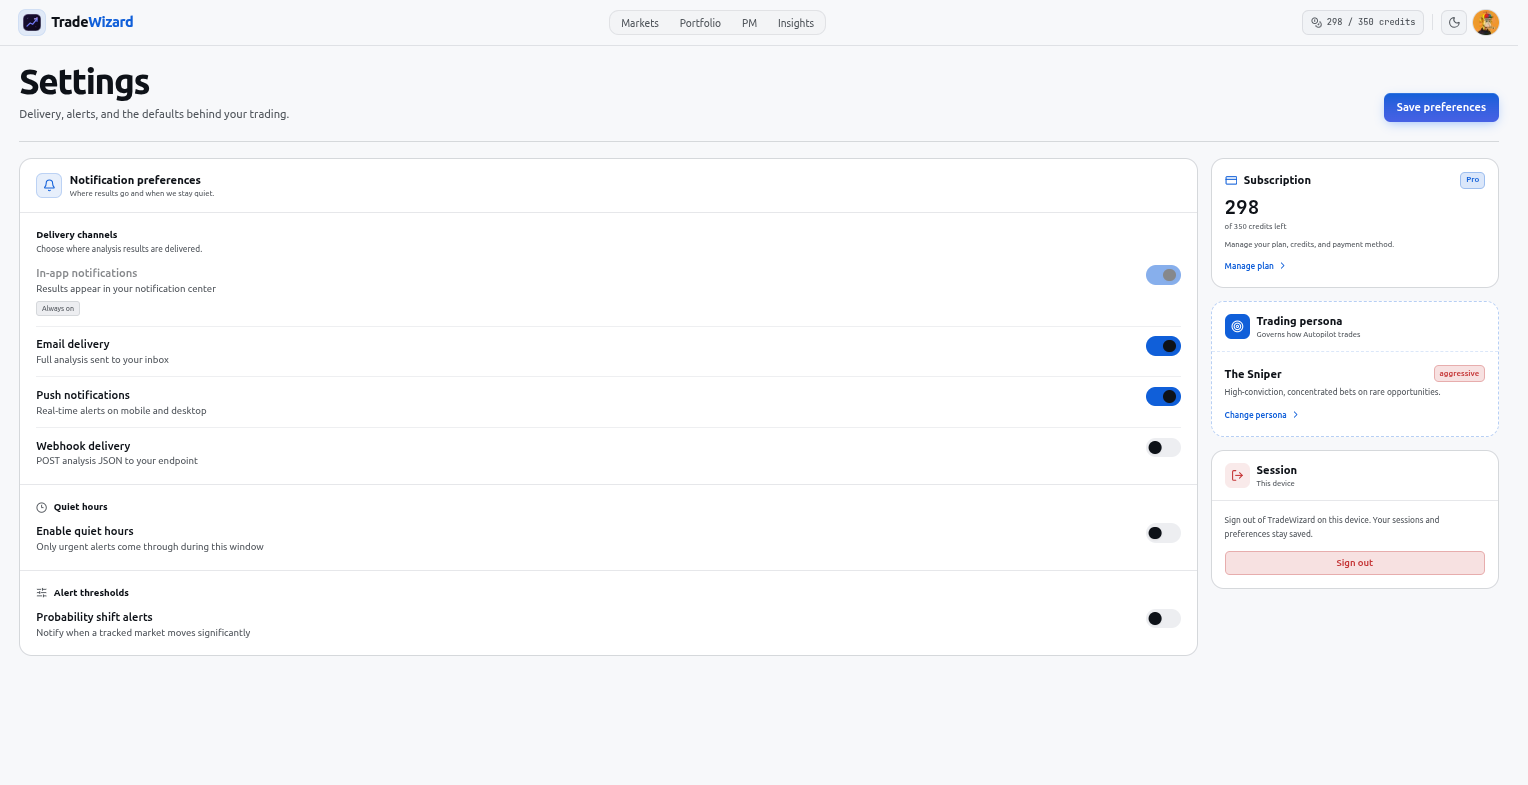
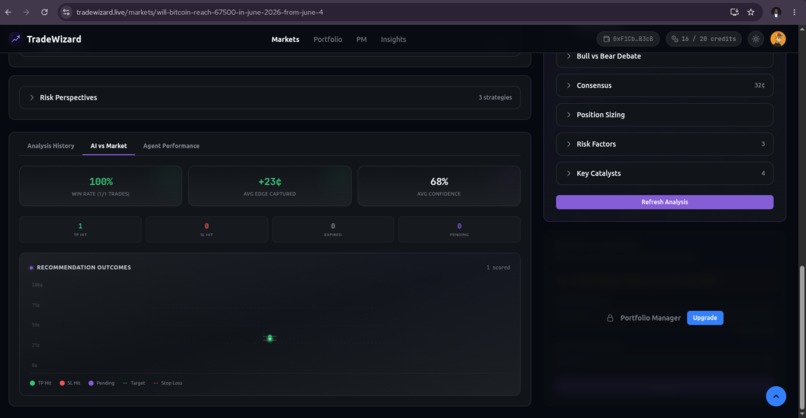
Intelligence layer. Any user can request analysis on any Polymarket market. Behind the request is an 11-stage workflow that runs 14 specialized intelligence agents in parallel, fuses their signals deterministically, debates the thesis adversarially, runs a deterministic consensus engine, asks three risk-philosophy agents about sizing, and emits a recommendation with entry zone, target zone, mandatory stop-loss, expected value, win probability, and a full reasoning chain. If agents disagree above a hard threshold, or expected value is non-positive, the system refuses to recommend - it returns NO_TRADE and explains why. Results arrive through WebSocket, email, push, and webhook, respecting quiet hours and preferences. Every recommendation is scored once take-profit or stop-loss is hit, and every agent has a public accuracy leaderboard.
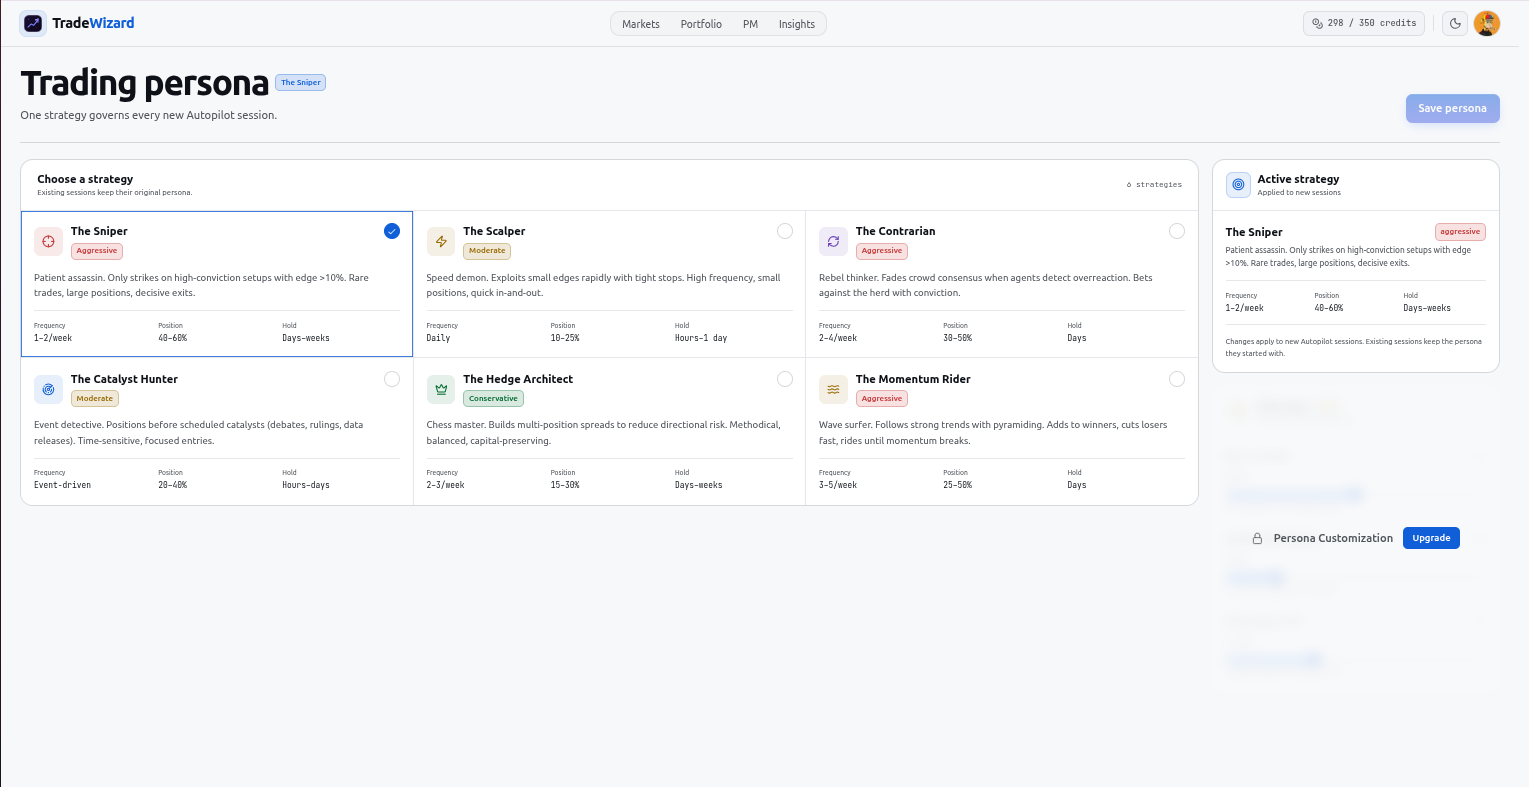
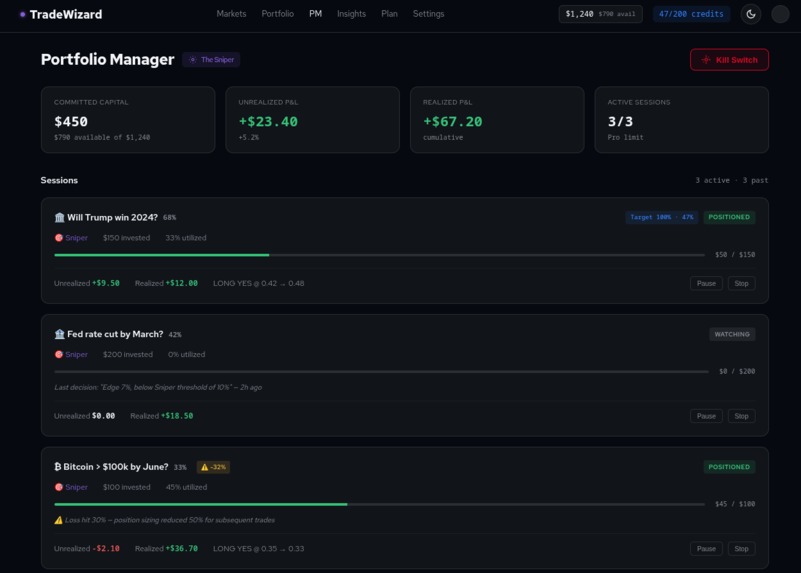
Autonomous Portfolio Manager (Pro and Elite). A user opts into autonomous execution on a specific market by activating a session with a persona (Sniper, Scalper, Contrarian, Catalyst Hunter, Hedge Architect, Momentum Rider), a capital envelope, and pre-approved guardrails. The Portfolio Manager consumes recurring analyses for that market - it never triggers its own - and decides entry, sizing, stop-loss, and take-profit. Orders go to the Polymarket CLOB. A Position Guard watches open positions for regime shifts and stale markets; a Risk Engine enforces loss limits, cooldowns, and a kill switch that fails closed. The user can pause, resume, stop, or kill all sessions at any time, and every trade, exit, and risk event fans out across notification channels.
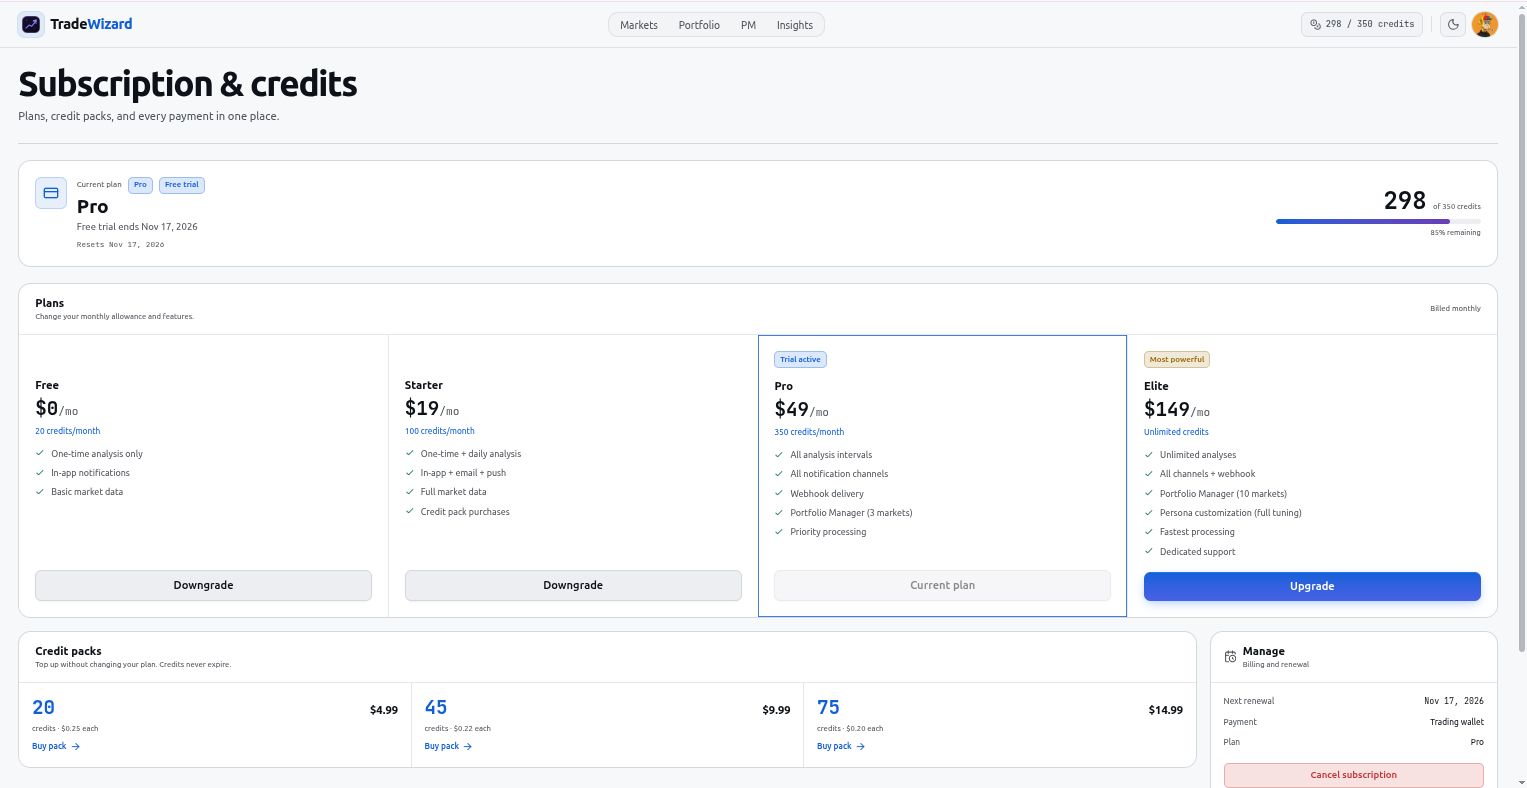
Around these sit the pieces a real product needs: passwordless Cognito Magic Link auth, on-chain pUSD (Polymarket USD) billing on Polygon with legacy USDC.e read compatibility and auto-renewal via ERC-20 allowances, a market-level analysis pool that prevents redundant compute, a credit system with an immutable audit trail, and a Next.js 16 / React 19 frontend.
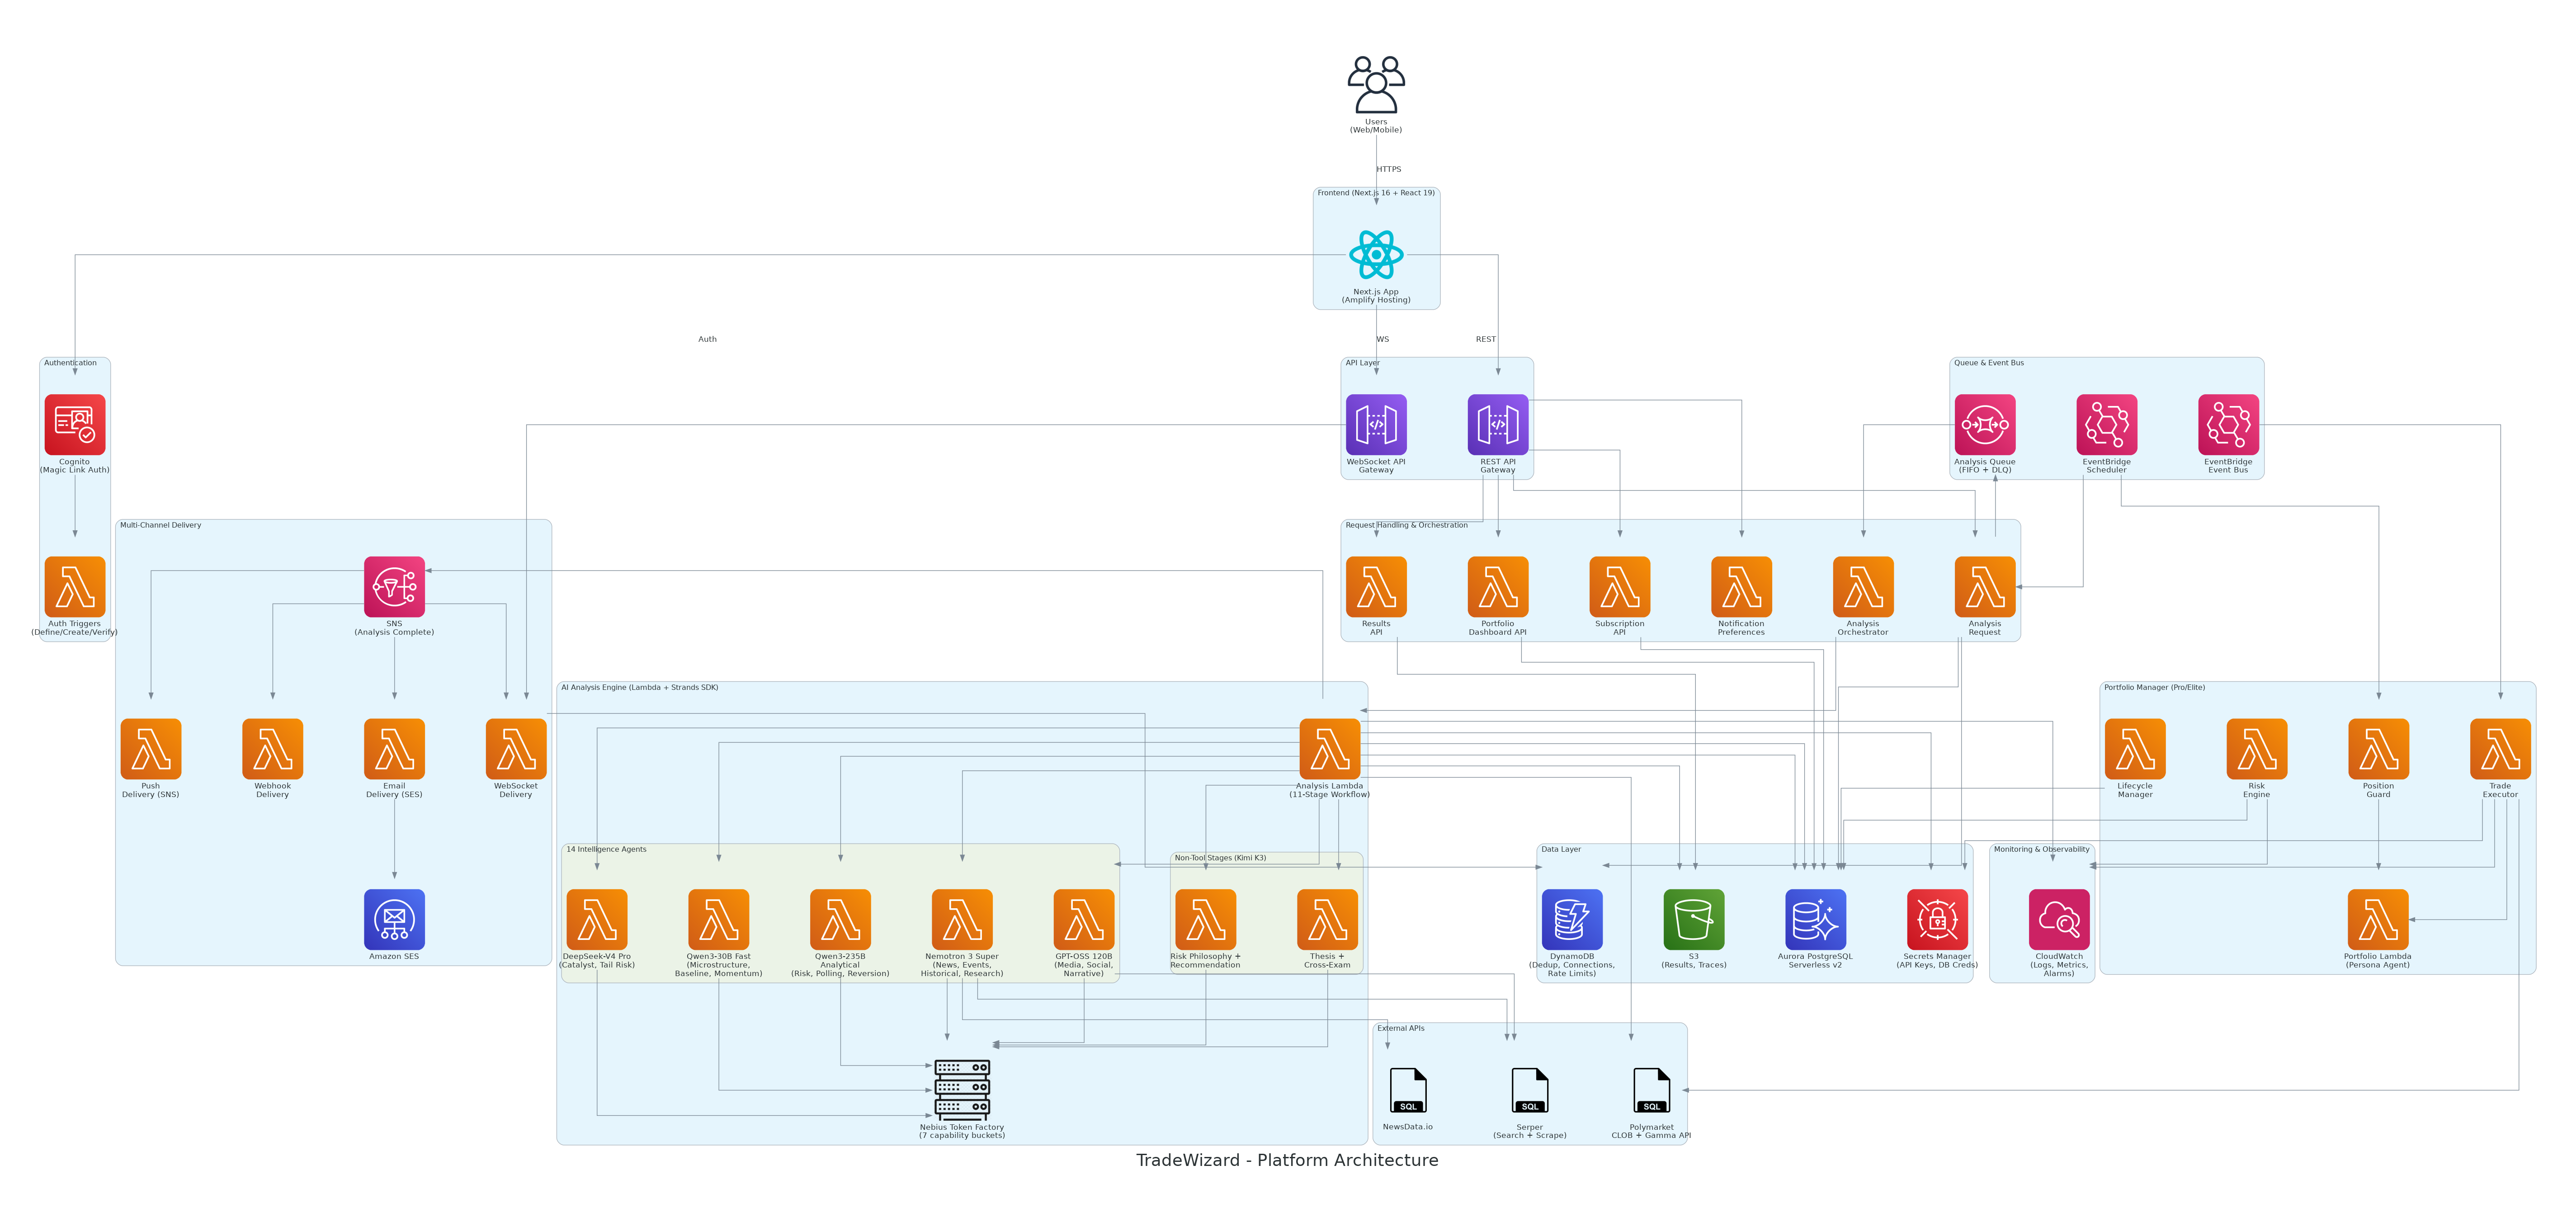
The inference layer runs on Nebius Token Factory. Every agentic stage - web research, the fourteen parallel analysts, the adversarial debate, risk philosophy, and the Portfolio Manager's decision - resolves through a provider abstraction to an open model on Token Factory. NVIDIA Nemotron 3 Super, an open-source NVIDIA model, is the agentic workhorse for tool-heavy research and news agents. Orchestration, persistence, and execution run on a serverless substrate, deliberately separate from the provider, so the intelligence layer is not coupled to a single model vendor.
How we built it
The product framing is simple. The architecture is where the work is.
AI Architecture Explanation
Inputs (what data goes in)
Every analysis begins with a market identifier from Polymarket. From that single seed, the system collects:
- Price history - OHLC-style data from the Polymarket CLOB API, written as a deterministic CSV to
/tmpfor agents to query numerically. - Market metadata - resolution criteria, expiry, current probability, bid/ask spread, volume, and liquidity from the Gamma API, plus related sibling markets and their aggregate metrics.
- Agent memory - per-agent historical signals from Aurora PostgreSQL's
agent_memorytable. Each agent loads only its own prior signals on this market (configurable depth, default 5). No cross-agent history. - Real-time web context - an autonomous research agent using NewsData.io and Serper search/scrape tools to gather breaking news, expert opinion, polling data, and social discourse.
- Agent performance weights and calibration - accuracy data from
agent_performance, used to scale each agent's influence during fusion.
For the Portfolio Manager, additional inputs include the user's active session (persona, capital envelope, current position state), order book depth, the latest completed analysis, trade history, and session performance - all fetched through read-only tools.
AI capabilities used
TradeWizard employs four distinct AI capabilities in a single pipeline:
| Capability | Where it's used | Models (Nebius Token Factory) |
|---|---|---|
| Multi-agent reasoning | 14 intelligence agents producing independent probability estimates from different analytical perspectives | Nemotron 3 Super, Qwen3-30B-A3B, Qwen3-235B-A22B, GPT-OSS 120B, DeepSeek-V4-Pro |
| Autonomous tool use | Agents calling external APIs (news, search, scrape, shell) for real-time data and numeric analysis | Nemotron 3 Super (web research), Qwen3-30B (shell/price analysis), Qwen3-235B (polling data) |
| Adversarial debate & synthesis | Thesis construction, cross-examination (5 tests × 2 theses), risk philosophy, final recommendation | Kimi K3 |
| Persona-driven decision-making | Portfolio Manager reasoning about entry/exit/sizing through a chosen trading persona | MiniMax M3 |
None of these are chatbots or classifiers. They are agentic workflows - LLMs orchestrated with tools, structured outputs, and deterministic gates that constrain what they may conclude. Model IDs are configuration, not architecture: the same logical assignments can be re-pointed without touching prompts, tools, or downstream validation.
What processing happens
The 11-stage pipeline alternates parallel agentic stages with deterministic ones:
- Data Preparation (deterministic) - Fetches market data from CLOB and Gamma. Writes price CSV and related-markets JSON to
/tmp. No LLM. - Historical Context Retrieval (deterministic) - Loads per-agent memory, performance weights, and calibration lines from Aurora. No LLM.
- Web Research (agentic) - A Strands Agent with news and search tools gathers real-time context. 60-second timeout, max 10 searches + 5 scrapes.
- Agent Selection (deterministic) - All 14 agents are activated. No conditional filtering.
- Parallel Intelligence Agents (agentic) - 14 agents execute via
Promise.all, each resolving to a capability-routed Token Factory model. Each produces a Zod-validatedAgentSignal: direction, confidence, fair probability, key drivers, risk factors. 120-second timeout; invalid output is excluded downstream. - Signal Fusion (deterministic) - Market-anchored log-odds aggregation. Each forecast is de-biased against that agent's own fitted calibration line, so habitual drift toward 0.5 is not counted as a directional vote; the surviving edge passes an evidence-scaled filter and the stage reports a noise floor. Weights are Brier-calibrated. Full detail is in the conflict-resolution section below.
- Thesis Construction (agentic) - Kimi K3 generates competing bull and bear theses from the fused signal: fair probability, edge, core argument, catalysts, failure conditions.
- Cross-Examination (agentic) - Kimi K3 runs 5 adversarial tests against each thesis (10 total): evidence, causality, timing, liquidity, tail risk. Each produces a survived/weakened/refuted outcome with a numeric score.
- Consensus Engine (deterministic) - Converts the anchored probability into a decision through the gate profile: cost floor from the market's spread, significance floor from ensemble noise, thesis confirmation, divergence cap, confidence floor. Every refusal records its gate. Full detail is in the conflict-resolution section below.
- Risk Philosophy (agentic) - Three agents (aggressive, conservative, neutral) run in parallel on Kimi K3, providing position-sizing perspectives without influencing probability estimates.
- Recommendation (agentic) - Kimi K3 synthesizes all upstream context into a final
TradeRecommendation, validated through Zod and price-ordering constraints. If EV ≤ 0 the recommendation is rejected → forcedNO_TRADE. Falls back to a structuredNO_TRADEexplanation on any parse failure.
For the Portfolio Manager, processing is simpler: Portfolio_Lambda receives the latest analysis and session context, runs one persona-driven agent with 7 read-only tools, and produces a structured entry/exit/skip decision. The Trade Executor validates that decision against hard limits before placing orders.
Outputs (what the user receives)
From the intelligence layer, a TradeRecommendation through the user's preferred channels: action (LONG_YES, LONG_NO, NO_TRADE), entry and target zones, mandatory stop-loss, expected value, win probability, a reasoning chain (core thesis, catalysts, failure scenarios, uncertainty notes), and metadata (agents used, disagreement index, consensus probability, edge, duration). Each result also exposes the per-agent signal breakdown, both thesis memos with cross-examination scores, and the three risk-philosophy perspectives.
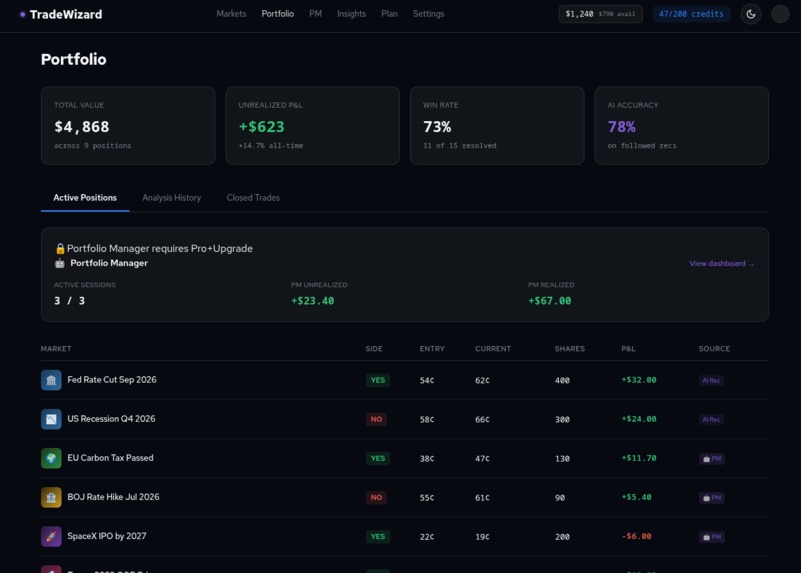
From the Portfolio Manager, real-time notifications for every lifecycle event: entry (size, prices, persona reasoning), exit (price, P&L, reason), risk alerts, kill switch, session status changes, and a daily summary. The dashboard shows active sessions, trade history with decision logs, aggregate statistics, and the audit trail behind every entry, exit, or skip.
Human-in-the-Loop Decision
The AI never decides how much of your money is at risk.
The intelligence layer recommends trades and the Portfolio Manager can execute them - but the system cannot activate itself. A human must explicitly choose which market to expose capital to, how much capital to commit, which persona governs decision-making, and whether to enable autonomous execution at all. Those four choices define the blast radius, and the AI is architecturally excluded from making any of them.
This is deliberate. A probabilistic system - no matter how well-calibrated - should never unilaterally decide what fraction of a person's wealth to put in play. The AI can estimate that a market has a 72% fair probability and positive expected value, but it cannot know the user's total financial picture, risk tolerance, liquidity needs, or emotional capacity for loss.
Concretely: the activation handler requires the user to submit and confirm a capital amount, and the Lambda cannot self-activate or increase committed capital; amount_available can only grow through an explicit user-initiated API call; the kill switch is always available and fails closed, and no amount of positive expected value overrides a user who wants out; and on the intelligence layer the user places the trade manually - the AI never touches the order book unless the user opted into bounded autonomy. The risk perimeter is always human-drawn. The AI operates inside it.
Responsible AI Guardrail
Risk: over-reliance - users trusting AI recommendations without critical evaluation, leading to financial harm.
Over-reliance is the most dangerous failure mode in any AI trading system. If users treat recommendations as certainties rather than probabilistic estimates, they over-size positions, ignore warnings, and suffer outsized losses when the system is inevitably wrong. The risk compounds when the system is accurate most of the time, because success breeds uncritical trust. We reduce it through four mechanisms.
1. The system visibly refuses. When disagreement exceeds 30% or expected value is non-positive, TradeWizard returns NO_TRADE with a structured explanation - the only output the pipeline can produce under those conditions. Users who see the system regularly decline learn that it is not omniscient. A system that always has an answer trains users to stop thinking.
2. Uncertainty is surfaced, not hidden. Every recommendation exposes its disagreement index, confidence band, dissenting agents, and the failure scenarios that would invalidate the thesis. The UI does not present a clean "BUY YES" button without context - it presents the reasoning chain, cross-examination scores, and the conditions under which the recommendation is wrong. We deliberately make it harder to act without reading.
3. Mandatory stop-losses bound the cost of misplaced trust. Even if a user over-relies on a recommendation, the mandatory stop-loss caps the maximum loss per position, enforced at the executor layer. It does not prevent over-reliance; it bounds its financial consequence.
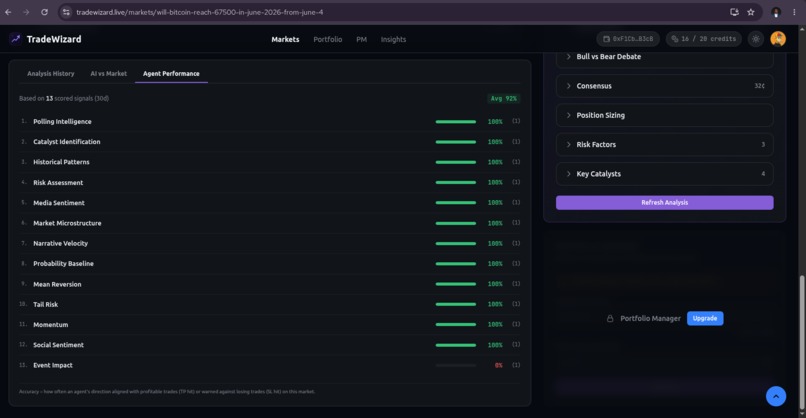
4. The accuracy leaderboard creates calibrated expectations. Every recommendation is scored against eventual outcomes, and the public leaderboard shows users, with real numbers, that the system is not always right: an agent at 62% accuracy is visibly, provably fallible. Calibrated data produces calibrated trust instead of binary faith.
The goal is not to stop users following recommendations - that would defeat the product. The goal is for them to follow with appropriate confidence, informed by visible uncertainty, bounded by mechanical exits, and calibrated by historical accuracy. Over-reliance is reduced not by disclaimers, but by making the system's limitations structurally visible at every decision point.
Stack at a glance
- Deployment substrate: AWS CDK in TypeScript. Stacks for network, database, auth, queue, notification, storage, monitoring, and compute. Aurora PostgreSQL Serverless v2 for state, DynamoDB with TTL for dedup and WebSocket connections, SQS FIFO with a DLQ for the analysis queue, EventBridge for scheduling and routing, SNS fan-out for delivery, S3 for artifacts and agent traces. The substrate is deliberately boring: it holds state, schedules work, and fans out results. It is not where the intelligence lives.
- Compute: Lambda on Node.js 20 throughout. No long-lived servers, no NAT Gateway. Aurora is reachable on a public endpoint with SSL enforced, scales to 0.5 ACU at idle, and auto-scales under load.
- AI runtime: Nebius Token Factory through the Strands Agents SDK in TypeScript. Two agentic Lambdas -
Analysis_Lambdaruns the 11-stage workflow,Portfolio_Lambdaruns the persona-driven decision. Every model call goes throughservices/shared/ai-provider.ts, which resolves a capability (fast,analytical,agentic,reasoning,deep_reasoning,non_tool,default) to a configured Token Factory model ID. Model IDs and token limits are env-driven, so routing changes need no code change. - Frontend: Next.js 16 App Router on AWS Amplify Hosting. React 19, TypeScript strict, Tailwind 4, TanStack Query, WebSocket client with exponential backoff and ping keepalive. Magic SDK plus viem for on-chain operations, Polymarket CLOB client for orders.
- Payments: On-chain pUSD on Polygon with legacy USDC.e read compatibility. Subscriptions and credit packs settle by transaction-hash verification using viem; auto-renewal uses a pre-approved ERC-20 allowance and
transferFrom. No card processor in the loop.
Nebius Token Factory integration
The provider boundary is one file: infra/services/shared/ai-provider.ts. It exposes a model factory and a capability mapping. The analysis pipeline never names a vendor. It asks for getModelForAgent('tail_risk') or getModelForStage('recommendation'); the registry resolves that logical key to a capability, then to the active provider's concrete model ID. Switching AI_PROVIDER does not touch prompts, tools, Zod schemas, or the deterministic stages.
Token Factory is OpenAI-compatible, so the integration uses Strands' OpenAIModel with api: 'chat' and a custom baseURL. The API key is read from Secrets Manager (tw-{env}-nebius-api-key), cached in-process for five minutes, and never injected into the browser or baked into the Lambda environment. If the provider is nebius and any required model ID is missing, the Lambda fails fast at cold start rather than starting an analysis that fails halfway through.
The capability split is intentional. Tool-using agents must resolve to a tool-capable bucket; the registry throws if one is mapped to non_tool. That single check prevents the most expensive failure mode in a multi-model pipeline - a news agent that silently stops calling tools and starts inventing context. The non_tool bucket exists only for pure synthesis stages.
Model validation is a deployment step, not a hope. infra/scripts/validate-nebius.ts checks that every configured ID exists in /v1/models, that tool-capable buckets actually return tool_calls, and that each model can emit JSON the pipeline's extractor can parse. Catalog changes are caught before a user request is. After a swap, agent-calibration-report.sql reports whether the new model argues better: calibration slope per agent, the no_trade_reason breakdown, and shadow-vs-live P&L.
Rate limits on Token Factory are account-level and dynamic, so the system does not pretend to know a fixed RPM budget. The 14 agents run in parallel because the pipeline needs independent signals, not because the provider guarantees unlimited concurrency. If the account throttles, the pipeline degrades exactly as it handles any partial agent failure: valid signals continue, failed agents are excluded, and the run aborts to NO_TRADE if coverage falls below threshold. Inference is a dependency; it is not allowed to become an unhandled single point of failure.
Agent architecture and coordination
The 14 intelligence agents run on every analysis. No conditional selection by market type, no router model deciding who gets to talk. We tried router-style designs early and they introduced a single point of failure hidden behind the appearance of efficiency: when the router is wrong, the system is missing the agent that mattered. Running all 14 in parallel costs more per analysis but produces a complete, comparable signal set every time, which is what the deterministic stages downstream need.
Agents are distributed across five tool-capable models by capability match. Data-crunching agents (microstructure, momentum, mean reversion) run on Qwen3-30B and Qwen3-235B. News and event agents that hit external APIs run on Nemotron 3 Super, the same model used by the web-research stage. Sentiment agents run on GPT-OSS 120B. Deep-reasoning scenario agents (catalyst identification, tail risk) run on DeepSeek-V4-Pro. Non-tool stages - thesis, cross-examination, risk philosophy, recommendation - run on Kimi K3, which receives the full deterministic context produced upstream. No single model is the bottleneck: each handles at most three agents concurrently, and the provider boundary keeps rate-limit behaviour visible and configurable.
Each agent gets a tool kit matched to its job. News agents get the NewsData.io tool. Browser-style agents get Serper search-and-scrape. Price-aware agents get a sandboxed shell tool that runs Python and bash on /tmp over the price CSV the data-preparation stage wrote. Tools are wrapped with timeouts, key rotation, and error handling so one dead key or slow source doesn't crater the run.
Conflict resolution and validation chain
This is the part that distinguishes TradeWizard from a chat-bot recommending trades. Three deterministic gates sit between raw agent output and what reaches the user.
Gate 1: Signal Fusion (no LLM). Signals are aggregated through market-anchored log-odds fusion. Two corrections make this honest rather than merely conservative. First, each forecast is de-biased against that agent's own fitted calibration line - the regression of its past forecasts on the price it saw - which removes habitual drift toward 0.5 before it can masquerade as a directional view. Second, the surviving edge passes an evidence-scaled filter: 60% of a moderate disagreement, half of a large one, and nothing above 30%, where the model is more likely wrong than early. Weights respond to agent type, confidence, data freshness, and Brier-calibrated accuracy, and a divergence penalty drops fusion confidence when estimates spread too far. The stage also reports a noise floor - the standard error of the fused estimate, from the Kish effective sample size, so uneven weighting is not mistaken for consensus. The output is a single fair probability with a conflict map, not a vote.
Gate 2: Adversarial Debate. A thesis-construction agent generates competing bull and bear cases from the fused signal. A cross-examination agent then runs five adversarial tests against each - evidence, causality, timing, liquidity, tail risk - for ten tests total. Each produces a survived/weakened/refuted outcome and a numeric score, so the debate output is a structured object, not prose.
Gate 3: Consensus Engine (no LLM). The anchored probability becomes the consensus probability; the debate's only job is confirmation. If the winning thesis disagrees with the direction by a margin of at least 1.0, the actionable profile discounts confidence by 30% rather than vetoing - the role-play debate informs sizing, it does not have absolute veto power over a measured edge. The edge must clear the market's round-trip cost (spread + slippage) and two standard errors of ensemble noise; a cheap market with a 1c spread should not trade on a 2c drift, which is a coin flip paying fees. A divergence circuit breaker still hard-blocks edges above 15%, because a model that disagrees with a liquid market that much is usually wrong. If disagreement exceeds 30% or confidence falls below 20%, consensus fails and the recommendation stage is forced to emit NO_TRADE with a structured explanation. The same applies to negative expected value. These are not LLM behaviours we hope for; they are deterministic checks the model cannot override. Every refusal writes its gate to analysis_results.no_trade_reason (consensus_failed, divergence_cap, edge_below_threshold, edge_below_significance, thesis_veto), so "why is everything NO_TRADE?" is a SQL query instead of a guess.
Memory without anchoring
Each agent's prior signals on the same market are loaded from agent_memory before each run, and an agent only sees its own history. We deliberately avoided cross-agent history because it produced anchoring - agents converging on each other rather than reasoning independently. Independence at the agent layer is what makes the disagreement index a meaningful signal. Depth is configurable through ANALYSIS_HISTORY_DEPTH, and every signal is logged back to memory and to the scorer that grades agents against outcomes.
The same rows are reused for a second purpose. Because every stored signal carries the price it was made against, we can regress each agent's forecasts on that price and recover its habitual output. A slope near 1.0 means the agent tracks the price; a slope well below 1.0 means it regresses toward 0.5 and would otherwise contribute a permanent vote for the cheaper token in every lopsided market. Fusion subtracts that fitted line before a forecast may vote, and agent-calibration-report.sql reports the slope per agent so the correction is auditable rather than assumed.
Hallucination resistance
A multi-agent LLM system is a hallucination amplifier if it isn't built carefully. Defenses are layered. Tools are real - NewsData.io, Serper, the Polymarket CLOB and Gamma APIs - and data preparation writes deterministic CSV and JSON to /tmp, so any agent quoting numbers is quoting numbers that exist. Outputs are forced through Zod schemas. The JSON extractor handles markdown code fences and balanced-brace recovery, and falls back to NO_TRADE rather than to a guess. If more than ten of fourteen agents fail to produce valid signals, the workflow aborts to NO_TRADE and the user is refunded - analysis_deliveries records that they never received the result.
Autonomous Portfolio Manager: bounded autonomy
This is where the critic asks the right question: how does an autonomous trade executor coexist with "the user is the final decision maker"? The autonomy is bounded by an Investment Policy the user signs at activation, encoded as hard, machine-checked invariants.
The activation handler validates prerequisites - subscription tier, session quota, a recurring analysis on that market, wallet balance, selected persona - and the user supplies the three things the Lambda cannot change: the market, the capital envelope, and the persona. Everything else flows from those choices.
The decision Lambda is read-only at the tool layer. Its tools fetch market data, the order book, full analysis, trade history, session performance, and agent accuracy. It has no "place order" tool. Its output is a structured decision; the Trade Executor validates that against hard limits and only then calls the CLOB. This split - the agent decides, a separate service enforces - is what lets us reason about safety properties.
The hard limits are concrete and enforced in code, not in prompts:
- Mandatory stop-loss and take-profit on every position. A trade is rejected at the executor if SL or TP is missing or out of bounds.
- Per-session loss limit at 50% of capital, cross-session at 40%. Hitting either terminates the session or trips the kill switch.
- 30-minute cooldown after a loss exit. Re-entry attempts are blocked at the executor.
- Position size cap at 50% of session capital. Concentration is bounded.
- Concurrent session limits: 3 for Pro, 10 for Elite.
- Capital conservation invariant. No trade can be sized above what the session has uninvested; the executor checks before submission.
- Mutual exclusion between Trade Executor and Position Guard. The Guard can decide to exit and the Executor can decide to enter, but the pair cannot act on the same position simultaneously, eliminating a class of double-action races.
- Token-ID resolution by outcome string, never by array index. The CLOB does not guarantee outcome ordering, and indexing by position is the bug that puts a YES order on a NO token.
- Kill switch totality. It immediately exits all positions and terminates all sessions, and it fails closed: if any check inside it errors, the system errs on the side of stopping. Re-activation requires explicit user action.
The autonomy is real, but the perimeter is auditable. The user has not handed over their wallet - they authorized a capital envelope on one market under one persona, and the system cannot exceed it by design. If the market resolves, capital depletes, the subscription downgrades, the recurring analysis is cancelled, or the kill switch fires, the lifecycle handler tears the session down and emits a notification for every state change.
What happens when a recommendation is wrong
This is the question critics should ask first. A system that only describes its successes is not one anyone should trust with money. TradeWizard is designed around the assumption that recommendations will be wrong - regularly - and the architecture's job is to contain the damage, learn from it, and get less wrong over time.
At the intelligence layer: scoring, demotion, and memory correction
Every recommendation carrying a trade action enters a pending outcome state in analysis_results. A Recommendation Scorer Lambda runs every five minutes via EventBridge Scheduler, fetches the current YES-token midpoint from the Gamma API, and checks whether take-profit or stop-loss was hit. Three outcomes are possible: target hit (success), stop-loss hit (failure), or expired after a configurable window (default 7 days) with no clear verdict - in which case no agent scoring occurs, because the market gave no clear verdict.
When a recommendation is marked failure, every contributing agent is evaluated. Aligned agents - those whose direction matched the failed recommendation - take +1 incorrect. Dissenting agents take +1 correct; they were right to dissent. Neutral agents are excluded entirely: taking no side earns neither credit nor blame.
This is not a cosmetic leaderboard. The data feeds the next analysis through fetchAgentPerformanceWeights, which queries per-market calibration first (minimum 2 scored signals per agent, at least 3 agents qualified) and falls back to global calibration over the last 30 days.
The weight formula is Brier-calibrated, blended with directional accuracy. Brier score is mean((P(YES) - realized_outcome)^2); a coin-flip forecaster scores 0.25, so Brier skill is 1 - Brier / 0.25. Perfect calibration maps to a 2.0 weight, coin-flip to ~1.0, worse-than-coin-flip is demoted toward 0.4. Directional accuracy maps into 0.5–2.0. The final weight is 0.7 × Brier weight + 0.3 × accuracy weight. A consistently miscalibrated agent isn't just lower on a dashboard - it is mathematically demoted in real time, and its fair-probability estimate counts for less in fusion. With insufficient data (cold start, new category), all agents fall back to 1.0; the system does not hallucinate confidence in its own track record.
At the Portfolio Manager layer: mechanical damage containment
When the PM enters a trade that goes wrong, containment is mechanical, not probabilistic.
Stop-loss fires. Every position has a mandatory stop-loss resting at the CLOB from entry - not a trailing stop managed by the Lambda, but an order that executes whether or not our infrastructure is available. It is placed only after confirming the SL price is present and in bounds; if both SL and TP placement fail after the BUY, the BUY is cancelled to prevent an unprotected position.
Cooldown activates. A loss exit records last_loss_exit_at; the executor checks it against LOSS_EXIT_COOLDOWN_MINUTES and records skipReason: 'cooldown' instead of trading - the automated equivalent of blocking revenge trading.
Loss limits ratchet. At 30% session loss the Risk Engine warns and sets position_size_reduction_active, halving the maximum position size for subsequent trades. At 50% the session terminates: pending orders cancel and the position exits at market through an emergency path (aggressive limit order 5% worse than best bid if a market order doesn't fill in 60 seconds). If cumulative losses cross 40% across all sessions, the Risk Engine trips the kill switch programmatically rather than waiting for the user.
Fail-closed semantics. If any step inside the kill switch errors (e.g. the CLOB is unreachable during exit), the system stops rather than retrying and continuing. Sessions are marked terminated regardless, un-exited positions are flagged for manual review, and the user is notified. Three consecutive API failures independently pause all activity.
What the user sees
A failed recommendation is a first-class event with its own notification and scoring path. The result in their history updates from pending to failure with the price at which stop-loss was hit. The agent leaderboard updates: wrong agents are visibly demoted, dissenters promoted. If the Portfolio Manager was active on that market, they receive a multi-channel notification with exit price, loss amount, and cooldown window, and the dashboard reflects the loss in real time. If a limit tripped, a separate risk-event notification explains what happened and what was stopped. The goal is not to never be wrong - impossible in probabilistic markets - but to be wrong in a way that is bounded, visible, and self-correcting.
Cost and operational shape
The market-level analysis pool is the most consequential design choice for unit economics. Analysis runs at most once per market per hour, deduped through DynamoDB with a 1-hour TTL; per-user delivery is tracked in analysis_deliveries, so a user pays one credit for an analysis they haven't seen and never twice for the same one. Recurring schedules from many users on one market coalesce to the shortest active interval. At scale this turns ten thousand users requesting the same popular market into one Nebius inference run, while still collecting ten thousand credits of attribution - the failure mode of naive per-user execution is bankruptcy.
Delivery has the same shape: SNS fan-out triggers WebSocket, email, push, and webhook Lambdas in parallel, each respecting quiet hours, preferences, and plan availability. Stale WebSocket connections are cleaned up on 410 Gone, the SQS DLQ retries failed dispatches three times with exponential backoff, and any failure refunds all subscribers - not just the requester - because under coalescing a failed analysis affected everyone.
Challenges we ran into
The autonomy paradox. "Human is the final decision maker" and "autonomous trade execution" sound contradictory. We landed on bounded autonomy expressed as machine-checked invariants the user pre-authorizes. The breakthrough was separating the agent's decision authority from the executor's enforcement authority, and treating the kill switch as a fail-closed totality rather than a feature.
LLM determinism is a fantasy; pipeline determinism is achievable. Early prototypes tried to make the model behave consistently. That never worked at the tail. The fix was to stop asking the model to be deterministic and bracket it with deterministic stages - fusion, consensus, EV check, schema validation, divergence threshold. The LLM produces signals; the pipeline decides what to do with them.
Agreement is not consensus. When all 14 agents agree, that's frequently a sign they're all looking at the same news item, not that the market is clear. Our first version under-weighted divergence. We added the divergence penalty and the 30% disagreement gate, and made each agent see only its own history. Counter-intuitively, the system became more useful once we let it refuse to answer.
Cost runaway under naive deduplication. Initial designs cached per user, which is the same as not caching. The market-level pool fixed it, but forced us to redesign delivery accounting end-to-end.
Token ID and outcome ordering on the CLOB. Outcome arrays are not stably ordered. An executor that indexes YES at [0] will eventually place a YES position on a NO token. We rewrote the resolver to match by outcome string and added a regression test.
Exits are more expensive than entries. We made SL and TP mandatory at the executor layer rather than the prompt layer, because prompts are persuasive and executors are not.
Graceful degradation without lying. Partial agent failure must not crash the pipeline, but it also must not masquerade as success. We degrade the run, surface what failed, abort to NO_TRADE if the failed share crosses a threshold, refund the credit, and tell the user.
Accomplishments that we're proud of
- A multi-agent system that is allowed to refuse. When disagreement is above 30% or expected value is non-positive, TradeWizard returns
NO_TRADEwith a structured explanation and does not bill the user. Most "AI trading" products are constitutionally incapable of saying "we don't know." Ours is built around it. - Three deterministic gates around the LLMs. Fusion and consensus are non-LLM stages; so are schema validation and EV rejection. Fusion de-biases every agent against its own calibration line, scales the surviving edge by how much evidence supports it, and reports its own noise floor; consensus then asks whether the edge pays for the trade and whether it is distinguishable from that noise. Weights are Brier-calibrated from resolved outcomes rather than assigned by intuition.
- Gate changes are measured before they ship. Every analysis computes an agent-driven (shadow) consensus beside the live one, and both are graded on the same fixed price move. The knobs that decide whether a trade happens are environment variables over pure functions, so a threshold can be argued about with recorded outcomes instead of re-read in a prompt.
- Bounded-autonomy execution. Fail-closed kill switch, mandatory SL/TP, hard loss limits, cross-session caps, cooldowns, capital conservation, executor/guard mutual exclusion, and token-ID resolution by outcome. The Portfolio Manager's perimeter is small and provable.
- A market-level analysis pool with per-user delivery accounting. Costs scale with markets analyzed, not users requesting; users pay only for analyses they actually receive, exactly once. The whole substrate idles at fifteen to twenty dollars a month with no NAT, no ElastiCache, and no always-on compute.
- Multi-channel delivery that respects preferences. WebSocket, email, push, webhook - each with quiet hours, thresholds, and plan-based gating. Kill-switch and loss-warning events override quiet hours because some events are too important to wait.
- End-to-end TypeScript, multi-model inference on Nebius Token Factory. One language across CDK, Lambdas, Strands agents, and frontend. Seven capability buckets resolve to open models - no single model bottleneck, no Python runtime in the agent path, no vendor-specific agent code.
What we learned
- Refusing to recommend is a feature, not a failure mode. The most professional thing a trading system can do under high disagreement is decline. Critics expect AI products to over-recommend; ours under-recommends on purpose, and the design makes under-recommending easy.
- Independence beats agreement at the agent layer. Cross-agent history made our agents more confident and less informative. Per-agent isolated memory made disagreement signal-bearing.
- The right place to enforce safety is below the LLM, not inside it. Prompts that say "always set a stop-loss" will eventually be ignored. Executors that reject any trade missing one never will.
- Dedup is product strategy, not infrastructure. A market-level pool reshapes unit economics; the credit-and-delivery model has to be built around it from the start.
- You can't separate analysis from execution and call the job done. The hard part of retail trading is the gap between the recommendation and the trade. The Portfolio Manager exists because that gap is where users get hurt.
What changed during the submission period
TradeWizard's product surface and deterministic execution layers predate this hackathon. The submission-period work covered the inference port, the analysis calibration pass, and the product surface:
- Extracted the provider boundary into
infra/services/shared/ai-provider.ts, so both pipelines resolve models through a capability mapping instead of vendor-specific constructors. - Added the Nebius Token Factory registry: seven capability buckets, env-driven model IDs, per-capability token limits, and a hard invariant that tool-using agents cannot map to the non-tool model.
- Integrated Token Factory through Strands'
OpenAIModelwith the Chat Completions surface, Secrets Manager key loading with an in-process cache, and cold-start validation that fails when a model ID is missing. - Added
validate-nebius.tsto check model availability, tool calling, and JSON extraction before deployment. - Rebuilt signal fusion around market-anchored log-odds: per-agent calibration re-centres each forecast on the price before it votes, evidence-scaled pass-through decides how much ensemble edge survives, and the stage reports a standard-error noise floor. Rebuilt consensus around that anchored probability, with a gate profile deriving the edge floor from the market's own spread, a two-standard-error significance floor, thesis confirmation, a confidence floor, and a divergence circuit breaker.
- Added the measurement loop that makes gate changes arguable: a shadow consensus on every analysis (never shown to users), fixed-horizon live-vs-shadow P&L scoring, a machine-readable
no_trade_reason, andagent-calibration-report.sqlto read all three back. - Redesigned the frontend around the product narrative - landing page with animated pipeline demos, cleaner market detail, redesigned portfolio/autopilot surface, mobile navigation - and added the Remotion compositions behind the demo videos.
- Kept the deterministic gates, risk engine, executor, and kill switch unchanged. The port and calibration pass were not allowed to weaken the system's safety properties.
The design constraint throughout: the provider should be replaceable without weakening the parts of the system users depend on, and the probability pipeline should stay accountable to the market it is trying to beat.
Feedback on Nebius Token Factory
These are integration notes from building against Token Factory, not a review of the product roadmap.
What worked well. The OpenAI-compatible Chat Completions surface made the port small. Strands already had an OpenAIModel adapter, so the boundary was mostly pointing it at a different baseURL, supplying a key resolver, and mapping capabilities to model IDs. We did not have to rewrite prompts, tool definitions, or the deterministic pipeline.
What required care. Tool calling is the contract that matters for this workload, and it is not uniform across a catalog. We added validate-nebius.ts because a model ID existing in /v1/models is not the same as that model returning usable tool_calls. Every tool-capable bucket is verified before deployment, and the non_tool bucket exists so synthesis stages do not silently inherit a tool-use requirement they do not need.
Where more would help. Account-level dynamic rate limits suit a shared service but make fixed RPM planning unreliable, so we routed throttling through the same partial-failure path as any other agent failure; more per-account observability around 429s and concurrency would make that easier to tune. On routing, keeping the agent-to-capability mapping observable when a model changes underneath it is the hard part - a first-class capability or alias concept on the platform side would remove a lot of environment bookkeeping.
NVIDIA Nemotron 3 Super. We put it on the most demanding inference path in the system: multi-step news and research tasks where the model has to call tools and decide what to do with the results. That is a different workload from single-turn synthesis, and it is the right place to spend the agentic bucket.
What's next for TradeWizard
- Model performance benchmarking. Routing is live across seven capability buckets. Next is systematic quality and cost benchmarking per agent category, with automated routing updates when a model's price-to-quality ratio shifts.
- Agent specialization and ablation. With a leaderboard backed by real outcomes, we can retire under-performing agents, split strong ones into specialized variants, and run A/B comparisons with statistical rigor.
- Verticals beyond politics. The architecture is event-agnostic. Macro and central-bank decisions are next, then sports and entertainment - each domain inherits the same workflow with domain-specific tools. In parallel, analysis becomes portfolio-aware: recommendations conditioned on existing exposure, with correlation-aware sizing and cross-market hedges.
- Institutional surface. A research-grade API for hedge funds and political-risk firms, with audit logs, signed reasoning chains, and SLA-backed delivery. The intelligence layer is already explainable enough; the work is packaging.
- Public performance reporting. We track recommendation accuracy internally. Publishing it, with methodology, is a moat - as is turning every newly observed failure mode into a deterministic check rather than a prompt instruction.
TradeWizard is a product. It is also a system designed assuming critics would read every line. The agent league produces signals; the deterministic gates decide what the user sees; the executor enforces what the autonomous Portfolio Manager is allowed to do; the kill switch ends everything if it has to. The user always retains the perimeter - they choose the market, the capital, the persona, and the off switch - and inside that perimeter, an AI hedge fund of fourteen specialists works the problem twenty-four hours a day.
Built With
- amazon-web-services
- nebius
- nextjs

Log in or sign up for Devpost to join the conversation.