-
-
System Architecture
-
Evaluation Score
Inspiration
Our traditional e-commerce search assumes that shoppers like ourselves, already know exactly what we want. However, real shoppers often have only a vague idea and discover their preferences through conversations. We wanted to build an AI shopping assistant that could understand these minute preferences and uncover the product the shopper actually had in mind just by a few conversations.
What it does
ShopMind Shopping Copilot is a conversational product-search agent for TechJam Track 4. A hidden simulated shopper reveals what they want one reply at a time; the agent must put the shopper's hidden target product into a list of at most 10 parent_asin values — as high as possible, in as few turns as possible.
The agent uses only the frozen product catalog and the text revealed in the current conversation — never evaluator labels or sample IDs. It optionally calls OpenAI gpt-4.1-mini for intent parsing and semantic reranking, and otherwise runs a fully deterministic, offline, byte-reproducible pipeline. The mode is chosen by whether an API key is present — not by any command.
Impact & Relevance
Most product search assumes the shopper can already name what they want — but a huge share of real shopping is exploratory. ShopMind turns that vague, conversational discovery into a solved problem: it asks the fewest, most informative questions and surfaces the right product in a handful of turns. Because the scored pipeline is fully deterministic and offline, it deploys at zero inference cost and with no external dependencies, and the architecture is catalog-agnostic — the same approach applies to any large product catalog, from fashion to electronics to grocery. The optional LLM layer means teams can dial capability up or down against their own budget without changing a line of the core system.
System Architecture
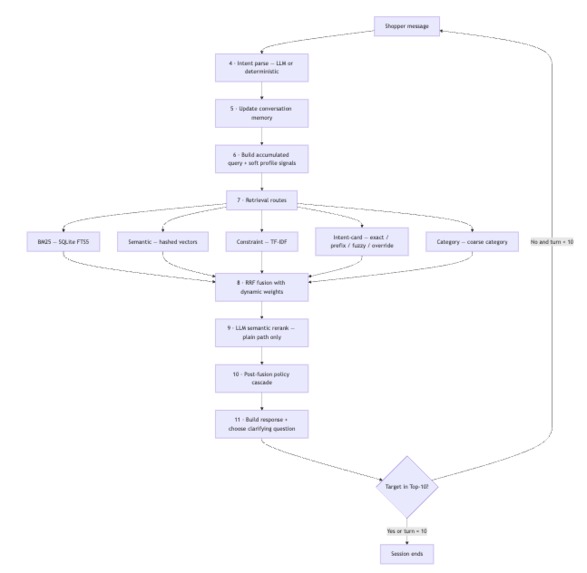
The agent runs a five-stage pipeline every turn:
- Intent parsing — classifies the conversation mode (buying, browsing, or intent override) and extracts structured constraints like category, material, budget. Uses gpt-4.1-mini when available; falls back to a deterministic regex-based parser.
- Conversation memory — tracks active requirements, retired intent after an override, declined attributes, already-asked questions, and a stable recommendation ladder, all isolated per session.
- Parallel retrieval — five complementary routes run simultaneously: BM25 (SQLite FTS5), constraint TF-IDF, catalog-derived intent-cards (exact/prefix/fuzzy matching), exact-category lookup, and semantic hashed-vector search.
- Intent-aware rank fusion — Reciprocal Rank Fusion with dynamic weights and an adaptive fusion constant. As constraints accumulate, fusion shifts trust toward structured evidence; after an intent override, it leans on semantics.
- Semantic reranking — an LLM reranker (gpt-4.1-mini) reorders the top candidates by title relevance. Falls back to the fusion order on failure. Offline alternative: a local cross-encoder via fastembed.
- Response policy — emits the Top-10 and picks the single most useful clarification question, prioritising LLM-suggested attributes, then open questions, then a fixed attribute sequence — without repeating declined or already-answered attributes.
User message + conversation state + profile │ ▼
- Intent parsing
│ ▼ - Conversation memory │ ▼
- Retrieval (parallel) BM25 · semantic · constraint · intent-cards · category │ ▼
- Rank fusion intent-aware RRF + dynamic weights │ ▼
- Semantic reranking
│ ▼ - Response policy Top-10 + one clarification question
Tools, APIs & Libraries
| Tool / Library | Purpose |
|---|---|
| Python 3.10+ | Core language |
| NumPy | Vector operations, scoring, and the only runtime dependency for the deterministic path |
| SQLite FTS5 | BM25 full-text search over the product catalog |
| OpenAI gpt-4.1-mini | Optional intent parsing and semantic reranking (LLM mode only) |
| fastembed (optional) | Offline cross-encoder reranking via ONNX weights; degrades to identity if absent |
| pytest | Test suite (123 tests covering contracts, adversarial inputs, and regressions) |
Dataset
The agent is built on the Amazon Reviews 2023 dataset (McAuley Lab, UCSD), specifically the Clothing_Shoes_and_Jewelry category. The frozen catalog contains 50,000 products with text and metadata fields only — no images or reviews. The public development set has 200 sessions (80 Buying, 80 Browsing, 30 Intent Override,de
Challenges we ran into
One of the biggest challenges we faced was balancing the coverage, speed and accuracy. One highly confident product can improve its ranking but risks missing the target, while showing many products improves coverage but can dilute the ranking.
We also had to handle edge cases whereby shoppers change their minds, paraphrase their requirements or state that they have no preference for certain attributes. Another challenge we faced was ensuring that the system could continue operating reliably in an offline evaluation environment.
Accomplishments that we're proud of
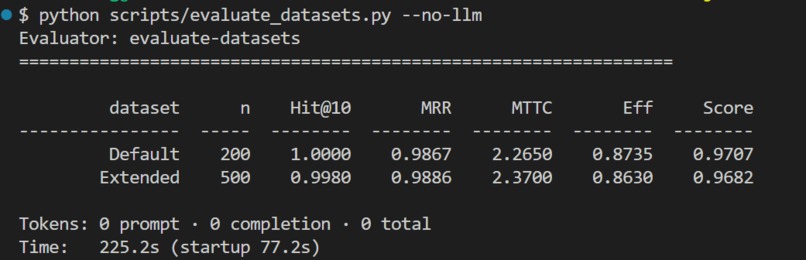
We managed to achieve a robust retrieval and ranking pipeline of 0.9707 Technical Score on the default public dataset. We are also quite proud of making our system resilient to paraphrased requirements and implementing an offline cross-encoder reranking stage that requires zero network access and zero API tokens.
What we learned
Through this project, our team learnt that developing an AI shopping agent involves more than just having a LLM. Decision-making, ranking strategies, conversation state, evaluation scores must all work together.
We also learnt how important it is to evaluate every component individually. Some approaches such as replacing the lexical embeddings with pretrained semantic embeddings, did not improve the overall system. This allows us to understand the importance of measuring changes against held-out data rather than assuming that a more sophisticated model will always perform better.
Improvements over baseline
The organizer-provided weak BM25 baseline scores 0.107 TechnicalScore on the 200 public sessions (Hit@10 0.125, MRR 0.068, MTTC 9.81). Key improvements:
| Improvement | Effect |
|---|---|
| Multi-route retrieval (BM25 + constraint + intent-card + category + semantic) | Hit@10 from 0.125 to ~0.95; single BM25 misses structured constraints entirely |
| Intent-aware RRF with dynamic weights | Fuses complementary routes; adapts trust per turn and constraint count |
| Conversation memory + intent override detection | Handles mid-session mind-changes; prevents stale constraints from dominating |
| Catalog-derived intent-cards with fuzzy/prefix fallback | Exact + approximate matching of disclosed attributes against catalog fields |
| Fusion-seeded late-turn exploration | Lifts coverage on hard turn-10 boundary sessions |
| Proactive clarification strategy | Asks one targeted follow-up per turn, reducing average MTTC from 9.81 to 2.27 |
| LLM intent parsing (gpt-4.1-mini) | Structured JSON extraction of mode, constraints, and confidence; falls back to deterministic on failure |
| LLM semantic reranking | Reorders top candidates by title relevance; optional local cross-encoder alternative via fastembed |
| Whole-run fallback latch | Instant, permanent degradation to deterministic on first network failure — no per-turn penalty |
Final results vs baseline (0.107 TechnicalScore): | Mode | Public (200) | Extended (500) | |---|---:|---:| | Deterministic | 0.9707 (+807%) | 0.9682 | | LLM (gpt-4.1-mini) | 0.9384 (+777%) | 0.8886 | | LLM (gpt-4.1-nano) | 0.9471 (+785%) | 0.8904 |
What's next for Track 4 - ShopMind Shopping Copilot
Our next steps to make ShopMind even more advanced is to learn route weights from session-outcome features with strict cross-validation. Secondly, to estimate question value from candidate-pool entropy (beyond LLM suggestion). We also hope to achieve richer numeric parsing for size and price ranges, as well as cross-session profile learning (profiles are per-session today).
Our long-term goal is to move beyond finding the right product, but to also build a shopping copilot that can truly understand a shopper's intent and guide them towards the best decision.


Log in or sign up for Devpost to join the conversation.