-
-
Threads Insight Ingestion
Inspiration
Social media platforms like Meta Threads generate massive volumes of raw, unstructured conversational data—riddled with slang, hashtags, informal banter, and erratic formatting. For data analysts, extracting structured insights from these messy text dumps usually requires brittle regular expressions or manual cleaning, both of which carry the risk of exposing Personally Identifiable Information (PII).
While initially exploring a standard Retrieval-Augmented Generation (RAG) architecture, we realized the more critical bottleneck in modern data engineering is turning chaotic, unstructured inputs into deterministic, schema-compliant payloads. That realization inspired the Threads Insight Pipeline: a privacy-first, minimalist analytics workbench designed to ingest raw scraped Threads posts, strip PII at the ingestion boundary, and output strictly validated JSON alongside clean category and demographic distributions.
What it does
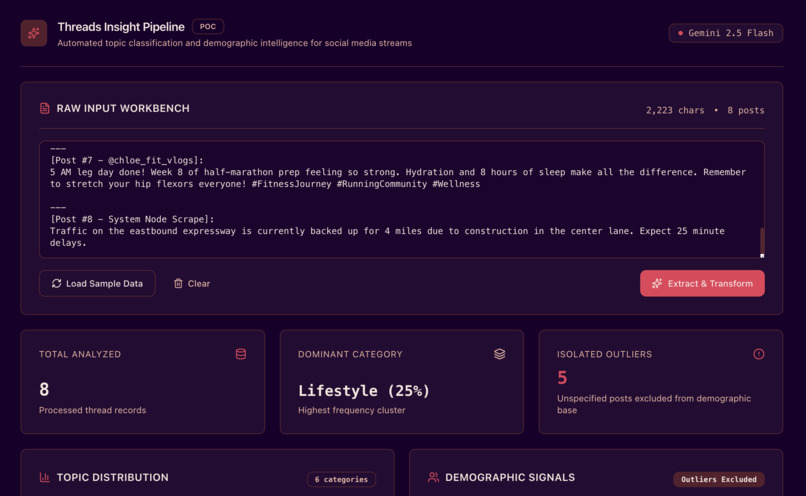
Threads Insight Pipeline is a single-surface analytics workbench that transforms messy social media text dumps into structured, privacy-safe datasets and visual distributions:
- Data Ingestion & Instant Demo Loop: Analysts can paste arbitrary raw scraped Threads posts or click "Load Sample Scraped Data" to instantly populate realistic noisy posts (complete with hashtags,
@mentions, and slang) to test the pipeline in under 60 seconds. - Automated PII Sanitization: Cleans and strips personal identifiers—including usernames, handles, email addresses, and phone/contact references—producing a verified zero-PII record table.
- Category & Topic Classification: Evaluates each post and maps it into a predefined taxonomy (
Politics,Sports,Tech,Business,Entertainment,Lifestyle), calculating real-time proportional breakdowns. - Outlier-Aware Demographic Inference: Analyzes linguistic cues to infer Age Group (Gen Z / Youth, Millennial / Young Adult, Mature Adult) and Gender, while isolating ambiguous posts as
"Unspecified"outliers so they never distort known demographic percentages. - Schema-Validated JSON Export: Pairs a human-readable Clean Records Table with a syntax-highlighted Raw Validated JSON viewer and a one-click "Copy JSON" action for immediate downstream integration.
How we built it
We approached the project using a spec-driven, plan-first workflow—establishing strict proof-of-concept (POC) requirements and UI states before writing application code.
- Frontend Architecture & UI: Built on a rigid, flexible 12-column grid inspired by
shadcn/ui. We used a high-contrast neutral slate/zinc palette,Intersans-serif typography, and monospace accents for the JSON inspector. To maintain an objective enterprise aesthetic, we enforced a strict no-emoji policy, relying exclusively on functional Lucide/SVG icons. - Client-Side Pre-Validation: Implemented immediate input checks on the "Extract & Transform" action. Empty or whitespace-only submissions trigger an inline error alert right above the action bar, preventing unnecessary network requests.
- Backend Extraction & Transformation Pipeline: Offloaded all heavy LLM extraction and statistical aggregation to the server to keep the client bundle lightweight. The backend sanitizes raw strings, enforces a deterministic JSON schema for classification, and computes category and demographic distributions before returning the payload.
- Resilient State Management: Designed explicit visual states for every stage of the core journey—from an unobtrusive Empty State and skeleton-loaded Processing State to a non-destructive Service Failure State that preserves the analyst's raw input and provides an inline "Retry" mechanism.
Challenges we ran into
- Demographic Ambiguity & Mathematical Distortion: Short-form social posts often lack enough linguistic context to determine age or gender. Initially, treating
"Unspecified"posts as a standard slice of the pie chart heavily skewed the distributions and compressed the visibility of identified demographics. To preserve analytical integrity, we separated the underlying math: - Category Distribution: Every post maps to a primary topic, so the proportion $P(c)$ for category $c$ across $N$ total processed posts is calculated across the full dataset:
$$P(c) = \frac{n_c}{N} \times 100\%$$
- Outlier-Adjusted Demographic Distribution: Posts lacking clear demographic signals are isolated into an outlier count $U$. The percentage $P(d_i)$ for an identified demographic group $d_i$ is computed strictly against the subset of posts with recognizable signals ($N - U$):
$$P(d_i) = \frac{n_{d_i}}{N - U} \times 100\% \quad \text{where} \quad N - U = \sum_{j=1}^{k} n_{d_j}$$
When $N - U = 0$, the pipeline gracefully defaults to $0\%$ rather than dividing by zero, displaying $U$ in a dedicated Unspecified Outliers counter badge.
- Enforcing Deterministic Schema Compliance: LLMs can occasionally hallucinate JSON keys or invent categories outside the defined taxonomy when parsing heavy internet slang. Shaping the structured-output constraints and validation boundaries required strict enumeration enforcement and graceful fallback error handling.
- Scoping Against Brittle Scrapers: Direct live scraping of Meta Threads introduces login walls, rate limits, and brittle DOM dependencies. We made the deliberate product decision to defer live scraping and focus strictly on the data ingestion, sanitization, and schema-validation kernel.
Accomplishments that we're proud of
- Zero-PII Analytical Integrity: Building an extraction pipeline that strips personal identifiers before structuring the output, proving that rich aggregate insights do not require compromising individual user privacy.
- Frictionless 60-Second Walkthrough: Combining the one-click sample loader, skeleton loading states, metric cards, and tabbed/split JSON inspector into a cohesive 12-column workbench that feels like a production-ready internal tool.
- Mathematically Sound Outlier Handling: Solving the "missing signal" problem in AI demographic inference by separating known distributions from unspecified outliers ($U$) directly in both the backend aggregation logic and the frontend badge UI.
What we learned
- LLMs as Typed Transformation Functions: Moving from conversational prompting to structured data extraction requires treating the model like a strict compiler step. Enforcing explicit schemas and enums at the boundary eliminates downstream UI rendering bugs.
- Statistical Honesty in Dashboard Design: How an analytics tool represents missing or low-confidence AI classifications is just as important as the classifications themselves. Excluding $U$ from the percentage denominator $N - U$ while surfacing it as an explicit badge gives analysts both clean ratios and full visibility into data coverage.
- The Power of Spec-Driven Development: Drawing on formal software engineering practices to lock down our Product Requirements Document (PRD), states, and non-goals early prevented scope creep and kept our focus squarely on validation and error handling.
What's next for Threads Insight Pipeline
- Multi-Format Export: Adding one-click CSV and Apache Parquet file exports alongside the existing JSON clipboard copy so analysts can drop sanitized datasets directly into Python/Pandas, DuckDB, or BI tools.
- Custom Taxonomy Configuration: Allowing analysts to define their own custom classification categories and extraction schemas directly from the dashboard UI before running the pipeline.
- Persistent Workspace History: Introducing optional local or database-backed session storage so teams can compare historical batches of scraped posts across different campaigns over time.
- Batch File Ingestion: Expanding the input surface beyond raw text pasting to support drag-and-drop
.txt,.jsonl, and raw scraper log files.
Built With
- css3
- data-analytics
- data-pipeline
- data-sanitization
- etl
- html5
- json-schema
- llm
- lucide-icons
- natural-language-processing
- nextjs
- node.js
- pii-redaction
- prompt-engineering
- react
- rest-api
- shadcn-ui
- structured-outputs
- tailwindcss
- typescript
- zod

Log in or sign up for Devpost to join the conversation.