Inspiration
Third Eye was inspired by a real-world accessibility challenge: how can blind and visually impaired people better understand the objects and surroundings around them?
I wanted to explore how computer vision could help address this problem by identifying objects through a camera and making environmental information more accessible.
What it does
Third Eye is an experimental blind-assistance prototype that uses a phone camera as its video source while processing the footage on a laptop.
The system has three main components:
Object detection and tracking: YOLO detects selected objects, while ByteTrack tracks them across video frames.
Proximity-based alerts: Custom heuristics use object position, bounding-box size, and changes over time to identify potentially concerning obstacles.
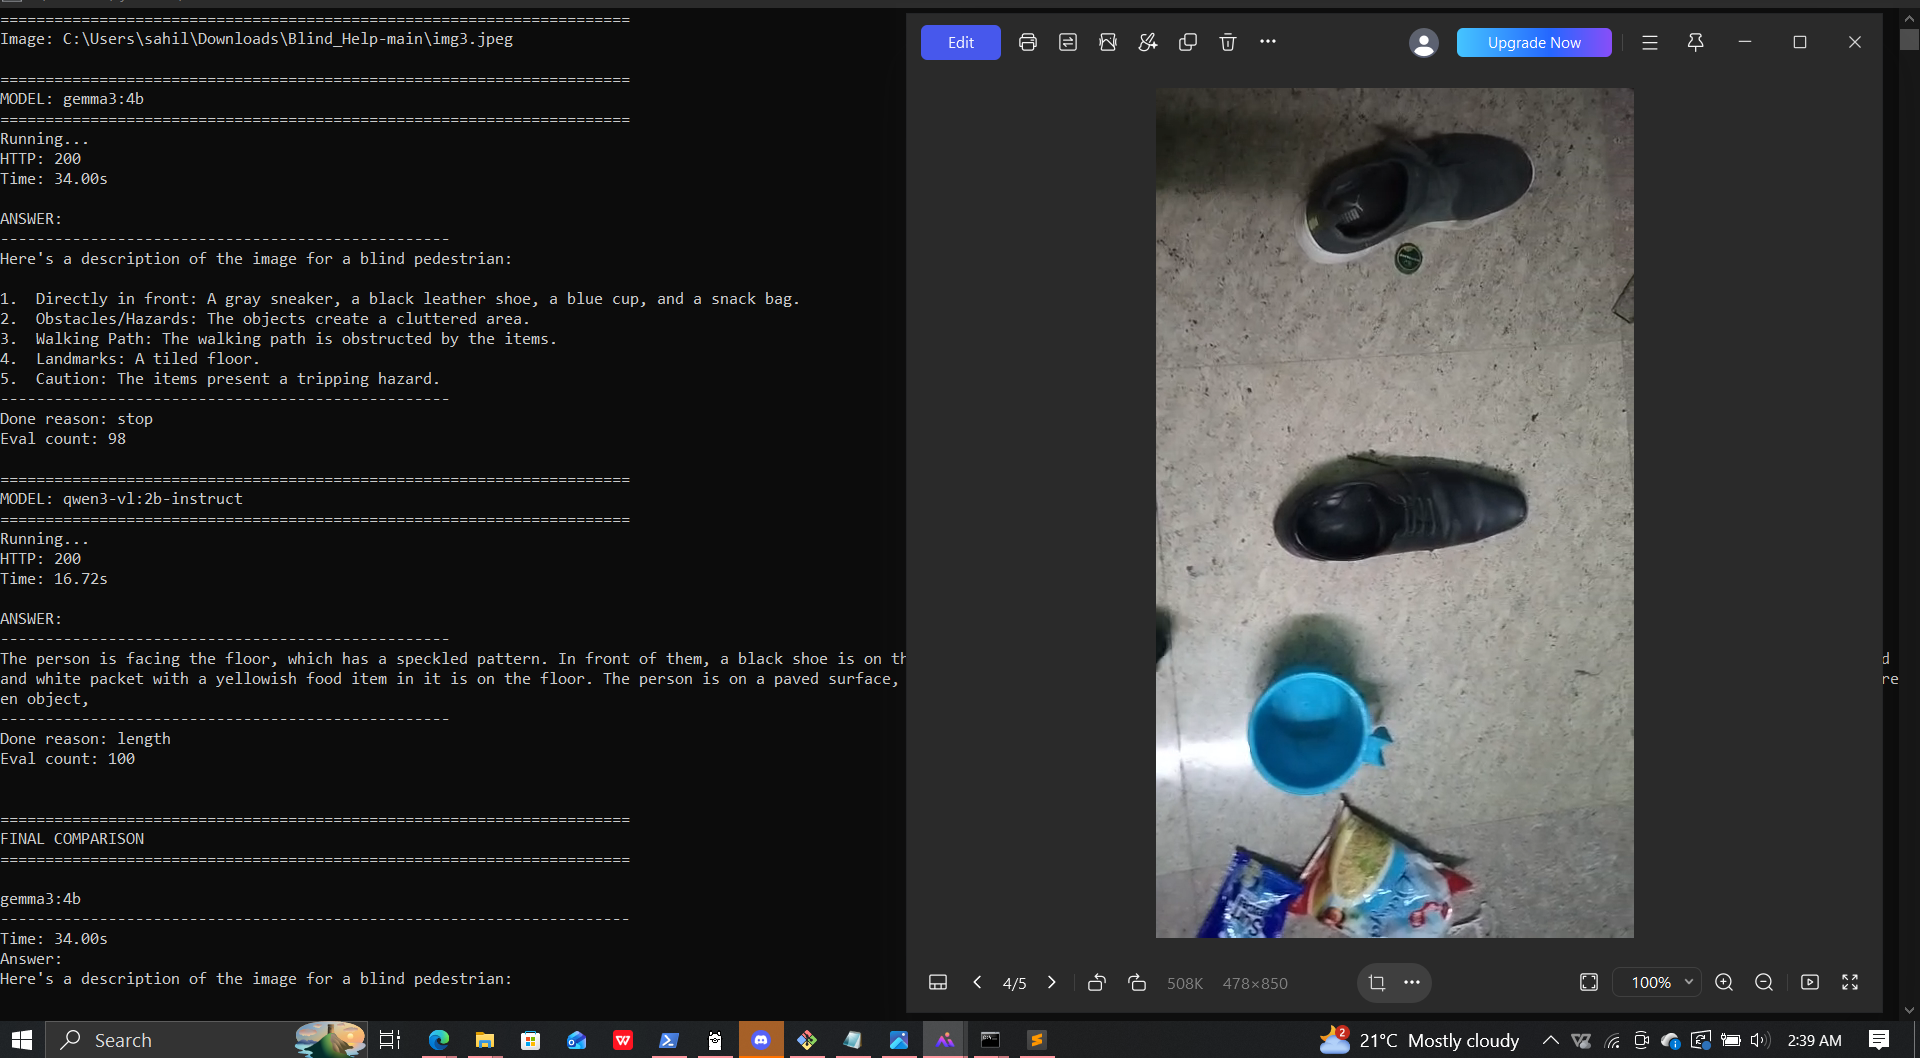
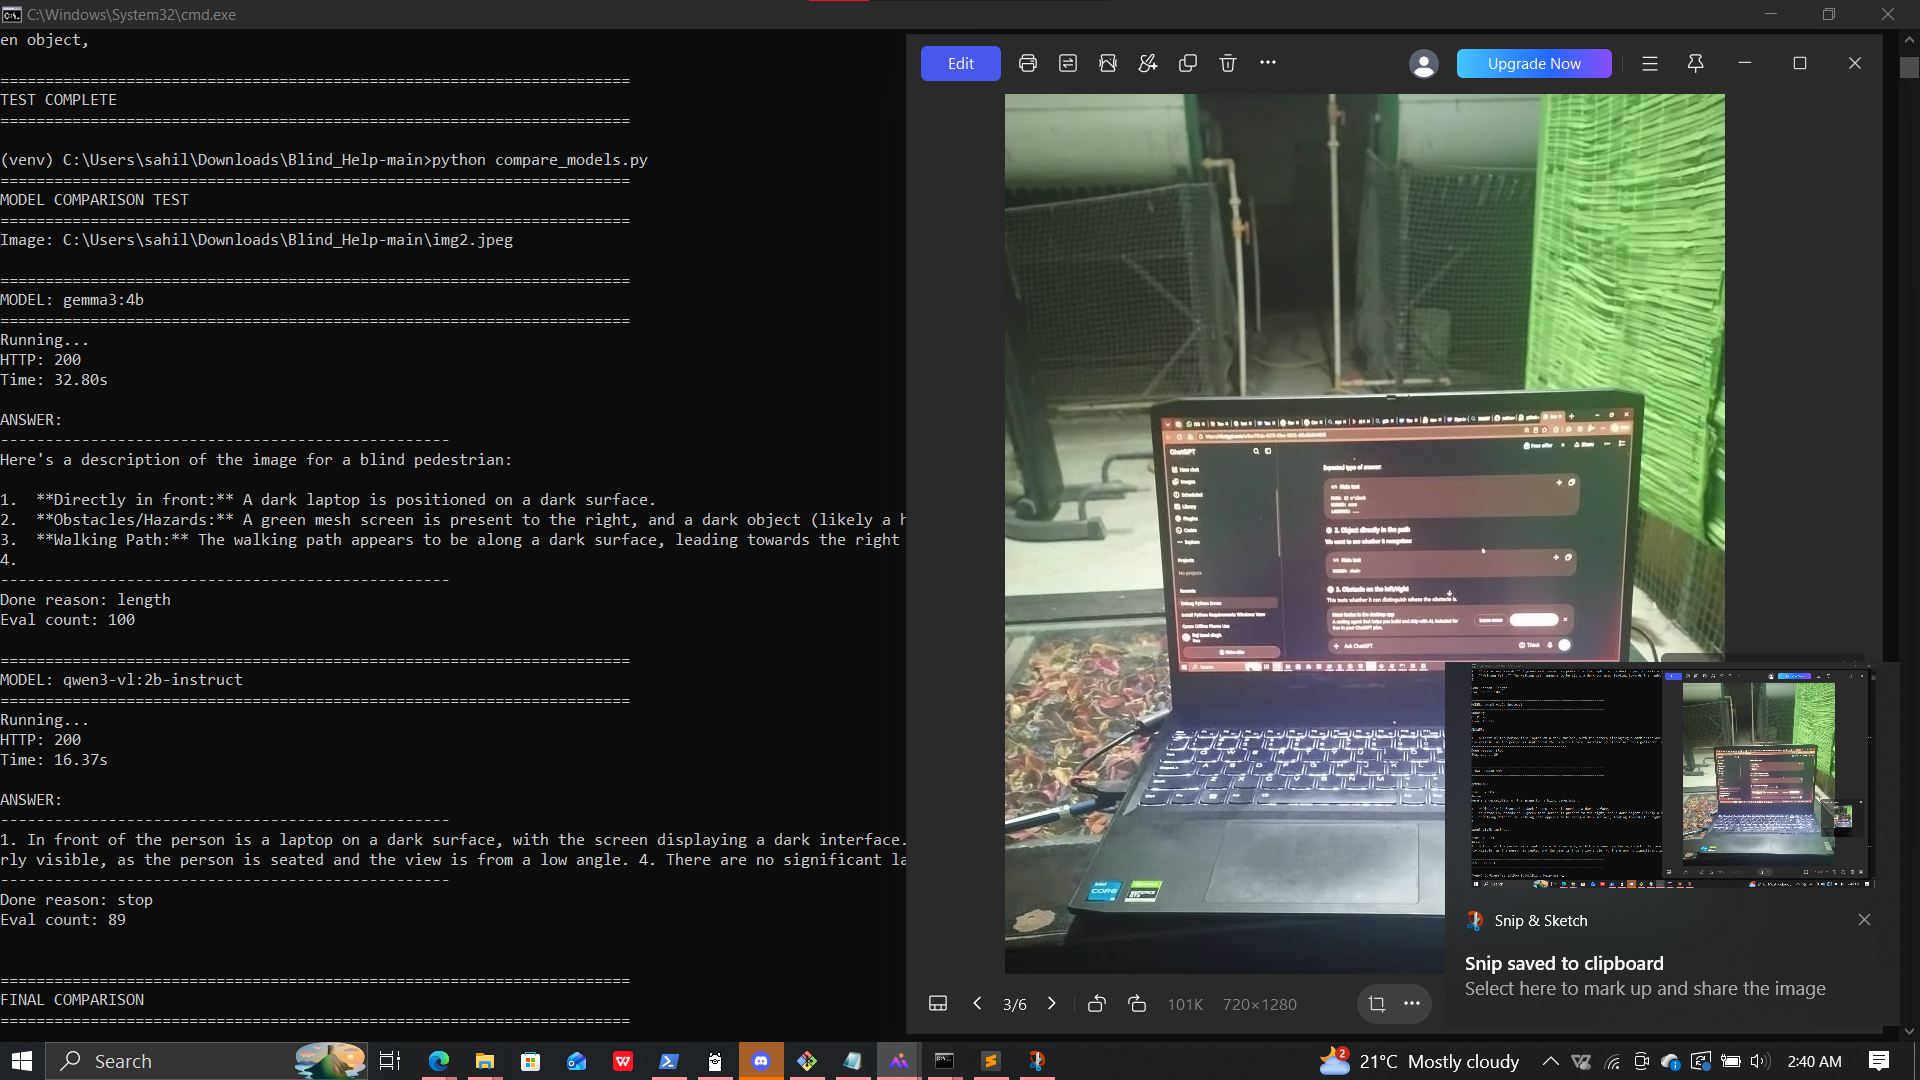
AI scene understanding: Gemma 3, running through Ollama, is integrated to describe the surroundings and answer questions about camera images.
The prototype also includes a voice-interaction pipeline using Whisper for speech recognition and Windows text-to-speech for spoken responses. However, the spoken feedback system is not yet working reliably and requires further debugging.
I am also exploring how Google Maps could be integrated in a future version, allowing users to select or mark destinations and potentially connect location information with environmental assistance. This functionality is still in the planning and development stage
How we built it
I built Third Eye in Python using several computer-vision and AI technologies:
OpenCV for camera capture, frame processing, and the live video interface.
YOLO11 for object detection.
ByteTrack for tracking objects across frames.
Custom Python logic for proximity-based alerts and approximate time-to-collision estimates.
Gemma 3 and Ollama for local AI-powered scene understanding.
Faster-Whisper for speech recognition.
Windows SAPI for text-to-speech output.
The application uses separate threads for camera capture, object detection, AI processing, and audio output. The local AI pipeline is designed to process images on the laptop, with an optional cloud backend also available.
Challenges we ran into
One of the biggest challenges has been balancing real-time object detection with the computational demands of running an AI vision model on the same machine.
Camera connectivity, model initialization, concurrent processing, and response latency have also required attention.
Another major challenge is the audio pipeline. Although the application includes speech recognition and text-to-speech components, spoken feedback is not yet reliable, so debugging and integration remain important tasks.
Reliable obstacle awareness is also difficult. Bounding-box size and movement can provide rough proximity clues, but they cannot guarantee accurate physical distance or predict every collision.
Integrating navigation and destination selection through Google Maps presents another challenge because location-based guidance must work coherently with the camera-based assistance system.
Accomplishments that we're proud of
I am proud to have developed a prototype that brings together several AI and computer-vision components in a single application.
Some of the key accomplishments include:
Connecting a phone camera feed to a live computer-vision pipeline.
Integrating YOLO object detection with ByteTrack object tracking.
Developing custom proximity-based alert logic.
Integrating Gemma 3 through Ollama for scene understanding.
Designing a modular architecture for camera processing, AI inference, and audio feedback.
Establishing a foundation for future voice interaction and location-aware assistance.
This project has given me the opportunity to work through the practical challenges of building an integrated AI system rather than experimenting with a model in isolation.
What we learned
I learned that building an assistive AI application involves much more than detecting objects. Responsiveness, reliability, audio feedback, model limitations, and user experience all matter.
I also learned how object detection and vision-language models can complement each other: object detection identifies specific objects, while a vision model can provide broader descriptions of a scene.
Debugging the spoken feedback pipeline has reinforced the importance of testing every component independently before relying on the complete system.
Most importantly, I learned that assistive technology must be developed responsibly. A working prototype is only an early step toward a dependable tool, and real-world reliability requires extensive testing and user feedback.
What's next for Third Eye
The next stage is to improve the existing prototype and gradually expand its capabilities.
Planned improvements include:
Debugging and stabilizing spoken feedback and voice interaction.
Improving object detection and reducing false alerts.
Evaluating proximity estimates and alert timing.
Improving the speed and reliability of scene descriptions.
Exploring Google Maps integration for destination selection and marking.
Investigating how location information could complement camera-based environmental awareness.
Exploring mobile deployment to reduce dependence on a laptop.
Conducting usability and safety testing with appropriate feedback from visually impaired people.
The long-term vision for Third Eye is to combine environmental awareness with location-based assistance in a more portable and accessible system.
Current status: Experimental laptop-based prototype under active development. Google Maps integration is planned, and spoken feedback still requires debugging. The system is not a validated mobility aid and should not be relied upon as the sole means of navigation or obstacle avoidance.
Built With
- ollama
- openai
- opencv
- whisper
- yolo
