-
-
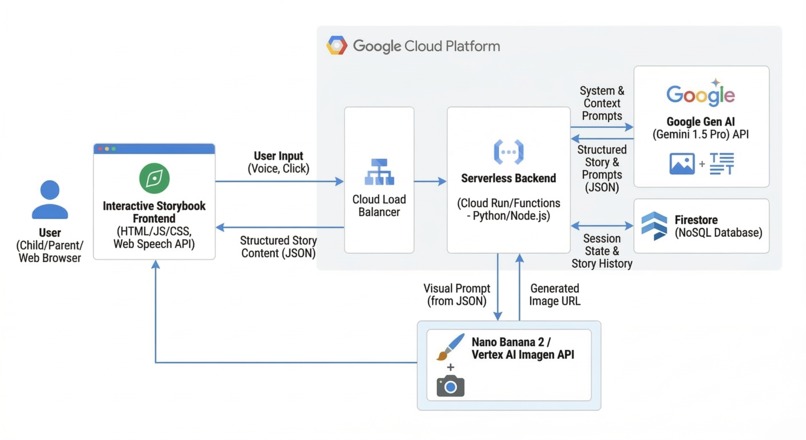
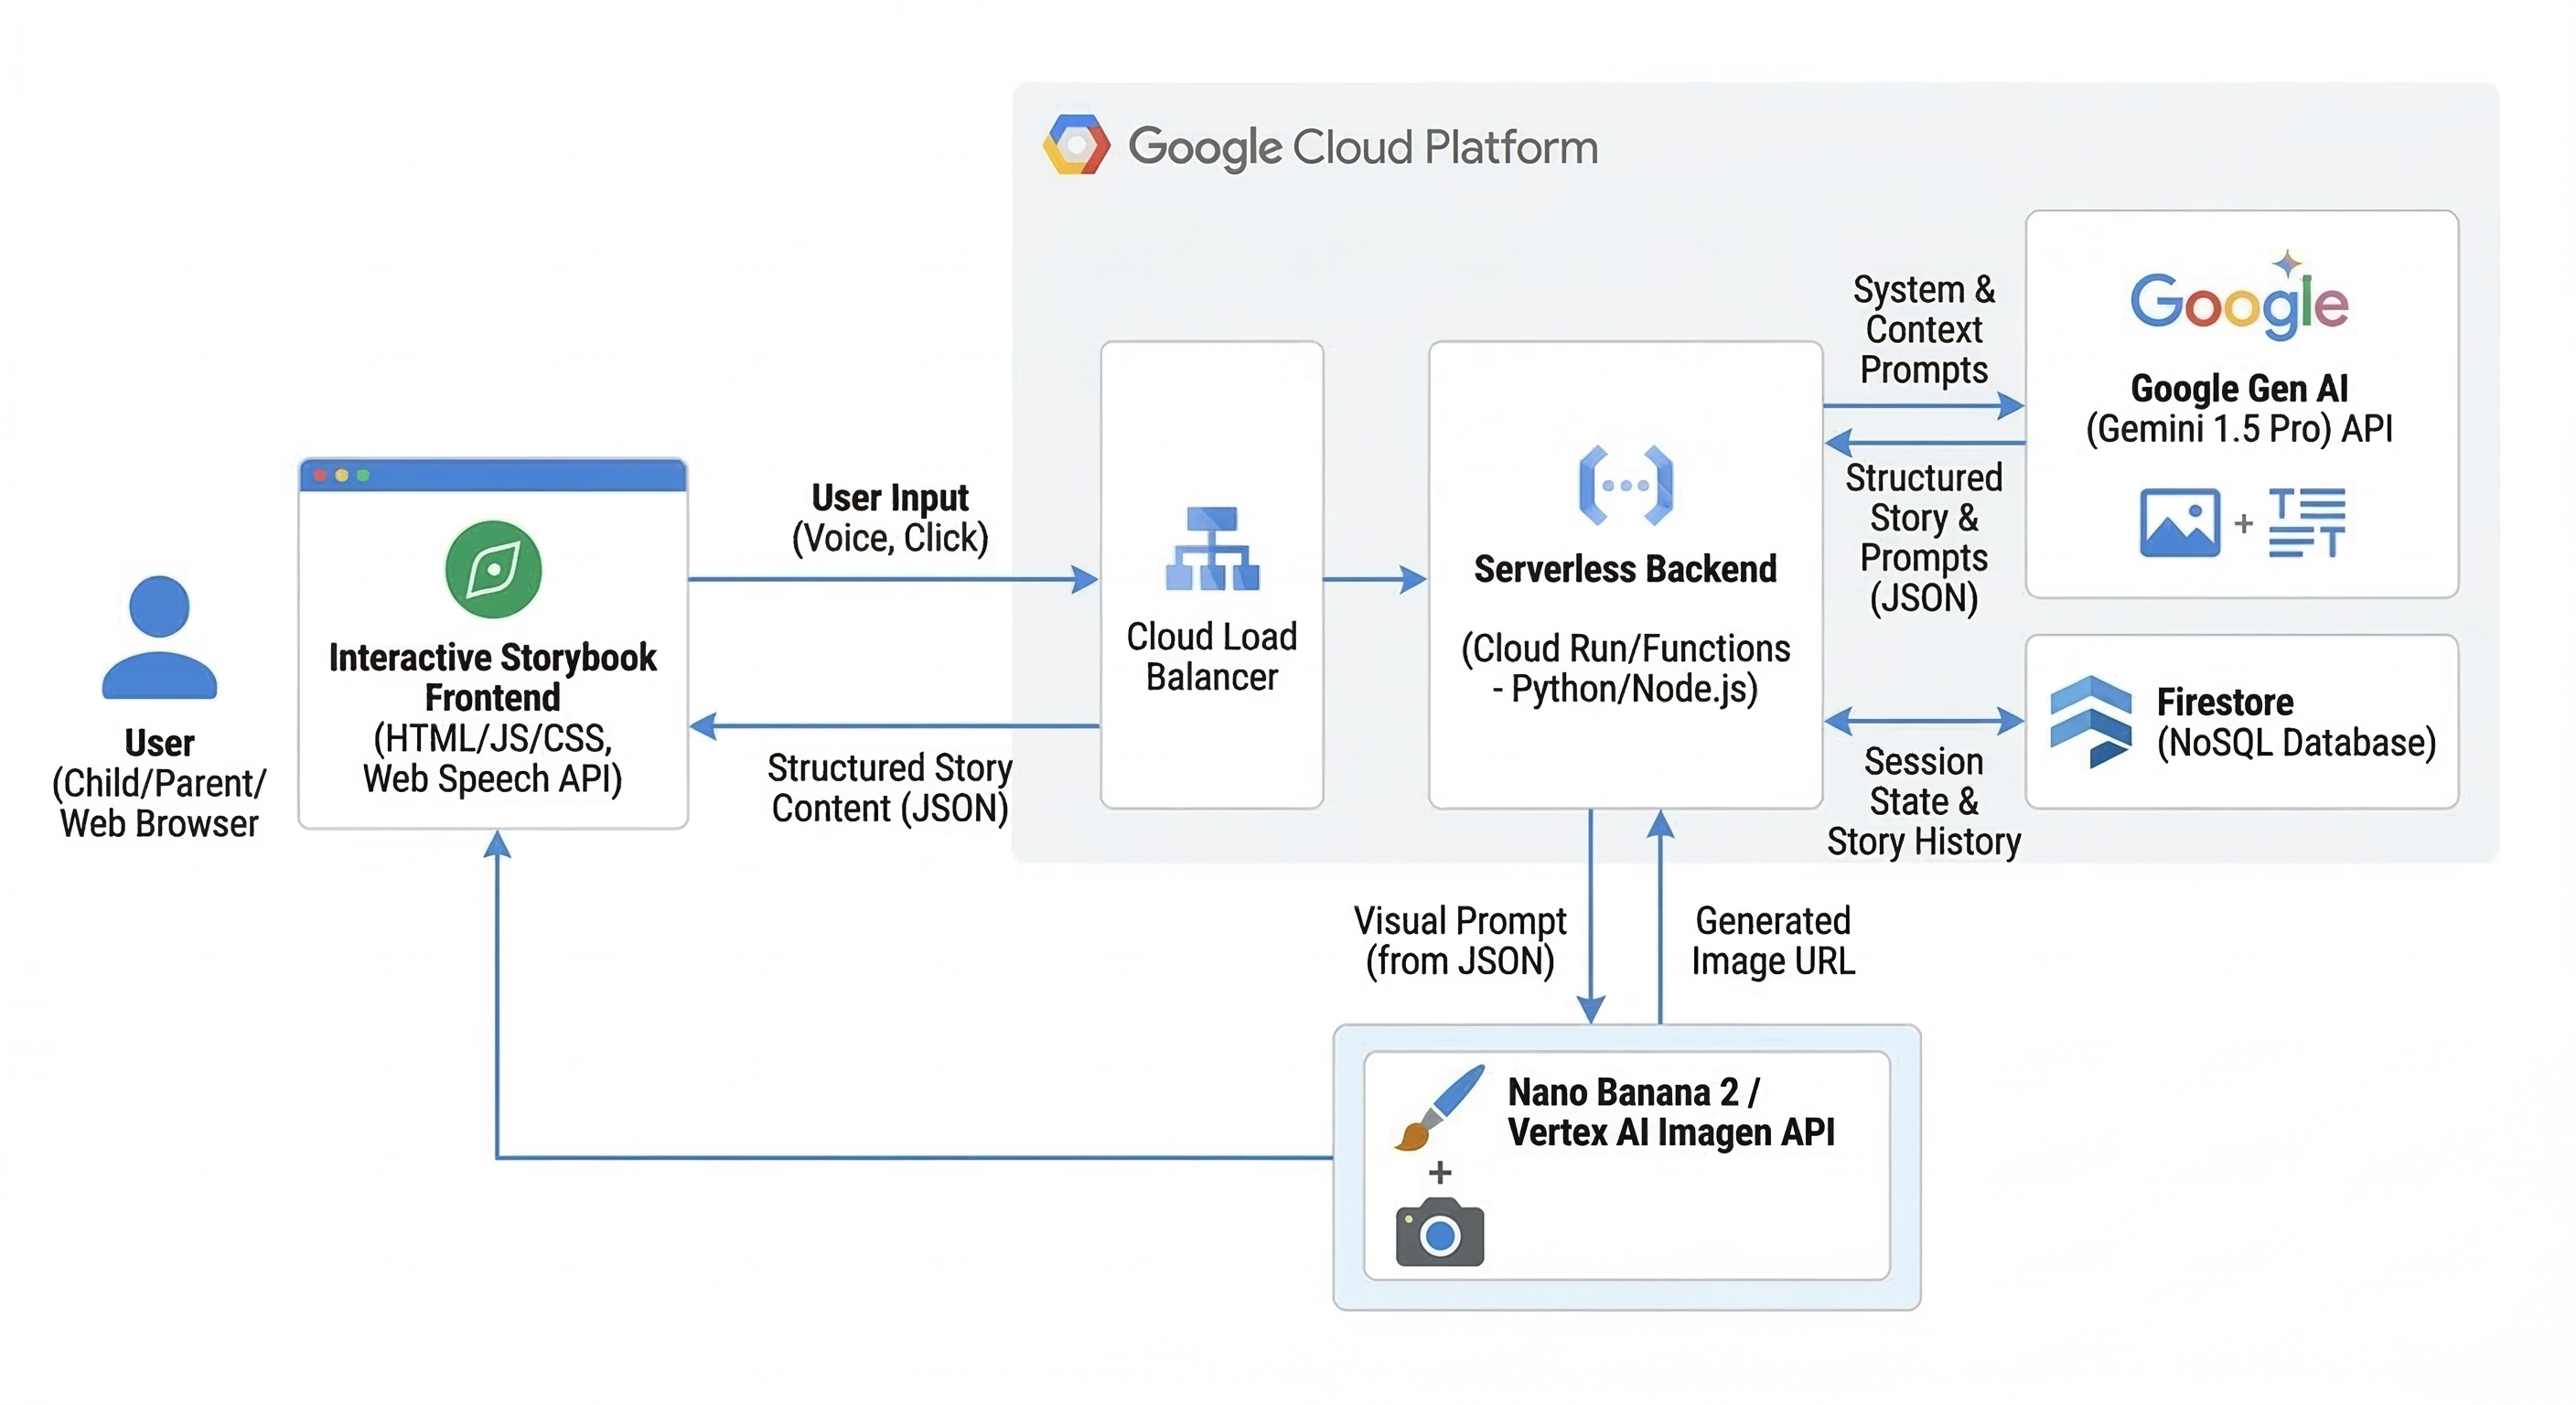
Whimsical Storyteller Architecture Diagram
-
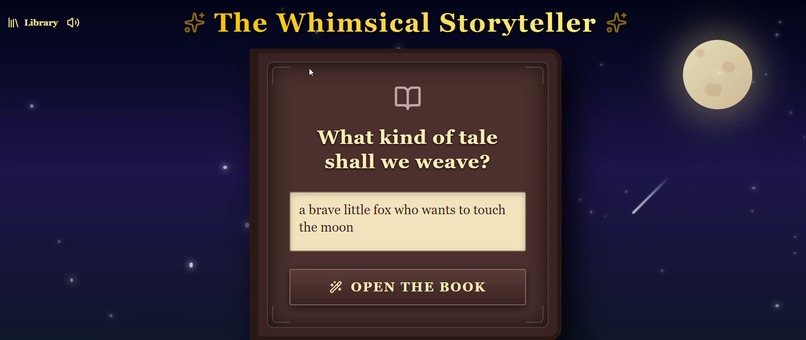
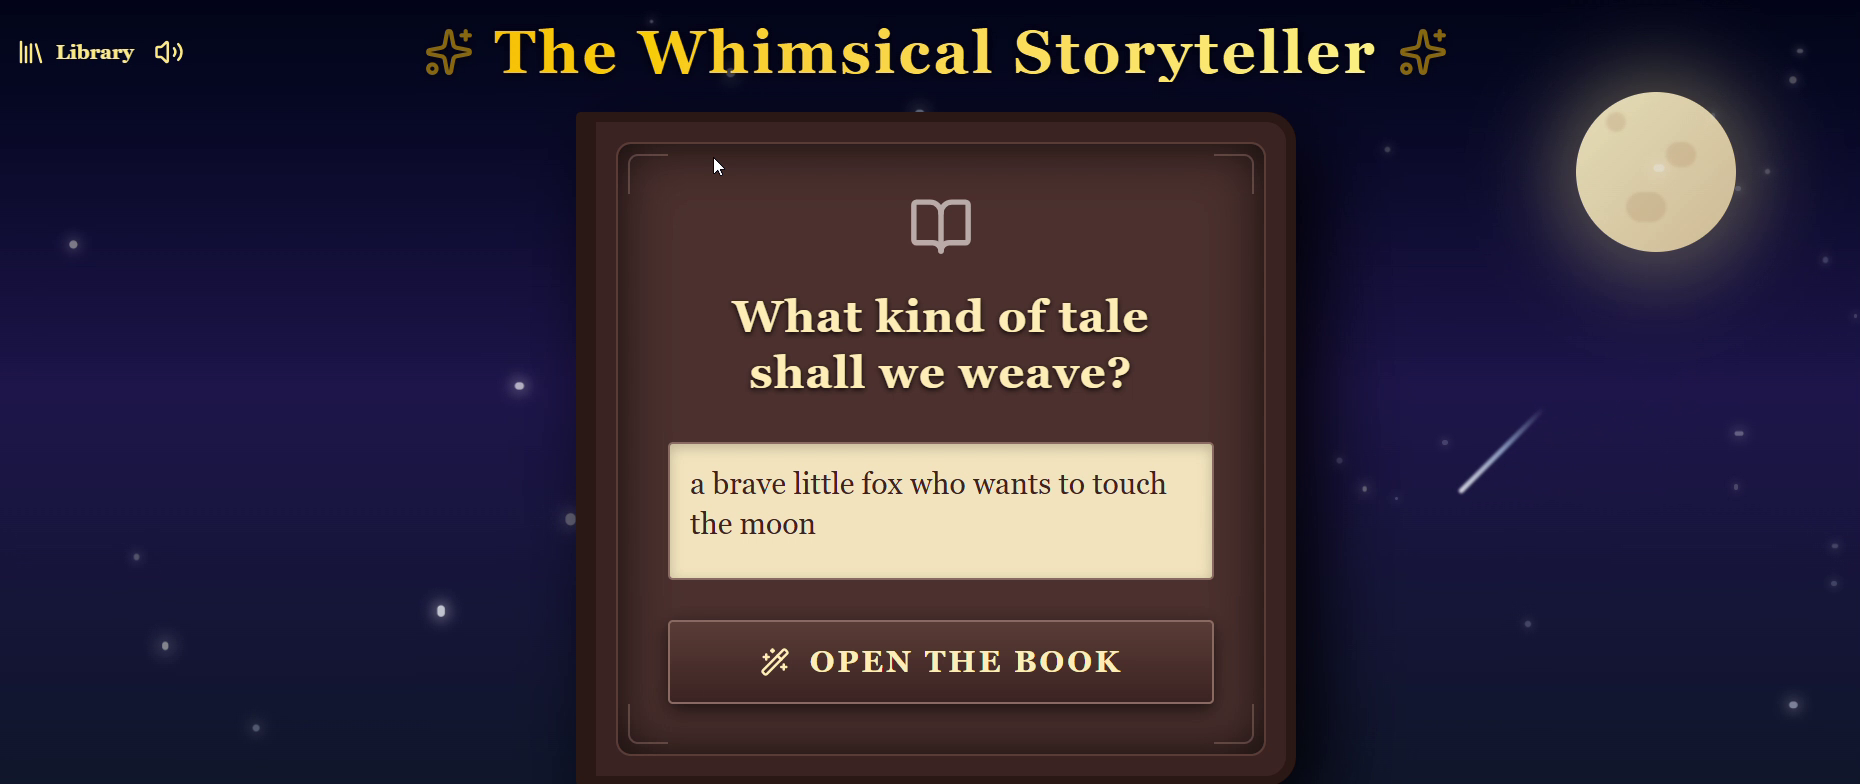
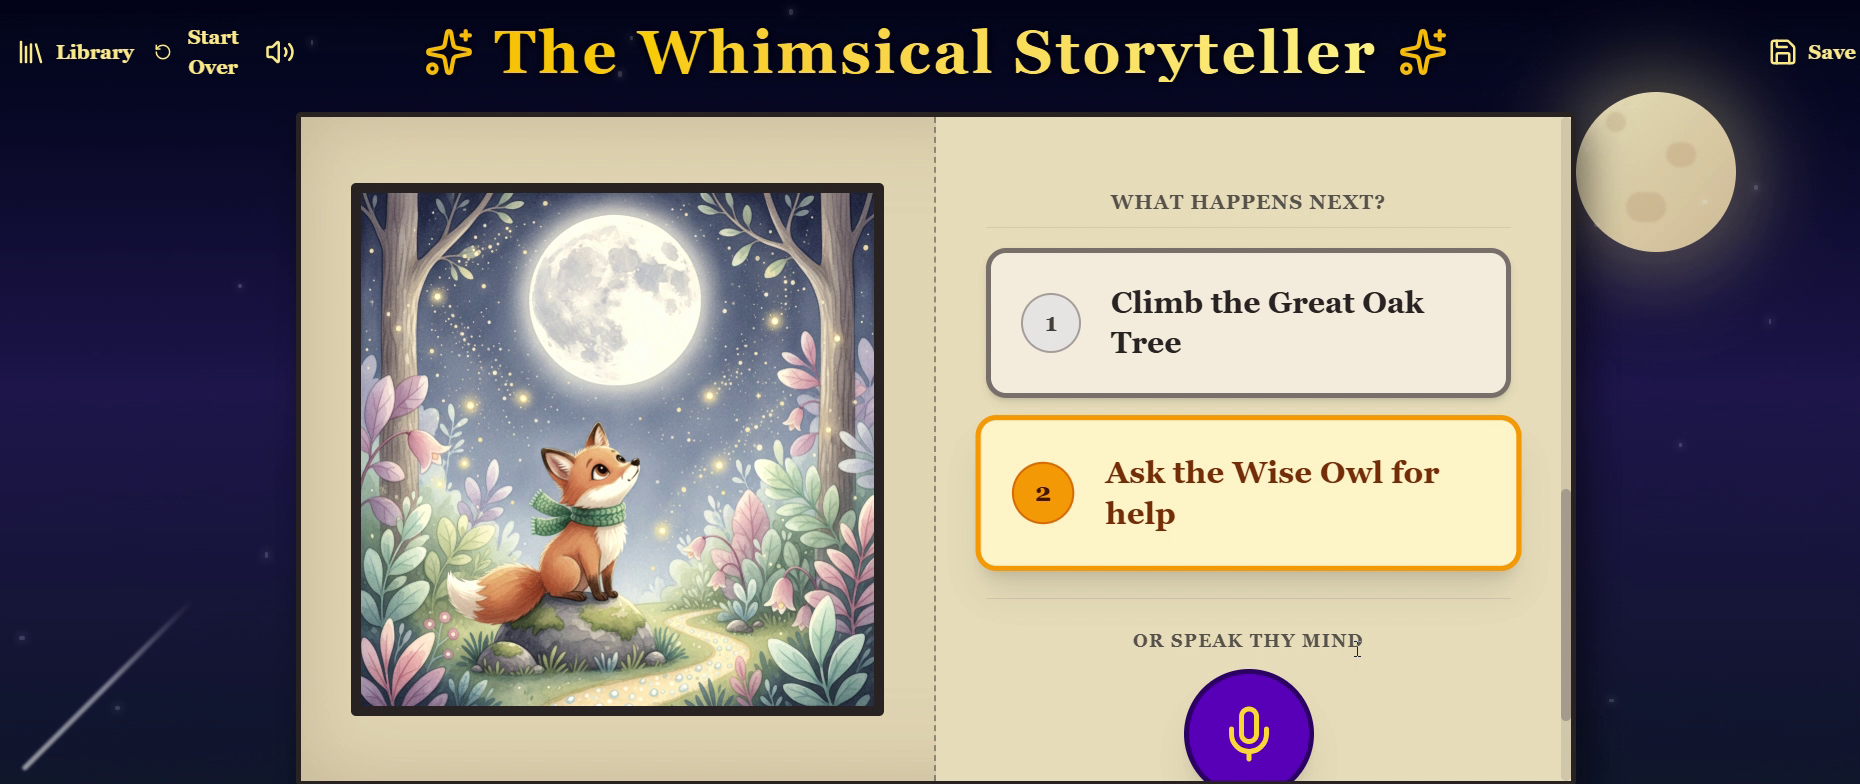
Begin with your own story or let the Storyteller decide
-
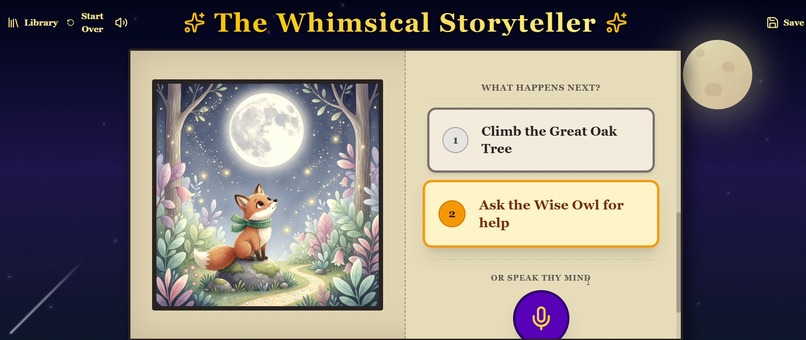
Choose the path to the story or speak out loud
-
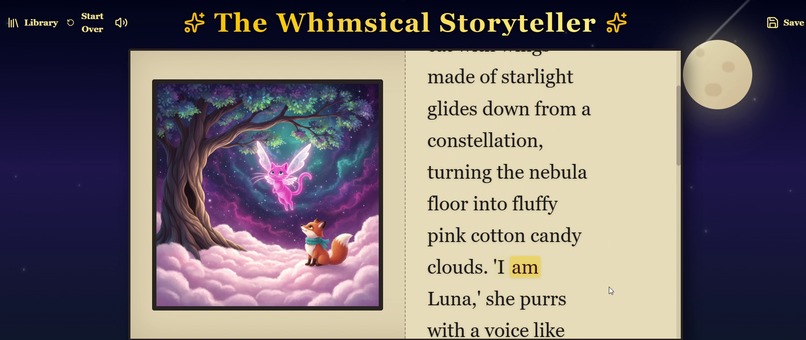
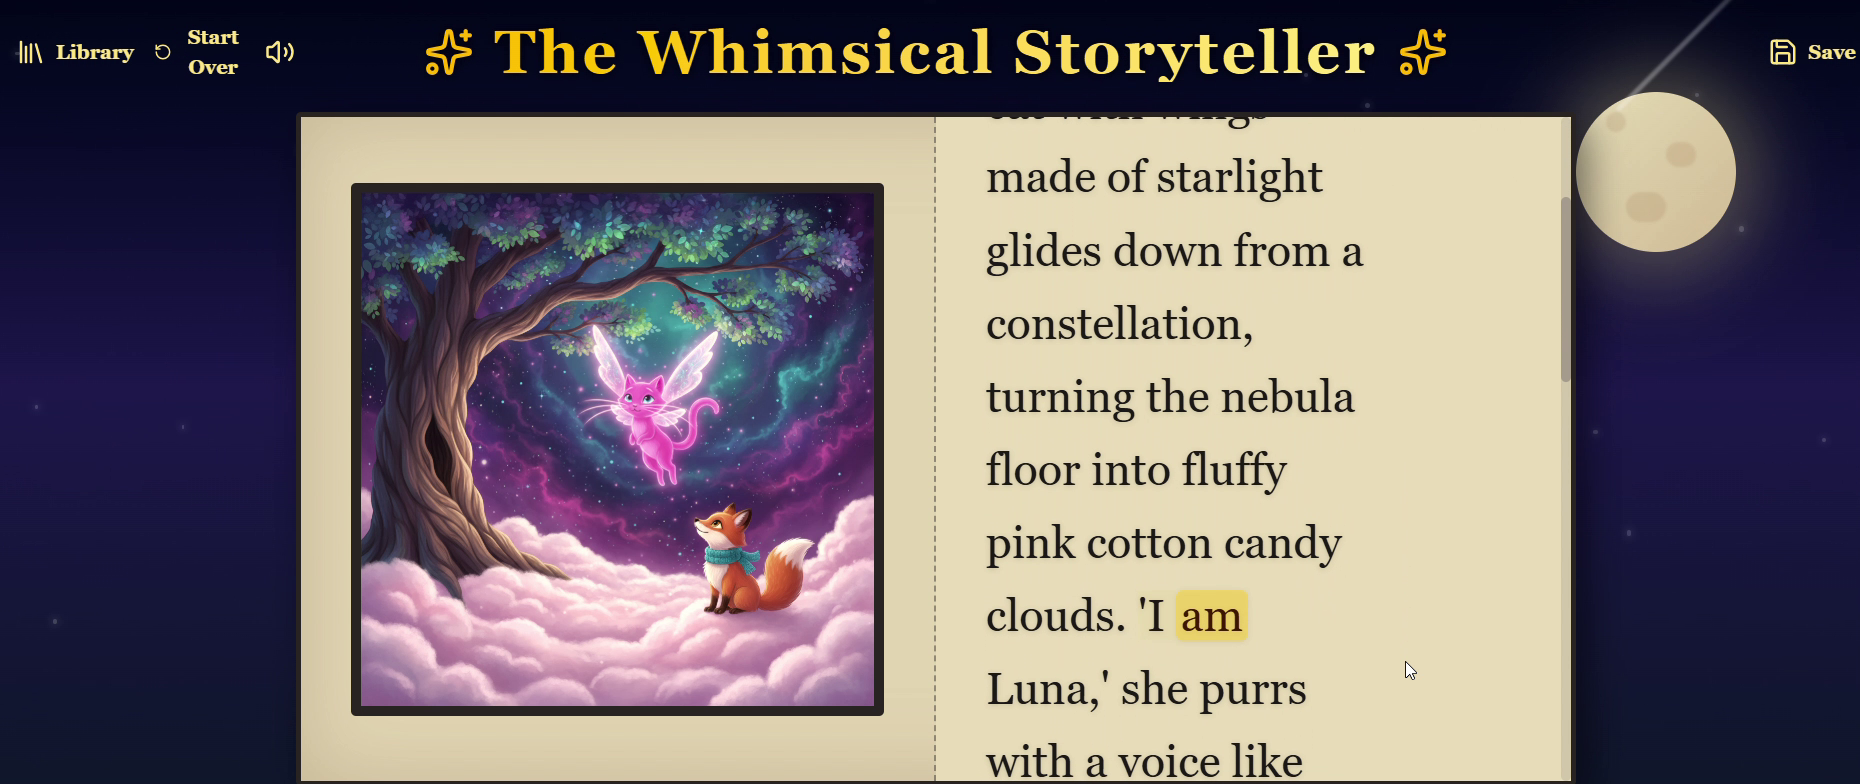
Choose your own Story
-
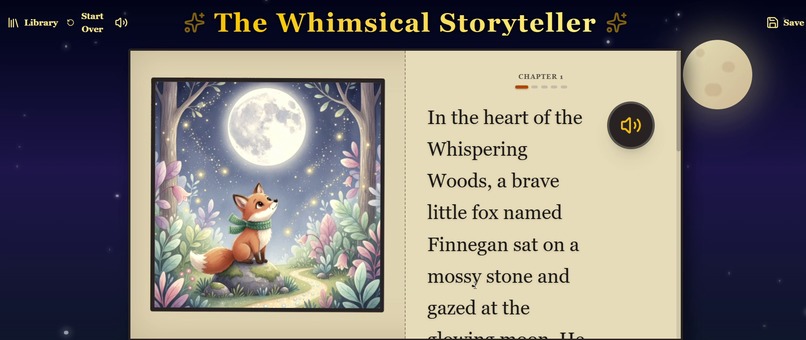
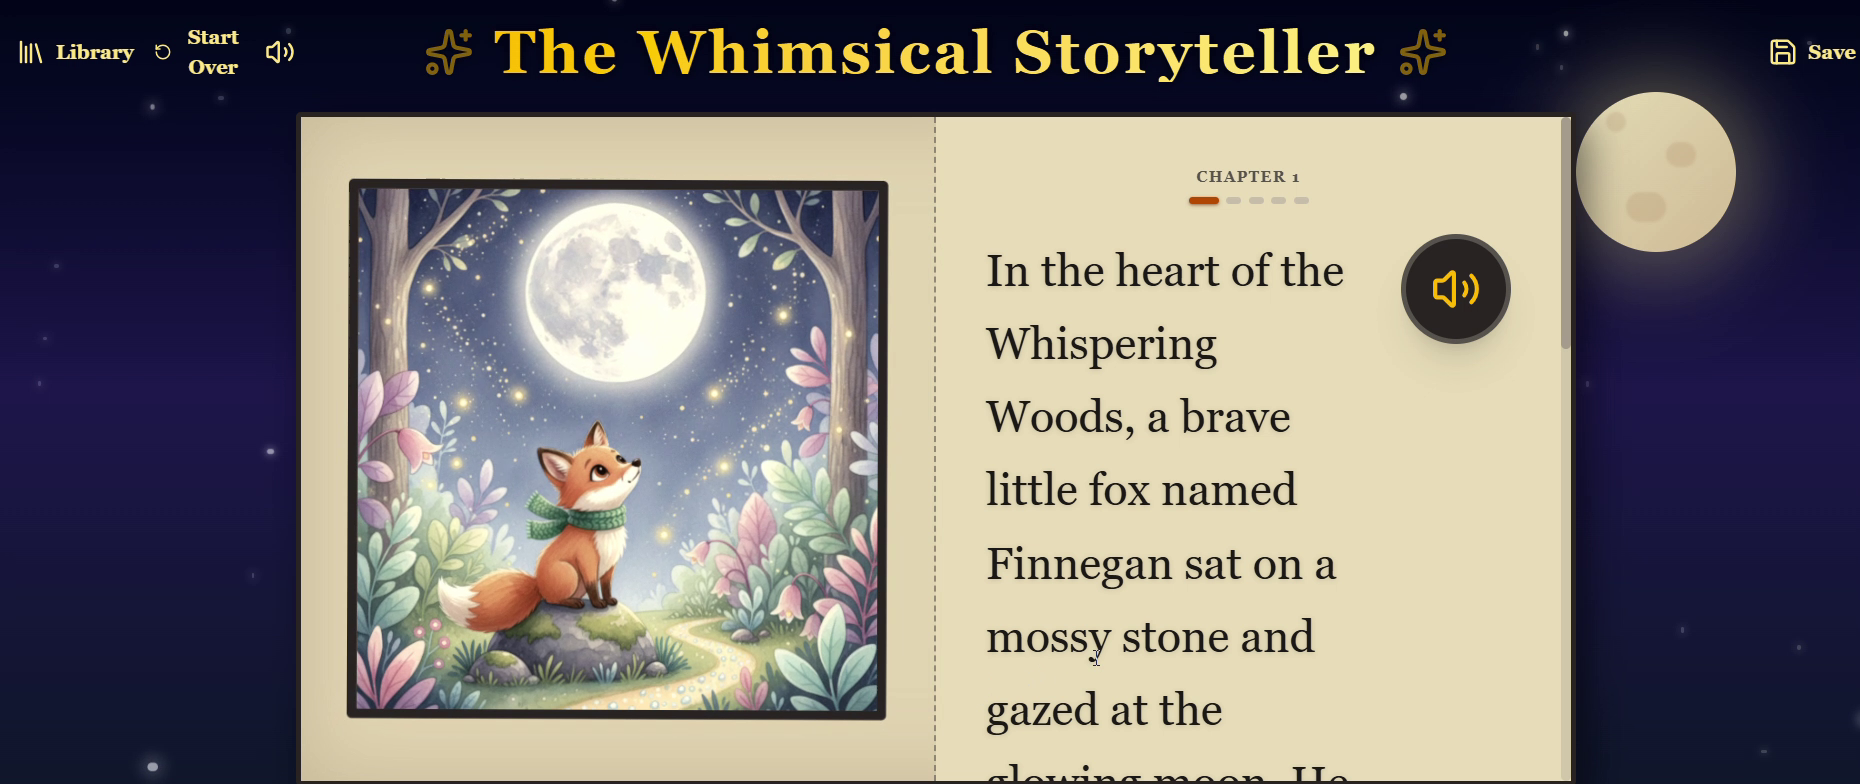
Let the narrator do the magic
-
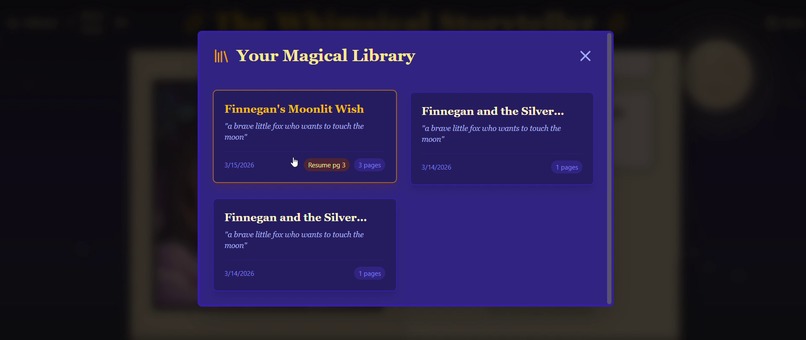
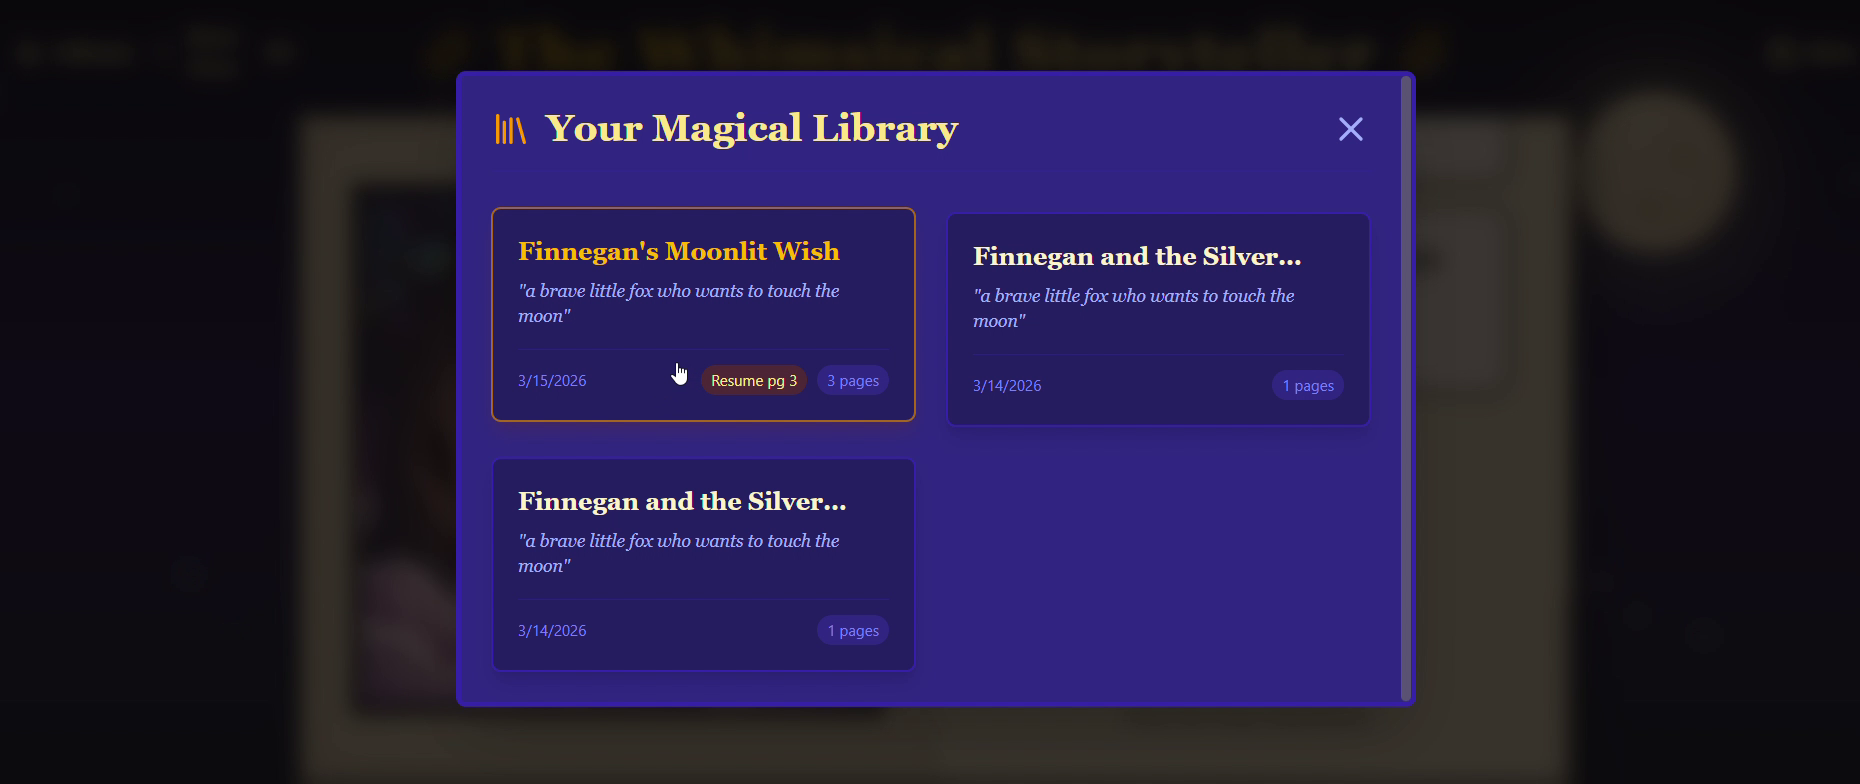
Save your progress in the library. Revisit your stories.
Inspiration
Once upon a time, in a forest of glowing whispers, There was a little fairy, flying about...
But suddenly, a little voice from beneath the blankets interrupts: "No, wait! The fairy shouldn't fly—she needs a purple rocket ship!"
In a traditional book, the story ignores them. But we asked: what if the magic actually listened?
Bedtime stories have historically been a one-way street, leaving children to passively consume a static narrative. The Whimsical Storyteller was inspired by the desire to transform this quiet, sacred space into a living theater of co-authorship. We wanted to build an empathetic, multimodal AI companion that doesn't just read pages, but actively invites a child's imagination inside, proving to them that their voice has the power to shape the universe.
What it does
The Whimsical Storyteller is a deeply interactive, real-time multimedia storybook where the child becomes the co-author. Powered by a coordinated suite of Gemini models, the app seamlessly weaves a child's spoken words into a dynamic narrative as it happens.
- Real-Time Voice Co-Authorship: Instead of just tapping buttons, children hold the microphone and speak their ideas naturally. The app listens to their raw audio and understands whether they picked an on-screen option or invented a completely new, imaginative twist.
- Adaptive StoryWeaving: When a child makes a choice, the narrative instantly branches. The environment alters, new magical elements appear, and the atmospheric UI dynamically changes color to match the mood of the new scene.
- Enchanting Visuals: As the story shifts, the app generates high-quality, whimsical illustrations (and occasionally animated GIF/pixel art) that visually react to the child's input while maintaining strict character consistency.
- The Magical Narrator: The entire experience is read aloud by a warm, dramatic storyteller voice that guides the child through their newly created world.
How we built it
We built a highly responsive, multimodal web application using React 19, Vite, and Tailwind CSS, with Framer Motion driving the immersive, 3D page-flipping animations and atmospheric particle effects.
The core "brain" of the app is orchestrated using the @google/genai SDK, leveraging three distinct Gemini models working in harmony:
- The Story Engine (
gemini-3-flash-preview): We heavily utilized Gemini'sresponseSchemacapabilities to force structured JSON outputs. This allowed the model to simultaneously generate the story text, plot out multiple narrative branches, extract detailed image prompts, and assign hexadecimal mood colors in a single fast inference call. - Voice Intent Processing (
gemini-3-flash-preview): Instead of relying on traditional speech-to-text, we pass the child's raw base64 audio directly to Gemini along with the context of the story options. Gemini evaluates the audio multimodally to determine if the child selected an option or suggested a custom path. - Visual Generation (
gemini-2.5-flash-image): We built a prompt-chaining system where the initial story generation defines a strictcharacterDescription(e.g., "A small orange fox with a white-tipped tail wearing a tiny blue scarf"). This description is dynamically appended to all subsequent image generation prompts to ensure visual continuity across pages. - Dynamic Audio (
gemini-2.5-flash-preview-tts): We utilized the text-to-speech capabilities to stream the dramatic 'Fenrir' voice. We built a custom Web Audio API integration to decode the raw PCM/WAV buffers and play them alongside fading background music.
Challenges we ran into
- Maintaining Visual Continuity: Image generators notoriously struggle to keep characters looking the same across different prompts. We solved this by forcing the text model to generate a strict, detailed visual anchor (
characterDescription) on page one, which our frontend dynamically injects into all futuregemini-2.5-flash-imageAPI calls. - Audio Decoding & Playback: Processing the raw audio buffer returned by the Gemini TTS model required building a robust fallback mechanism in our
audio.tsutility. We had to manually convert raw 16-bit PCM arrays at $24,000\text{Hz}$ into Float32 arrays so the browser'sAudioContextcould play the narration smoothly. - Parsing Unstructured Child Speech: Children don't always speak clearly or pick the exact options provided. Using Gemini multimodally to interpret the audio blob allowed us to capture the intent of the child's imagination rather than just transcribing their words, which drastically improved the reliability of the branching logic.
Accomplishments that we're proud of
- A True Multimodal Agent: We successfully orchestrated Text, Vision, and Audio generation into a single, seamless user experience that feels like magic rather than a disjointed series of API calls.
- The Atmospheric UI: The 3D perspective animations, dynamic mood colors, fading ambient music, and dialogue-highlighting text make the application feel like a premium, immersive video game.
- Zero-Friction Interaction: Empowering a child to simply press a button, speak their mind, and watch the story physically change on the screen without ever needing to touch a keyboard.
What we learned
- The Power of Structured Outputs: Forcing Gemini to output strictly typed JSON (using
Type.OBJECTschemas) transformed the LLM from a simple text generator into a robust state machine capable of driving our entire React frontend. - Audio handling in the Browser: We deepened our understanding of the Web Audio API,
MediaRecorderstream handling, and MIME type conversions to facilitate seamless two-way voice communication with the Gemini API.
What's next for The Whimsical Storyteller
- Full Duplex Interruptibility: We plan to migrate the application to the Gemini Multimodal Live API (WebRTC). This will allow the child to interrupt the narrator mid-sentence (e.g., "Wait! The dragon should be friendly!") and have the agent instantly adapt the audio and story.
- Pedagogical Storytelling (Hidden Learning): We want to introduce a "Parent Dashboard" where parents can set learning objectives (e.g., 2nd-grade math, emotional regulation). The agent will organically weave these challenges into the narrative (e.g., "To cross the bridge, the troll says you must solve $5 + 7$!").
- Persistent Worlds (RAG): Integrating Google Cloud Firestore and Vertex AI Vector Search so the agent remembers characters and choices from past bedtime sessions, creating a continuous, personalized fairy tale universe that grows with the child.
Built With
- gemini
- gen-ai
- nanobanana
- react
- tailwind
- typescript


Log in or sign up for Devpost to join the conversation.