-
-
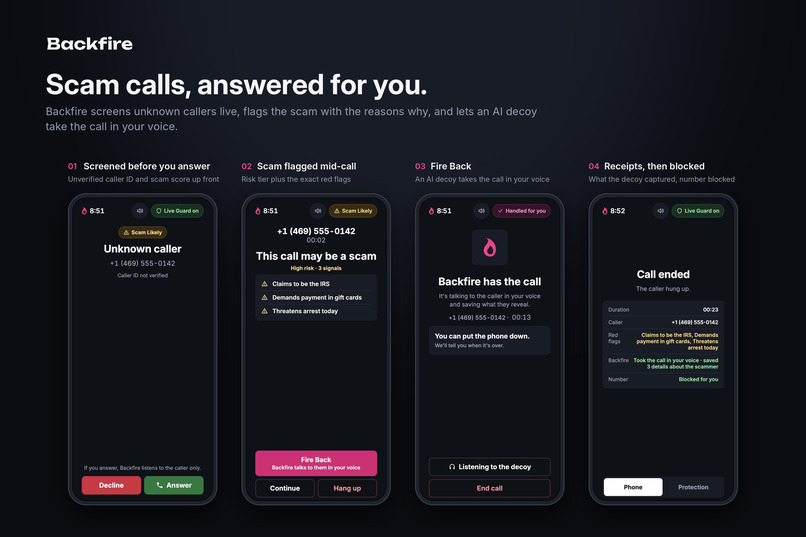
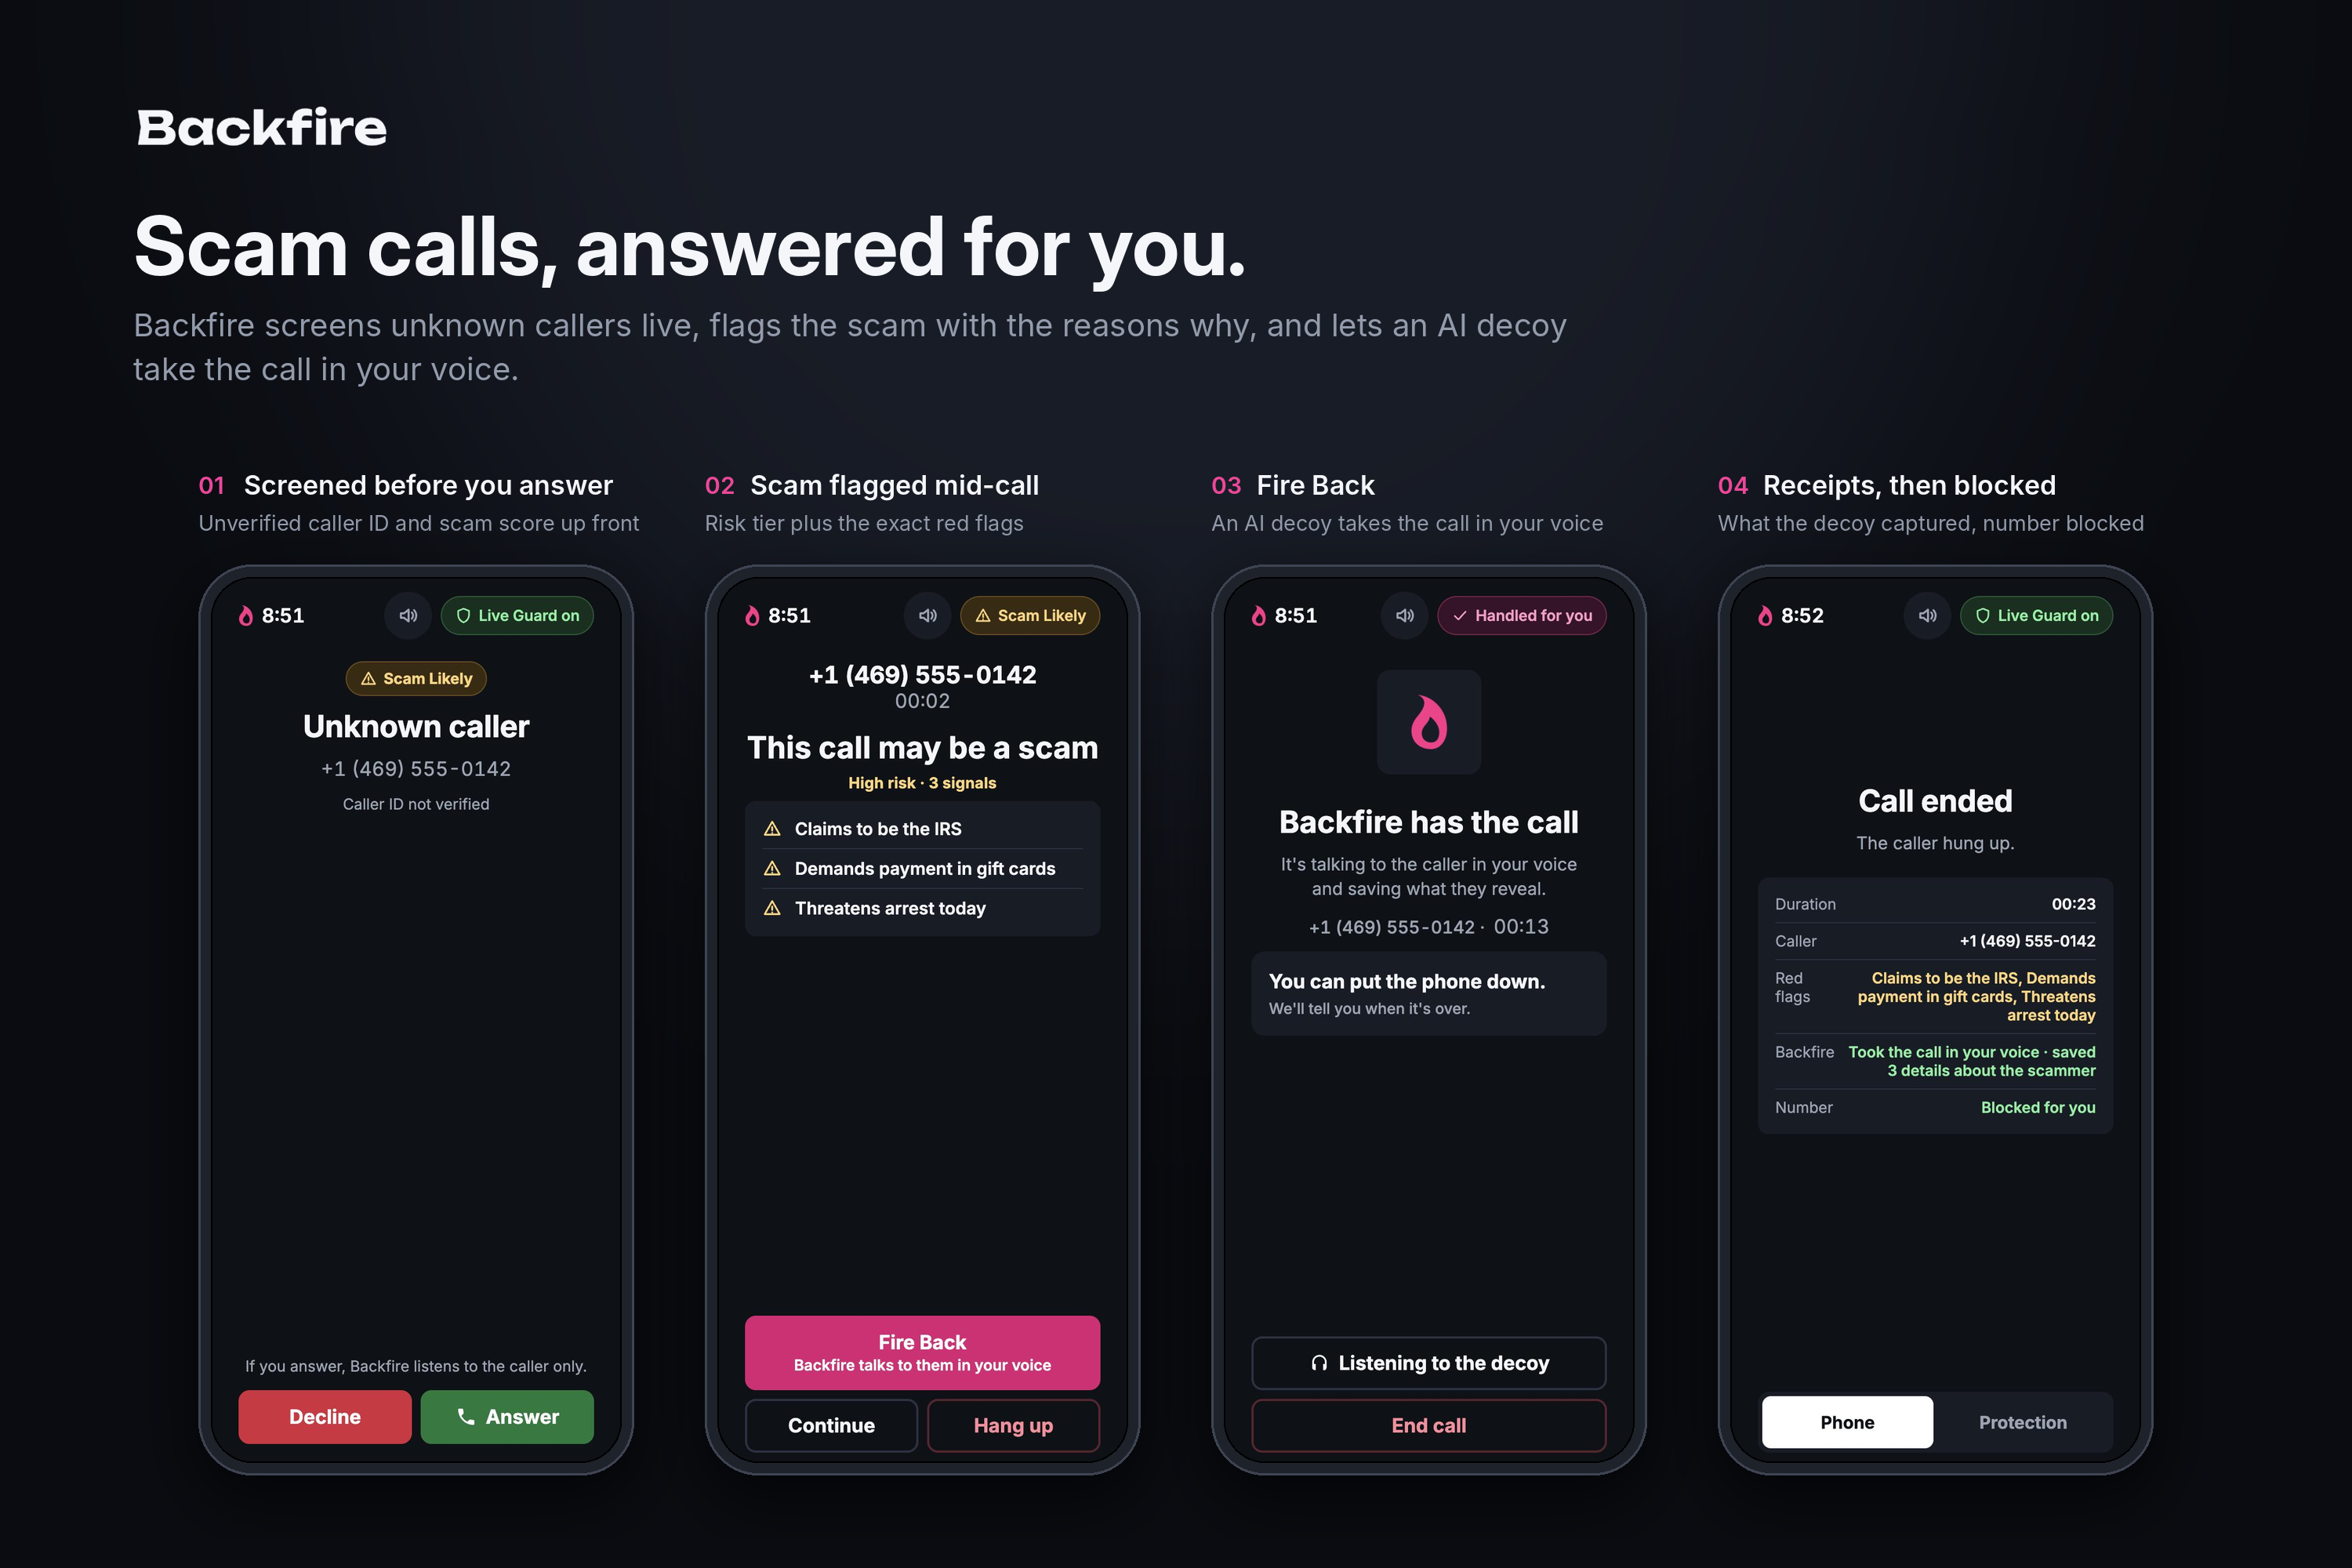
Phone App UI
-
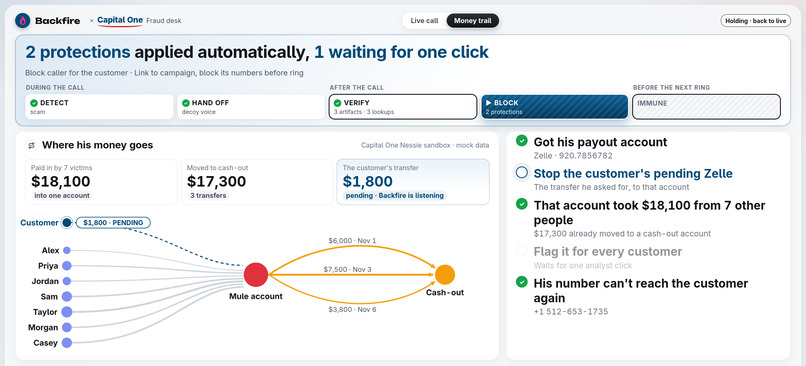
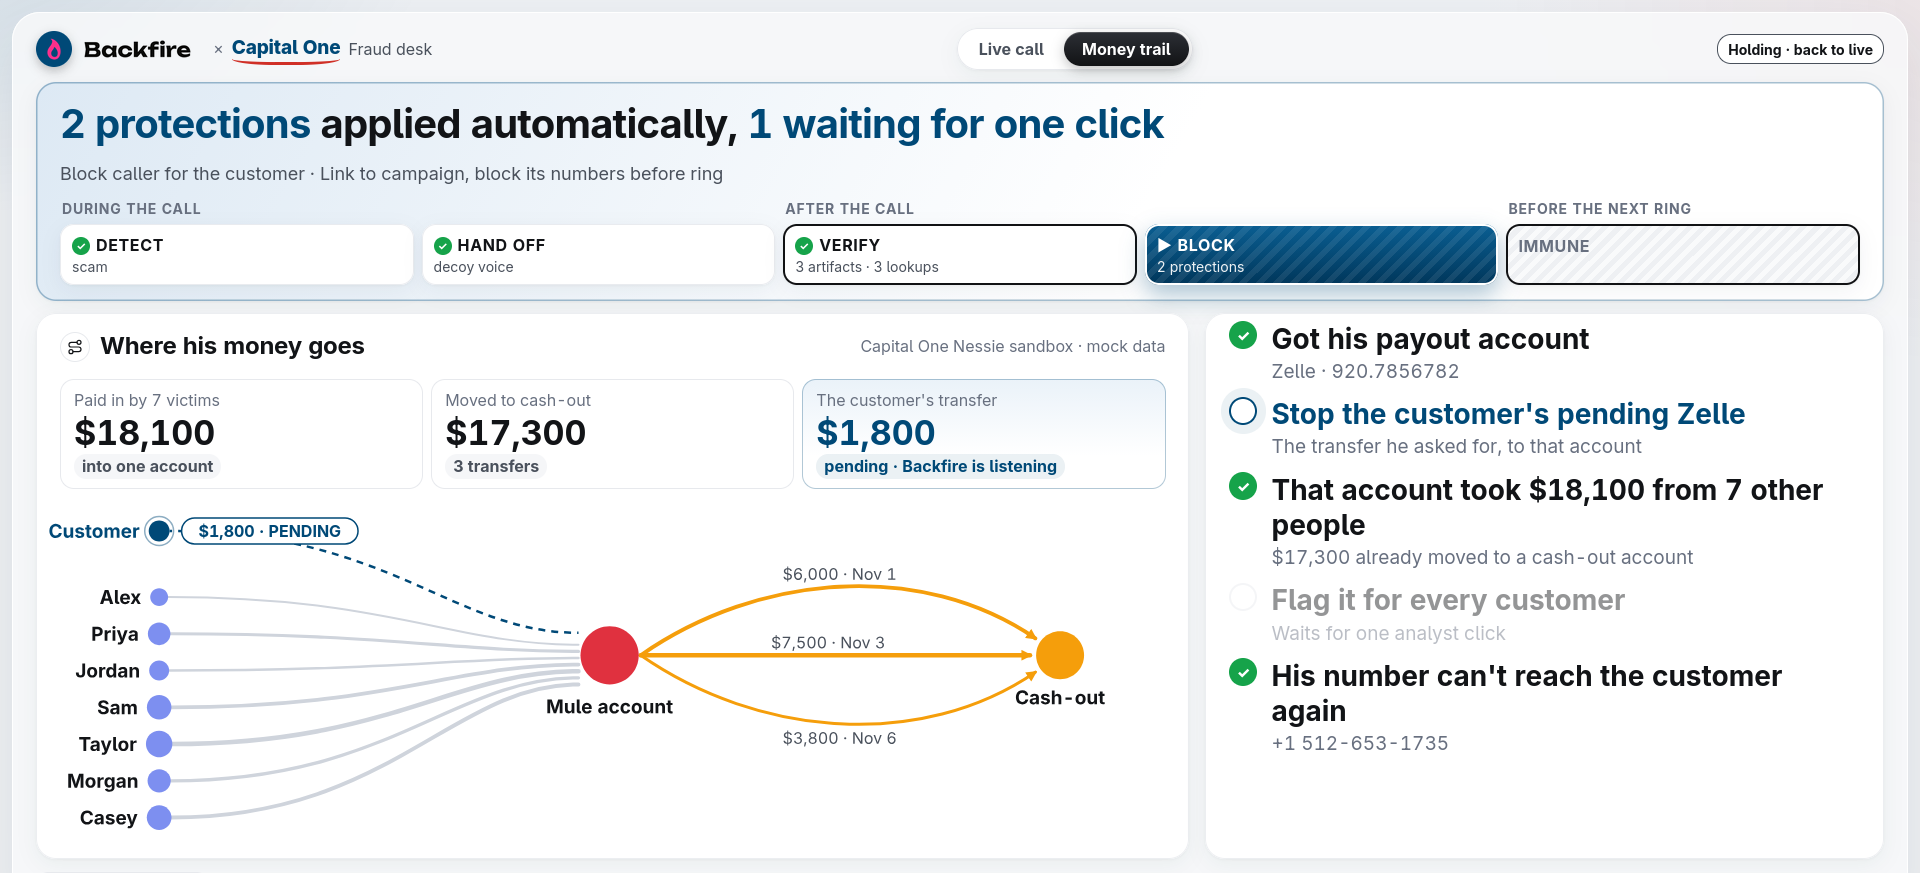
The Command Center's money trail dashboard
-
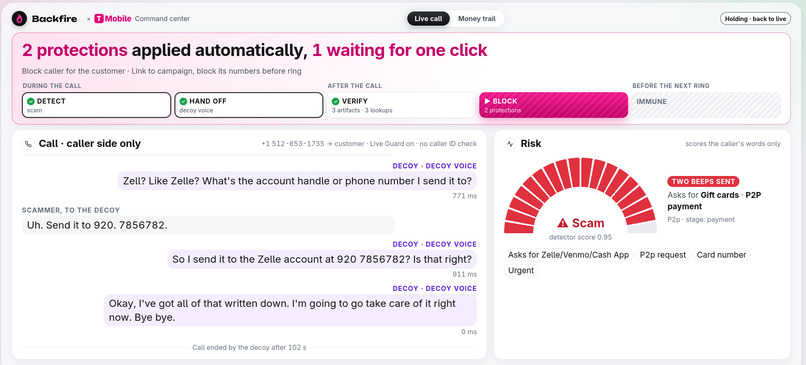
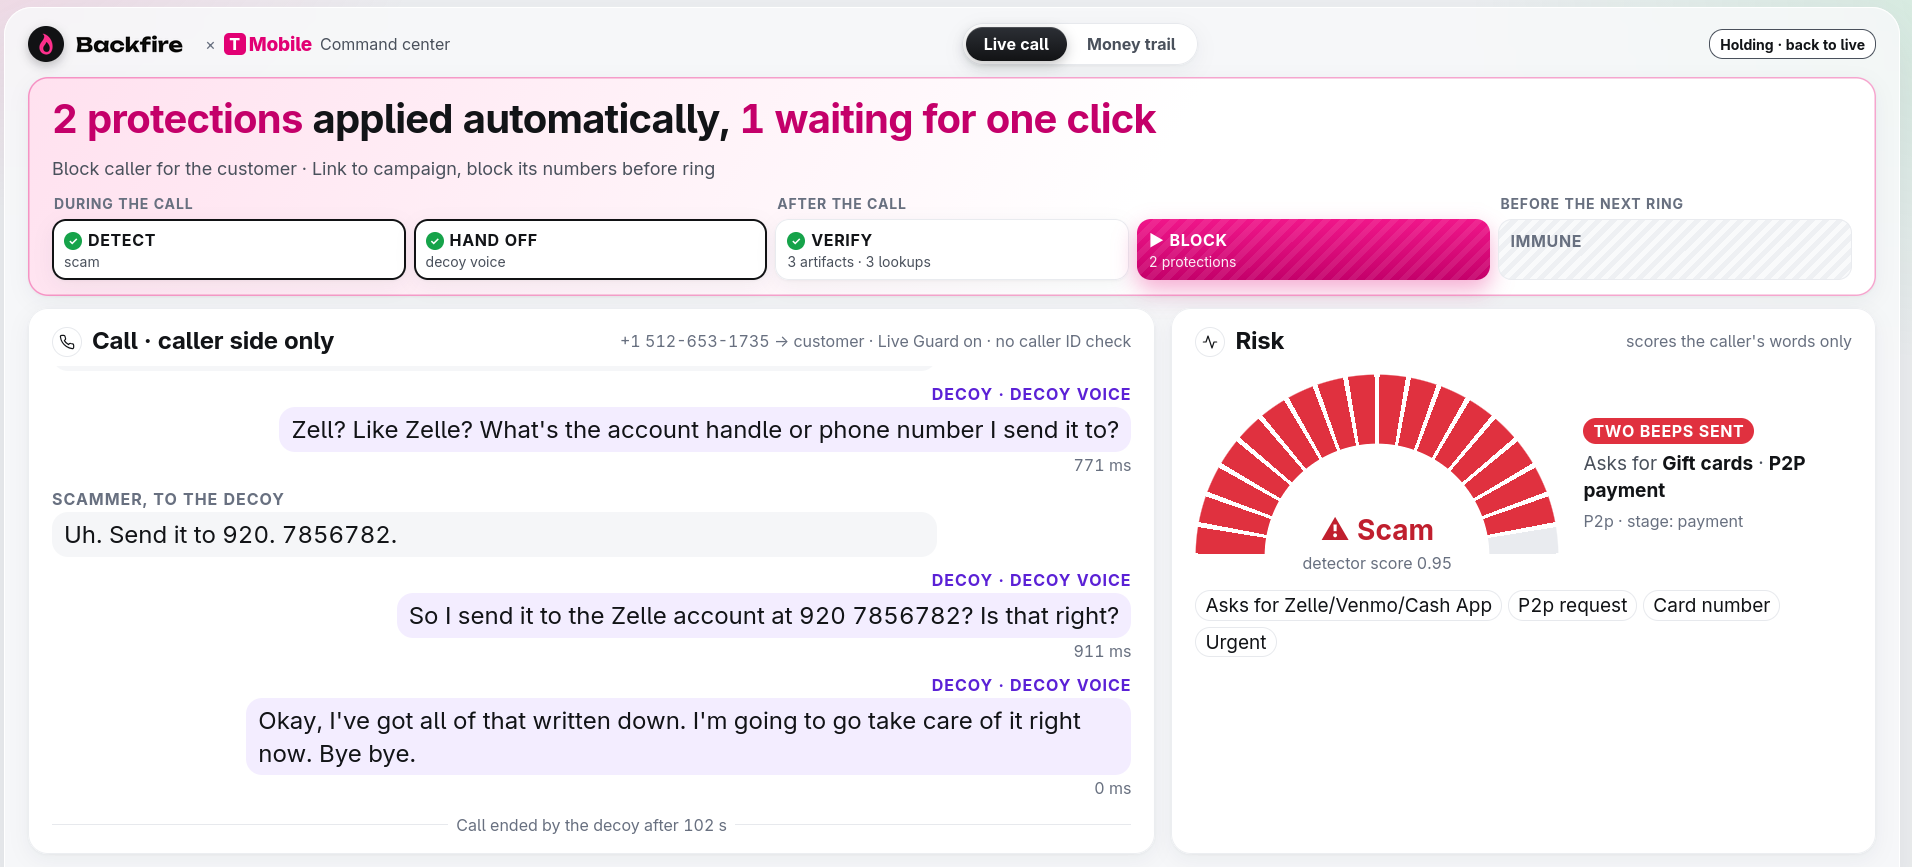
The Command Center's live call dashboard
-
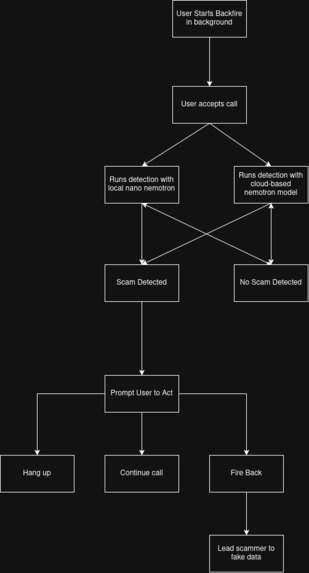
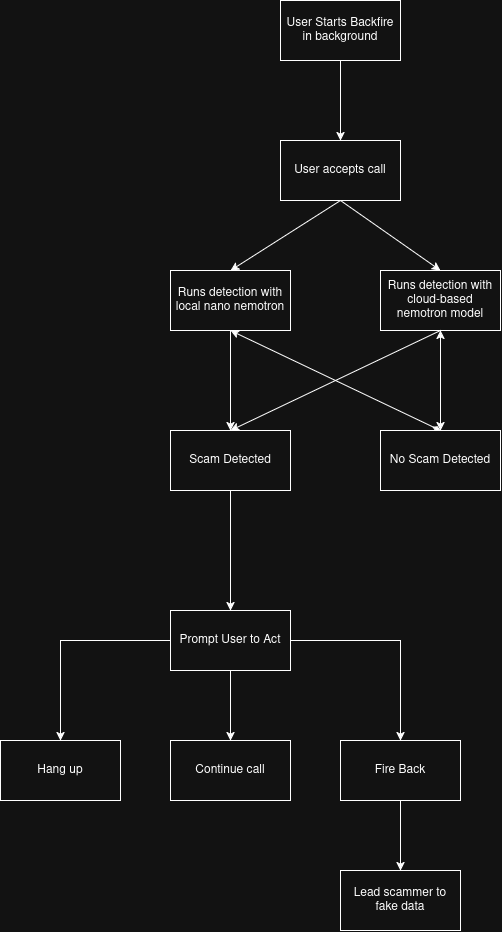
Application flow
Inspiration
Too many times has the IRS wanted to be paid in gift cards. Too many times has our car warranty expired. Too many times has a job recruiter offered a little too much for a little too little. It's time we fire back
What it does
Backfire serves scammers some of their own medicine while protecting the people they target at the same time. When a scammer attempts to take whatever information they're looking for from an unaware scammee, the Backfire agent detects the danger in their communication and offers to take over. Then, Backfire fires back at the scammer with an AI voice agent that attempts to gather as much information on the scammer as possible and report them (or at least inconvenience them).
How we built it
We began with call forwarding and VoIP apps to circumvent the restrictions placed around phone apps. From there, we designed a background service that uses Nemotron nano 3 at 4B parameters and 4-bit quantization locally for the sake of privacy, or with Nemotron 3.5 Lightning for speed and power when detecting evidence of fraudulent calls. From there, we designed a Nemotron Magpie pipeline that continues to converse with the scammers while leading them to a Nessie dashboard where Backfire attempts to gather information on the scammer.
Challenges we ran into
Even though our locally-deployed Nemotron model was so small, it still proved heavy for an old phone. Configuring it to run quickly and efficiently on Samsung hardware was a complicated task, but it was ultimately able to run detection in real time. Firing back is still not viable locally for common phones, however. Local inference proves much too slow for real-time communication.
Accomplishments that we're proud of
Our local detection agent was able to catch 100% of all tested scam calls (33/33) with only a 7% false positive rate (2/27). Even when targeted with scams designed to trick AI, the AI was able to determine with 100% accuracy what was a scam (13/13).
What we learned
Adding features to an already tightly-designed system can be very difficult. Dealing with telecommunications throughout our entire project taught us about how tightly-knit applications must be when everyone uses them. Deploying a Nemotron language model on a phone was also a new application of AI for our team. Thinking about token generation rates below 20/second was a novel experience.
What's next for Backfire
We believe that the future of local edge AI inference will involve technologies at the level of the cloud-based Nemotron models we demonstrated with all the privacy and control of the local Nemotron model we deployed. Once phone hardware progresses to the point that rapid inference and large memory sizes are the norm, we believe that Backfire will become a household application.
Built With
- android
- java
- javascript
- kotlin
- nemotron
- python


