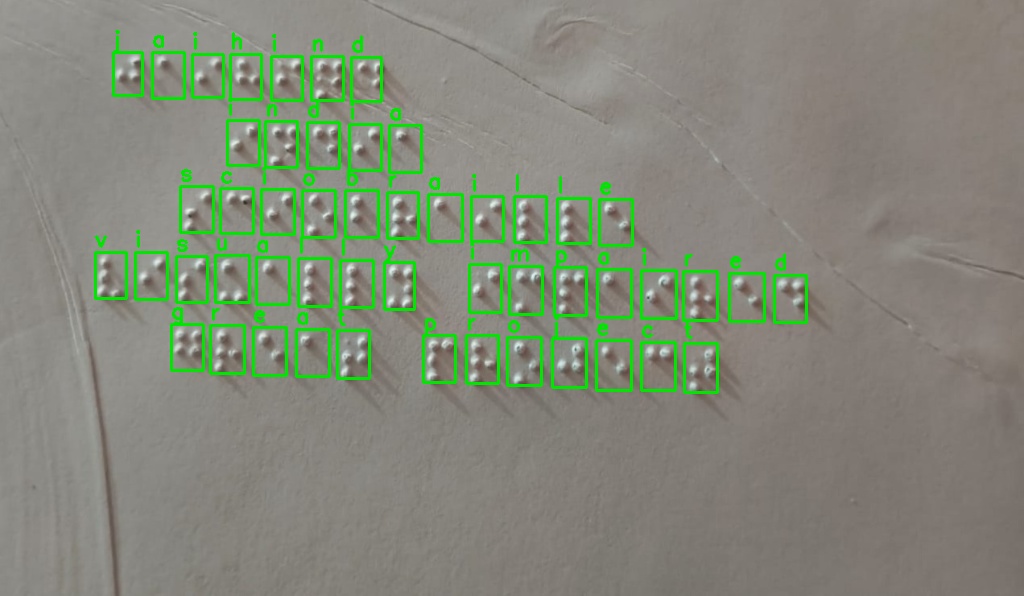
Reads real embossed Braille from camera images and converts it to English text and speech. Uses fine-tuned YOLO object detection to identify individual Braille cells, then reconstructs readable text using a deterministic reading-order algorithm.
93.15% mAP@50 accuracy across 26 Braille letter classes (a–z), trained on 1,614 images / 90,469 bounding boxes merged from multiple datasets.
✅ Quick Verify (for Judges) git clone https://github.com/prabh505/the-decoders-braillevision.git && cd the-decoders-braillevision pip install -r requirements.txt python inference.py --source sample_inputs/ --weights model/best.pt This detects Braille letters in all sample images, prints decoded text, and saves annotated images to sample_outputs/.
🎯 What It Handles Input Type Supported How Real embossed Braille from paper ✅ Trained on 212 printed book photos Handwritten Braille (slate & stylus) ✅ Trained on 28 handwritten student samples Braille writer output ✅ Machine-embossed detected same as printed Camera-captured images ✅ inference.py — any photo Live camera scanning ✅ app.py — real-time webcam with TTS 🏗️ How It Works Camera Image → YOLO Detection → Bounding Boxes + Letters → Reading Order → Text → Speech Capture — photograph Braille under oblique side-lighting (dots cast shadows) Detect — YOLOv8s identifies each Braille cell and classifies it as a letter (a–z) Decode — reading-order algorithm sorts detections into lines (left→right, top→bottom), inserts spaces at gaps Speak — text-to-speech output (macOS say, gTTS for web) 📊 Model Performance We trained and compared 3 models with different strategies:
Model Architecture mAP@50 Precision Recall Size Strategy A YOLOv8 + DotNeuralNet transfer 92.88% 97.14% 91.50% 50MB Braille-pretrained backbone B (Primary) YOLOv8s 93.15% 95.72% 90.85% 21MB Best overall accuracy C YOLOv11n 89.29% 89.70% 86.73% 5.2MB Smallest — for mobile/edge Model B is deployed as best.pt — best mAP@50 at a practical 21MB size.
See docs/model_journey.md for the full development story.
📦 Dataset Engineering We merged multiple sources to create a diverse training set:
Source Images Boxes Type yapayzeka/braille-detection (Roboflow) 1,324 ~21K Mixed braille Angelina Braille Images (GitHub) 290 ~69K Real books + handwritten Total 1,614 90,469 Printed + handwritten + camera Key challenge: Angelina uses bitmask-encoded labels (integer → dot pattern → letter). We built a custom converter (converters/angelina_to_yolo.py) to decode these into standard YOLO format.
🗂️ Repository Structure the-decoders-braillevision/ ├── README.md ← this file ├── requirements.txt ← pip dependencies ├── inference.py ← offline image inference ├── app.py ← live webcam demo (OpenCV + TTS) ├── app_web.py ← web app (Gradio, works on phone) ├── evaluate.py ← validation metrics ├── merge_datasets.py ← multi-source dataset merger ├── converters/ │ └── angelina_to_yolo.py ← Angelina bitmask → YOLO converter ├── model/ │ ├── best.pt ← primary weights (Model B, 21MB) │ ├── best_A.pt ← Model A weights (50MB) │ ├── best_C.pt ← Model C weights (5.2MB) │ └── model_info.md ← architecture & metrics detail ├── training/ │ ├── train_kaggle.py ← Kaggle notebook (Model A & B) │ └── train_kaggle_v11.py ← Kaggle notebook (Model C) ├── sample_inputs/ ← test Braille images ├── sample_outputs/ ← inference results ├── docs/ │ ├── model_journey.md ← full development story │ ├── results_A.png ← Model A training curves │ ├── results_B.png ← Model B training curves │ └── results_C.png ← Model C training curves ├── dataset/ │ └── dataset_info.md ← dataset details ├── flutter_app/ ← Android app (stretch goal) ├── ai_tools_disclosure.md └── LICENSE ← AGPL-3.0 🚀 Usage Offline inference (any image/folder) python inference.py --source sample_inputs/braille_book_page.jpg --weights model/best.pt python inference.py --source sample_inputs/ --weights model/best.pt # whole folder Live webcam demo python app.py --weights model/best.pt
Keys: q=quit s=speak space=pause
Web app (works on phone browser too) python app_web.py
Opens at http://localhost:7860 — point phone camera at Braille
🔧 Tech Stack Detection: Ultralytics YOLOv8/v11, OpenCV Training: Kaggle T4 GPU, AdamW optimizer, mosaic augmentation Dataset: Roboflow API, custom Angelina bitmask converter, MD5 deduplication Application: Python, Gradio (web), OpenCV (desktop), gTTS/macOS TTS (speech) Transfer Learning: DotNeuralNet pretrained braille backbone (64-class → 26-class) 🙏 Acknowledgments Resource Author Usage Angelina Braille Dataset Ilya Ovodov 290 real-world Braille photos DotNeuralNet snoop2head Pretrained YOLOv8 braille backbone yapayzeka/braille-detection yapayzeka 1,324 labeled detection images Ultralytics YOLOv8 Ultralytics Detection framework 📜 License AGPL-3.0 — See LICENSE.

Log in or sign up for Devpost to join the conversation.