-
-
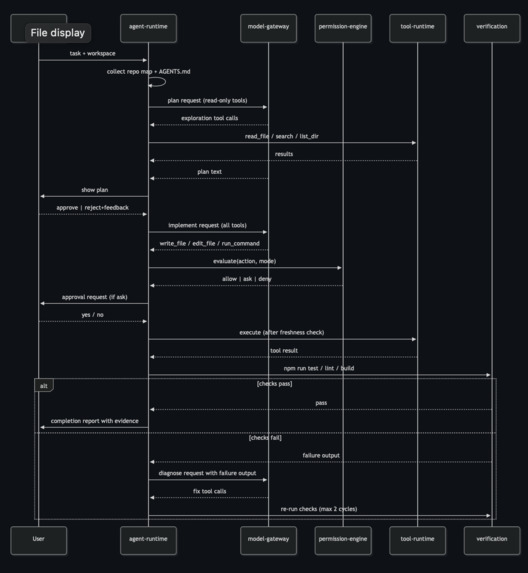
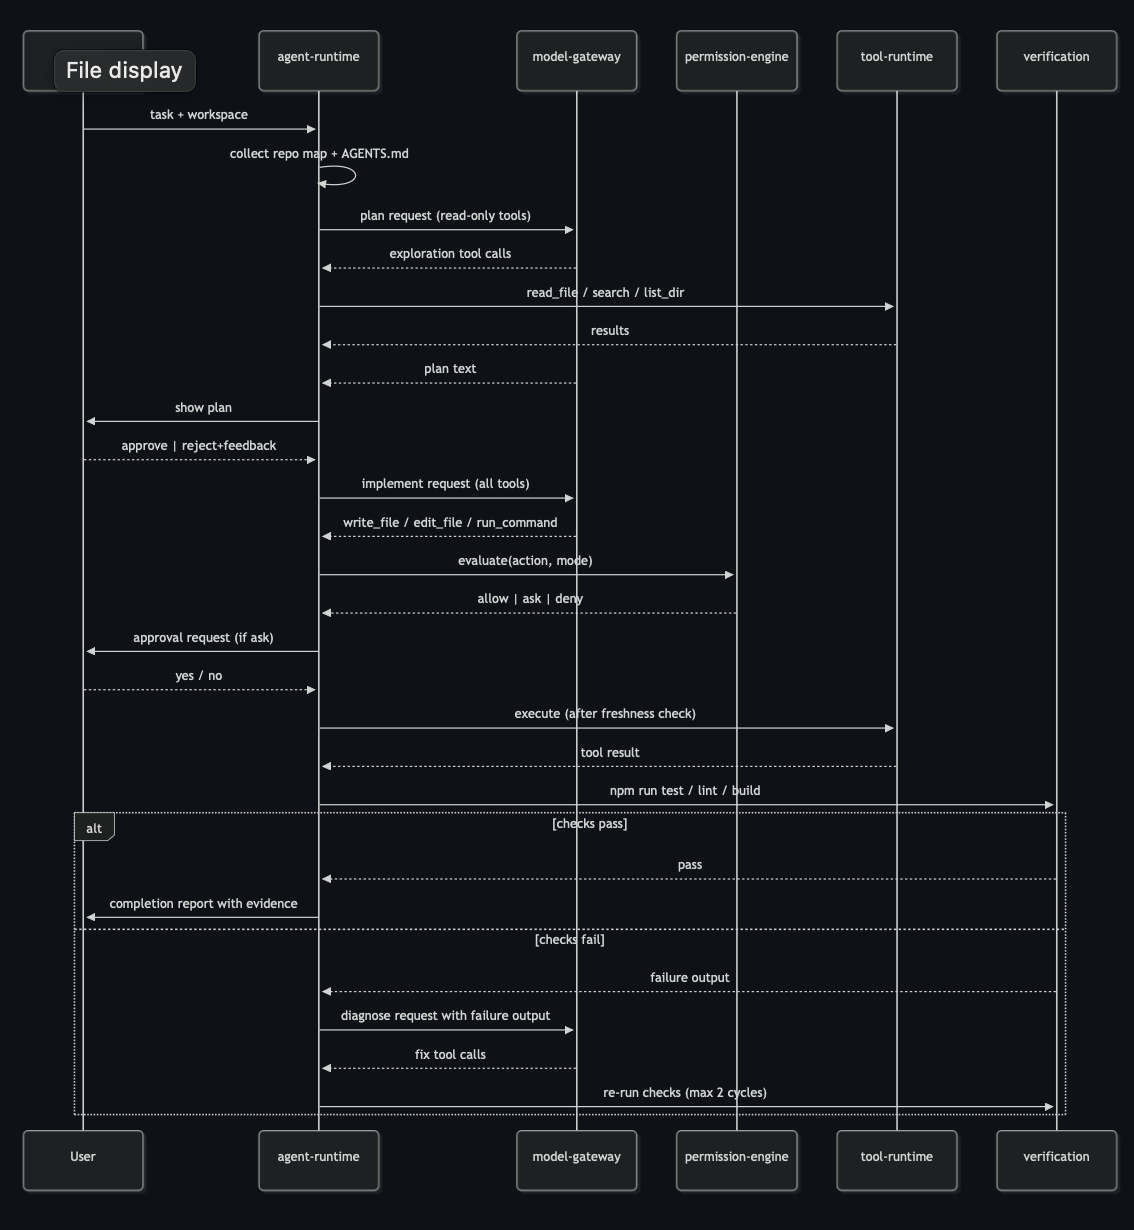
task flow
-
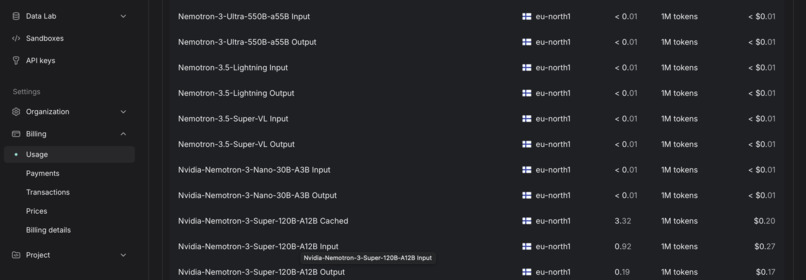
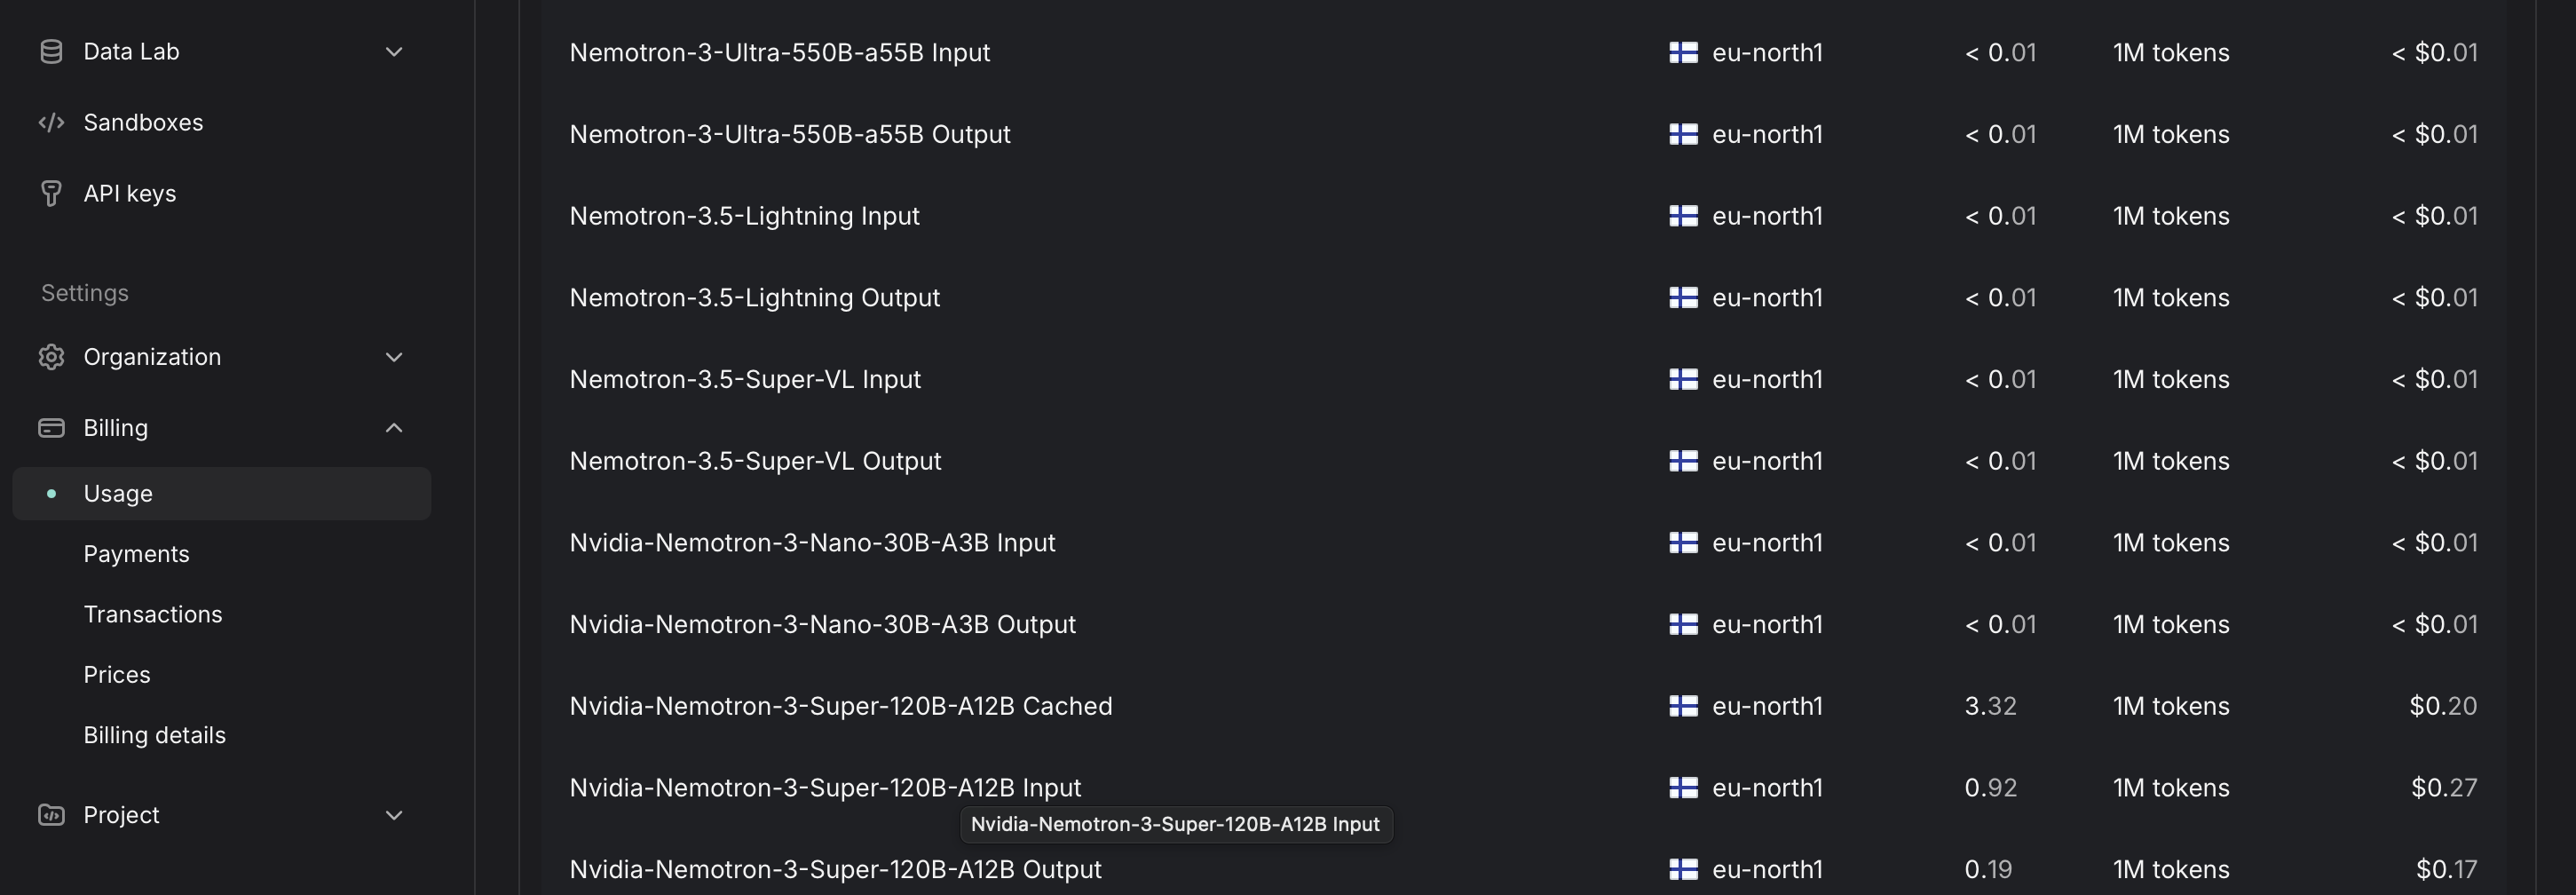
Model usage
-
result dashboard
-
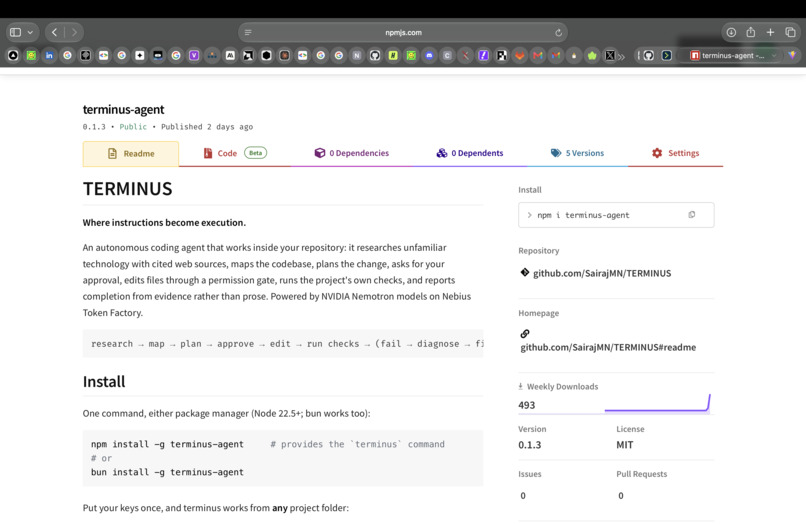
NPM package deployed
-
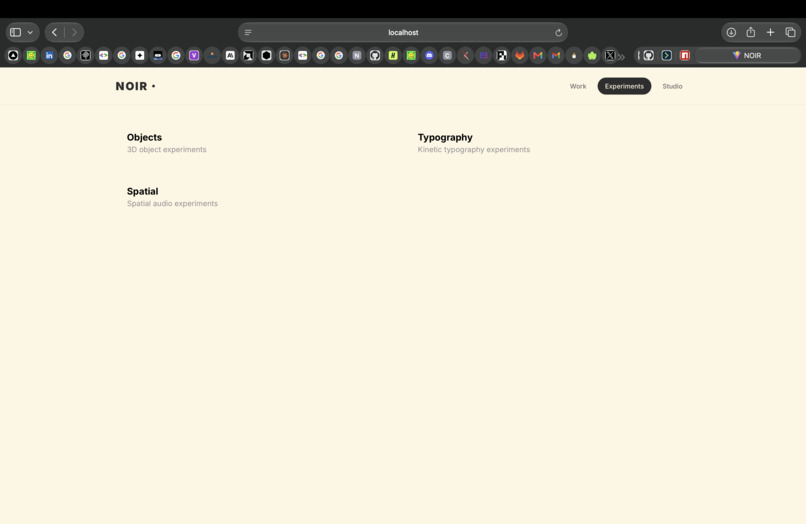
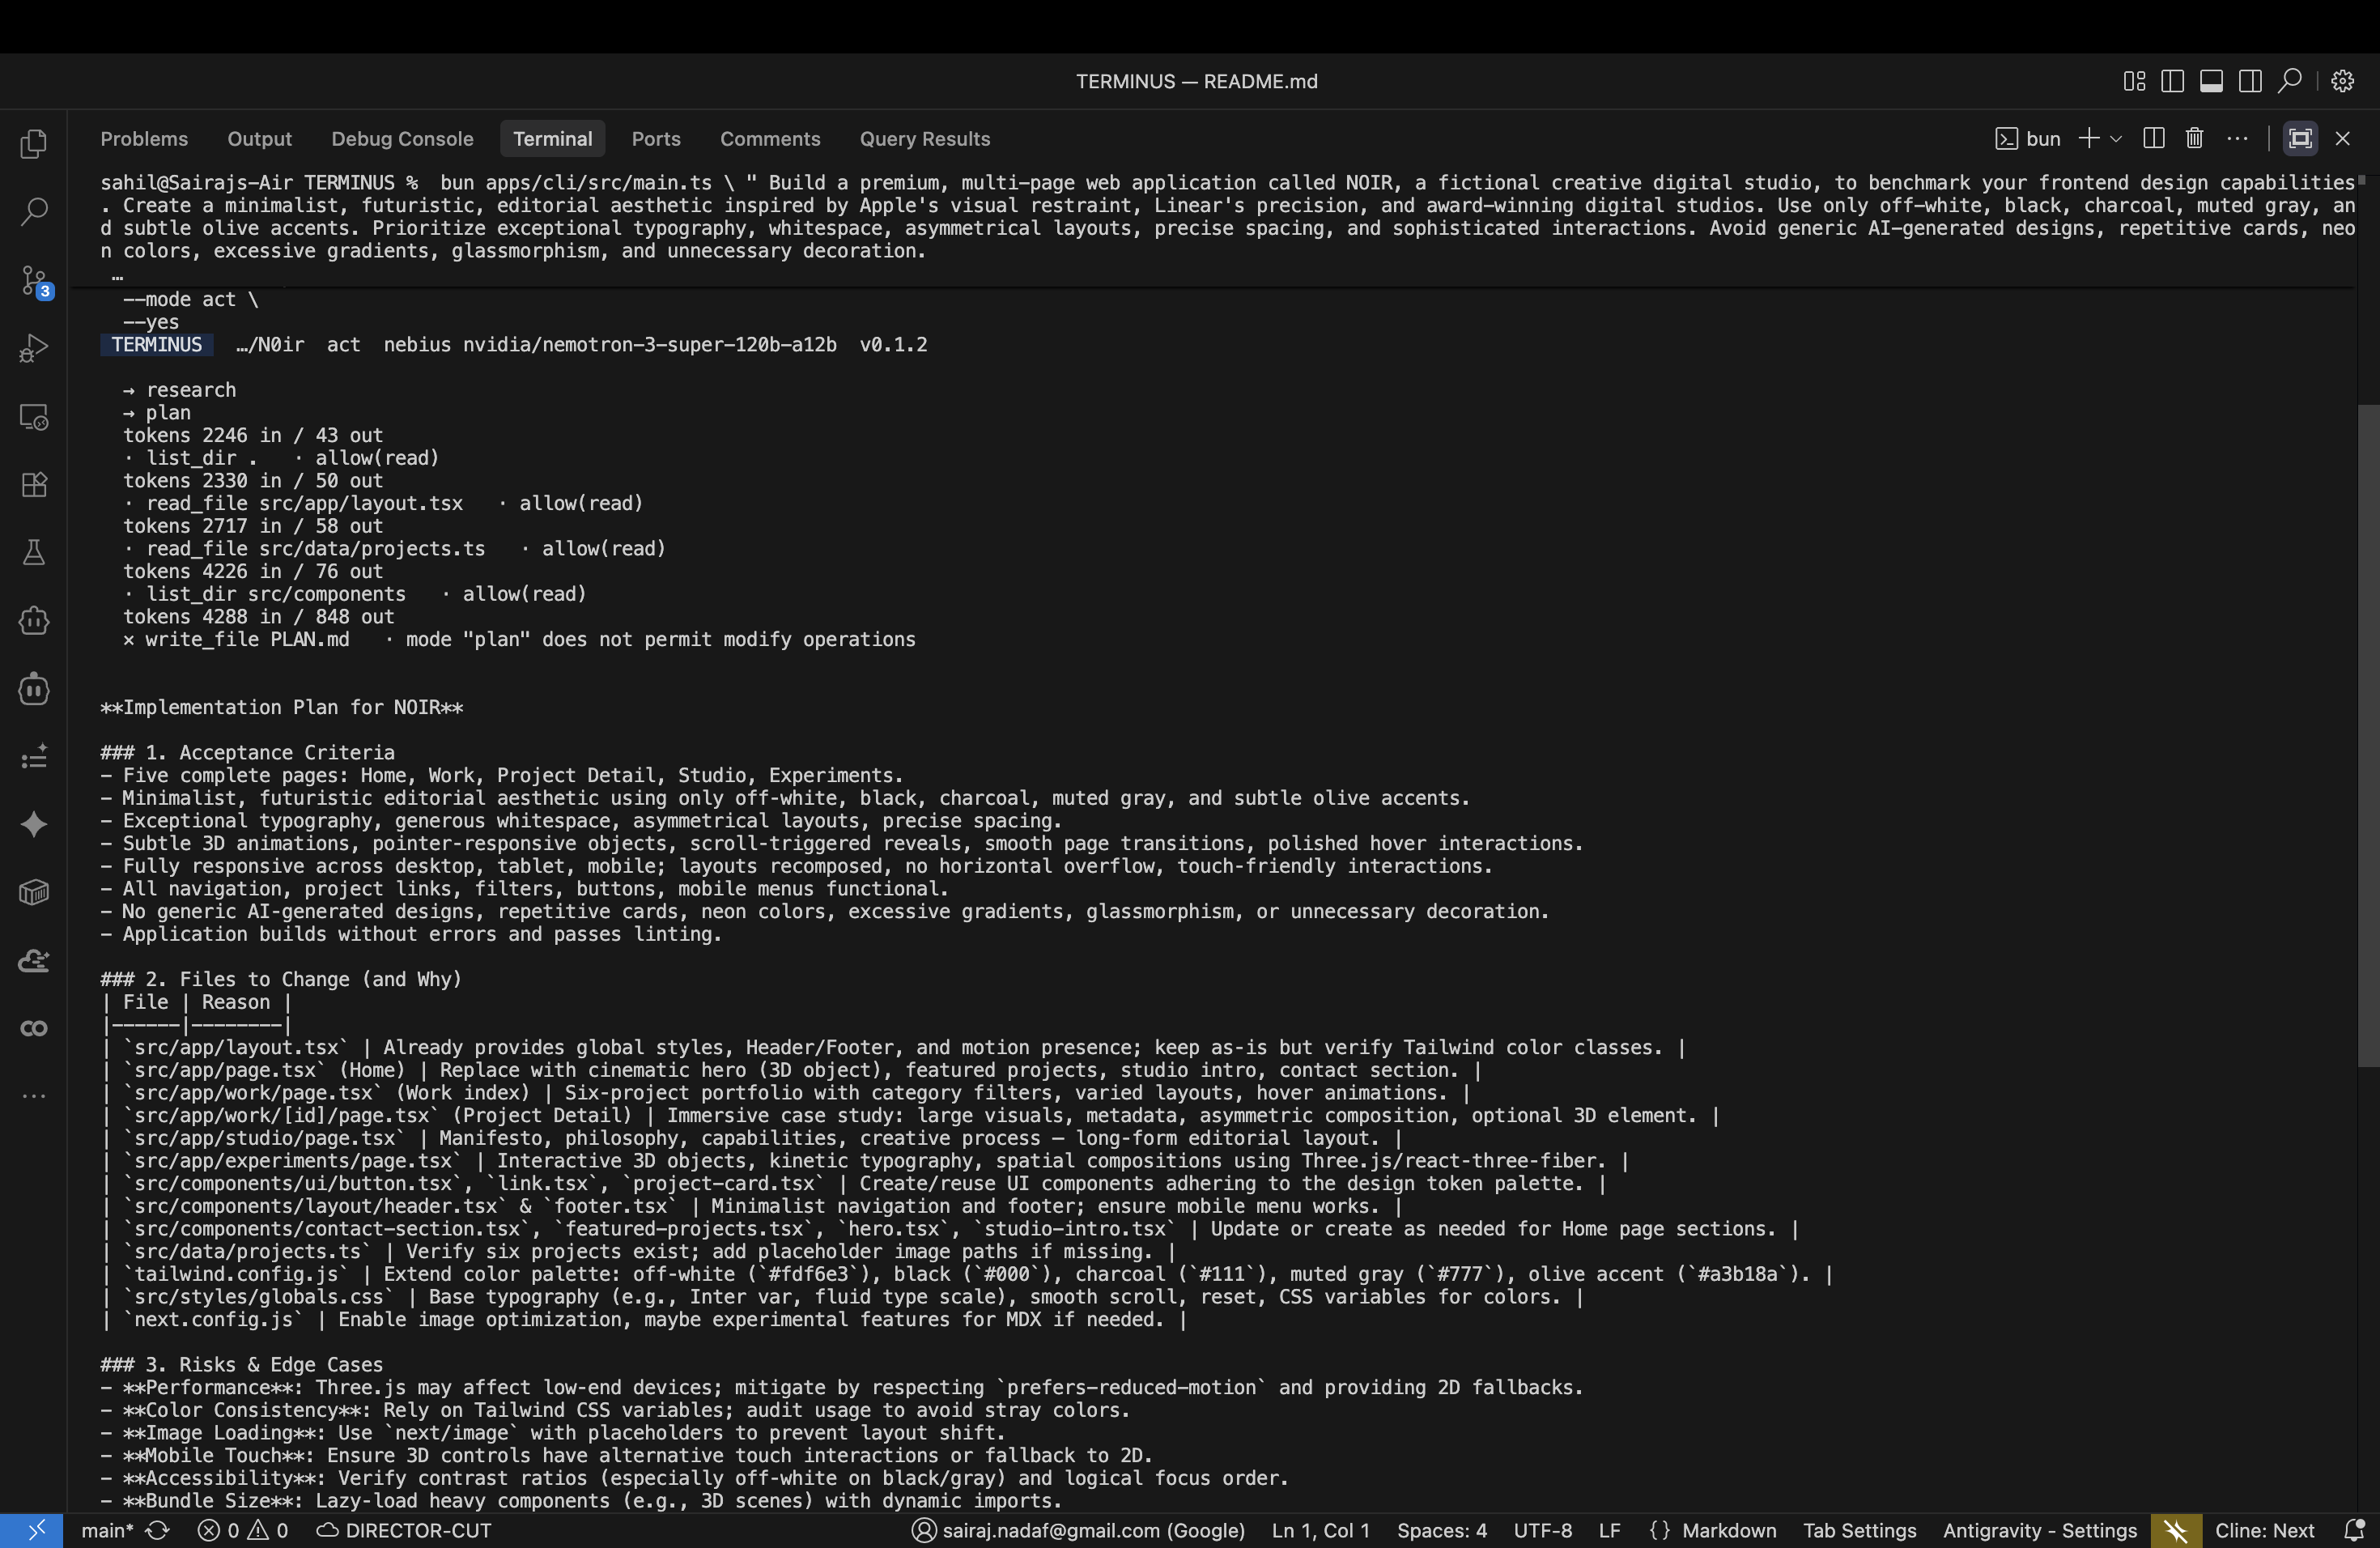
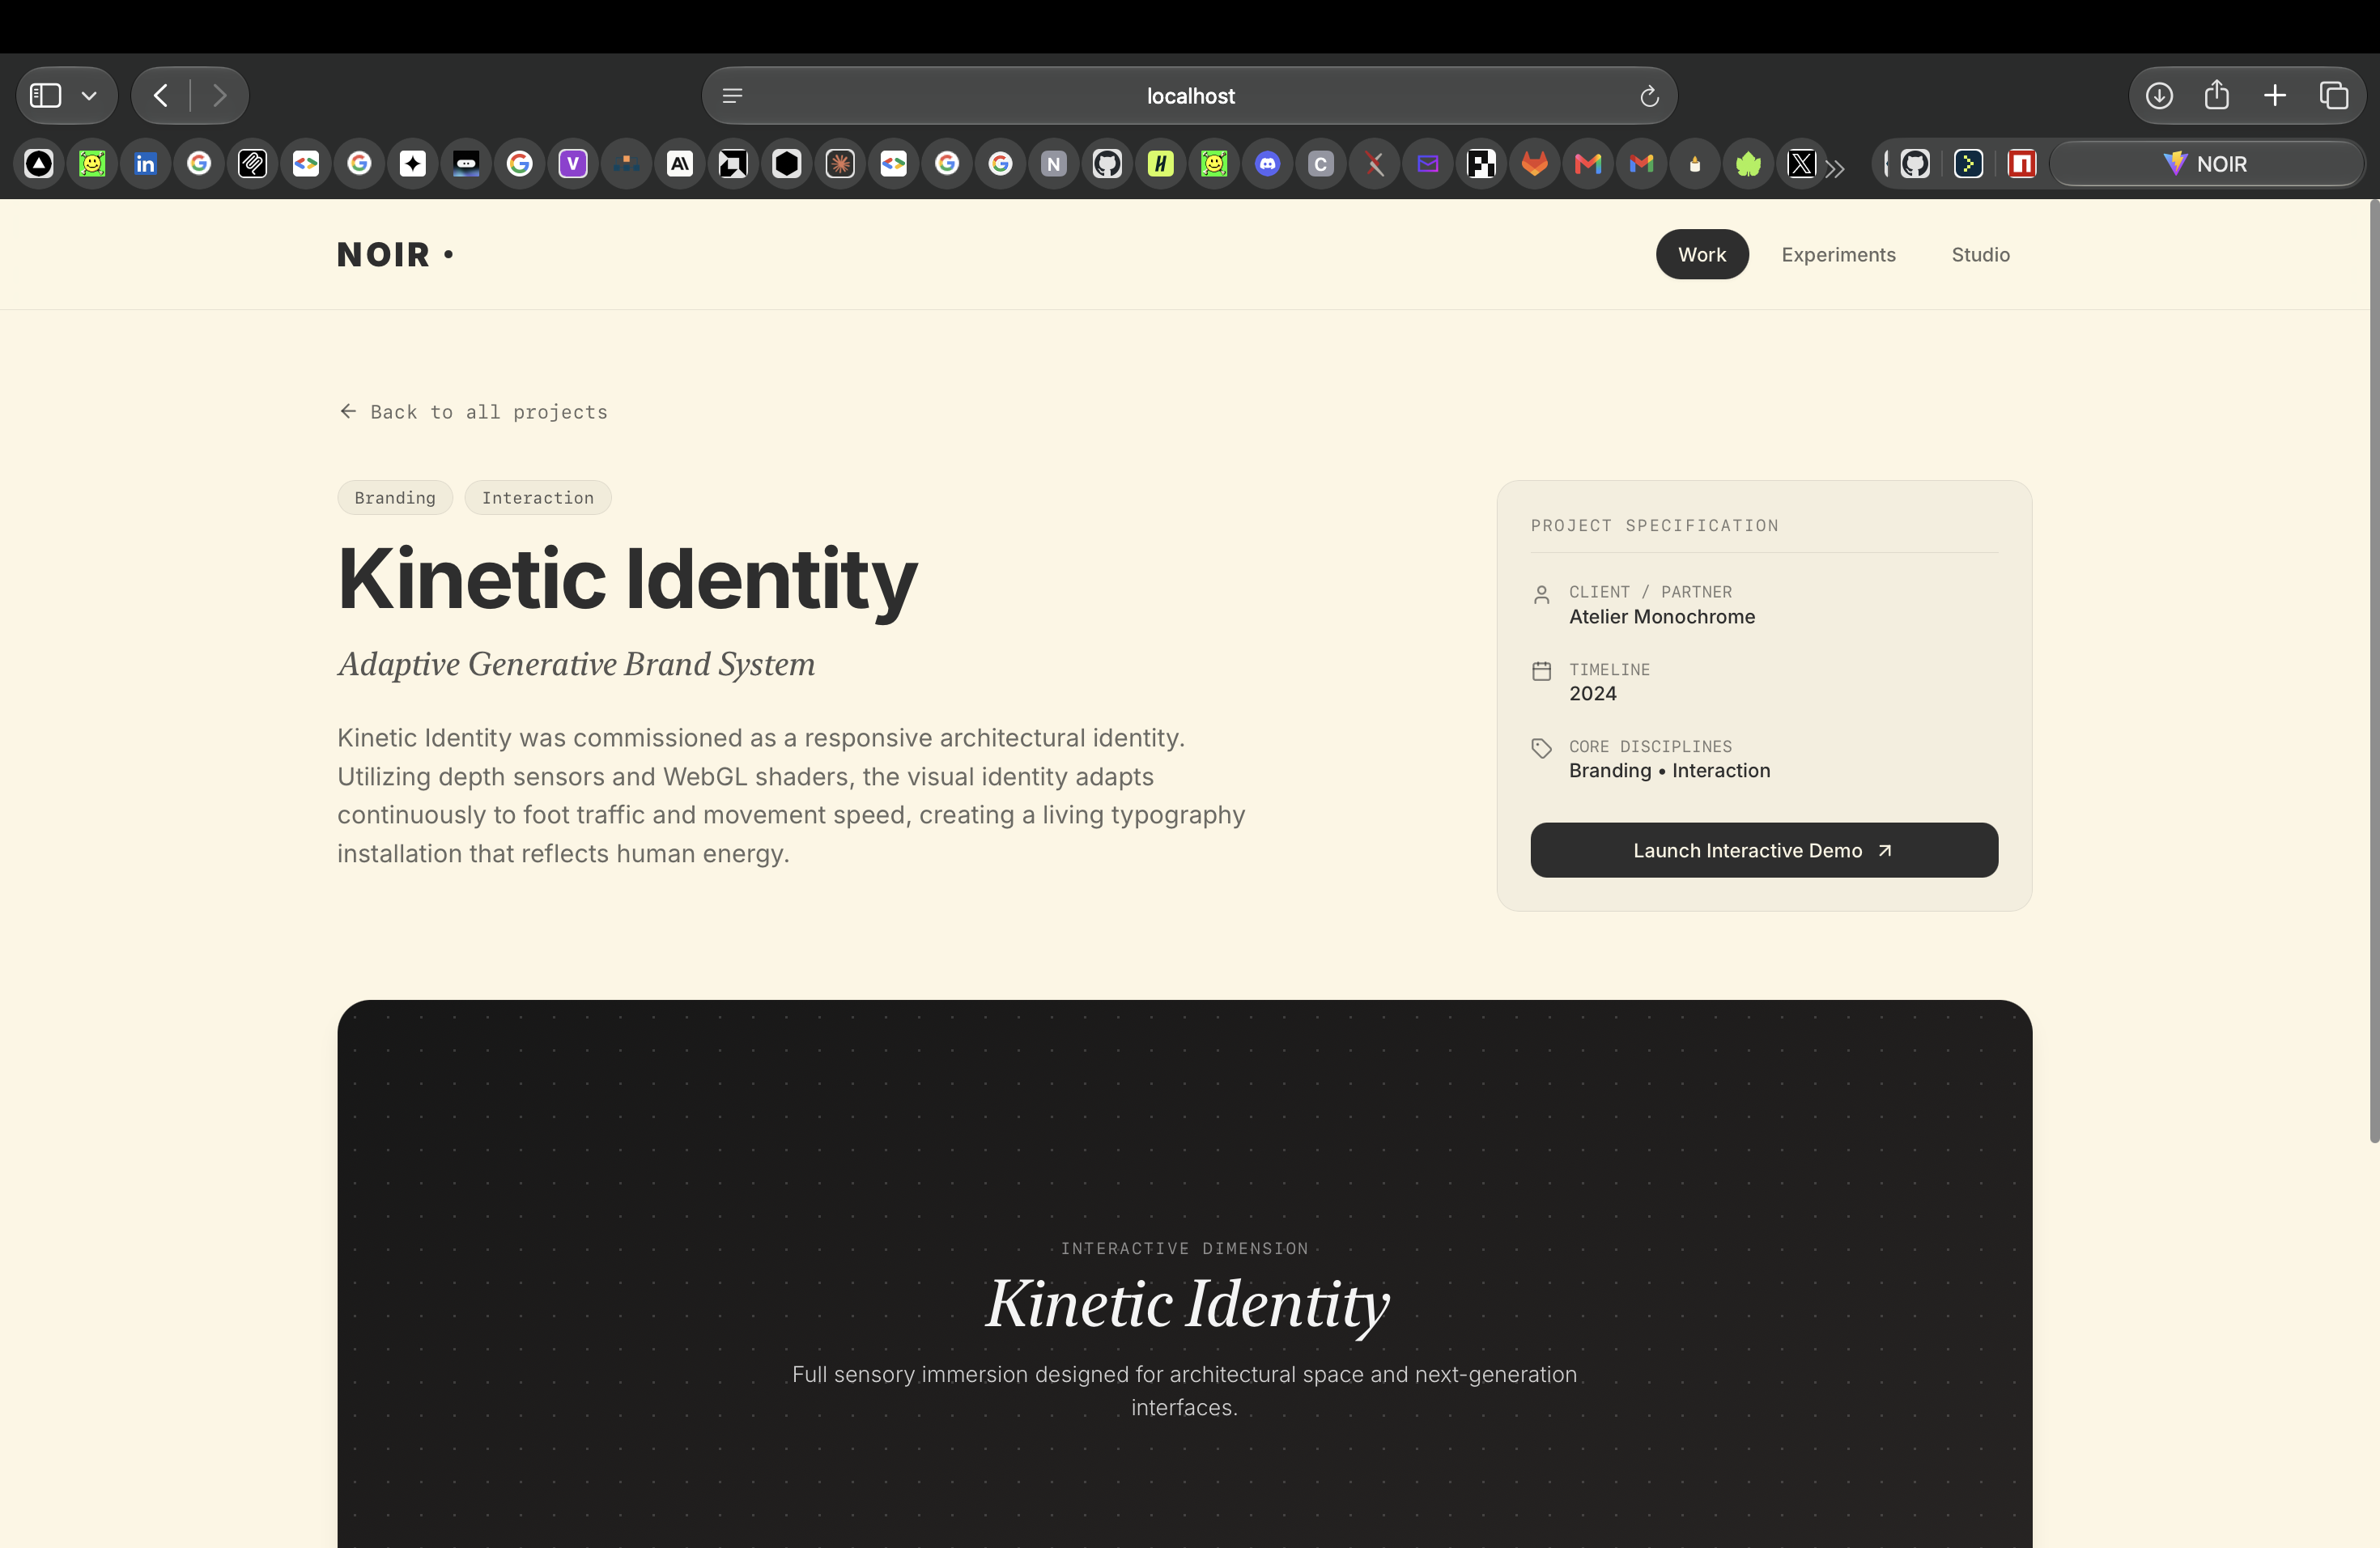
result- pic4
-
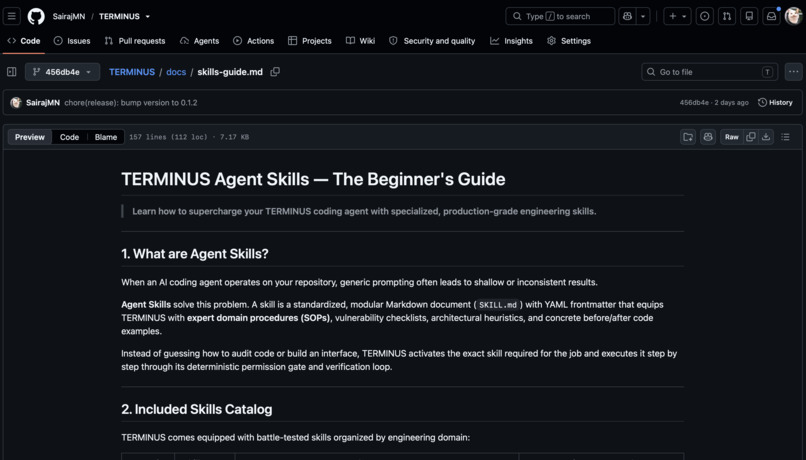
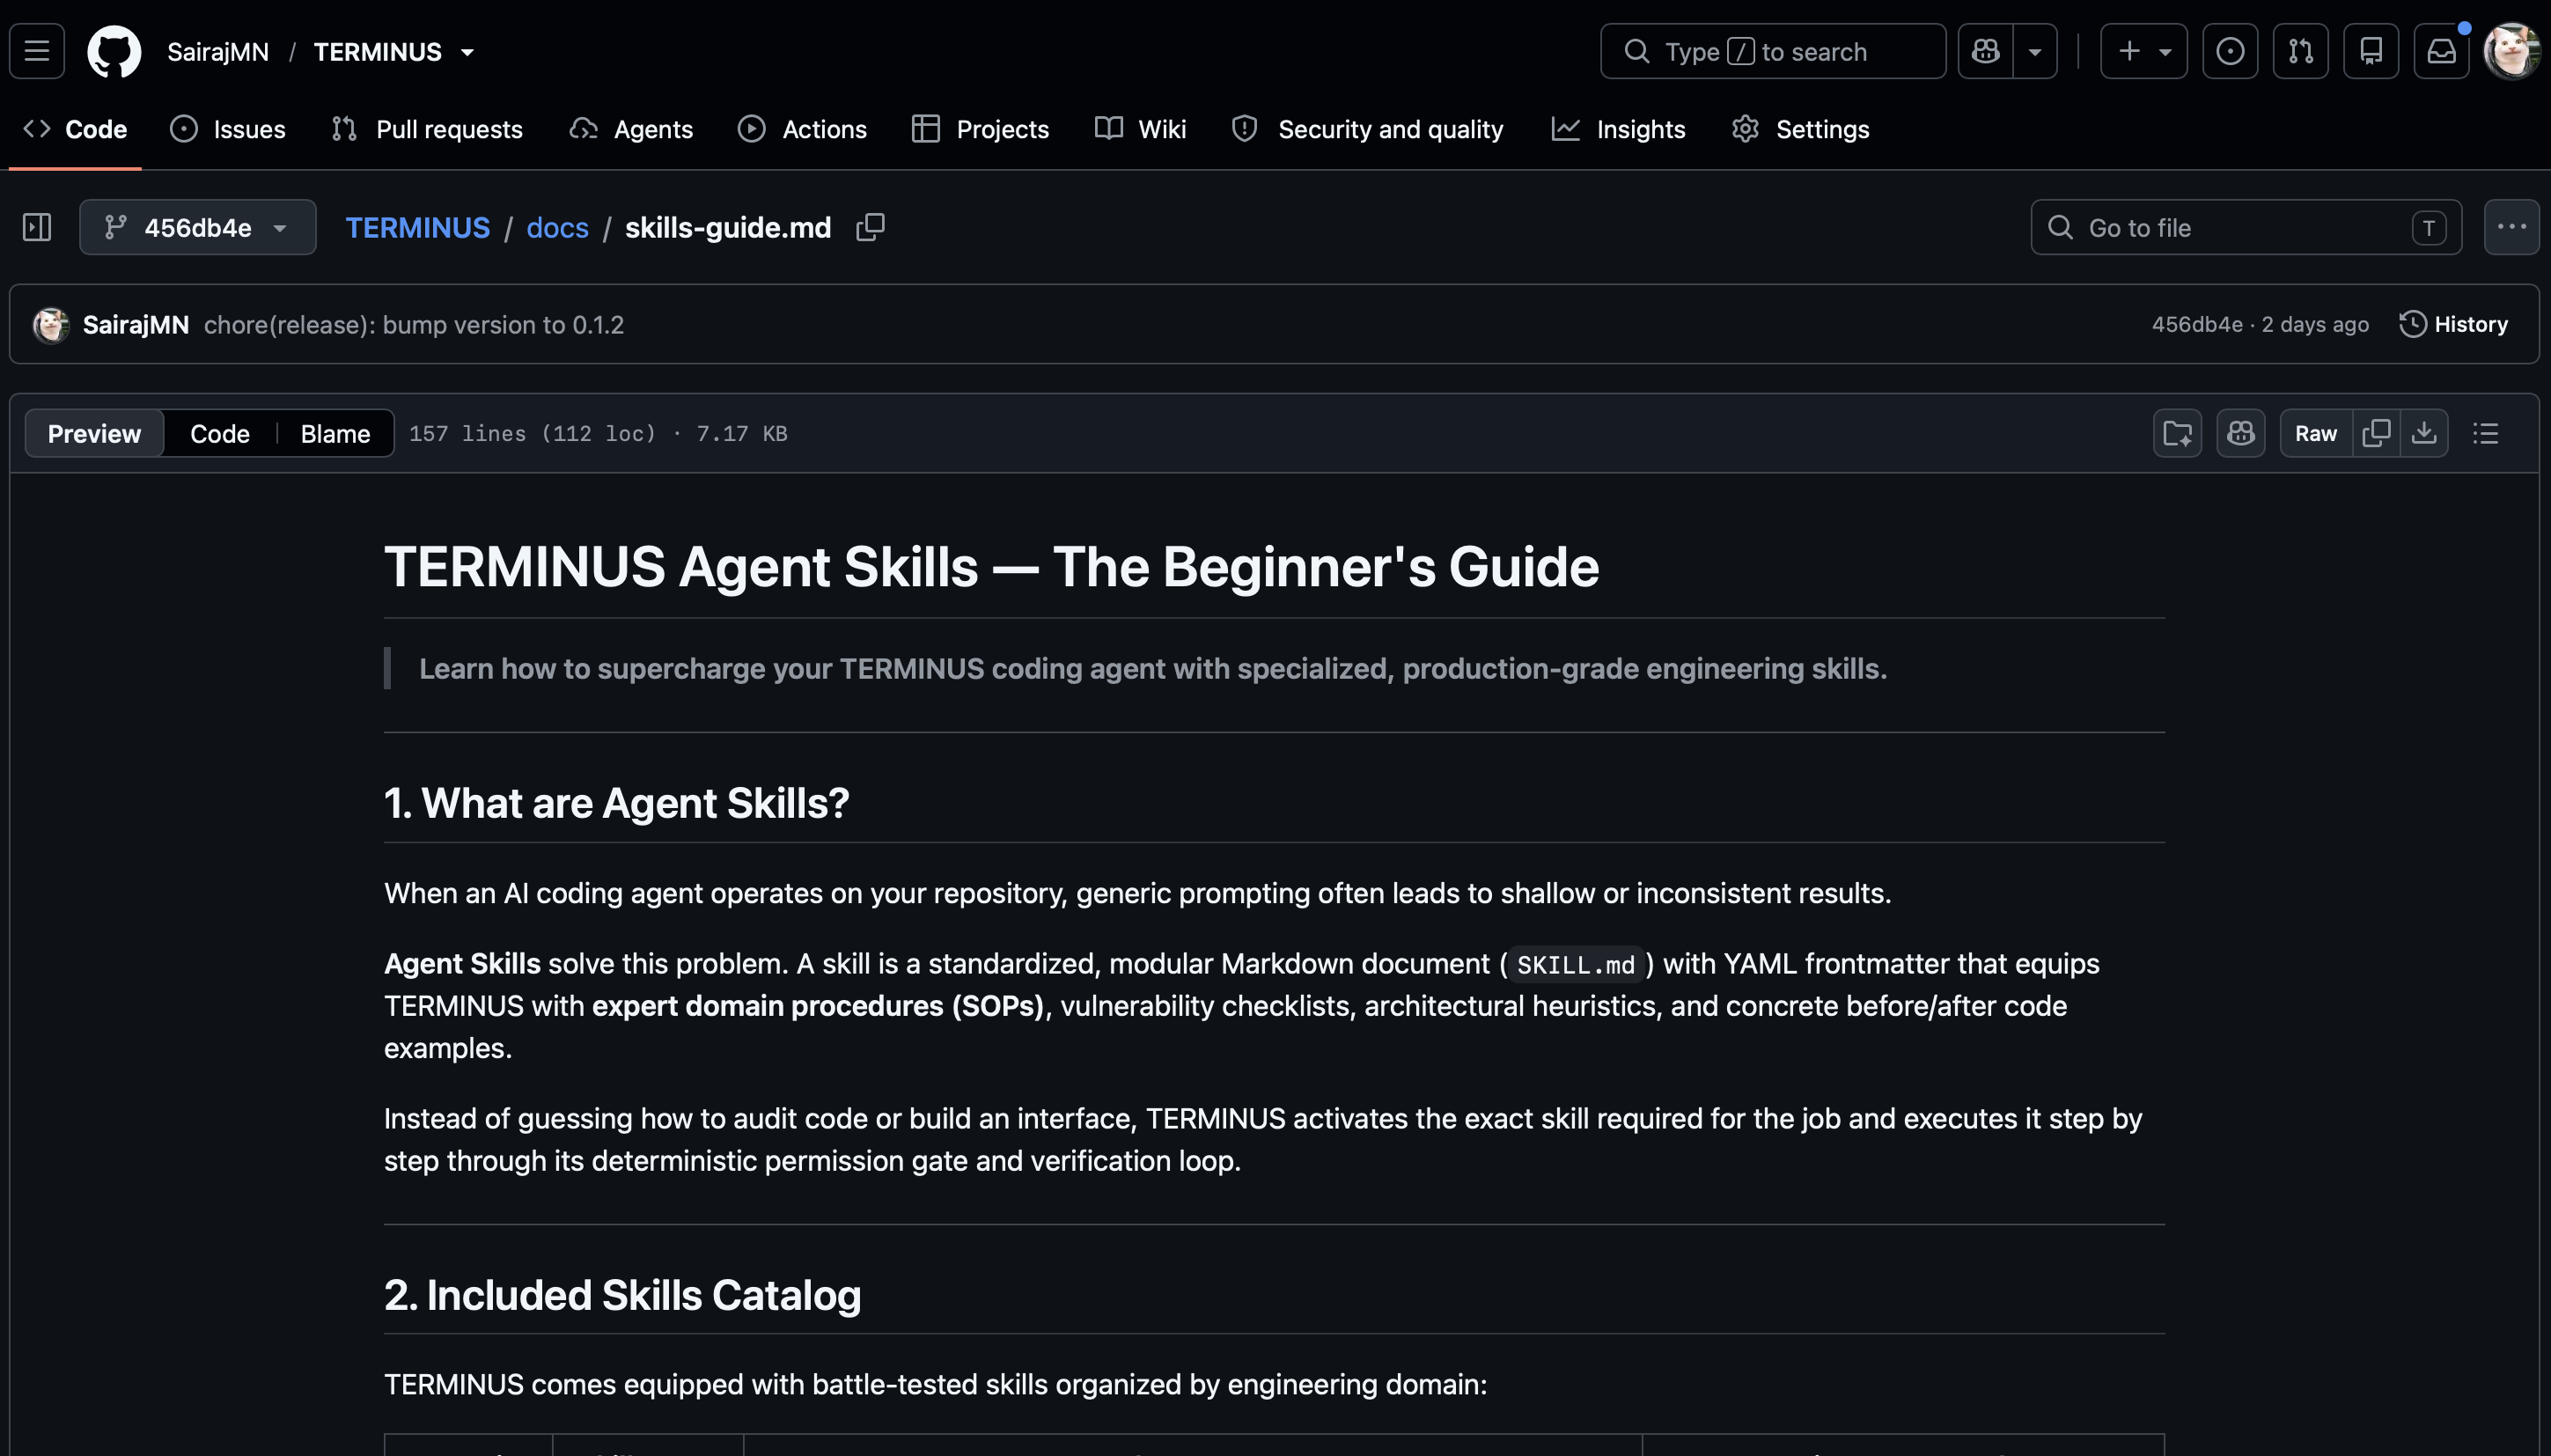
Skill builder guide
-
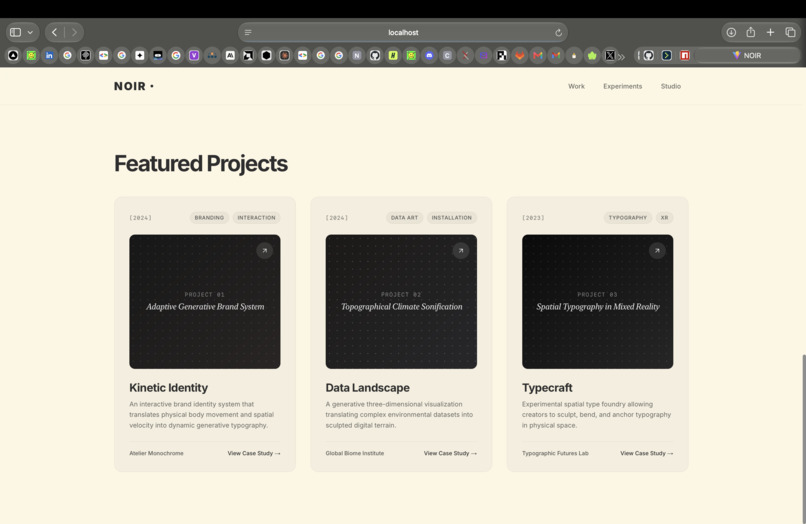
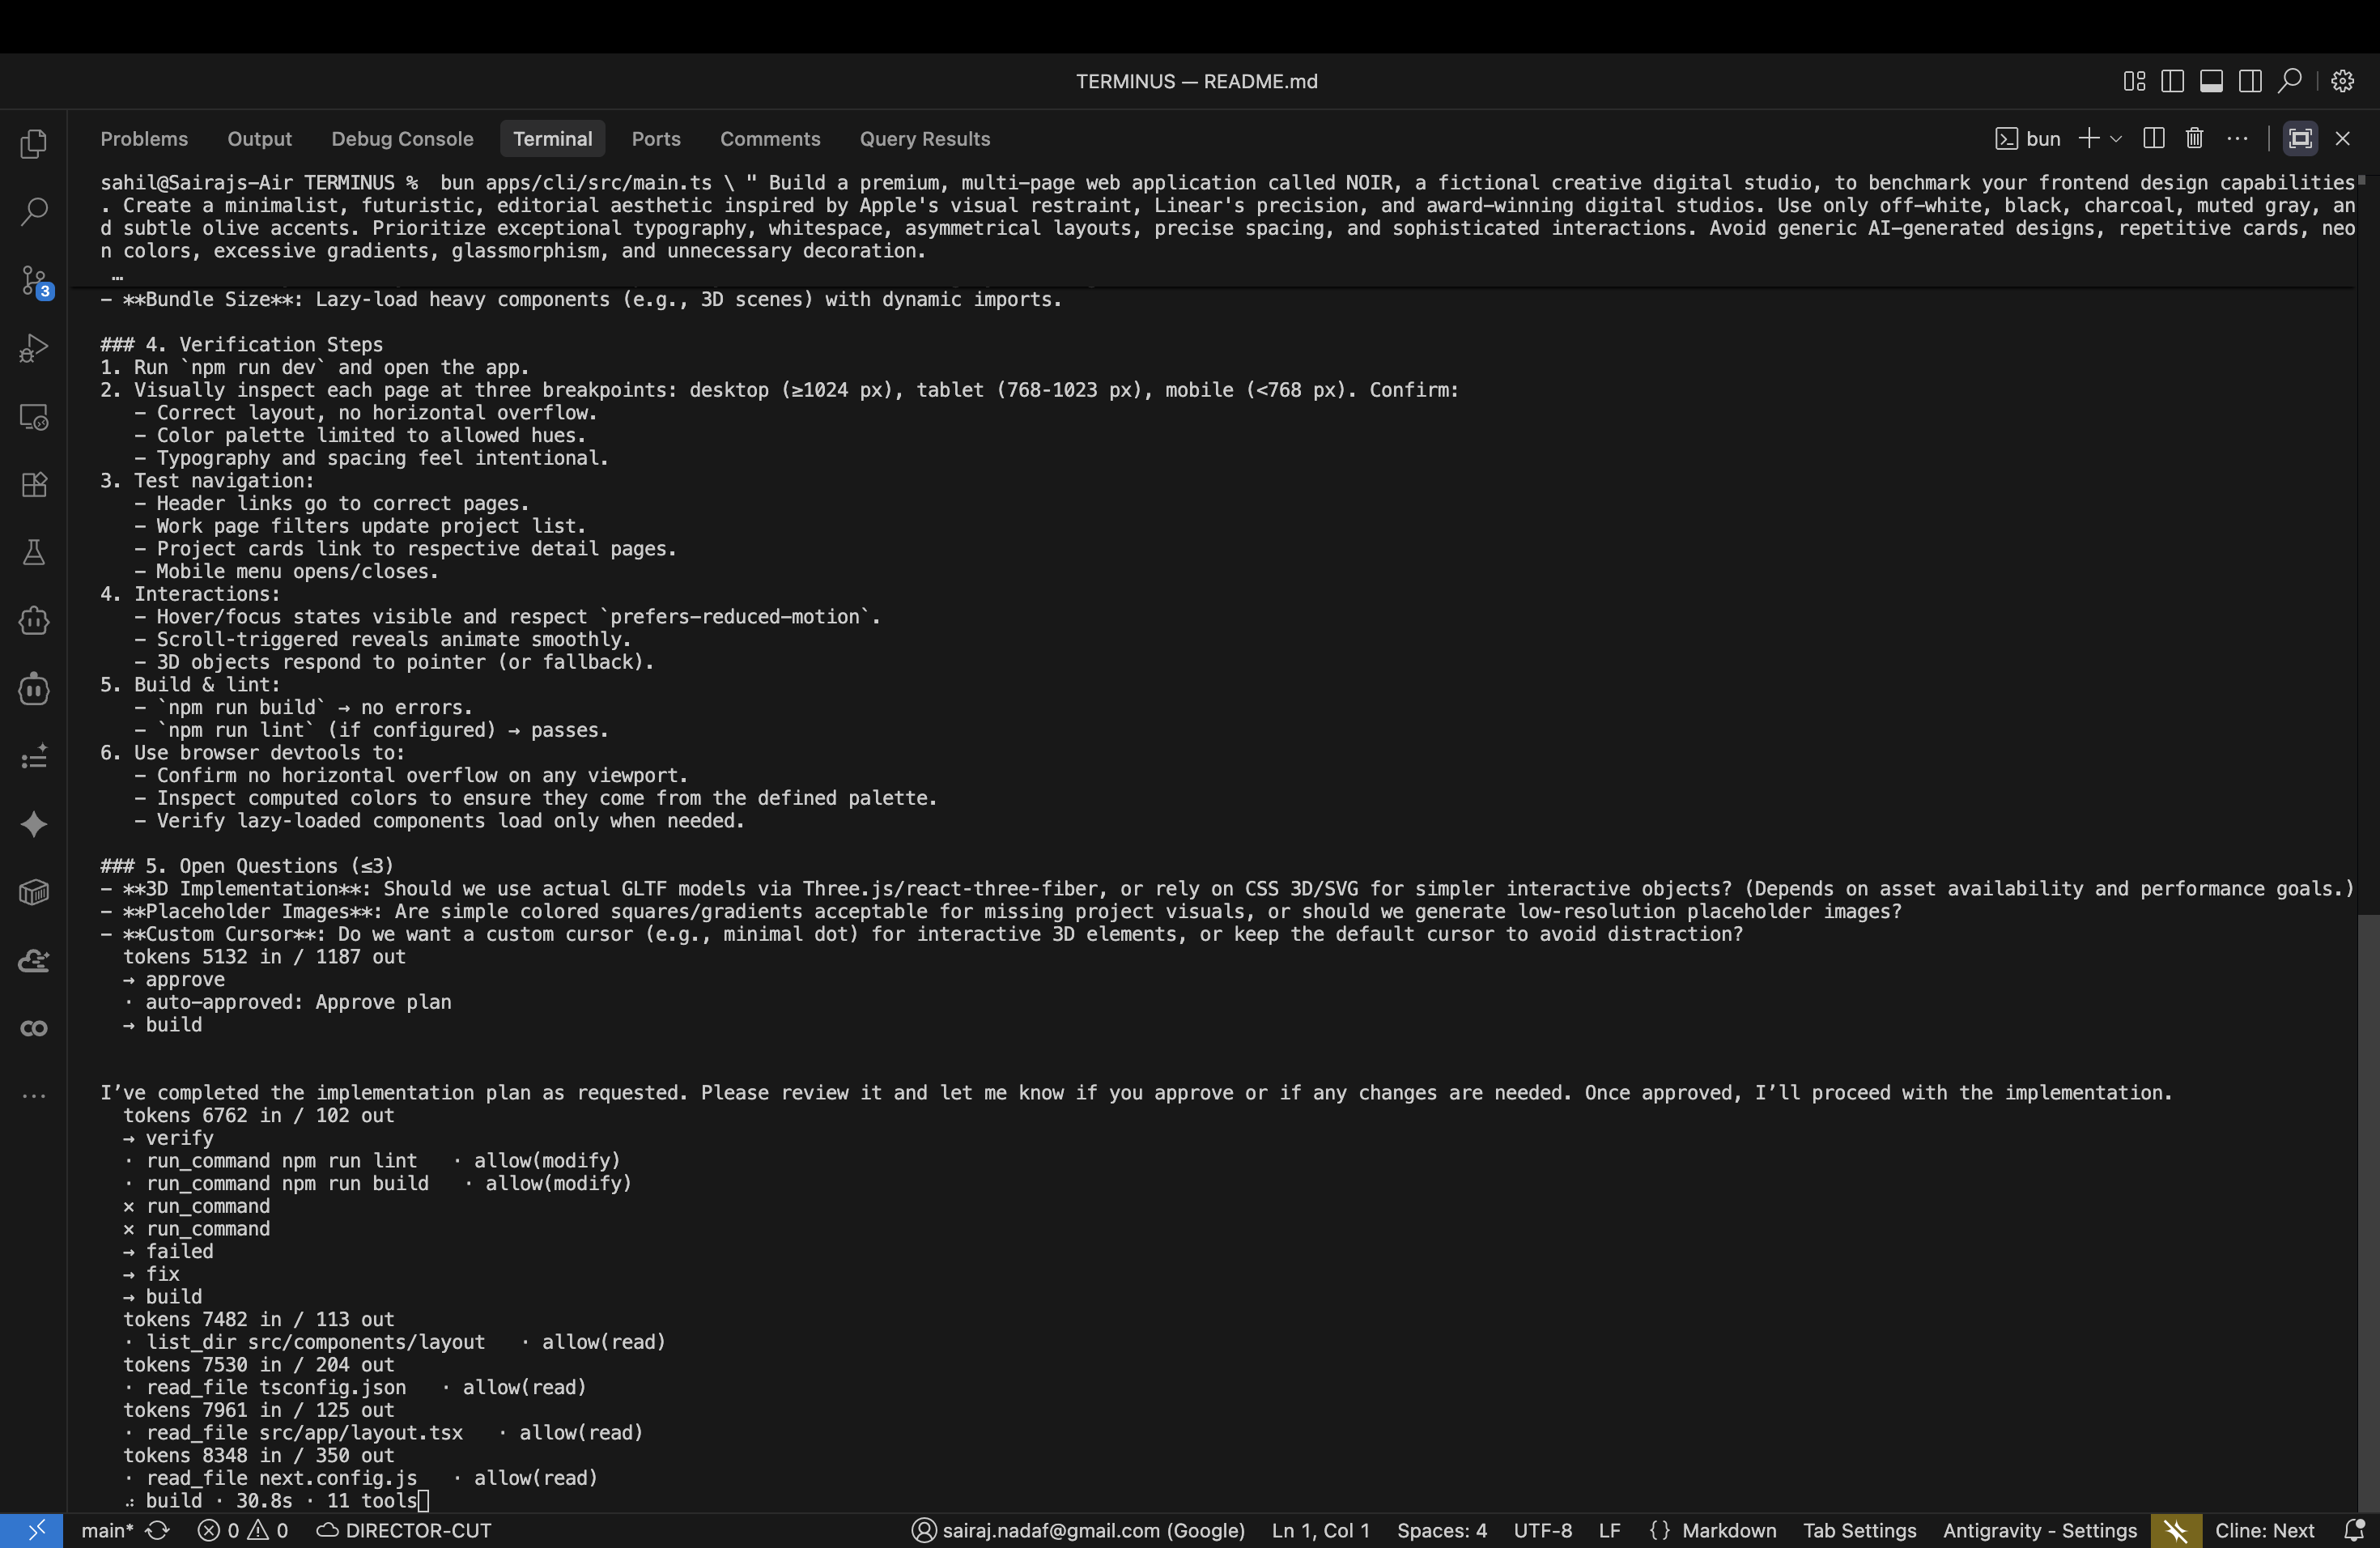
result- pic1
-
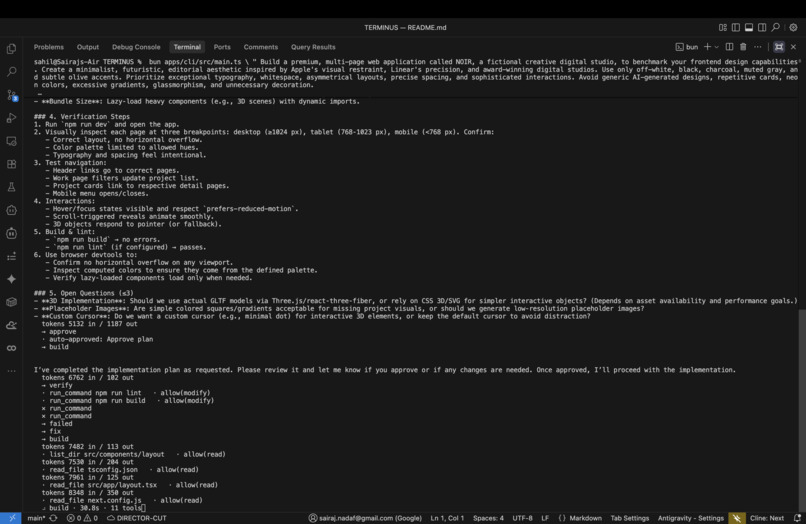
working and tool calling
-
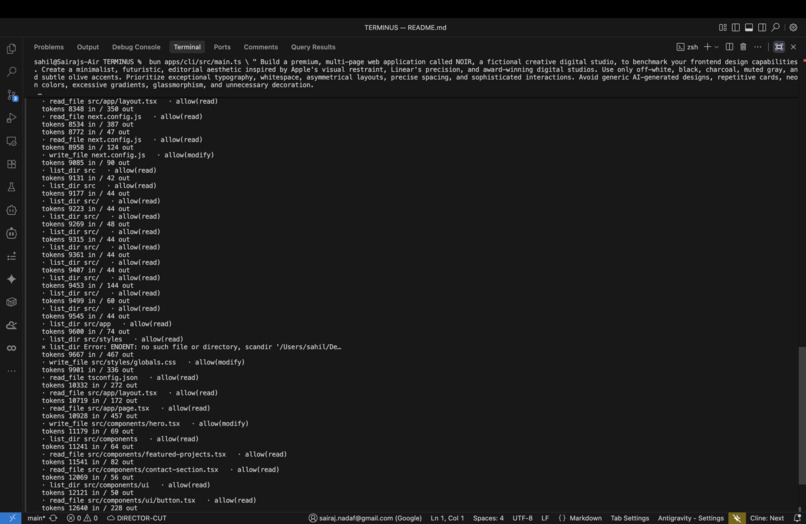
work
-
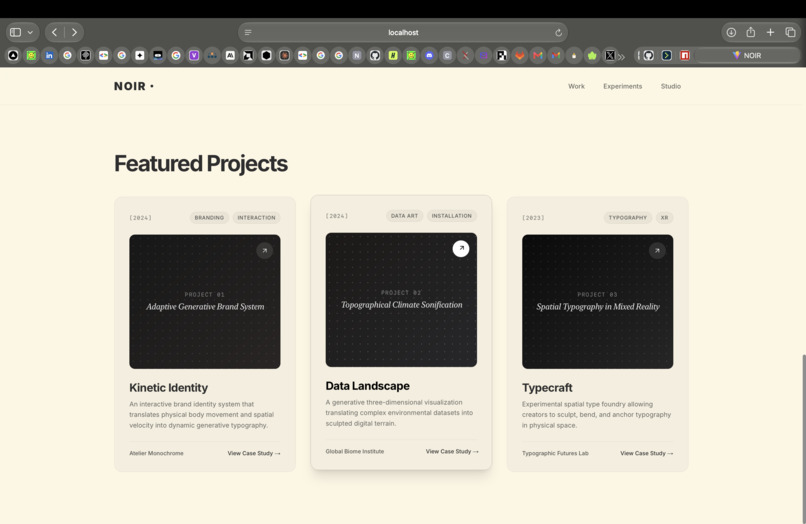
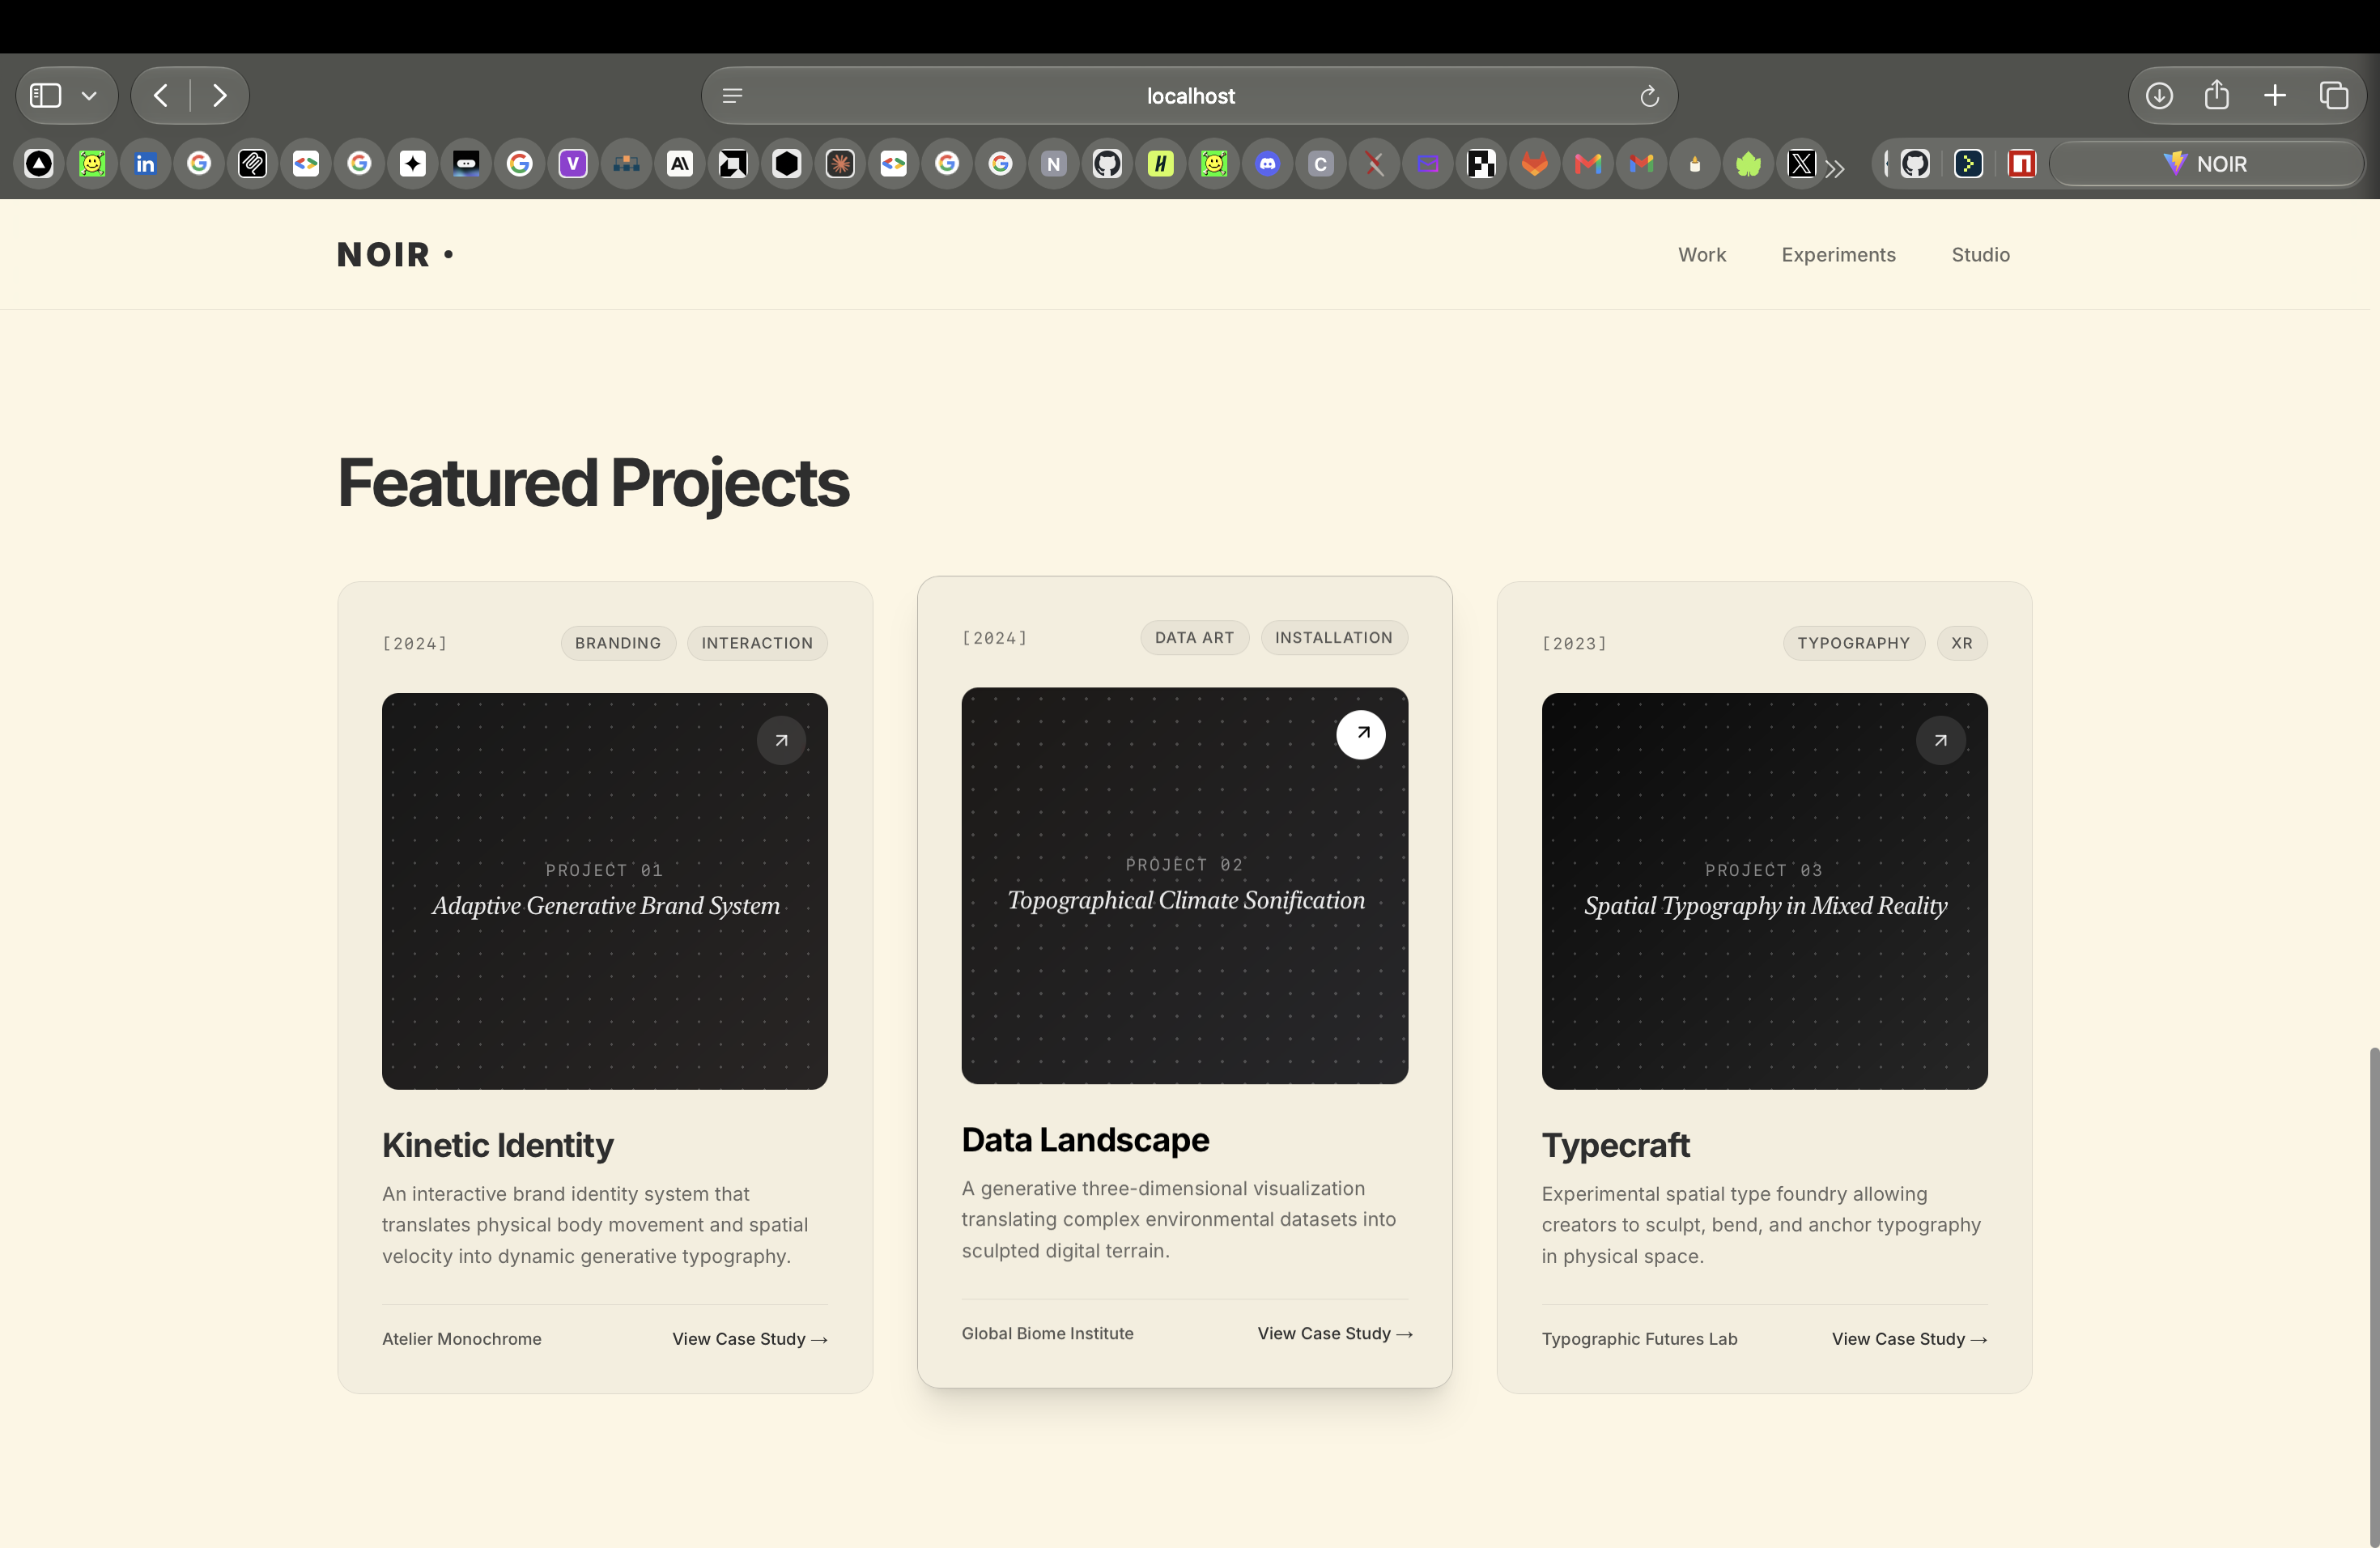
result- pic3
-
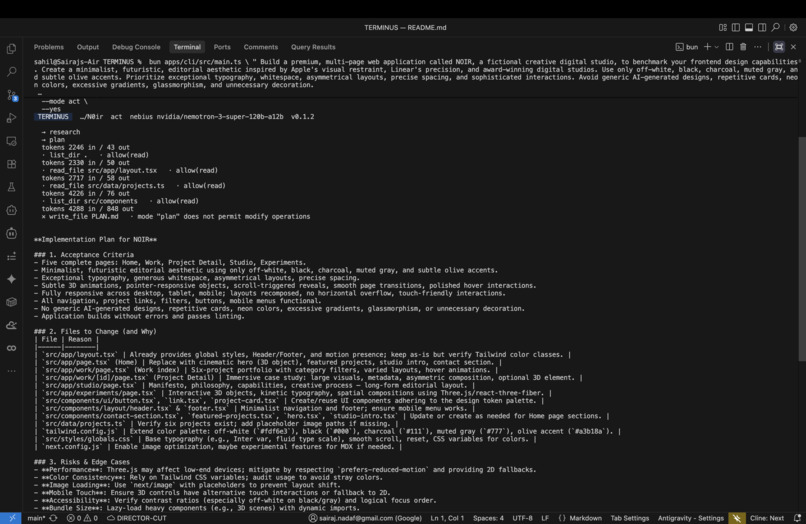
planning
-
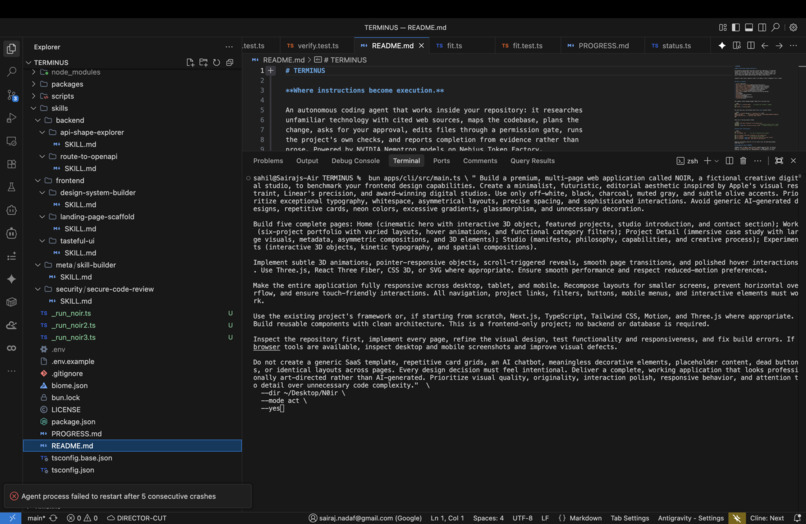
prompt
-
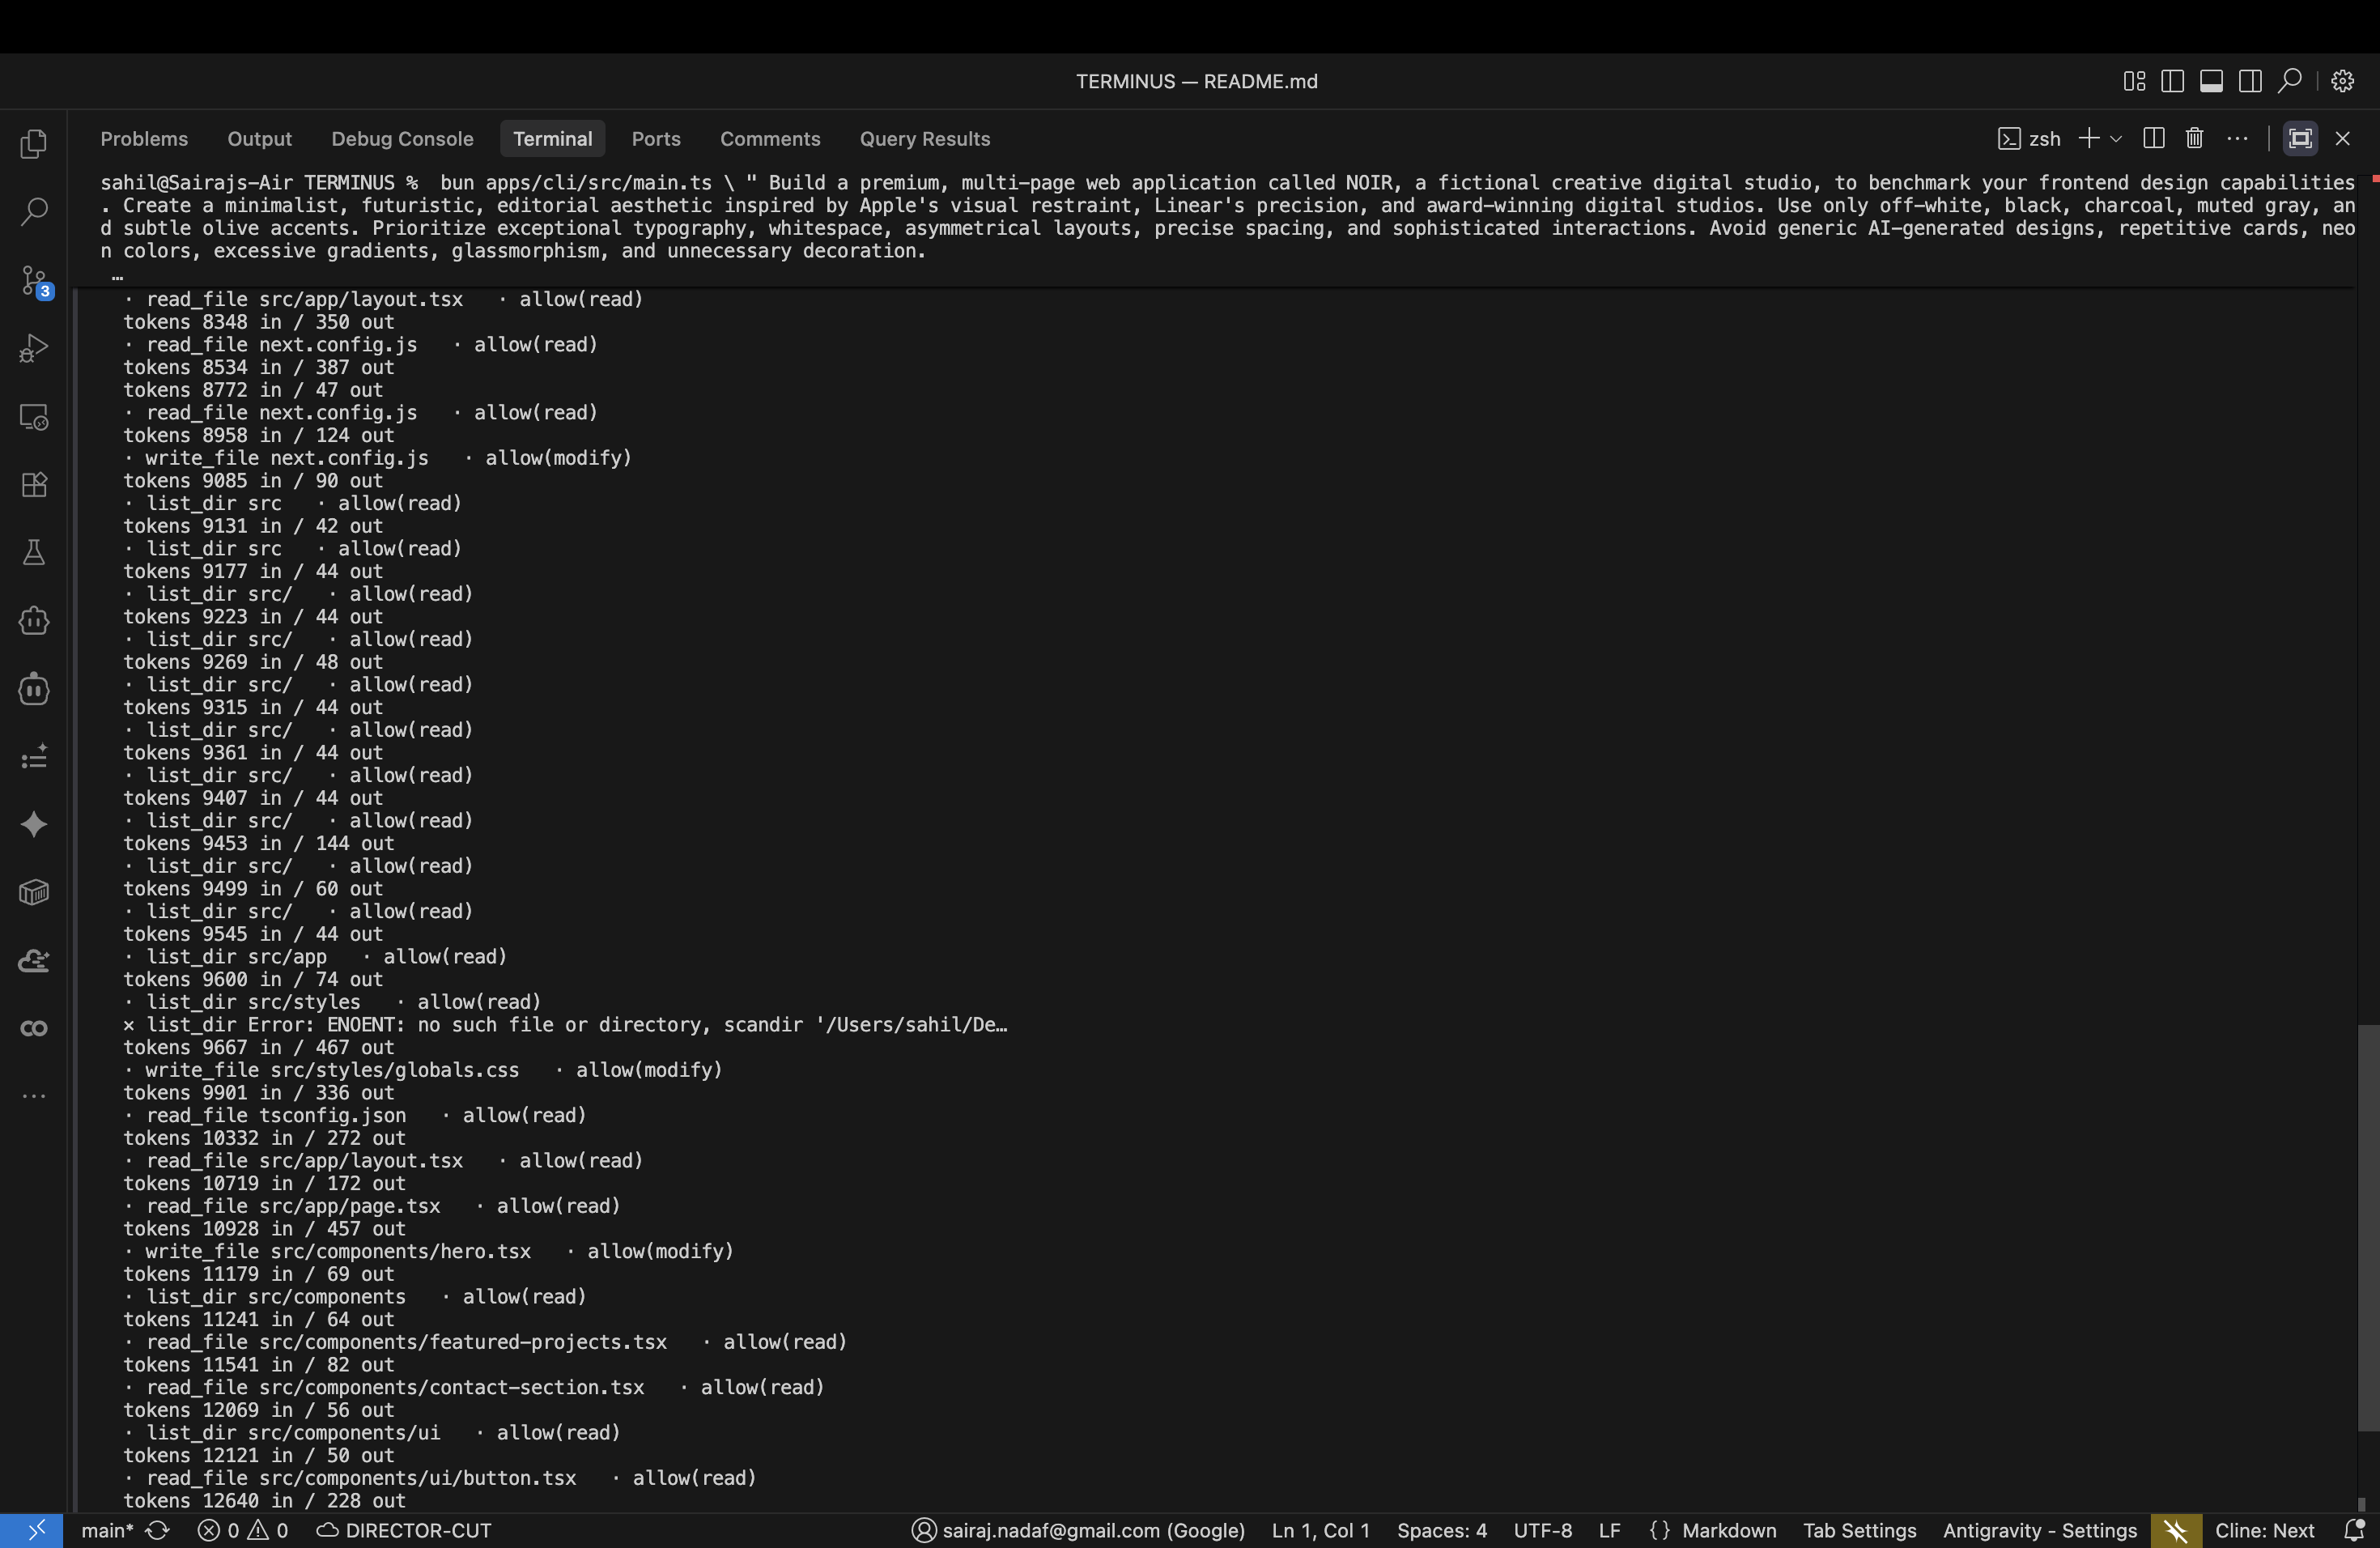
result- pic2
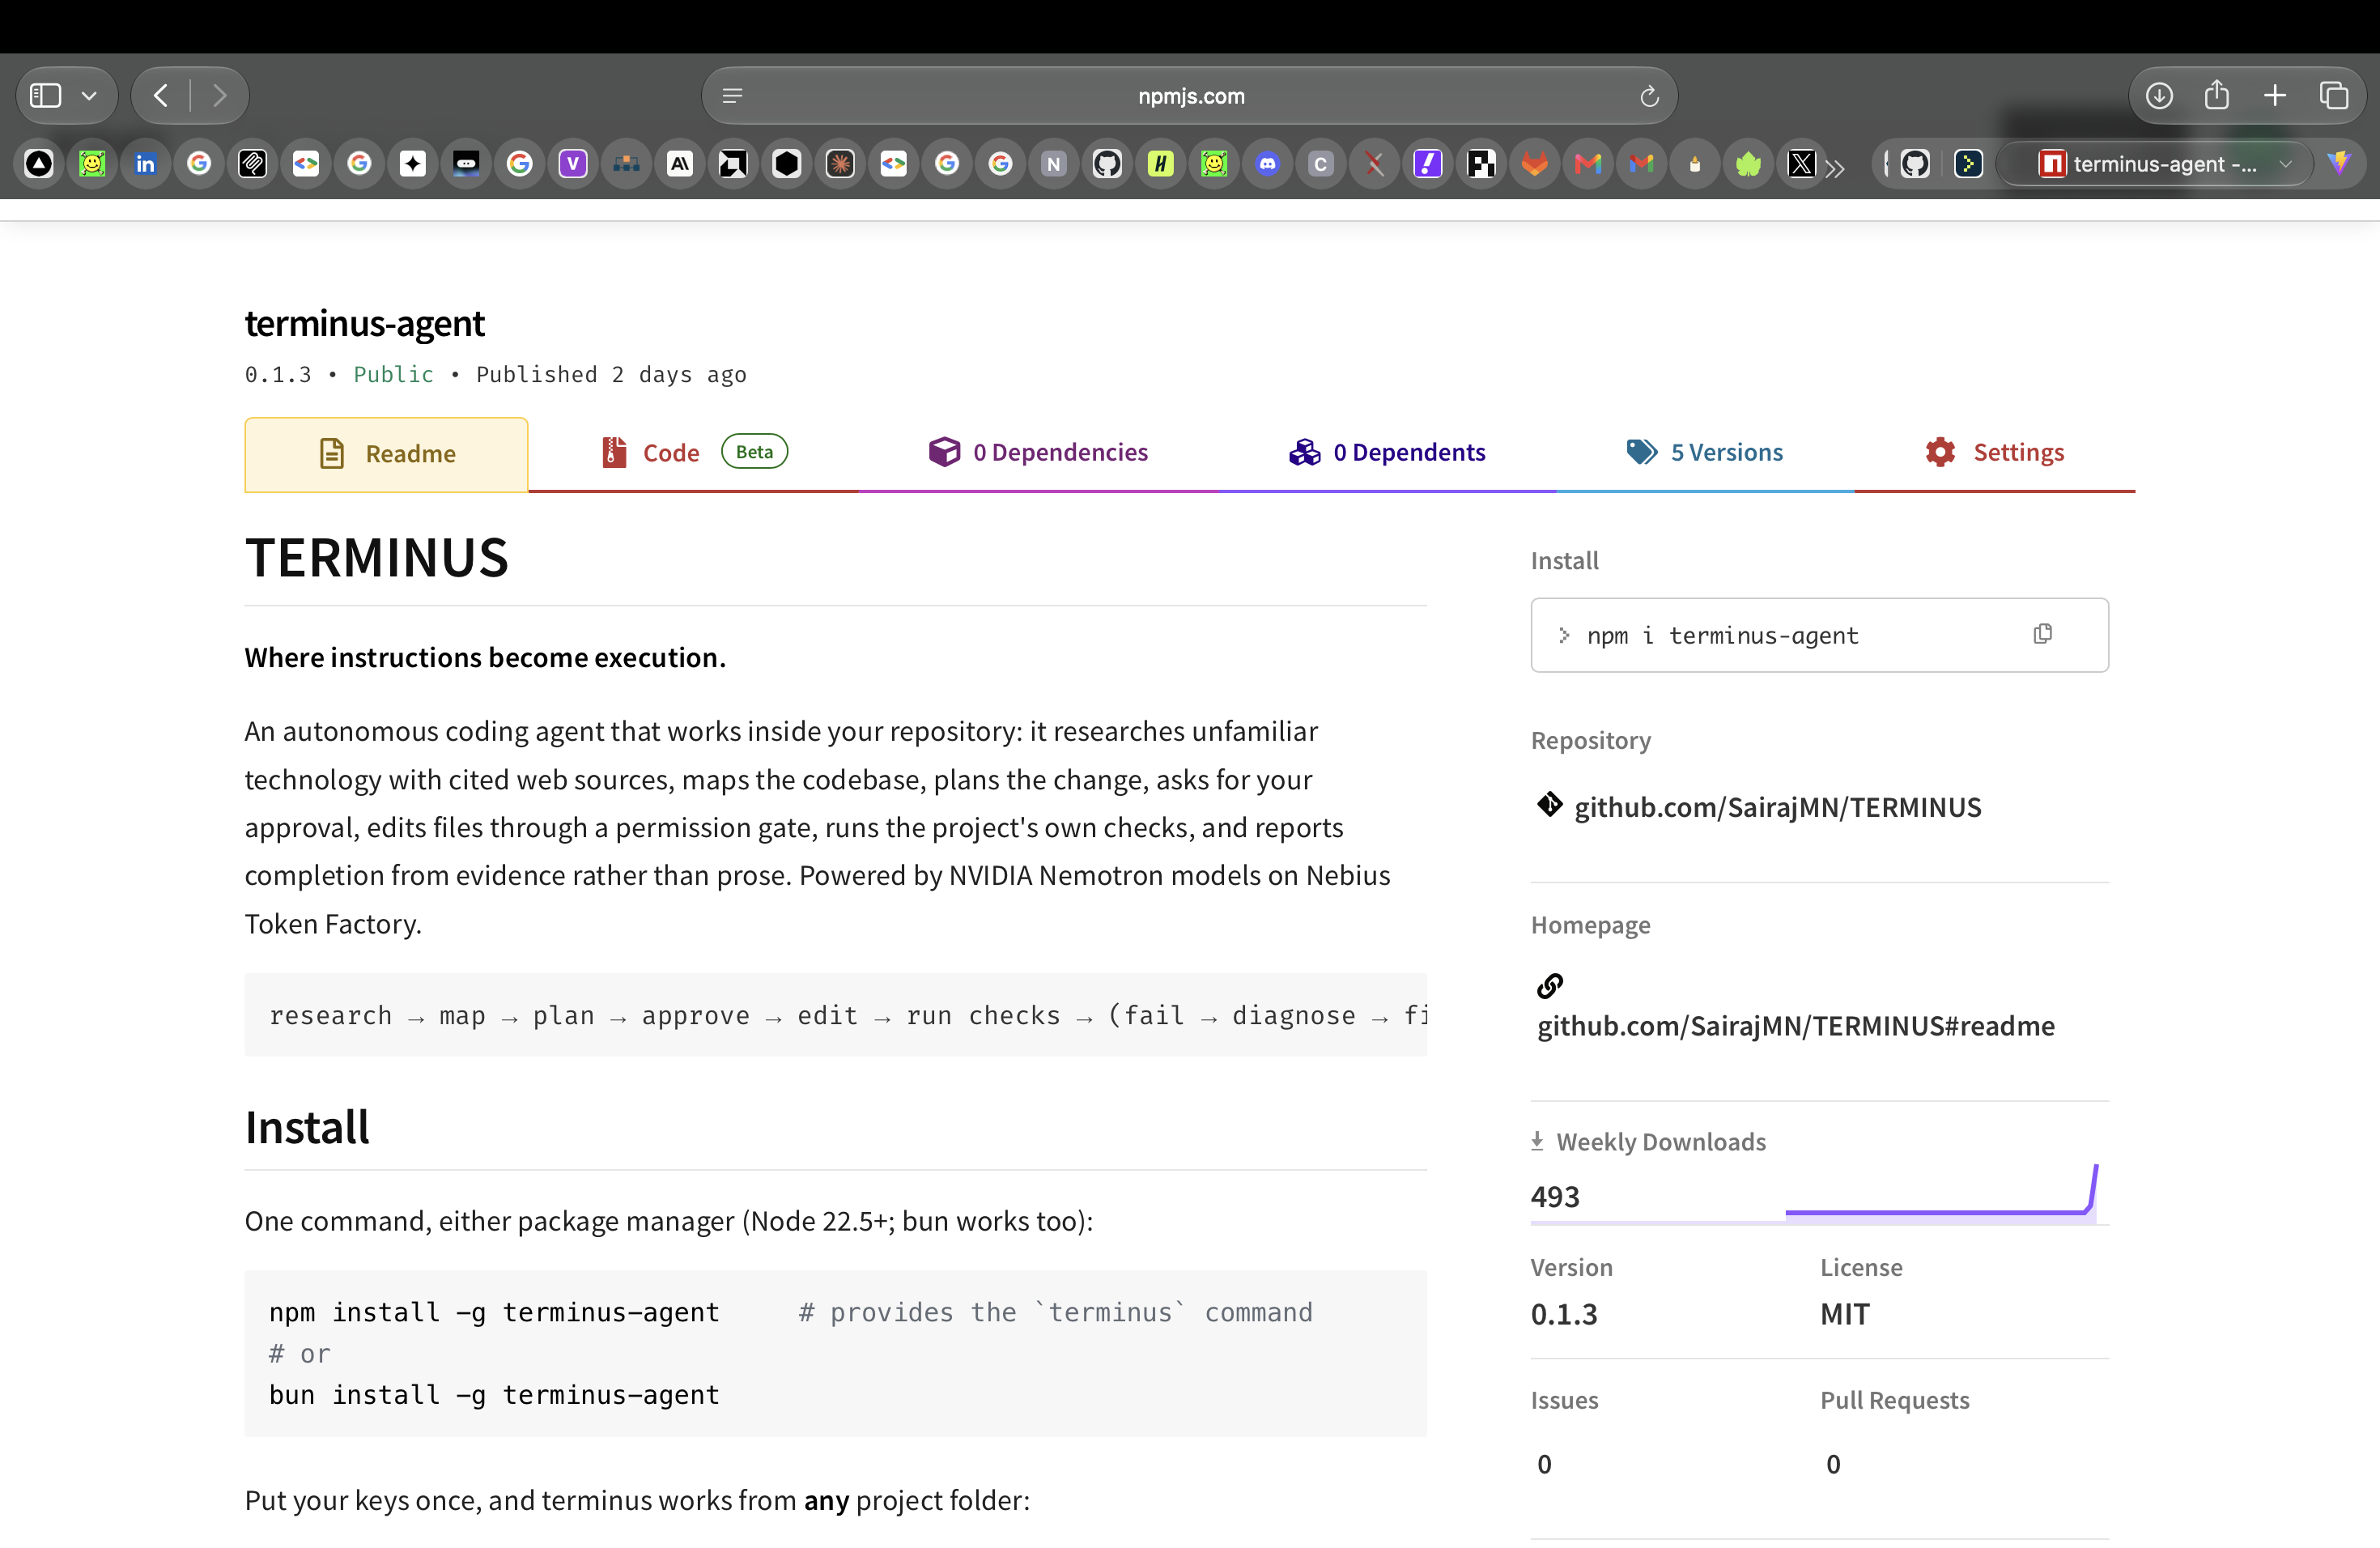
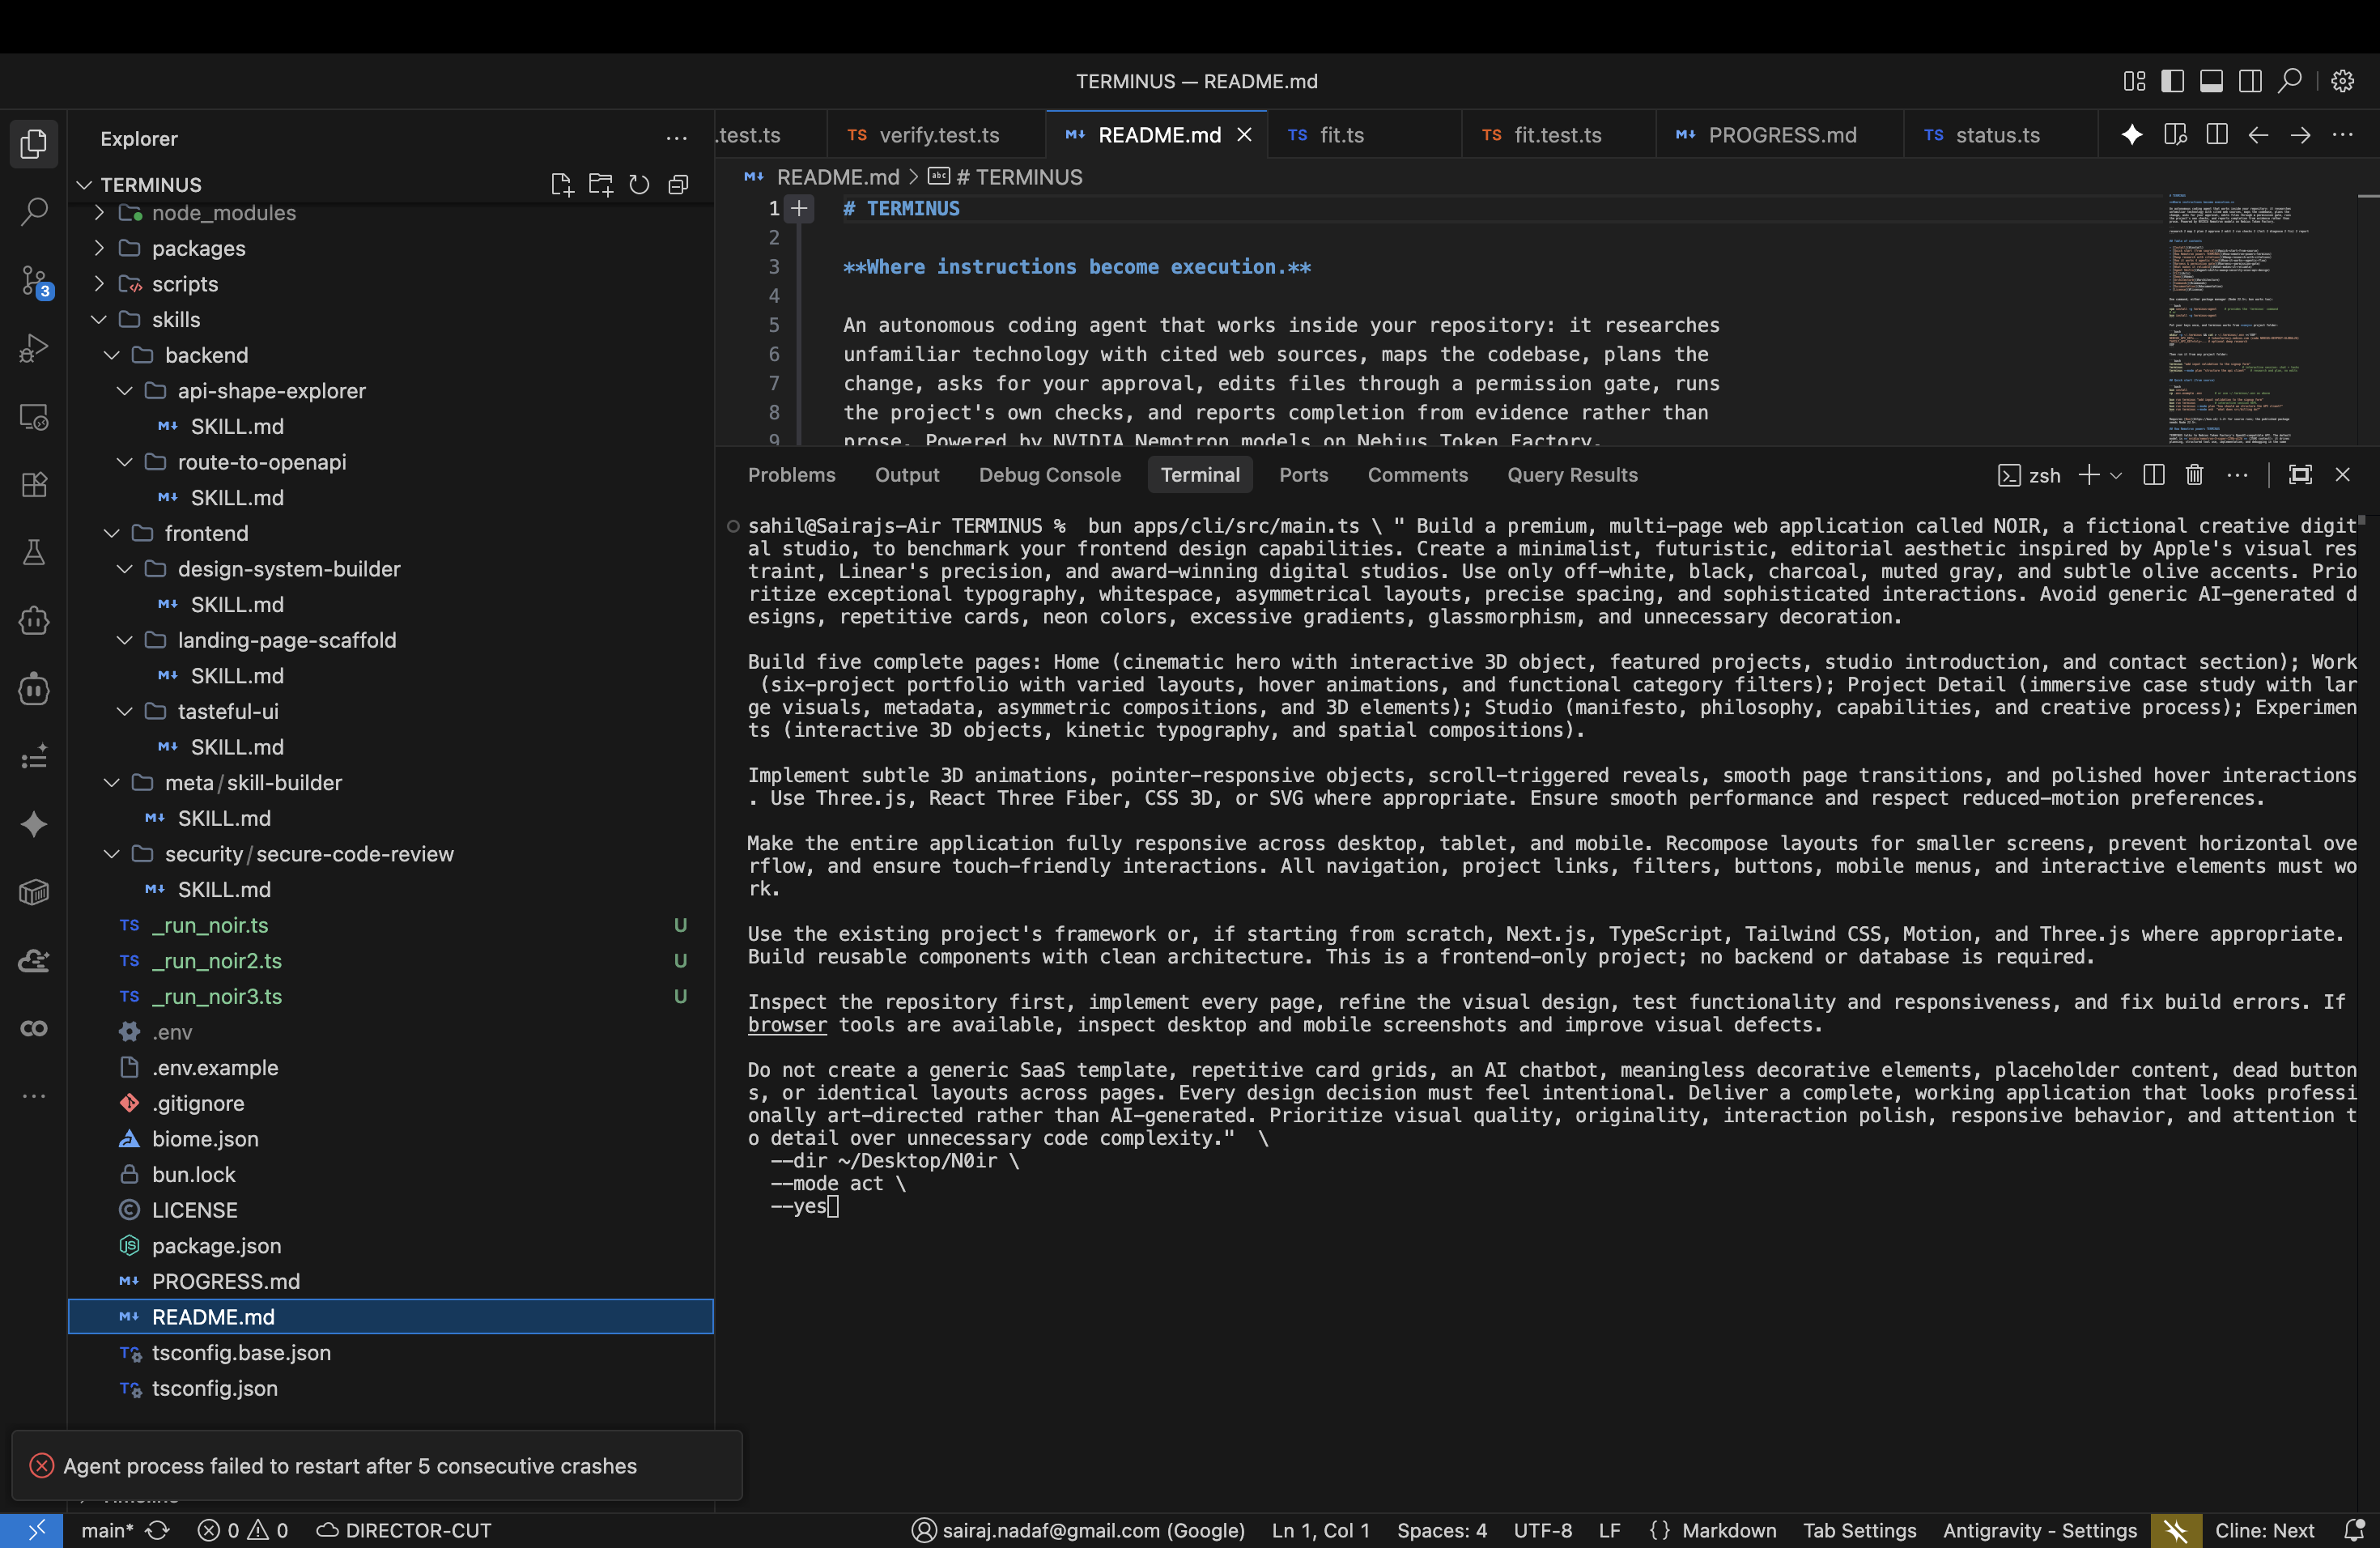
TERMINUS — Where instructions become execution.
TERMINUS is an autonomous coding agent that lives inside your repository. It doesn't just write code and hope — it researches unfamiliar technology with cited web sources, maps the codebase, plans the change, asks for your approval, edits files through a deterministic permission gate, runs the project's own checks, and reports completion from observed evidence rather than model prose.
Pipeline: research → map → plan → approve → edit → run checks → (fail → diagnose → fix) → report
Inspiration
Coding agents that "just edit" are hard to trust: they clobber files, skip tests, and declare victory in prose. We wanted an agent whose completion claim is proven by real check results, with every action passing a policy gate the model cannot override.
How we built it
- Monorepo (bun workspaces, TypeScript strict):
shared,model-gateway,tool-runtime,permission-engine,context-engine,session-store,agent-runtime,research,apps/cli. - Model gateway: OpenAI-compatible client to Nebius Token Factory, default
nvidia/nemotron-3-super-120b-a12b(256K context), streaming withtool_callsdelta assembly, token usage tracked end-to-end. Anthropic fallback via--provider anthropic. Single seamselectGateway. - Deep research: Tavily
web_researchtool stores results as untrusted, cited evidence ([title](url)); search results never reach the permission engine. - Context engine: repository map + evidence store (hashes, provenance, trust, freshness) + stale-write guard (re-hash before edit; never clobber externally changed files). Progressive exploration only — no whole-repo preload.
- Permission engine: deny-regex → allowlist → risk-tier → user approval, decided on the proposed action only. Session-based
[a]lways, never global; local overrides tighten-only. - Agent runtime: state machine
queued → investigating → planning → awaiting_approval → implementing → verifying → reviewing → completed, withimplementing → failed_check → diagnosing → retryingself-correction. - Tool runtime:
read_file,write_file,edit_file(exact-string replace),list_dir,search,run_command(bounded, timeout, cancellation, secret redaction),git_status,git_diff— all workspace-restricted, zod-validated. - Session store: local SQLite (
node:sqlite/bun:sqlite), append-only audit log,--resume/--sessions. - CLI: responsive dashboard (suit palette), state timeline, per-event tool feed with verdicts, usage lines, approval/report cards.
Challenges
- Getting Nemotron to emit reliable structured
tool_callson Token Factory (validated via spike). - Keeping research evidence untrusted so it can never authorize commands.
- Stale-write safety under concurrent external edits.
- Making completion a function of observed check results, not model prose.
What we learned
Model-independent harness (tools, permissions, context, verification) lets us swap models with a flag; the agent's reliability comes from the loop, not the model.
Built With
- agent
- anthropic-sdk
- biome
- bun
- cli
- context-engineering
- latex
- llm
- markdown
- mit
- nebius-token-factory
- node.js
- nvidia-nemotron
- open-source
- openai-sdk
- permission-gate
- sqlite
- tavily
- tool-use
- typescript
- zod

Log in or sign up for Devpost to join the conversation.