-
-
Legibol turns legacy COBOL into plain-English rules and Python, and proves they match.
-
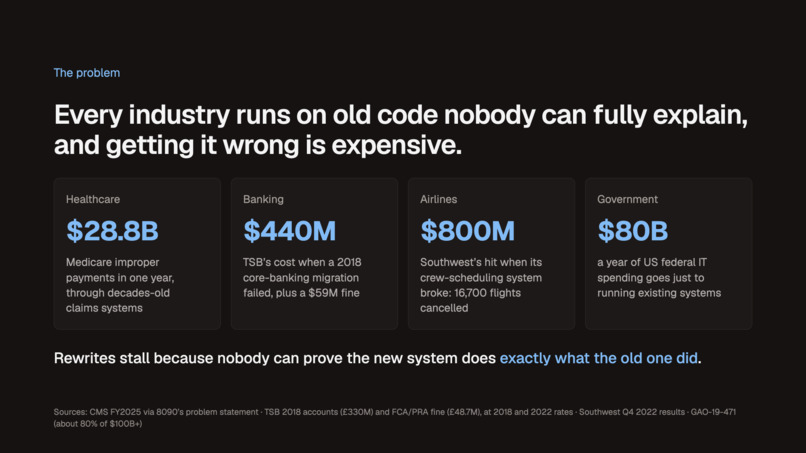
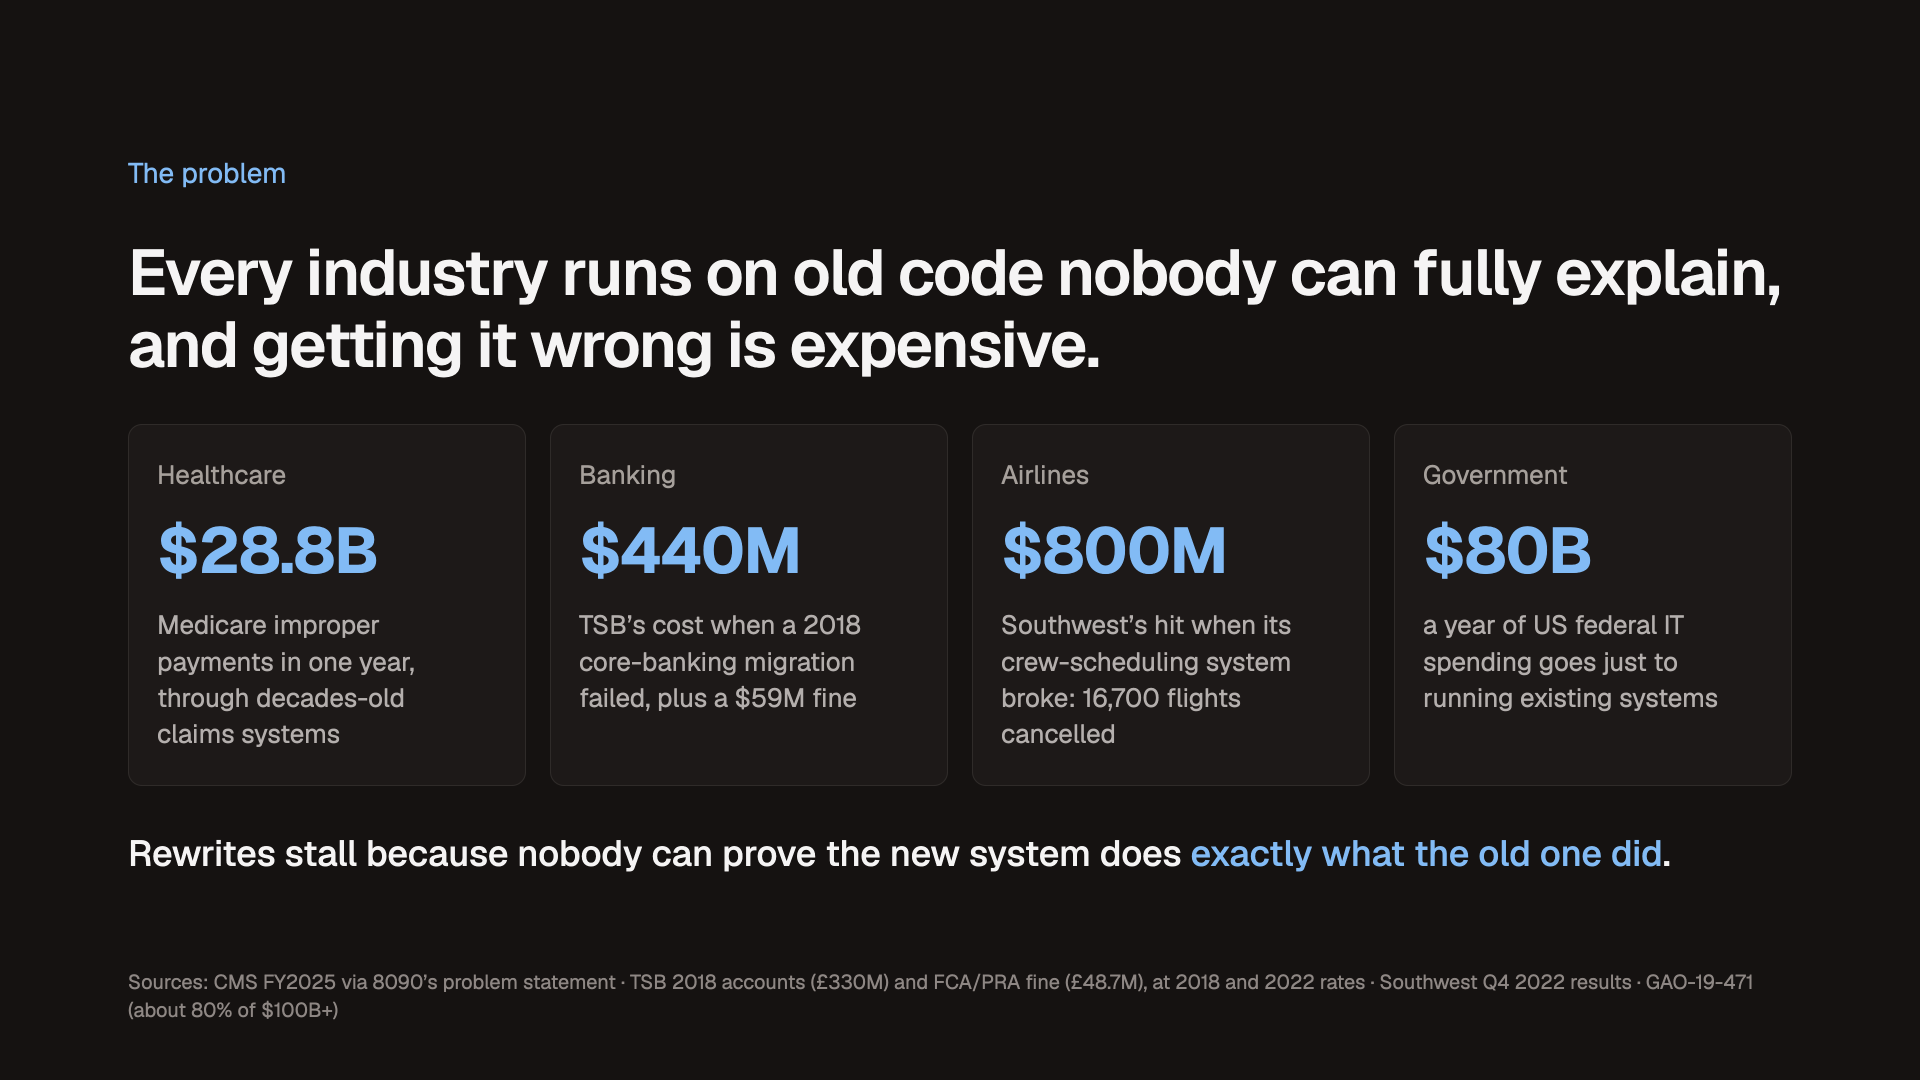
Old code runs every industry, and rewrites stall because nobody can prove they work the same.
-
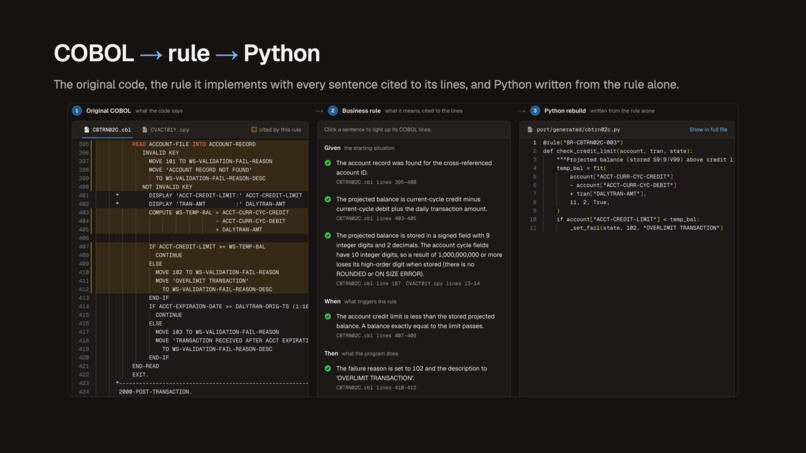
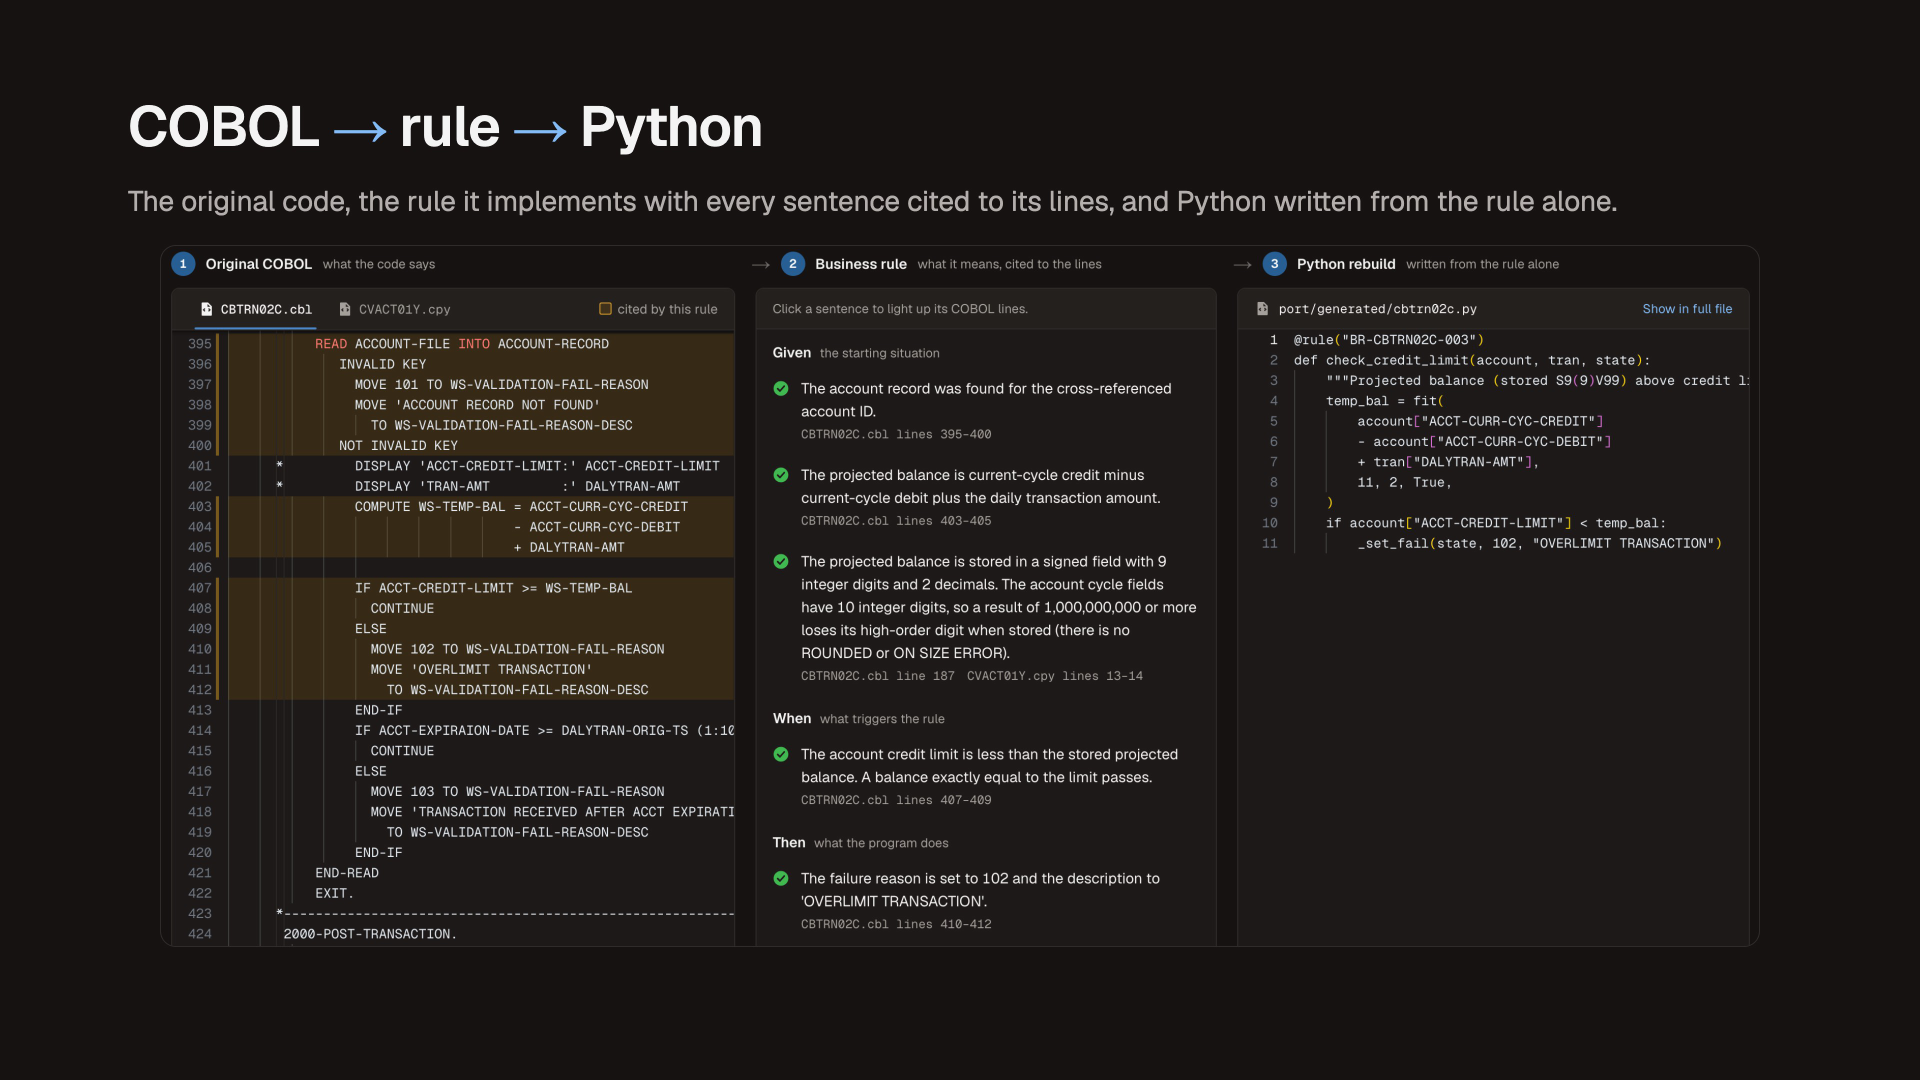
COBOL to rule to Python: every rule sentence is cited to its source lines, and the Python never sees the COBOL.
-
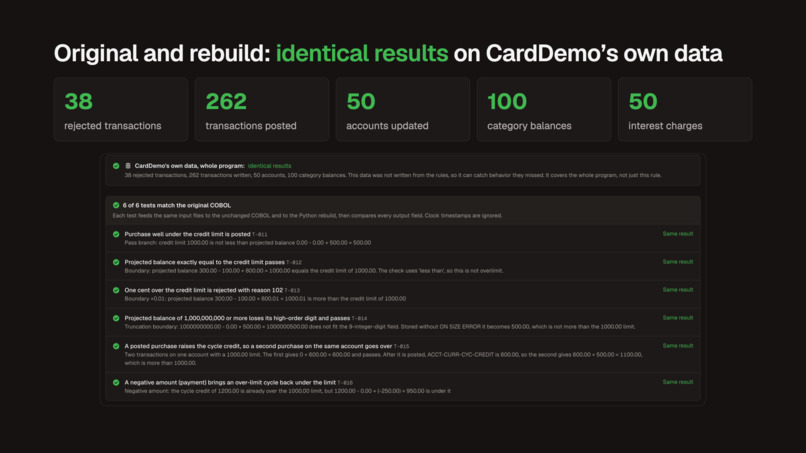
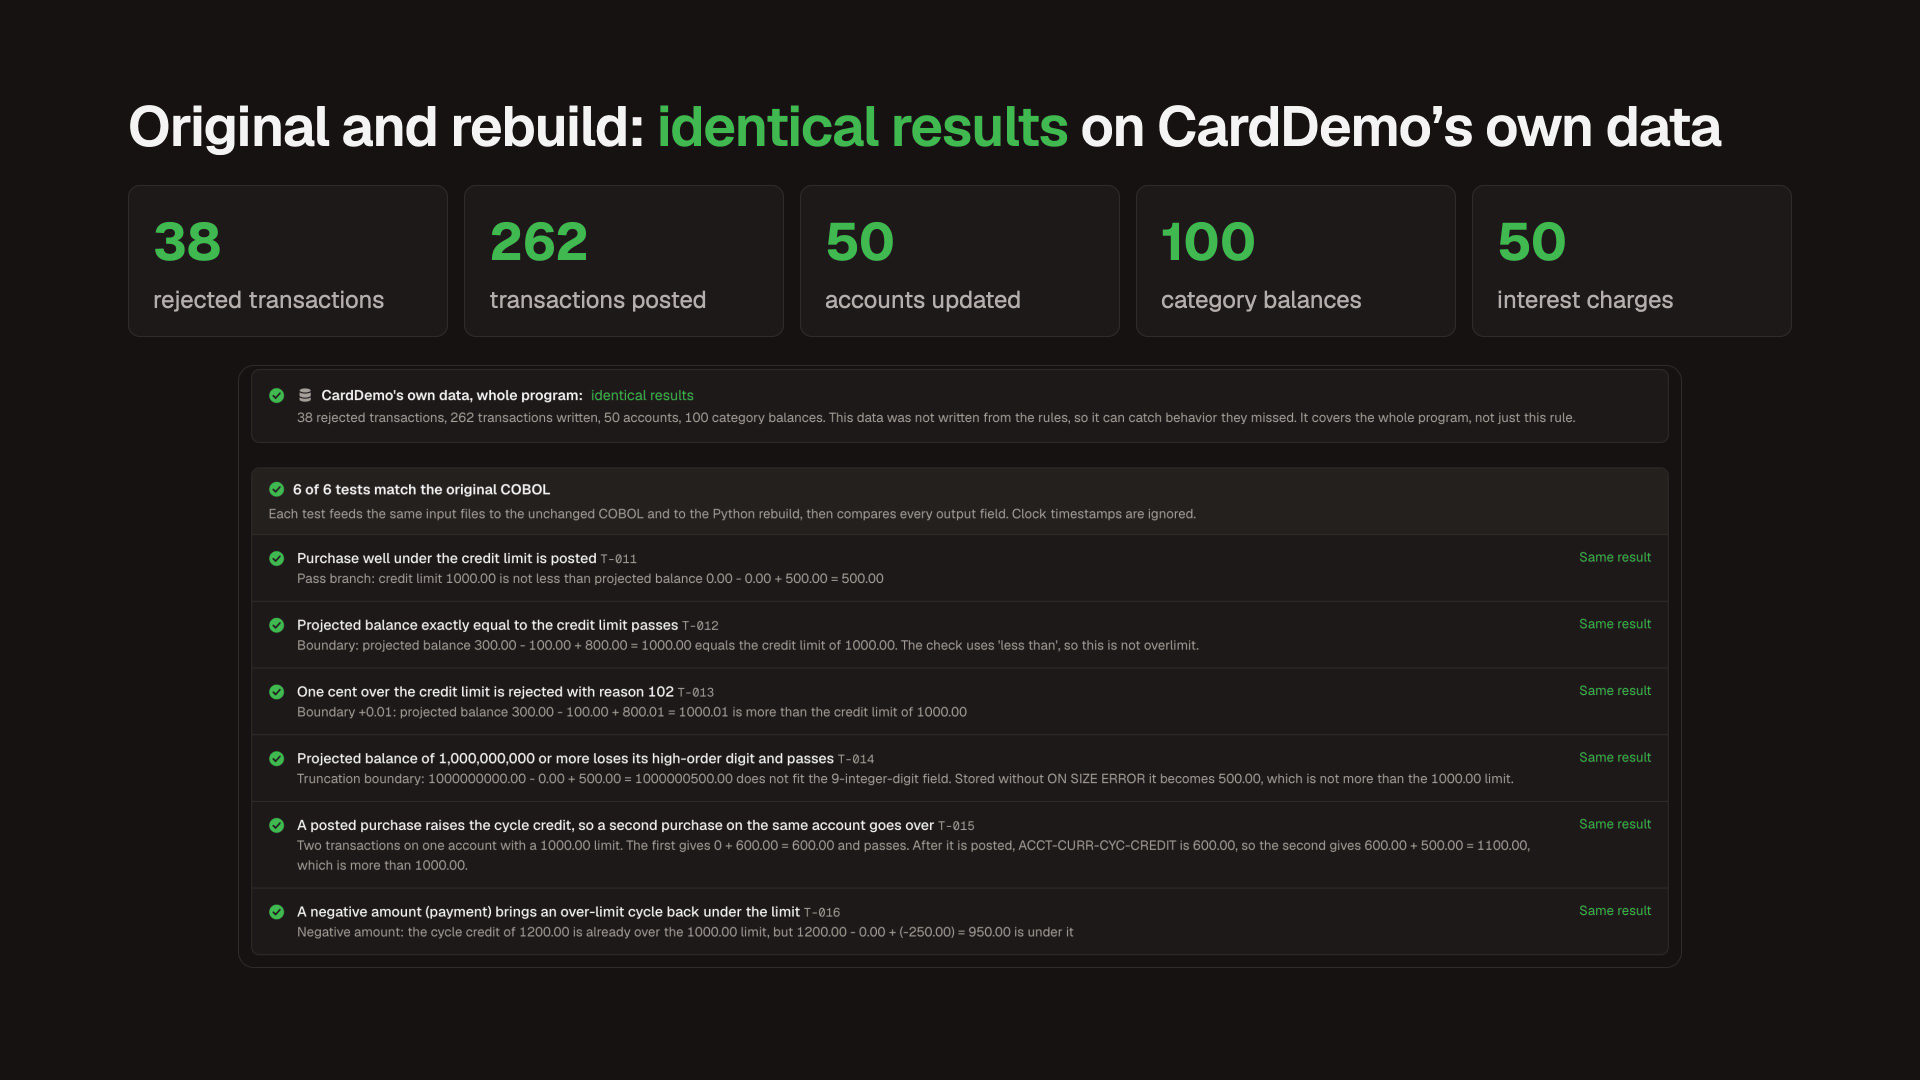
On 300 real transactions, the original COBOL and the Python rebuild matched field for field.
-
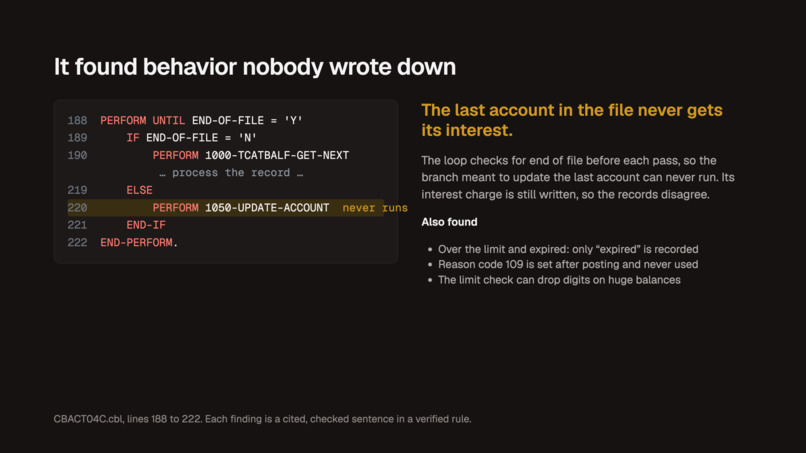
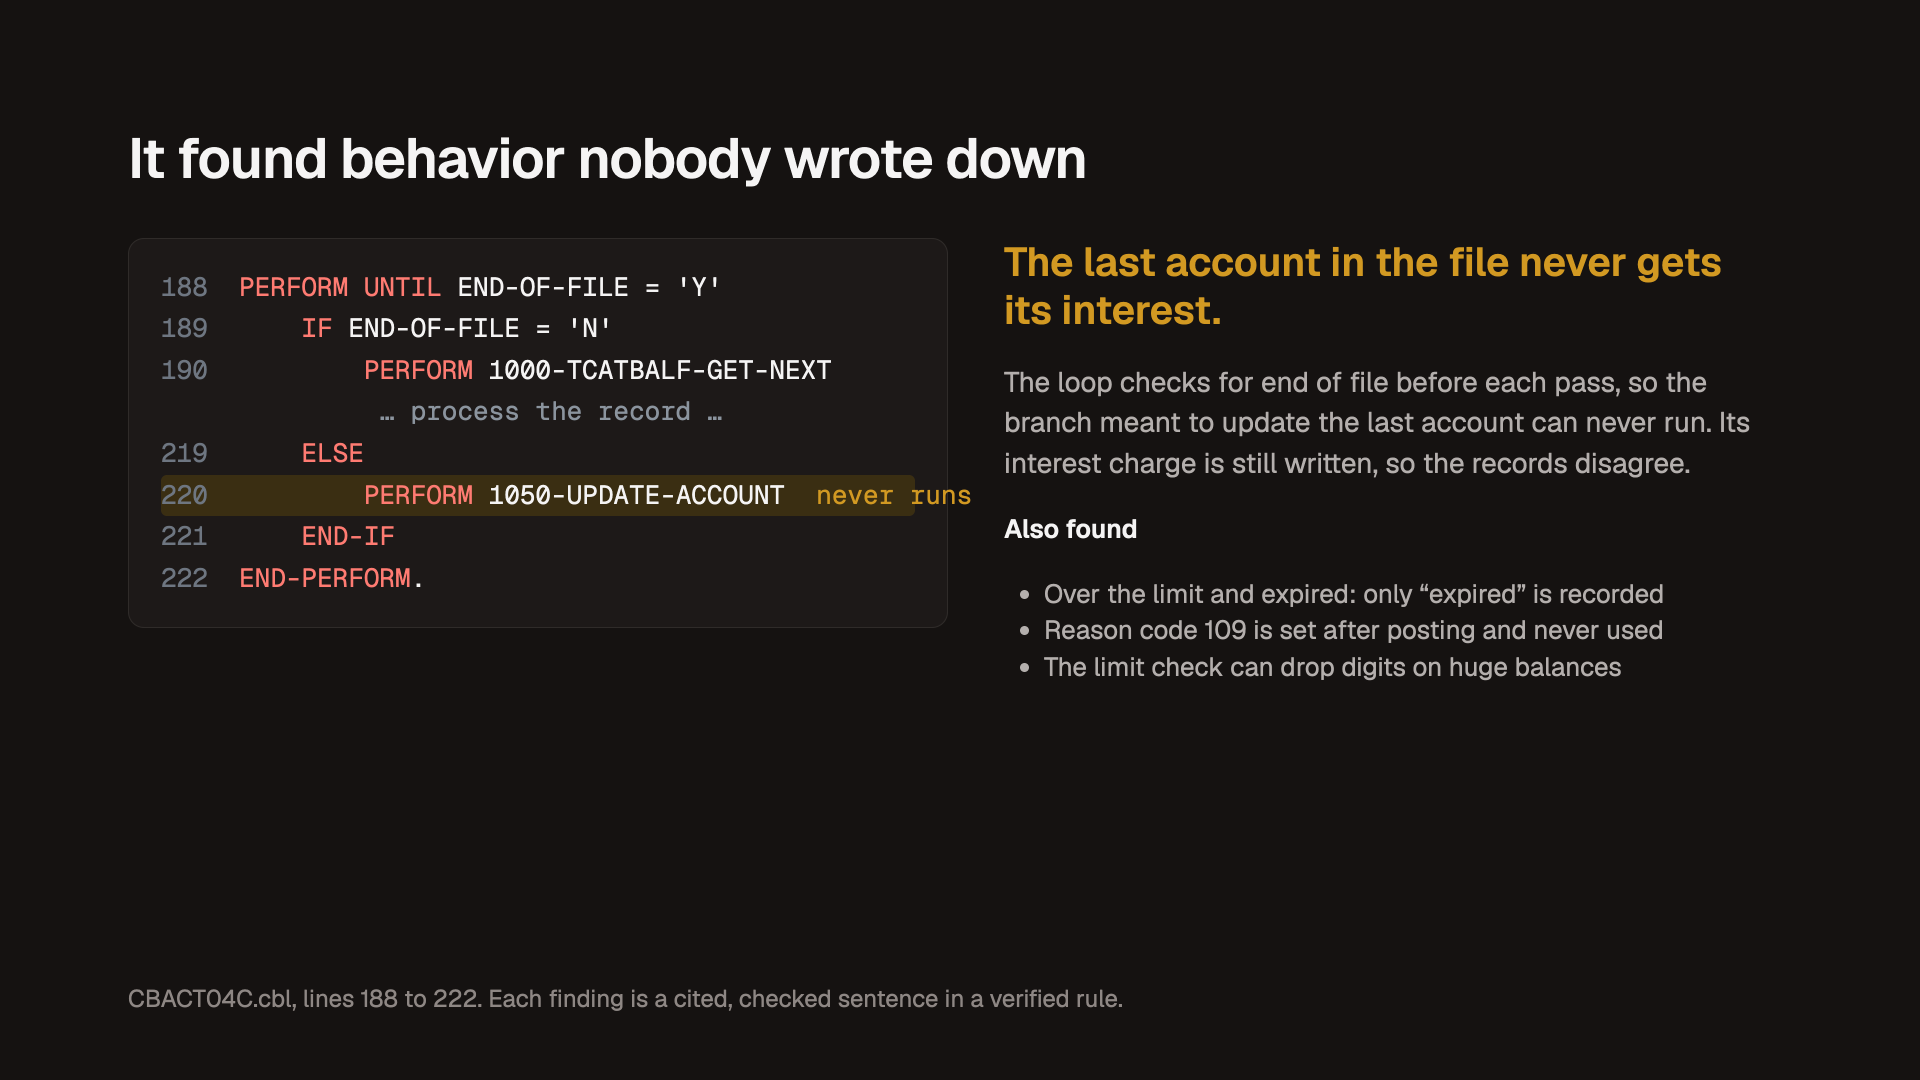
Legibol found undocumented bugs, like the last account never getting its interest.
-
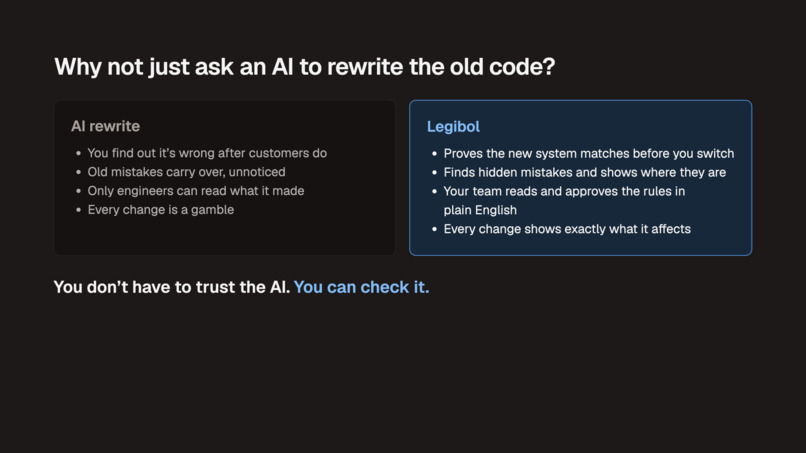
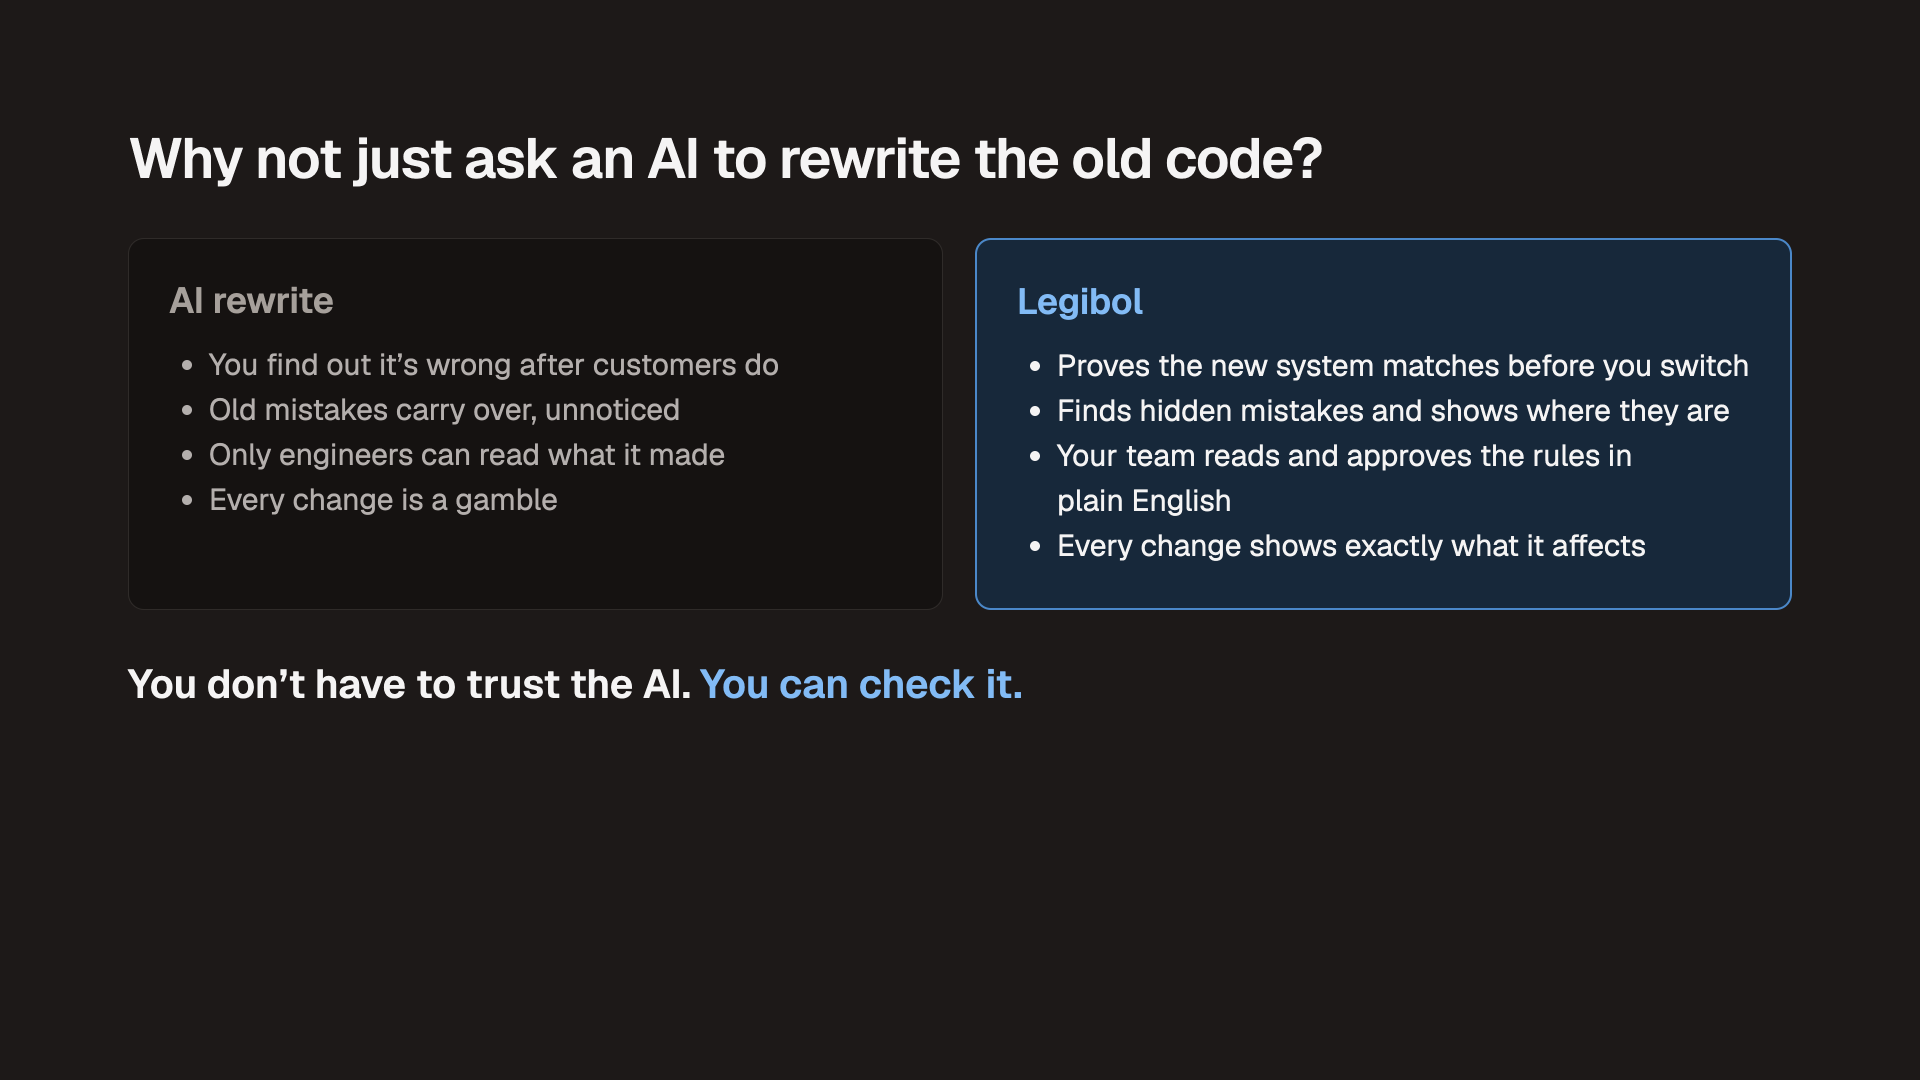
An AI rewrite asks you to trust it. Legibol lets you check it.
-
Nothing unsourced. Nothing unverified.
Inspiration
8090's work extracting business rules from Medicare's claims systems (18M+ lines of COBOL and Assembly, 100,000+ rules) showed that plain-English rules traced to source can make legacy code reviewable. Their public story covers extraction; the rewrite is another contractor's job. We wanted to see if one tool could do both: extract the rules, rebuild the program from them, and prove the rebuild behaves exactly like the original. That fit the track's goal of speeding up legacy modernization.
What it does
Legibol (legible COBOL) turns legacy COBOL into a plain-English ruleset, then rebuilds the program in Python from those rules alone.
- Every Given/When/Then sentence cites its exact COBOL lines, checked by plain code and an AI judge.
- The Python is written by an AI that never sees the COBOL, so it can only match the original if the rules are complete.
- The unchanged COBOL and the Python run on the same inputs, and every output field is compared.
- A person can fix a legacy bug on purpose, see exactly what changes, and sign off.
AI drafts. Plain code, the running COBOL and a person do all the checking.
How we built it
Claude (claude-opus-5-5) powers four agents: extractor, citation judge, modernizer and test generator. A deterministic parser maps every field to its exact byte position. The original COBOL runs unchanged under GnuCOBOL in Docker. Every AI call is cached, so the pipeline replays with 0 API calls. Review app: FastAPI + Next.js. Tested on two AWS CardDemo batch programs.
Challenges we ran into
Running mainframe COBOL on a laptop: without the right sign setting, refunds read as purchases. Our first version verified only 2 of 12 rules because each sentence could cite only one place.
Accomplishments that we're proud of
- 12/12 rules verified, 58/58 tests match the COBOL
- Identical results on 300 real transactions
- A second run from scratch reproduced everything
- Found real legacy bugs on its own, like the last account never getting its interest
What we learned
Let AI draft, never let it grade. Its wording changes between runs, but its behavior doesn't. Limits: verified isn't proof. 184 error-handling statements went untested, and both runs missed one finding.
What's next for Legibol
- Rebuild into other target languages, not just Python
- More programs, and matching the same rule across programs and systems
Built With
- claude
- claude-code
- cobol
- gnucobol
- next.js
- python
