-
-
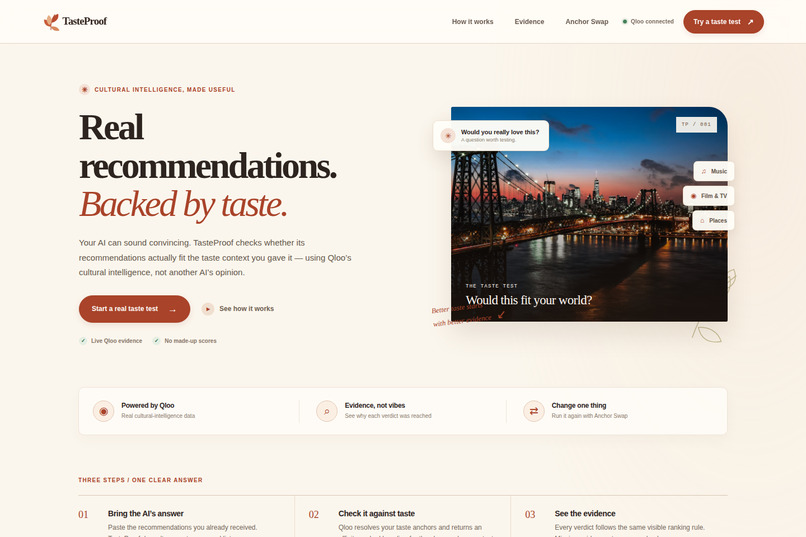
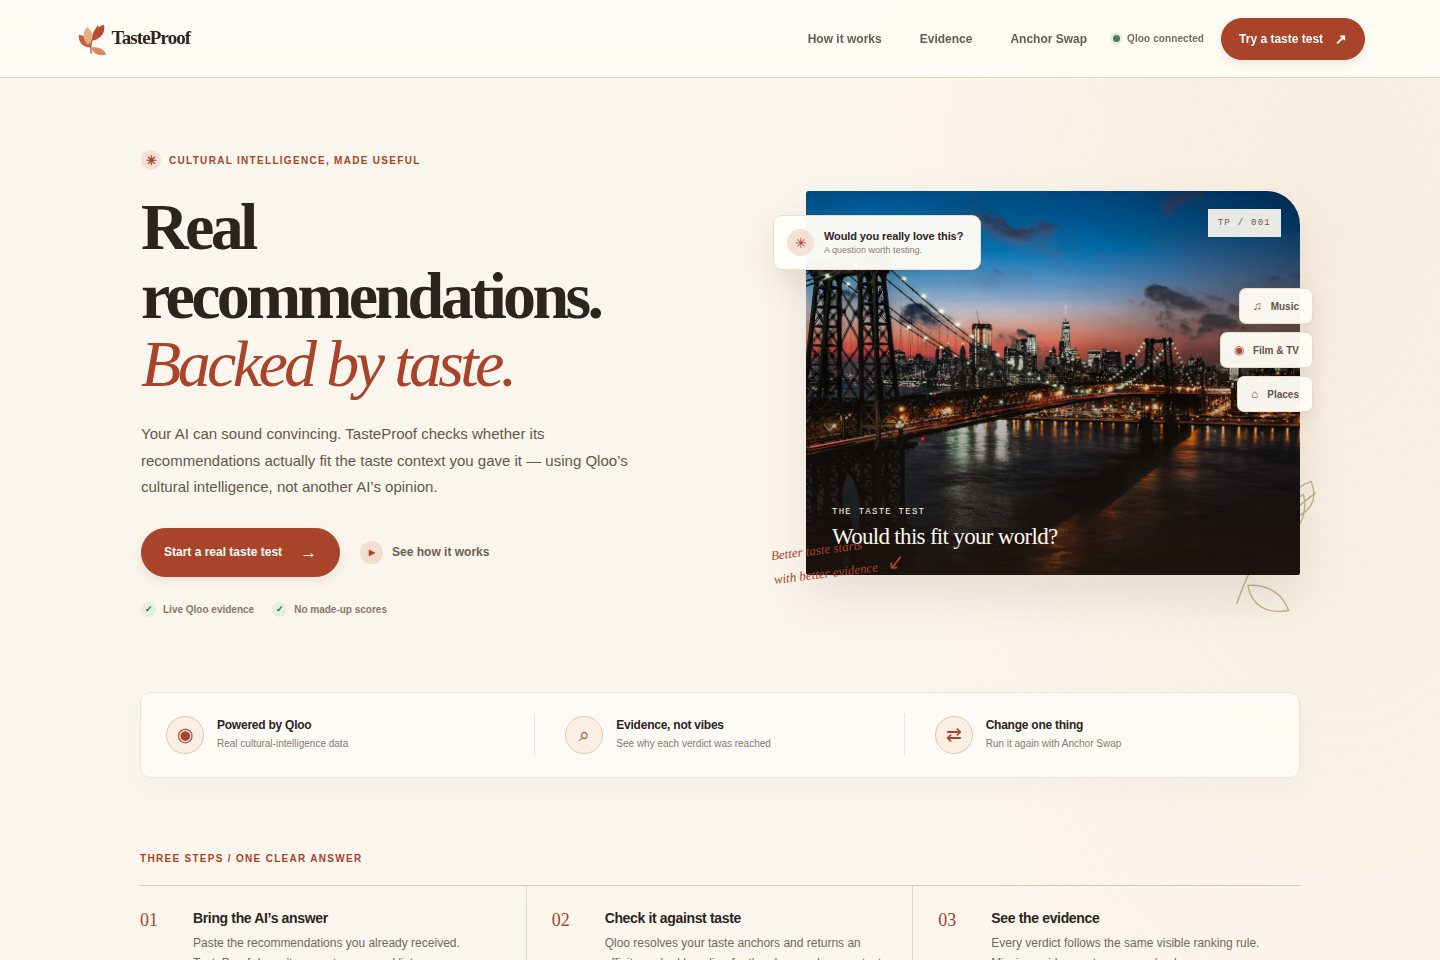
TasteProof tests AI-generated place recommendations against your taste context using Qloo evidence, not guesswork.
Inspiration
AI agents can generate impressive recommendations, but a convincing answer is not necessarily a good answer. An agent might recommend places that sound relevant without adequately matching the user's interests, cultural preferences, or requested context.
We wanted to address a simple question: How can we test whether an AI agent's recommendations actually align with the taste context it was given?
That question inspired TasteProof, a taste quality-assurance layer for AI agents, powered by Qloo's cultural intelligence. Instead of generating yet another list of recommendations, TasteProof evaluates recommendations produced by an external agent and presents evidence that people can inspect.
What it does
TasteProof lets a user provide taste anchors, such as an artist, brand, or film, specify a location, and submit place recommendations generated by an AI agent.
It then uses Qloo to resolve the relevant entities and obtain ranking evidence for the submitted candidates. TasteProof applies a transparent, deterministic rule to classify ranked candidates as PASS, REVIEW, or FAIL. When there is insufficient evidence, it reports UNRESOLVED rather than inventing a result.
Its signature feature is Anchor Swap. Users can change one taste anchor, rerun the evaluation, and compare the actual results. This makes it possible to inspect how recommendations rank under a different taste context instead of simply accepting an agent's output at face value.
How we built it
TasteProof is built with Next.js, React, and TypeScript, with Qloo providing the cultural-intelligence data.
The application combines entity search and selection, Qloo Insights, candidate evaluation, and an evidence-focused results interface. Its API also exposes an agent-callable evaluation endpoint, allowing another agent or application to submit recommendations for testing.
We designed the interface around a warm, editorial Test Lab aesthetic. Rather than presenting a generic analytics dashboard, TasteProof emphasizes the inputs, candidate leaderboard, verdicts, and inspectable evidence so users can understand what was evaluated and why.
We also implemented automated checks through GitHub Actions, including type checking, unit tests, production builds, live verification, and browser-based UI checks.
Challenges we faced
One of the hardest parts was making candidate evaluation evidence-based. Resolving a place name to a Qloo entity is not the same as proving that the entity was ranked, and appearing in a broad discovery list is not the same as receiving a candidate-specific result.
We worked through candidate-ranking and entity-resolution issues, improved the separation between evaluation results and contextual discovery results, and tested the application against live Qloo responses. We also had to make the verdicts meaningful without manufacturing affinity percentages or treating missing evidence as a negative result.
Another important challenge was validating Anchor Swap honestly. A changed input should not automatically imply a changed outcome. The comparison must reflect what the evaluation actually returned.
What we learned
We learned that AI quality assurance needs more than another AI-generated explanation. It needs clear inputs, evidence from an external source, repeatable evaluation rules, and an explicit way to represent uncertainty.
We also learned that a useful evaluation tool must distinguish between what it knows and what it cannot establish. A missing rank should remain unresolved, not be presented as proof that a recommendation is bad.
What is next
We see TasteProof as a foundation for testing recommendation quality across AI agents and applications. As agents increasingly make personalized suggestions, developers need ways to inspect whether those suggestions align with the context they were given.
TasteProof's principle is simple: don't just trust the recommendation. Test it against evidence.
Built With
- github-actions
- next.js
- node.js
- openapi
- qloo-api
- react
- rest-api
- typescript
- vercel
