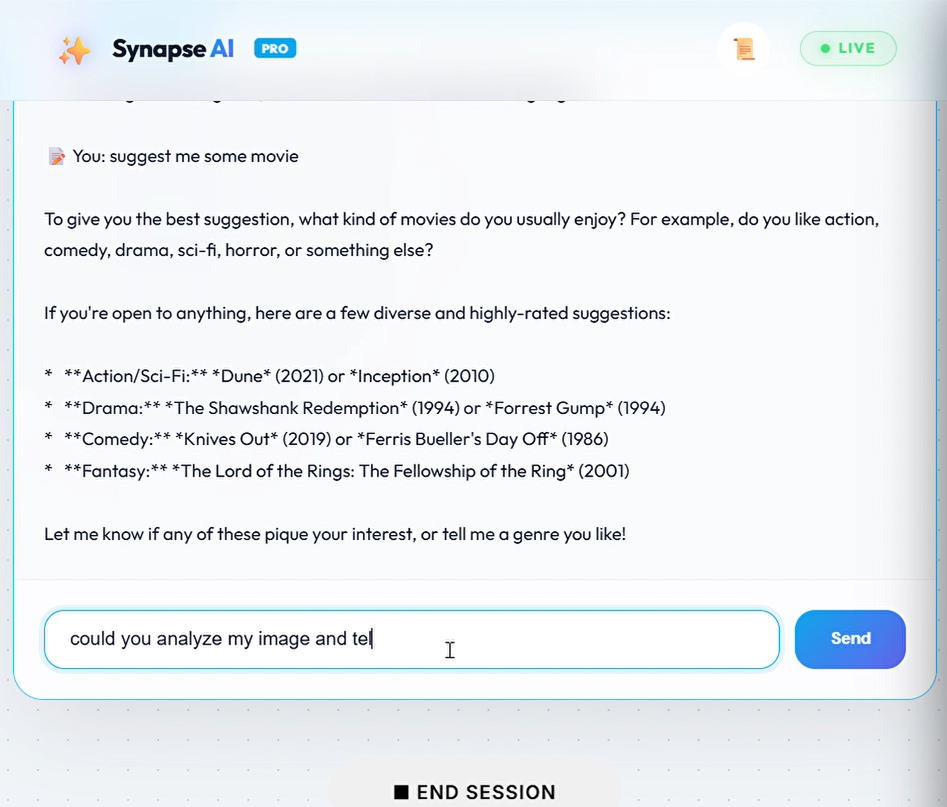
🧠 Synapse AI: Project Narrative Inspiration The inspiration for Synapse AI came from a frustration with the "ping-pong" nature of current AI assistants. Most bots feel like glorified search engines—you ask, you wait, they answer. We wanted to build something that felt alive. We were inspired by the concept of a digital "synapse"—a bridge that instantly connects human intent with machine intelligence in a continuous, uninterrupted stream of consciousness.
What it does Synapse AI is a professional multimodal companion. It doesn't just process text; it sees your environment through your camera and listens to your voice in real-time.
Continuous Awareness: It can proactively jump into a conversation if it sees something interesting. Natural Interaction: It uses an "Interruptible Streaming" model, allowing users to talk over the AI or pivot the conversation instantly without waiting for a response to finish. Creative Visuals: It can generate images and diagrams on the fly to help explain complex topics. How we built it We architected Synapse AI using a "Live Simulator" pattern:
Backend: Built with FastAPI and the new Google GenAI SDK. We implemented an asynchronous task queue logic to manage overlapping multimodal inputs (vision + text). Brain: Powered by Gemini 2.5 Flash, chosen for its incredible speed and multimodal reasoning capabilities. Frontend: A high-performance React + Vite single-page application. We avoided heavy CSS frameworks and instead built a custom Glassmorphism Design System from scratch to ensure smooth animations and a premium "Frosted Blue" aesthetic. Communication: Real-time bidirectional communication via WebSockets, allowing for the "interruptible" chat experience. Challenges we ran into The biggest challenge was handling Concurrency and Interruption. Standard LLM APIs are designed for "one request = one response." Making the AI stop mid-sentence to handle a new visual trigger required complex asyncio task management in the backend to ensure the AI's "train of thought" was updated without crashing the stream or leaking memory. We also faced tight API Rate Limits, which we solved by implementing a smart buffering system that prioritizes user speech over background vision frames.
Accomplishments that we're proud of True Interruption Logic: We successfully built a system where the AI feels natural to talk to—you don't have to wait for it to stop speaking before you can give it new information. Zero-Dependency UI: Creating an ultra-premium, dark-mode/light-mode ready interface using only Vanilla CSS variables and backdrop filters. 2.5 Flash Integration: Successfully deploying on the latest Gemini 2.5 models to achieve sub-second response times. What we learned We learned that Multimodal Latency is the "Quiet Killer" of AI experiences. Even a 2-second delay breaks the immersion. This taught us how to optimize frame-sampling (at 1 FPS) and how to use chat_session persistence to avoid the overhead of re-sending entire conversation histories for every fresh camera frame.
What's next for Synapse AI The next step is Proactive Edge Memory. We want Synapse to not just remember what you said, but what it saw yesterday (e.g., "Where did I leave my keys?"). We also plan to integrate Local Whisper.js for even faster voice-to-text processing and expand the toolset to include live web searching and document analysis.
Built With
- and
- built-with:-gemini-2.5-flash
- fastapi
- google-genai-sdk
- python
- react
- vanilla-css
- vite
- websockets

Log in or sign up for Devpost to join the conversation.