-
-
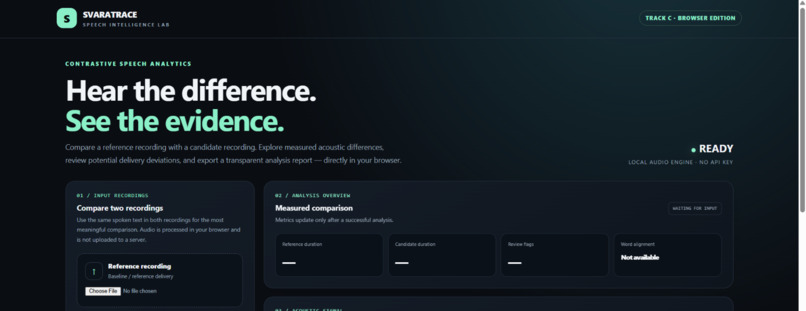
landpage
-
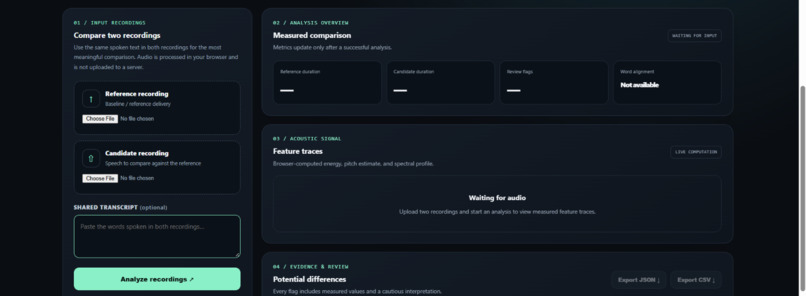
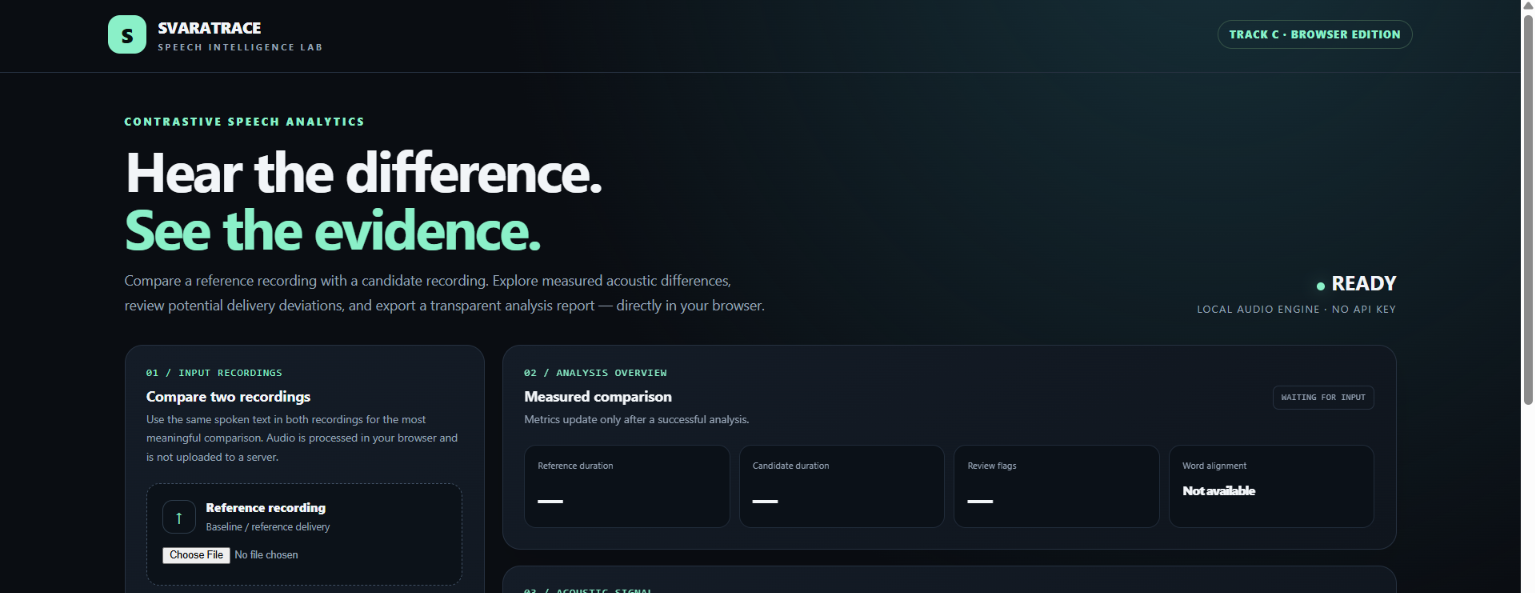
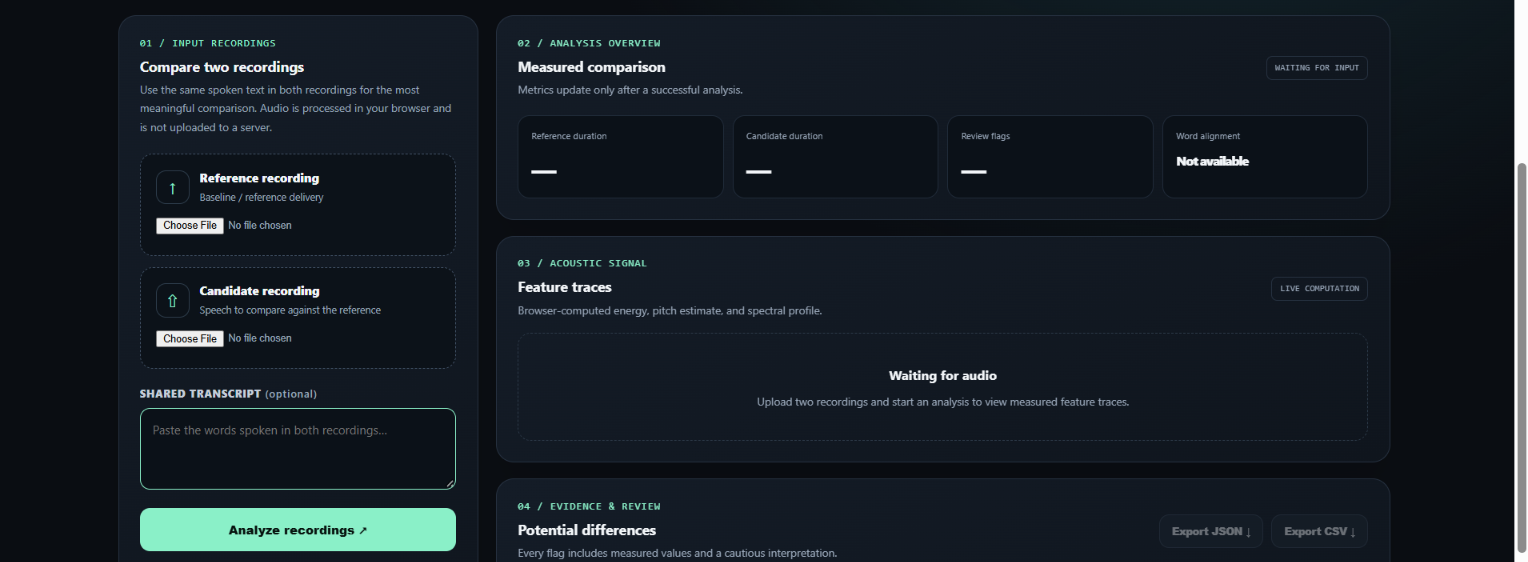
SvaraTrace — Contrastive Speech Analytics & Temporal Flaw Grounding
💡 Inspiration
Speech feedback often tells people to “speak more clearly” or “improve your pacing,” but it rarely explains exactly where a problem occurred or provides measurable evidence to support that feedback.
We wanted to explore a better approach: comparing a reference speech recording with a candidate recording and using audio signal analysis to identify meaningful differences. Instead of providing only a general score, our goal is to make speech analysis more transparent, evidence-based, and actionable.
🚀 What is SvaraTrace?
SvaraTrace is a speech analytics project focused on contrastive speech analysis and temporal flaw grounding.
The system compares reference and candidate audio recordings, extracts acoustic features, visualizes their differences, and generates evidence-based suggestions for reviewing speech delivery.
Our approach focuses on connecting speech feedback with measurable audio characteristics rather than relying entirely on subjective judgments.
✨ Key Features
- Reference vs. Candidate Comparison: Compare two speech recordings to identify differences in their acoustic characteristics.
- Audio Signal Analysis: Extract features such as RMS energy, estimated pitch, spectral centroid, spectral flatness, pause/activity patterns, and MFCC summaries when supported by the installed dependencies.
- Visual Analytics: Display reference and candidate feature traces to make acoustic differences easier to inspect.
- Evidence-Based Feedback: Generate transparent, rule-based suggestions from measured feature differences.
- Audio Upload and Validation: Accept supported audio formats and validate uploaded recordings before processing.
- Report Export: Export analysis results as JSON for further inspection and reproducibility.
- Interactive Web Interface: Access the analysis through a browser-based dashboard connected to a Python backend.
🛠️ How We Built It
We developed SvaraTrace using Python and FastAPI for the backend, with NumPy, SciPy, SoundFile, and Librosa for audio processing and feature extraction where available. The browser interface uses HTML, CSS, and JavaScript to present analysis results and visualizations.
The processing pipeline validates the recordings, extracts acoustic features, compares the reference and candidate measurements, and produces structured findings with corresponding evidence and suggestions.
We began with a transparent baseline so that the reasoning behind each flag is understandable and testable rather than presenting an unexplained score.
🧩 Challenges We Faced
Speech analysis is difficult because two recordings can differ for many reasons, including speaking style, microphone characteristics, background noise, and recording conditions.
A measurable acoustic difference does not automatically indicate a genuine speaking flaw. This makes careful interpretation, normalization, uncertainty handling, and meaningful evaluation essential.
Another major challenge is temporal precision. Identifying a difference across an entire recording is not the same as locating the exact word or interval where it occurred. Integrating reliable forced alignment and validating timestamp-level detections are important remaining development tasks.
📚 What We Learned
Developing SvaraTrace has helped us explore audio signal processing, acoustic feature extraction, API integration, interactive data visualization, software testing, and explainable analysis.
We also learned the importance of distinguishing measured evidence from assumptions and evaluating a system using labelled data rather than relying on impressive-looking charts or unsupported accuracy claims.
🔬 Current Status and Future Work
The current prototype supports whole-recording acoustic comparison, feature visualization, evidence-based review suggestions, and JSON export.
Our next priorities are integrating a genuine forced-alignment engine, implementing time-window-level flaw localization, building a reproducible labelled dataset, and evaluating temporal detection using precision, recall, F1 score, timestamp error, and interval overlap.
Our long-term goal is to make speech feedback more precise and understandable by connecting every detected difference to its acoustic evidence and, where alignment is reliable, its corresponding transcript segment.
🤖 Responsible AI Development
AI coding assistance was used during initial scaffolding and documentation. Generated code and outputs must be reviewed and tested, and all implementation claims must reflect verified functionality. Any additional AI tools used by the team will be disclosed in the project documentation.
SvaraTrace is a speech-analysis prototype, not a validated clinical or diagnostic system.
Built With
- api
- audio
- css3
- data
- fastapi
- github
- html5
- javascript
- librosa
- numpy
- processing
- pytest
- python
- rest
- scipy
- signal
- soundfile
- visualization

Log in or sign up for Devpost to join the conversation.