Inspiration
Problem
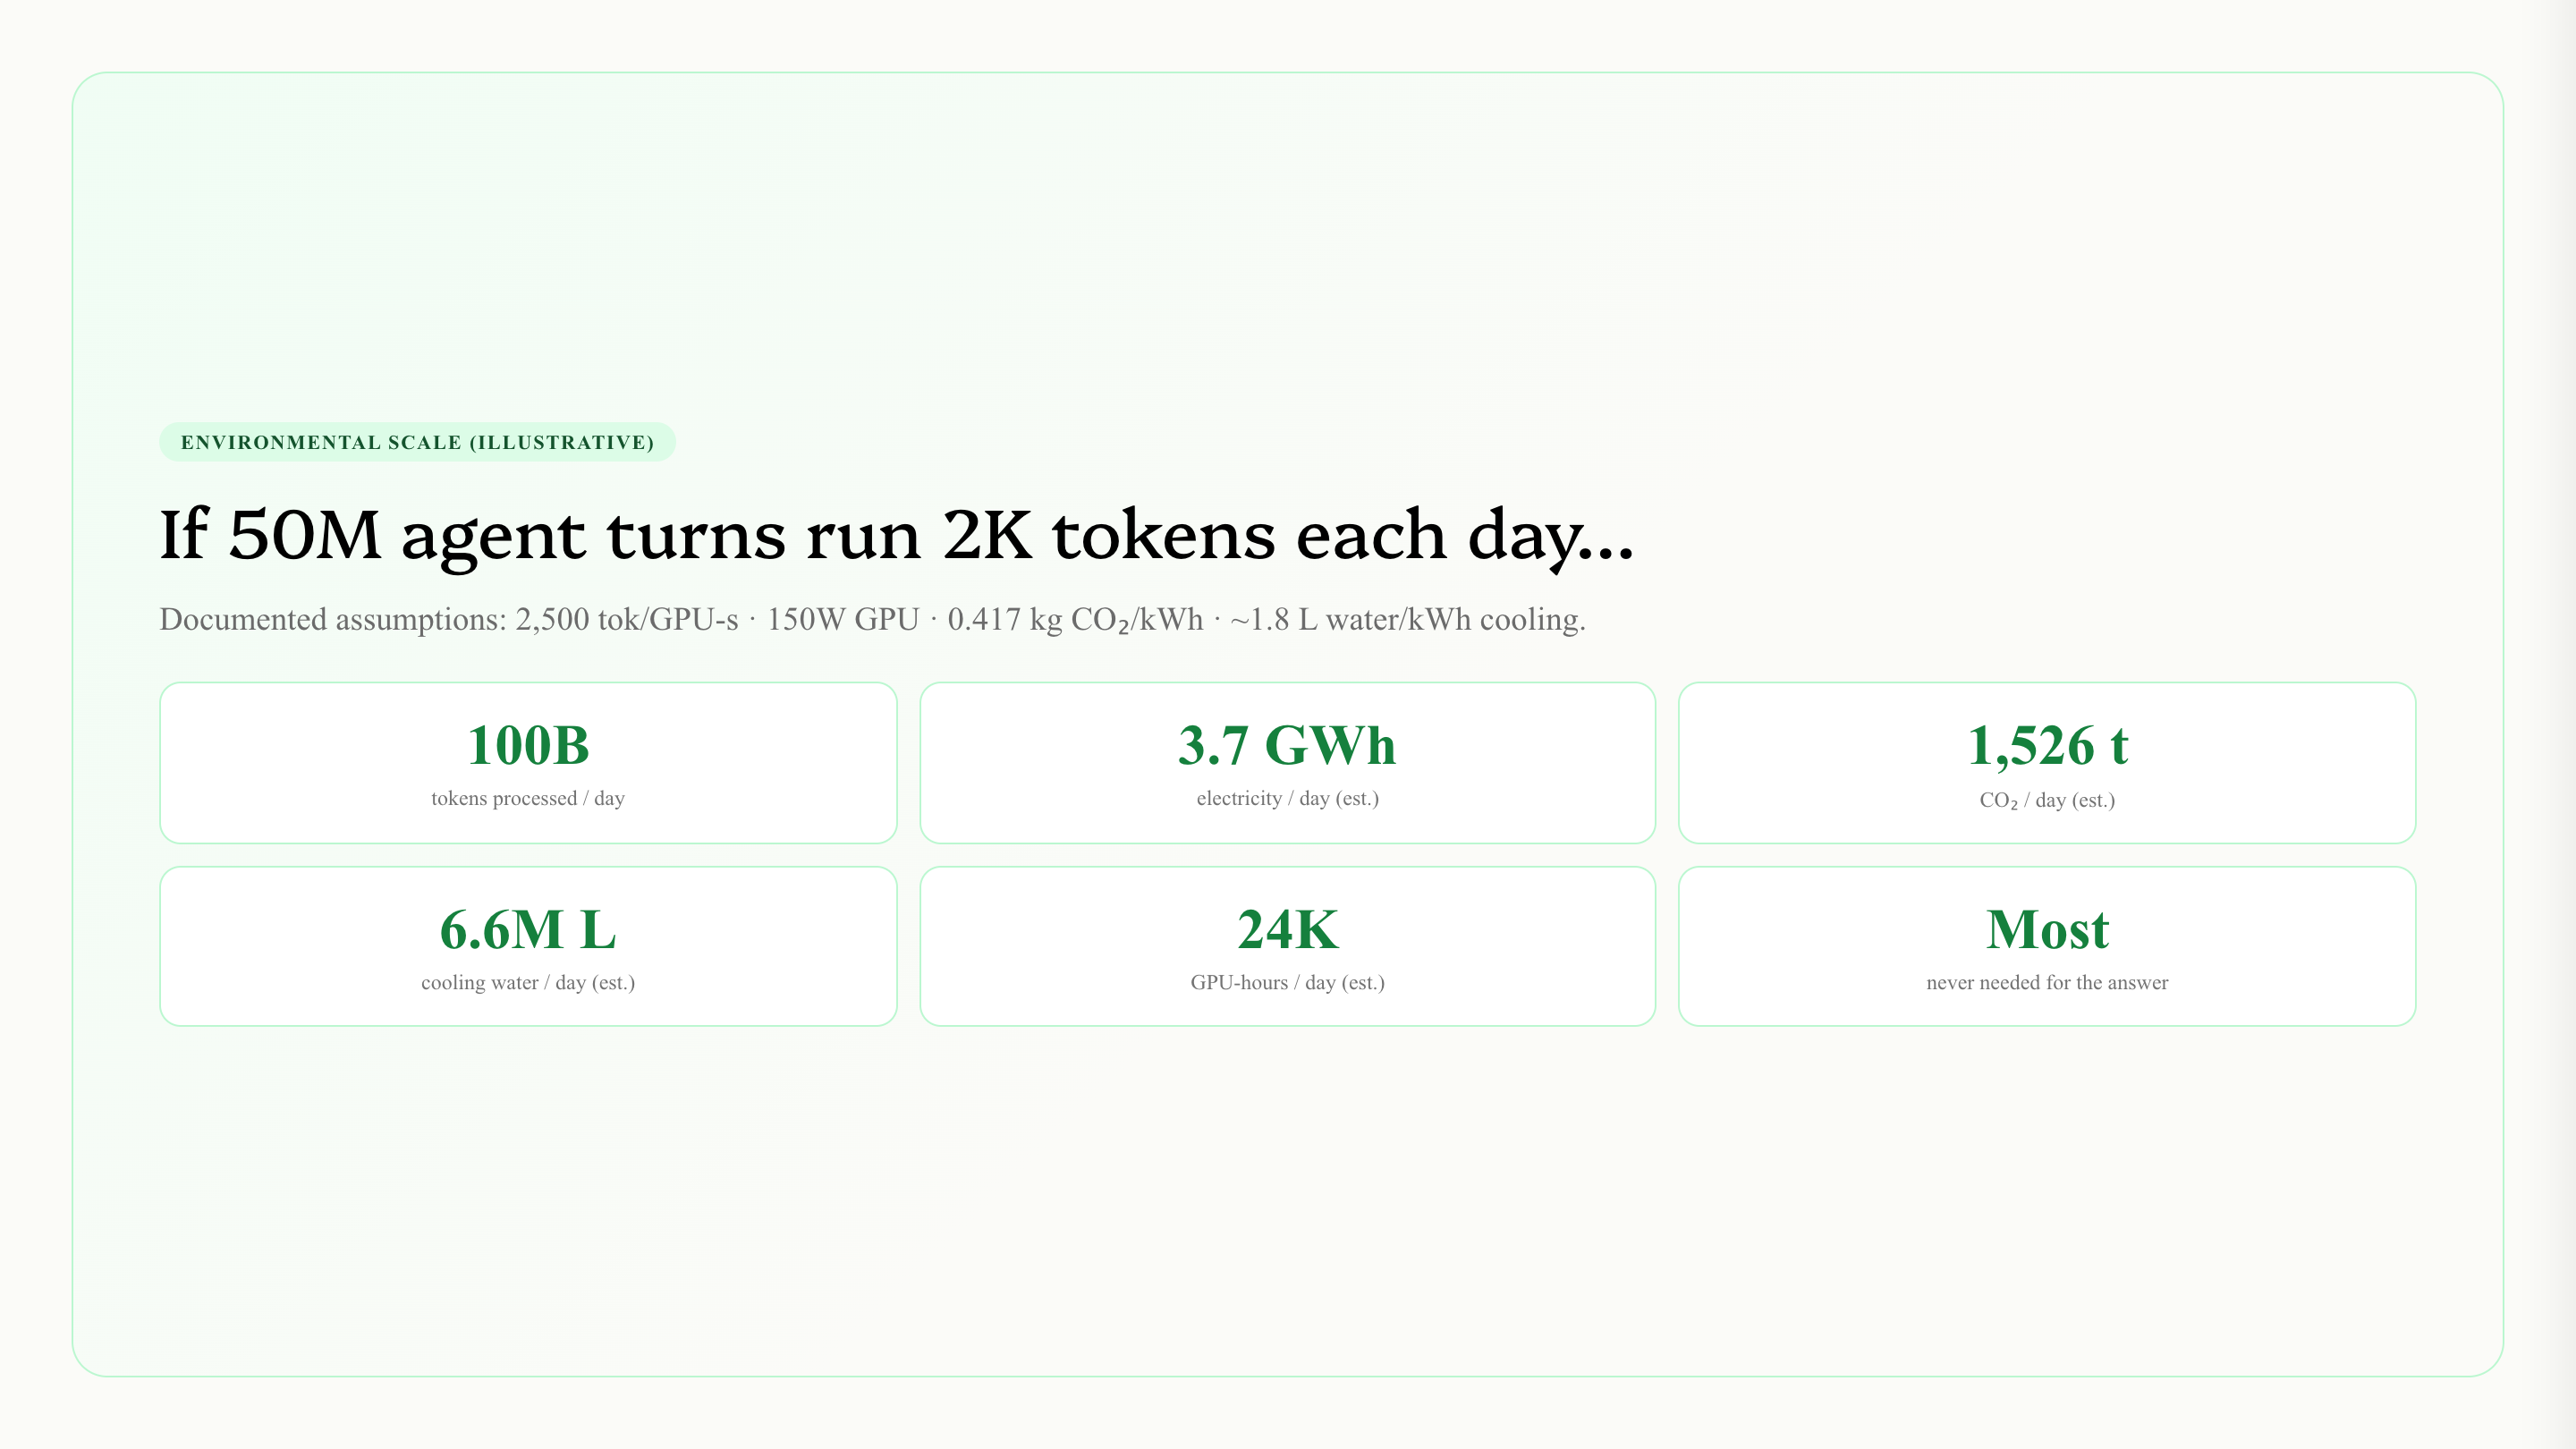
AI agents, RAG systems, and coding assistants are accumulating massive amounts of low-value context. Every workflow sends old logs, irrelevant RAG chunks, boilerplate files, stale tool calls, and filler conversation turns to the model. The result: bloated token bills and higher latency, as models get distracted by noise instead of focusing on what matters. At small scale it's wasted cents. At agent scale with millions of tokens, it becomes millions of useless tokens processed—driving up costs, latency, and context-window pressure.
Solution
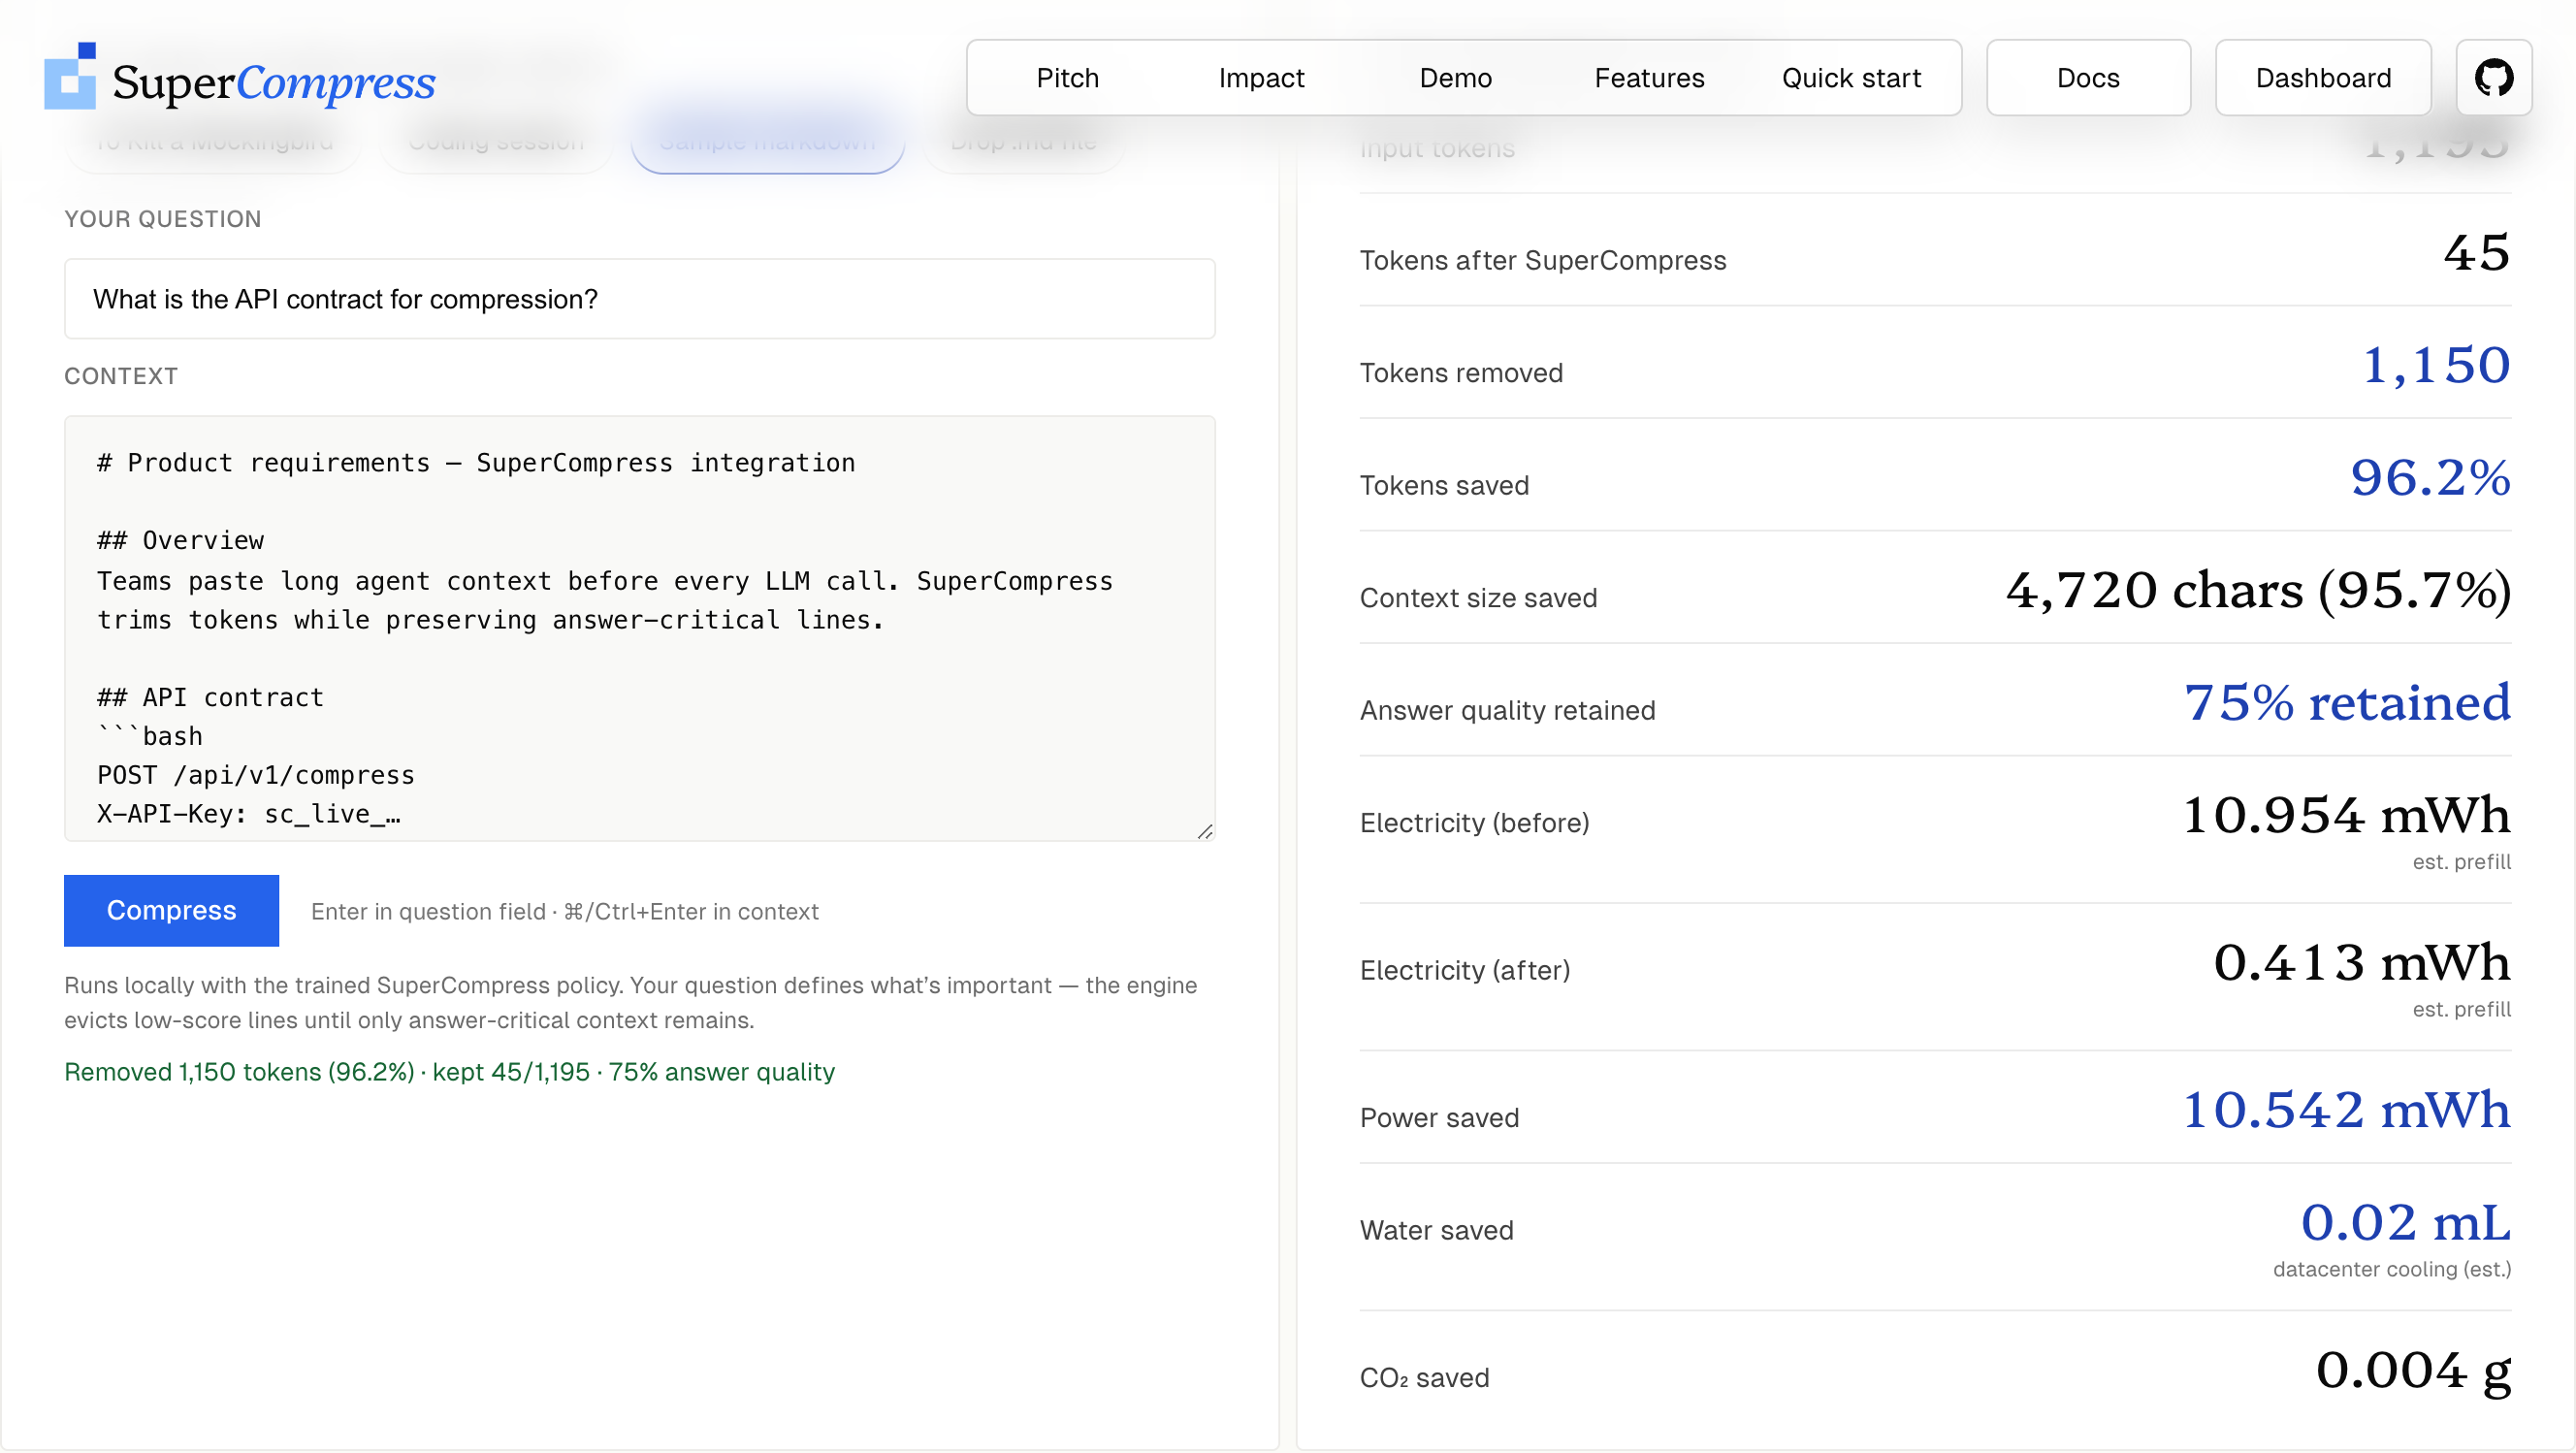
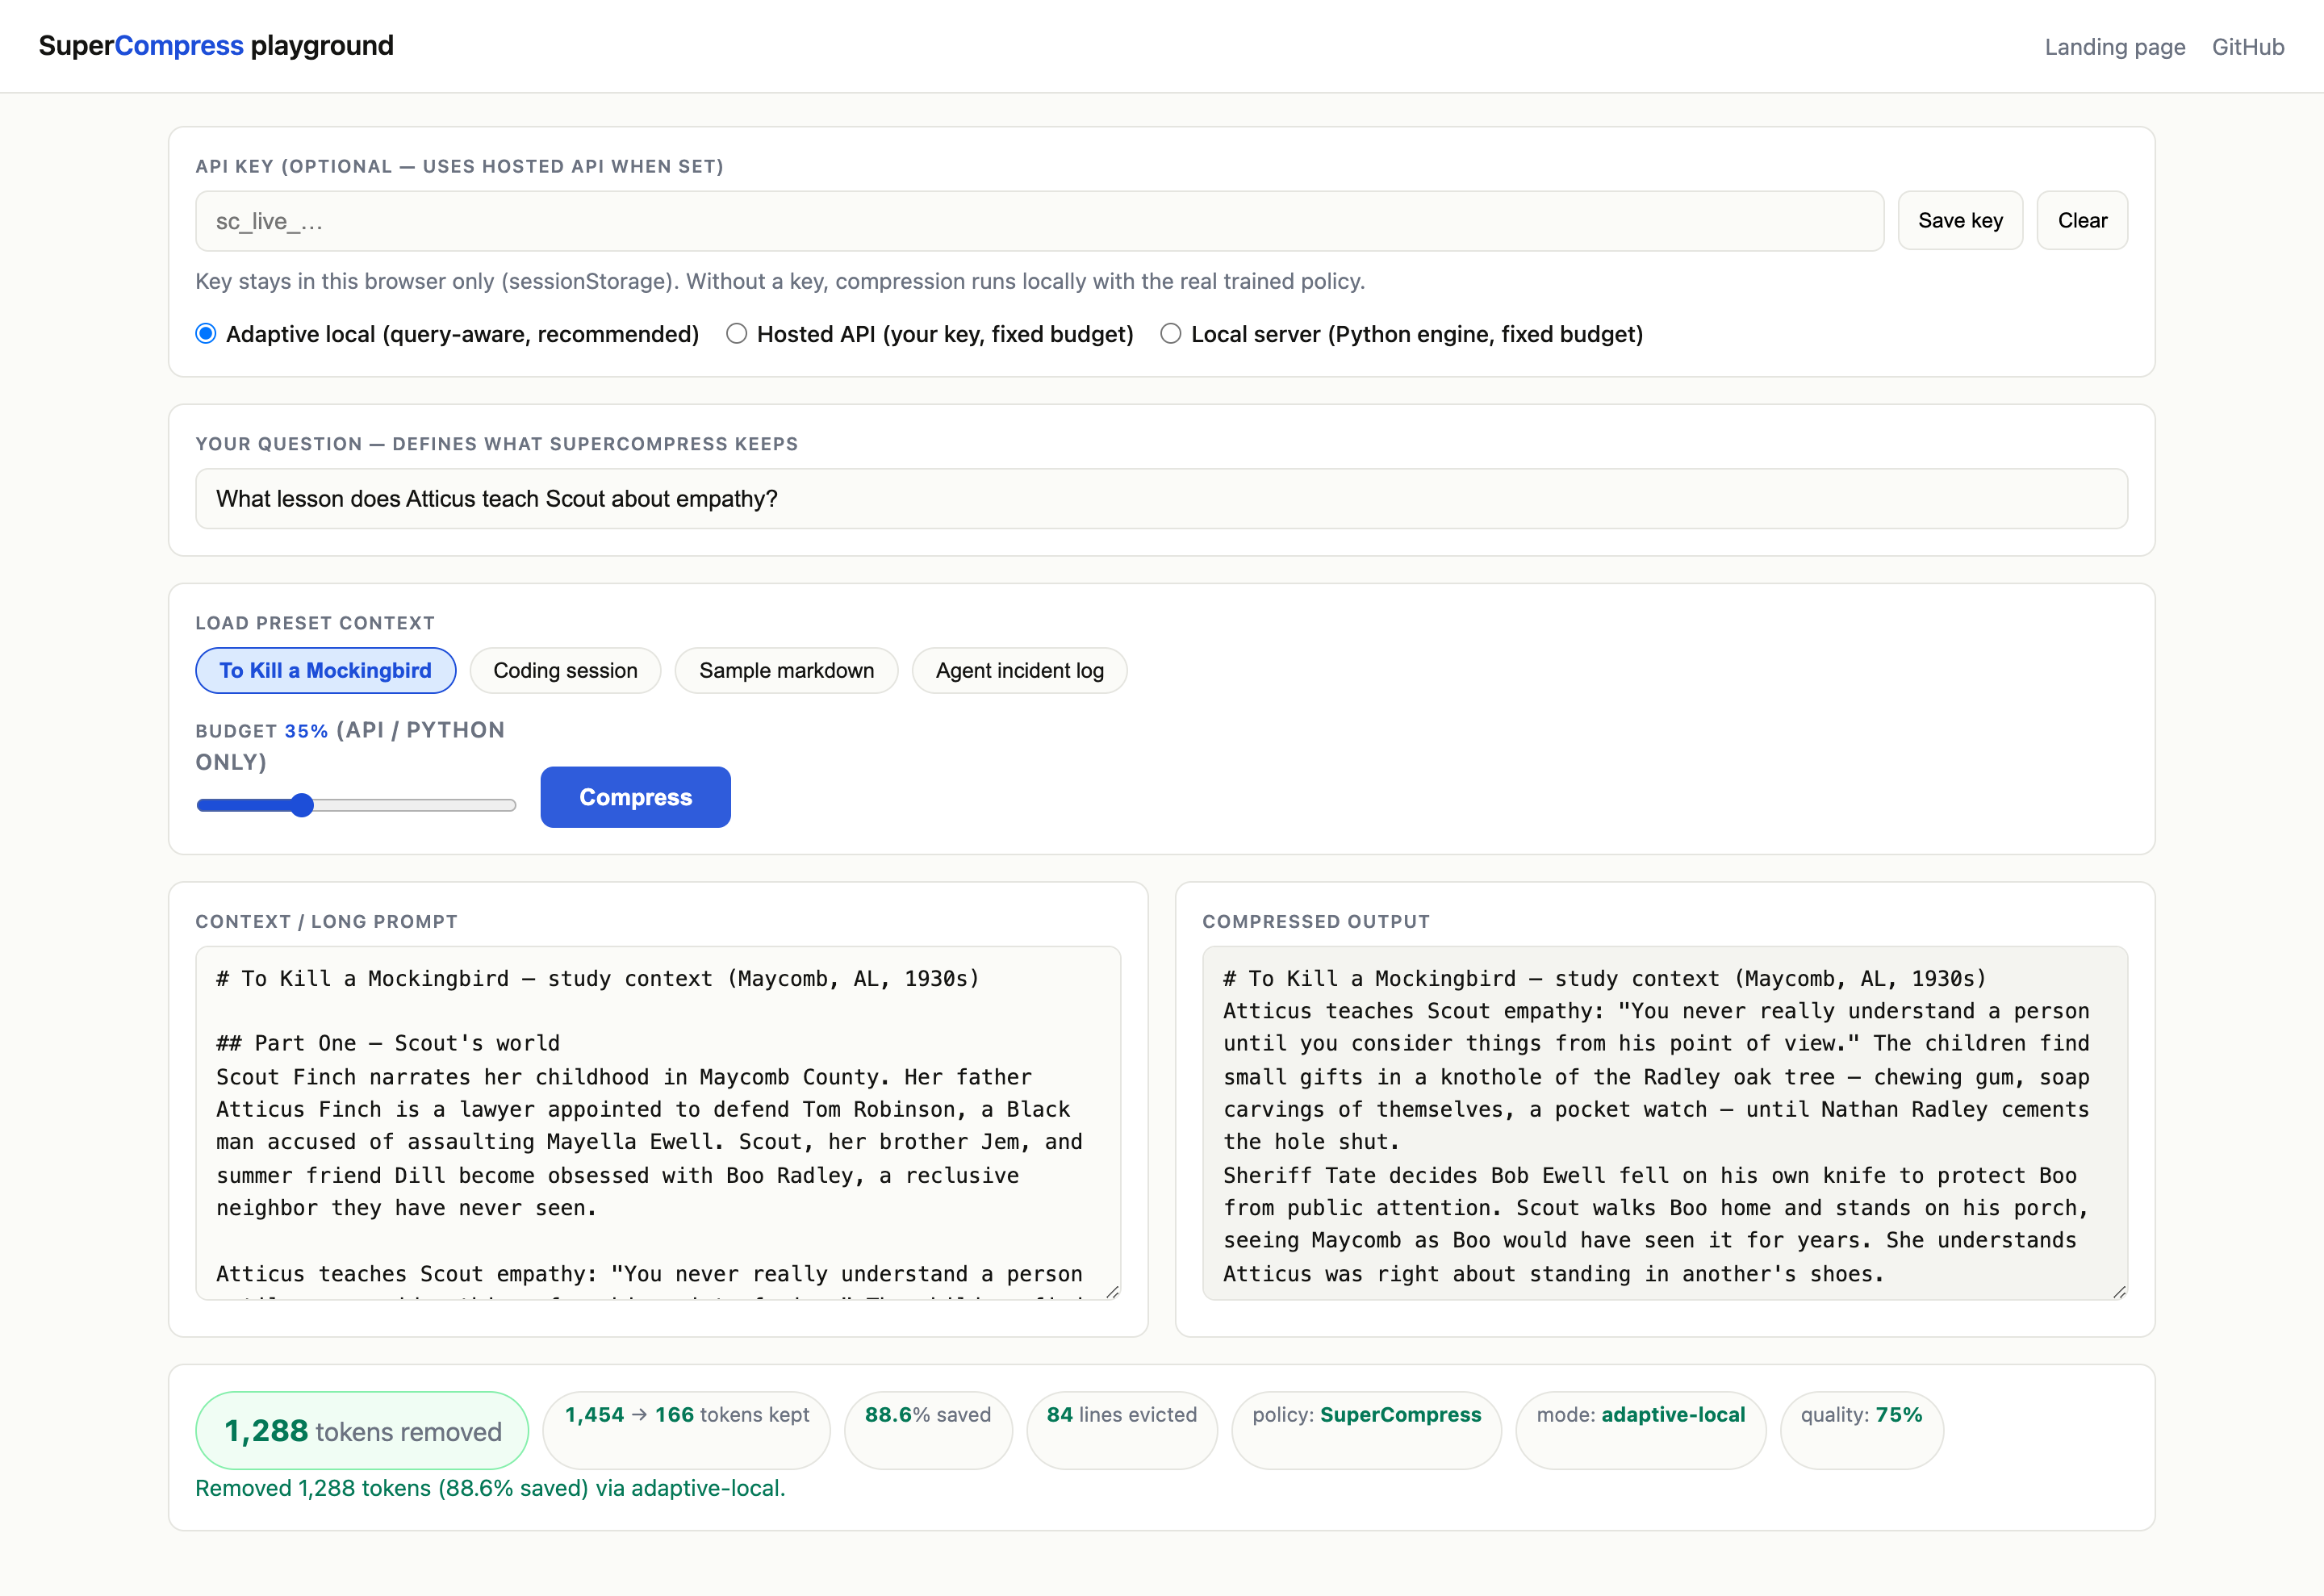
SuperCompress is a query-aware context compression layer for production AI applications and agents. It sits between an application and an LLM, evaluates every token against the active query, and removes low-value context while preserving critical evidence. Unlike naive truncation or risky summarization, SuperCompress is extractive and query-aware—it keeps exactly what the model needs to answer the question and discards the rest. The result is far fewer tokens per request, while the evidence the model needs to answer is kept in its original wording.
SuperCompress is an existing, publicly available project created by student founder Arjun Shah before this competition. It is being entered as an existing student-founded startup, not a project built for this competition.
How It Works at a High Level
- Normalize & Route: Input context is segmented by type—text, code, JSON, logs—and routed through type-specific preprocessing.
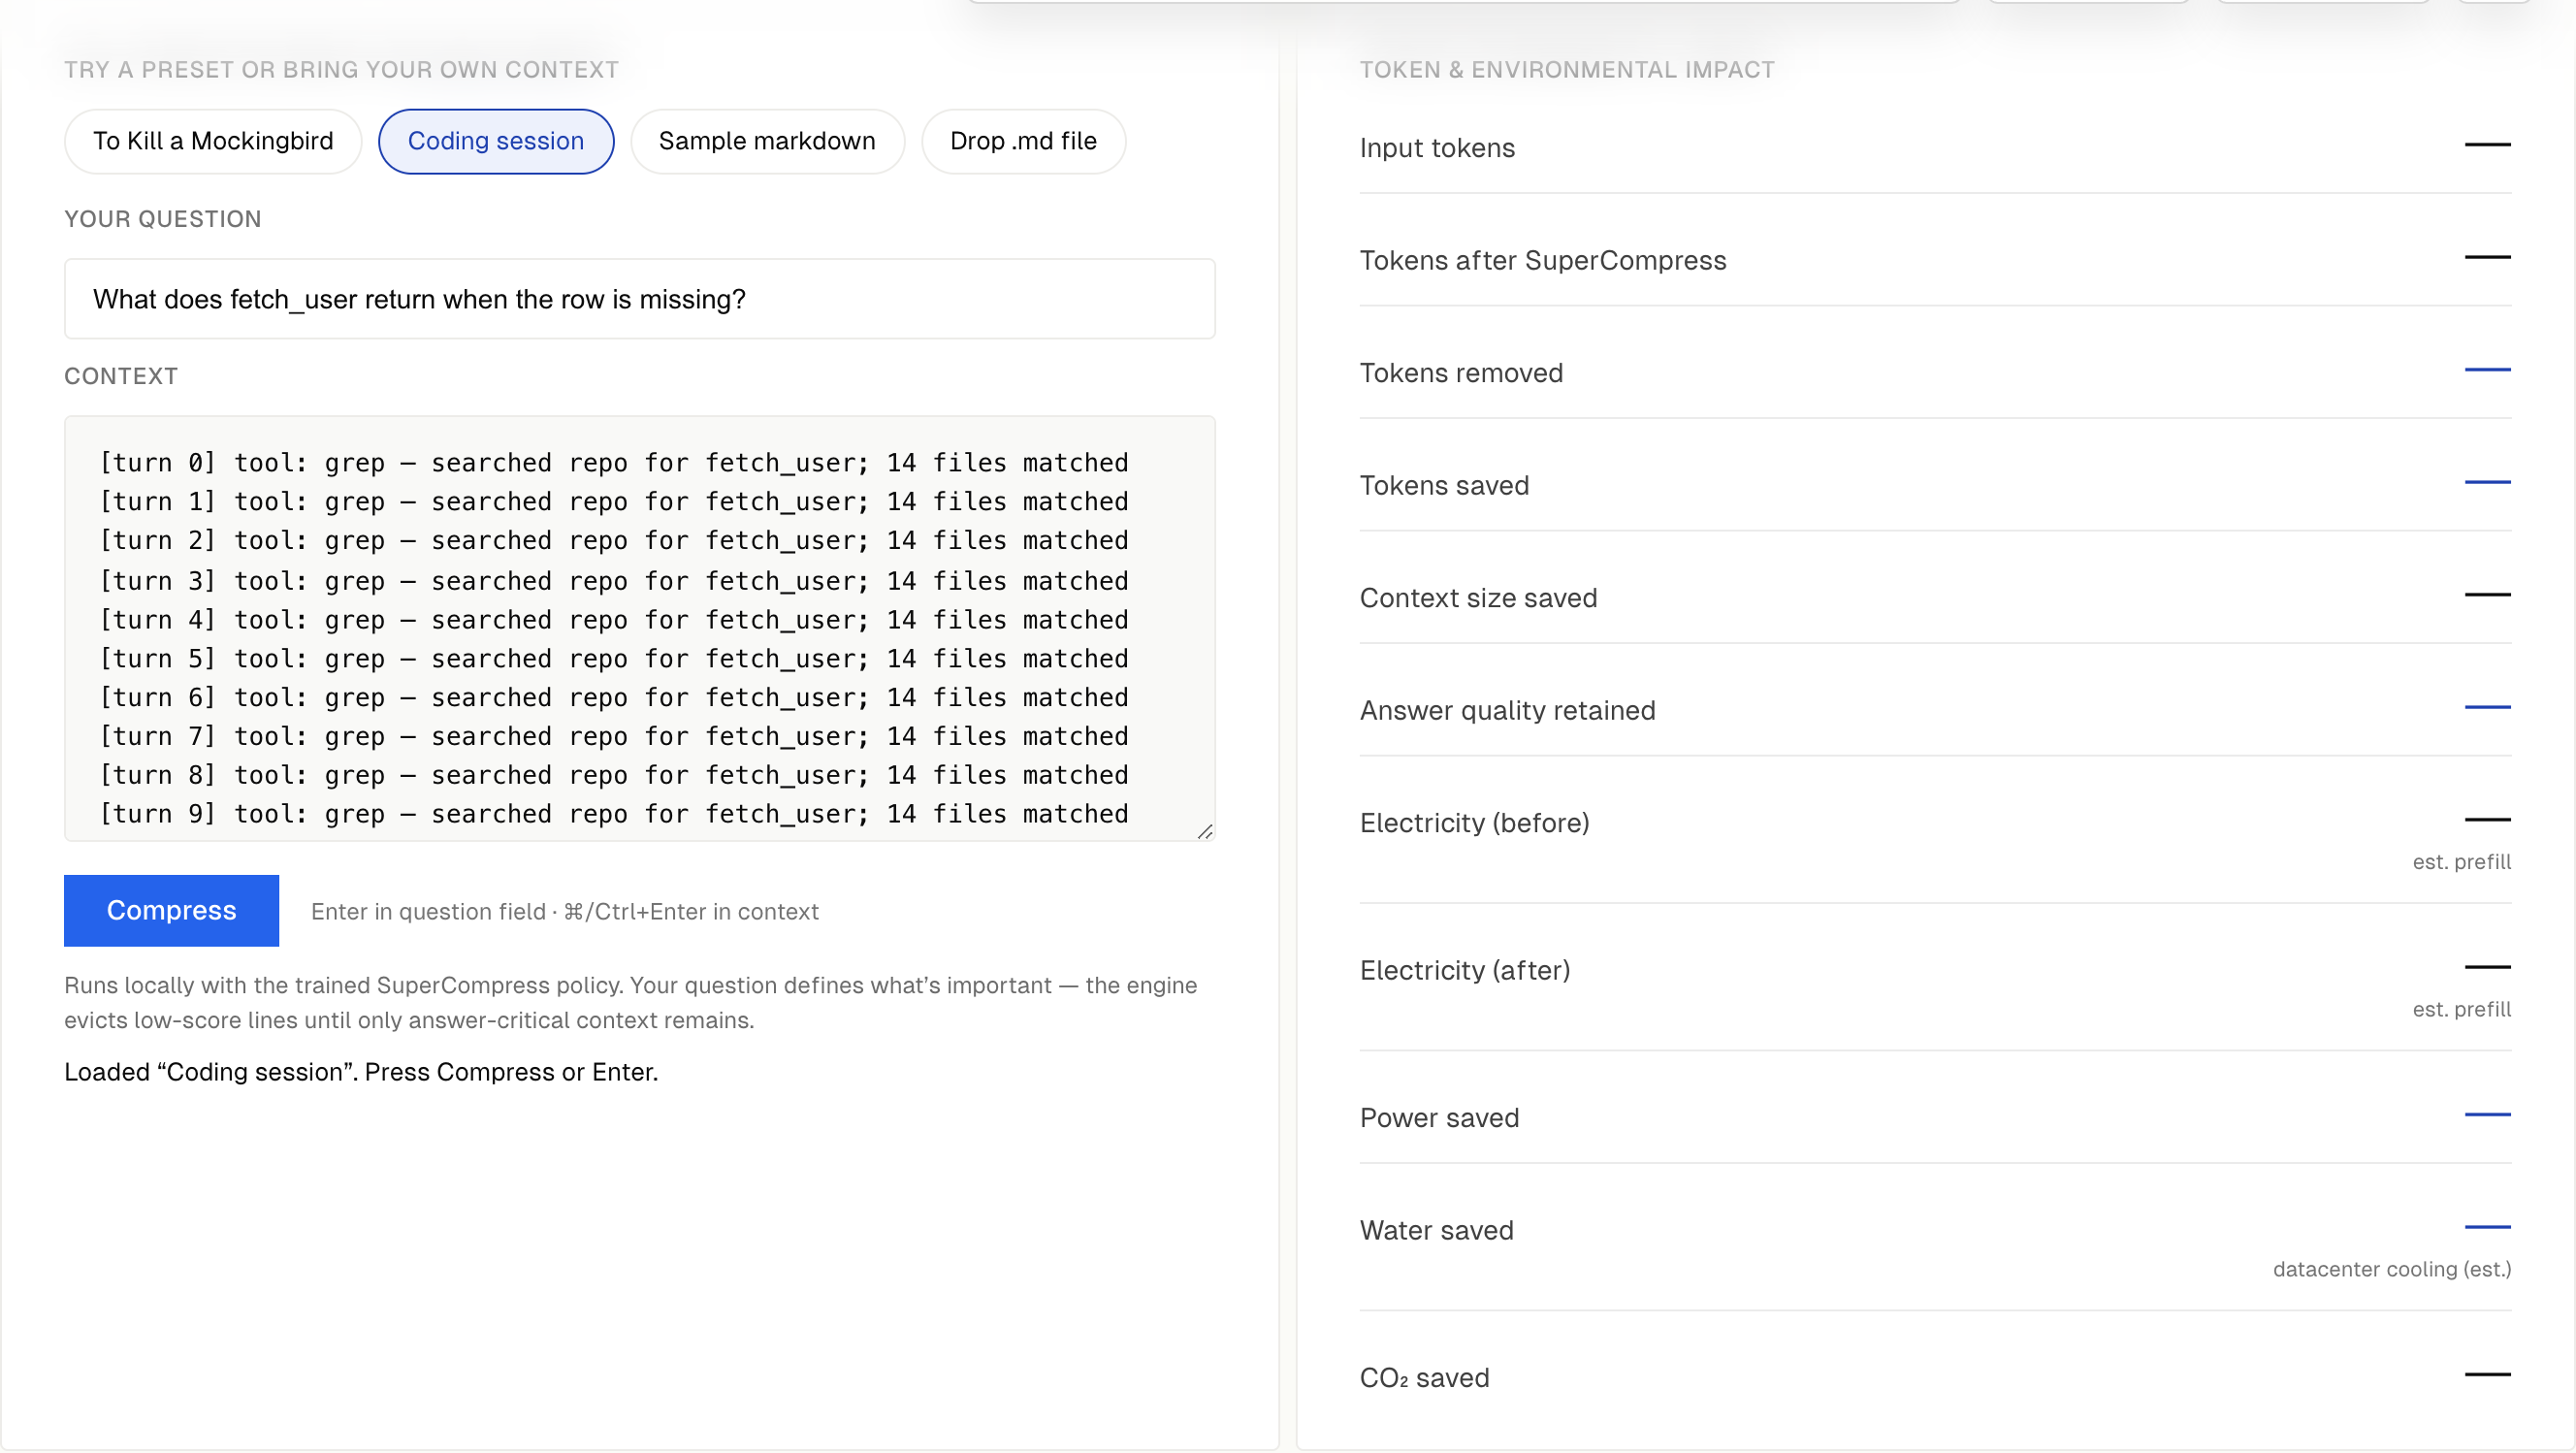
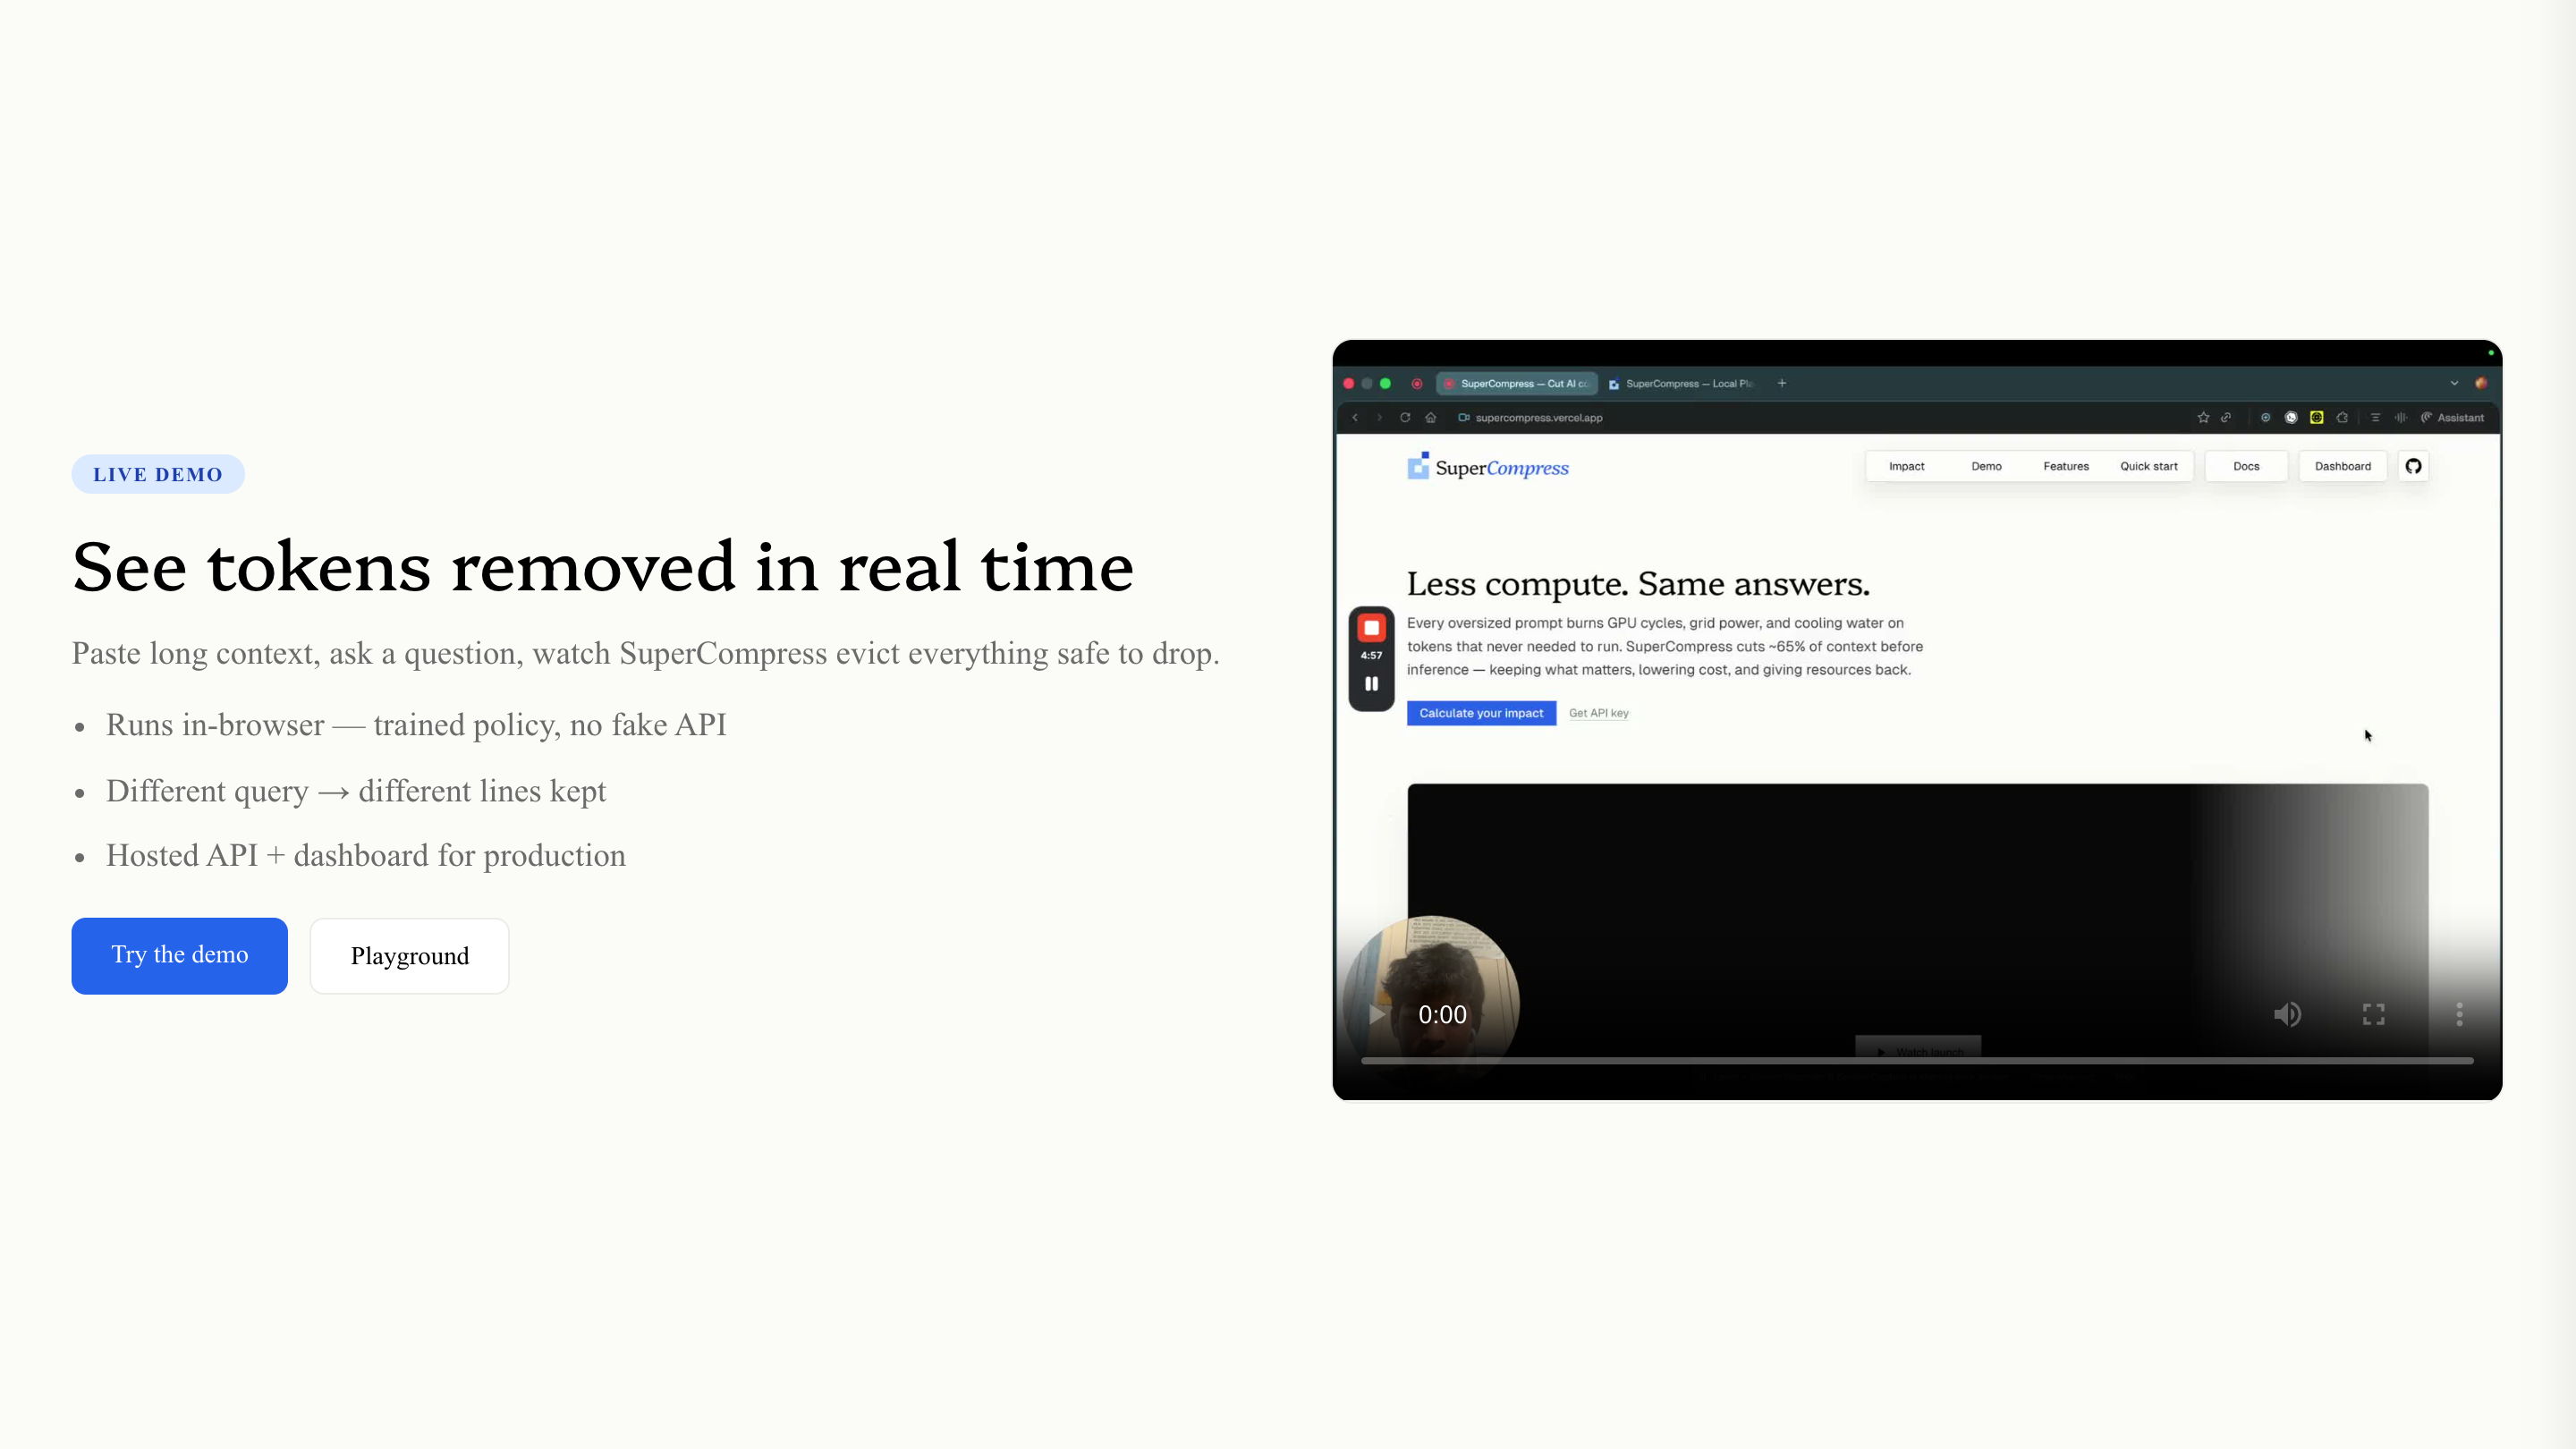
- Score Against the Query: Context is ingested and scored for relevance against the current ask using our query-aware Neural Keep model. Required evidence is retained in original wording, and fewer tokens are sent to inference.
- Preserve Critical Evidence: Critical entities, dependencies, and answer-relevant blocks are protected from eviction, even if they score low on pure utility.
- Emit Compressed Output: The system emits compressed context plus token-savings and risk metadata, letting downstream systems make informed decisions.
- Reversible Cache-Compress-Retrieve: Omitted blocks can be retrieved on demand via a reversible retrieval option, providing a safety net when compressed context proves insufficient.
Users & Market
- Developers building agentic AI applications and multi-agent workflows
- Agent frameworks that need to reduce context before passing it to LLMs
- RAG platforms seeking to cut token costs while preserving retrieval quality
- Coding assistants handling large codebases with massive context windows
- Enterprise AI teams building support systems and long-context workflows where latency and cost matter
Long-context AI apps, agents, RAG, copilots, and enterprise AI workflows all pay for context sent to inference, so context efficiency directly affects cost and latency.
Differentiation
SuperCompress is not naive truncation or summarization:
- Extractive & query-aware: It scores context against the actual query, so it keeps the right things—not just the most recent or most common ones
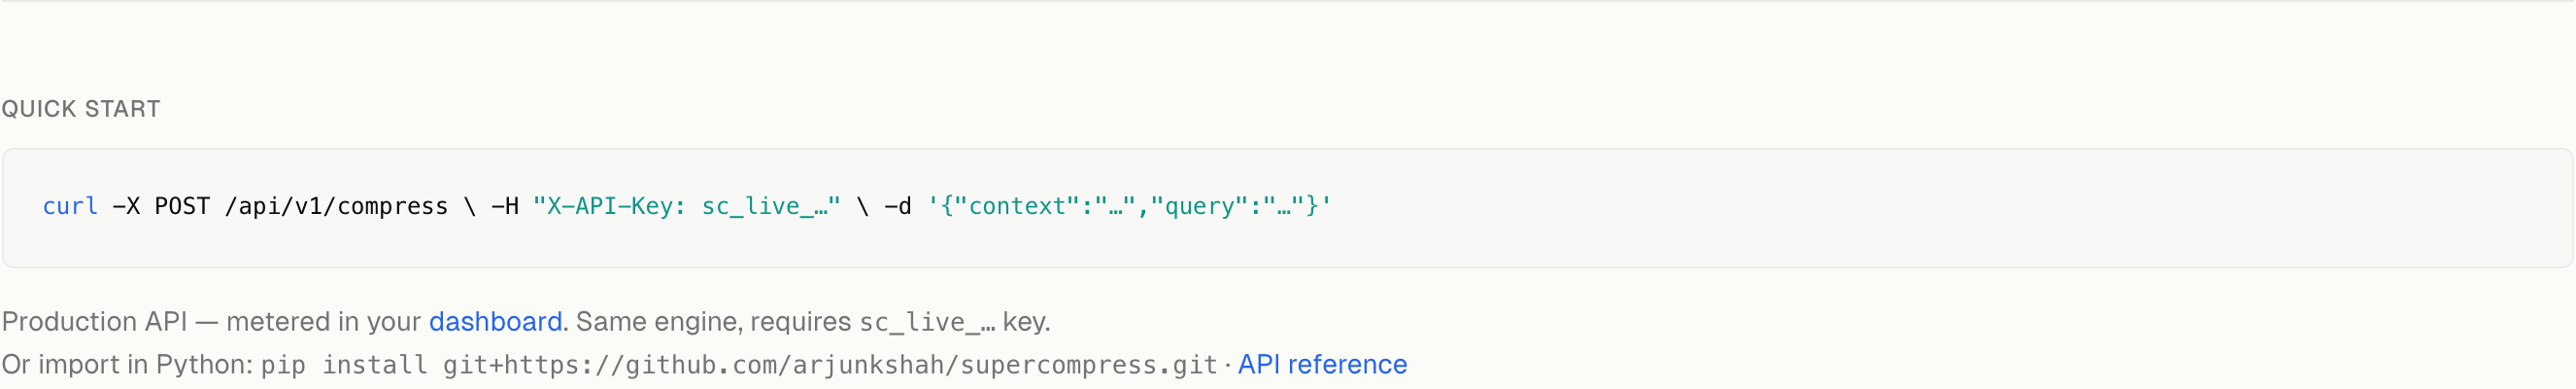
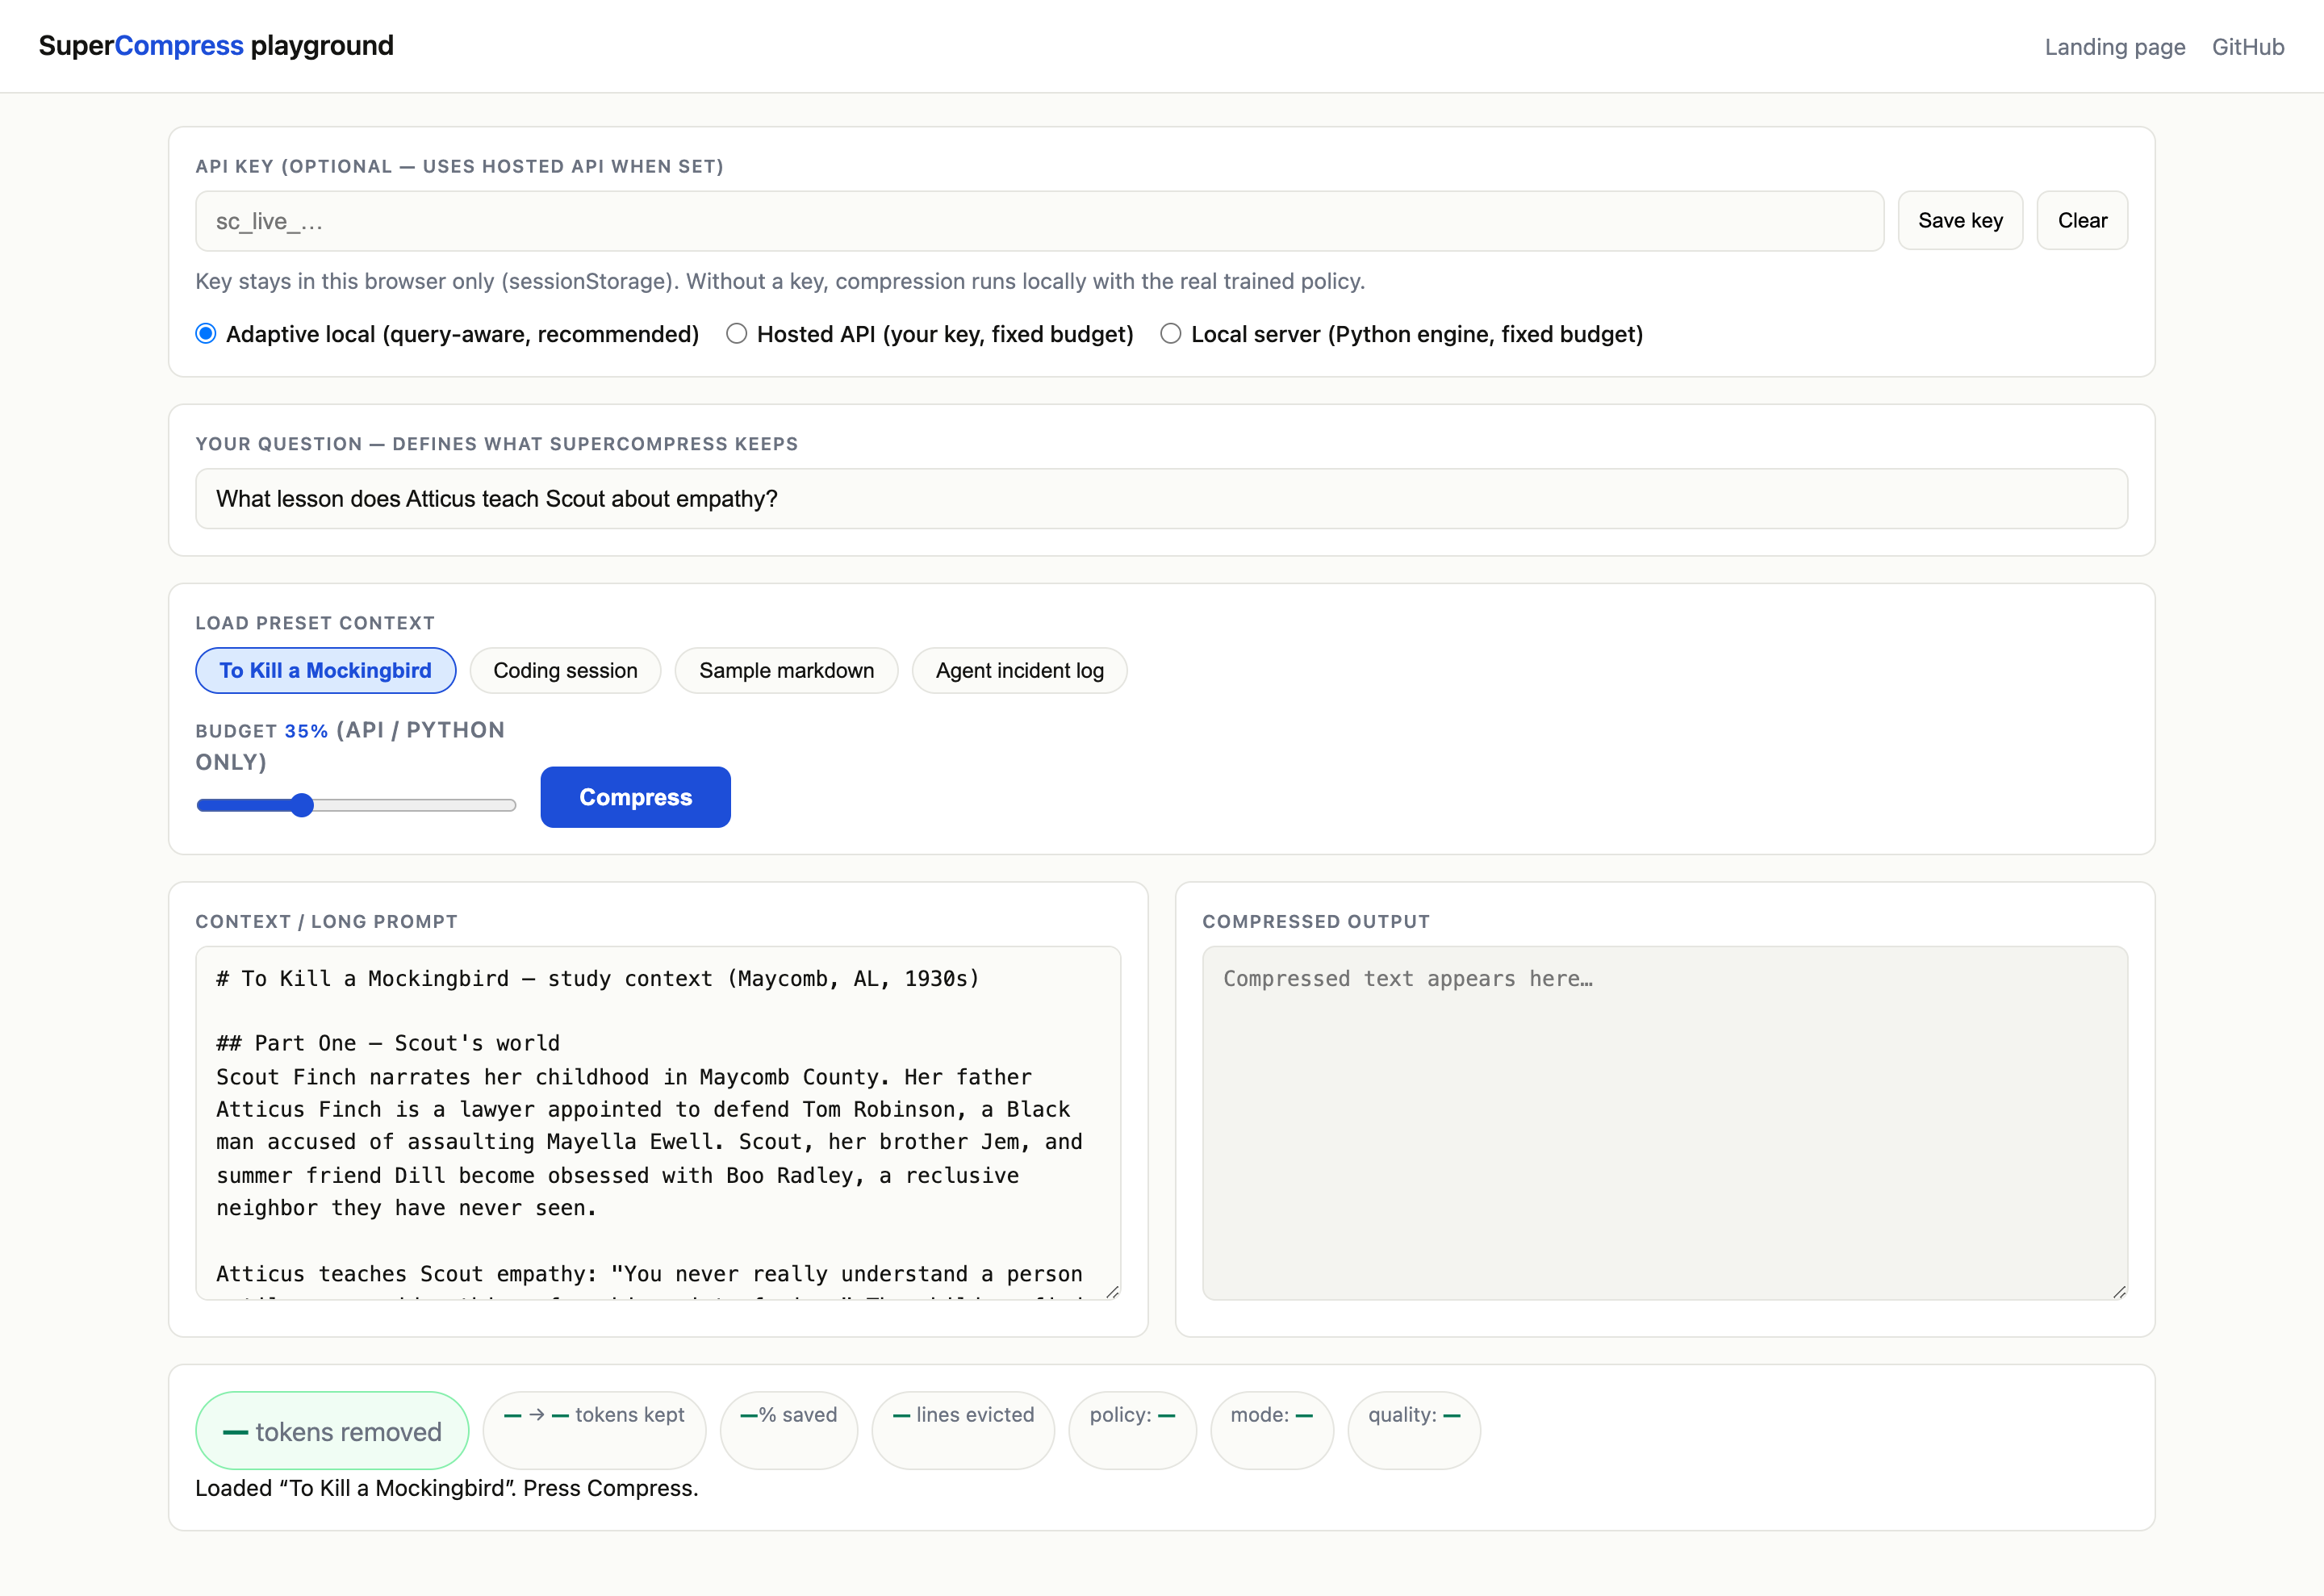
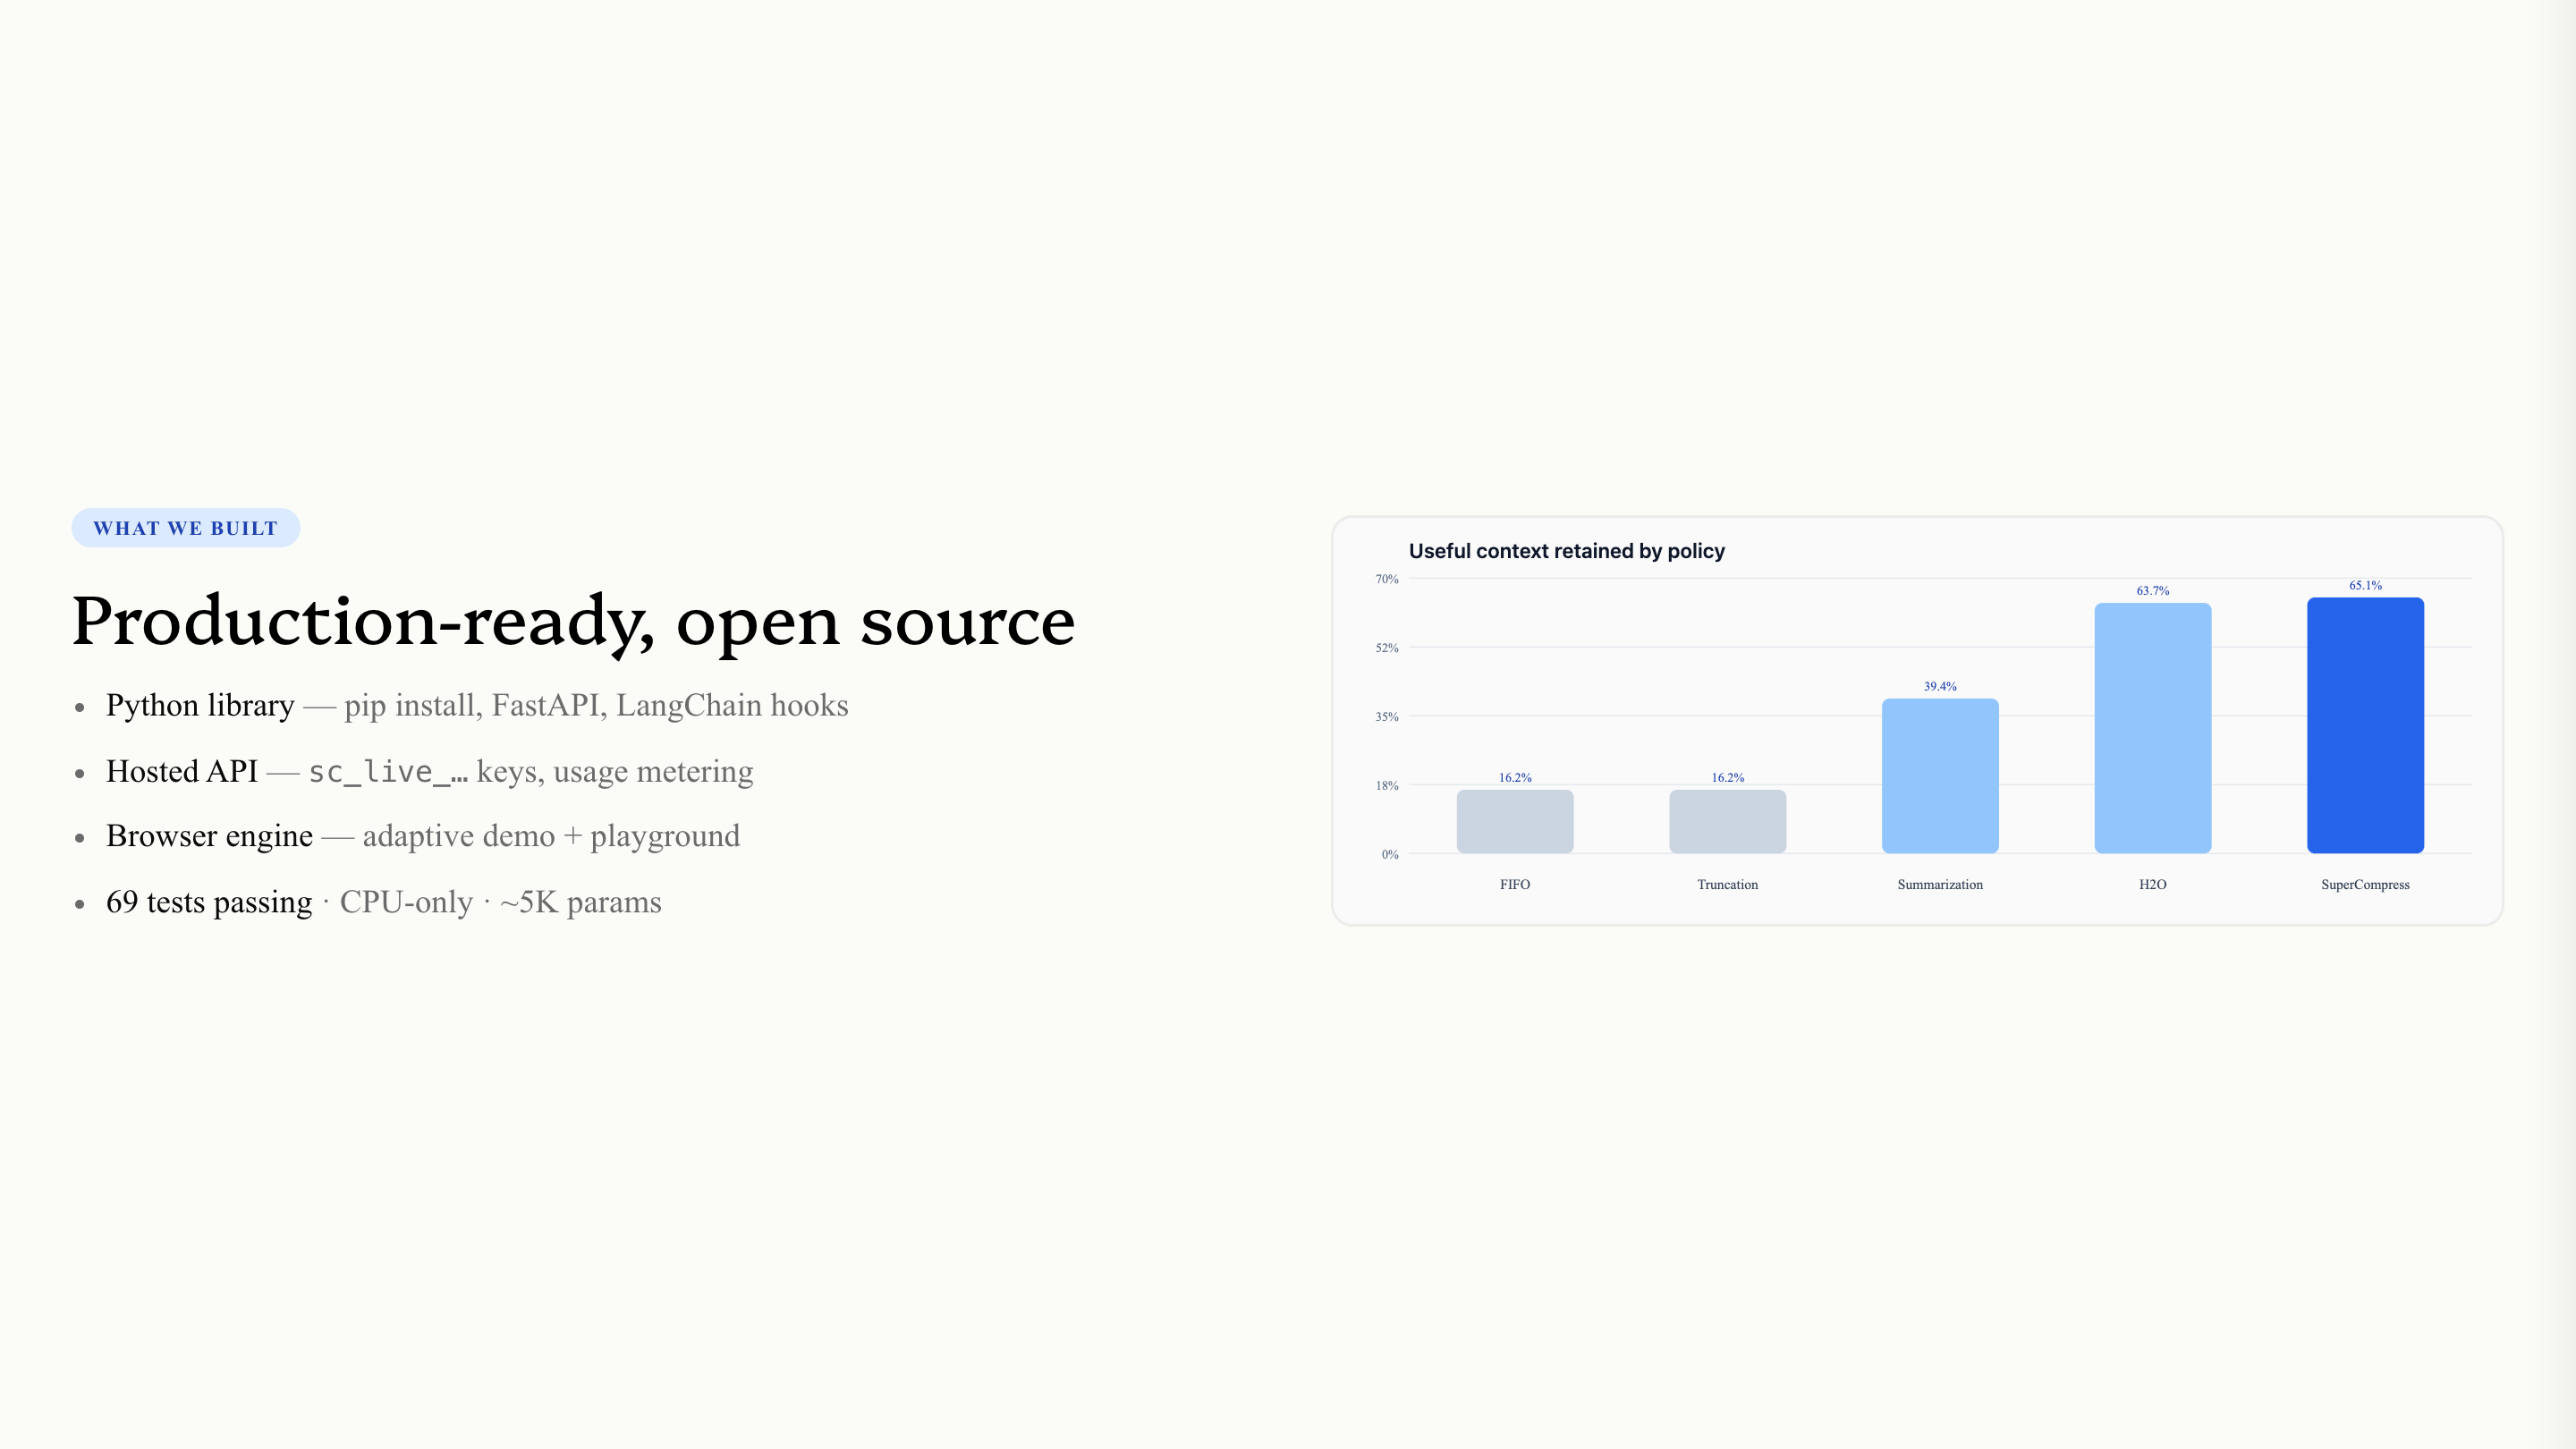
- Integration-friendly: Ships as a Python library, a hosted API, and a browser engine—plug it into any existing stack
- Auditable: Returns token-savings and risk metadata alongside compressed context
- Cross-format: Works across structured (JSON, code) and unstructured (text, logs) context with content-specific preprocessing
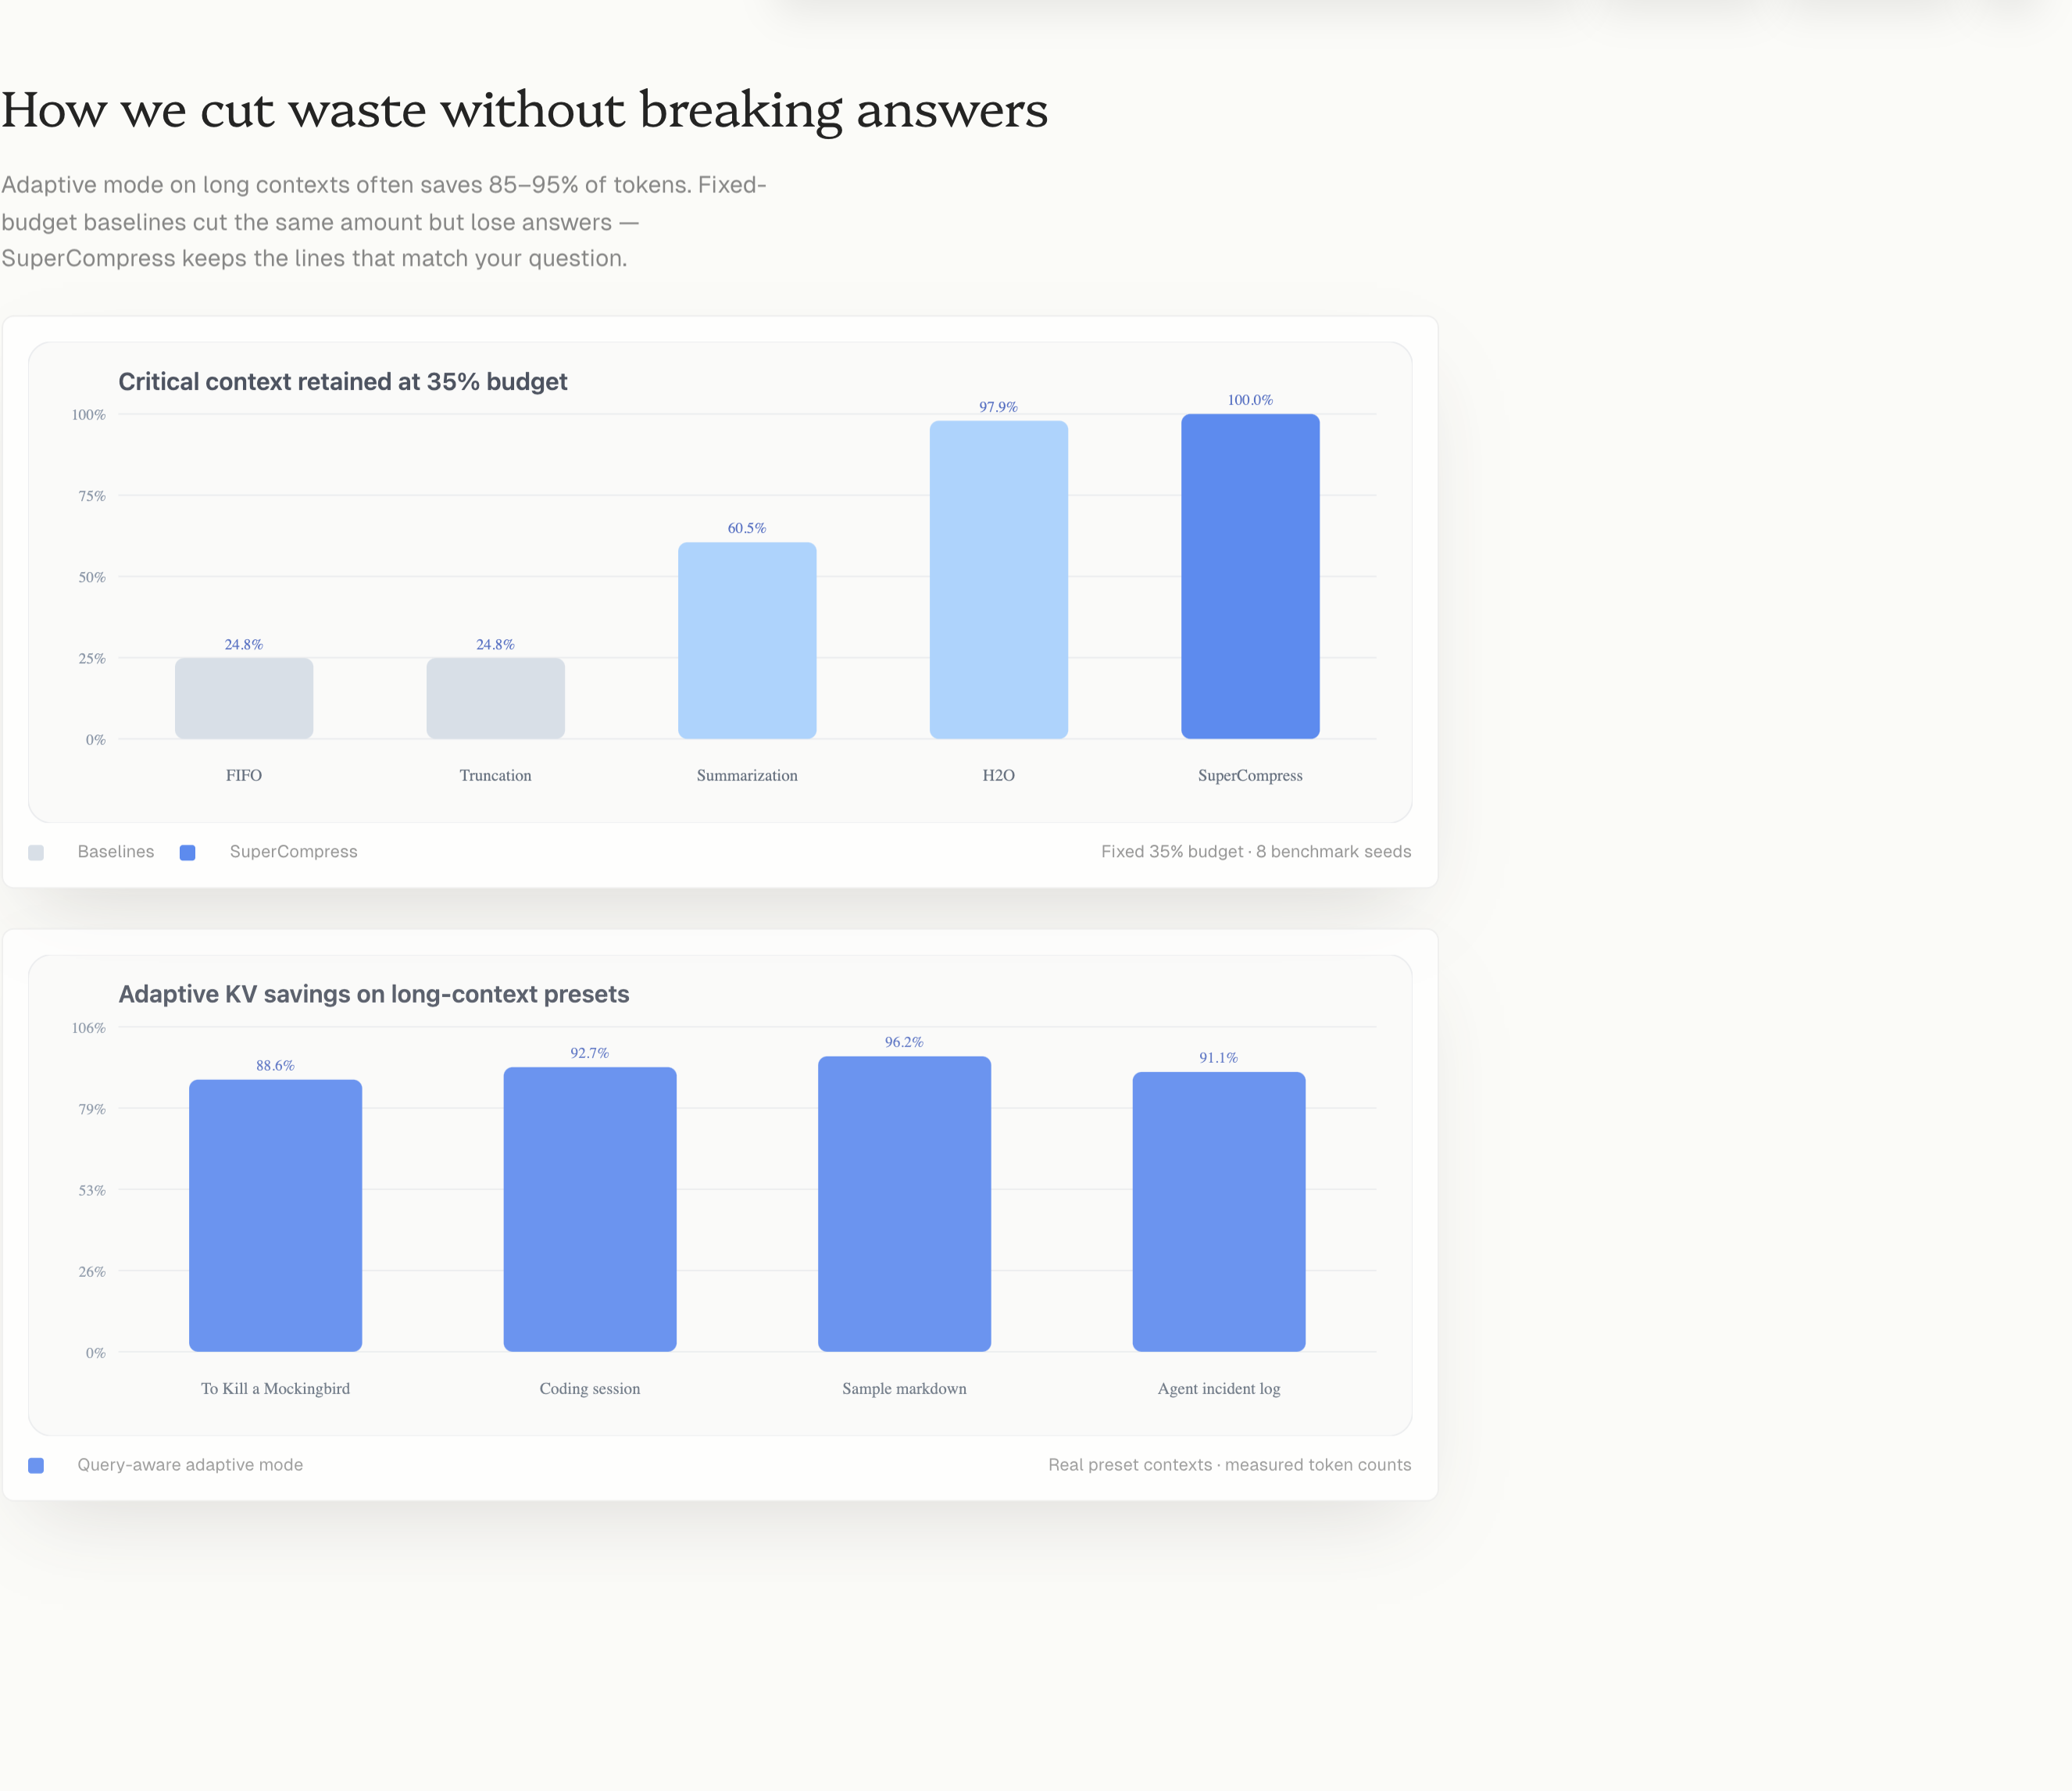
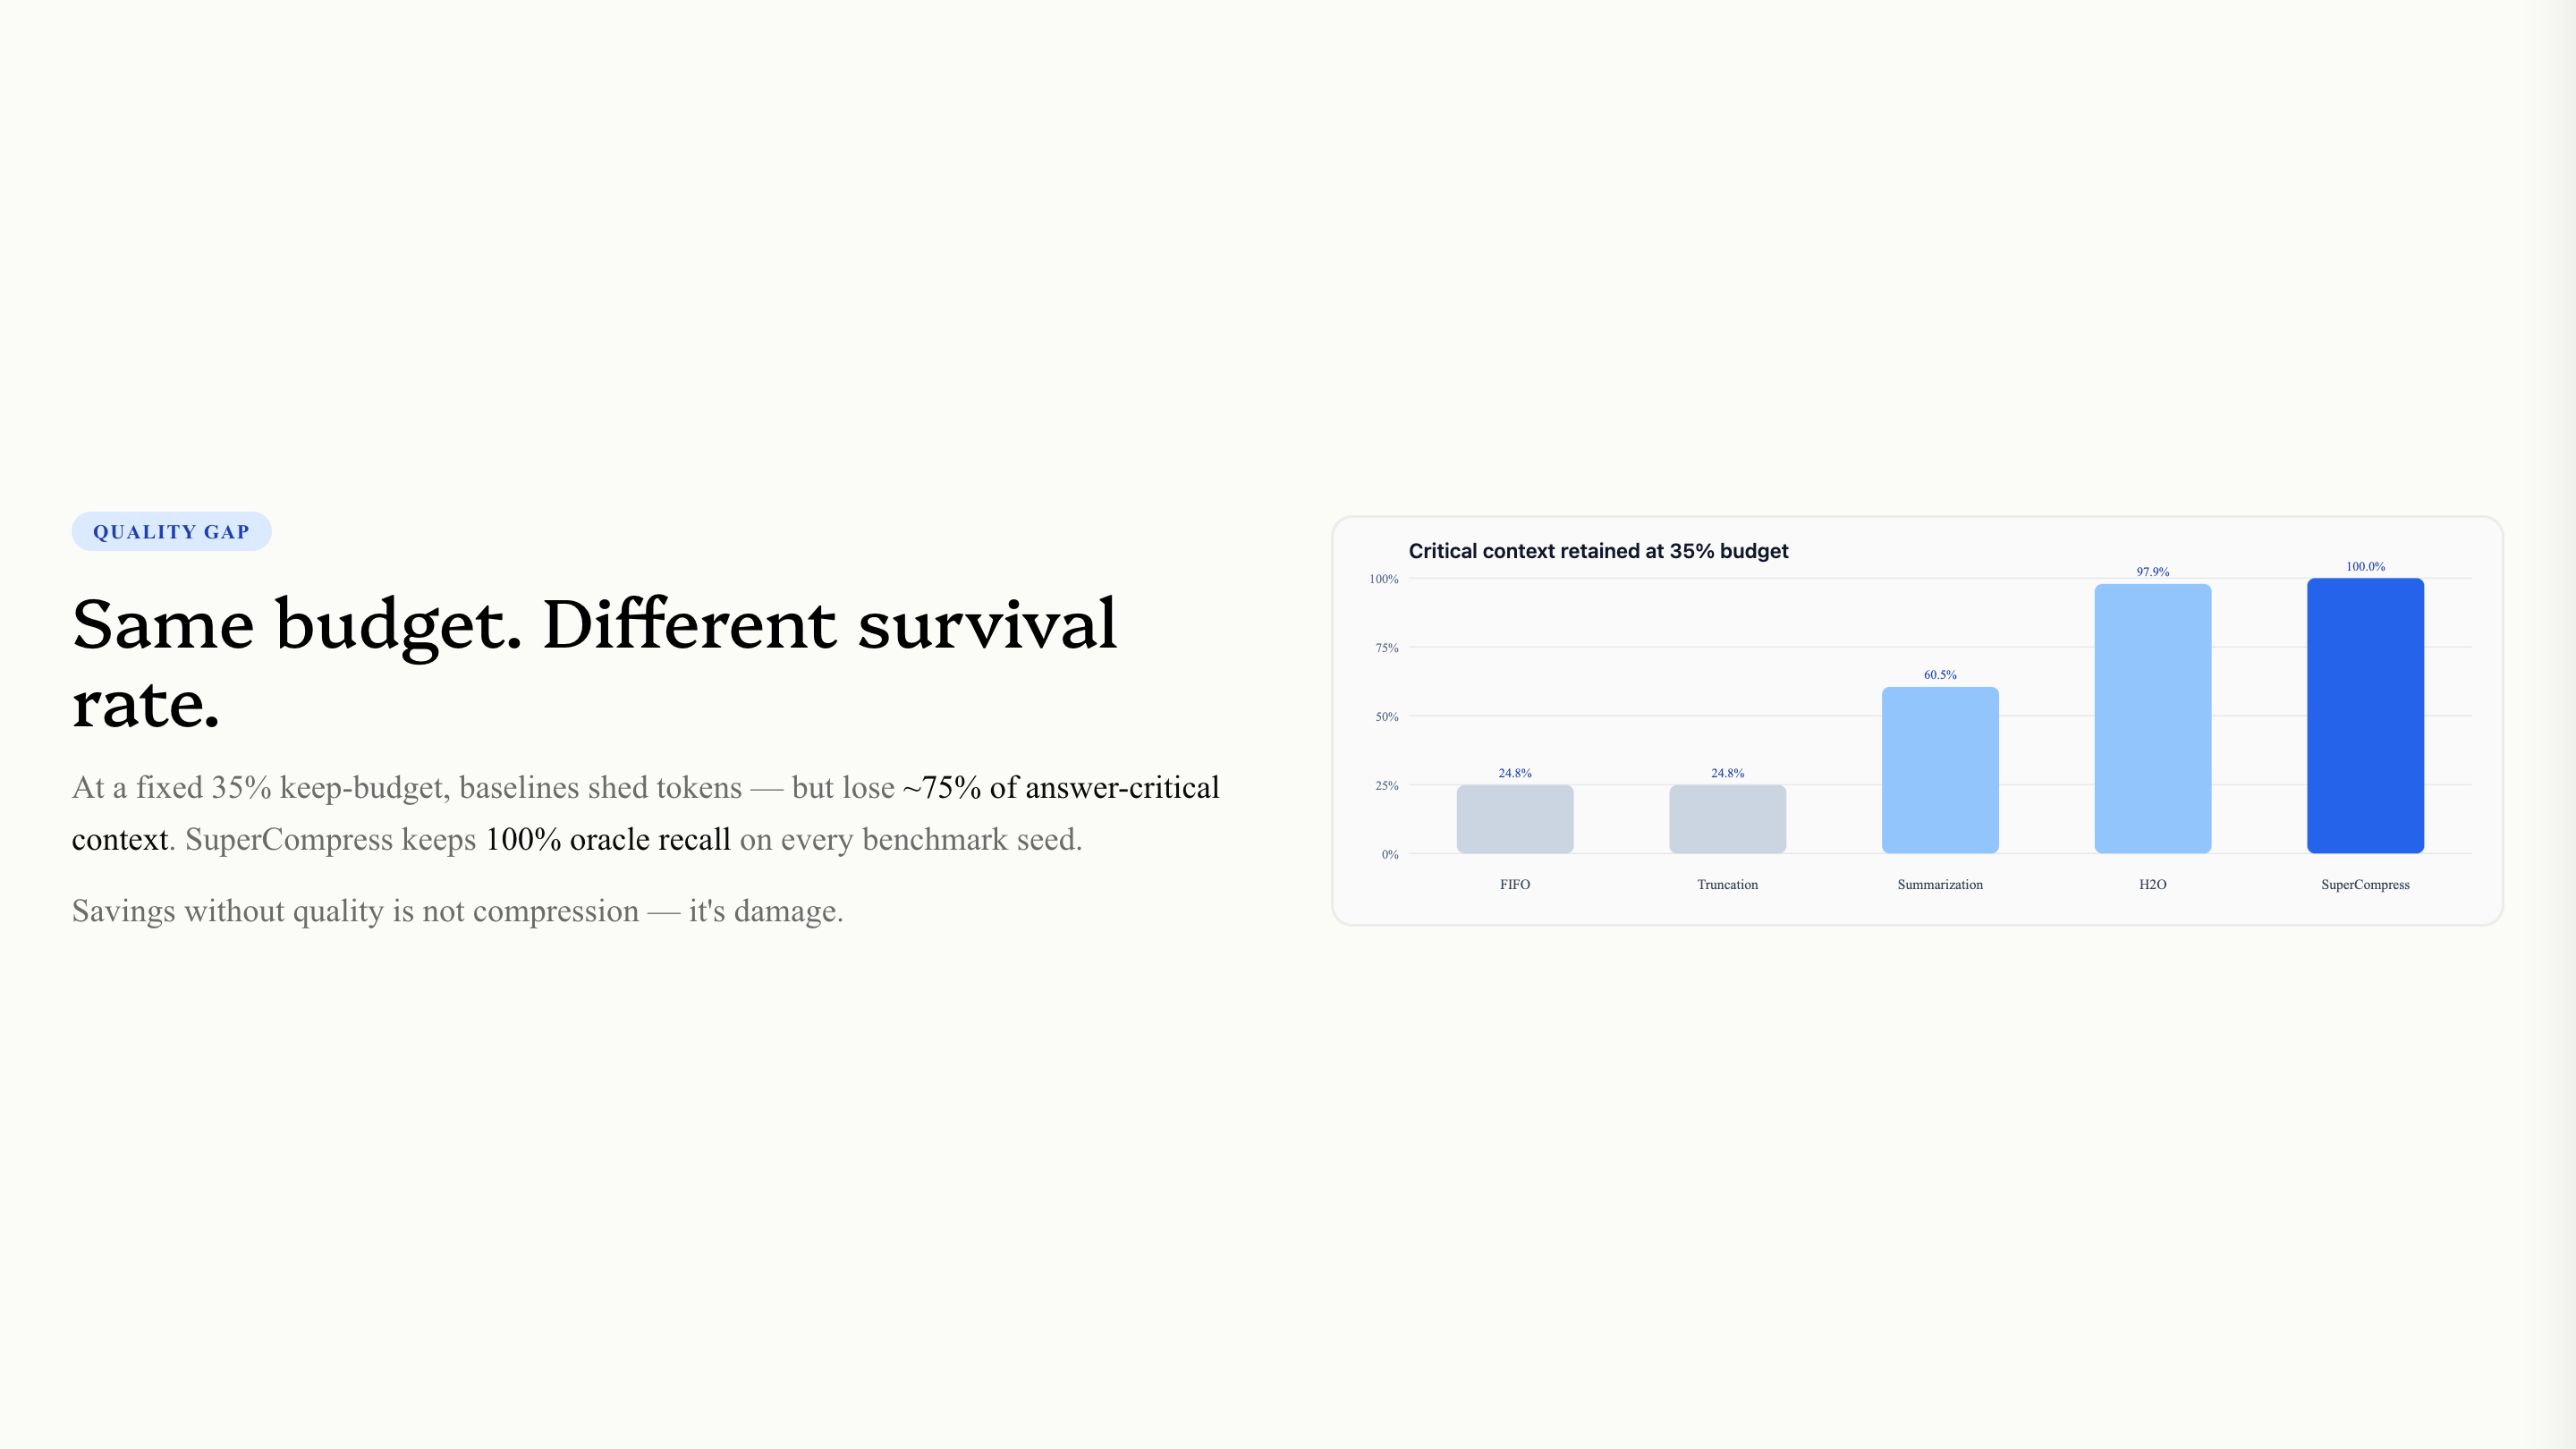
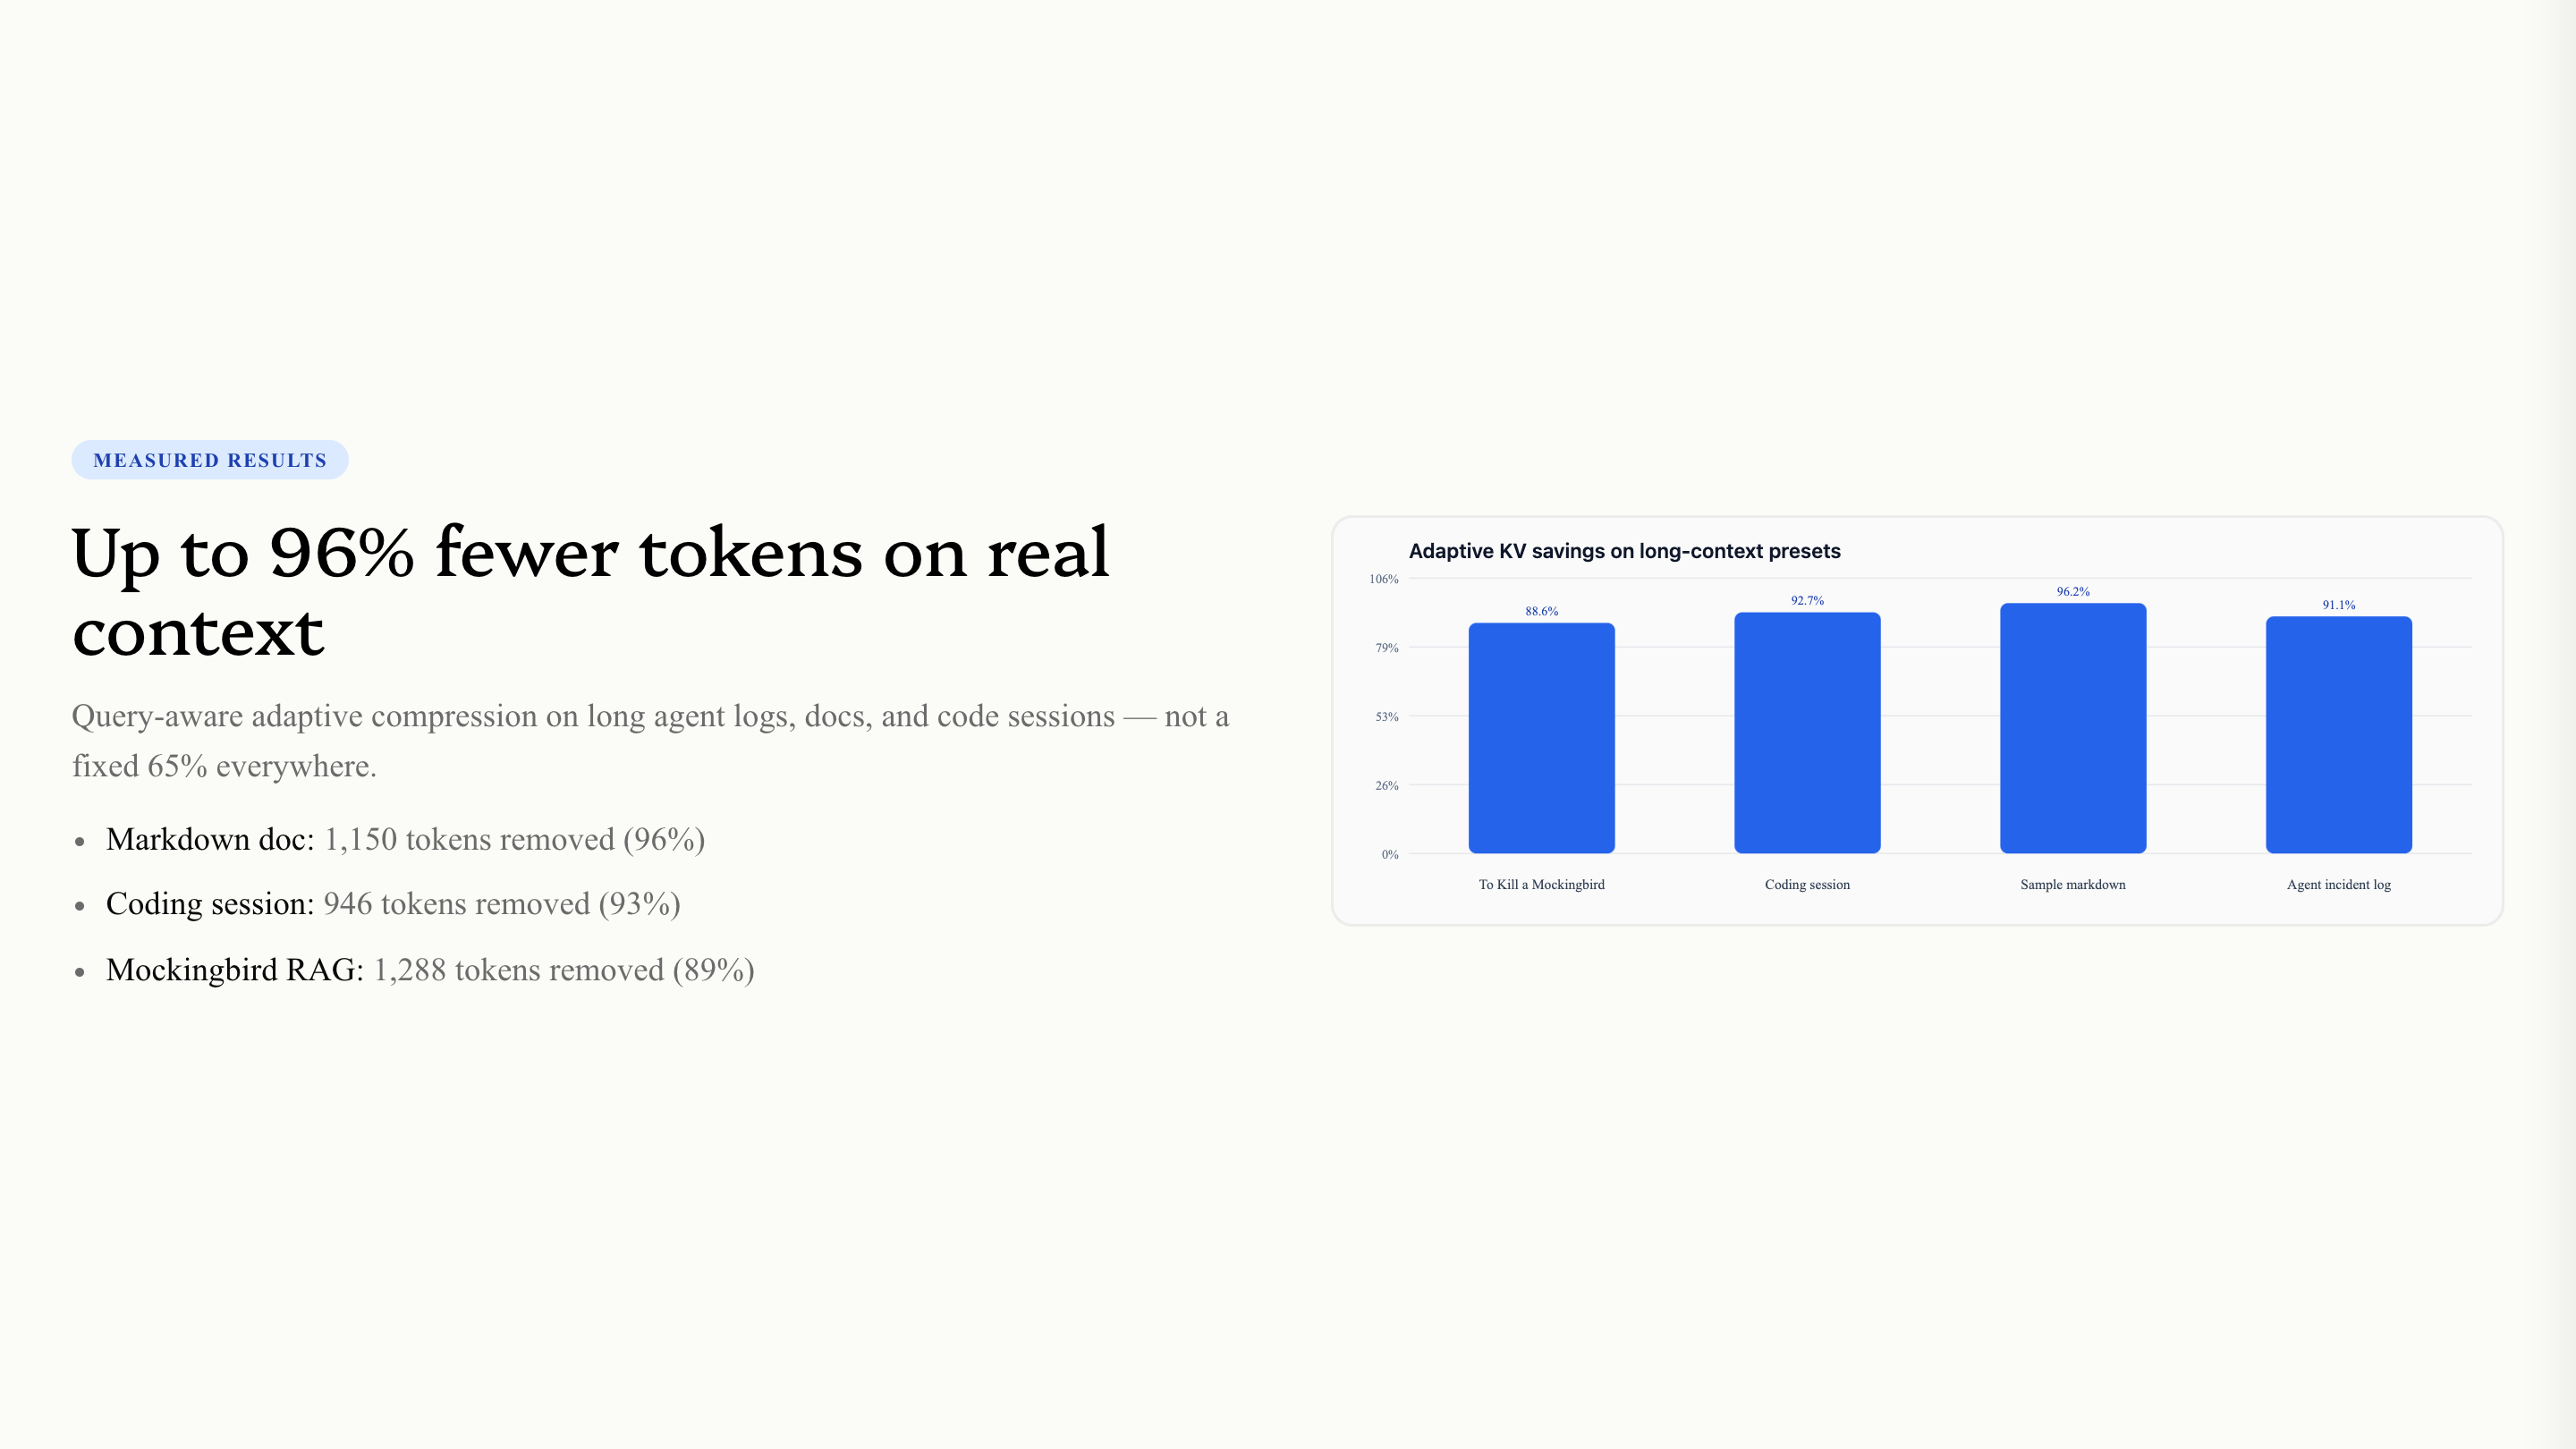
Traditional approaches (FIFO, head-tail truncation, summarization) can cut KV memory but drop to much lower oracle recall on benchmark seeds. SuperCompress reaches the same KV savings with full oracle recall—dramatically better answer quality.
Execution Plan
- Deepen integrations: Build adapters for LangChain, LlamaIndex, and other agent frameworks
- Benchmark on real production traces: Move beyond synthetic benchmarks to real-world agent workloads
- Enterprise controls & privacy: Add on-premise deployment options, SOC 2 compliance, and fine-grained audit trails
- Developer distribution: Grow the open-source community, create documentation, examples, and templates
- Hosted API monetization: Scale the hosted API service with usage-based pricing
Evidence & Traction
- Developers have been using SuperCompress (open-source API + playground)
- Large context cuts on our coding-agent benchmark while keeping the evidence each answer needs
- Open-source project with a public GitHub repository, live playground, and production API
- Production-ready: Includes an API, open-source package, live dashboard, and integrations
Founder Story
SuperCompress was founded by Arjun Shah, a 9th-grade freshman at St. Francis High School in California. He built this project to solve a real problem he identified while working with AI agents: they waste enormous amounts of compute processing irrelevant context. His mission is to make AI inference and context handling substantially more efficient—one token at a time.

Log in or sign up for Devpost to join the conversation.