-
-
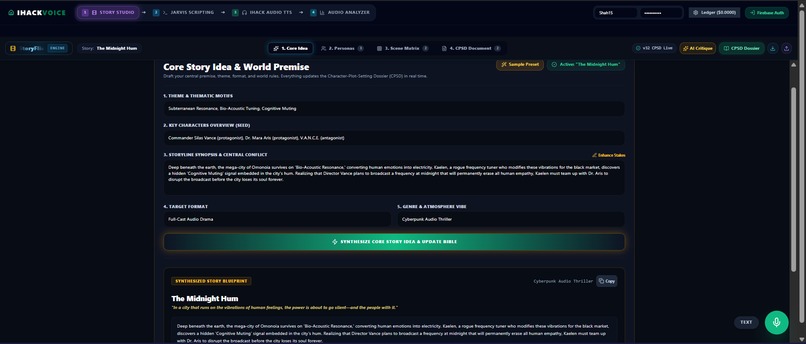
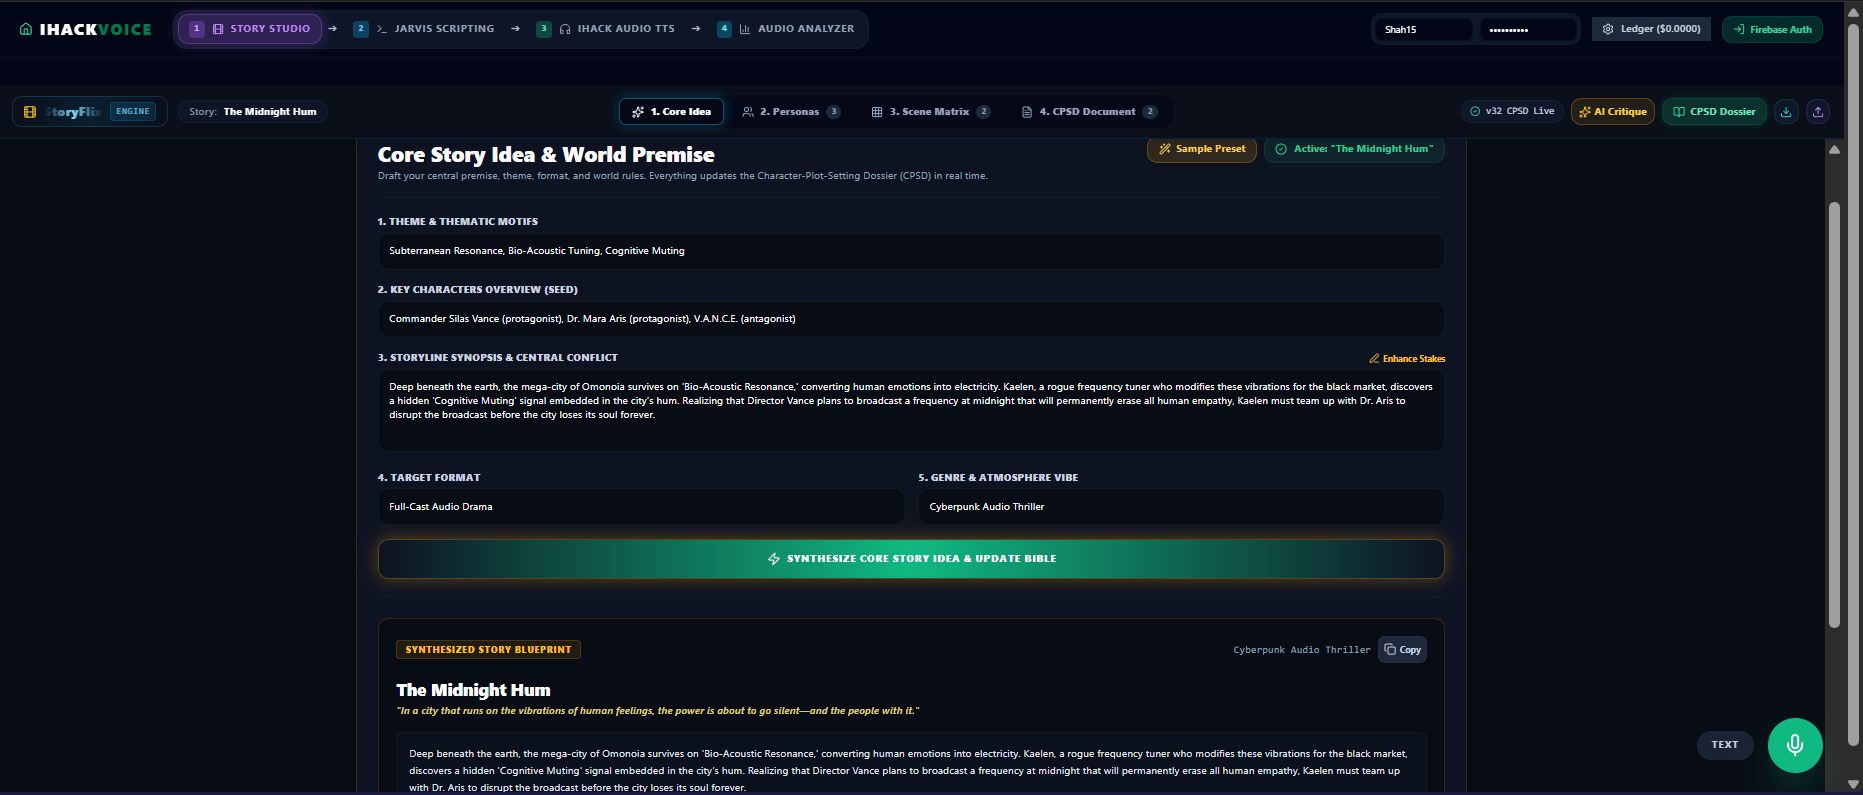
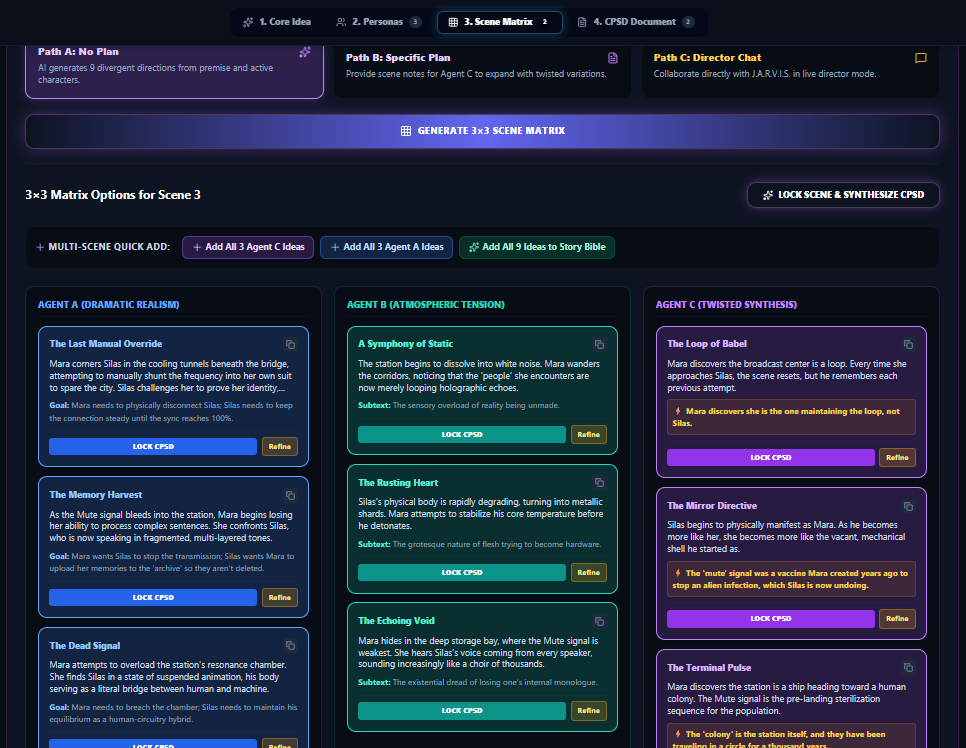
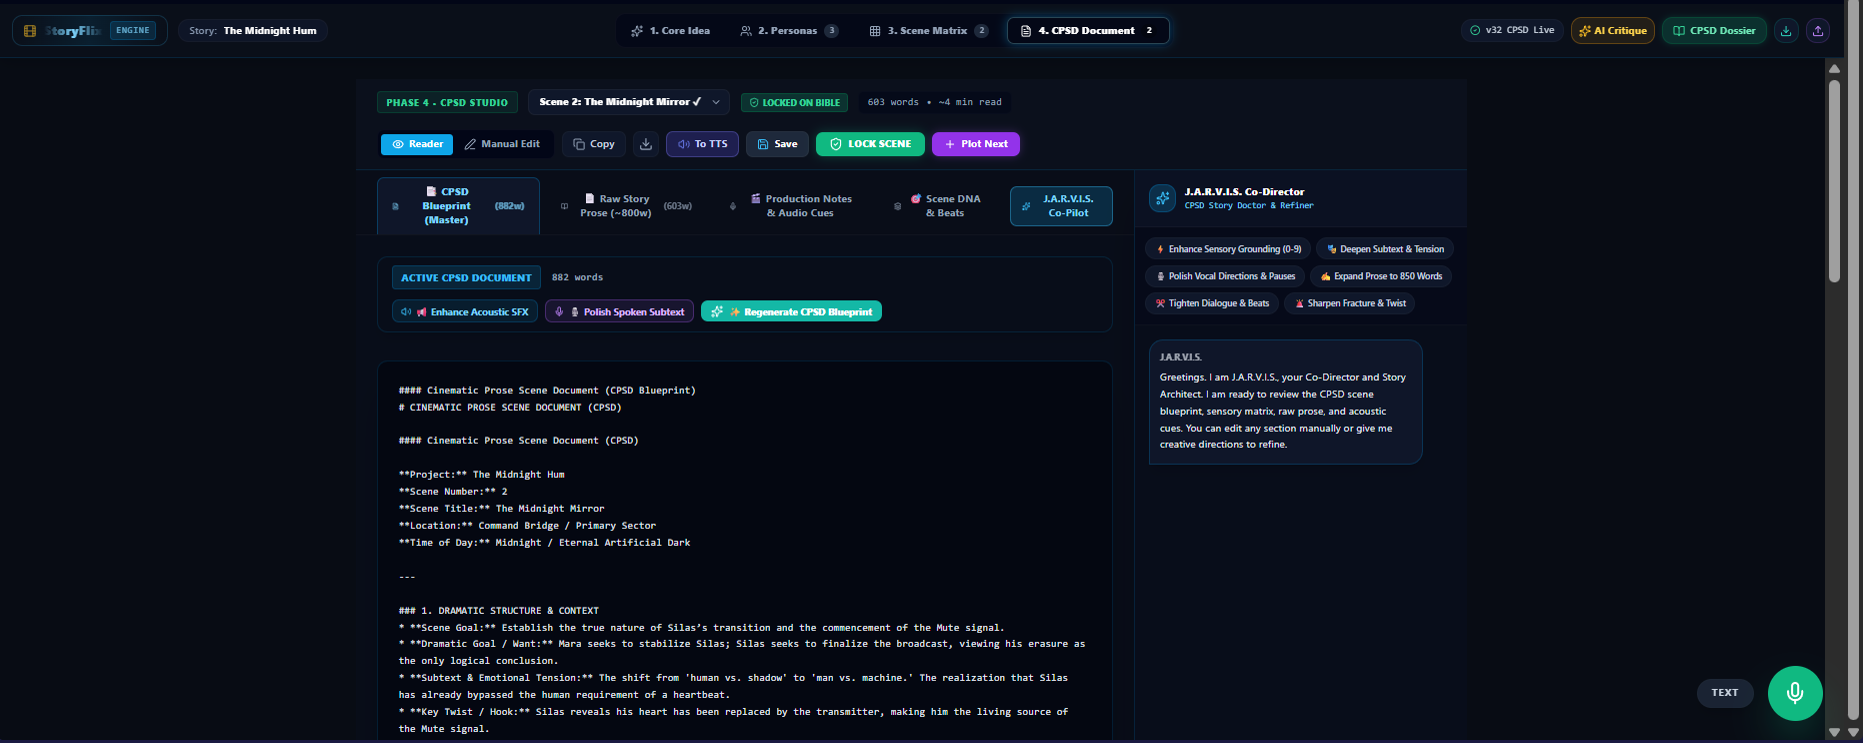
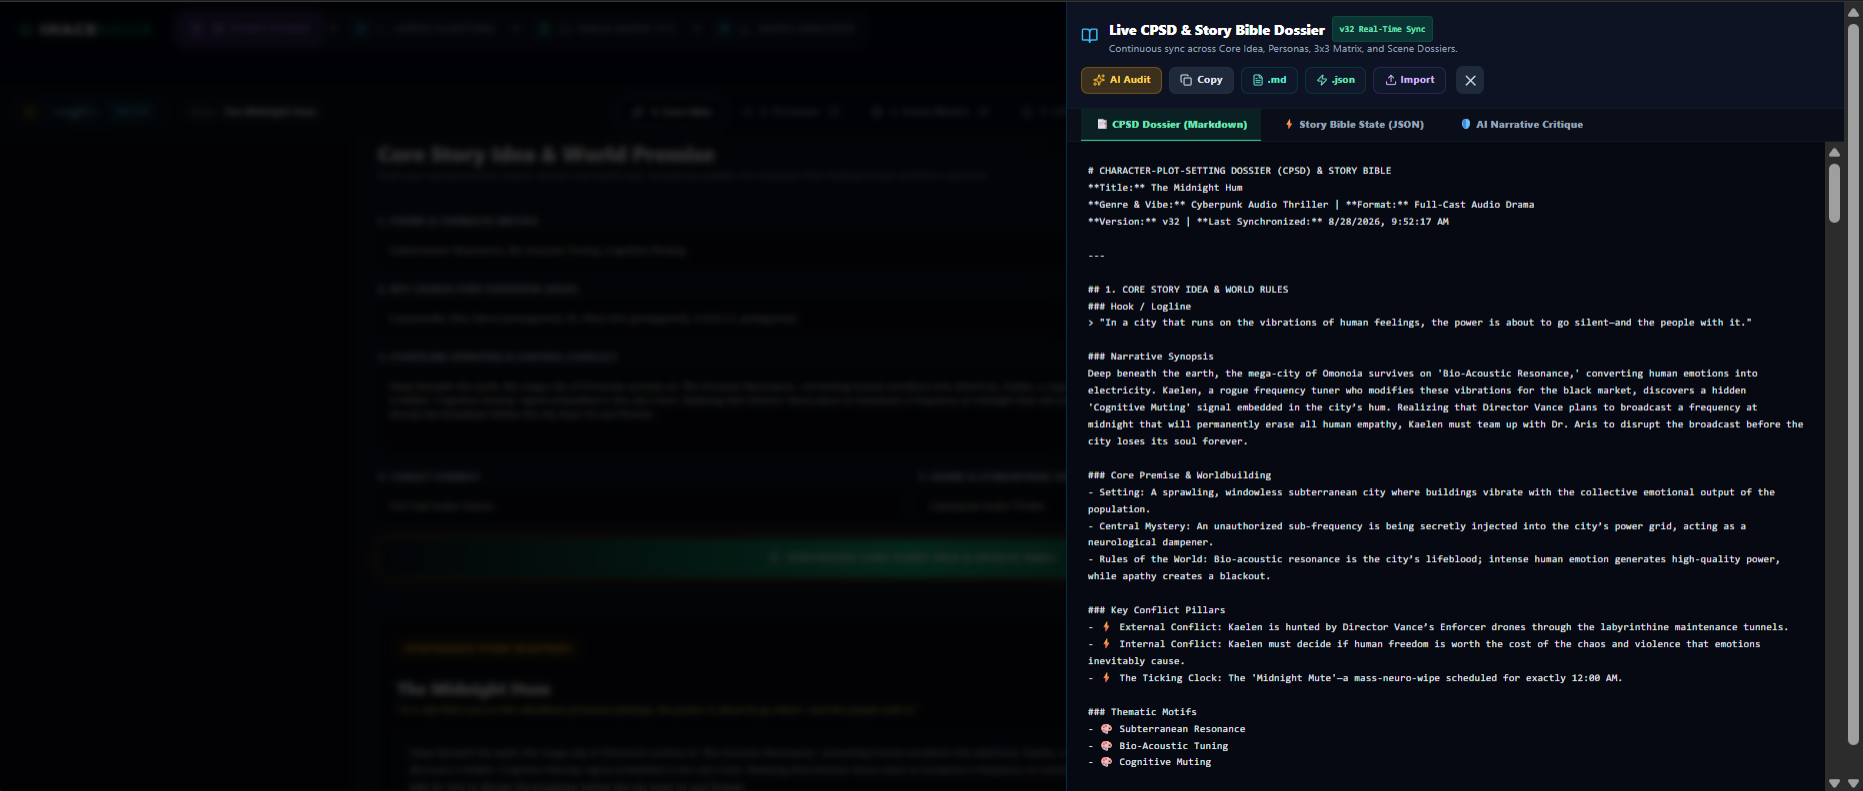
Storyflix
-
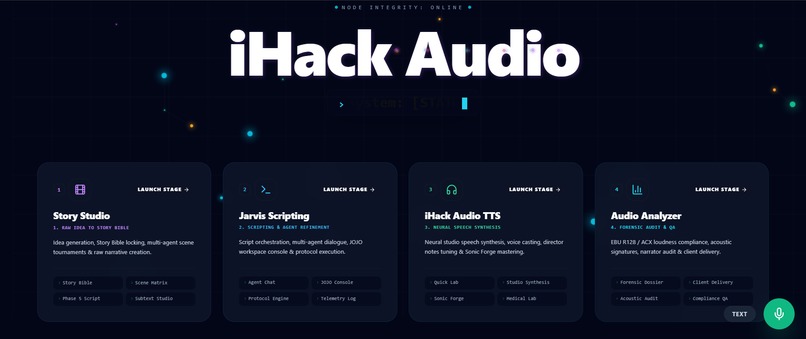
Homepage
-
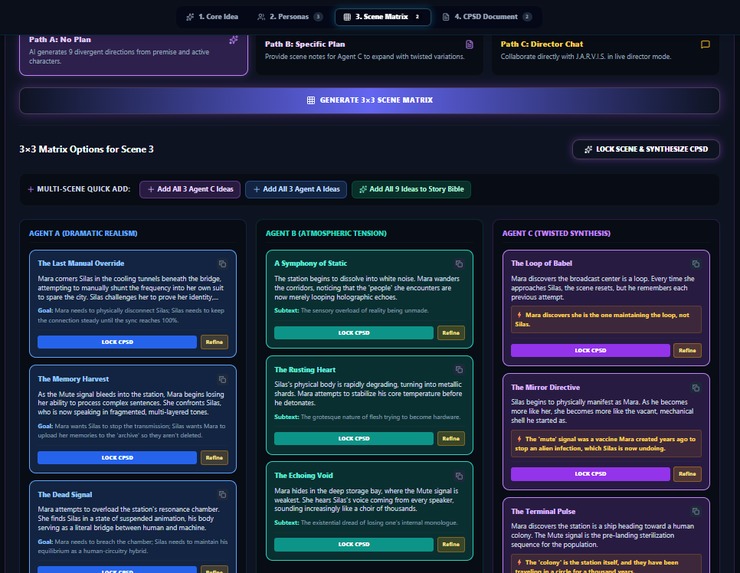
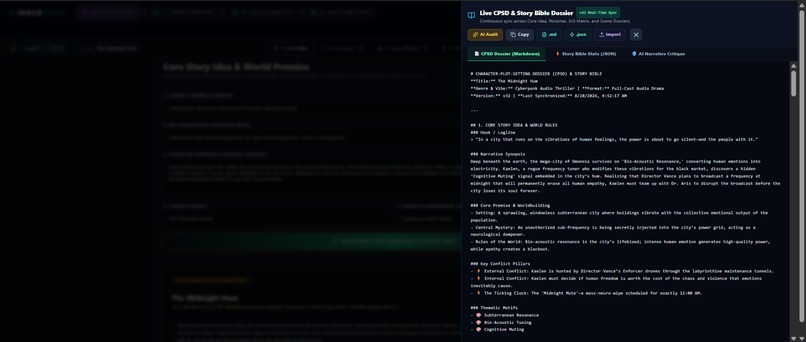
Scene matrix
-
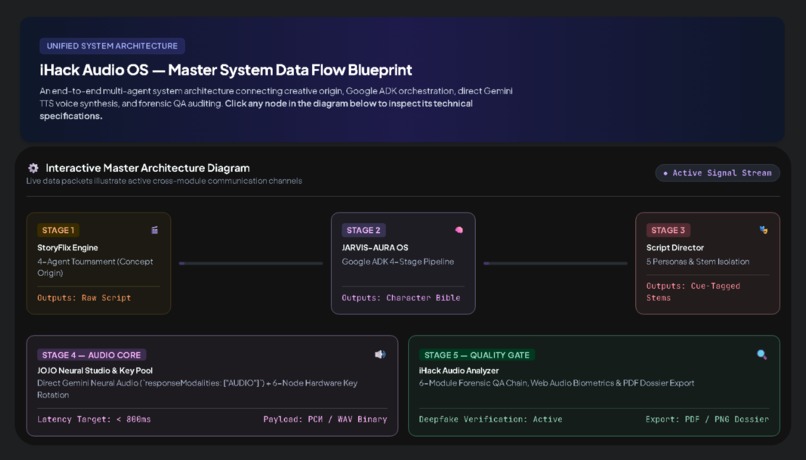
-
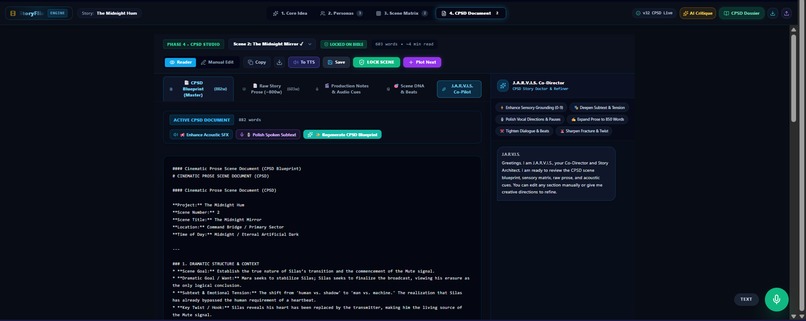
CPSD
-
-
-
-
-
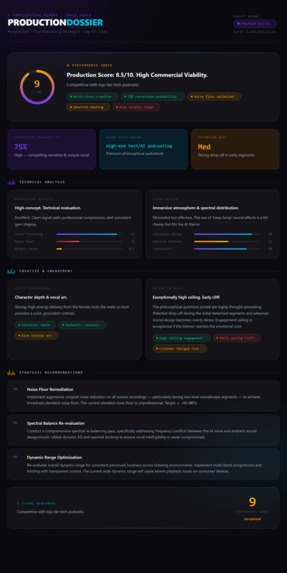
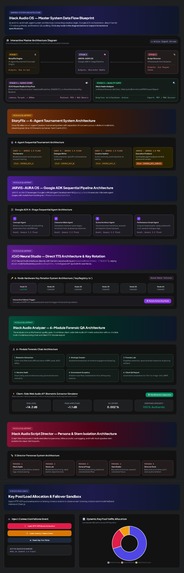
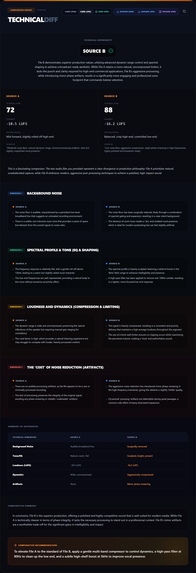
Audio Analyzer
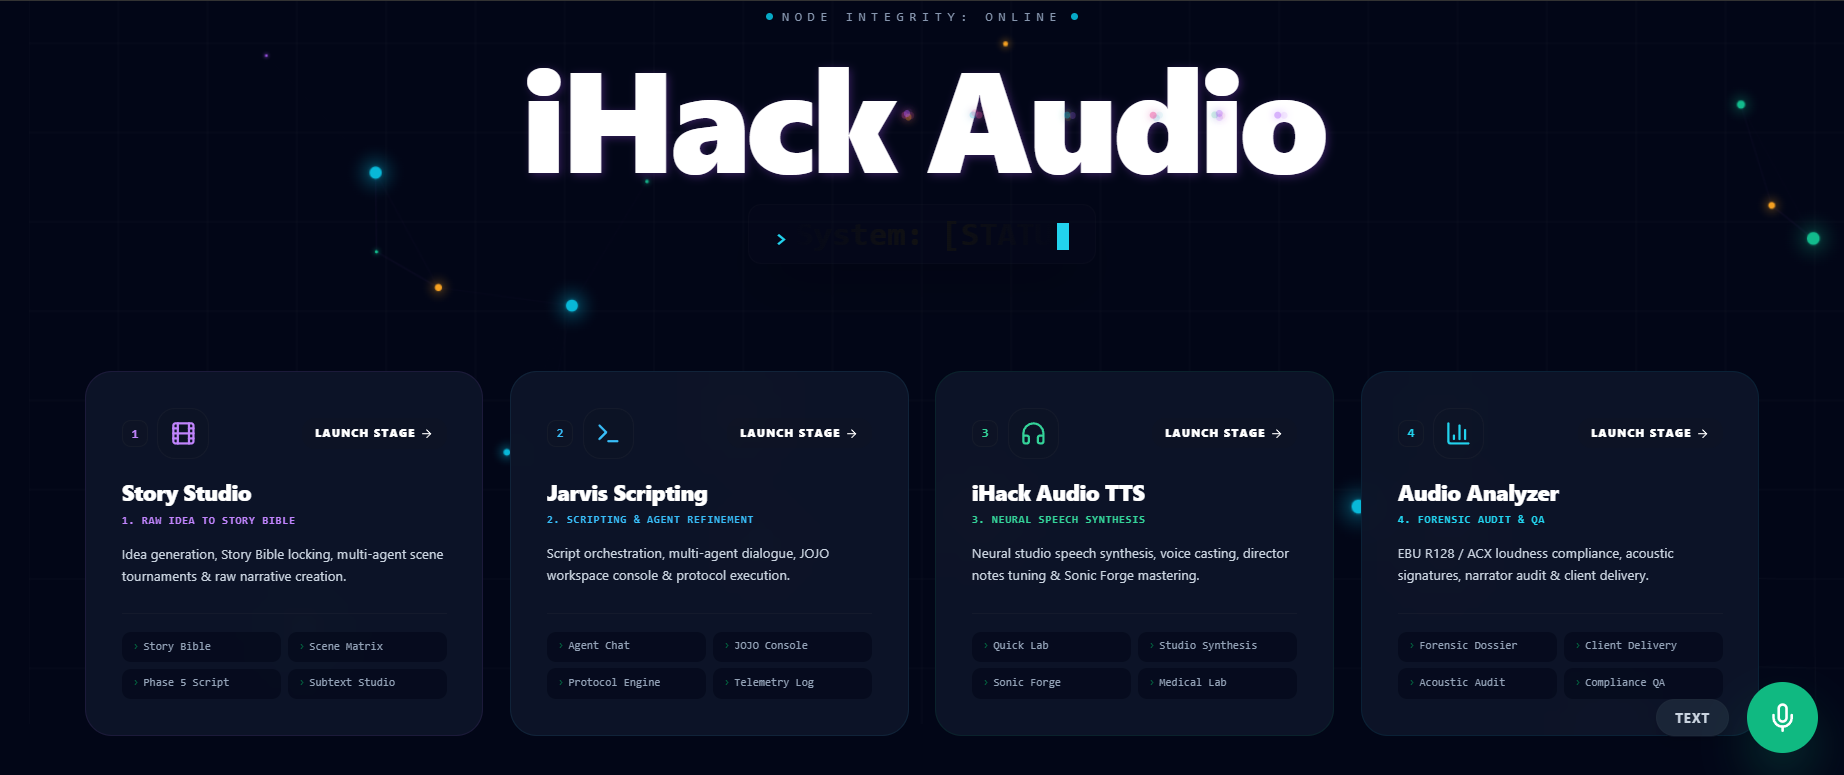
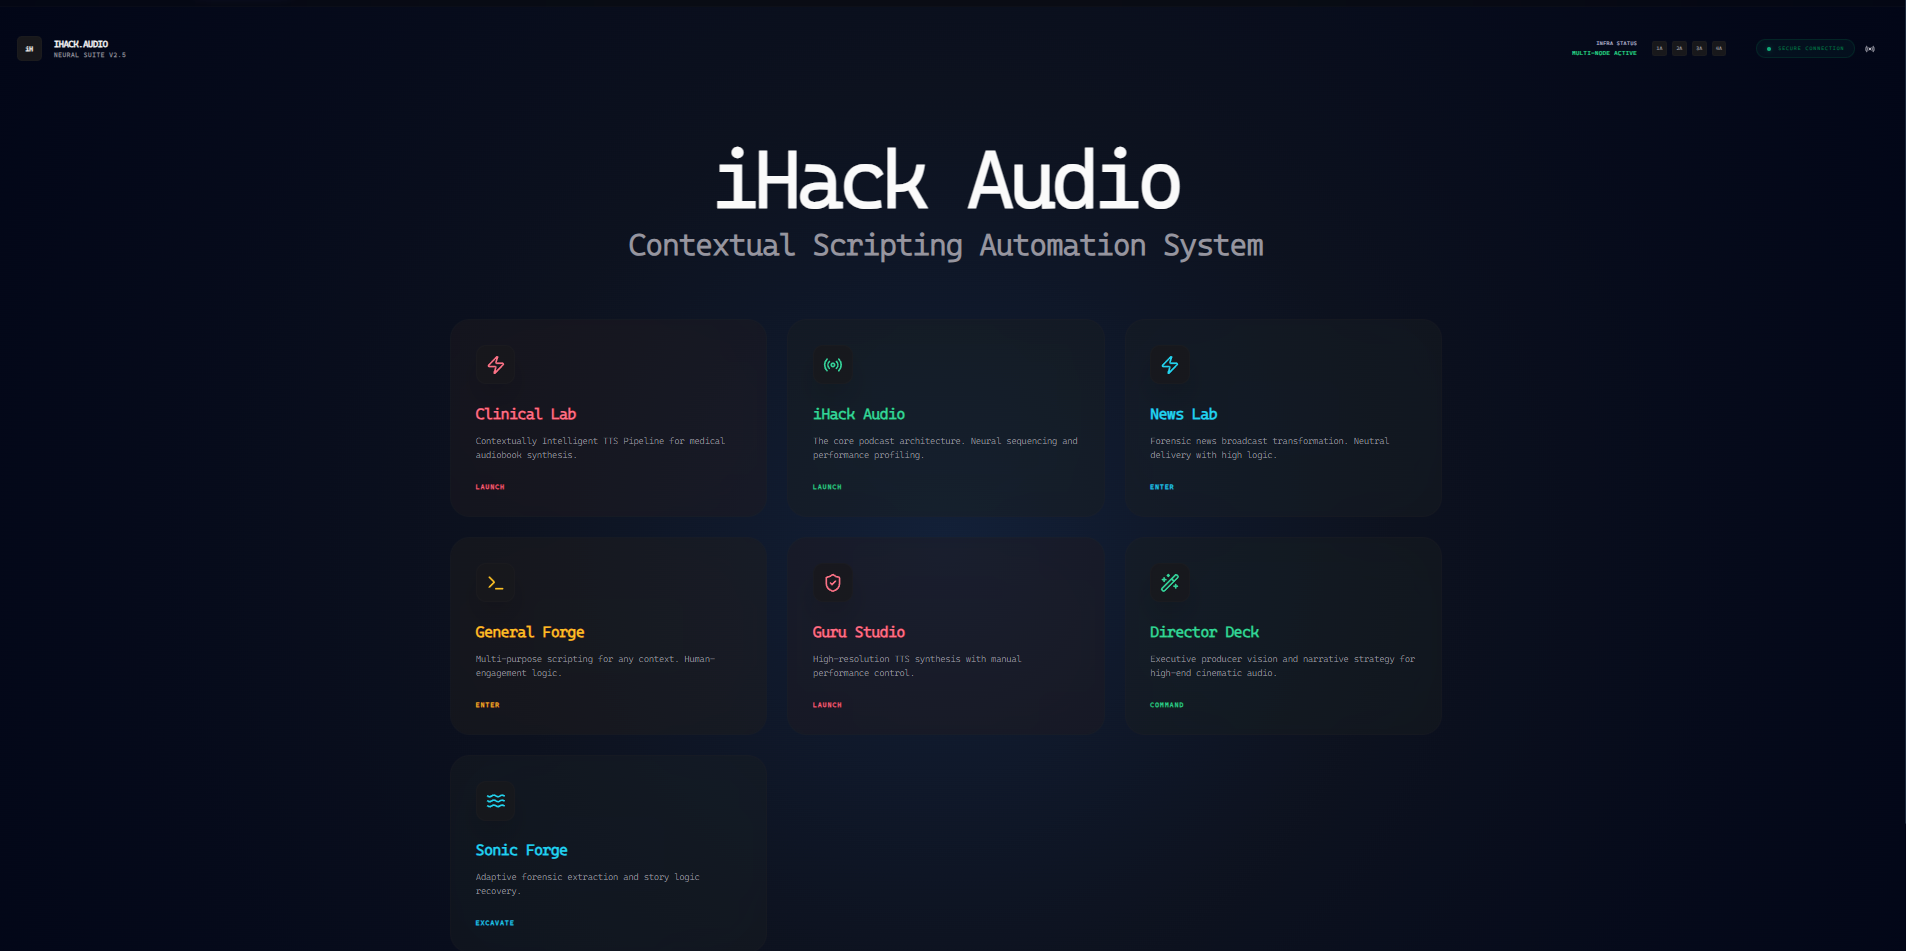
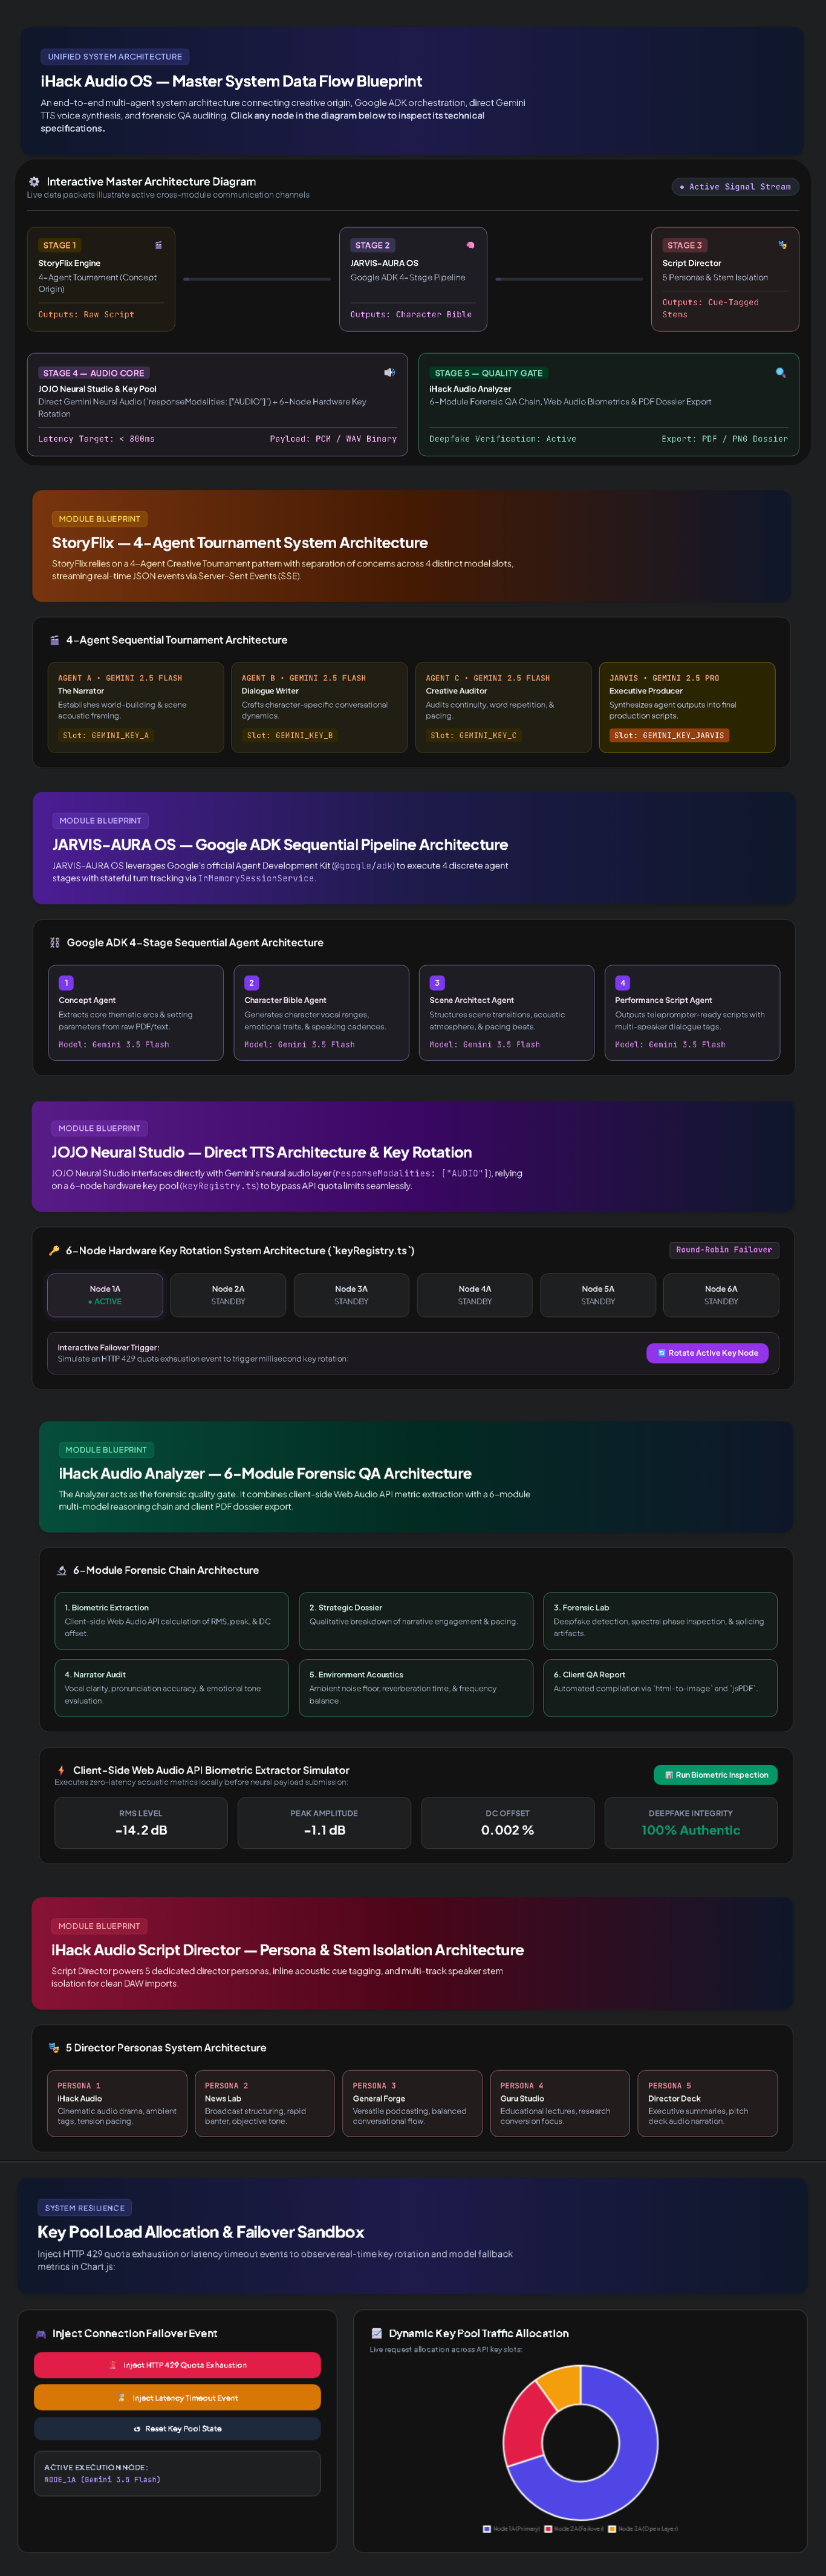
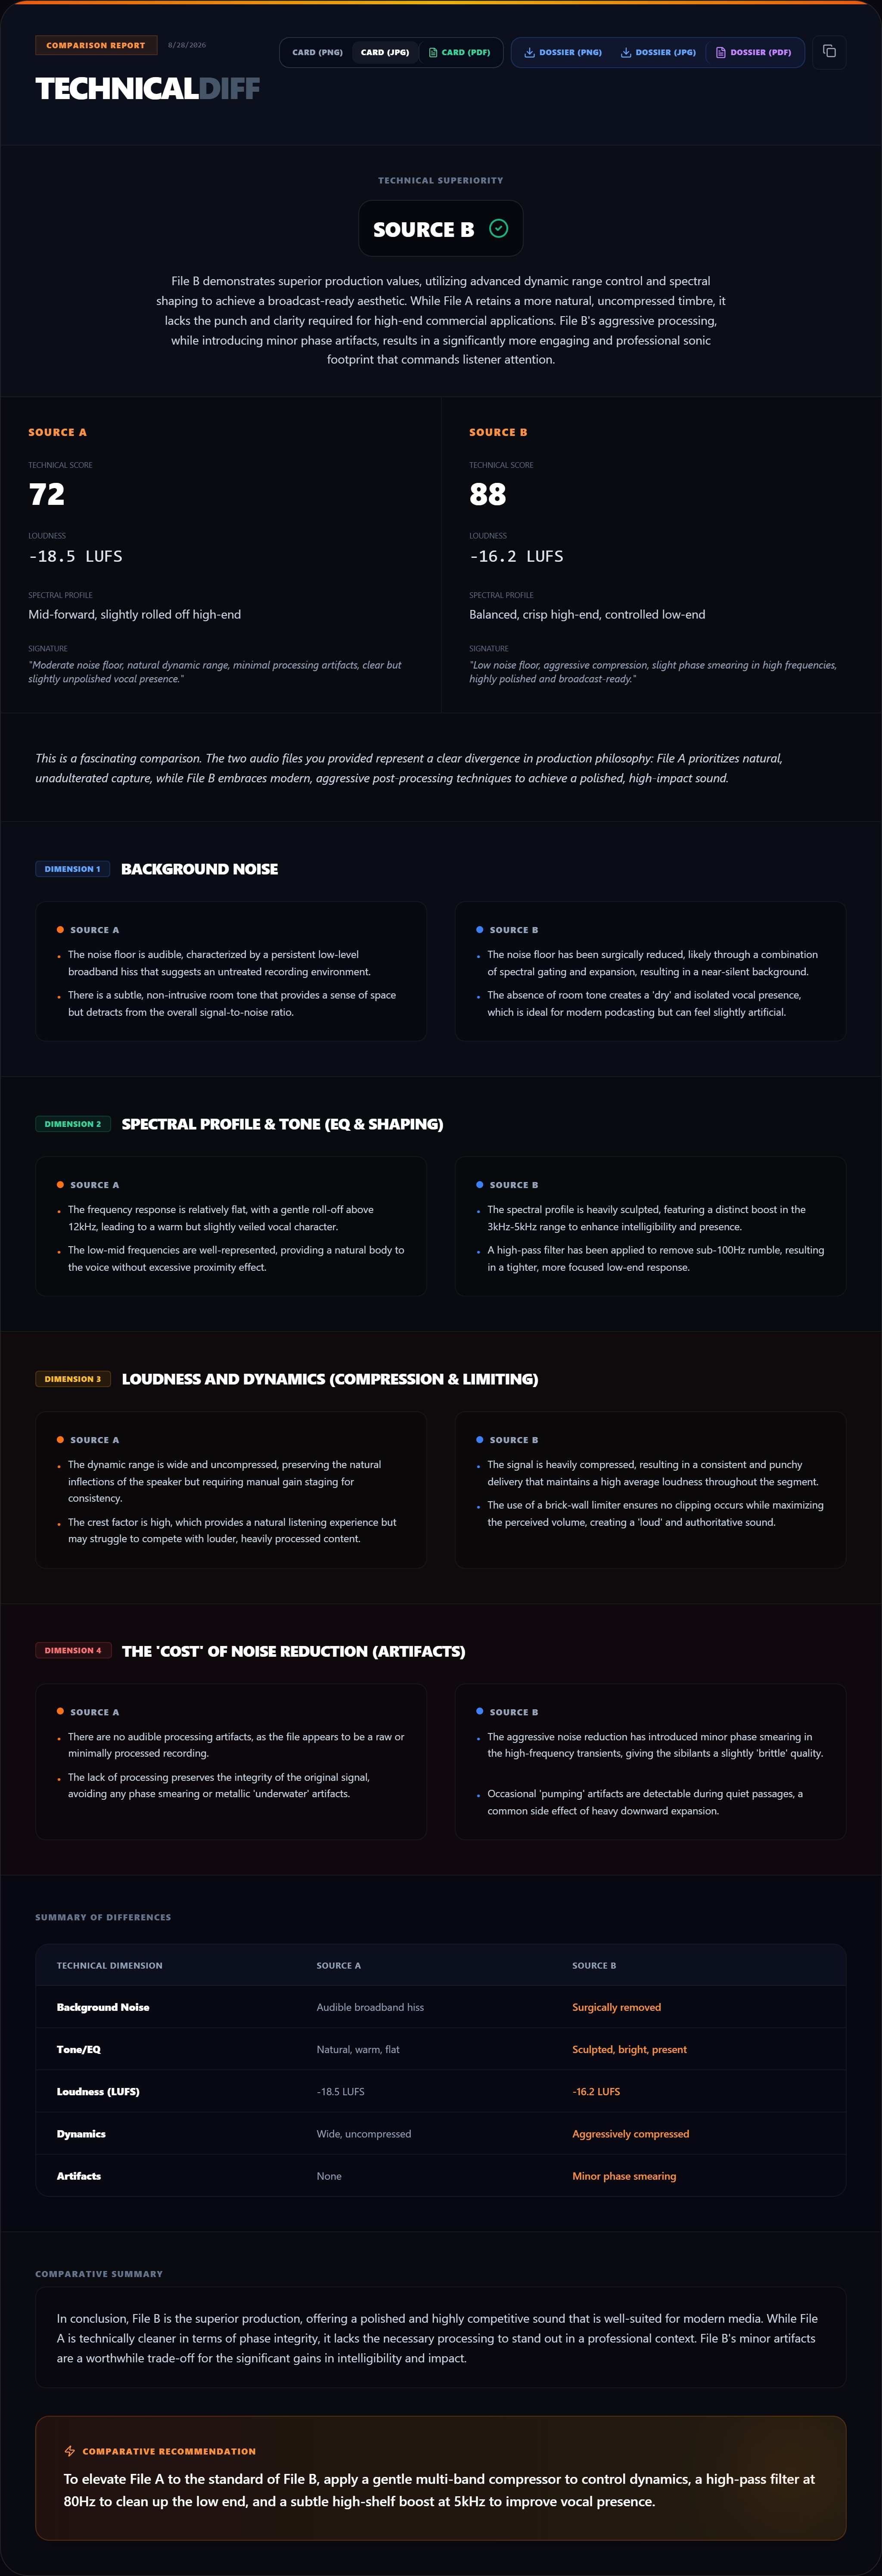

iHack Audio OS
Autonomous AI Publishing Pipeline — Taskmaster Track Shahnam Jilan | iHack Audio | Dhaka, Bangladesh Top Rated Upwork Contractor — 900+ hours | Apple Podcasts Publisher | Google Developer Program Member
The Problem
Traditional audiobook and podcast production is slow and expensive. A single narrator for a full-length book requires weeks of studio time and costs thousands of dollars—a figure that multiplies rapidly the moment a project demands multiple distinct character voices rather than a single flat narration.
Existing AI voice tools solve the cost barrier but introduce a critical quality and trust deficit:
- The Emotion & Consistency Deficit: Off-the-shelf text-to-speech produces flat, mechanical narration. Worse, long-form models suffer from context amnesia—hallucinating plot points and losing character vocal identity mid-chapter.
- The Missing QA Loop: Traditional tools offer zero automated quality control, allowing phonetic errors, spectral anomalies, and compliance failures (LUFS/noise floor) to ship directly into final release files.
By 2035, the global audio and podcast market is projected to cross $135 Billion—yet trust in autonomous AI audio production remains low. The industry does not have a voice model realism problem; it has a model orchestration and control problem.
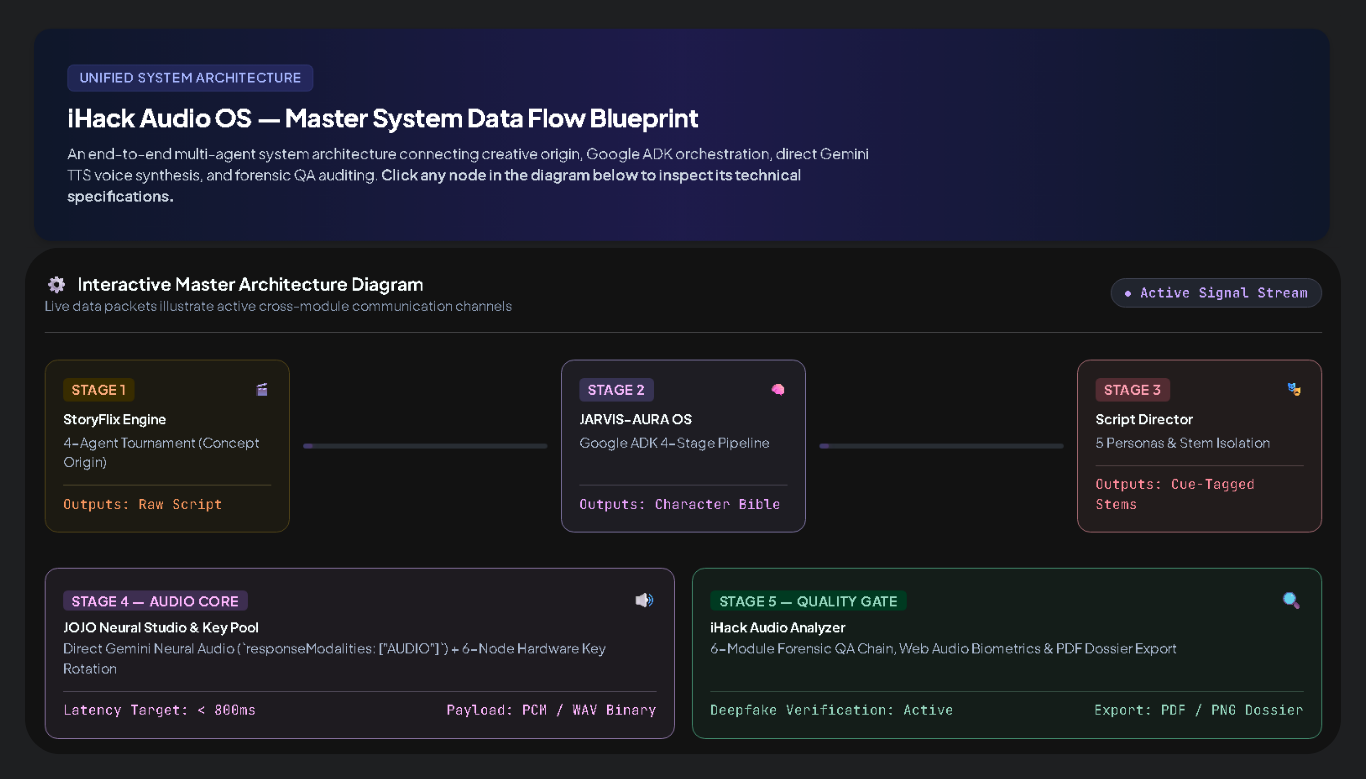
iHack Audio OS was built to eliminate this friction entirely. It is a 7-stage autonomous pipeline that scripts, voices, forensically verifies, visualizes, and distributes broadcast-grade audio end-to-end—keeping a human in the loop only where high-level creative judgment matters, executed entirely on a $0 infrastructure budget using free-tier APIs.
What I Built
Two standalone autonomous pipelines. Both built on Google's AI ecosystem. Both produce real, broadcast-ready output from a single concept input.
System 1 — iHack Audio OS
Concept → Published Audiobook
RAW CONCEPT
    │
    ▼
[Stage 1] STORYFLIX ──────────── Story generation, 4-agent creative tournament
    │
    ▼
[Stage 2] JARVIS SCRIPTING ─────── Script orchestration, Glass Box observability
    │
    ▼
[Stage 3] NEURAL STUDIO ─── Native Gemini TTS, 6-node key pool
    │
    ▼
[Stage 4]  AUDIO ANALYZER ─ Forensic QA, LUFS compliance, deepfake detection
    │
    ▼
PUBLISHED AUDIOBOOK
Stage 1 — StoryFlix | Story Generation Engine
Transforms a bare concept into a publication-ready audio drama script. No manuscript required. The system originates content — it does not just process it.
Core Capabilities
- 4-Agent Creative Tournament — Agent A (Narrator), Agent B (Dialogue Writer), Agent C (Auditor), JARVIS (Executive Producer) execute sequentially via Google ADK SequentialAgent
- Agent-Isolated Key Slot Architecture — dedicated API key per agent with automatic rotation and silent failover on rate limits
- Multi-Model Fallback Chain — Gemini 2.5 Flash → 2.5 Pro → 3.1 Flash Lite, cascades without breaking the pipeline
- Multimodal Input — accepts PDF manuscripts via Base64 inline processing; bare concept also accepted
- Real-Time Streaming — agent outputs stream live to React frontend via Express API
Tech Stack: Google ADK SequentialAgent · GenAI SDK v1.29.0 · Gemini 2.5 Flash / 2.5 Pro · Cloud Run · Express.js · React
Stage 2 — JARVIS-AURA SCRIPTING | Script Orchestration Core
Converts story bible into a performance-ready TTS script with character bibles, vocal profiles, and phonetic pronunciation guides. Full agent reasoning visible at every step.
Core Capabilities
- 4-Stage ADK Sequential Pipeline — Concept Agent → Character Bible Creator → Scene Breakdown Architect → JARVIS Lead Script Writer
- Glass Box Observability — full agent thought traces stream live via WebSocket and SSE (
thinking → working → idle) - Native Function Calling —
parse_pdf_manuscript,verify_pronunciation,count_script_tokens,generate_teleprompter_view - CSIP Guard Protocol — prevents agent loop failure and hallucination at pipeline scale
- Multi-Protocol Support — five execution protocols for different production modes
- Scored 10/10 on live medical audiobook content audit
Tech Stack: Google ADK · GenAI SDK v2.0+ · Gemini 3.5 Flash (primary) · Gemma 4 31B (fallback) · Cloud Run · WebSocket + SSE
Stage 3 — Neural Studio | Podcast Automation & TTS Synthesis Engine
Native Gemini TTS synthesis with zero third-party voice APIs. Dual-speaker audio generated directly from script. Zero synthesis downtime across production runs.
Core Capabilities
- Native Gemini TTS — direct audio via
responseModalities: ["AUDIO"] - 6-Node Neural Key Pool —
keyRegistry.tswith hardware node aliases 1A–6A, round-robin rotation on HTTP 429 in milliseconds - Solo & Duo Production Modes — single narrator and dual-speaker dialogue with customizable voice profiles (Puck, Charon, Aoede, Fenrir, Kore)
- PCM/WAV Browser Decoding — raw binary audio decoded client-side via Web Audio API, no intermediate conversion
- Tiered Model Strategy — Flash for prototyping, Pro for mastered final output, same pipeline throughout
Tech Stack: GenAI SDK · Gemini 2.5 Pro Preview TTS · Gemini 2.5 Flash Preview TTS · Gemini 3.1 Flash TTS Preview · Web Audio API · WebSockets · React 19 + TypeScript
Stage 4 — iHack Audio Analyzer | Forensic QA & Intelligence Suite
Where every other stage generates audio, the Analyzer deconstructs it — exposing what the human ear misses and what traditional DAWs cannot measure.
The Closed Autonomous Loop: The Analyzer audited its own pipeline's hackathon podcast episode with no human in the loop. The system produced content, quality-controlled it, and delivered a client-ready compliance document autonomously.
| Metric | Result |
|---|---|
| Overall Score | 9.4/10 — Premium Broadcast Quality |
| ACX Compliance | PASS — -18.42 LUFS |
| Apple Podcasts | PASS — -18.42 LUFS |
| True Peak | -1.26 dBTP |
| Noise Floor | -62.4 dBFS |
| Vocal Clarity | 95/100 |
Core Capabilities
- 6-Module Automated Pipeline — Biometric Extraction → Strategic Dossier → Forensic Lab → Narrator Performance Audit → Acoustics Inspection → Client QA Report
- Deepfake & Tampering Detection — synthetic artifacts, spliced edits, phase anomalies, linguistic continuity breaks
- Platform Compliance Matrix — ACX, Spotify, Apple Podcasts checked and reported automatically
- AI Persona Extraction — derives TTS voice personas from uploaded audio for direct handoff to JOJO Neural Studio
- Client-Ready Dossier Export — auto-converted to PNG/PDF via html-to-image and jsPDF
Tech Stack: GenAI SDK · Gemini 3.1 Flash / 2.5 Flash / 2.5 Pro · Web Audio API · html-to-image · jsPDF · Express.js
System 2 — Podcast Automation
Concept → Published Podcast Episode
Standalone autonomous workflow. One concept input triggers full script generation and dual-speaker audio production — no manual steps. Supports full automation or manual override at any stage.
RAW CONCEPT
    │
    ▼
SCRIPT GENERATION ─── System instructions + skills backend
    │
    ▼
DUAL-SPEAKER SYNTHESIS ─── Echo (Host 1) + Noise (Host 2)
    │
    ▼
PUBLISHED PODCAST EPISODE
Core Capabilities
- Concept-to-Episode Automation — input one sentence, receive a fully scripted and voiced podcast episode
- Dual-Speaker Engine — Echo and Noise, two distinct AI host personas with separate tonal profiles and delivery styles
- Three Gemini TTS Engines — Gemini 2.1 Flash (rapid), 2.5 Flash (mid-tier), 2.5 Pro Preview (mastered output)
- Skills-Based Backend — modular system instructions per production context, swappable without pipeline rebuild
- Manual Override — full automation default with per-stage manual control available
Proven Output: The hackathon podcast episode submitted as bonus content was produced entirely by this system.
Additional Tools
Script Director Neural Suite — 5 AI director personas with the proprietary Kinetic Notation System [Archetype, Intensity, Stage] ((Kinetic Action)) — turns robotic TTS into cinematic voice performance. Multi-track stem isolation for direct DAW import.
Cinema Visual Studio — FLUX.2 on Kaggle free-tier GPU. Seed-locked character registry for cross-panel consistency. Generated a 26-panel Sherlock Holmes storyboard from StoryFlix output in under 6 minutes at 12.8s per panel average.
YouTube Automation — Vertex AI Express Mode thumbnails, automated OAuth upload, burned subtitles, SRT captions, archive management. Pipeline ends with a monetization-ready published video.
Technical Compliance
| Requirement | Status |
|---|---|
| Gemini 3.5 or newer | ✅ Gemini 3.5 Flash (primary) + 2.5 Pro / 2.5 Flash |
| Google Agent Framework | ✅ Google ADK + GenAI SDK |
| Google Cloud Service | ✅ Cloud Run (live deployment) |
| Vertex AI | ✅ Express Mode — YouTube thumbnail generation |
| New build Aug 3–31 | ✅ Orchestration layer built during submission window |
| Prior work disclosed | ✅ All pipeline stages disclosed as dependencies |
Bonus: Podcast episode published on Apple Podcasts · Social post with #AllThingsAgenticHackathon
Built On Zero
Google Cloud Run free tier · Gemini API free tier · Kaggle GPU free tier · Groq free tier.
The constraint was the design brief. Near-zero cost. Maximum quality output. This system works for every independent creator, educator, and publisher in the world who cannot afford a production team.
Solo builder. Zero dollars. Bangladesh. This is what agentic AI looks like when it's built for craft.
Built With
- express.js
- fastapi
- flux.2
- framer-motion
- gemini-2.5-flash
- gemini-2.5-pro
- gemini-3.5-flash
- gemini-tts
- google-adk
- google-cloud-run
- google-genai-sdk
- gradio
- groq
- html-to-image
- jspdf
- kaggle-gpu
- node.js
- python
- react-19
- tailwind-css
- typescript
- vertex-ai-express-mode
- web-audio-api
- websocket

Log in or sign up for Devpost to join the conversation.