-
-
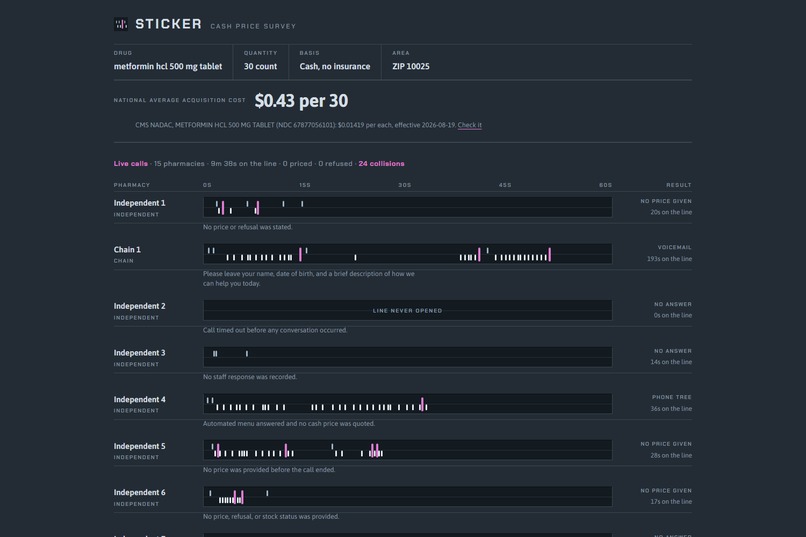
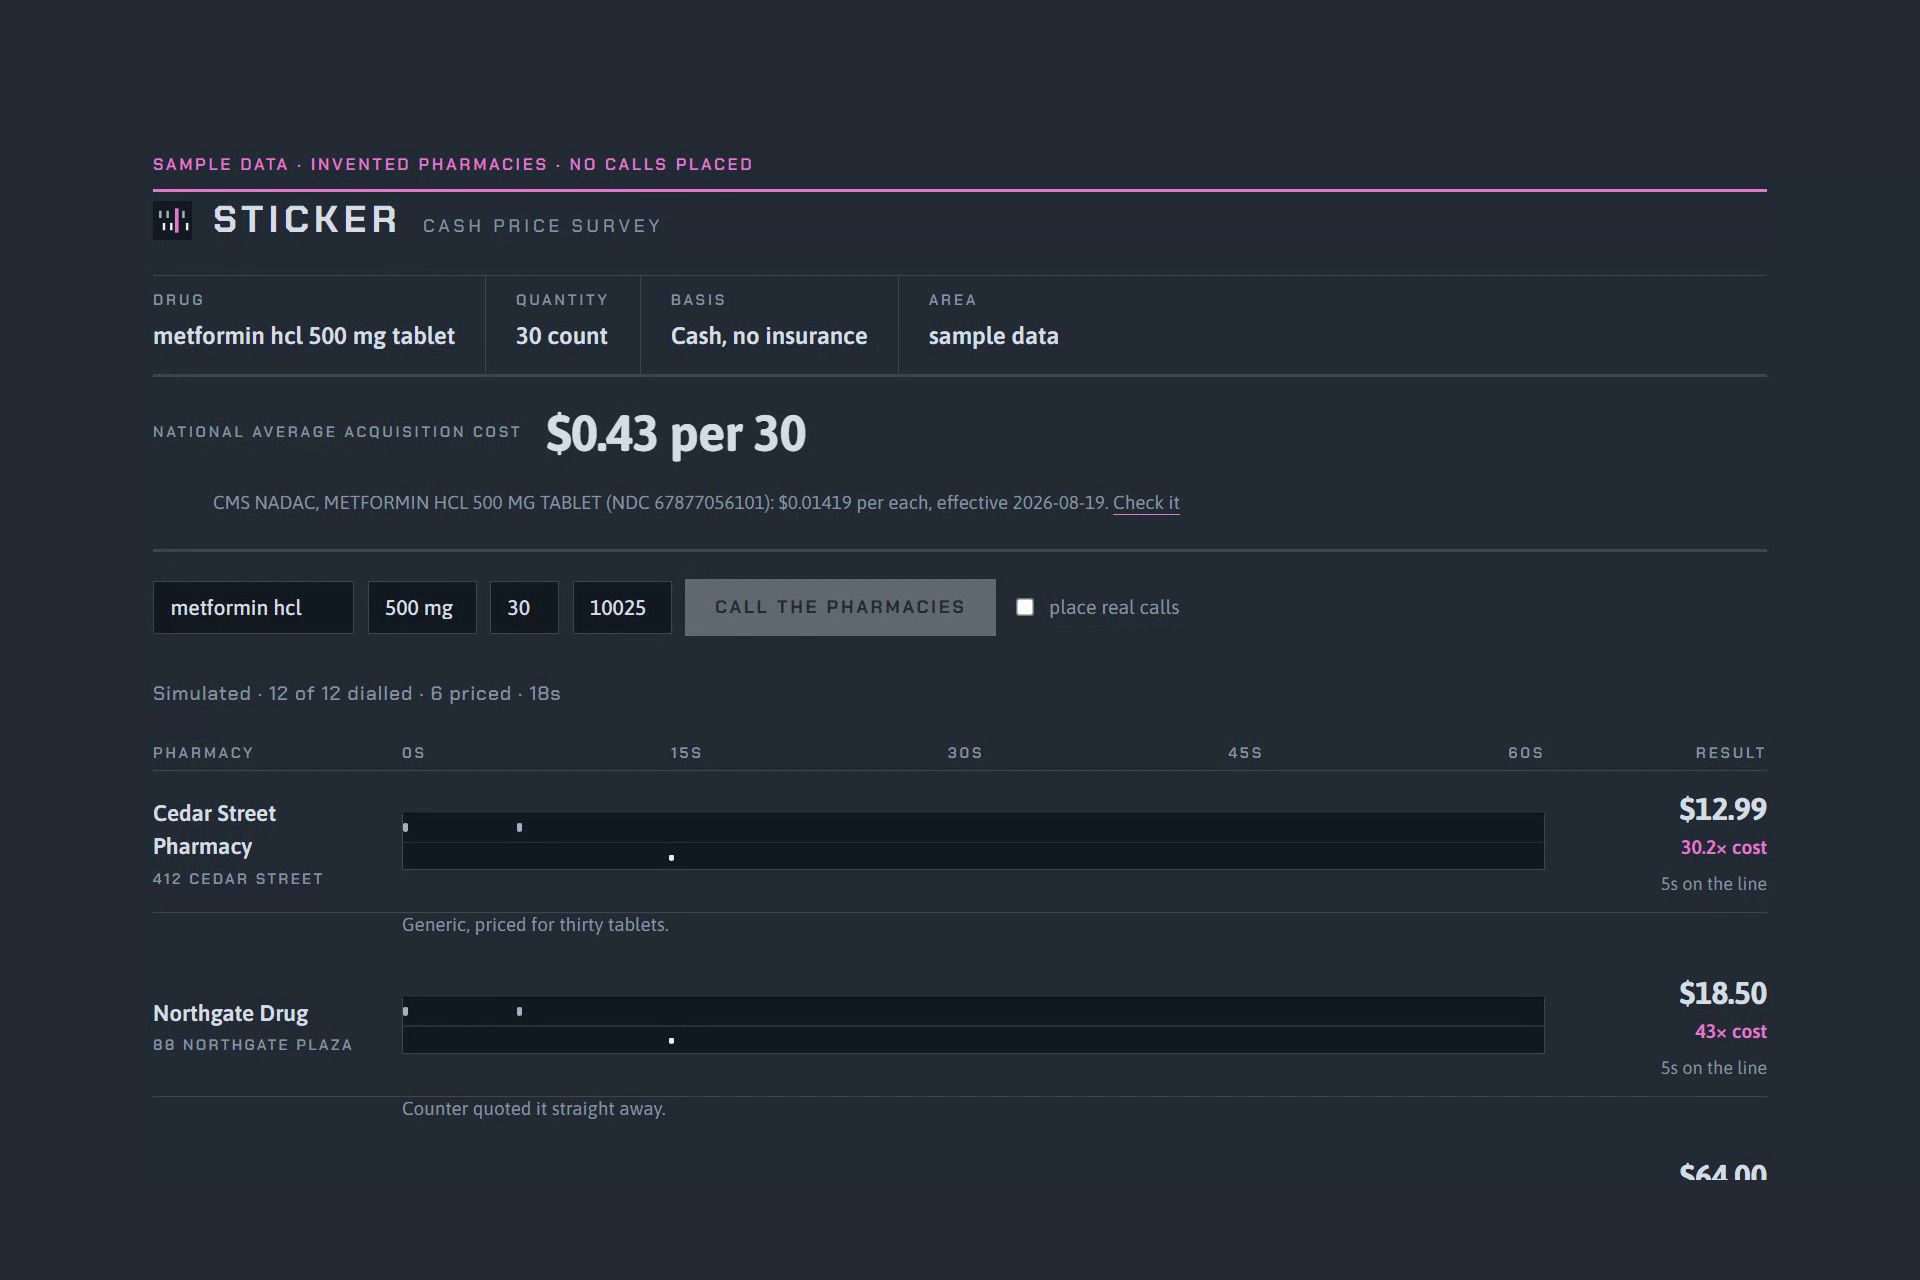
Sticker phones pharmacies for a prescription's cash price. The benchmark is CMS NADAC: 43 cents for thirty metformin, cited.
-
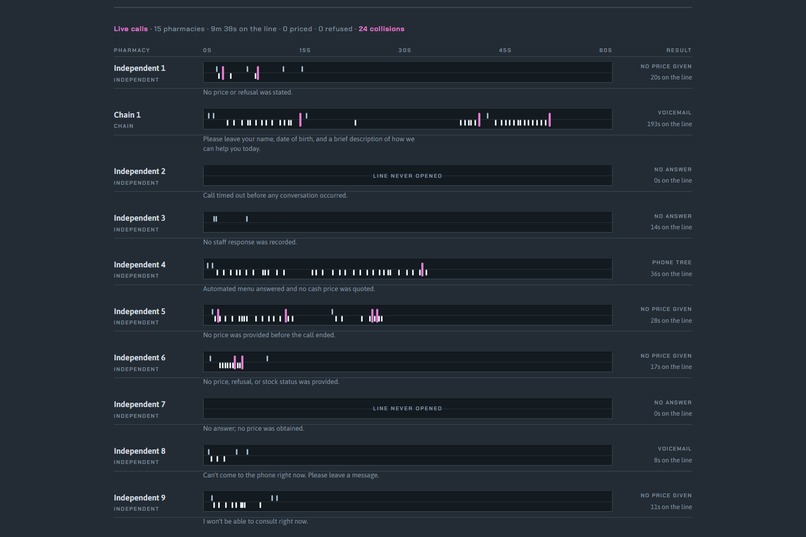
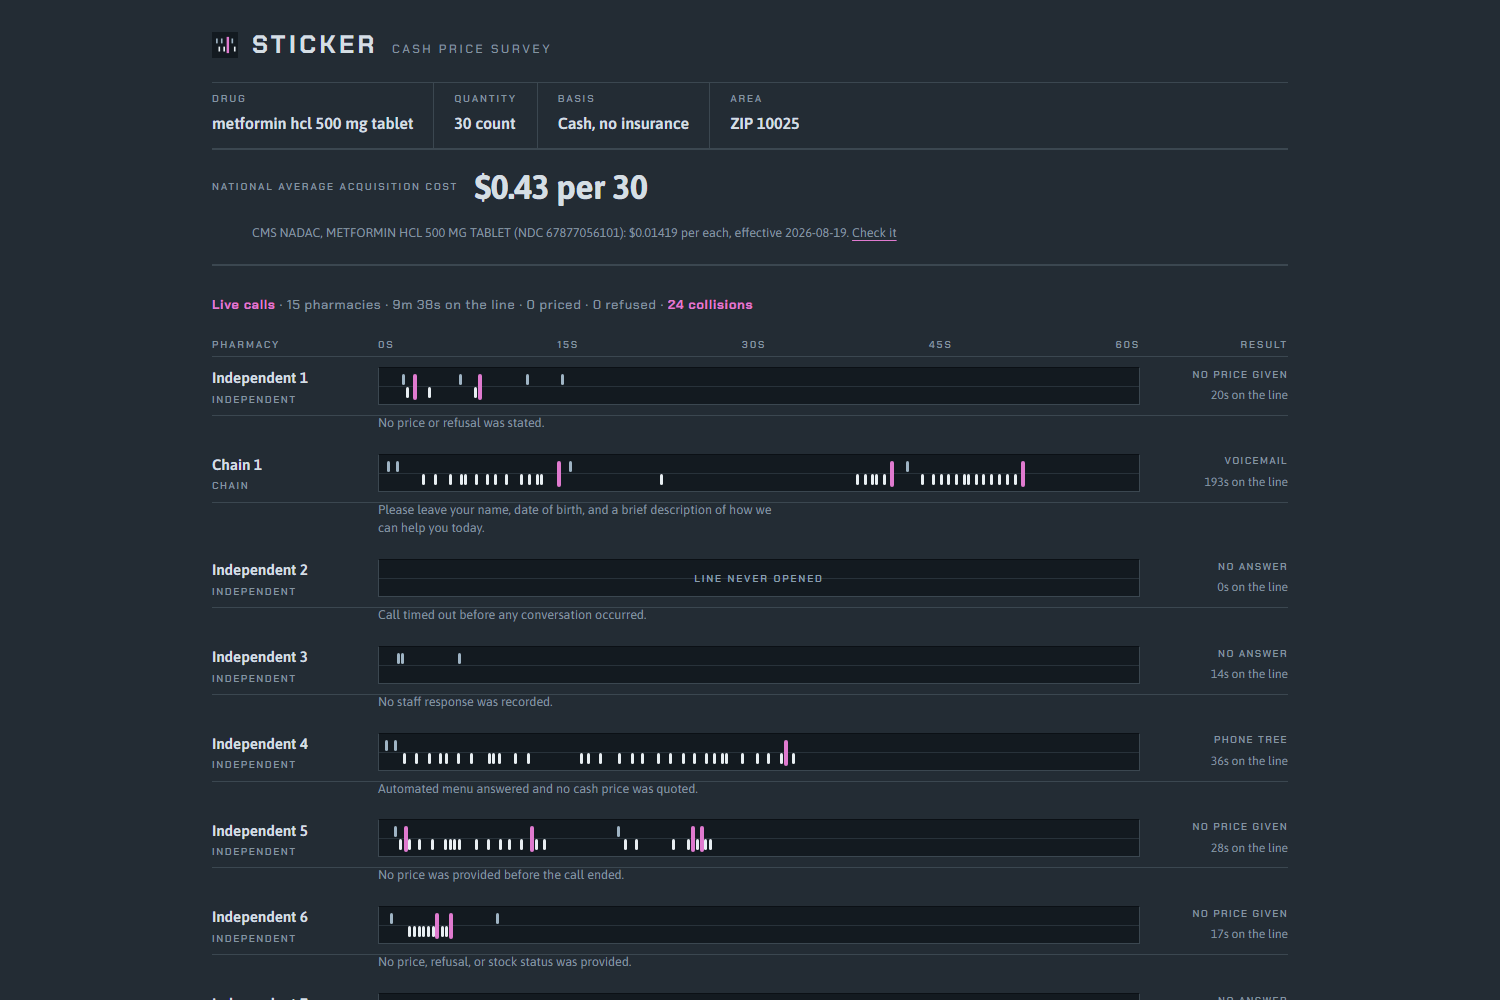
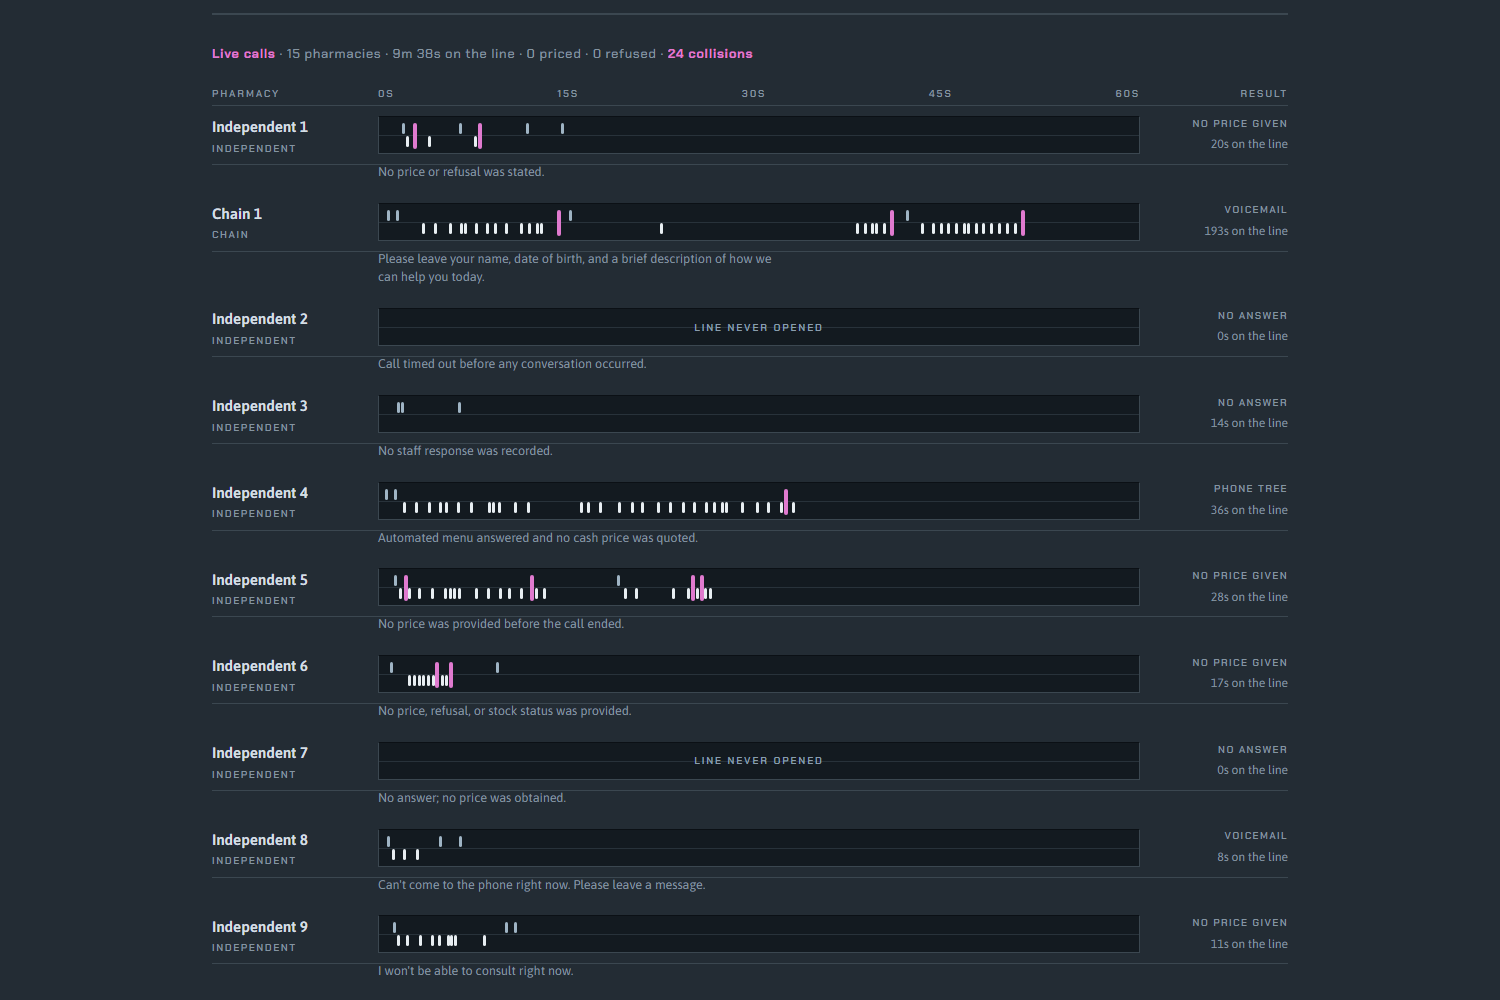
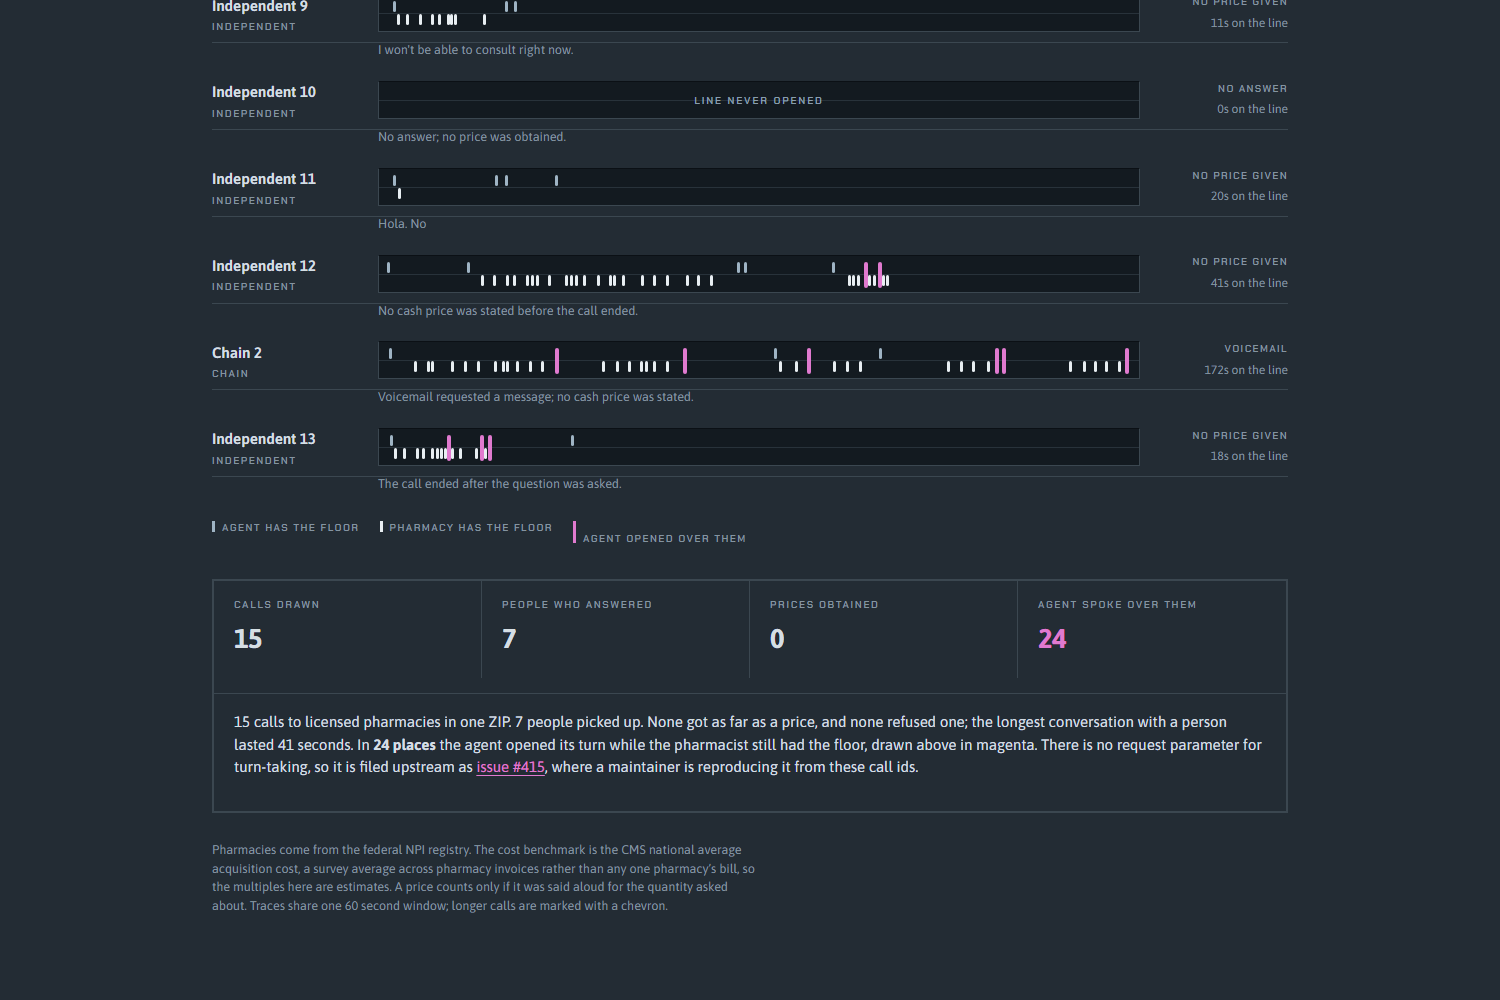
Fifteen real calls drawn as two-channel traces over 60 seconds. Magenta is the agent opening its turn while the pharmacist still speaks.
-
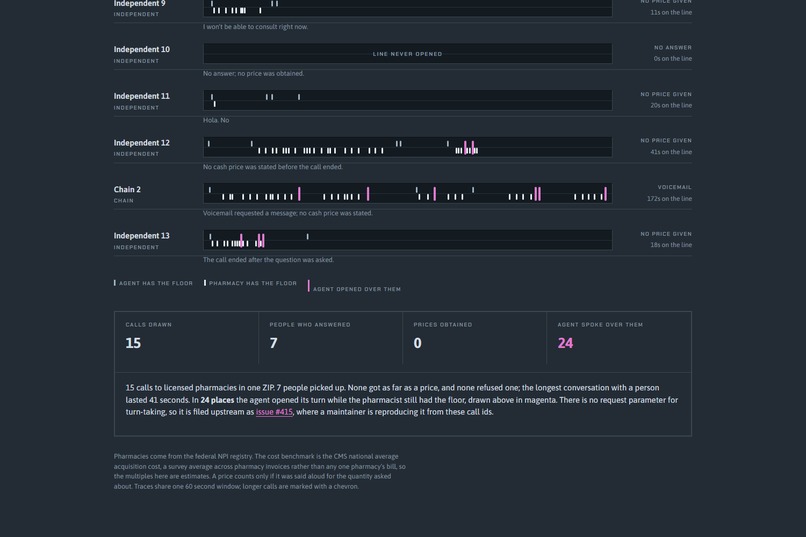
Fifteen calls, seven people answered, zero prices, 24 collisions. Filed upstream as issue #415, where a maintainer is reproducing it.
-
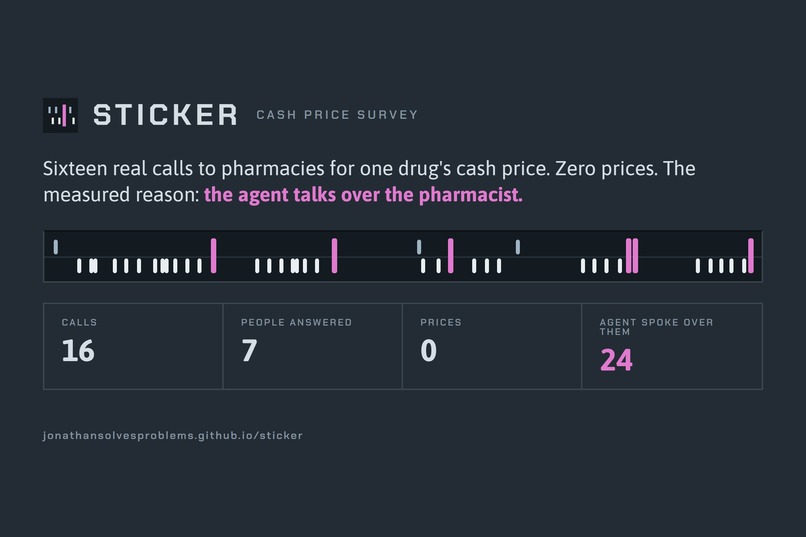
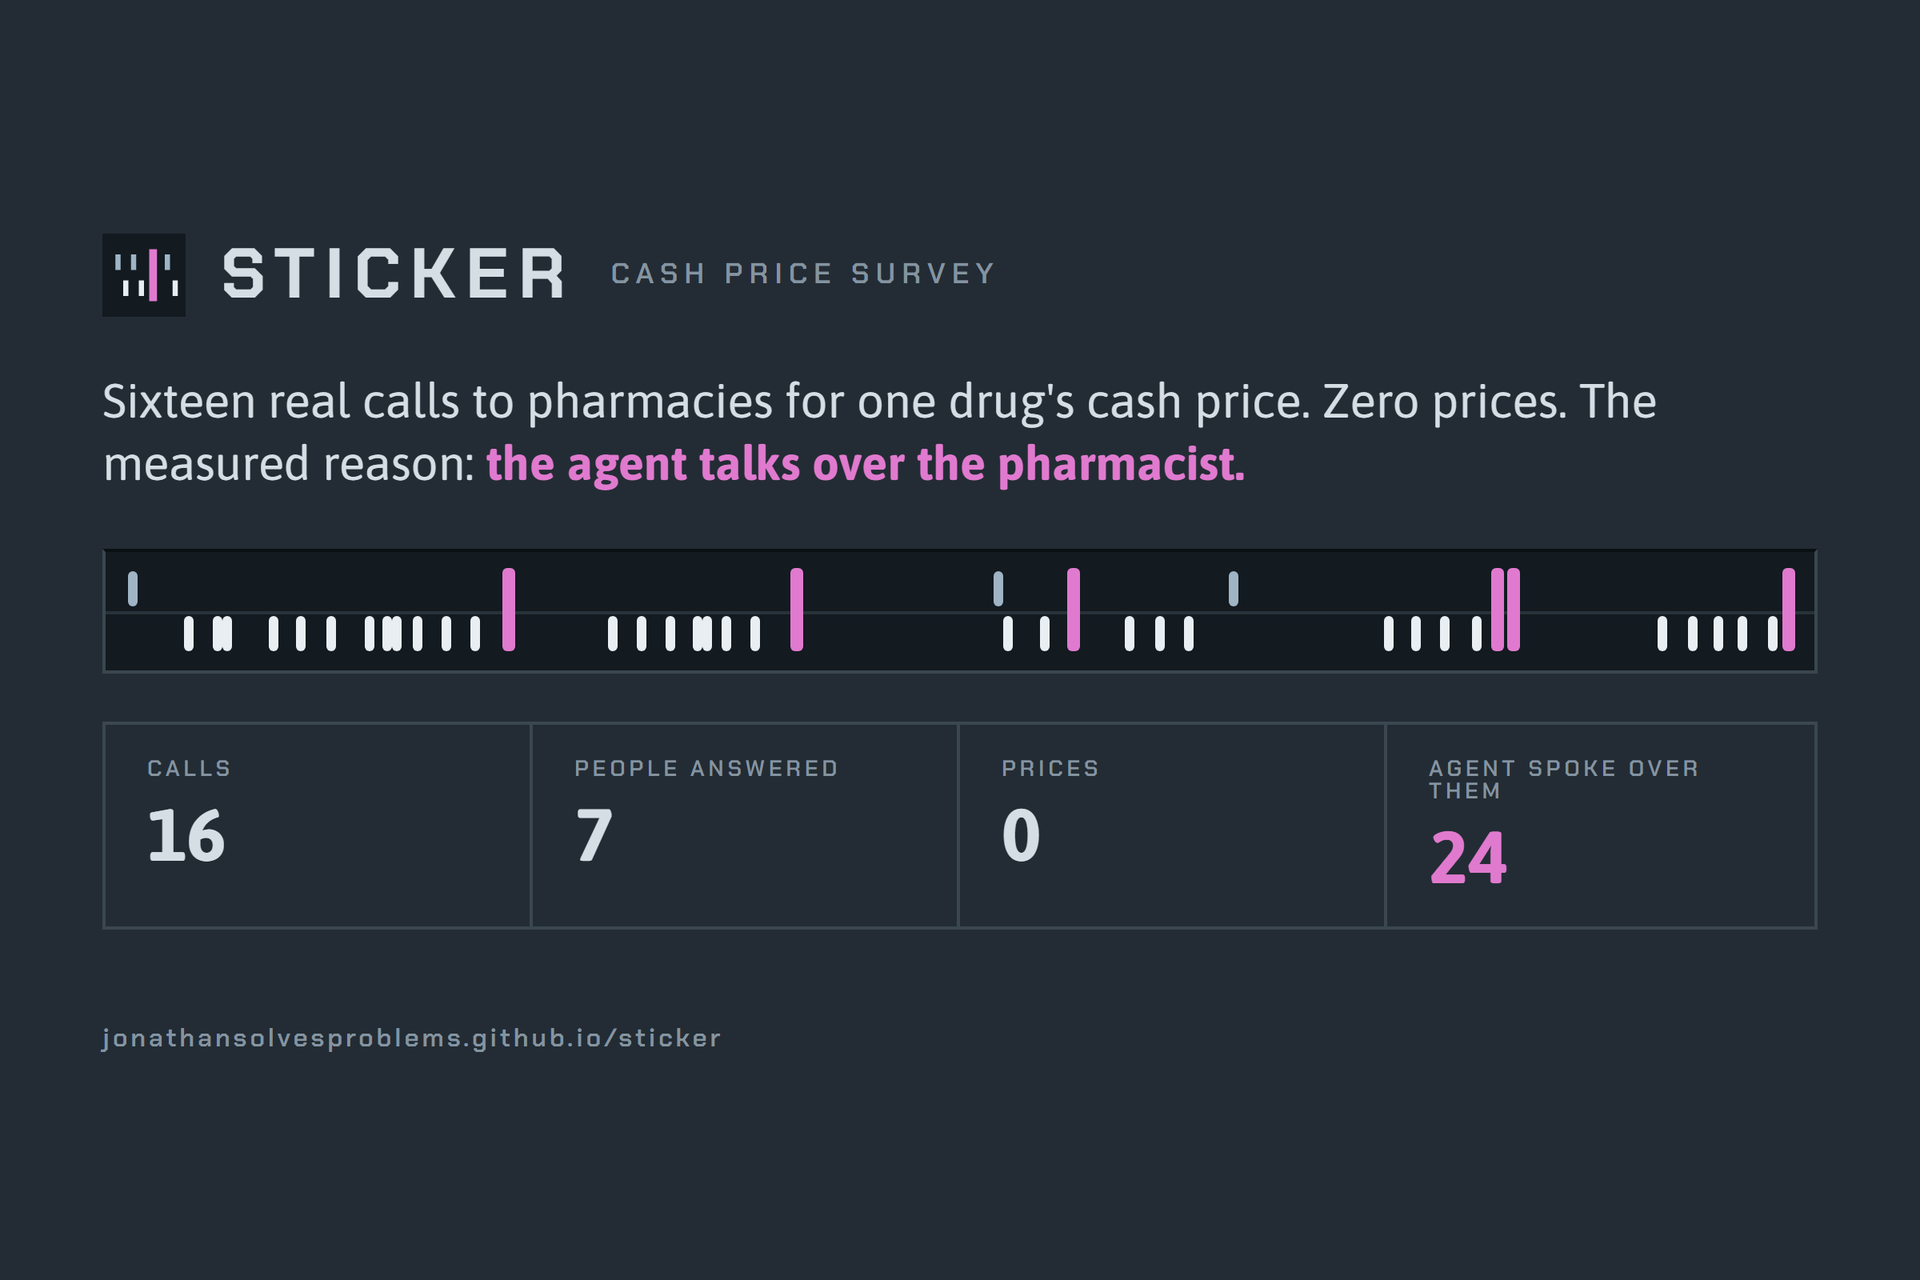
Sixteen real calls, zero prices, and the measured reason why. One real trace, the four figures, nothing invented.
-
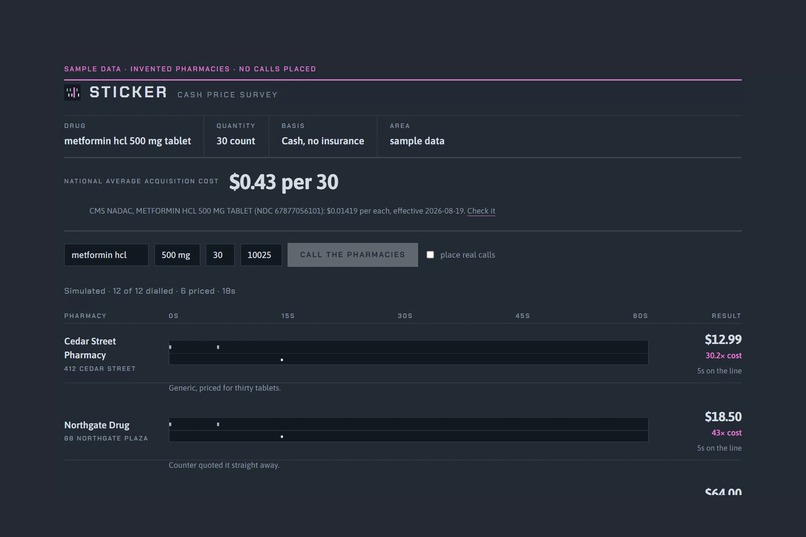
The console running a simulated survey under its SAMPLE DATA banner: invented pharmacies, no calls placed, prices landing row by row.
-
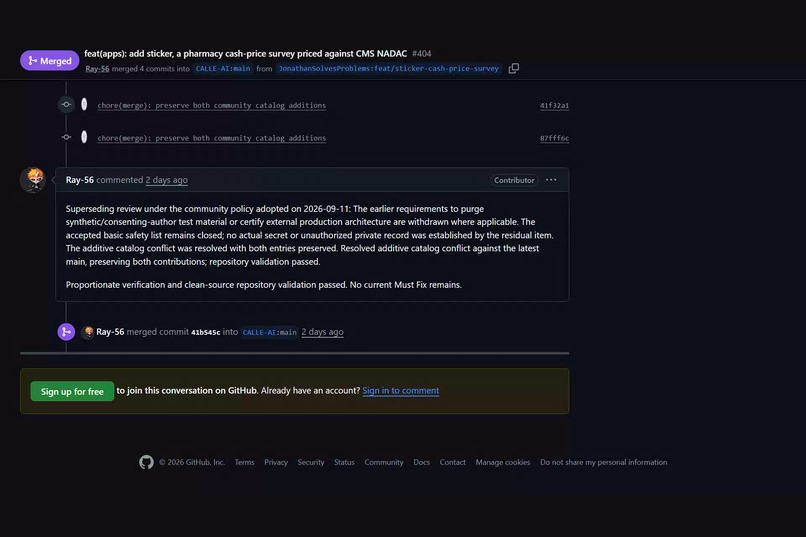
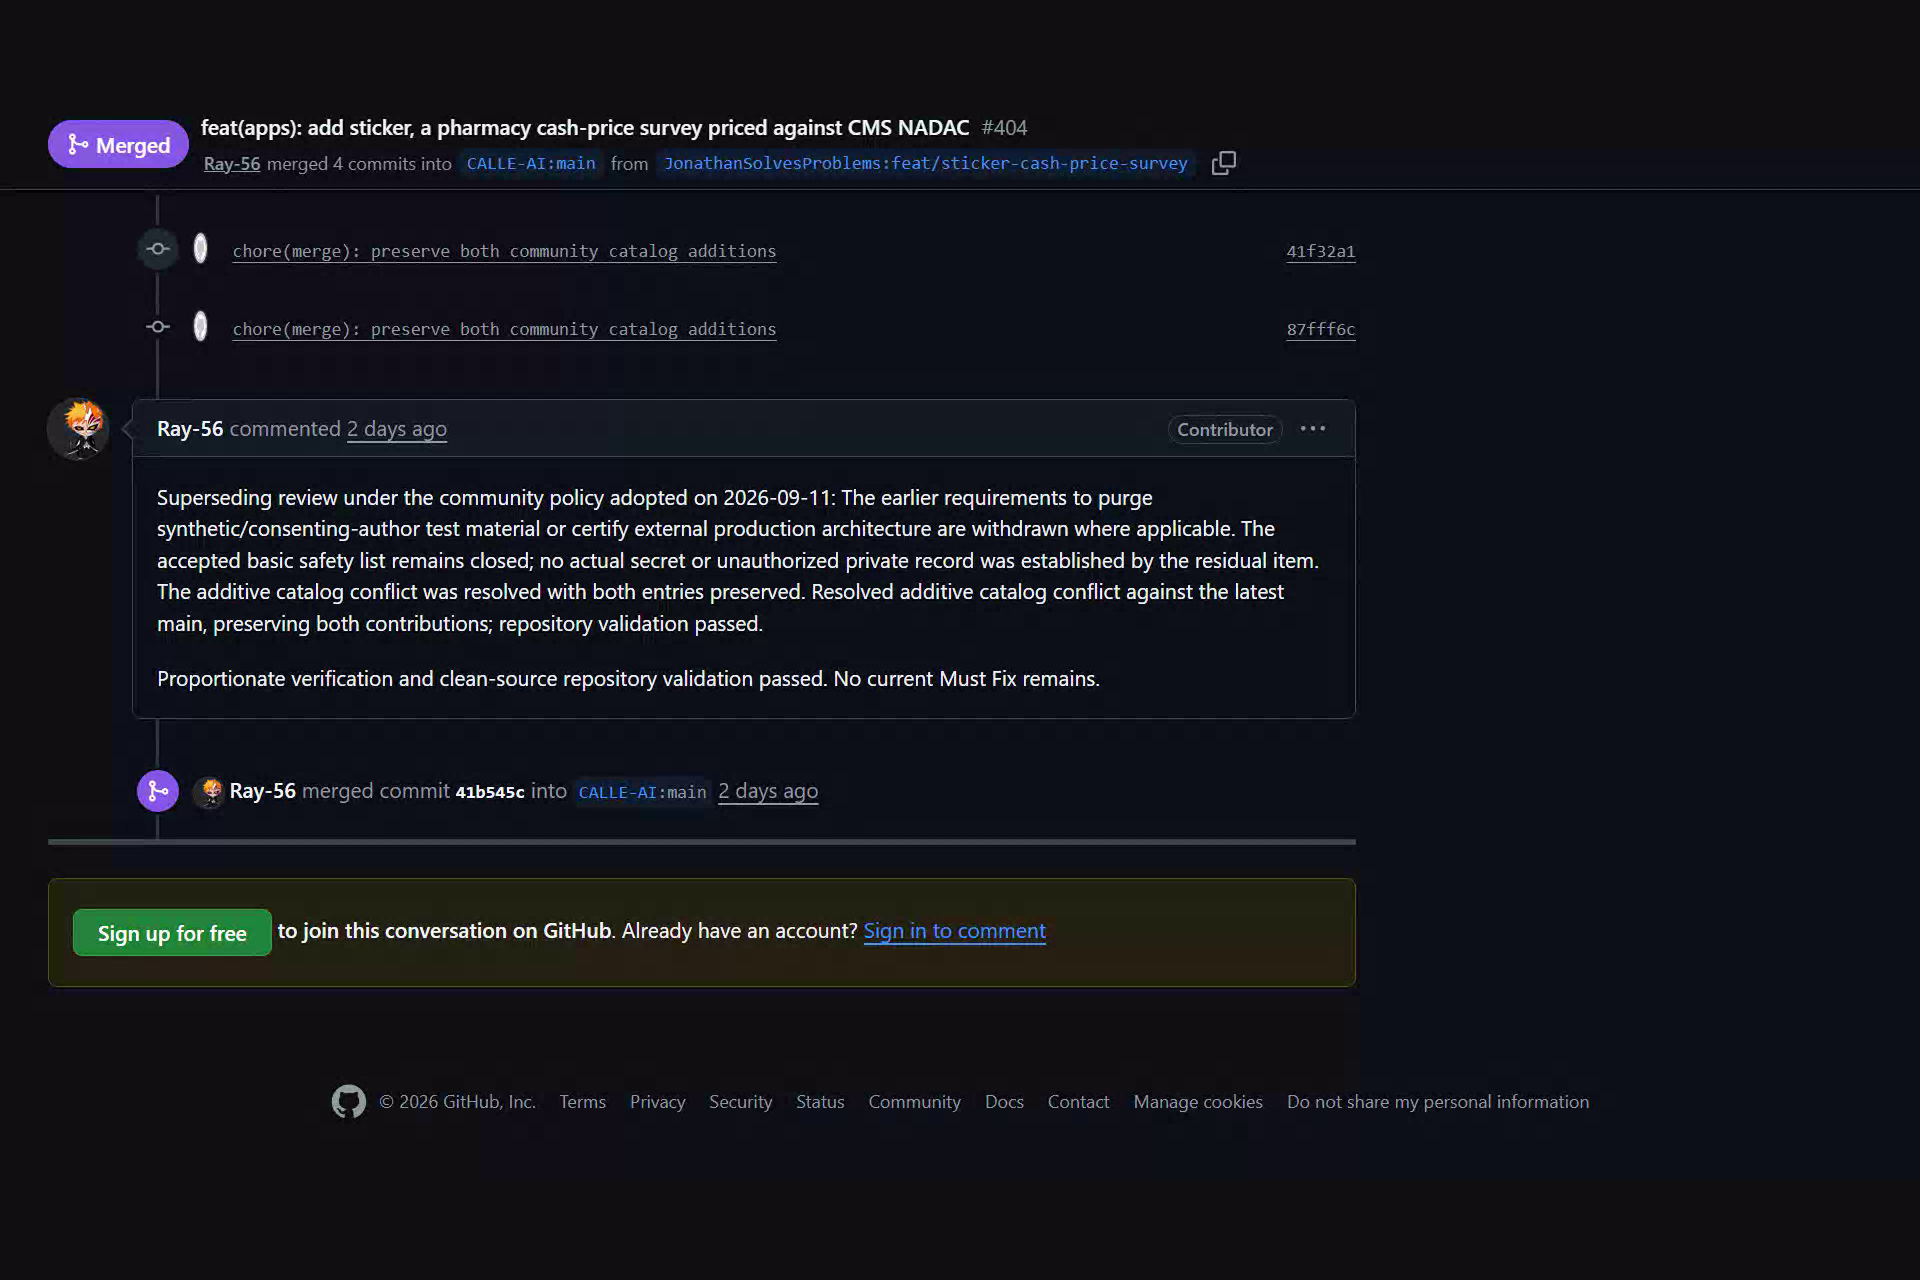
Pull request #404 merged upstream into CALL-E's community repository: a runnable app and a reusable skill across 24 files.
-
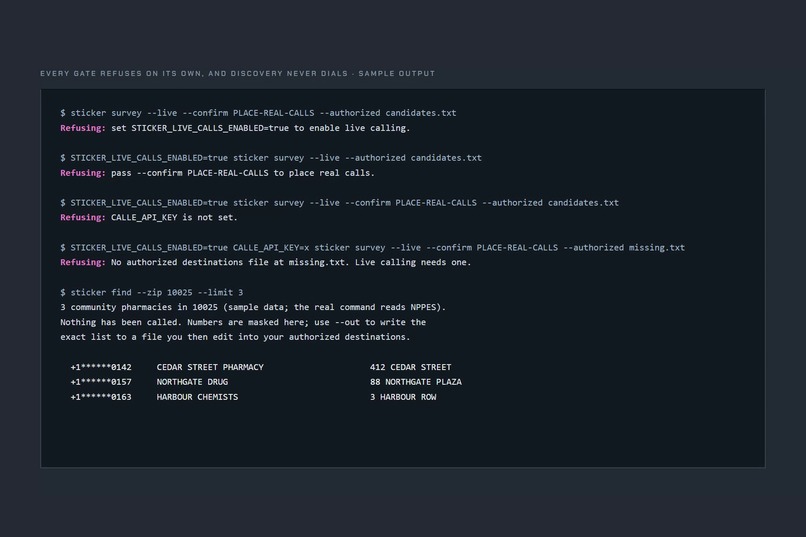
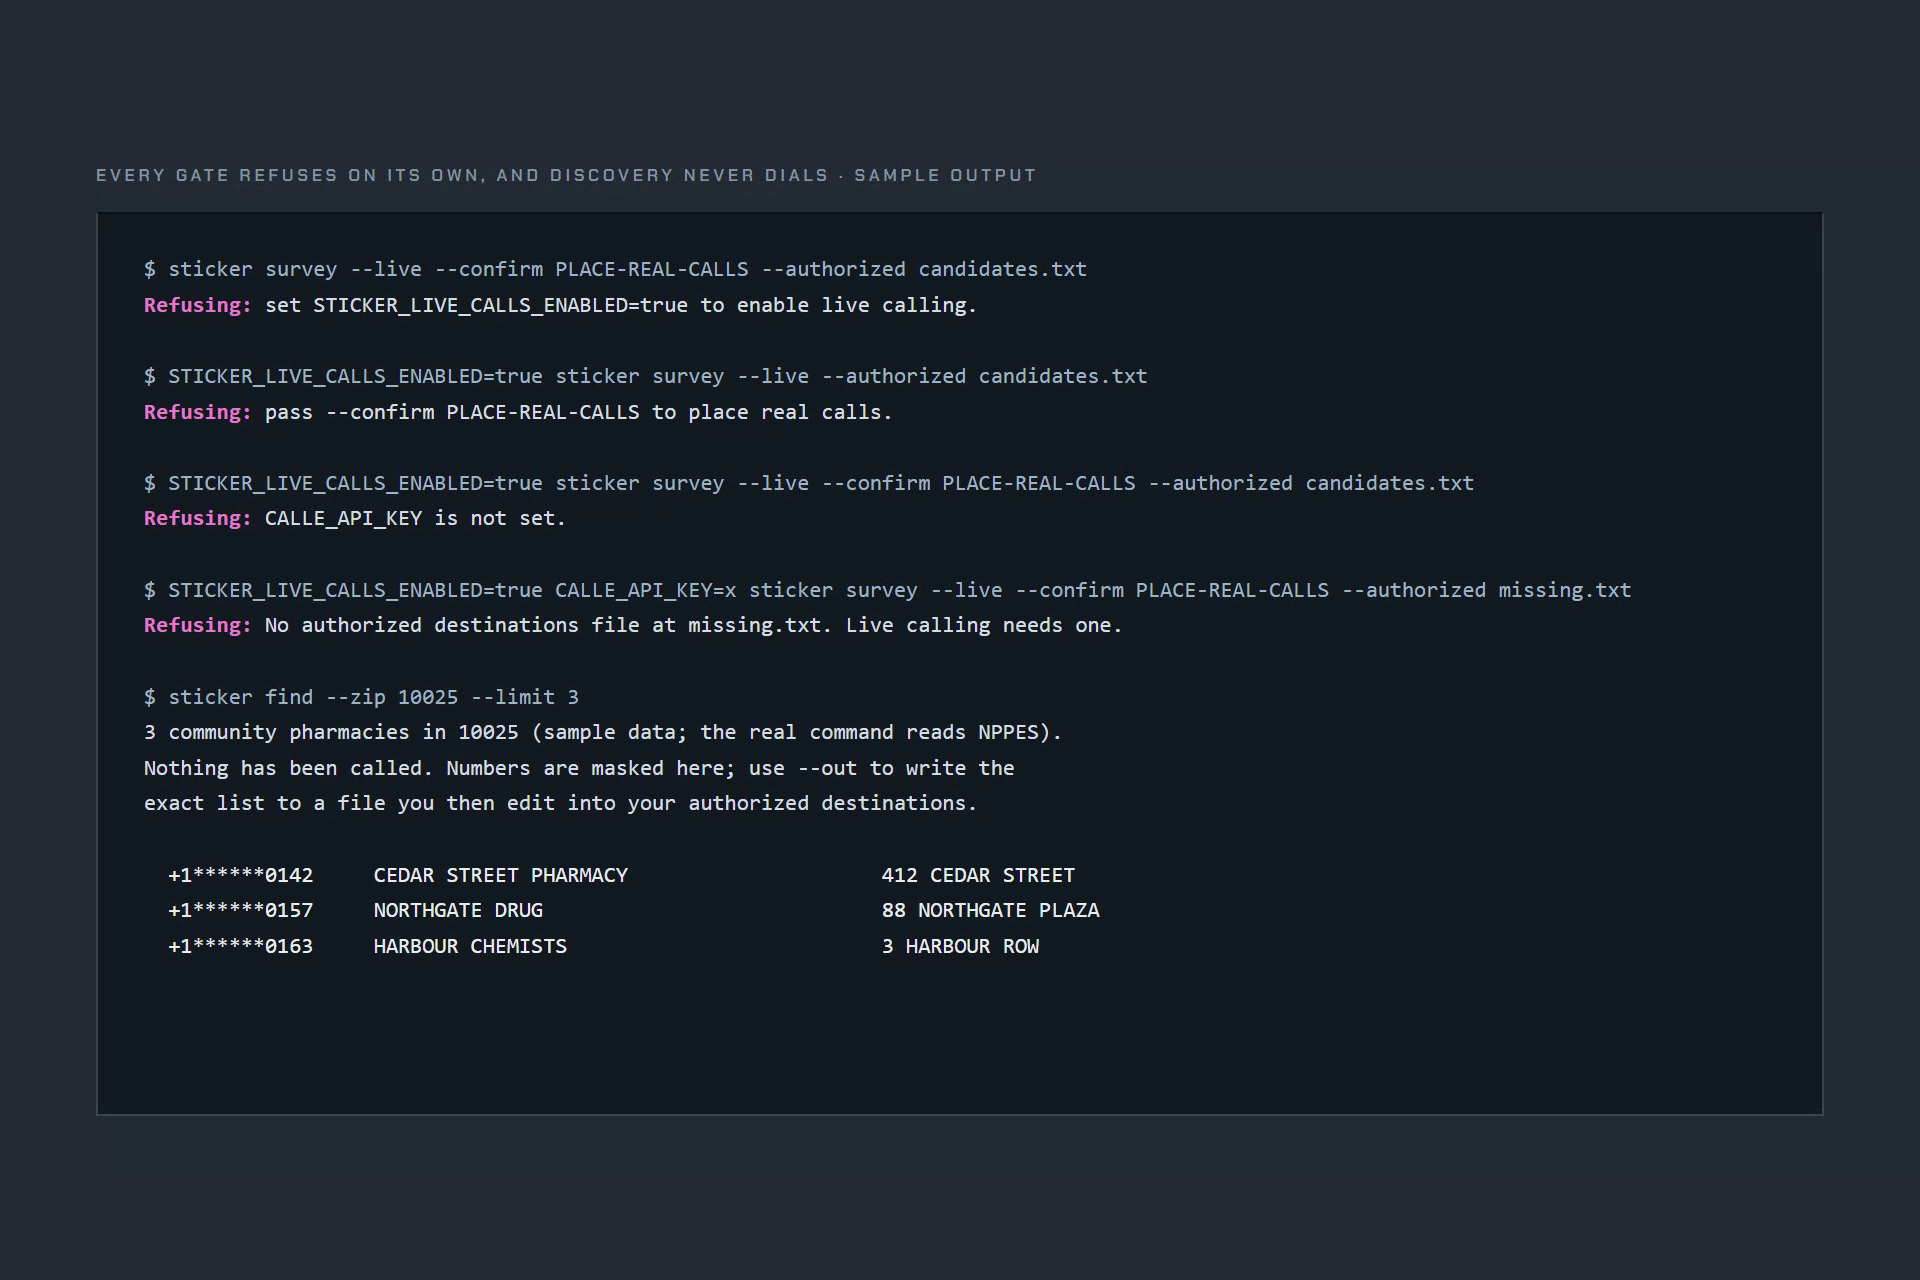
Four independent gates, each refusing on its own. Discovery prints masked numbers; the exact list goes only to a file a person edits.
-
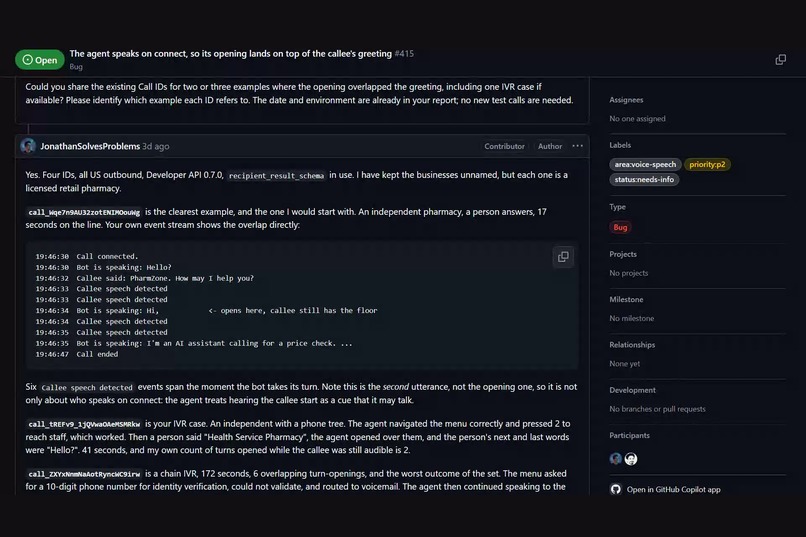
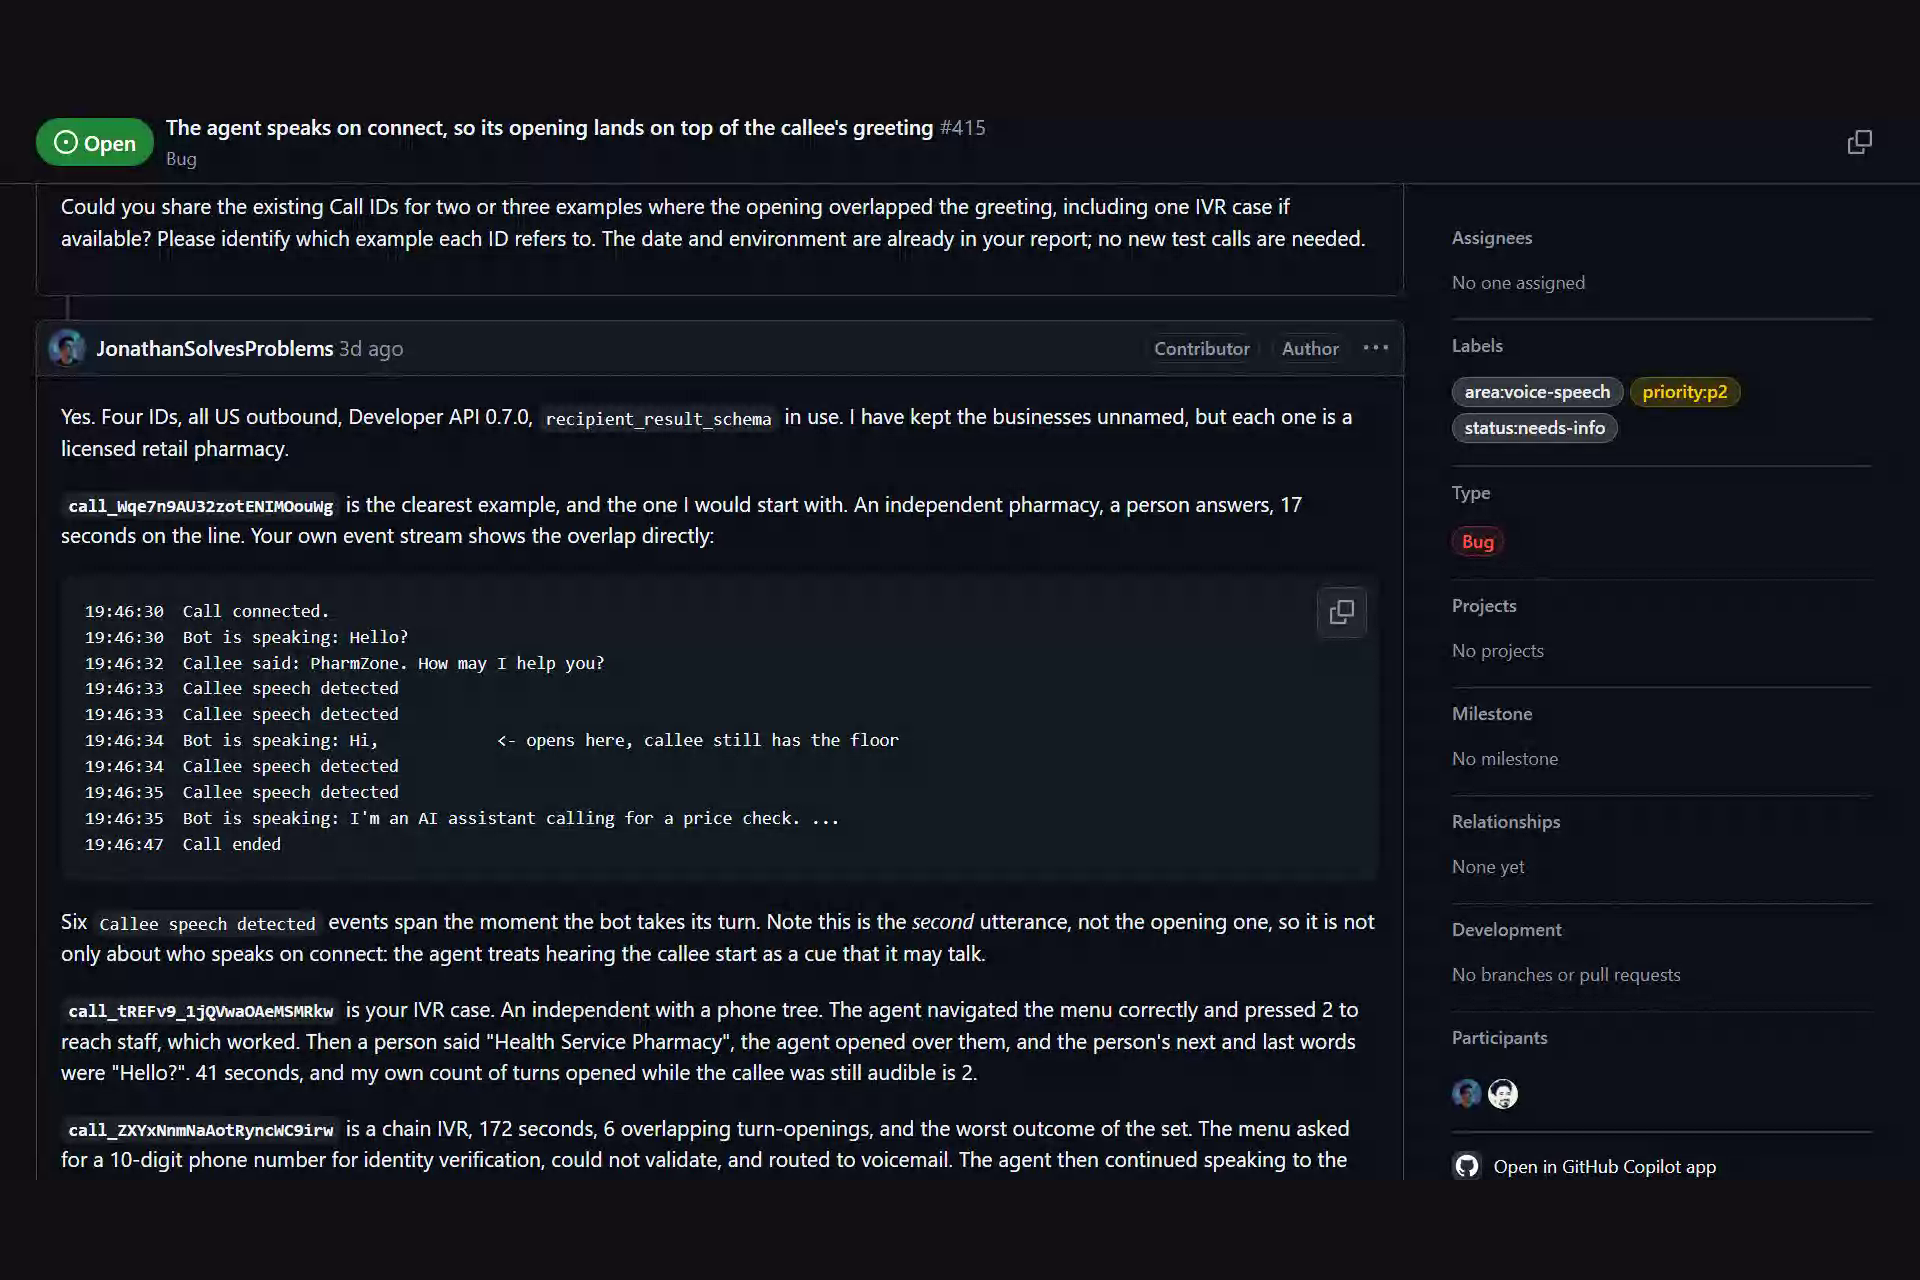
The turn-taking bug filed with reproducible call IDs. The CALL-E maintainer asked for examples the same day and is reproducing it.
Inspiration
Pharmacies nationally paid about 43 cents for thirty metformin tablets. That is not a guess. It is the national average acquisition cost the federal government publishes every week, surveyed from pharmacy invoices, and anyone can look it up.
What you pay is a different number. It is different at every counter, it changes, and it is published nowhere. If you have insurance you rarely see it. If you are uninsured, or have not met a deductible, it is the only number that matters.
There is a reason it stays hidden. Pharmacy contracts with pharmacy benefit managers commonly require the pharmacy to hand the PBM its lowest price, so pharmacies keep the posted cash price above their negotiated rates instead of competing on it. Comparison sites mostly show discount-card prices at chains. Around 19,000 independent pharmacies sit largely outside that surface.
So the only reliable way to learn a cash price is to telephone the counter and ask. That is not a workaround. It is the established research method, and it is done by hand. A 2020 study in Psychiatric Services phoned 265 pharmacies over one month and found a 30-day supply of one generic ranging from $29.99 to $1,345.00 inside a single metro area. A 2017 study phoned 528 pharmacies in Los Angeles County and found an average $52 difference inside one ZIP code.
Those studies took teams of people weeks. That is the thing a phone agent should be able to do in an afternoon.
What it does
Give Sticker a drug and a ZIP code.
It reads the federal NPI registry for licensed community pharmacies near that ZIP. It calls the ones you authorize and asks one question: the cash price, no insurance, for this quantity. It reads back a sorted price map. Then it joins every price to CMS NADAC, so each row also shows the national average pharmacies paid for the same bottle.
The markup column is the point. It is not my arithmetic about my own accuracy. It is a price a pharmacist said out loud, divided by a number the Centers for Medicare and Medicaid Services published that week. I authored neither.
NADAC is a benchmark and not an invoice. CMS surveys pharmacy invoices nationwide and publishes a per-unit average, so the multiple tells you how far a price sits above what the drug generally costs to buy. It is not a claim about what any one shop paid its wholesaler, and the report says so on every run.
Three rules decide what counts, and all three make the headline smaller:
A price counts only if a dollar amount was said aloud for the quantity asked about. A quote for a different bottle size is reported and never rescaled, because ninety tablets are not three thirties.
A refusal stays in the denominator. The share of pharmacies that will not price a drug by phone is a finding about price opacity, not a gap to drop.
A completed call is not an answered question. A voicemail box returns status completed with task_completed true, so the structured answer decides, never the status.
How I built it
CALL-E does the part no API can do.
The agent is given one goal and the handling for what actually happens on a pharmacy line: an automated menu to navigate with the keypad, a hold to wait through, a transfer to the pharmacist and a re-introduction on the other side, a voicemail box to hang up on, and a verification wall it cannot pass and so ends the call at. None of that is an API parameter. It is all steered from the task prose.
The answer comes back through a recipient result schema, so a price is a validated field rather than something regexed out of a summary. Every uncertain field can answer unknown, because a schema with no way to say "I did not find out" invites a fabricated number.
The transport speaks the REST API rather than the SDK's blocking create_and_wait, so calls overlap on one event loop instead of one thread each.
Two federal datasets, both public and keyless. NPPES supplies licensed community pharmacies, filtered to the walk-in retail taxonomy so mail-order and specialty pharmacies cannot quietly corrupt the sample. CMS NADAC supplies the acquisition cost.
The safety surface is the part I spent the most time on, because the side effect is a telephone ringing at a working counter. Discovery never dials: it writes a candidate list a person edits into an allowlist, and an empty allowlist authorizes nothing rather than everything. Numbers are validated as strict ASCII E.164, because Python's \d also matches Arabic-Indic and fullwidth digits and would dial something other than what you read. The API origin is parsed and allowlisted before the key is attached to a header, and redirects are off. Idempotency keys are derived from request content, so a crash and a restart reuse the key instead of dialling twice. A rejected request is a fact, but a timeout is not, so an ambiguous create halts the run for a human rather than retrying.
The agent's first word is only "Hello?", and it waits for the pharmacy to finish its greeting before saying anything else. Then one sentence both discloses that it is an AI and asks the question. The disclosure comes before the question every time, including after a transfer. CALL-E does not announce itself and offers no setting for it, so it exists only in the task prose. That is why the test suite asserts on it.
Challenges I ran into
Twenty real calls to licensed pharmacies in one Manhattan ZIP code, and not one produced a price. Not one refused either. Every conversation that reached a person ended within about forty seconds, usually right after the question was asked.
The first call reached an after-hours voicemail box and the agent waited on it for three and a half minutes, because nothing in the API says what to do at a recording. That was fixable in prose. What was not fixable in prose was the thing I found next.
CALL-E's own event stream logs "Bot is speaking" and "Callee speech detected" with timestamps, and reading them showed the agent opening its turn while the pharmacist was still mid-greeting. Six separate speech events from the callee bracket the moment the agent starts talking. A person who hears a machine speaking across their own words says "Hello?" and hangs up. I rewrote the opening four times, ending with a single word ("Hello?") followed by silence until the line was quiet, and the agent still cut in. There is no request parameter for turn-taking: the create call has six fields and rejects unknown keys. Another contributor's app hit the same wall independently.
Chain pharmacies were a second wall. One phone tree demanded a ten-digit phone number for identity verification, could not validate a caller with no patient record, and routed straight to voicemail. A price check cannot get past that by design.
And the account has a concurrent-call limit that the API reference does not mention. I found it by exceeding it: HTTP 429, account_concurrency_exceeded, whose message is the only place the limit is stated (one call at a time on the default shared line, shared across API, MCP and dashboard, ten after identity verification). That one turned into a feature, because a 429 means nothing was dialled, so it is the one error that is safe to wait out and retry.
Accomplishments that I'm proud of
The contribution merged upstream after five review passes with the repository maintainer. Three of them found something real in the code and the claims: false claims about what a pharmacy paid when the benchmark is a national average, real-call timings that had crept into docstrings as engineering rationale, an invented per-call cost, a call counter that credited calls a halted run had prevented. All fixed, and the suite went from 61 tests to 94 and from 47 seconds to under 2.
I measured the failure instead of describing it. 27 collisions across 19 traced calls, counted from the platform's own event stream, and drawn on a results page where each call is a two-channel trace over real seconds. The finding is visible without reading a word. The counter now ships as a command, sticker trace, so any CALL-E developer can run it on their own calls and attach the trace to a bug report; it merged upstream as a second pull request, #553, the morning of the deadline.
I filed it upstream as issue #415 with reproducible call IDs, and a CALL-E maintainer picked it up the same day. That is the sponsor's engineer investigating a bug their platform has, using evidence I supplied.
Every safety control failed closed under review. A rejected request is a fact and the survey continues. A timeout, a server error, a lost read or an unrecognised status is uncertain, so the run halts before any queued call is placed. Discovery never dials. An empty allowlist authorizes nothing. Numbers are masked everywhere except the one file a person edits. And the honest number shipped: zero prices, on the page, in the README, and here.
What I learned
A phone agent that cannot yield the floor cannot ask a busy person a question. Everything else about this project worked: the registry lookup, the federal benchmark, the schema, the safety model, the halt logic. None of it mattered, because the conversation never got to the point where a price could be said. The whole product lives or dies in about two seconds of turn-taking that I do not control.
A fact learned from a live call is a real-call artifact even when it is phrased as the reason for a design decision. The maintainer caught me reintroducing exactly the thing I had been told to remove, twice, because I had written it as rationale rather than as data. The behaviour it justifies can go in the repository. The observation that produced it cannot.
Zero is a result if you say how you got it. I could have shipped a simulated board with prices on it and a paragraph about "live testing pending." Instead the results page shows twenty real calls with nothing in the price column, the transcript of why, and a bug report the platform is acting on. I would rather be judged on that.
And a survey method built for human callers does not transfer to a disclosed AI caller without the platform's help. That is a finding about the tool, not about the pharmacies, and I have tried to say it that way everywhere.
What I reported to CALL-E
Four findings, each with the evidence attached, because a platform bug report is only useful if someone else can reproduce it.
The agent opens its turn while the person answering is still speaking, and there is no request parameter for turn-taking. Issue #415, with four reproducible call IDs and the event timestamps that show the overlap. A maintainer asked for examples the same day and is working on it.
The account has a concurrent-call cap that the API reference does not mention. It surfaces as HTTP 429 account_concurrency_exceeded, and the error message is the only place the limit is stated: one call at a time on the default shared line, shared across API, MCP and dashboard, ten after identity verification. Because nothing was dialled, it is the one error that is safe to retry, and Sticker treats it that way. The reference should say what the error says.
A voicemail box comes back as status completed with task_completed true, and nothing in the API distinguishes a person from a recording. The first live call waited on an after-hours box for three and a half minutes. Task prose can tell the agent to hang up on a recording; the API cannot tell it that it reached one.
The create call rejects unknown keys, which is good, but it means every behaviour a caller needs on a real business line, from greeting etiquette to voicemail handling, lives only in prose and cannot be tested except by ringing a telephone.
What a judge can do in five minutes
Open the results page: nineteen real calls drawn as traces, every collision in magenta, no price in any row. Clone the repo and run python -m pytest tests -q: 104 tests, under two seconds, no key. Run sticker survey --offline: the whole pipeline on invented pharmacies, headed SIMULATED, no calls placed. Run sticker trace --events examples/events.sample.json: the barge-in meter that produced the 27, on an invented stream. With your own CALL-E key, point it at any call on your own account with --call-id and see who had the floor. Try any of the four live gates without the others open: each refuses on its own and exits 2. Read issue #415 in CALL-E's repository: the bug, the evidence, and the maintainer's reply.
What's next for Sticker
The same engine points at a payer.
A self-insured employer or a benefits navigator already pays people to steer members toward cheaper pharmacies, and does it with stale data. A standing survey of a plan's own geography, refreshed on a schedule, is the same calls with a buyer attached.
The second direction is coverage. NADAC prices most generics but few brand-only drugs, and the drugs where cash price hurts most are often the ones with the thinnest published data.
The third is honesty about what a survey is. Prices collected in one morning are a snapshot, not a standing price, and a useful version of this tells you how old its own numbers are.
Built With
- asyncio
- call-e
- cms-nadac
- fastapi
- httpx
- npi
- nppes
- pytest
- python

Log in or sign up for Devpost to join the conversation.