-
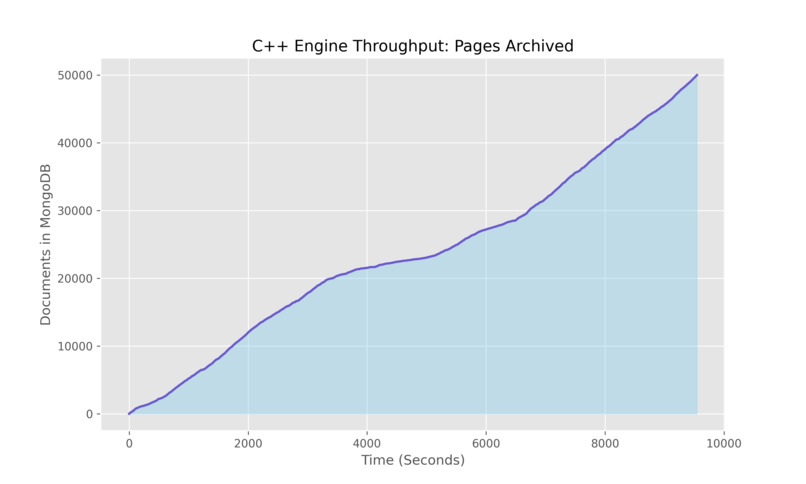
Throughput during the 50k document crawl
-
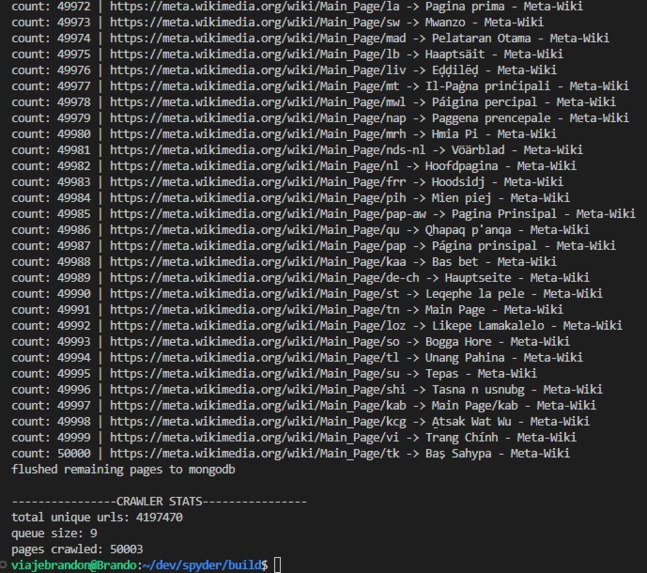
CLI Stats of Web Crawler Performance

A high-performance web crawler written in C++17, utilizing MongoDB as a scalable web archive.
spyder is designed for high-throughput web scraping and archiving. It successfully crawled and archived over 50,000 pages from Wikipedia (focused on Computer Science) while maintaining an active frontier of over 4,000,000+ unique URLs.
Achievements
Massive Scale: Handled a frontier queue of 4.19M+ unique URLs.
High Throughput: Successfully archived 50,000+ Wikipedia documents directly into MongoDB.
Search Integration: Fully queryable archive database, complete with a custom Search Tester UI to rank and retrieve documents using $search.
System Design Note: The architecture for this crawler was heavily inspired by the system design principles of Alexa Fazio 💯.

