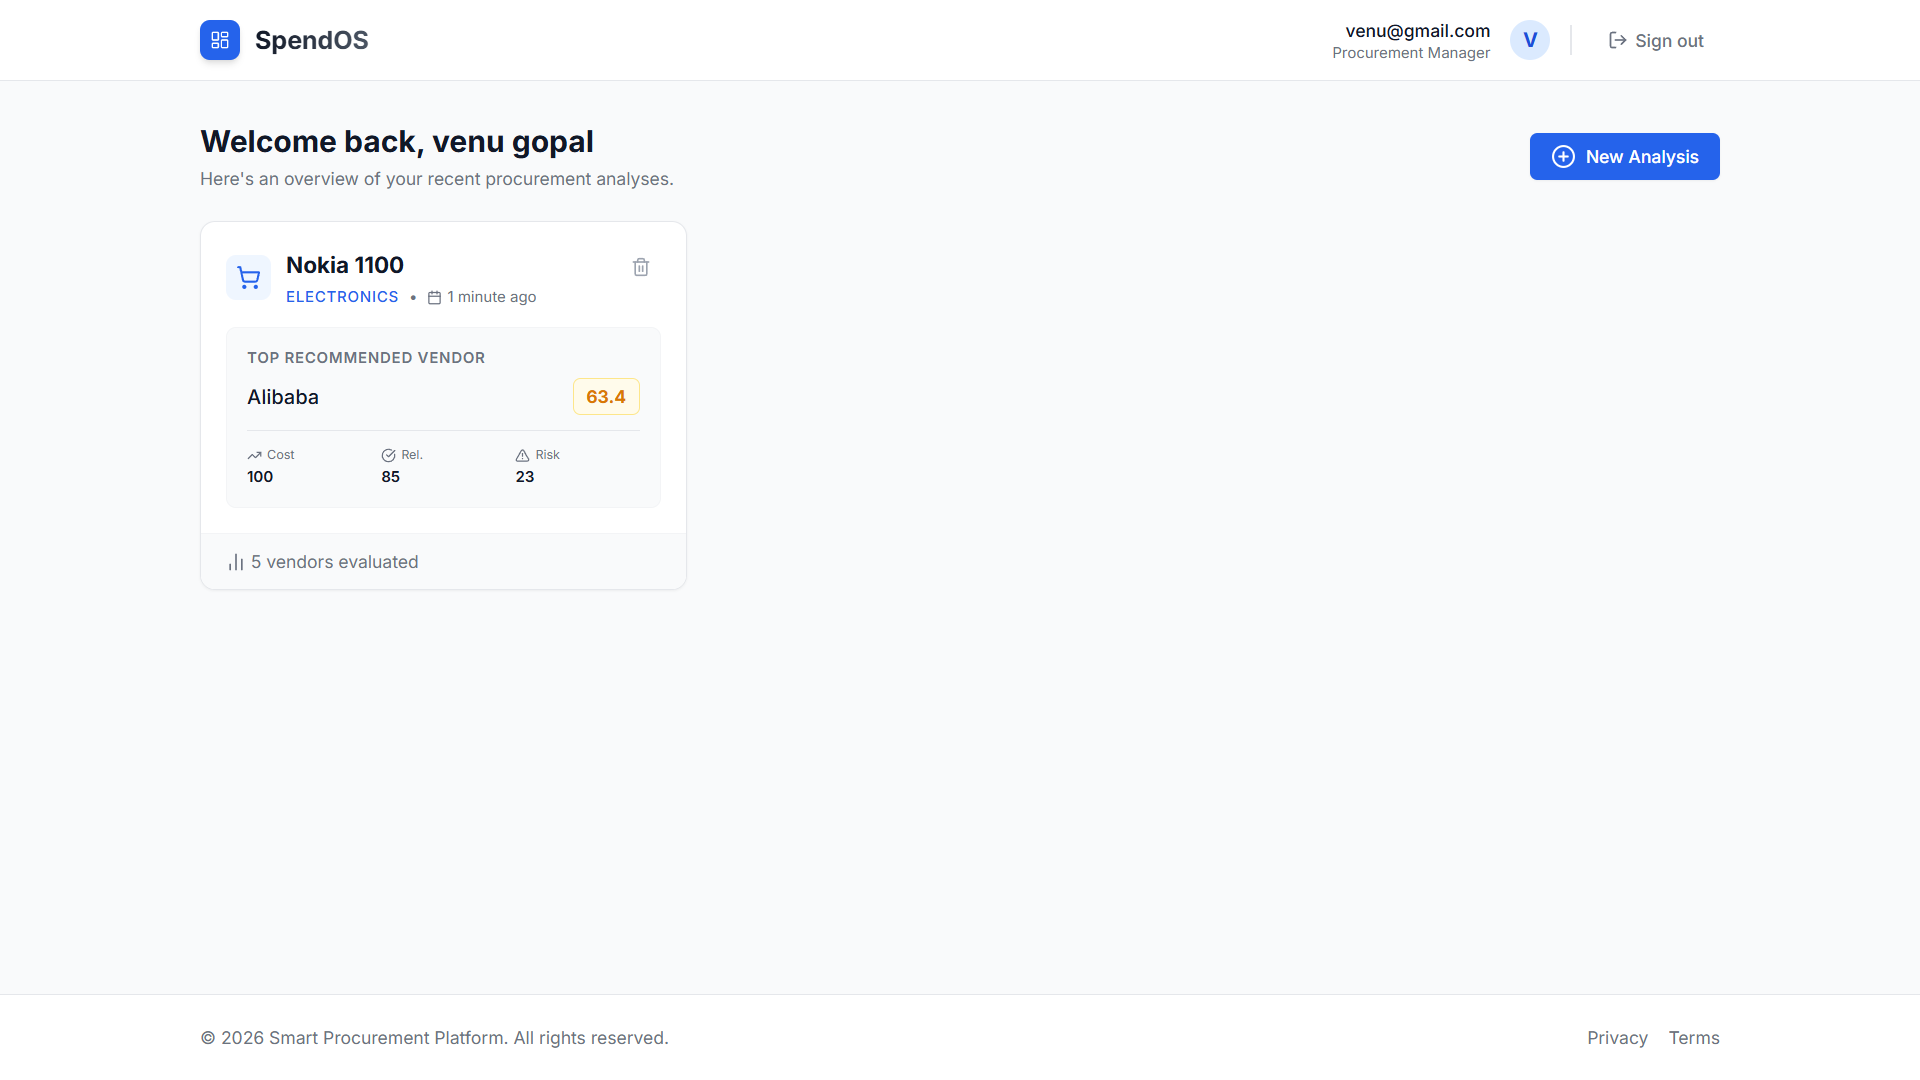
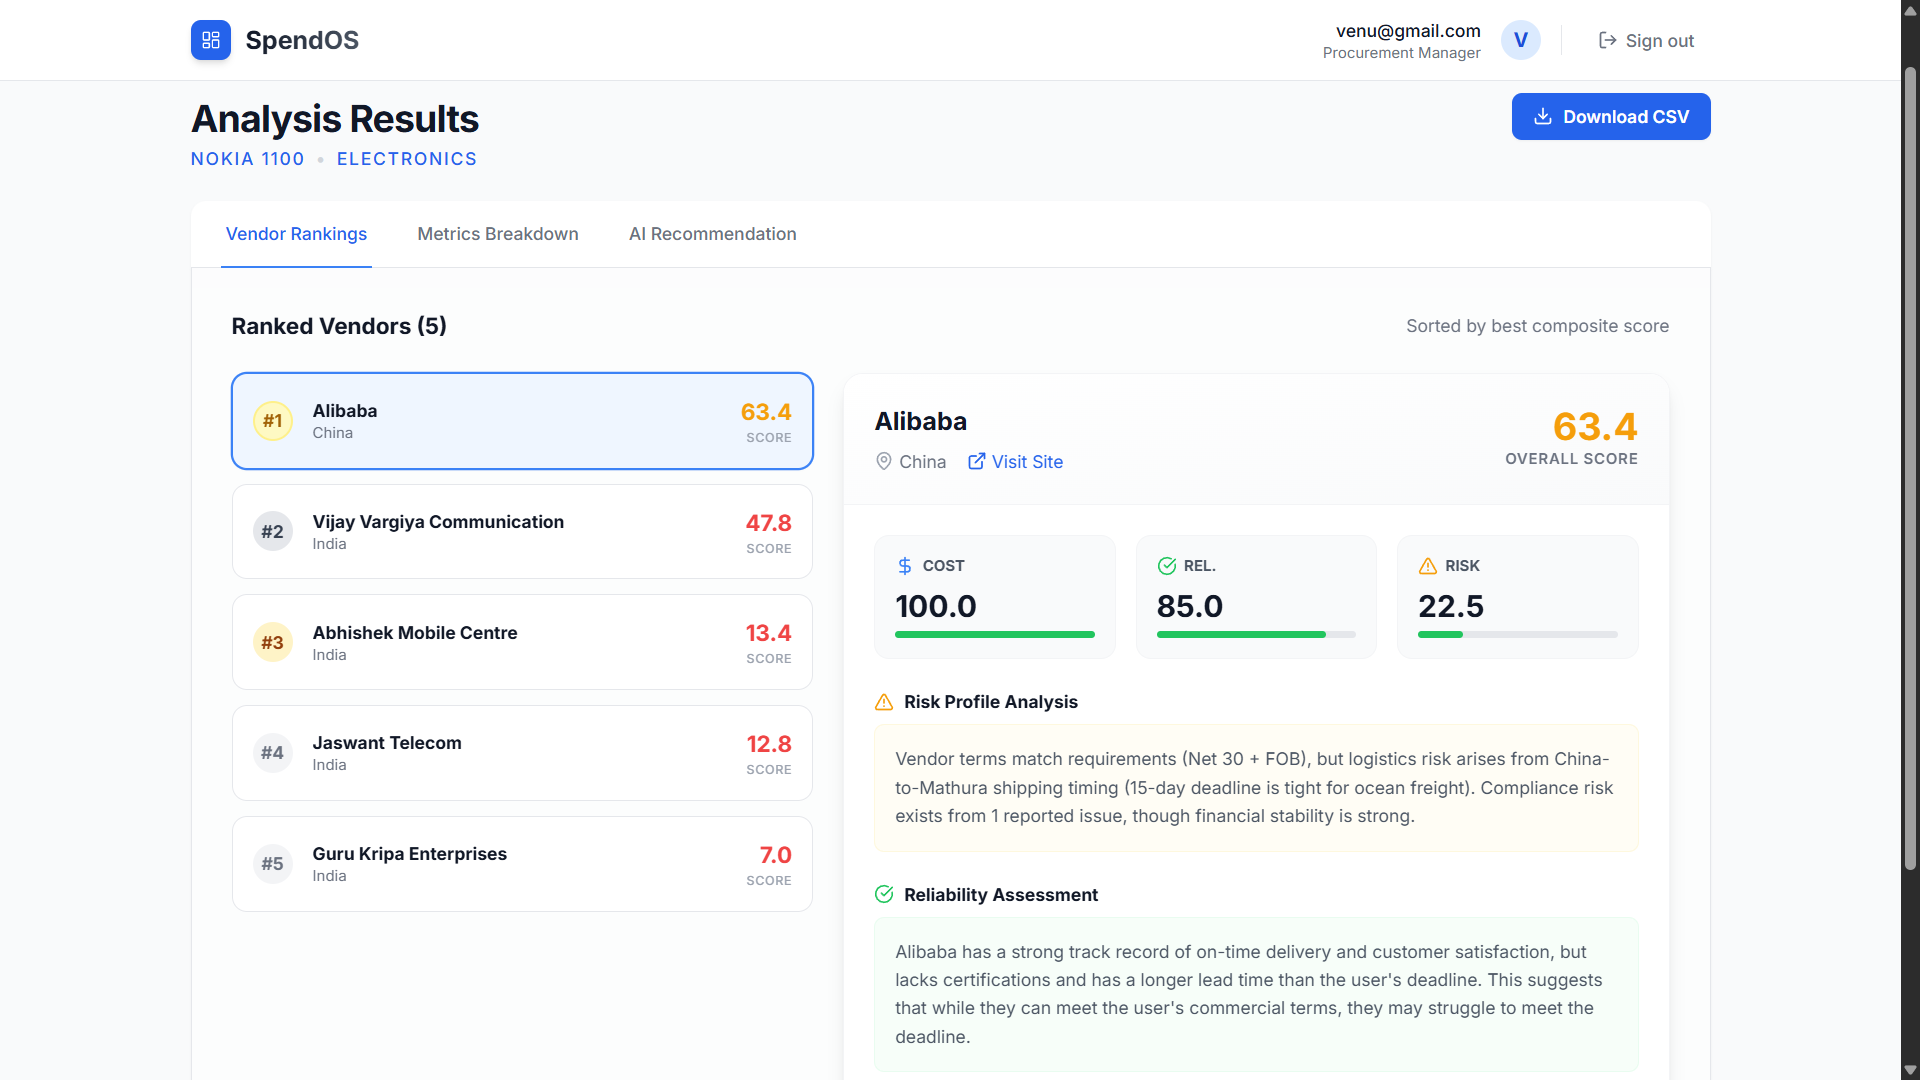
🚀 About the Project
💡 Inspiration
Procurement is still painfully manual—teams spend hours Googling vendors, cross-checking credibility, and making subjective decisions. We wanted to compress that entire workflow into seconds using AI, without sacrificing depth or reliability.
🏗️ How We Built It
We designed SpendOS as a decoupled, AI-first system:
- Backend:
FastAPIfor APIs + async handling - Worker Layer:
ARQ + Redisto process long-running AI tasks AI Orchestration:
LangGraphto manage a multi-step pipeline:- Vendor discovery (via SerpAPI)
- Data enrichment
- Parallel risk analysis
- Parallel reliability scoring
- Final recommendation synthesis
Inference Stack: Multi-model LLM setup (LLaMA, Qwen via Groq) for speed + specialization
Frontend:
React 19with SSE for real-time progress updates
We optimized for throughput using parallel nodes. Conceptually:
[ T_{total} \approx \max(T_{risk}, T_{reliability}) + T_{overhead} ]
Instead of sequential execution:
[ T_{total} = T_1 + T_2 + T_3 + \dots ]
⚔️ Challenges We Faced
Latency vs Depth Tradeoff Running multiple LLM calls can slow things down. We solved this with parallel execution + Groq inference.
Unstructured Data Noise Web results are messy. We built sanitization + structured extraction layers to maintain consistency.
State Management in AI Pipelines Coordinating multiple dependent steps wasn’t trivial—LangGraph helped manage state transitions cleanly.
Async Architecture Complexity Separating API response cycles from long-running AI workflows required careful handling of queues, retries, and streaming updates.
📚 What We Learned
- Parallelizing AI workflows is a game-changer for real-world latency
- Multi-model setups outperform single-model pipelines in both speed and accuracy
- Clean architecture (service + worker separation) is critical for scaling AI systems
- Real-time feedback (SSE) drastically improves user trust in AI systems
🎯 Outcome
SpendOS transforms procurement from a slow, manual process into a real-time, AI-driven decision engine—delivering structured, risk-aware vendor insights in seconds instead of hours.
Built With
- communication:
- groq-(llm-inference)-llms:-llama-3.x
- javascript-backend:-fastapi
- languages:-python
- qwen-32b-infra-&-deployment:-docker
- real-time
- render
- sqlalchemy-2.0-(async)-frontend:-react-19
- sses
- typescript
- vite-ai-orchestration:-langgraph-task-queue:-arq-with-redis-database:-postgresql-apis:-serpapi-(vendor-discovery)
