Inspiration
Effective communication and confident public speaking are vital skills for interviews, presentations, and leadership. However, getting personalized, objective feedback usually requires hiring an expensive coach or practicing in front of peers, which can be intimidating. We wanted to build SpeechCoach AI to democratize speech coaching by creating an intelligent, multimodal AI assistant that analyzes video, audio, and language in real time to give speakers actionable, constructive feedback.
What it does
SpeechCoach AI acts as your personal virtual speaking coach:
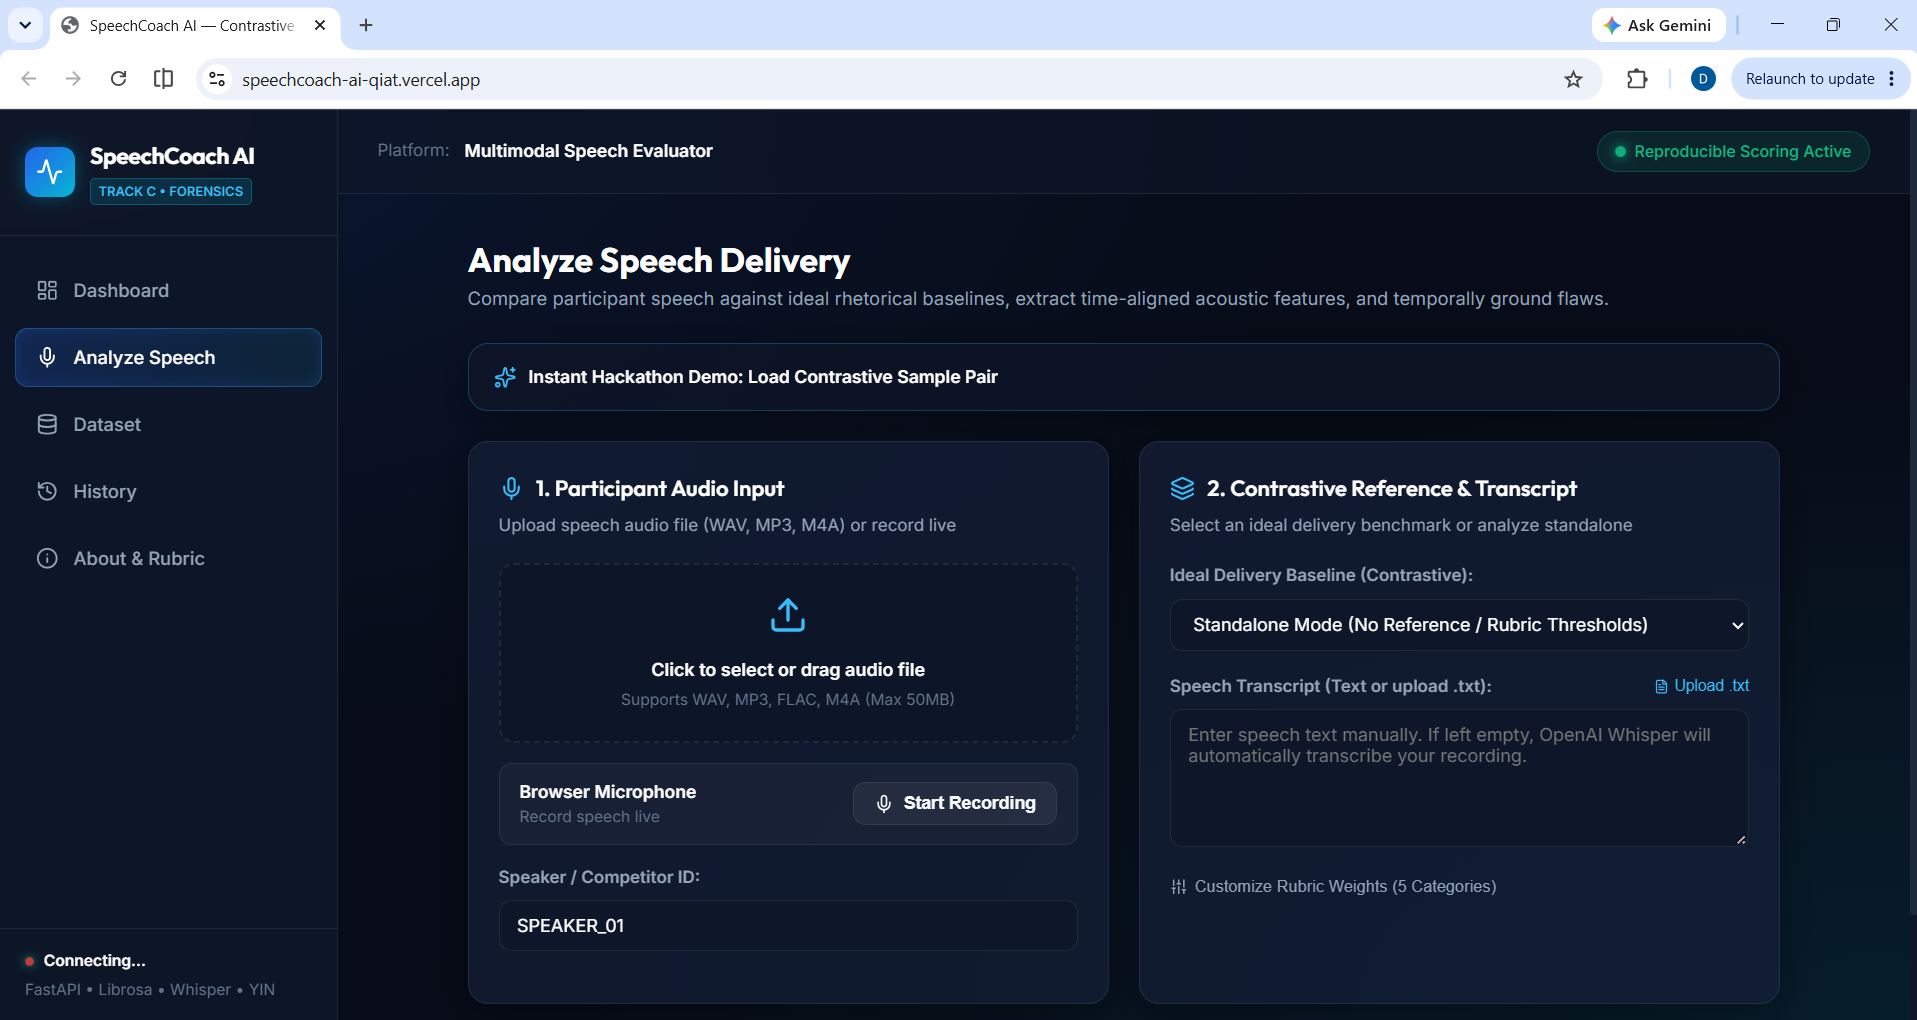
- Multimodal Evaluation: Listens to speech audio, reads transcriptions, and evaluates delivery metrics simultaneously.
- Pacing & Clarity Analysis: Monitors words per minute (WPM), pauses, pitch variation, and filler word usage (e.g., "um", "like", "you know").
- Language & Structure Feedback: Analyzes grammar, vocabulary strength, tone, and conciseness to help speakers refine their talking points.
- Actionable Performance Insights: Provides an instant session score, highlighted strengths, and prioritized areas for improvement after each practice run.
How we built it
- Frontend: Built with React / Vite and Tailwind CSS for a fast, responsive user interface and seamless audio/video recording controls.
- Backend: Powered by a high-performance Python FastAPI service handling real-time data streaming and analysis pipelines.
- AI & Multimodal Processing: Leveraged modern multimodal foundation models, speech-to-text recognition, and acoustic analysis to process spoken language and delivery dynamics.
Challenges we ran into
- Synchronizing Multimodal Streams: Ensuring real-time audio and textual analysis without introducing perceptible latency during live practice sessions.
- Handling Large Model Dependencies: Managing heavy ML and audio processing libraries within deployment environments while keeping build and response times fast.
- Actionable Feedback Generation: Prompt engineering multimodal models to provide precise, encouraging coaching tips rather than generic critiques.
Accomplishments that we're proud of
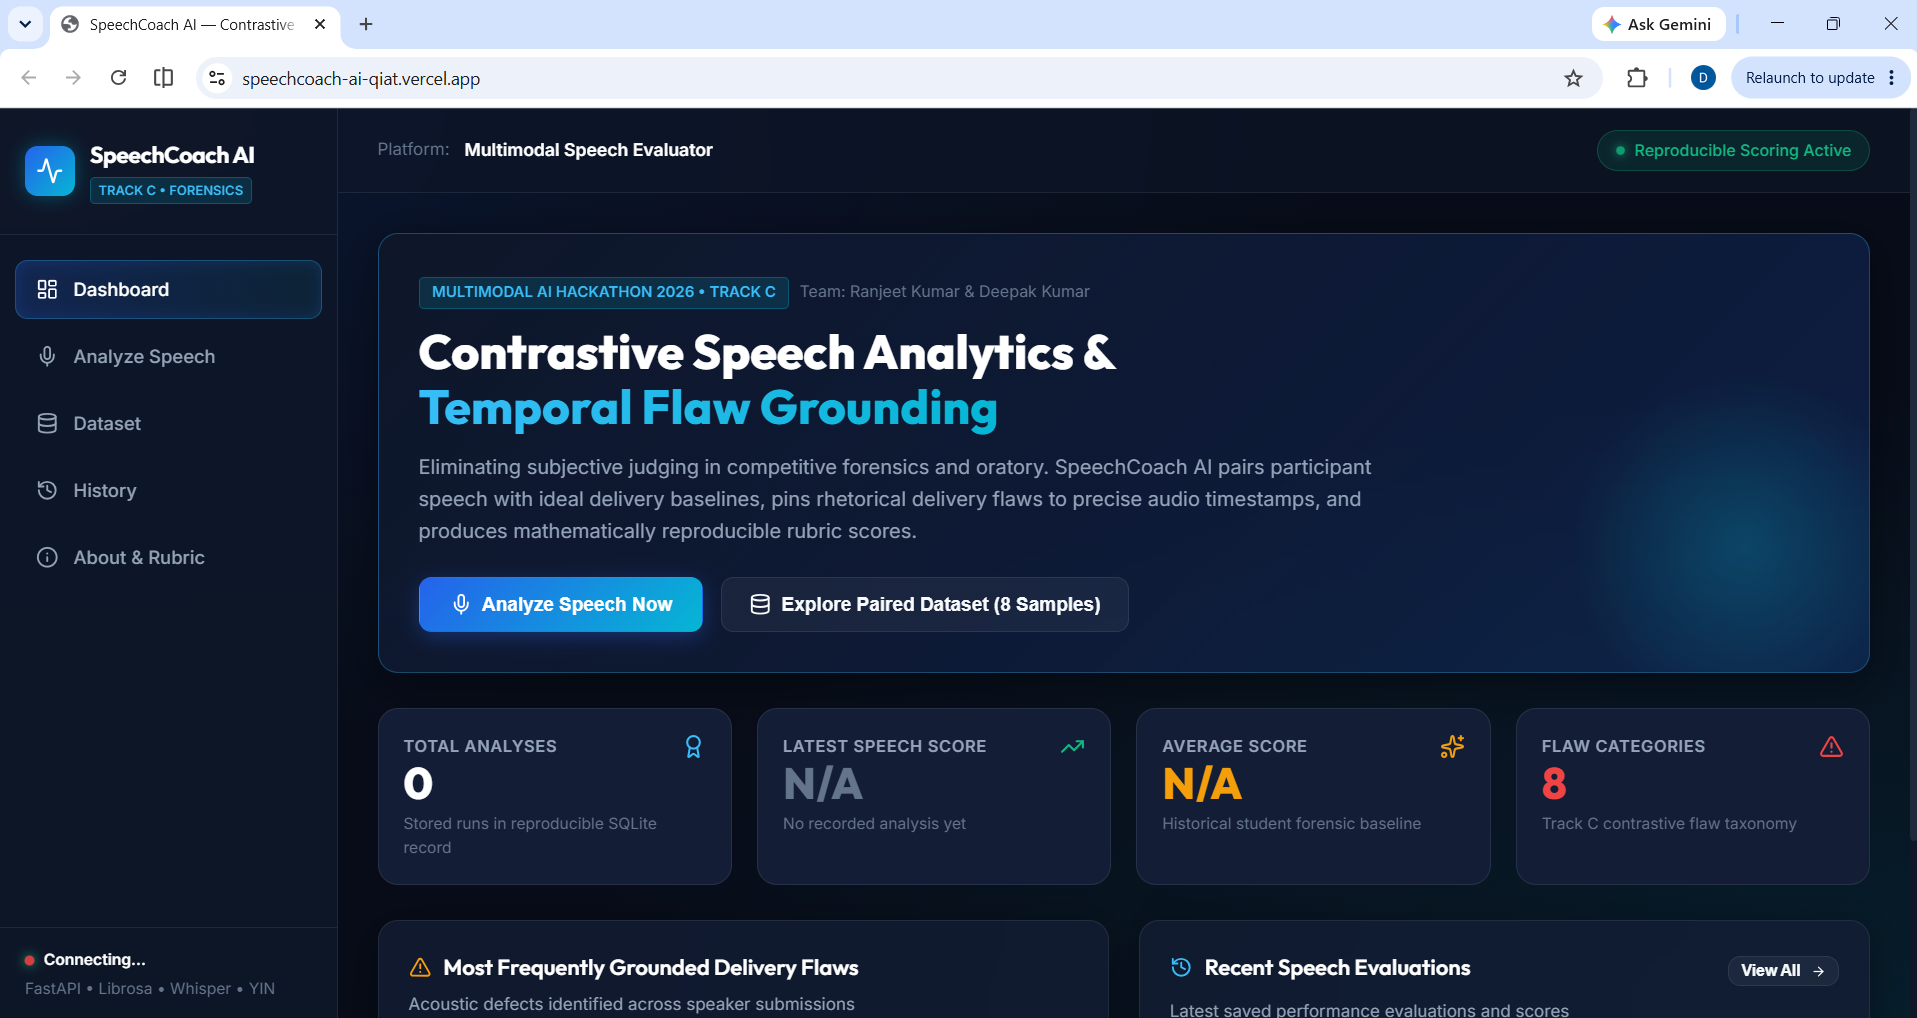
- Developing an end-to-end interactive workflow from user recording to instant multimodal feedback.
- Architecting a clean separation between the responsive Vite client and the asynchronous FastAPI backend.
- Creating an intuitive, user-friendly dashboard that makes speech evaluation feel encouraging rather than critical.
What we learned
- Deeper insights into multimodal model integration, real-time media handling, and asynchronous API architectures.
- Best practices for optimizing inference pipelines and handling heavy dependency trees in cloud environments.
What's next for SpeechCoach AI
- Live Facial & Body Gesture Tracking: Incorporating computer vision to assess eye contact, facial expressions, and posture.
- Customized Persona Scenarios: Adding tailored practice modes for job interviews, academic defenses, and TED-style keynote speeches.
- Progress Tracking Over Time: Long-term analytics to chart improvement across multiple practice sessions.
Built With
- fastapi
- javascript
- multimodalai
- python
- react
- tailwindcss
- vite
