Problem
Campus support inboxes mix access, fee, timetable and maintenance requests. A classifier can hide uncertainty or route a message incorrectly. Sort with Evidence keeps the final label with a reviewer and makes its evidence inspectable.
Working solution
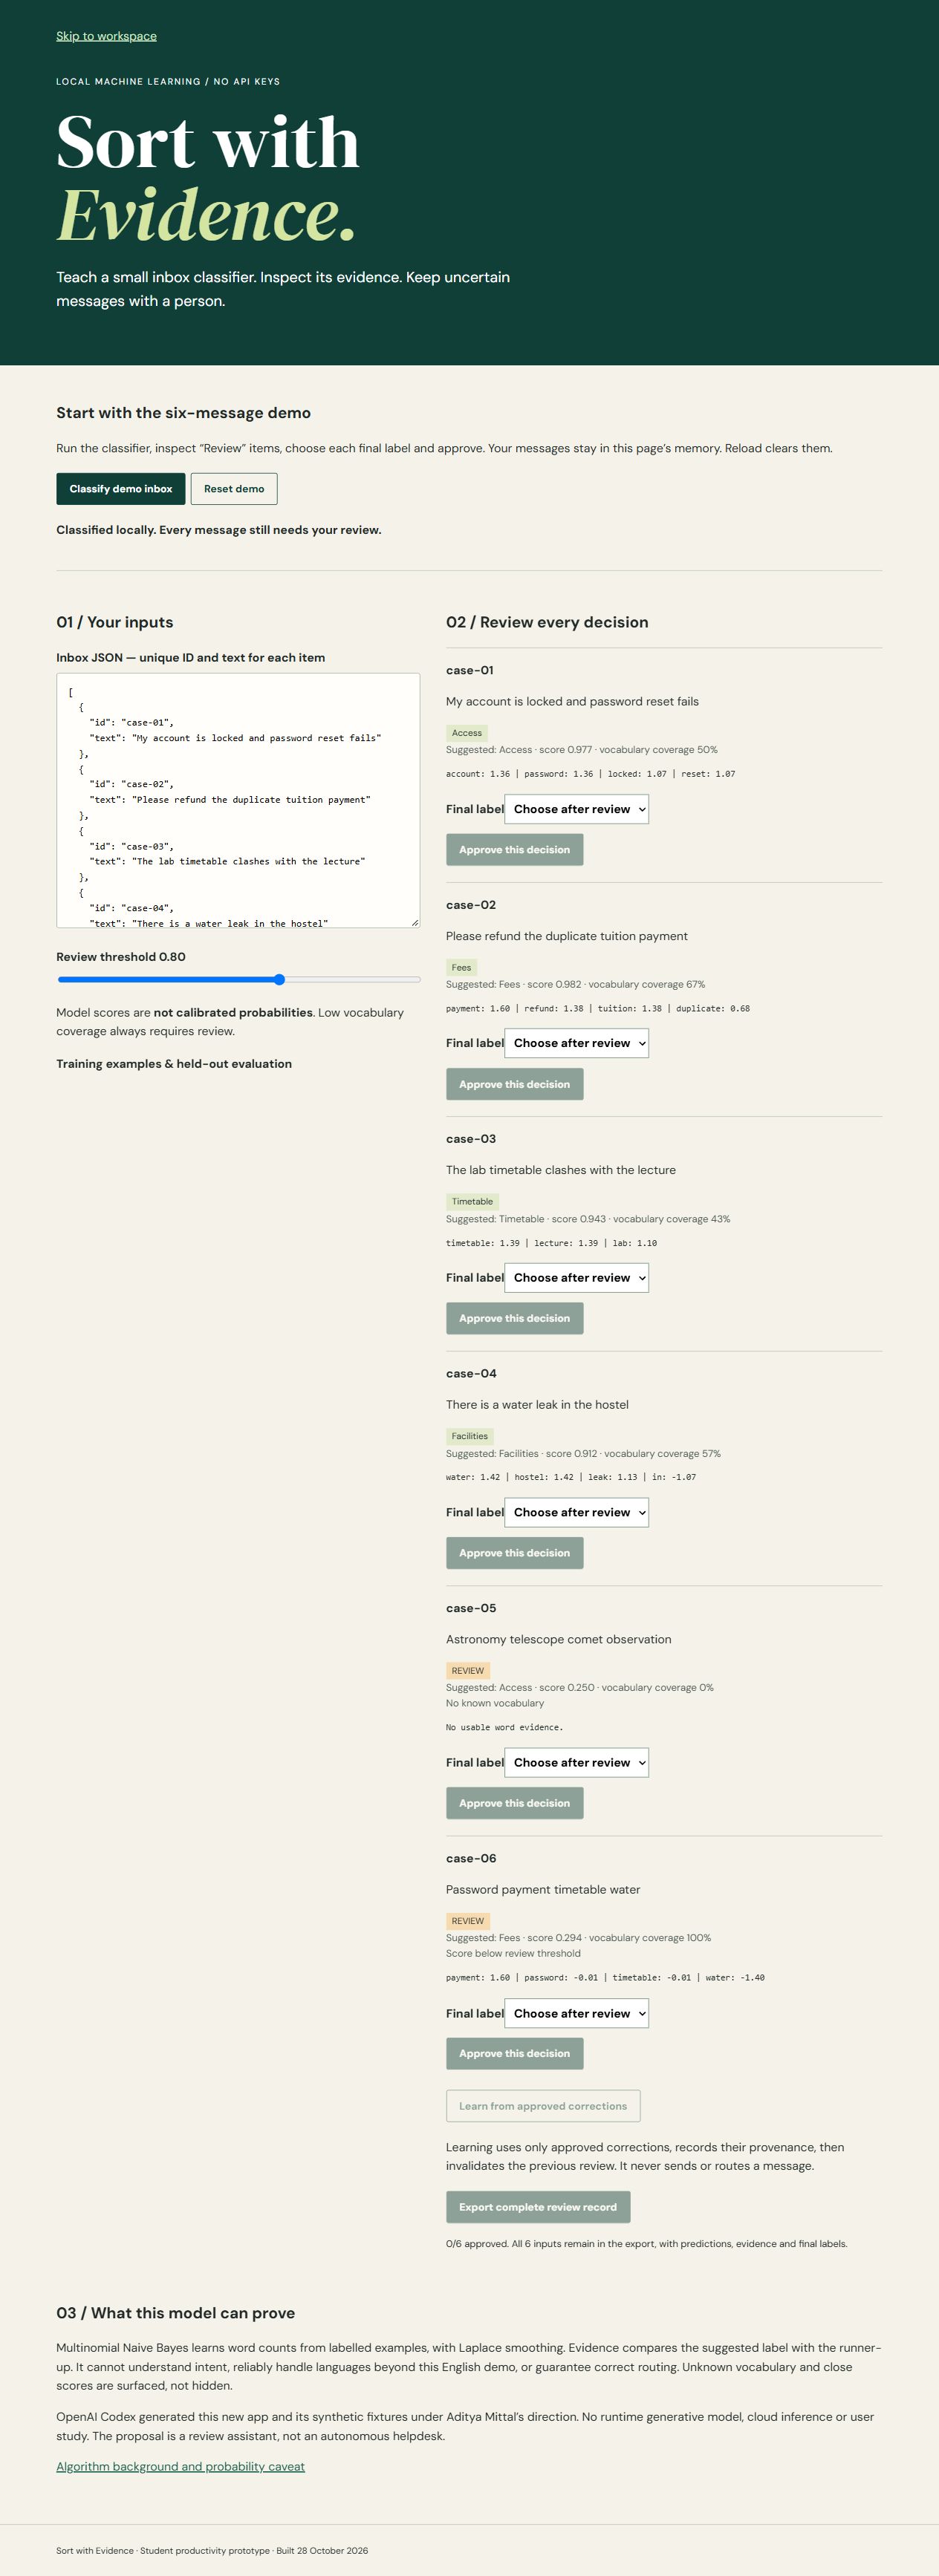
An actual browser-local multinomial Naive Bayes model learns word counts from labelled examples with Laplace smoothing. Each message shows the suggested label, uncalibrated score, vocabulary coverage and words favoring the top label over its runner-up. Unknown or ambiguous messages are flagged REVIEW and can remain Unassigned. Every final decision requires approval. Editing data invalidates review; approved corrections can train a new model with provenance. Export includes every input, prediction, evidence, final label, approval, training example and correction history. Nothing sends or routes messages.
Implementation and attribution
OpenAI Codex generated all new JavaScript, interface, tests, original synthetic fixtures and documentation on 28 October 2026 under Aditya Mittal’s direction. No previous competition code was reused. There is no runtime generative model or cloud API; this is supervised machine learning, not a chatbot wrapper. The standard algorithm is explained in the linked scikit-learn documentation; our implementation has no runtime package dependencies. Google Fonts supplies typography and receives no message payloads.
Verification
A hand-calculated two-class example independently checks a 0.75 posterior. Eight separate synthetic held-out messages produce eight correct suggested labels; this small, narrow fixture is not real-world accuracy. Tests cover overlap and duplicate IDs, input bounds, score normalization and unknown vocabulary. Browser checks cover all six reviewed inputs and an independently parsed downloaded audit, invalid-input rejection, approved correction provenance and review invalidation. A focus-loss bug caused by replacing a select was fixed. Narrow 390px embedded layout/core classification was checked; no physical phone test is claimed.
Demonstration screenshots
Limits and next steps
English-only synthetic demo vocabulary, uncalibrated scores and no field validation. No real correspondence, interviews, independent human implementation, savings or deployment impact claimed. Next: consented labels, drift and calibration evaluation against real held-out data, multilingual support and explicit routing policies. Personal learning reflections will be supplied only from actual entrant experience.
