-
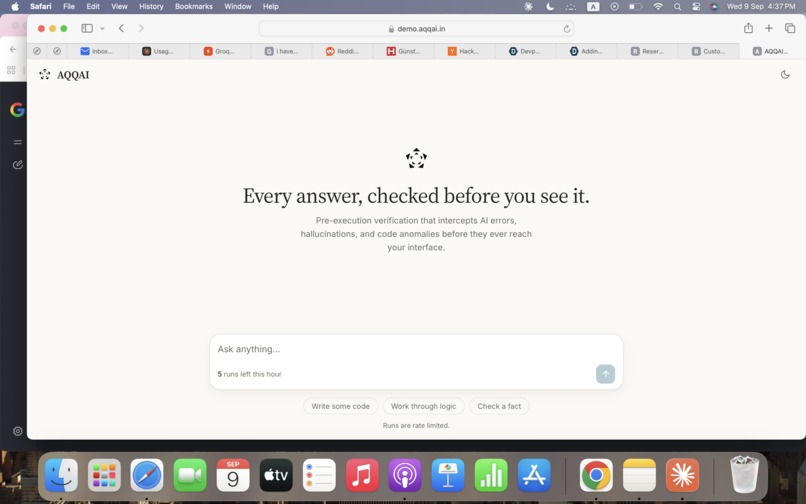
this is how it looks like
About the Project
The Inspiration
We are entering an era where businesses are moving from basic AI chatbots to autonomous AI agents that act on data. But there is a massive problem: Large Language Models (LLMs) have a baseline hallucination rate of 1.5% to 3.3%. They sound incredibly confident and fluent even when they are completely wrong—whether generating broken code, wrong math, or false data.
For companies, an unmitigated AI failure averages $4.4 Million in damages. But there is an unseen environmental crisis too. When an AI outputs broken data or syntax exceptions, it triggers automated downstream retry loops. These infinite background loops silently waste massive amounts of server power and cloud data center electricity. We built AQQAI to stop this.
How We Built It
AQQAI is an API-driven proxy gateway middleware platform that catches AI mistakes in real time before they reach a user's interface. Instead of running downstream log analyzers that report bugs after the damage is done, we built a proactive, pre-execution verification runtime layer.
The architecture operates in three clean, containerized layers:
- Layer 1 (Adversarial Routing): Incoming queries run concurrently across three independent foundation models to keep error distributions uncorrelated.
- Layer 2 (Mechanical Validation): The outputs pass through hard-coded python validation stacks: Natural Language Inference (NLI) scoring for context grounding, symbolic math logic boundaries, and secure Docker container runtimes to compile and test code strings under sub-second constraints.
- Layer 3 (Referee Fusion): A specialized referee model scores consensus. If metrics drop below safe boundaries, an automated low-consensus override trapes the error.
Our pipeline decisions are grounded strictly in peer-reviewed academic research on uncorrelated error aggregation, proving mathematically that combined results can significantly exceed single-model accuracy bounds:
$$ \text{Accuracy}{\text{Fused}} > \max(\text{Accuracy}{M_1}, \text{Accuracy}{M_2}, \text{Accuracy}{M_3}) $$
Challenges We Faced
The absolute biggest challenge was optimizing the latency overhead. Running multiple validation checks—especially compiling code inside isolated Docker sandboxes—can easily lag system responsiveness. We spent weeks rigorously profiling our Python container runtimes and in-memory workflows to harden execution paths, successfully dropping our verification cycles under active sub-second performance limits.
What We Learned
We learned that true AI safety cannot happen downstream, and foundation providers cannot grade their own homework. Enterprises building high-stakes applications require an independent, model-agnostic proxy layer to scale safely. On top of that, we realized that active error prevention is a highly effective Green Computing lever, cutting down massive amounts of digital energy waste at the core infrastructure layer.
Built With
- computing
- containerization
- devtools
- gatewayllm
- observabilitygreen
- pythonai
- safetymlopsdockerapi
- symp
