-
-
-
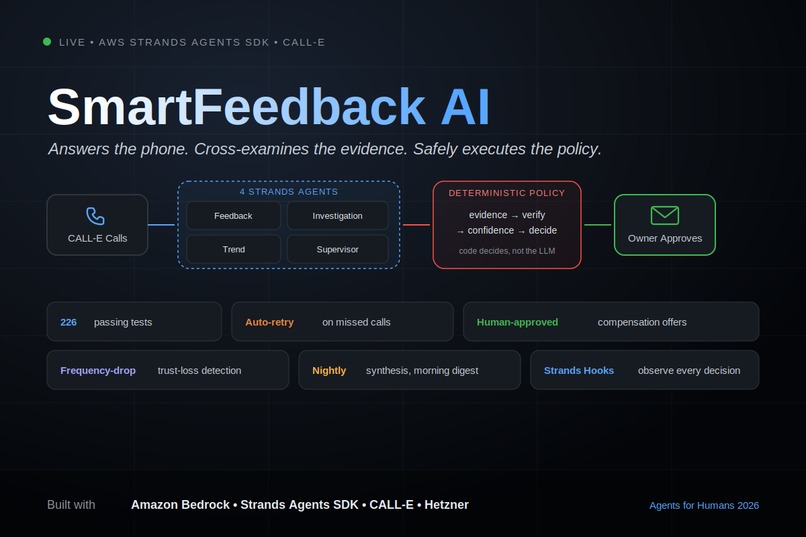
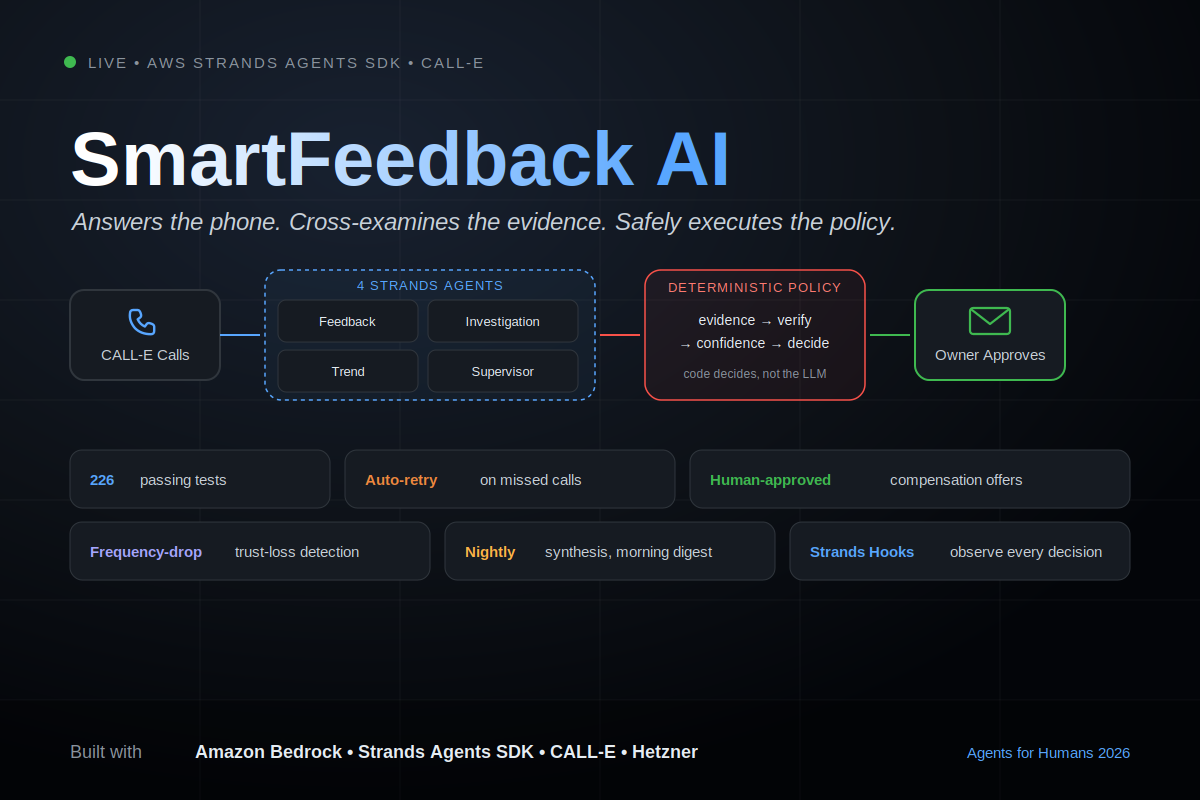
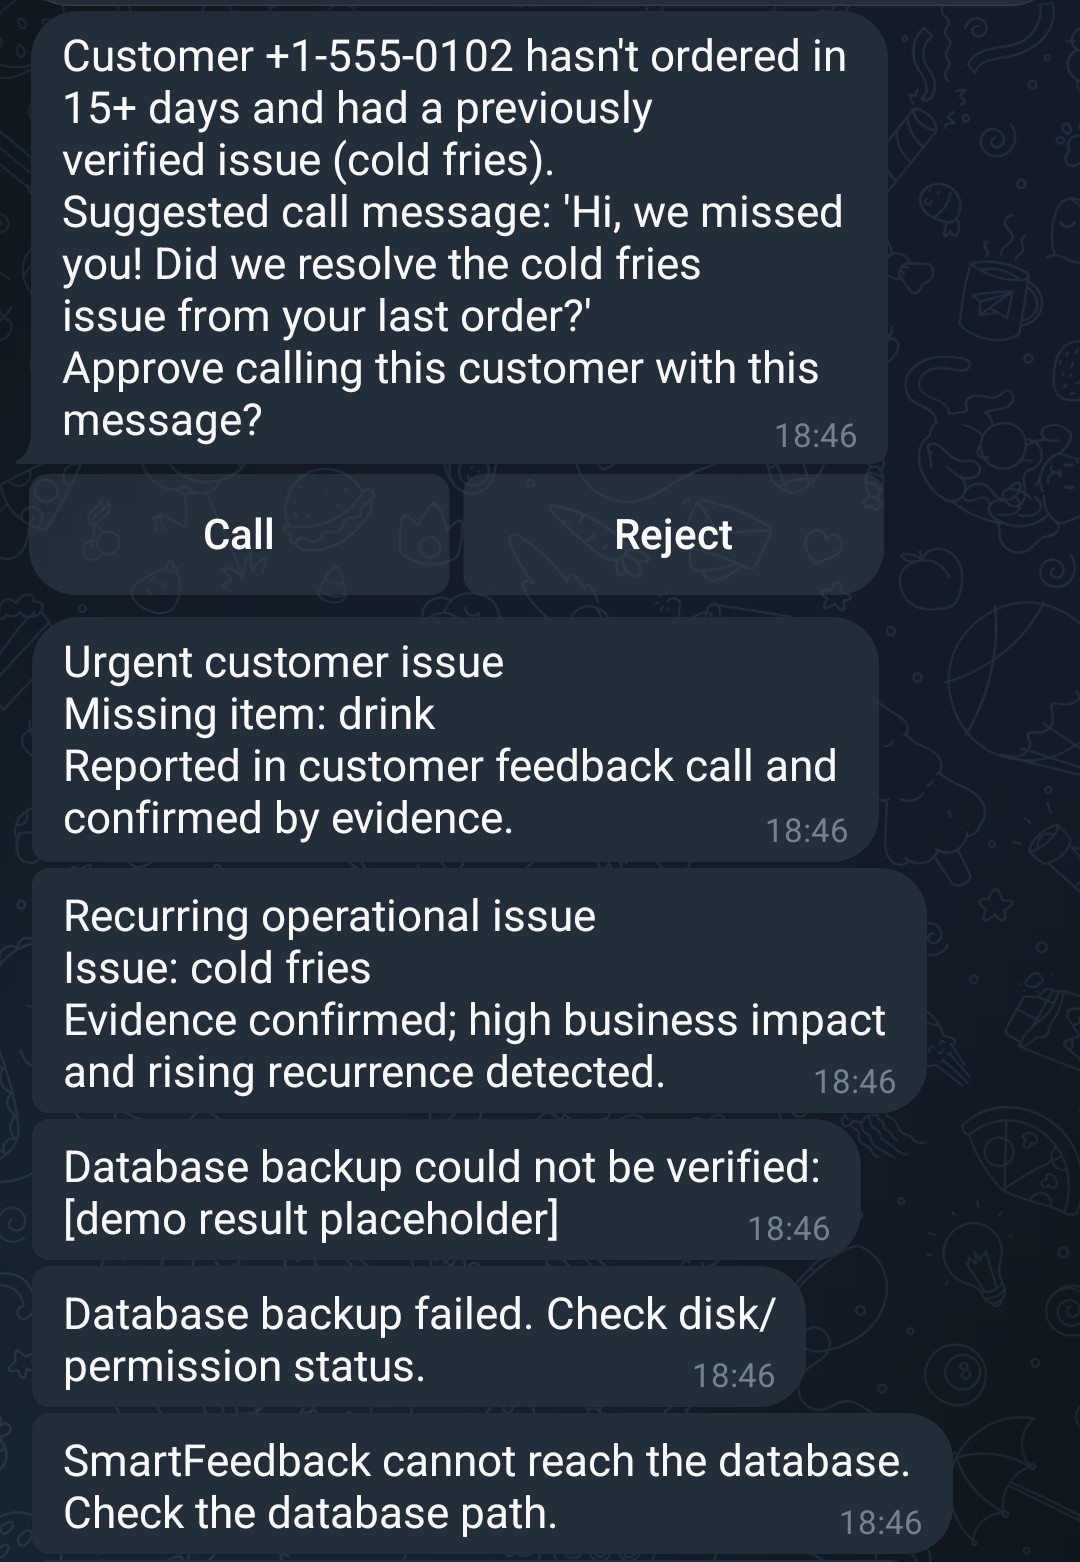
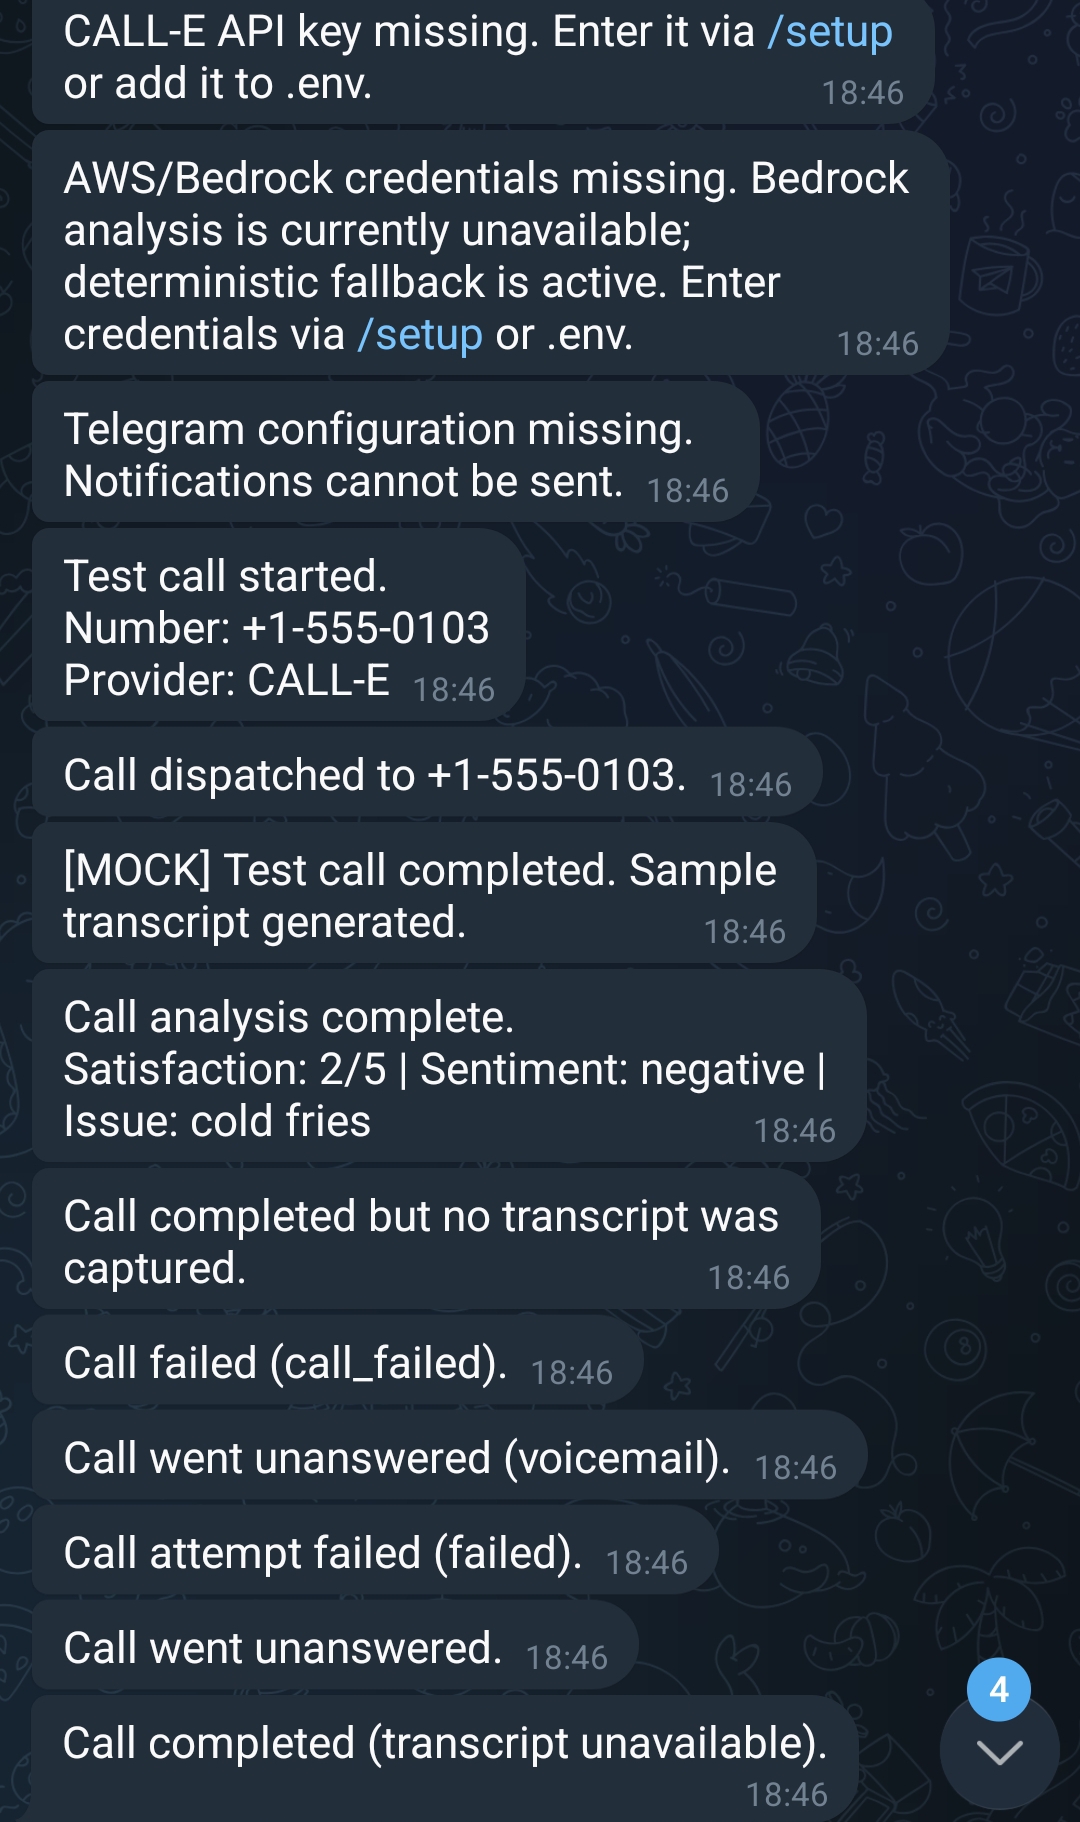
Order triggers a CALL-E call. Four Strands agents analyze it. A deterministic policy — not the LLM — decides, pending approval.
-
-
-
Inspiration
Finding the right idea was the hardest part for me — I spent days circling different directions before it clicked. A few months ago, I had used a service and, weeks later, got an email asking me to rate my experience. By then I had already forgotten the details, and I never engaged with it.
That's the moment it clicked — but the deeper problem wasn't just "feedback arrives too late." The real problem is that most "smart" feedback tools blindly trust whatever an LLM summarizes. If a model says "the customer was unhappy," nobody checks whether that's actually true. I wanted to build a system that never trusts a claim without evidence — one where the LLM's interpretation is never the final word.
The moment we locked in this idea (September 10th), we went straight into building. Everything you see here was built in the last five to six days.
What it does
1. A four-agent, structured analysis pipeline — the heart of the system Four agents run on the Strands Agents SDK:
- Feedback — extracts sentiment, satisfaction score, and the specific issue mentioned
- Investigation — looks up this exact customer's order and complaint history in the database
- Trend — checks whether this issue is isolated or part of a rising pattern across the business
- Supervisor — reconciles all three and proposes an action
Every agent's output is structured, not free text (Pydantic models) — the next agent in the chain doesn't have to guess what the previous one "meant"; it receives a well-defined schema.
2. A deterministic decision layer — the most important architectural decision in this project The Supervisor's proposal is never applied directly. A separate, fully deterministic Python layer computes two scores:
- Confidence score = evidence quality × verification rate × signal strength × sample size
- Impact score = recurrence × severity × number of affected customers × trend direction × recency
No alert fires and no compensation offer is generated until both scores clear defined thresholds. Every claim has to be tied to an exact span of the transcript — if the LLM says "the customer was angry," the system checks where in the transcript that's actually stated. If it isn't, the claim is rejected.
3. Observability through Strands Hooks — never influence We used BeforeToolCallEvent/AfterToolCallEvent hooks to observe every step of this deterministic decision as it happens. But the policy function itself is deliberately kept outside the reach of any LLM-facing agent — the hook can only watch and log; no LLM can ever reach it or influence it. Transparency and control are completely separated by design.
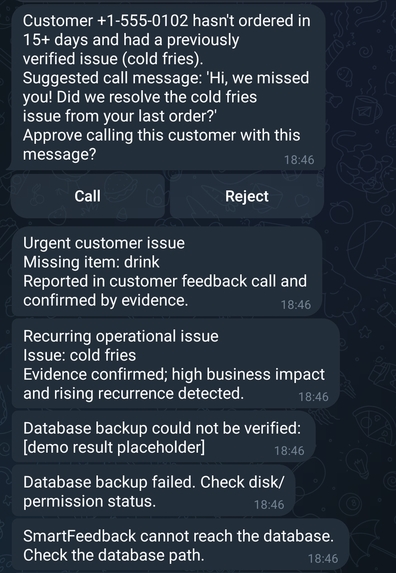
4. The input channel: a real phone call Where does this pipeline's input actually come from? Thirty minutes after an order is marked as fulfilled, the system places a real outbound call to the customer through CALL-E, while the experience is still fresh. The business owner can delay this timing from Telegram, and if the customer doesn't answer, the system automatically retries once before giving up. But this is just the data-collection mechanism — the real value is in what happens to that data afterward.
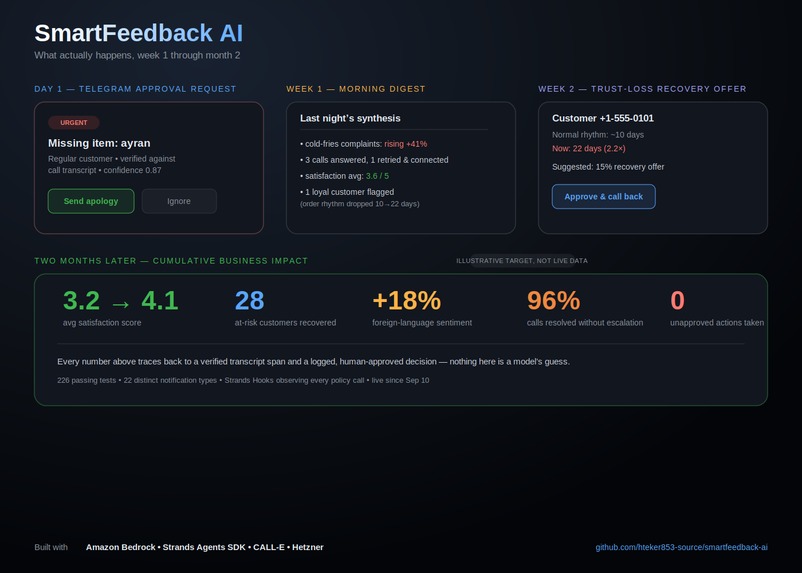
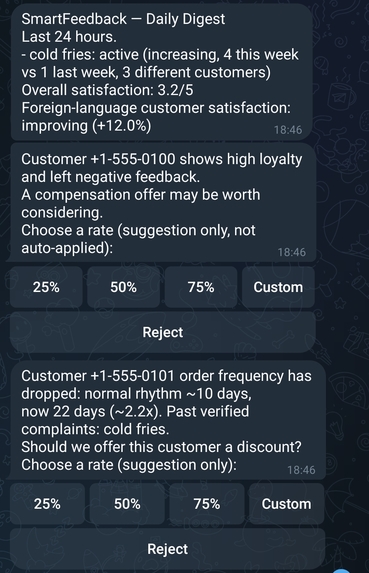
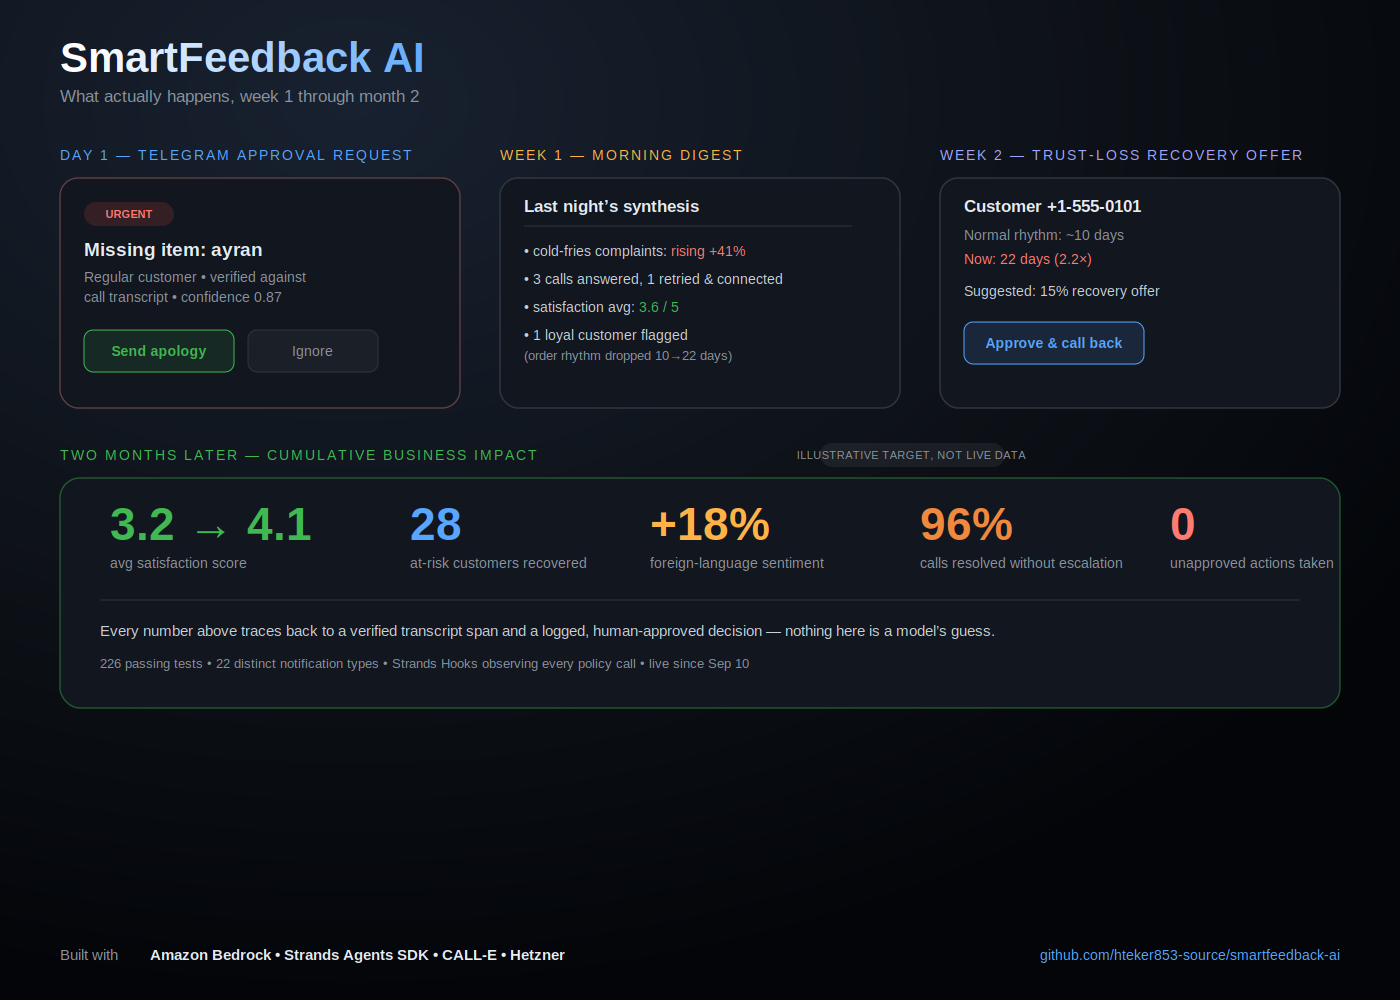
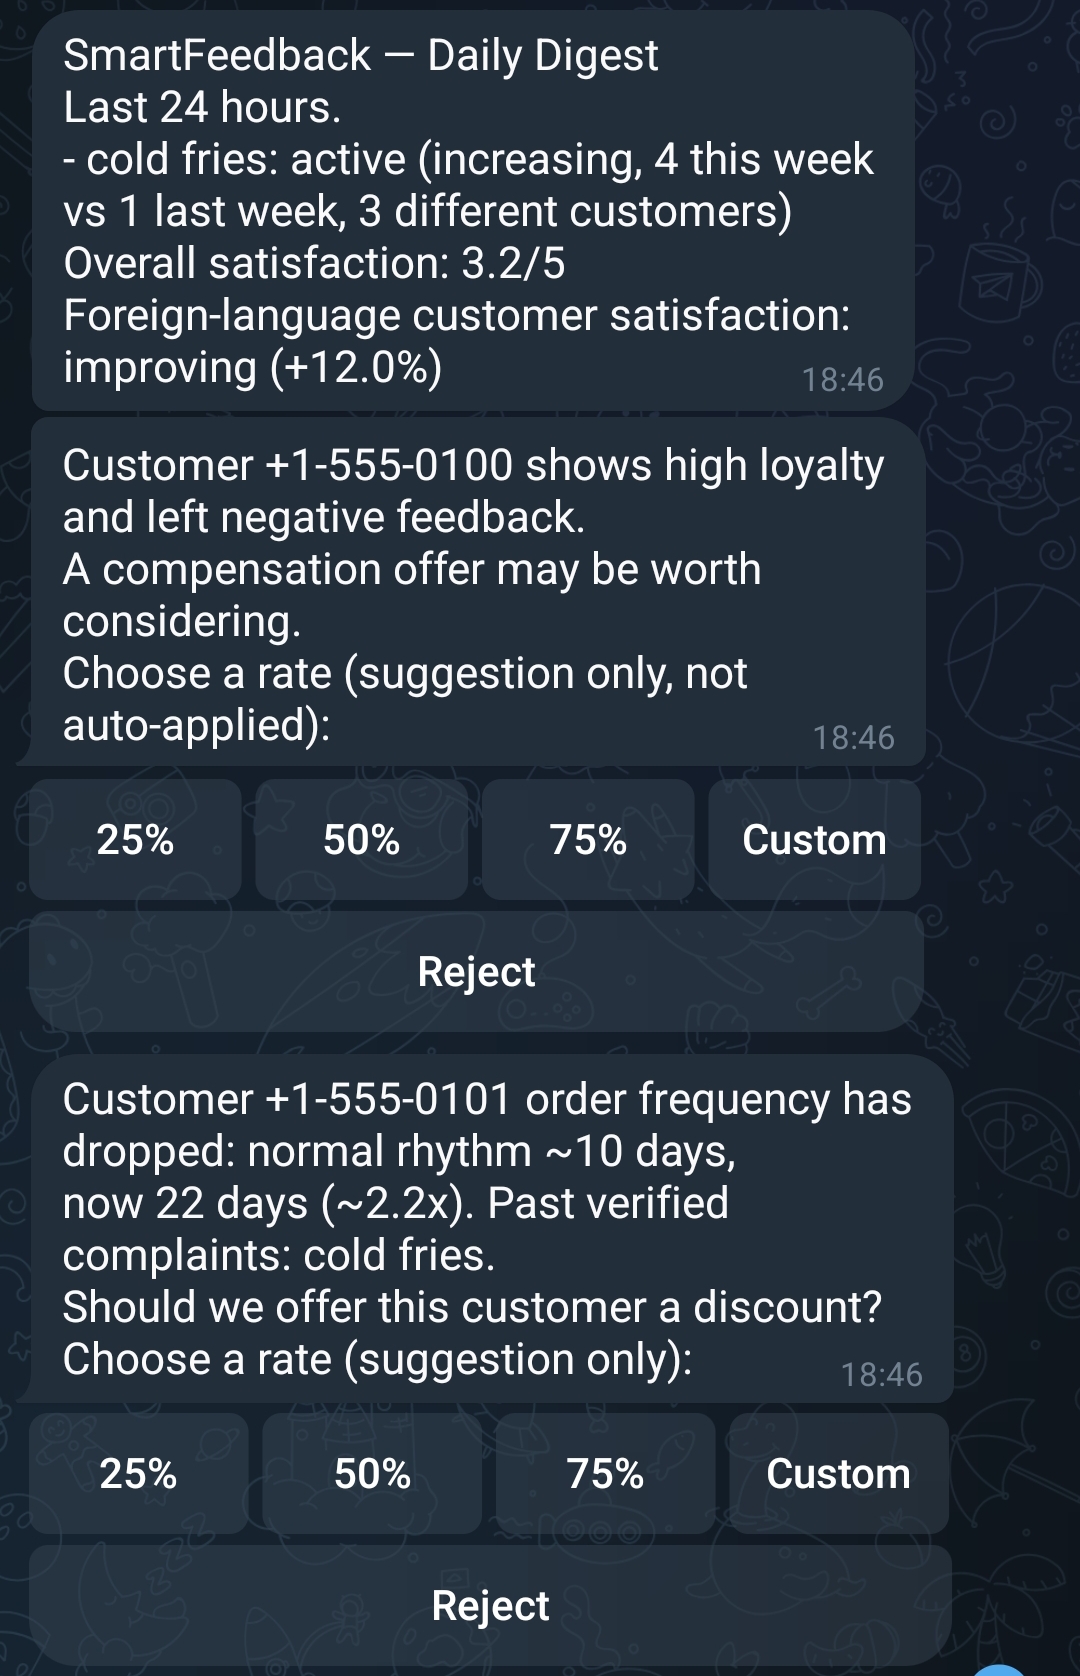
5. Loyal-customer trust-loss detection — the agents' background work The system calculates each customer's historical ordering rhythm. When that rhythm breaks down noticeably (for example, stretching from 10 days to 20+), it's flagged as a possible trust-loss signal, and a personalized recovery offer is proposed — again pending the owner's approval.
6. Nightly analysis, morning delivery Every night after closing, that day's data is analyzed, but the digest isn't sent immediately — it's delivered the next morning, an hour before opening.
7. Separate trend tracking by language Satisfaction trends for customers speaking a language different from the business's default are tracked separately, so language-driven dissatisfaction doesn't disappear inside an aggregate average.
Security
Customer phone numbers are stored in the database, but we didn't assume they stay private — we verified it. We audited every single GET endpoint in the system one by one: none of them return the raw customers.phone field; only an internal numeric customer_id is ever exposed externally. Every SQL query is parameterized — there is no raw string concatenation anywhere that could create an injection risk, which we also confirmed by scanning the entire codebase.
We also audited, category by category across 10 separate credential types (Telegram bot token, CALL-E API key, AWS credentials, LLM API keys, and more), that no real secret ever leaked into any GitHub commit or pull request — both in the main repository and in the open-source contribution repository. Both came back clean.
How we built it
The Strands Agents SDK orchestrates the four-agent pipeline, designed around Amazon Bedrock as the primary reasoning provider. Strands Hooks (BeforeToolCallEvent/AfterToolCallEvent) observe the deterministic decision as it happens, without ever being able to influence it. CALL-E handles the actual outbound calling that feeds the pipeline. The backend is FastAPI with SQLite, deployed on a small Linux server, backed by 226 automated tests.
Challenges we ran into
The biggest challenge wasn't the code — it was finding the right problem. We circled several directions for days before this one clicked. Once we locked it in on September 10th, we put everything into building a working, tested, live system in four days.
We'll be honest about where that time went: we're confident in the system itself, but we're not proud of the presentation. We didn't have time to prepare a public live-demo endpoint, and we didn't have time to polish a UI or a slide deck — this write-up and the demo video are the result of focusing every hour on making the underlying system real, tested, and correct rather than making it look polished. As we write this, there are roughly 13 hours left before this hackathon's deadline — this description is genuinely being finished at the last stretch, not written weeks in advance with time to spare.
What we deliberately chose not to build
A much easier project would have been a single-agent wrapper that just asks an LLM to summarize a call and forwards that summary as-is. Or a basic sentiment classifier with no verification step. Or a simple chatbot that answers questions about past orders. Or a one-shot "call and log" tool with no decision logic at all. Or a generic multi-agent demo where the agents just talk to each other without any real consequence. Or a dashboard that displays raw LLM output and calls it "insights."
Every one of those is a solved problem — useful, but not new.
We chose something harder on purpose: most small businesses have no feedback loop they can actually trust, and the tools that try to build one either trust an LLM's summary blindly or never verify it against anything real. We wanted to solve that specific, still-unsolved problem — a system where every decision is bound to verified evidence, never a model's best guess. . 226 automated tests passing — the same suite referenced throughout this write-up, run just before submission.

Log in or sign up for Devpost to join the conversation.