-
-
Let's get started...
-
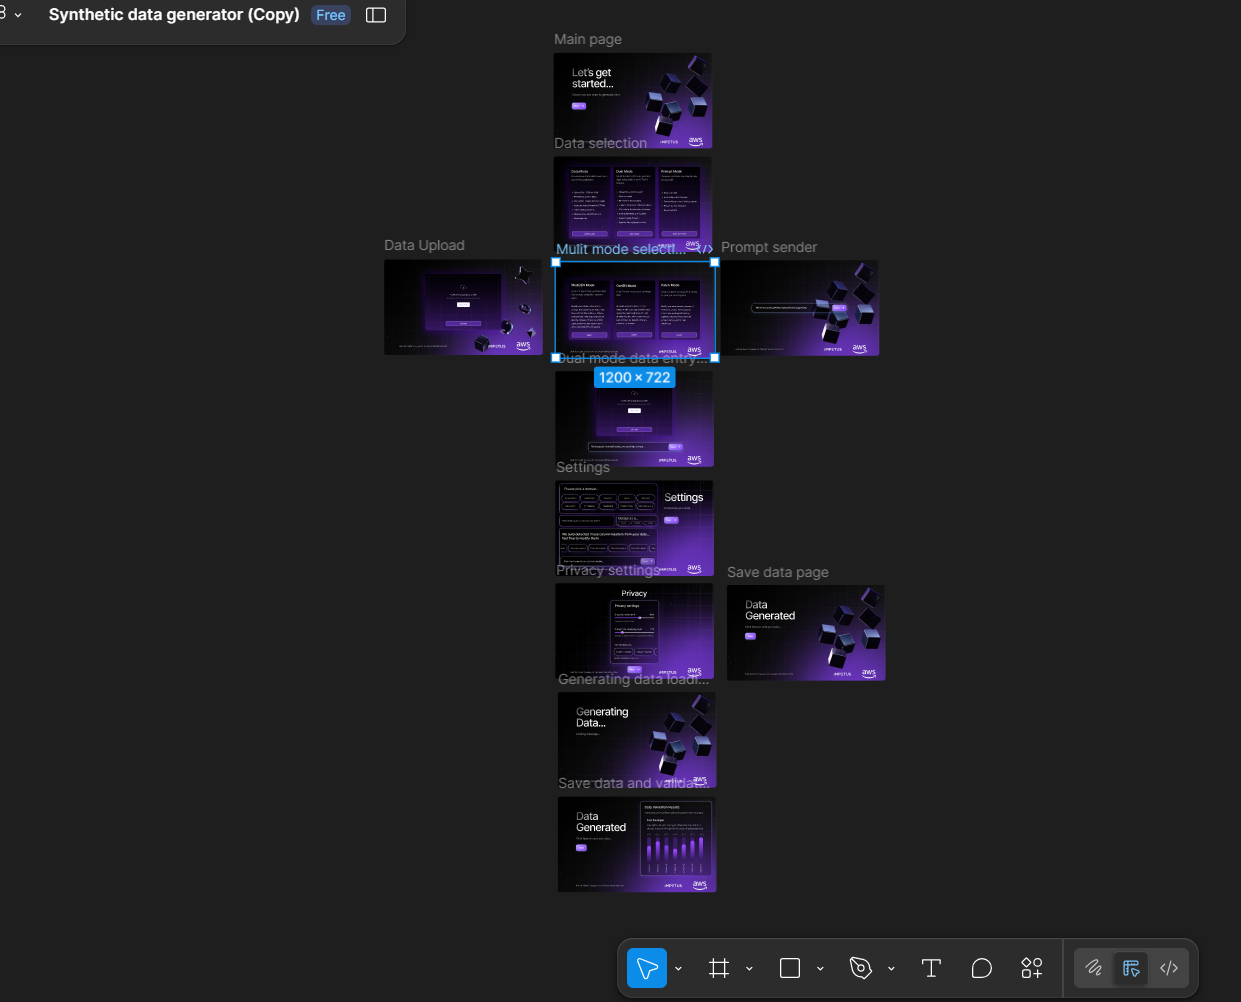
Figma Prototype - Final Download Page
-
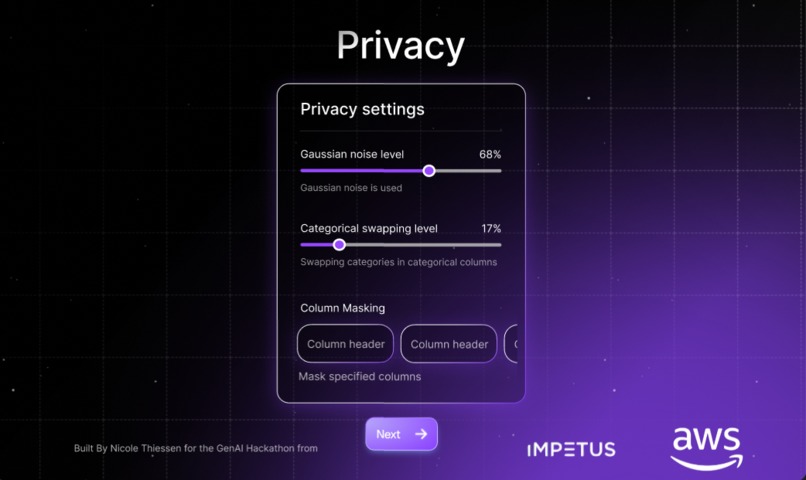
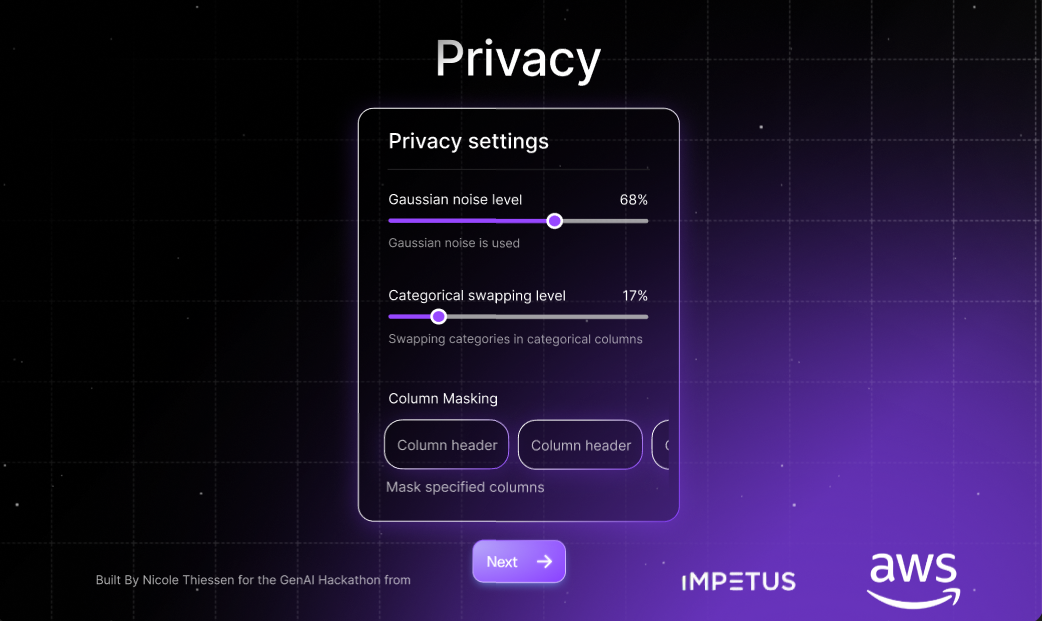
Figma Prototype - Privacy Settings
-
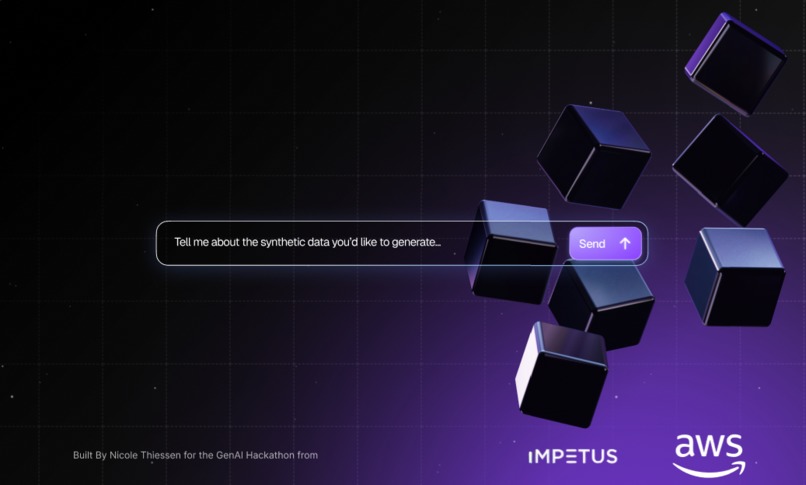
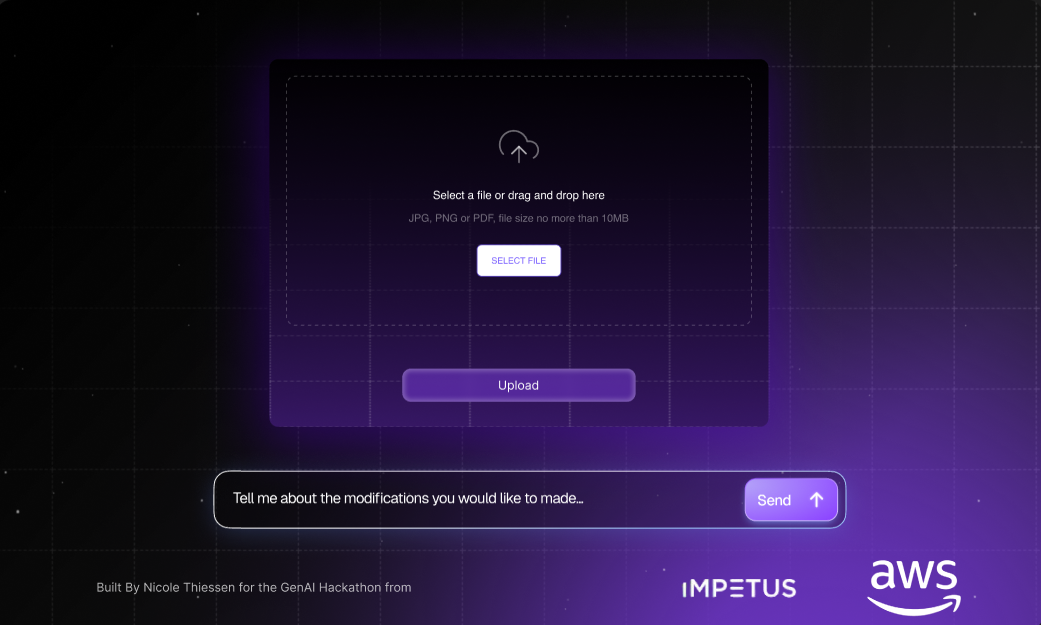
Figma Prototype - Prompt Feature
-
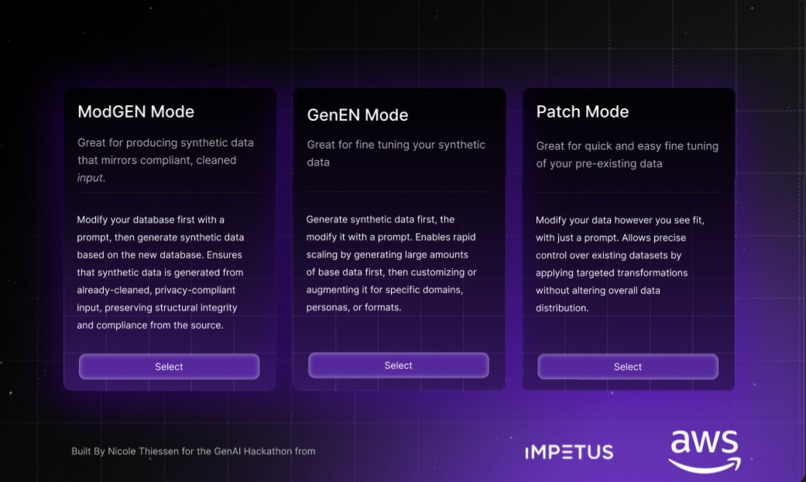
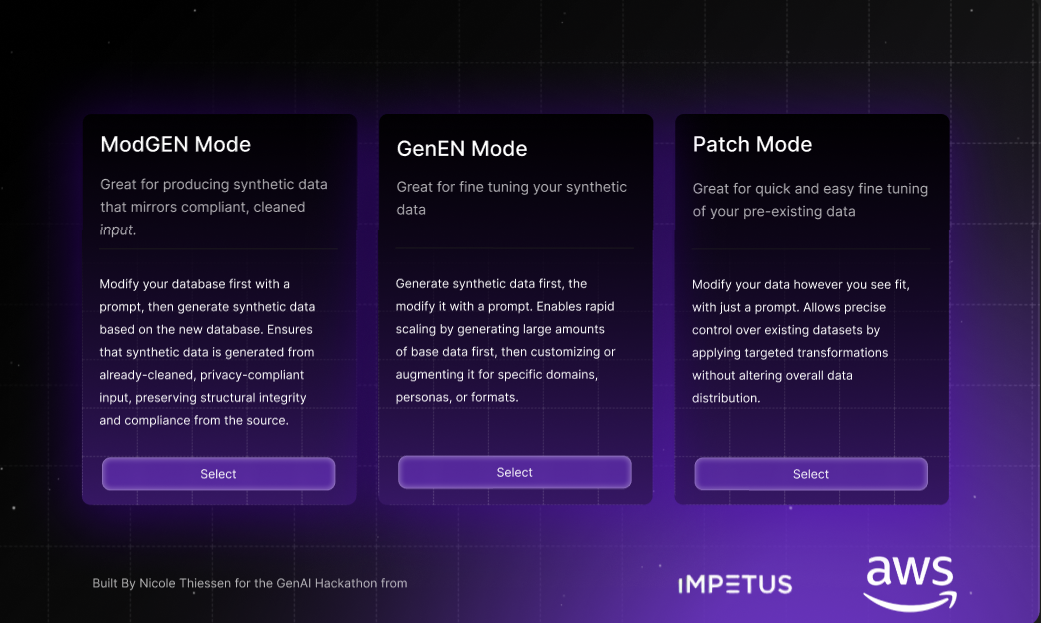
Figma Prototype - Mode Descriptions
-
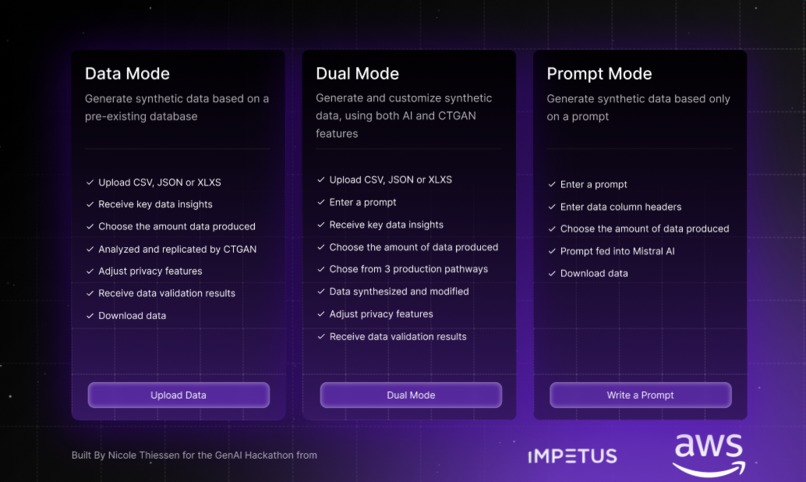
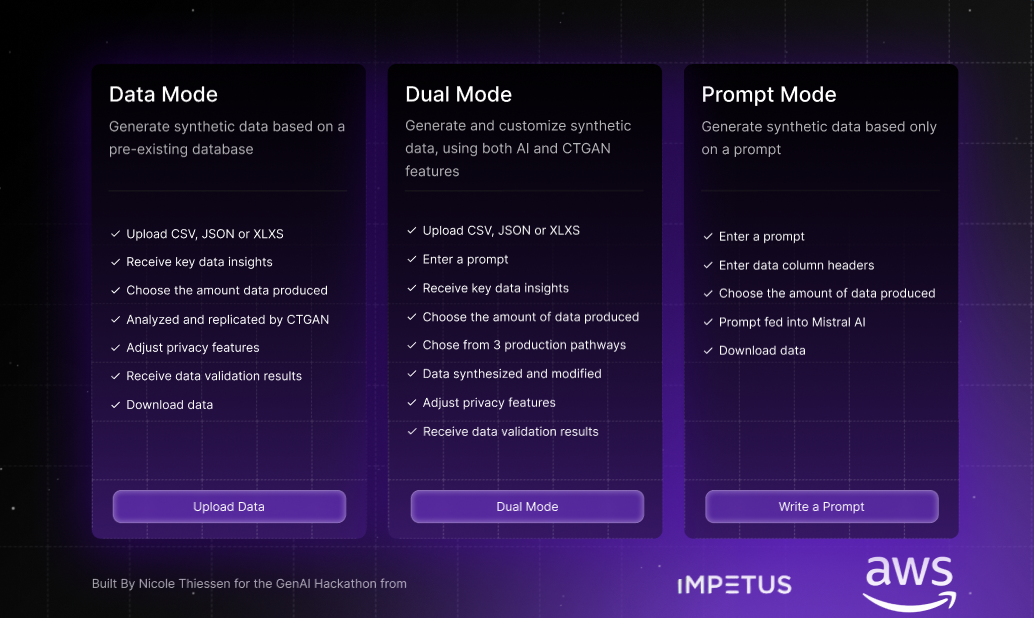
Figma Prototype - Dual Mode Descriptions
-
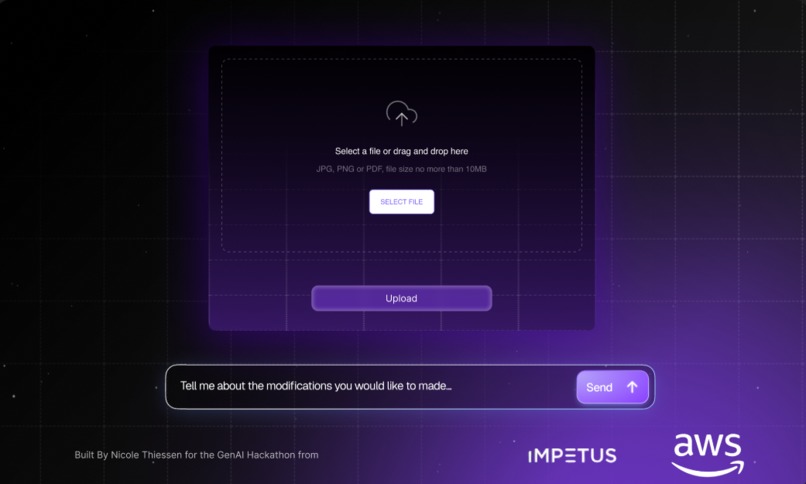
Figma Prototype - Dual Mode
-
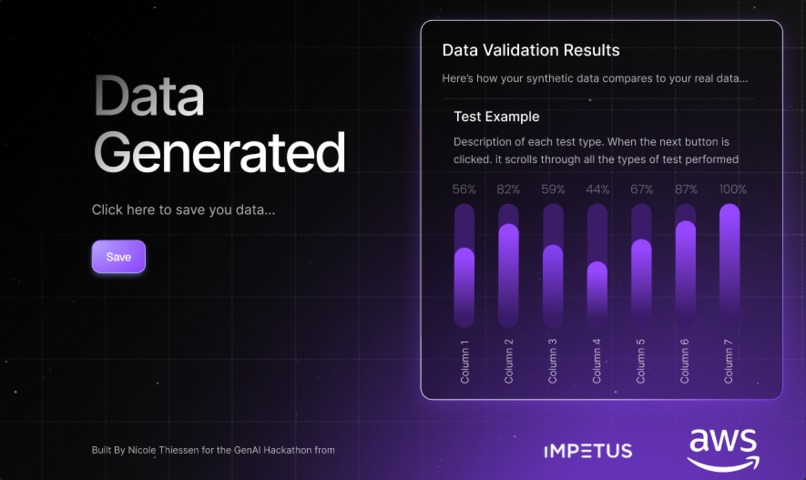
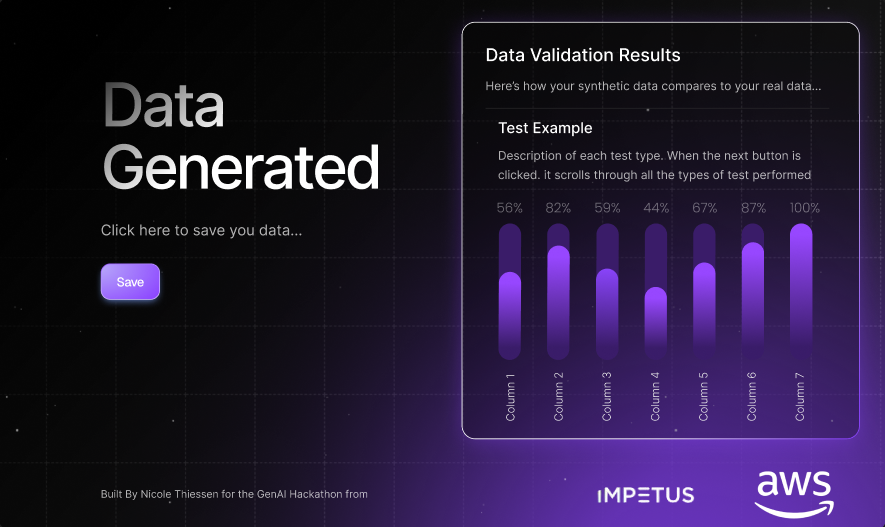
Figma Prototype - Validation Page
-
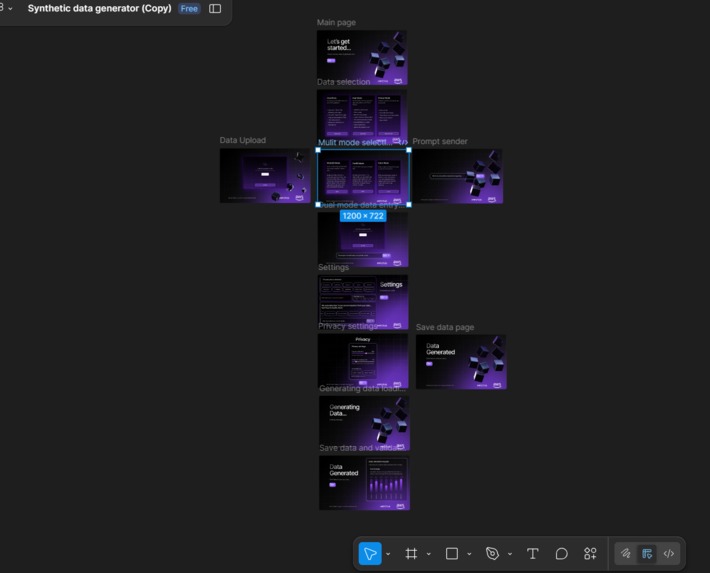
Figma Full Layout
-
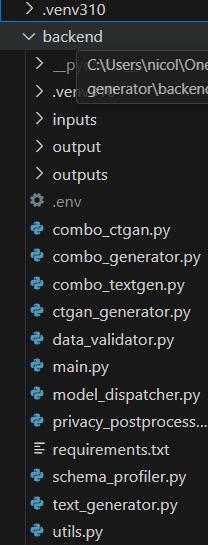
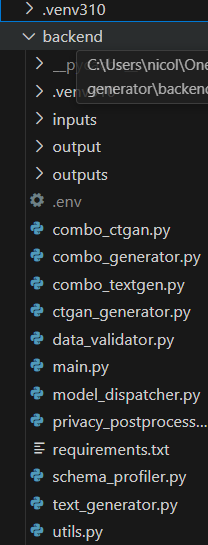
Backend Folder
-
Frontend Folder
-
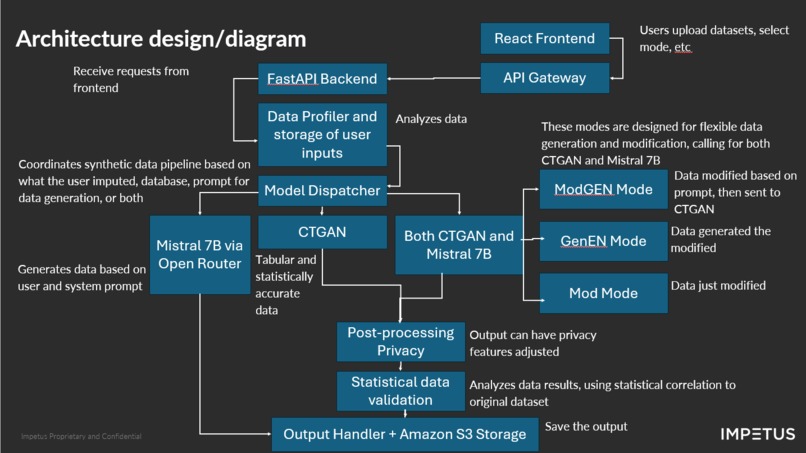
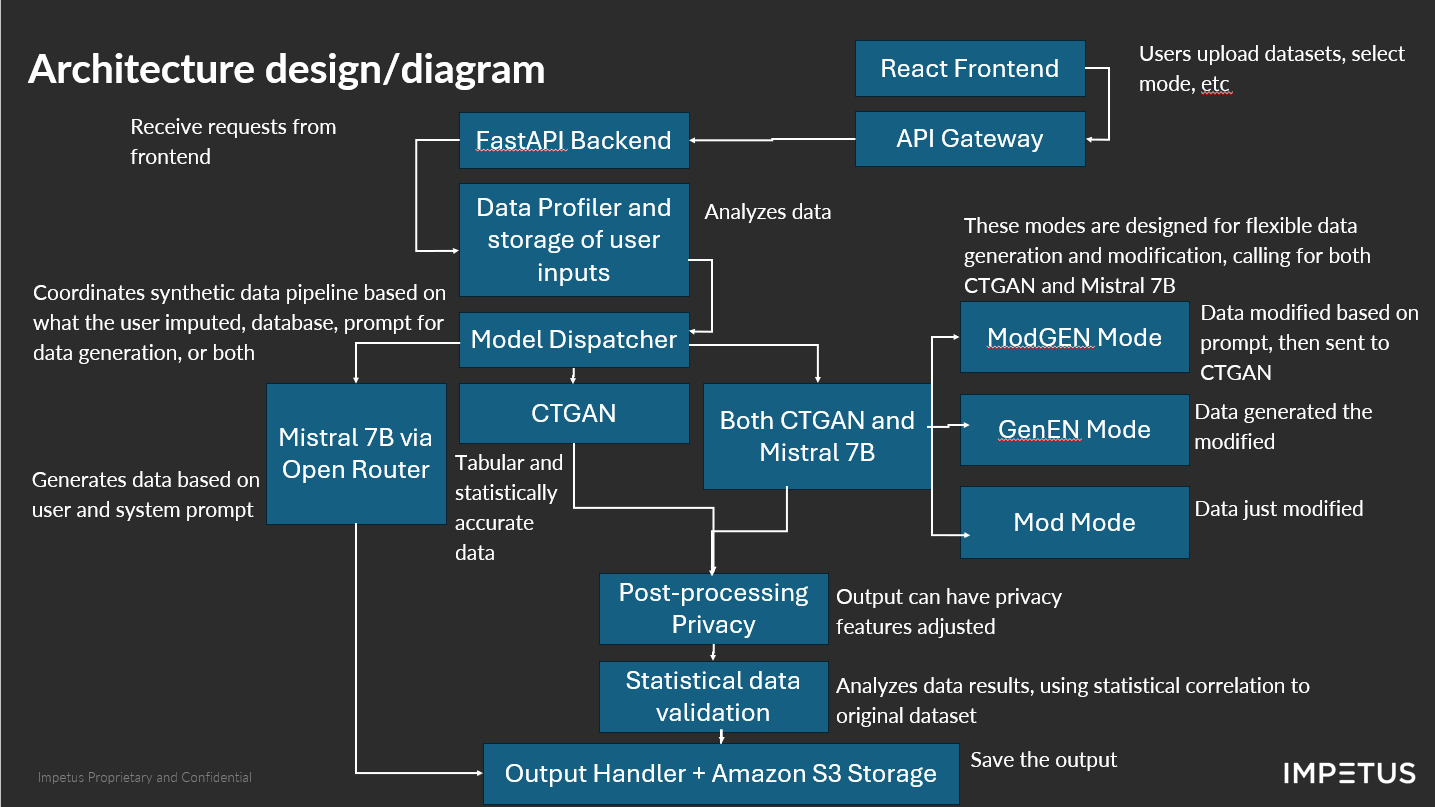
Full Architecture
Inspiration
Data is the backbone of every successful AI project, but collecting real-world datasets is often costly, time-consuming, and fraught with privacy concerns—especially in domains involving sensitive or proprietary information. As someone working on robotics inspired by Iron Man’s Jarvis, I needed a way to generate rich, realistic, and privacy-preserving synthetic data to train AI models without risking exposure of real user or operational data. Existing tools lacked flexibility in combining synthetic data generation with AI-driven enrichment and privacy controls in a user-friendly package. This motivated me to build a Smart Synthetic Data Generator that addresses these gaps.
What it does
The Smart Synthetic Data Generator is a versatile platform that enables users to create synthetic datasets through three key modes:
ModGen (Modify then Generate): Users modify their original dataset with privacy techniques like Gaussian noise, category swapping, and column masking, then generate synthetic data from the modified dataset using CTGAN.
GenEn (Generate then Enrich): Users generate synthetic data directly from a base dataset using CTGAN, then enrich it with detailed context and transformations powered by a large language model (Mistral 7B) based on customizable prompts.
Mod (Modify Only): Users apply privacy-preserving modifications to their existing datasets without generating new synthetic data.
The tool integrates AI enrichment, privacy postprocessing, and flexible generation pipelines through an intuitive React frontend and FastAPI backend.
How we built it
The project combines several cutting-edge technologies:
- CTGAN: A generative adversarial network specialized for tabular data that learns complex feature relationships to create realistic synthetic samples.
- Privacy Postprocessing: Custom implementations of Gaussian noise addition, category swapping, and column masking help users protect sensitive information before or after data generation.
- AI Enrichment Module: Leveraging the Mistral 7B language model via OpenRouter API, the system adds narrative details, fills missing information, and reshapes data based on user-provided natural language prompts.
- Frontend & Backend: The React-based UI provides seamless user interaction, while a FastAPI backend orchestrates the CTGAN generation, privacy functions, and AI enrichment calls.
- Multi-Mode Architecture: The pipeline supports flexible workflows (ModGen, GenEn, Mod) to cover a wide range of synthetic data needs.
Challenges we ran into
- Balancing Privacy and Data Utility: Applying privacy techniques without overly degrading the quality of generated data was a careful balancing act, requiring tuning of noise and masking parameters.
- Seamless Integration: Coordinating between the CTGAN model, privacy modules, and AI enrichment in a modular yet smooth workflow demanded thoughtful architecture design and API handling.
- File Format Support: Supporting different output formats (CSV, JSON) and ensuring consistent saving/loading without errors, especially during multi-stage processing, required debugging and pipeline refinement.
- Managing API Latency and Costs: Efficiently integrating calls to the Mistral 7B model while minimizing response times and API usage was critical for a responsive user experience.
Accomplishments that we're proud of
- Successfully built a multi-mode synthetic data generator that combines GAN-based generation, privacy postprocessing, and AI-driven enrichment in one cohesive tool.
- Developed an intuitive UI that empowers users with granular control over data privacy settings and enrichment prompts.
- Demonstrated the tool’s versatility by generating rich, narrative-enhanced “Iron Man” datasets suitable for AI training and simulation.
- Opened the door for domain-agnostic synthetic data workflows that can accelerate AI development across industries with sensitive or limited data.
What we learned
This project deepened my understanding of:
- The practical tradeoffs involved in privacy-preserving synthetic data generation.
- How GANs like CTGAN model complex tabular data distributions.
- The potential and challenges of combining large language models with traditional data synthesis pipelines.
- Building modular AI systems with clean separation between data generation, privacy, and enrichment.
- Frontend-backend integration for a smooth user experience in AI tools.
What's next for Smart Synthetic Data Generator - The ARM Generator
Looking ahead, I plan to:
- Enhance the AI enrichment capabilities with more sophisticated prompt engineering and multi-turn interactions.
- Expand privacy options to include differential privacy guarantees and automated privacy budget tracking.
- Add support for additional data types beyond tabular — such as images and time series — making the tool truly domain-agnostic.
- Integrate automated validation and quality assessment modules for synthetic datasets.
- Package the tool as an easy-to-deploy cloud service, making it accessible to developers and researchers worldwide.
- Apply the generator in real robotic and AI projects, including the “Jarvis” inspired robotic arm, to accelerate intelligent system development with safe, enriched synthetic data.
Thank you for considering my submission!
Built With
- amazon-web-services
- ctgan
- flaskapi
- mistral
- openrouter
- python
- react

Log in or sign up for Devpost to join the conversation.