Inspiration
Most sentiment analysis tools either send your text to a cloud API or need a big model. We wanted to know how far a small open model running on a laptop could go at a classic NLP task: telling whether a movie review is good or bad, with no internet and no API keys.
What it does
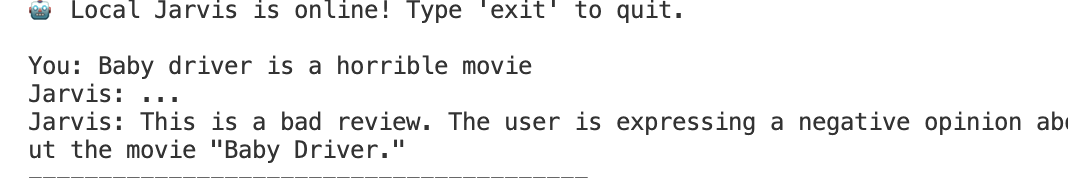
It’s a terminal chatbot that classifies movie reviews. You paste in a review and it answers whether it’s a good review or a bad review. Everything runs on your own machine through Ollama, so no review text ever leaves your computer.
How we built it
Model: Qwen 2.5 7B Instruct, served locally through Ollama. We set the temperature to 0 so the same review always gets the same answer. Agent framework: LangGraph’s create_react_agent with LangChain tools. The agent is set up so we can give it tools later, like looking up a movie or fetching reviews. Prompting: A system prompt that restricts the model to a single job, classifying review sentiment, and keeps its answers short. Interface: A streaming chat loop in the terminal that prints the agent’s replies as they arrive and exits cleanly on exit or Ctrl+C.
Challenges we ran into
Keeping answers short: Small models like to explain themselves. Getting a plain “good” or “bad” took several rounds of prompt changes. Mixed reviews: Reviews such as “great acting, terrible plot” or sarcastic ones are hard for a 7B model to call. Local hardware: Running a 7B model on a laptop forced trade-offs between speed and quality, so we used a quantized model through Ollama. Agent overhead: A ReAct agent is more than a simple classifier needs, and we had to stop it from calling tools it didn’t need.
Accomplishments that we're proud of
A sentiment classifier that runs entirely offline, with no API costs and no data leaving the machine. Deterministic output, so results can be reproduced. A clean setup that can grow into a fuller movie assistant without a rewrite.
What we learned
How to serve and call local LLMs with Ollama and LangChain. How LangGraph’s ReAct agents decide whether to call a tool or answer directly. That with a well-written prompt, a small instruction-tuned model handles simple sentiment surprisingly well, and that the system prompt matters a lot at this model size.
What's next for Small LLM model
Fine-tuning: Train a LoRA adapter on the IMDb or Rotten Tomatoes review datasets and measure the gain over the zero-shot baseline. Smaller models: Try Qwen 2.5 0.5B, 1.5B and 3B to find the smallest one that stays accurate. Evaluation: Report accuracy and F1 on a held-out test set. More labels: Add a “mixed” or “neutral” class and confidence scores. Movie tools: Replace the placeholder tool with real ones for movie lookup and review search, and recommendations based on what users liked.
Built With
- ollama
- python
