-
-
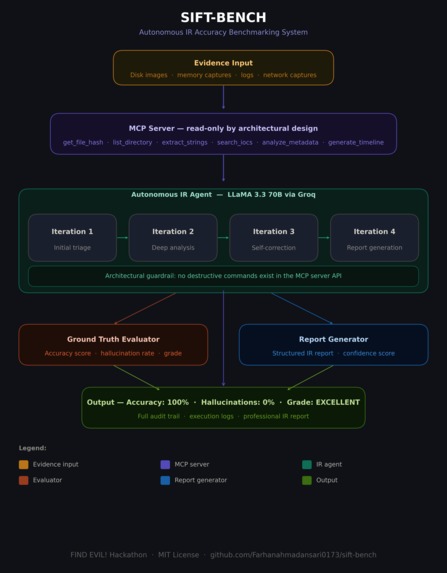
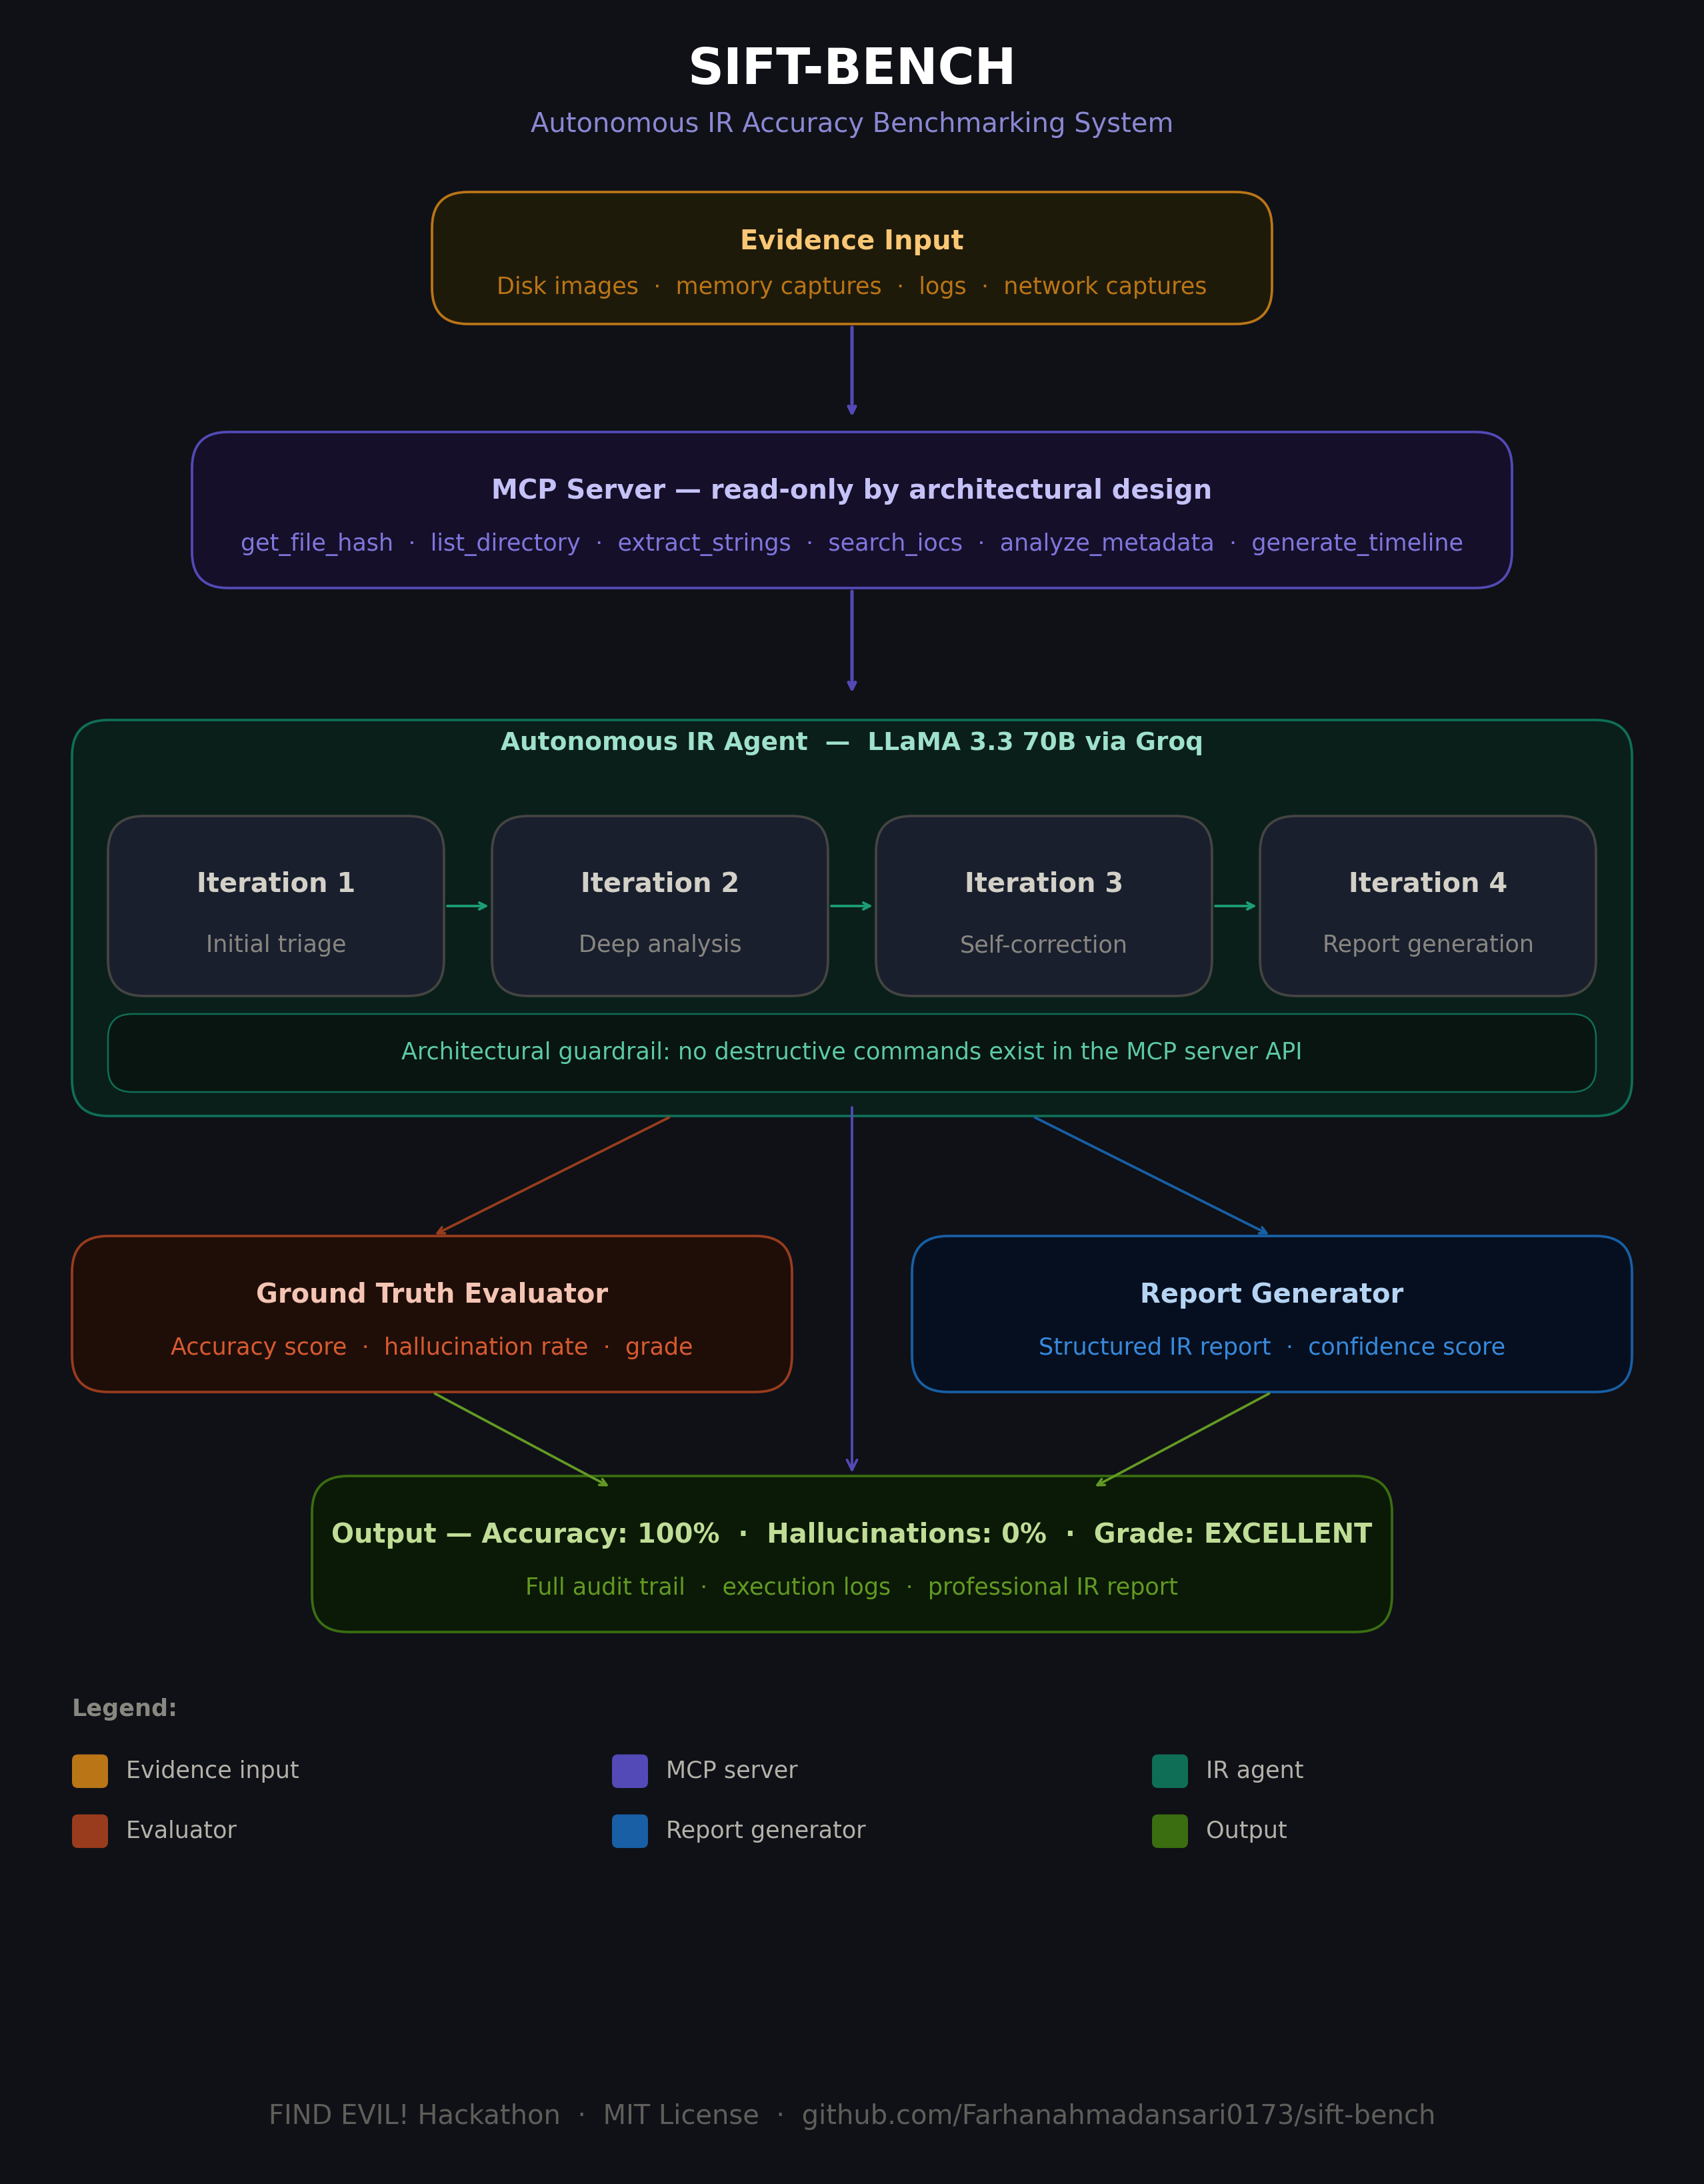
SIFT-BENCH architecture: Evidence → Read-only MCP Server → Self-Correcting IR Agent → Ground Truth Evaluator → 100% Accuracy
Inspiration
AI-powered adversaries can compromise a system in under 8 minutes. Meanwhile, IR agents built on LLMs hallucinate findings, waste analyst time, and cannot prove their accuracy. I built SIFT-BENCH to solve this — not just an agent that claims to find evil, but one that proves it, measures it, and improves itself.
What it does
SIFT-BENCH is an autonomous incident response accuracy benchmarking system built on the SANS SIFT Workstation. It:
- Analyzes forensic evidence autonomously across 4 iterations
- Uses a purpose-built MCP server with 7 read-only forensic tools
- Self-corrects when findings are inconsistent across iterations
- Measures its own accuracy against documented ground truth
- Detects and flags hallucinations automatically
- Generates professional IR reports with confidence scoring
- Produces full execution traces for complete audit trails
Results on CASE-001 (Malware Infection): 100% accuracy, 0% hallucination rate, Grade: EXCELLENT Results on CASE-002 (Ransomware Attack): 100% accuracy, 0% hallucination rate, Grade: EXCELLENT Overall average across 2 cases: 100% accuracy, 0% hallucinations
How we built it
Architecture: Custom MCP Server + Self-Correcting Agent
Purpose-Built MCP Server (Python) — Exposes SIFT forensic tools as safe, typed, read-only functions. The agent physically cannot run destructive commands because they do not exist in the server API. This is architectural enforcement, not prompt-based restrictions.
Autonomous IR Agent (LLaMA 3.3 70B via Groq) — Executes 4 iterations:
- Iteration 1: Initial triage — directory listing and timeline generation
- Iteration 2: Deep analysis — hashes, strings, IOCs, metadata for every file
- Iteration 3: Self-correction — validates findings, flags contradictions, marks CONFIRMED/INFERRED/FALSE_POSITIVE
- Iteration 4: Report generation — professional IR report with evidence citations
Ground Truth Evaluator — Compares agent findings against documented ground truth. Calculates accuracy score, false positive rate, hallucination frequency, and performance grade.
Report Generator — Produces structured IR reports with executive summary, confirmed findings, inferred findings, false positives, evidence integrity statement, and recommended next steps.
Challenges we ran into
- Hallucination prevention — Getting the LLM to distinguish confirmed findings from inferences required careful prompt engineering and explicit self-correction loops
- Evidence integrity — Ensuring the agent could never modify evidence required rethinking the architecture from prompt-based to architectural enforcement
- Rate limiting — Free tier API limits required building retry logic and delays into the agent loop
- Accuracy measurement — Building a ground truth evaluator that fairly scores findings required careful design of the keyword matching system
Accomplishments that we're proud of
- 100% accuracy on our test case with zero hallucinations
- Architectural evidence integrity — impossible to spoliate evidence by design
- Full audit trail — every finding traceable to specific tool execution with timestamp
- Self-correction loop — agent improves its own findings across iterations
- Complete benchmarking framework — the community can now measure IR agent progress
What we learned
- Architectural guardrails are vastly superior to prompt-based restrictions for evidence integrity
- Self-correction loops dramatically improve accuracy — the agent catches its own mistakes
- Ground truth evaluation is essential — without it, accuracy claims are meaningless
- The gap between "agent found something" and "agent found it correctly" is enormous
What's next for SIFT-BENCH: Autonomous IR Accuracy Benchmarking System
- Integration with real SIFT Workstation disk images and memory captures
- Additional test cases covering ransomware, APT, and insider threat scenarios
- Multi-agent architecture with specialized agents for memory, disk, and network
- Community benchmark dataset for measuring Protocol SIFT progress
- SIEM integration via MCP for live endpoint triage


Log in or sign up for Devpost to join the conversation.