-
-
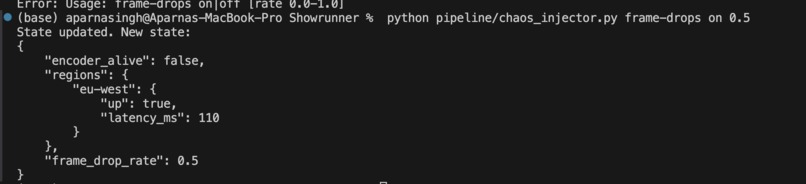
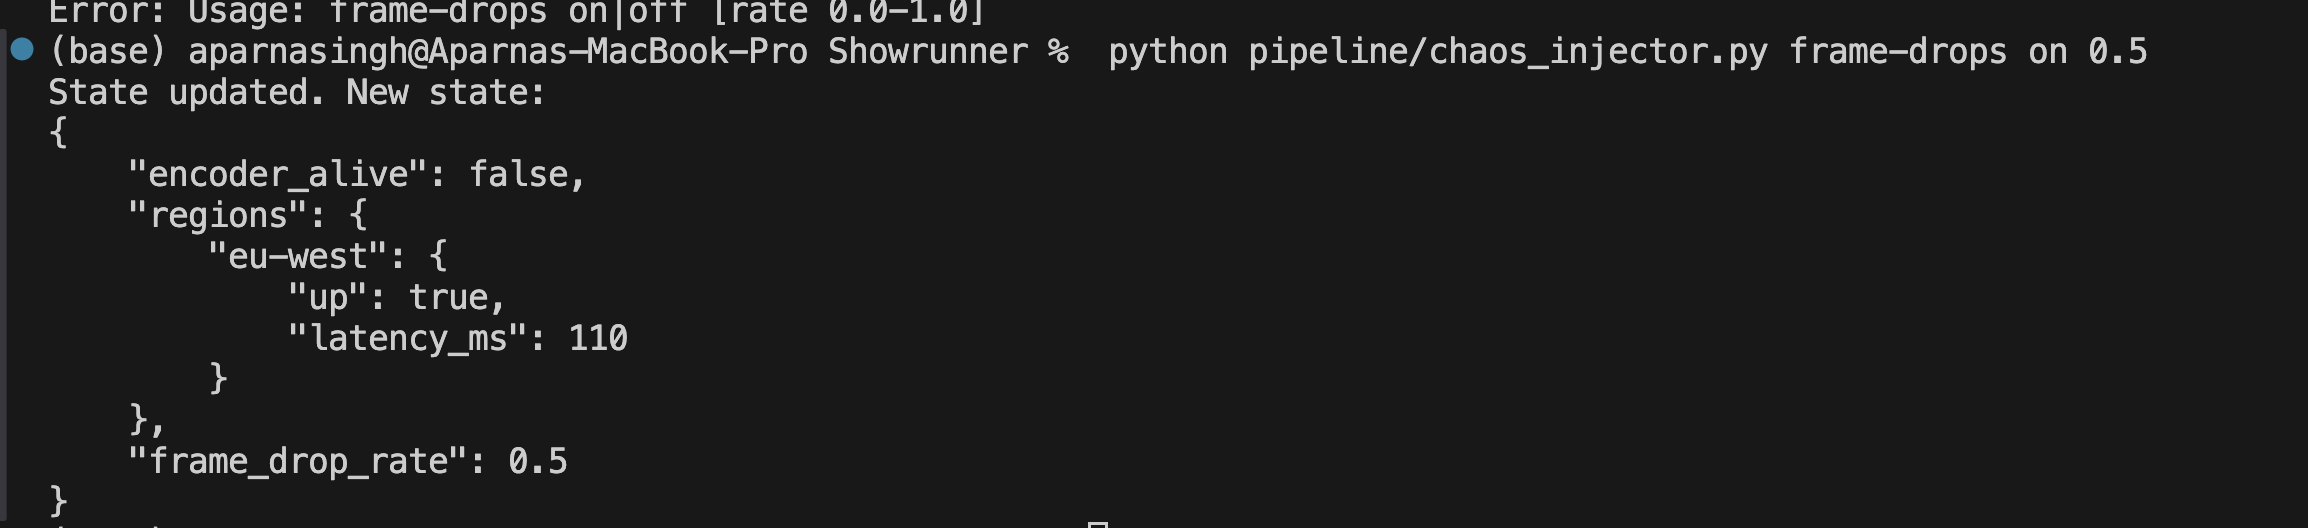
Chaos testing introduces a 50% frame-drop rate, demonstrating how ShowRunner detects degraded broadcast quality.
-
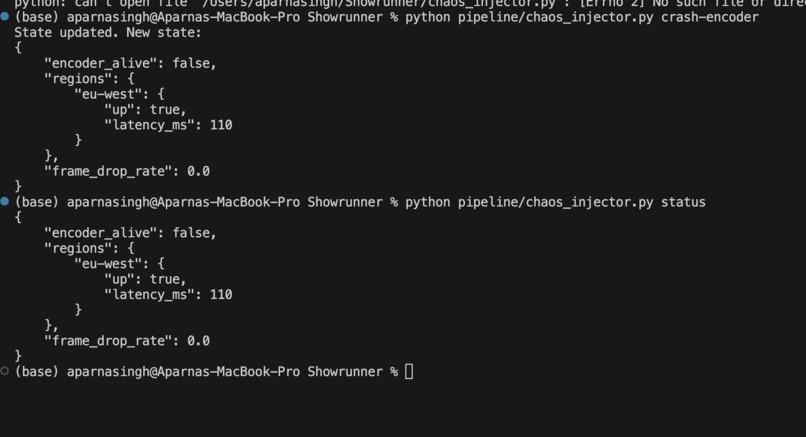
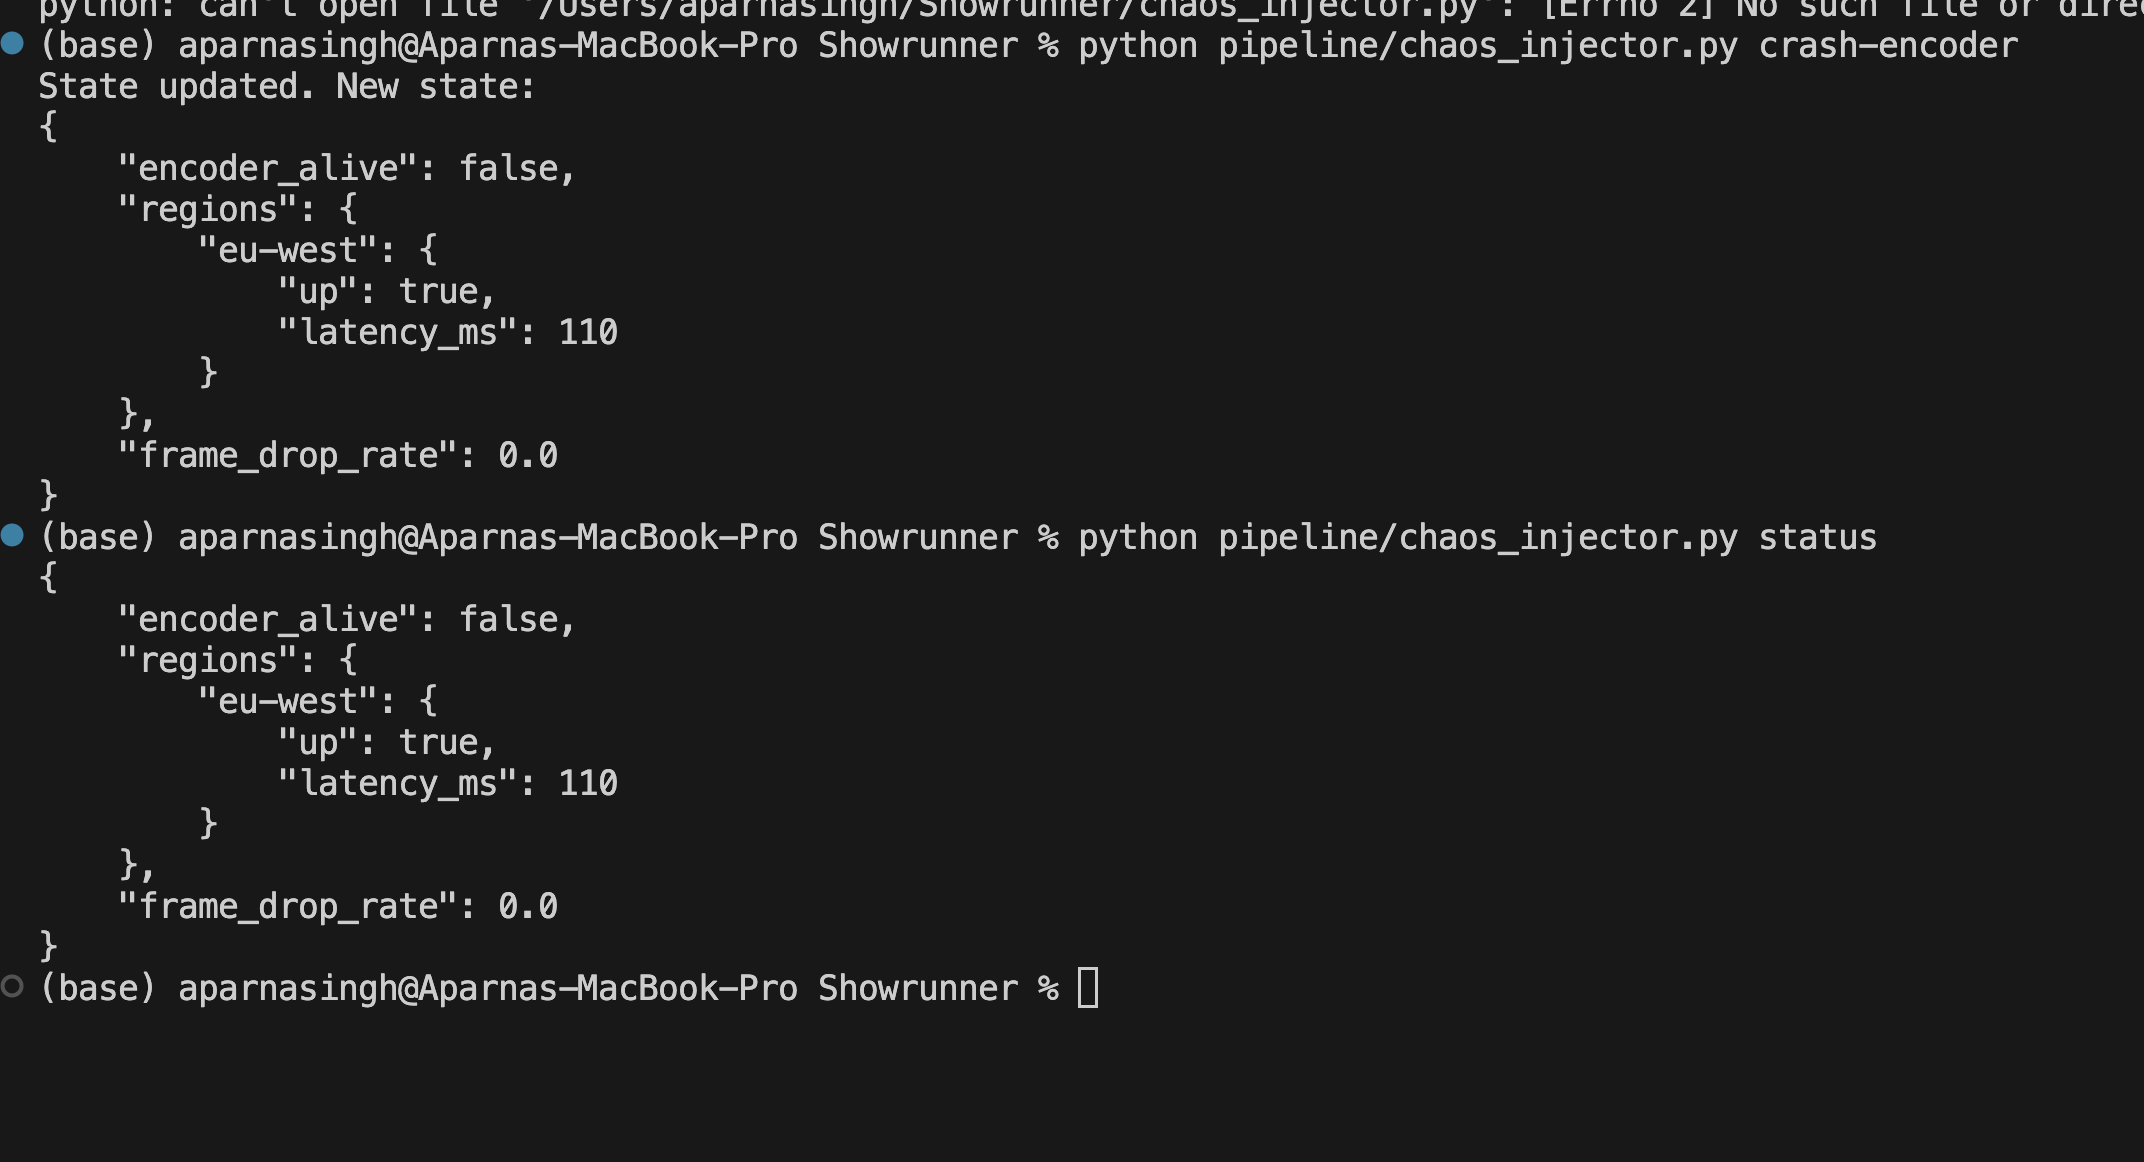
Chaos testing simulates an encoder failure, setting the broadcast encoder state to DOWN for automated incident detection.
-
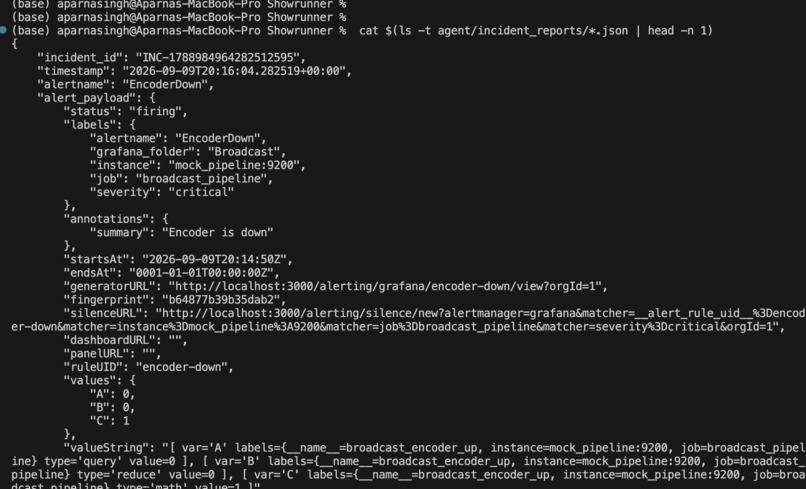
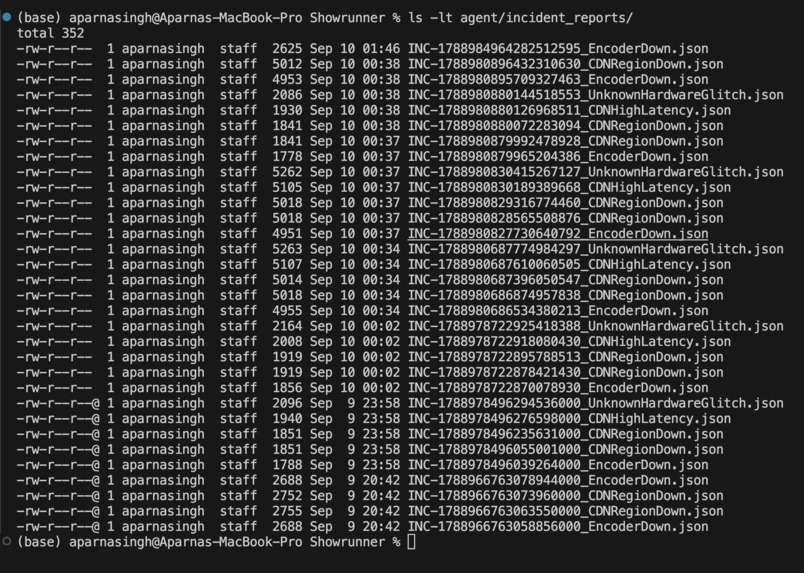
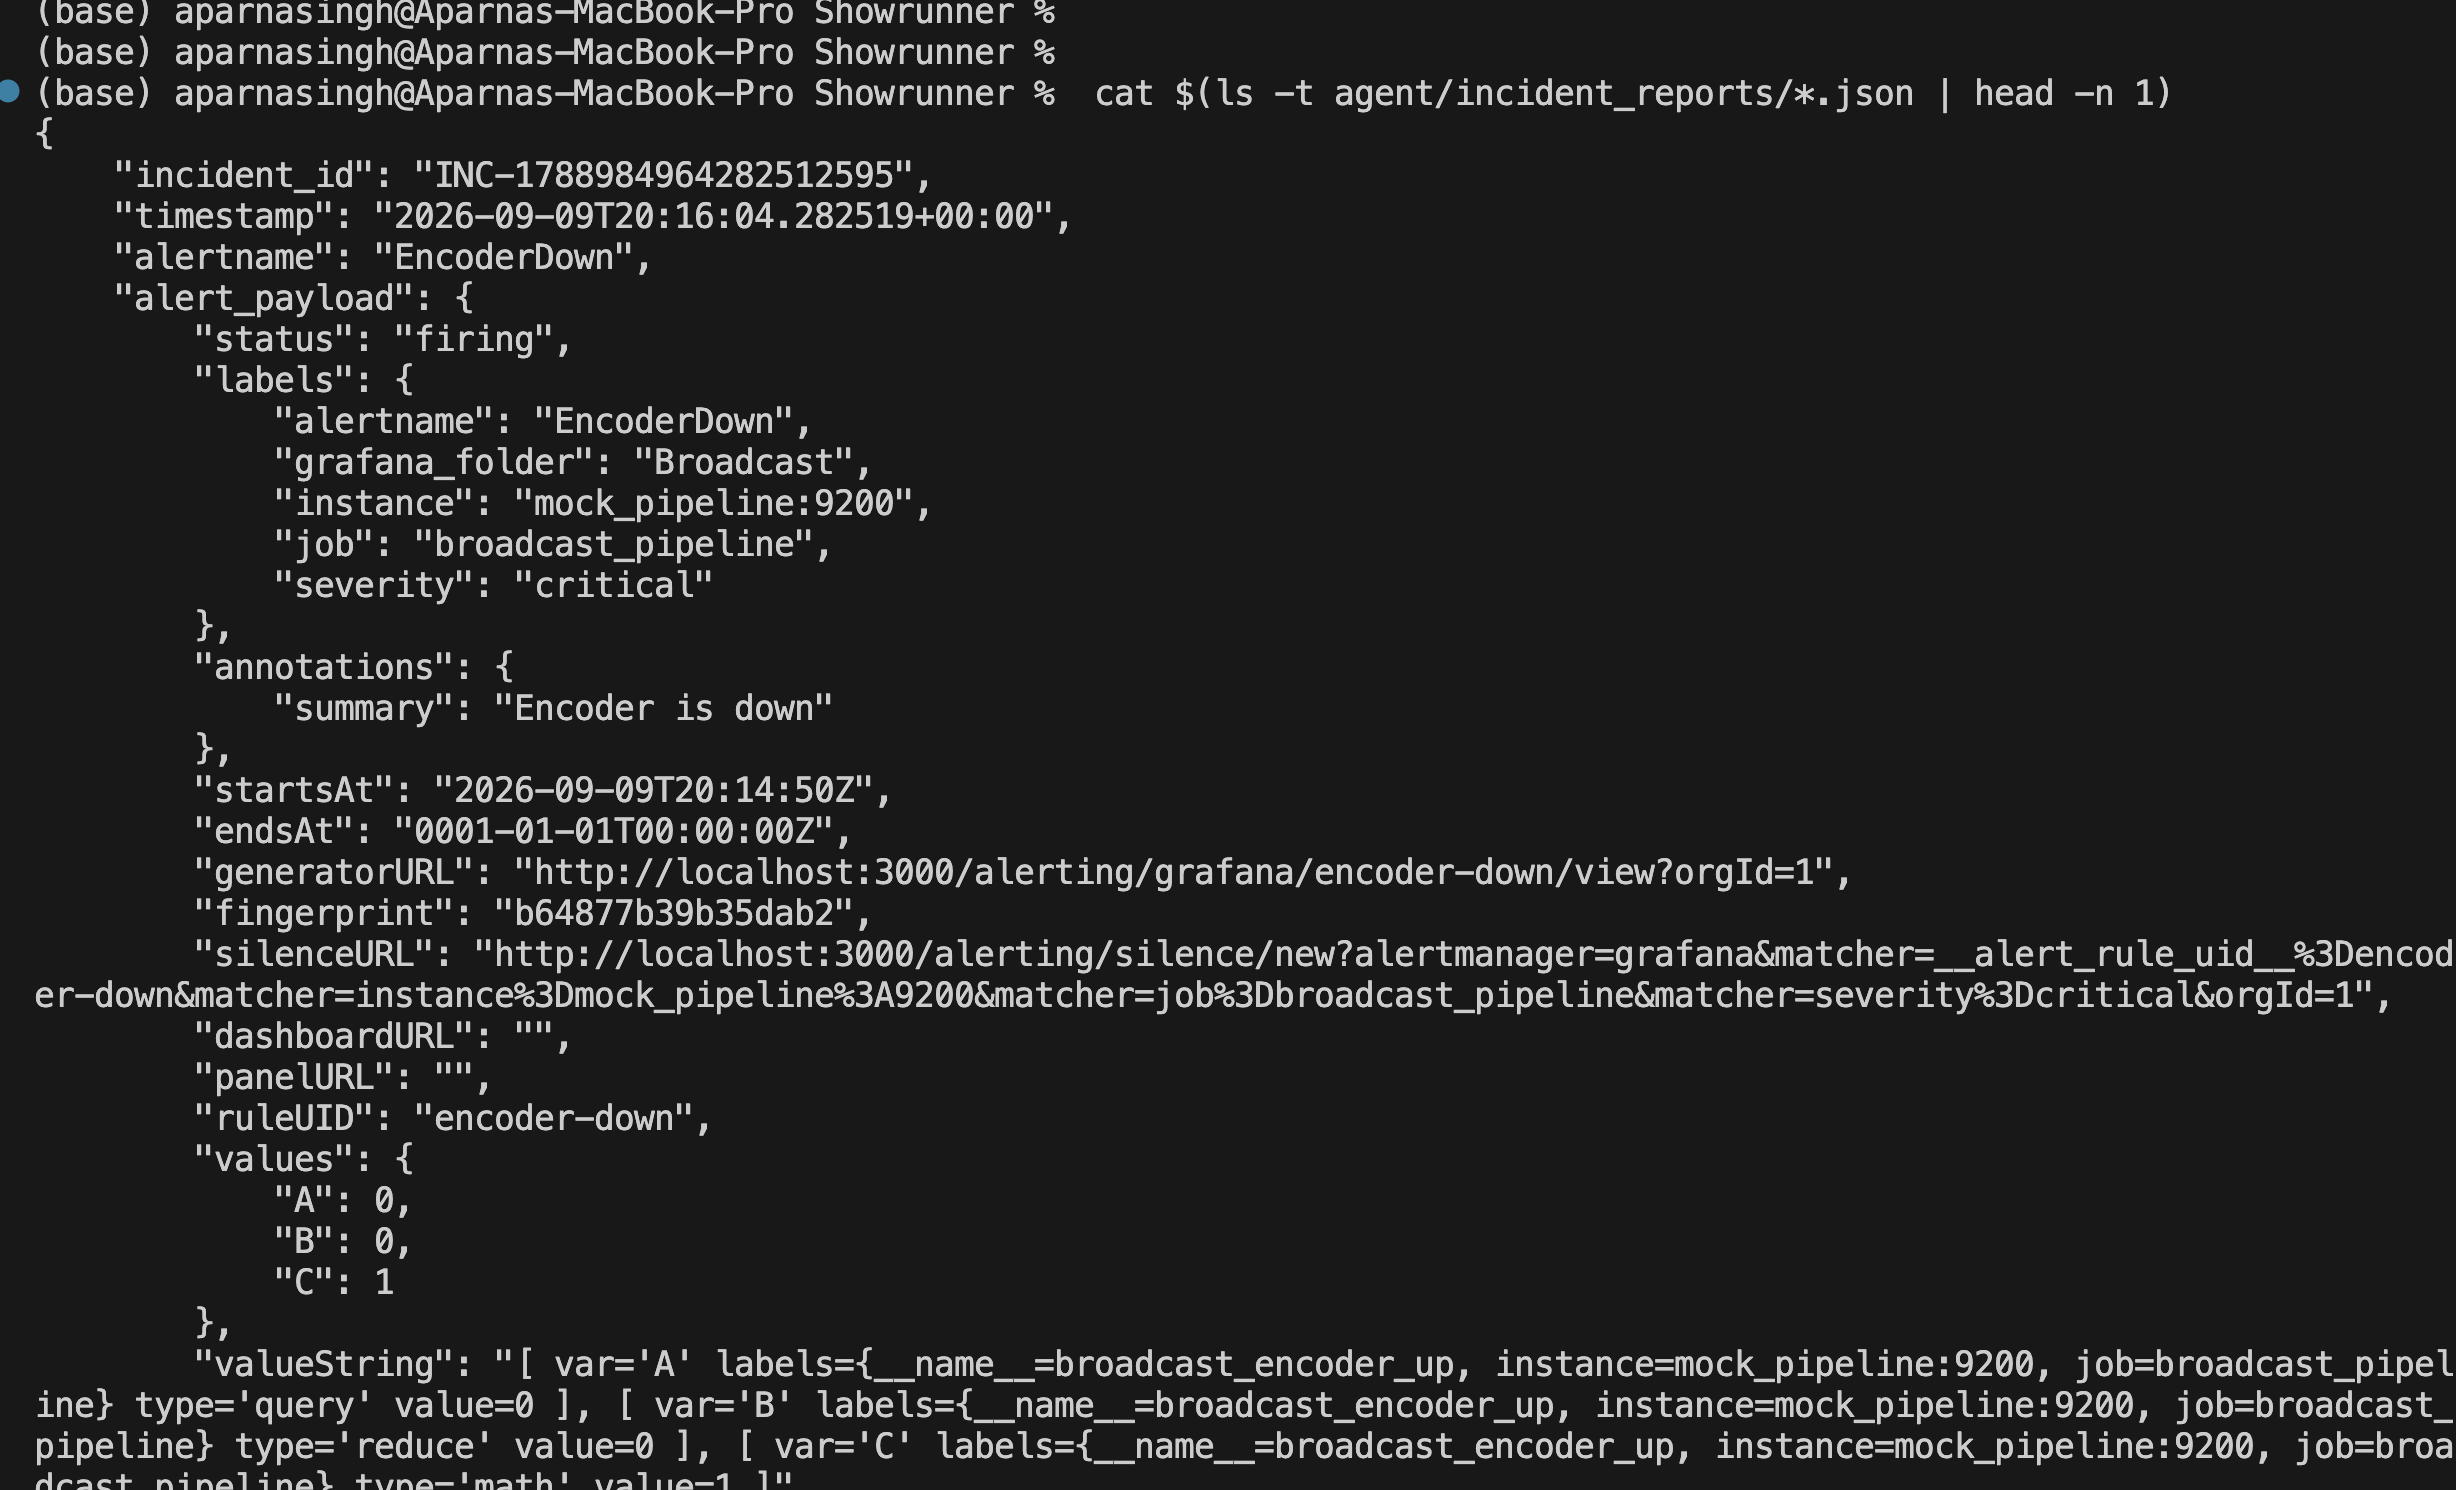
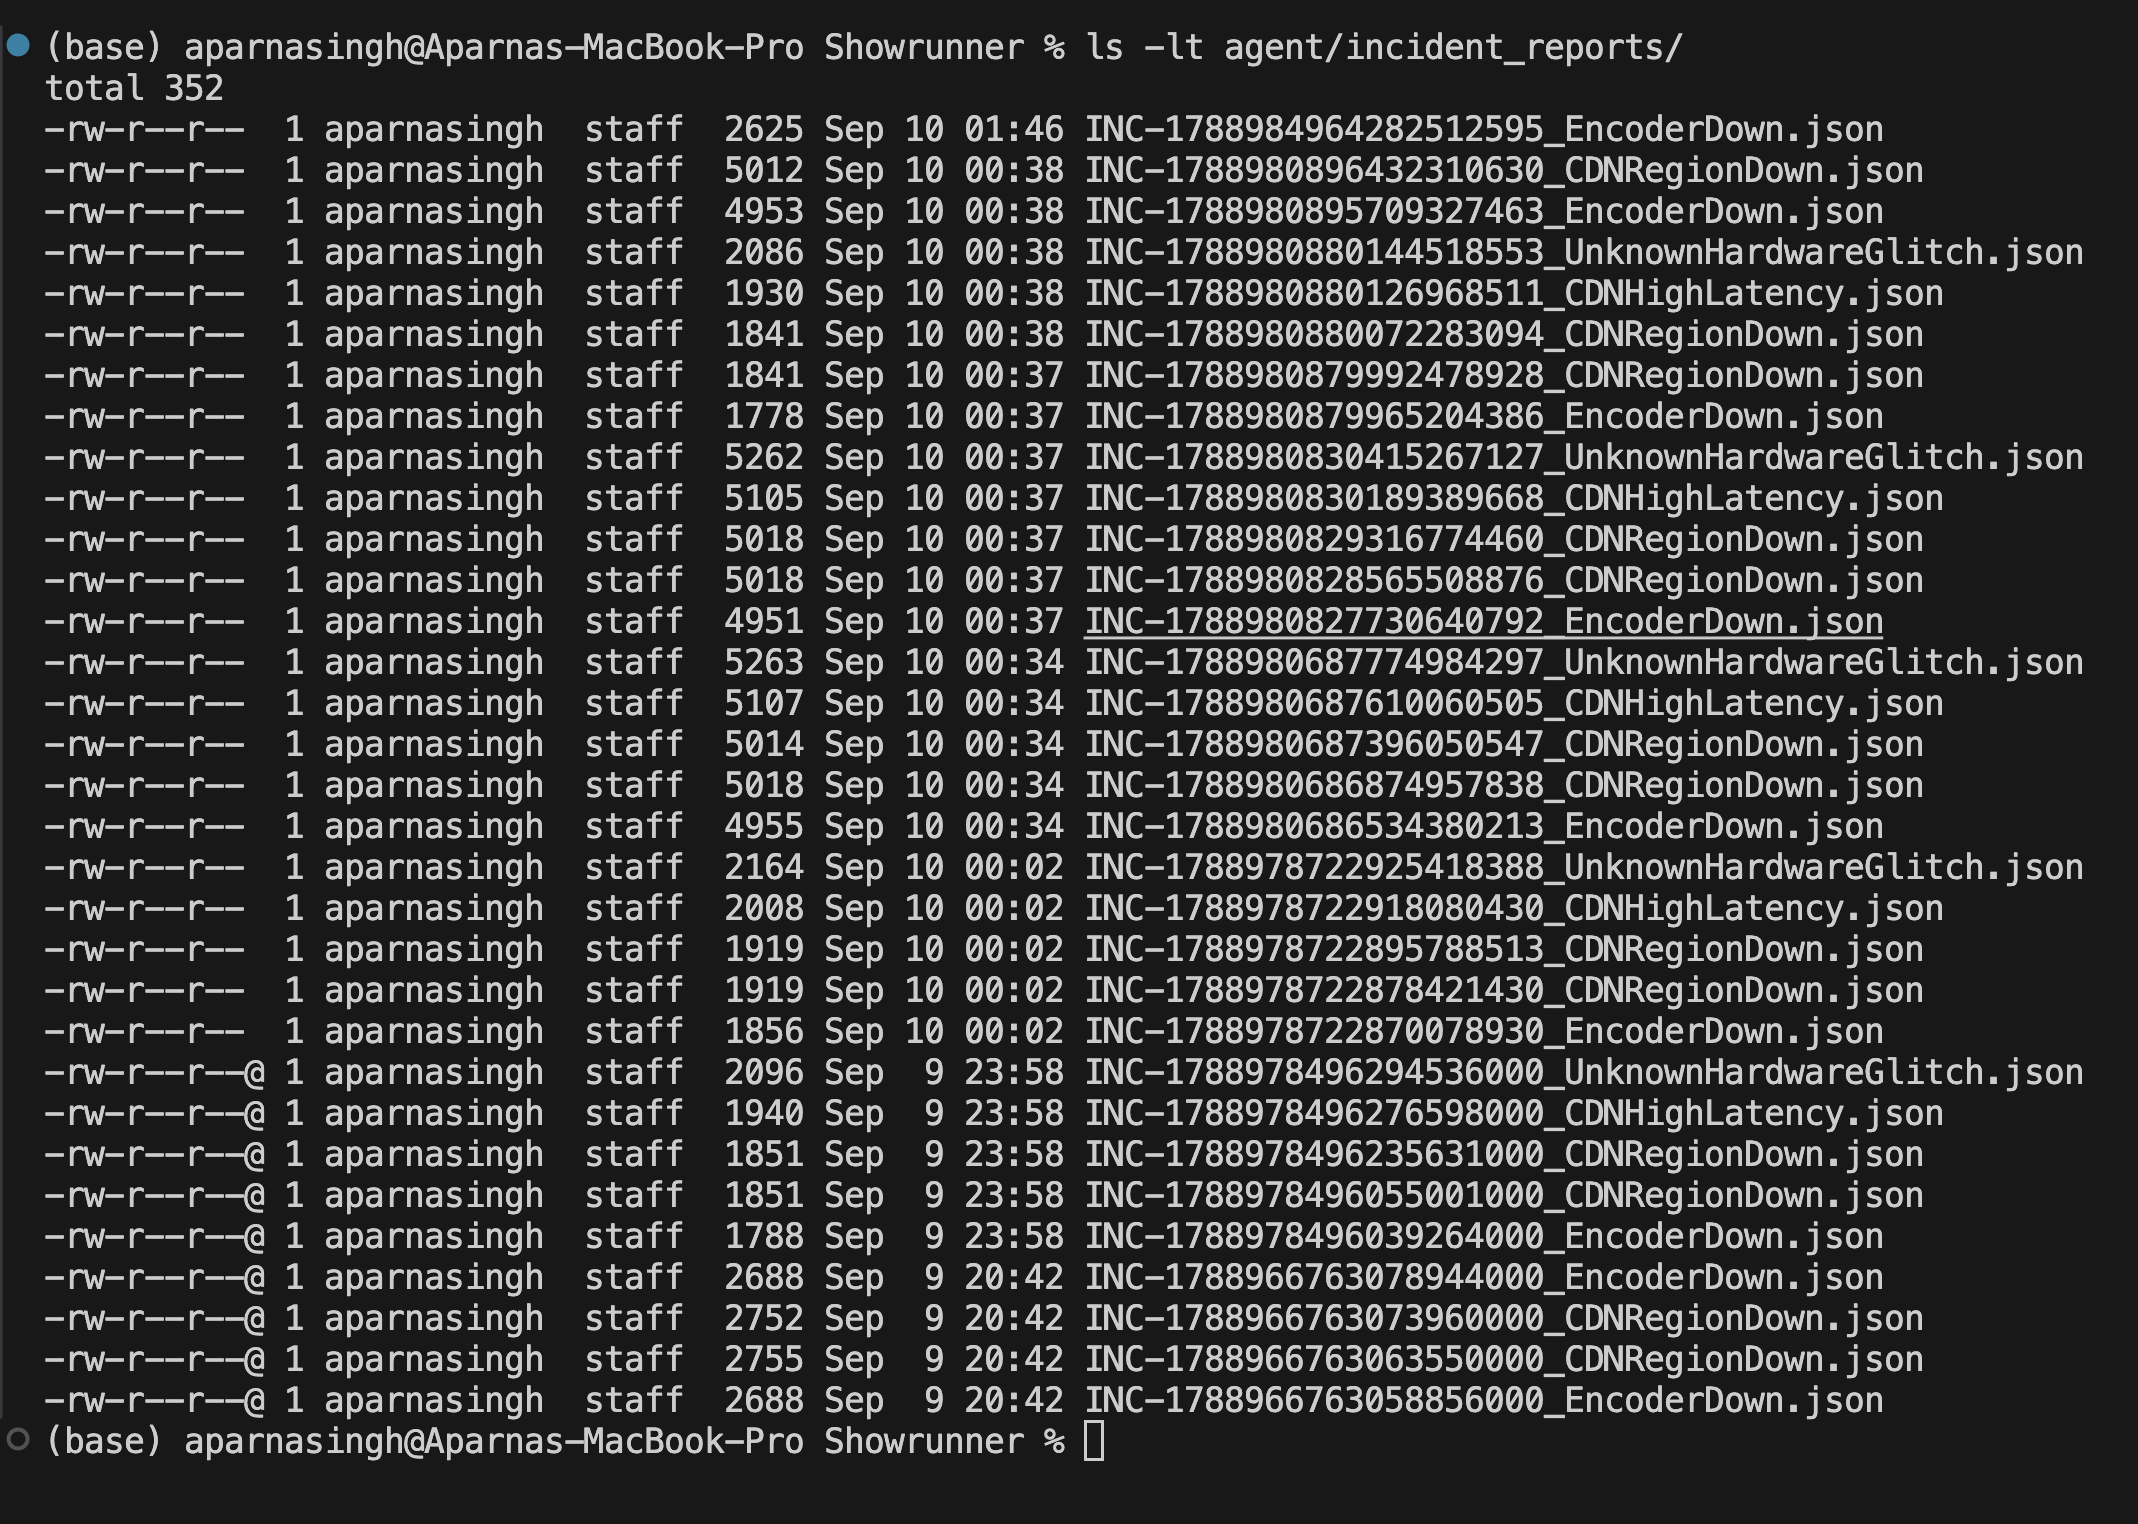
Incident reports generated by ShowRunner, capturing encoder failures, CDN outages, latency issues, and unknown hardware glitches.
-
ShowRunner agent successfully deployed as a container on Render, with the application server running on port 8080.
-
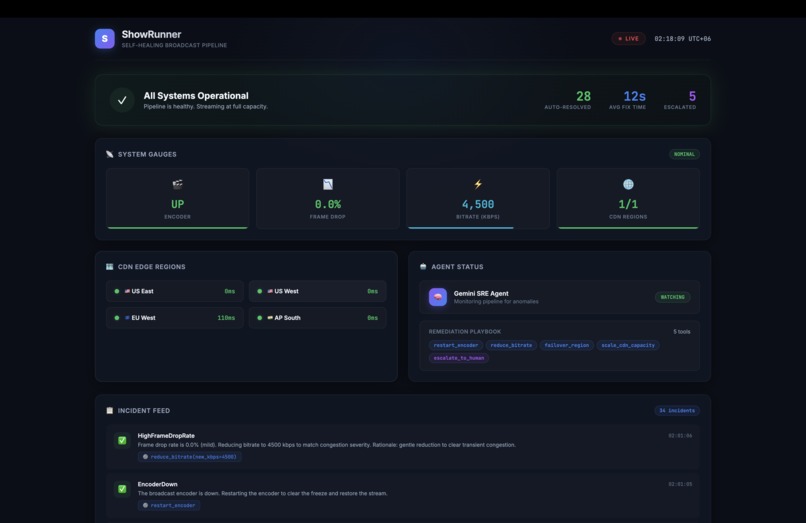
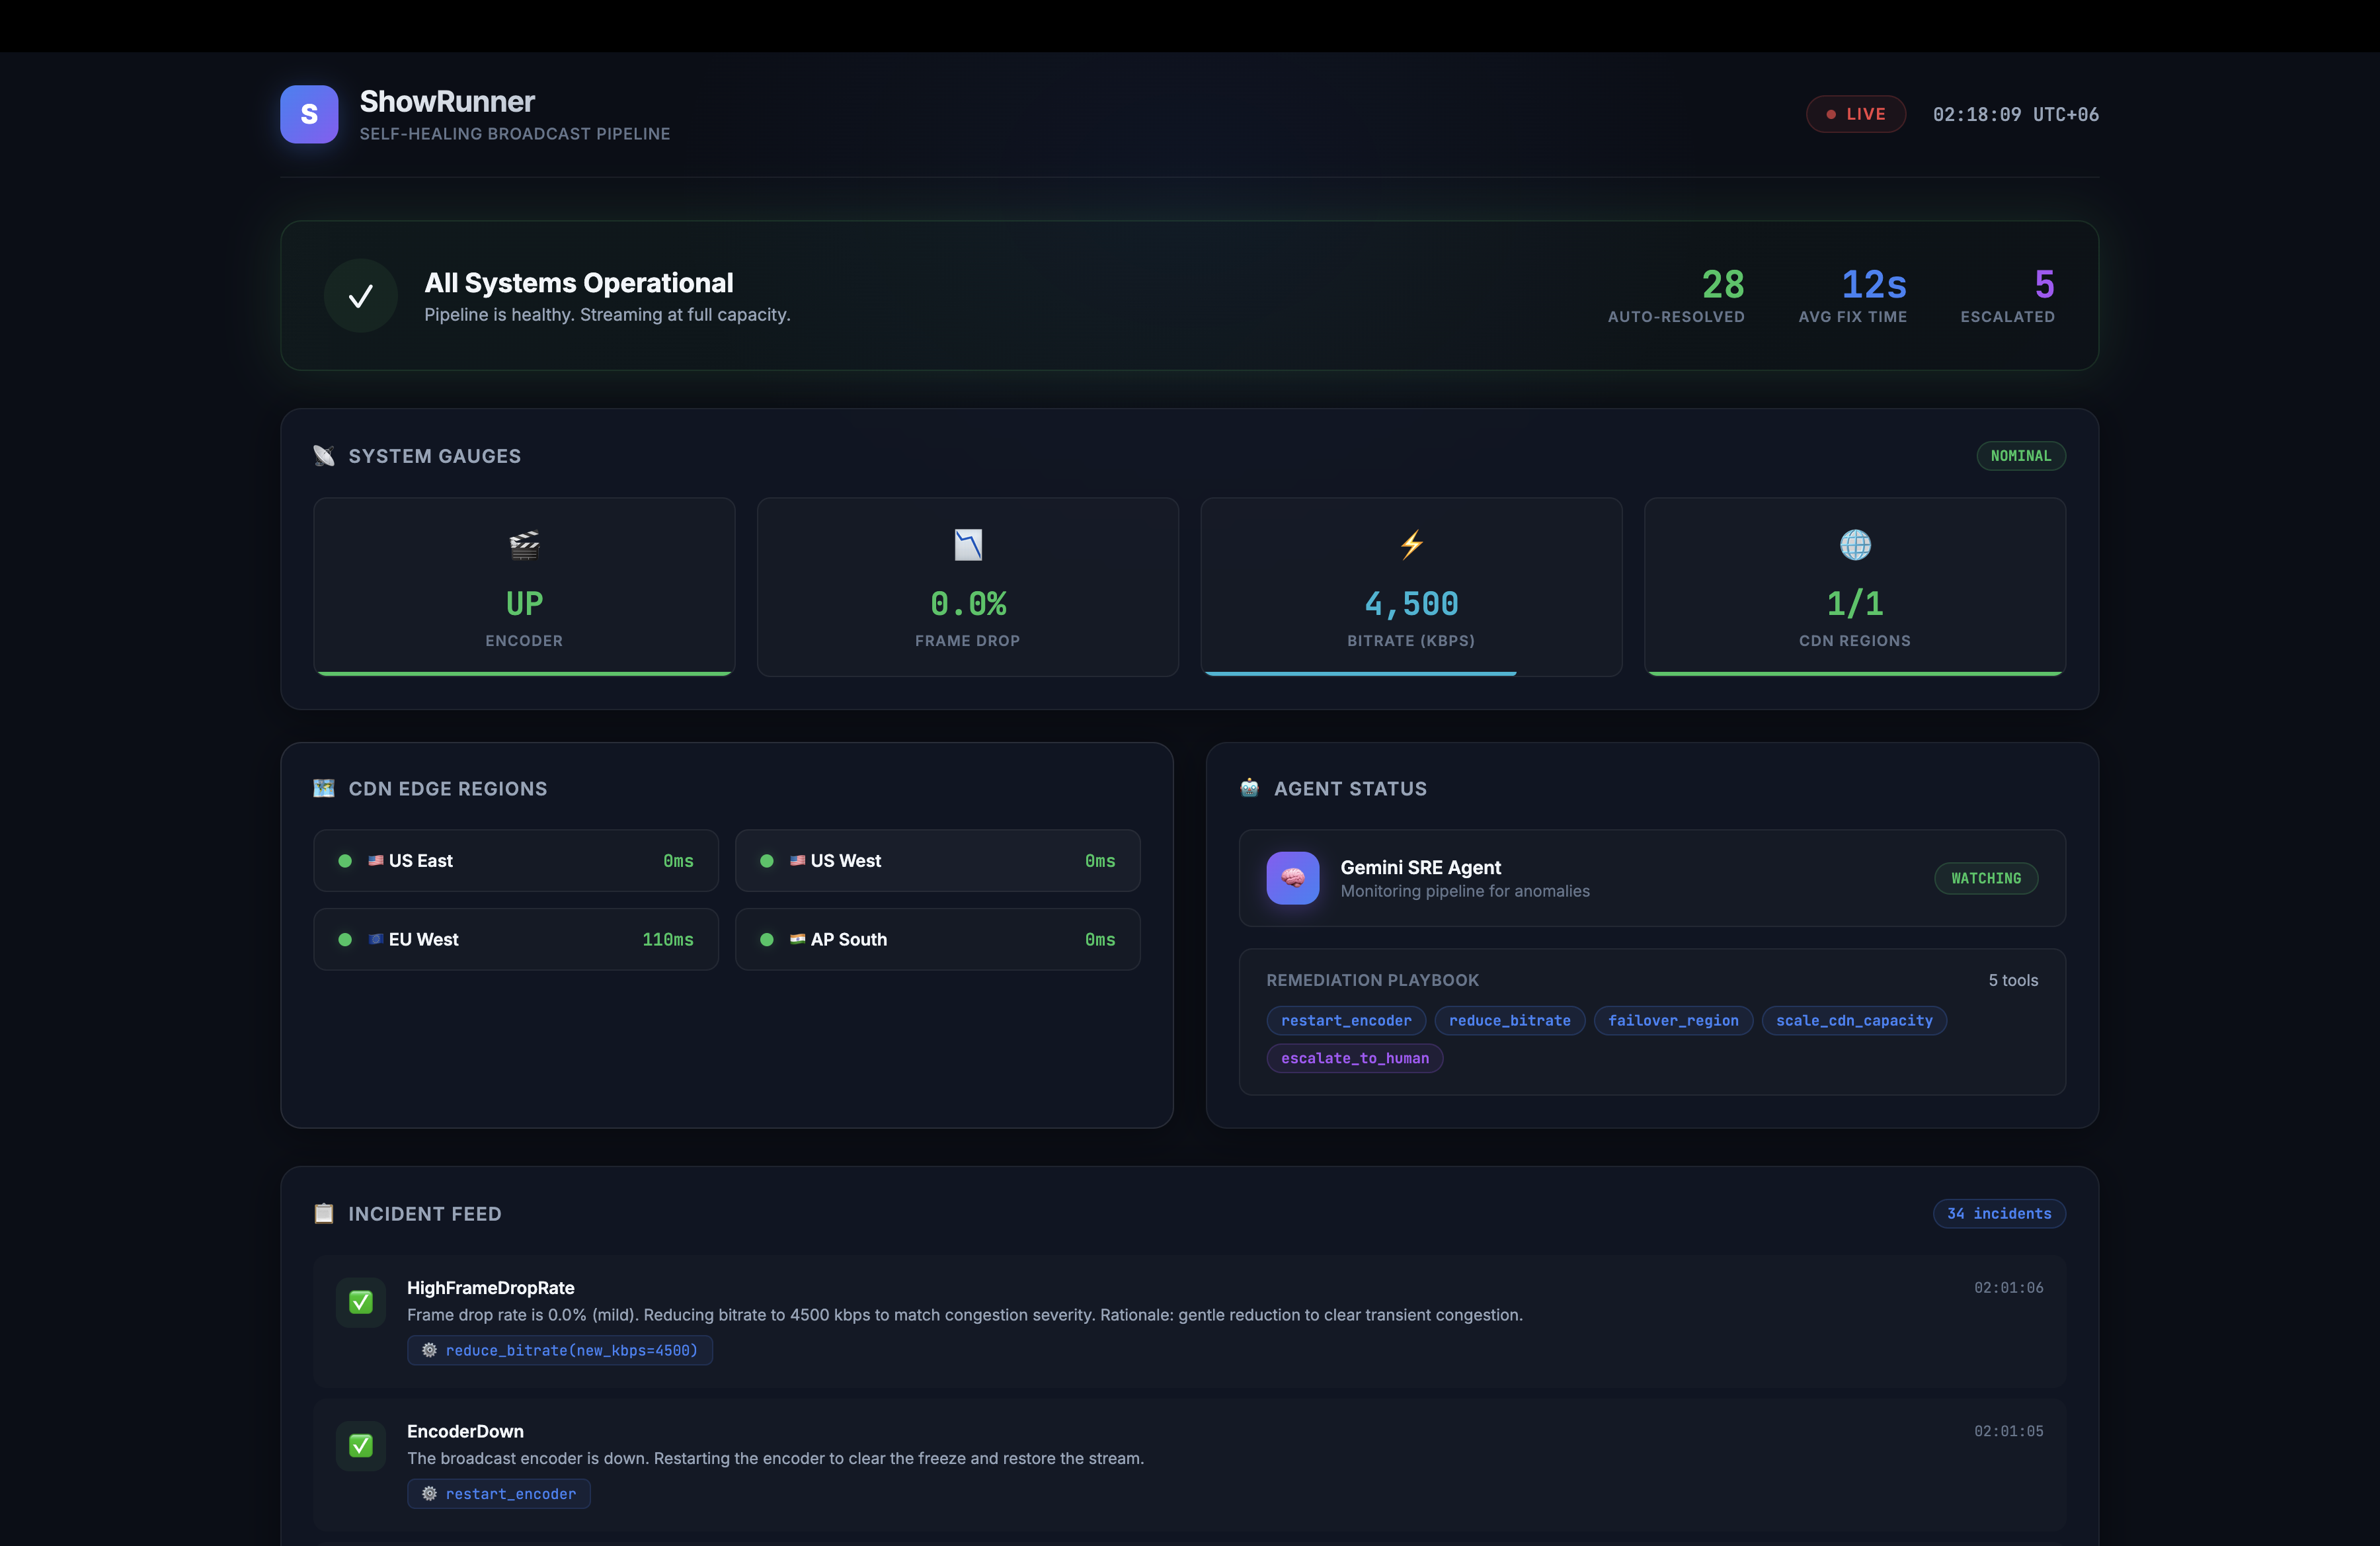
ShowRunner dashboard displaying real-time broadcast health, CDN regions, Gemini SRE Agent status, and automated remediation metrics.
-
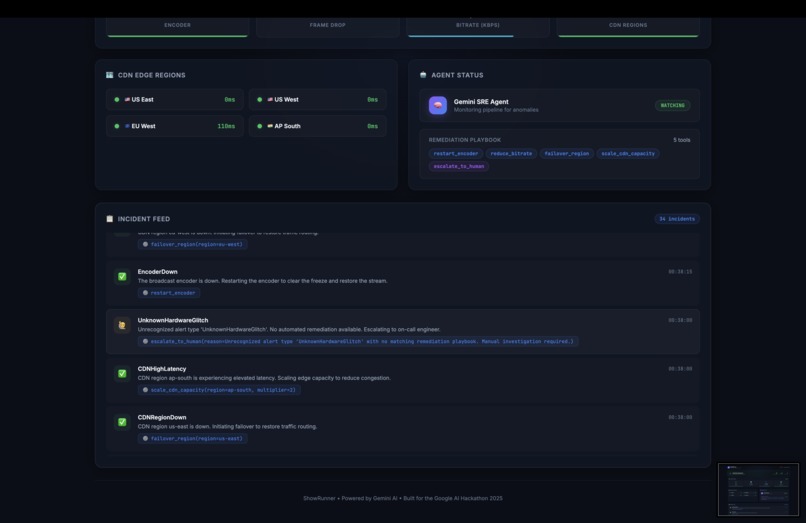
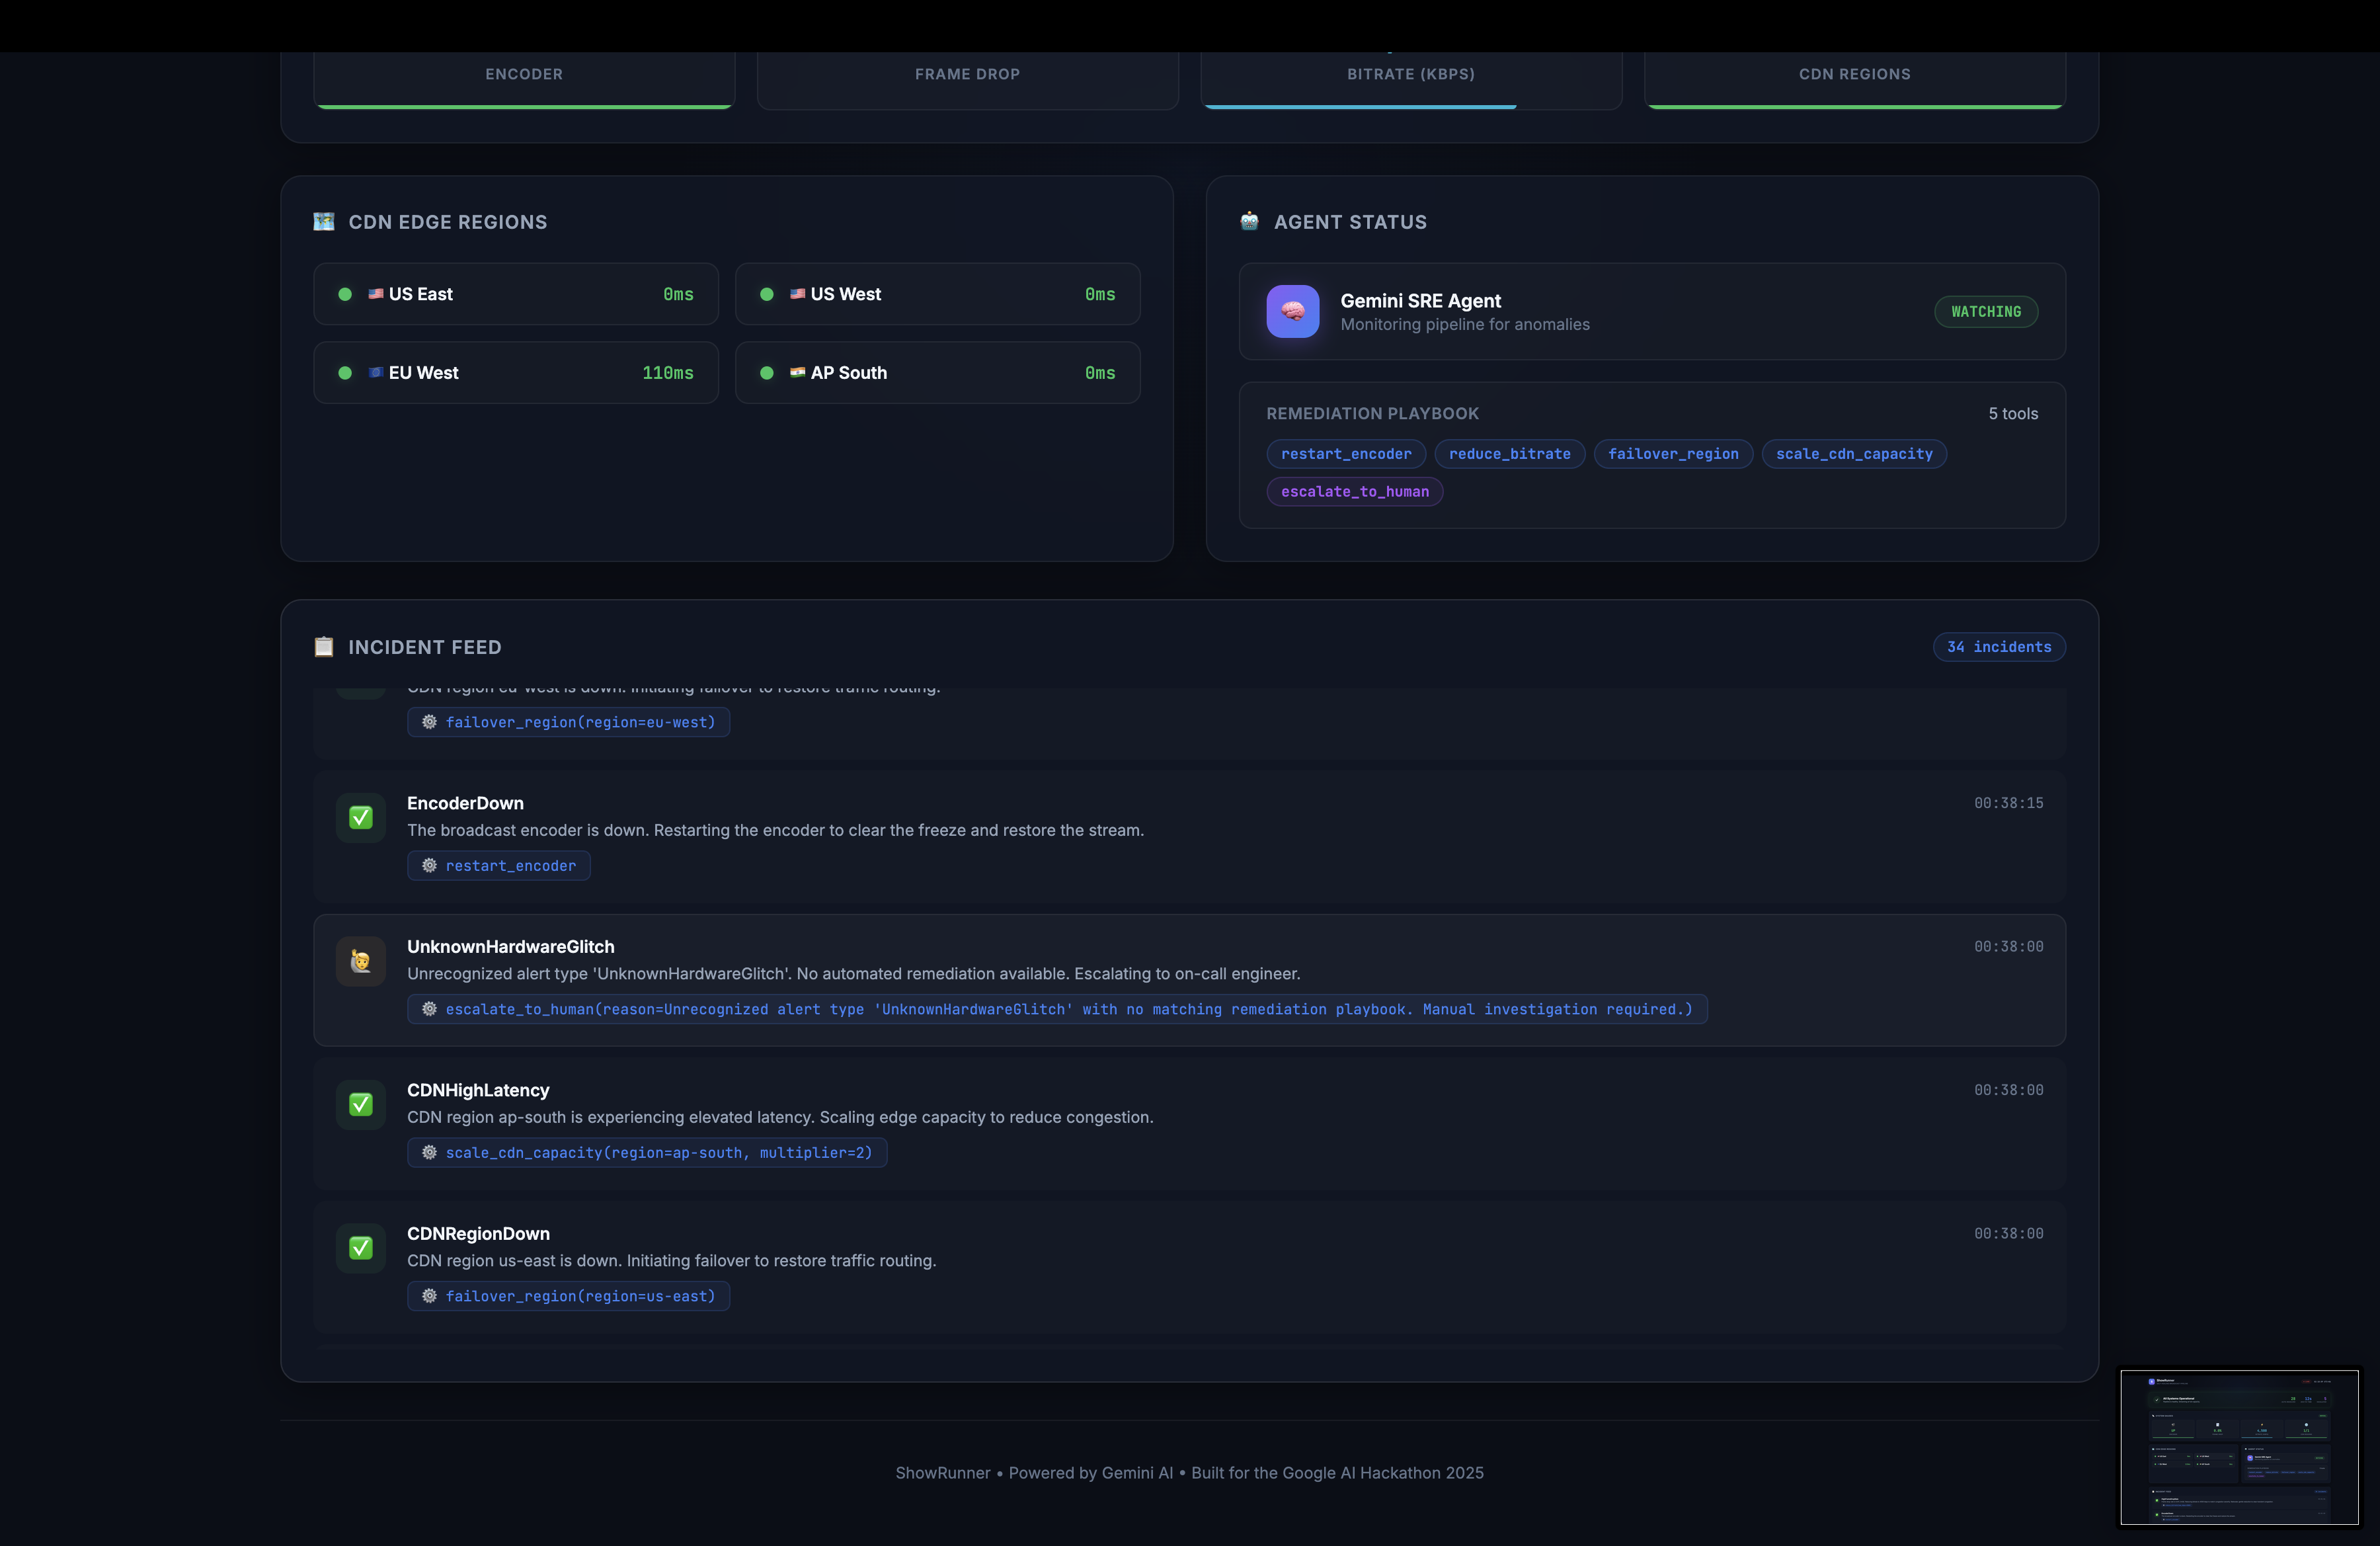
ShowRunner incident feed showing detected failures and the remediation actions automatically executed by the SRE agent.
Inspiration
Broadcast systems are expected to stay live even when something goes wrong. A failed encoder, overloaded CDN region, excessive frame drops, or degraded network conditions can quickly turn into a major interruption.
Traditional monitoring can tell an engineer that something is wrong, but the next steps still depend on a human noticing the alert, investigating metrics, deciding what to do, executing the fix, and documenting the incident.
We wanted to build something that could close that loop automatically.
That idea became ShowRunner — Autonomous SRE for Broadcast Systems: an AI-powered self-healing agent that detects incidents, investigates live telemetry, chooses a remediation, executes it, and records what happened.
Our goal is simple:
Because the show must go on.
What it does
ShowRunner continuously monitors a simulated broadcast pipeline using Prometheus and Grafana.
When a failure occurs:
- Detect — Grafana detects an abnormal condition and sends an alert to ShowRunner.
- Observe — ShowRunner retrieves recent system telemetry through the Grafana MCP integration.
- Diagnose — Gemini analyzes the alert together with the observed metrics.
- Decide — The agent selects an appropriate remediation tool.
- Act — ShowRunner executes the remediation automatically.
- Recover — The pipeline state is restored when the remediation succeeds.
- Document — A structured incident/postmortem report is generated automatically.
The remediation playbook includes actions such as:
restart_encoderreduce_bitratefailover_regionscale_cdn_capacityescalate_to_human
ShowRunner is designed to handle multiple incidents independently, so a failure in one incident does not prevent another alert from being processed.
How we built it
ShowRunner is built as a containerized, event-driven system.
Architecture
                    ┌─────────────────────┐
                    │   Broadcast Pipeline │
                    │    Mock System       │
                    └──────────┬──────────┘
                               │
                               ▼
                    ┌─────────────────────┐
                    │     Prometheus      │
                    │   Metrics + Rules   │
                    └──────────┬──────────┘
                               │
                               ▼
                    ┌─────────────────────┐
                    │       Grafana       │
                    │ Alerts + Observability
                    └──────────┬──────────┘
                               │ Webhook
                               ▼
                    ┌─────────────────────┐
                    │     ShowRunner      │
                    │     FastAPI Agent    │
                    └──────────┬──────────┘
                               │
                     ┌─────────┴─────────┐
                     ▼                   ▼
             ┌──────────────┐    ┌──────────────┐
             │ Grafana MCP  │    │    Gemini    │
             │   Server     │    │ AI Diagnosis │
             └──────────────┘    └──────────────┘
                     │                   │
                     └─────────┬─────────┘
                               ▼
                    ┌─────────────────────┐
                    │ Remediation Tools   │
                    │ restart / failover  │
                    │ scale / bitrate     │
                    │ escalation          │
                    └──────────┬──────────┘
                               │
                               ▼
                    ┌─────────────────────┐
                    │  Recovered Pipeline │
                    │   + Postmortem      │
                    └─────────────────────┘

Log in or sign up for Devpost to join the conversation.