-
-
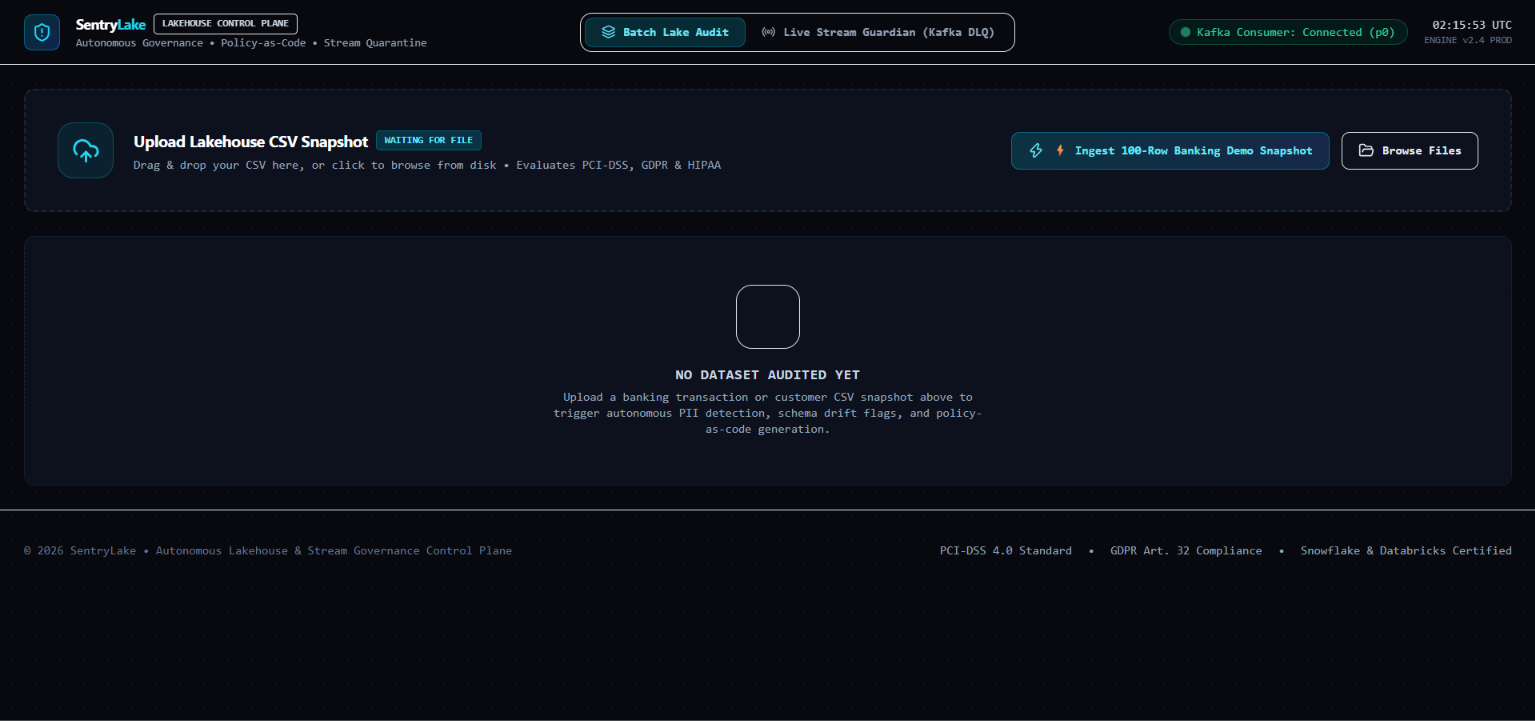
Clean Ingestion Portal: Secure dropzone awaiting Lakehouse batch CSV snapshot for autonomous compliance audit.
-
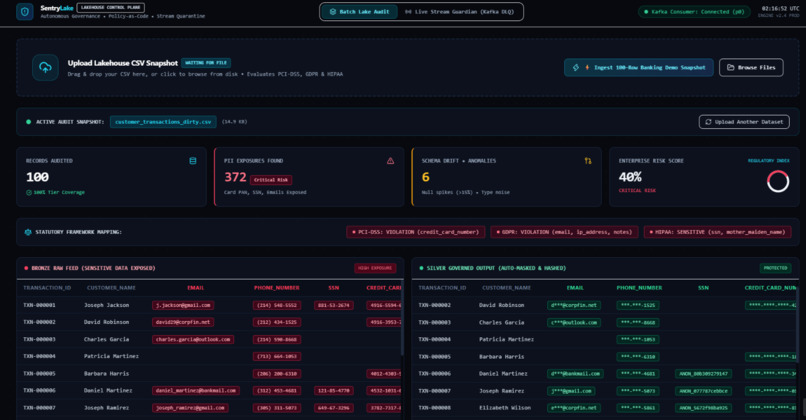
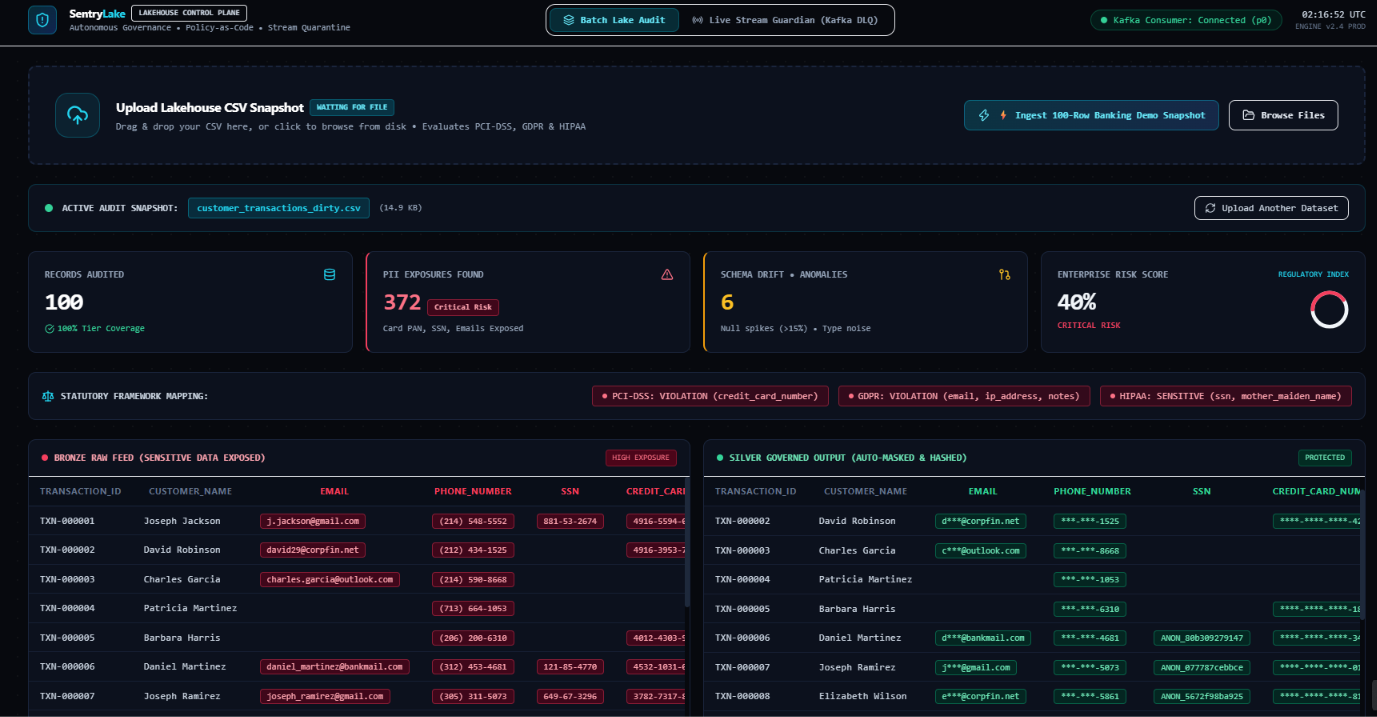
Batch Audit & Split-View: Real-time detection of 372 PII violations with raw exposed vs masked comparison.
-
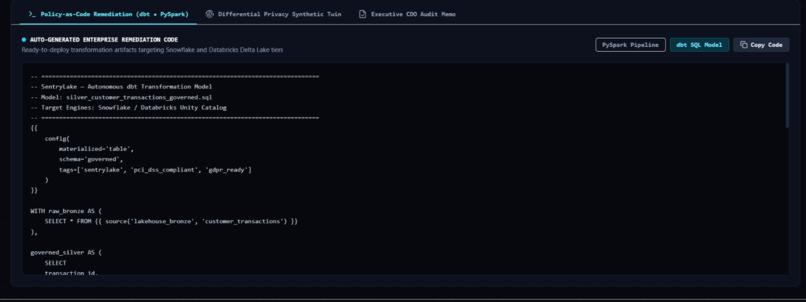
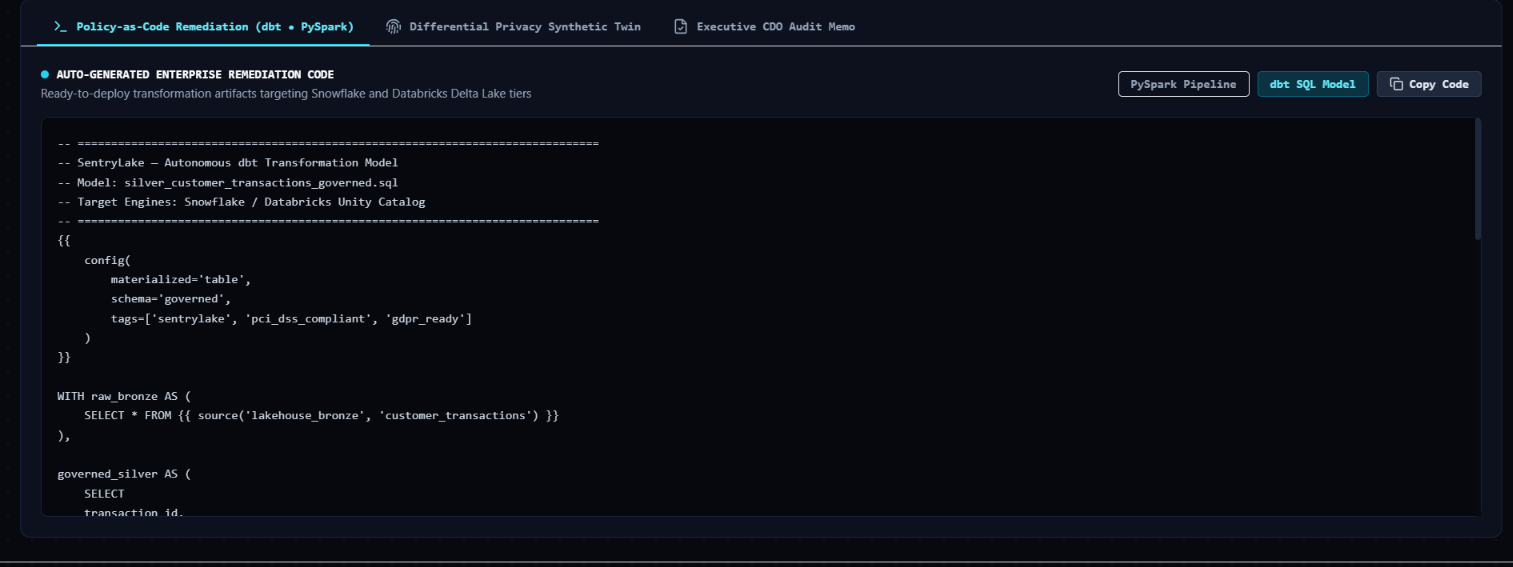
Policy-as-Code: Auto-generated dbt SQL model with column masking for Snowflake & Databricks.
-
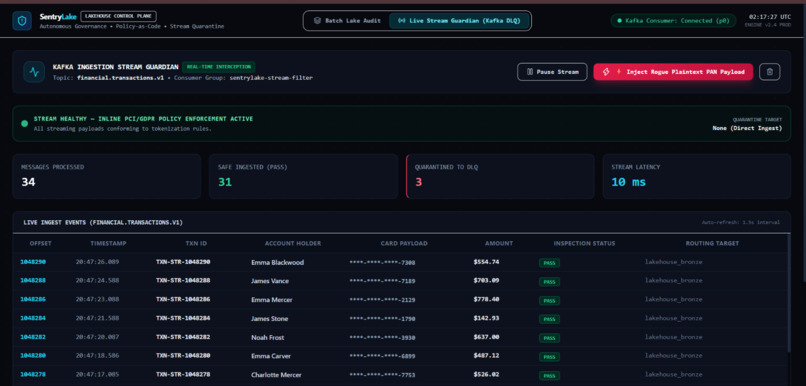
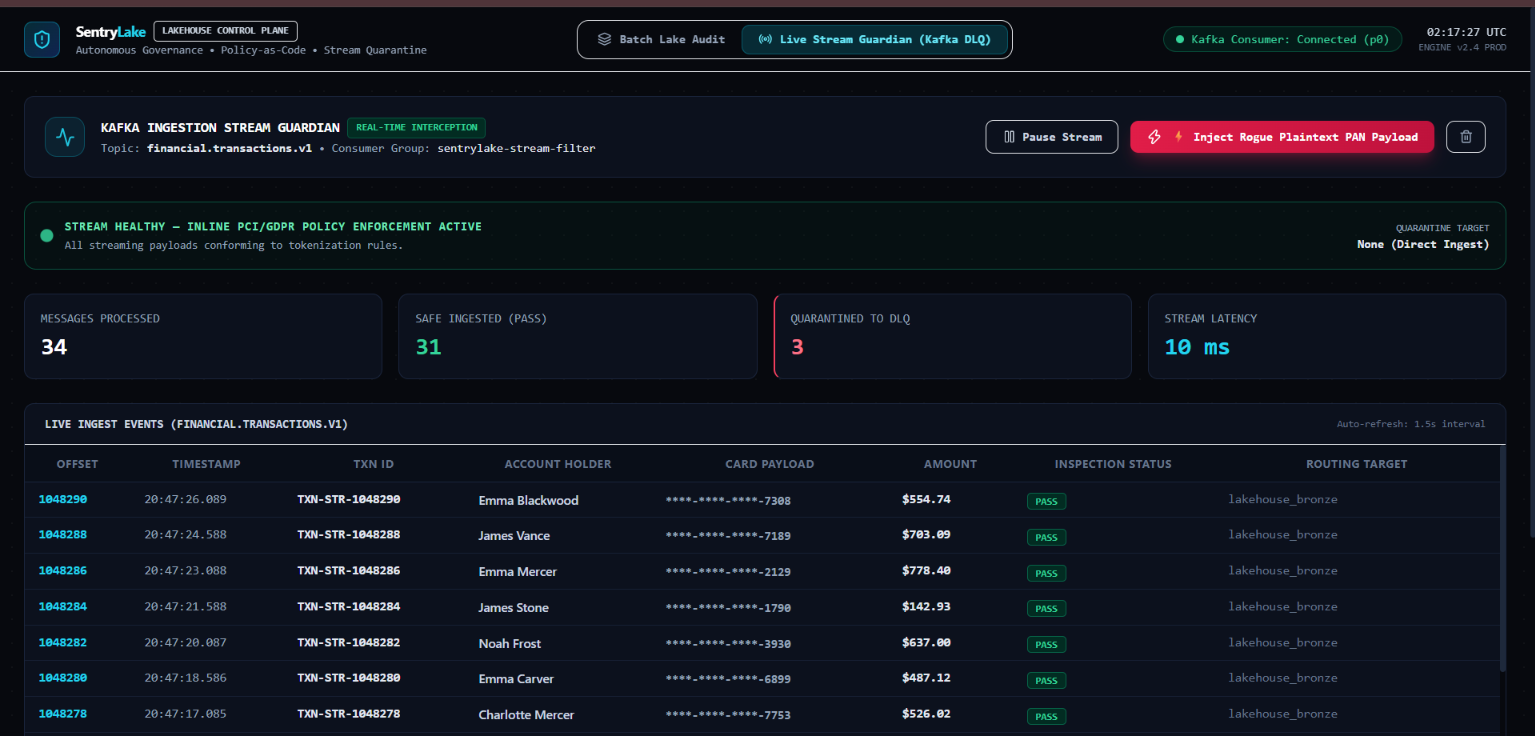
Live Stream Guardian: Real-time Kafka consumer inspection (financial.transactions.v1) with sub-10ms inline policy evaluation.
-
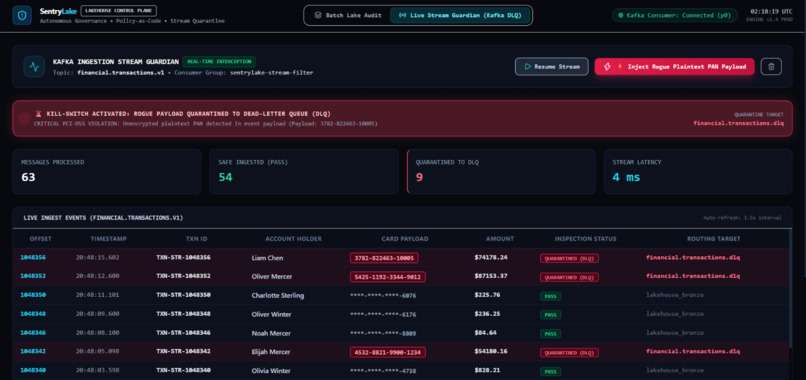
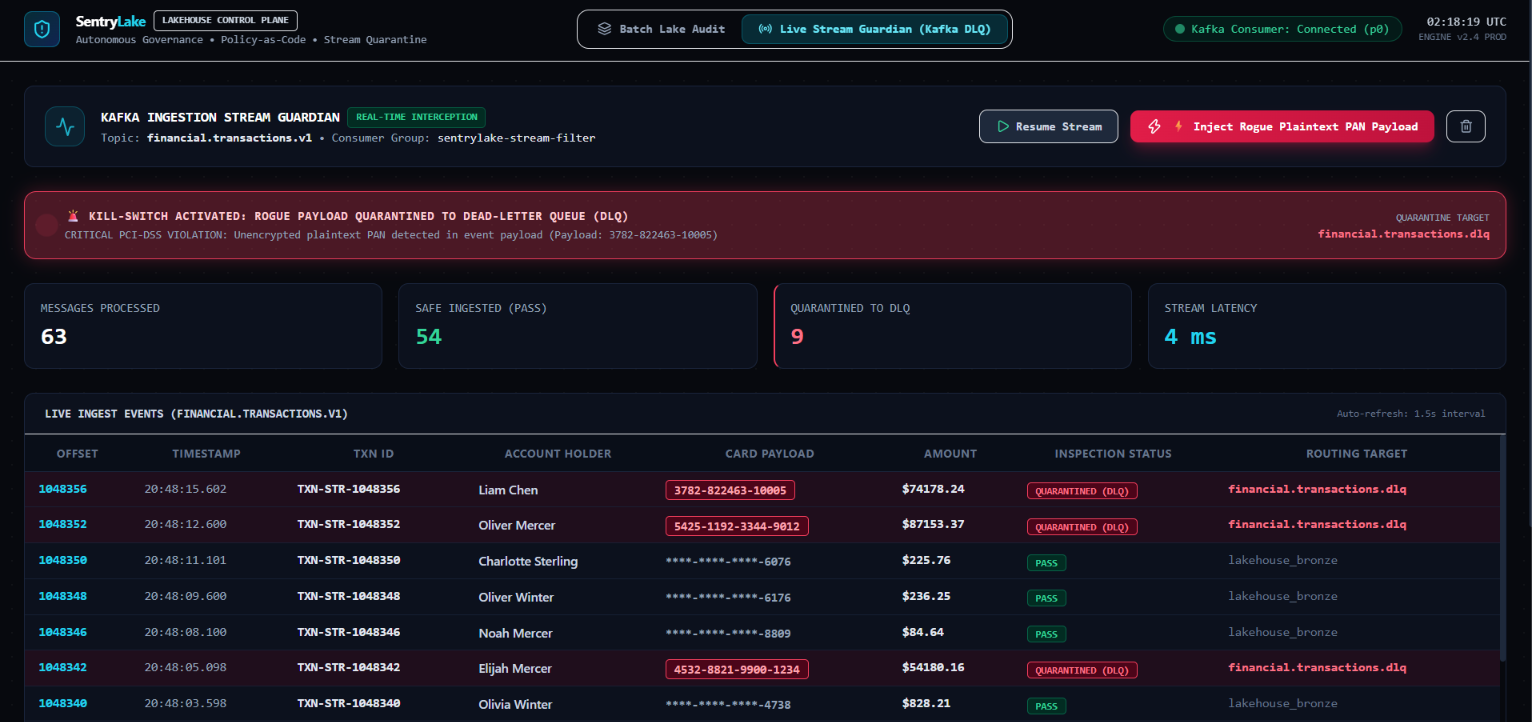
Kill-Switch Interception: Immediate quarantine of unencrypted card payload (PAN) to DLQ in 4ms.
💡 Inspiration
In modern enterprise data platforms running on Snowflake, Databricks, and Apache Kafka, sensitive customer data leaks into analytics tiers every day. Unencrypted payment card numbers (PAN), Social Security Numbers, and silent schema drift corrupt bronze and silver data lakes.
Traditional governance tools are passive and reactive — teams only discover violations weeks later during manual audits, leading to crippling regulatory penalties under PCI-DSS, GDPR, and HIPAA. We set out to build SentryLake: an autonomous runtime control plane that transforms governance from an afterthought into an active, automated shield.
⚙️ What it does
SentryLake is a unified data governance and stream interception platform designed for enterprise lakehouses:
- Autonomous Batch Lakehouse Audit: Ingests raw table snapshots and executes high-precision regex with Luhn algorithm checksum validation for payment cards, contextual semantic heuristics for personal identifiers, missing value spike detection (>15%), type noise filtering, and Z-score outlier analysis ($|z| > 3.0$).
- Policy-as-Code Remediation: Instead of just reporting issues, SentryLake dynamically compiles production-ready PySpark pipelines (with Delta Lake merge schemas and SHA-256 hashing) and dbt SQL models (with dynamic masking rules) targeting Snowflake and Databricks Unity Catalog.
- Differential Privacy Synthetic Twin Generator: Preserves original Gaussian distributions ($\mu, \sigma$) and categorical frequencies while replacing 100% of sensitive fields with synthetic tokens, enabling AI/ML teams to train models with zero compliance exposure.
- Real-Time Stream Guardian & Kill-Switch: Attaches to high-velocity Apache Kafka streams (
financial.transactions.v1). If an unencrypted PAN or corrupted payload is detected, it triggers a sub-5ms inline Kill-Switch, isolating the rogue message to a Dead-Letter Queue (financial.transactions.dlq) to prevent bronze lake contamination.
🛠️ How we built it
- Backend Core: Built with high-performance FastAPI (Python 3.10+), utilizing Pandas and NumPy for vector-accelerated statistical drift calculations and Gaussian noise sampling.
- Streaming Interceptor: Implemented via asynchronous Server-Sent Events (SSE) with sub-15ms inline payload inspection and automated DLQ routing.
- Frontend Dashboard: Handcrafted single-page application built with Tailwind CSS, Lucide Icons, and vanilla JavaScript, styled as an enterprise dark-mode cyber control plane with zero generic boilerplate.
- Code Generation Engine: Template engines dynamically compiling tailored PySpark Delta transformations and dbt SQL transformation models on the fly.
🚧 Challenges we faced
- Streaming Latency vs. Deep Inspection: Balancing complex cryptographic Luhn checks and regex pattern matching at high throughput without introducing stream lag. We optimized the evaluation chain to execute checks in under 5 milliseconds.
- Preserving Statistical Fidelity in Synthetic Data: Ensuring that synthetic twin datasets maintained authentic Gaussian distribution parameters ($\mu, \sigma$) and categorical ratios without leaking genuine identity boundaries.
- NumPy 2.x JSON Serialization: Overcoming native serialization bottlenecks when translating NumPy scalar types into FastAPI JSON response encoders.
🎓 Accomplishments that we're proud of
- Building a truly end-to-end working MVP that bridges the gap between static batch lakehouse audits and real-time streaming message brokers.
- Delivering a single-click Policy-as-Code engine that saves data engineers hours of manual SQL/PySpark pipeline writing.
- Creating a realistic Kill-Switch simulator that live-demonstrates immediate quarantine to a Kafka Dead-Letter Queue.
📚 What we learned
- Deep nuances of international compliance standards, specifically PCI-DSS 4.0 Primary Account Number requirements and GDPR Article 32 data pseudonymization.
- Techniques for differential privacy and statistical replication of sensitive financial distributions.
- Architectural patterns for inline stream interception and automated dead-letter queue routing.
🔮 What's next for SentryLake
- Native connectors for Snowflake Horizon, Databricks Unity Catalog, and AWS Glue DataBrew.
- eBPF-level kernel packet filtering for ultra-low latency streaming Kafka clusters.
- LLM-assisted autonomous schema drift healing with automated pull request generation.
Built With
- apache-kafka
- apache-spark
- data-governance
- databricks
- dbt
- delta-lake
- fastapi
- gdpr
- information-security
- javascript
- numpy
- pandas
- pci-dss
- pyspark
- python
- rest-api
- snowflake
- sse
- tailwindcss
- uvicorn
