-
10k file analysis result showing page
-
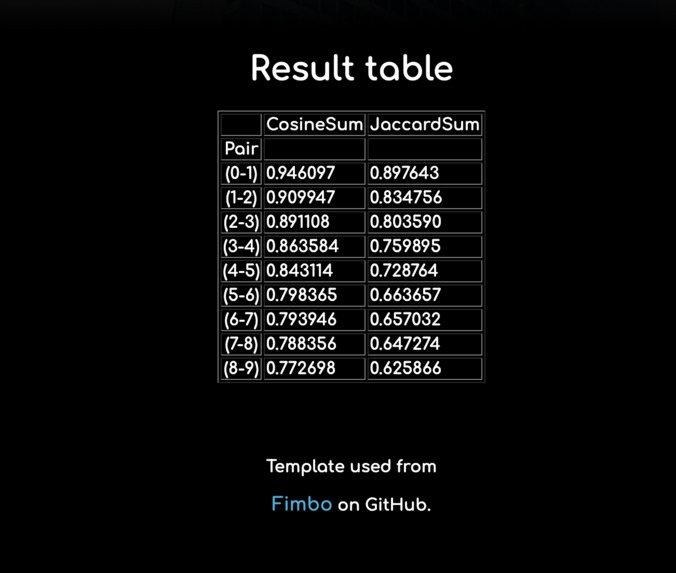
showing result table
-
contact our team part
-
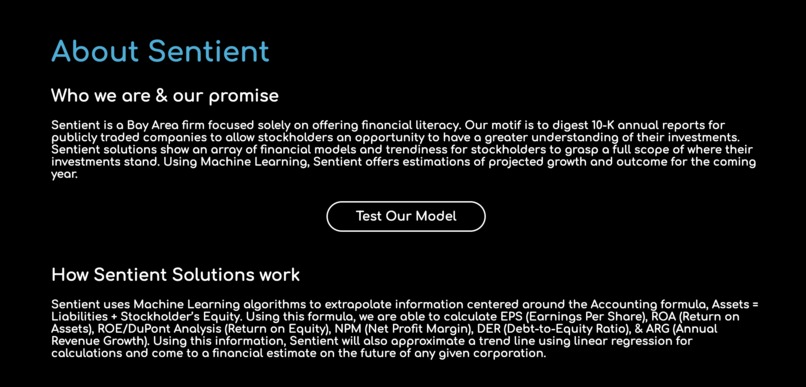
introduction of our project


Inspiration
- We offer everyday citizens access and understanding to exhaustive government documents by parsing the documents and utilizing natural language processing through presenting it in an understandable format. A 10-K Financial Report is a comprehensive report which must be filed annually by all publicly traded companies about its financial performance. That being said, these documents are often very long (average >= 42,000 words) and vague with dense terminology and boilerplate to beautify the organizations current state -> this project aims to extract keywords and analyze the sentiment from each document to predict low/high return of a certain stock.
What it does
- Given a stock ticker, Sentient extensively collects all the 10-K annual reports of the corresponding company. Then, the software parses an exhaustive list of SEC provided files. We also provide utility for users to converse with a finance chat bot and classification of terminology.
How we built it
- Decide to collect data from SEC EDGAR. However, this is not comprehensive enough for our purpose, so we had to scrape the entire 10K filings of each stock ticker by ourselves using beautifulSoup.
- After collecting the raw data, we preprocessed and cleanned our data using lemmatization, tokenization, removing stopwords and punctuations.
- We assume that if a company has been through drastic change in a fiscal year, they will have to make major modifications to their current fiscal year's 10K report.
- Based on our process and Cohere's API for classification, we predict if a certain stock is either going to yield low/high future return and by how much.
- Justify by returning key-word frequency and how many words.
- Save each user into a Cockroach DB to save preferences and search up stocks.
Challenges we ran into
- We ran into many problem, not only because the project is ambitious for our level but also because it is difficult trying to balance things out and dividing tasks evenly between team members, especially when our levels of knowledge are different. We also only had only one day shy for the whole project, so working under pressure was something we really got to explore more!
Accomplishments that we're proud of
- Even though we came in not knowing a lot about our tech stacks, we really had the opportunity to push our limits in 2 days, extend our knowledge, and reinforce our skills in terms of what we already know.
What we learned
- We learned a lot about many available interesting technologies: web scrapping, APIs, full-stack development, as well as how determination could help us fulfill our ambitious ideas, no matter how large they may seem.
What's next for Sentient
- We have had some even more ambitious ideas during the brainstorming phase such as analyzing the contemporary data from the stock market combined with what we have been doing (sentiment analysis) to strengthen our signal, they would have cost us a larger amount of time and effort to implement. Thus, if possible, our team members would love to get together and completely finish what we all want to build in the nearest future.


Log in or sign up for Devpost to join the conversation.