-
-
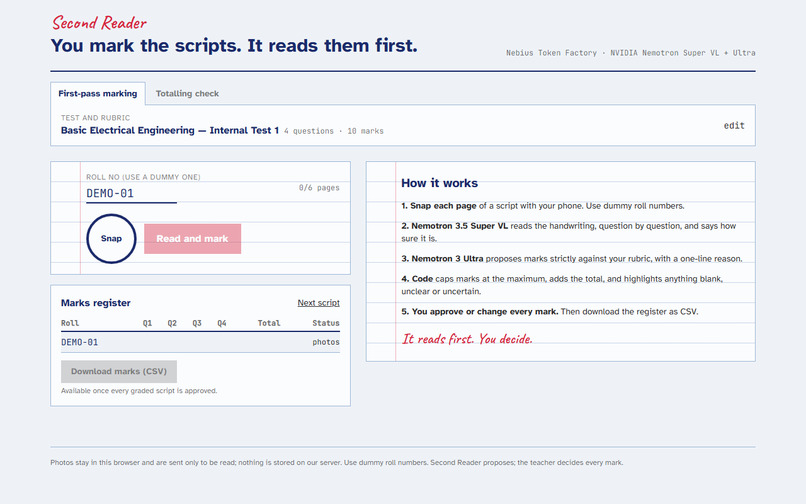
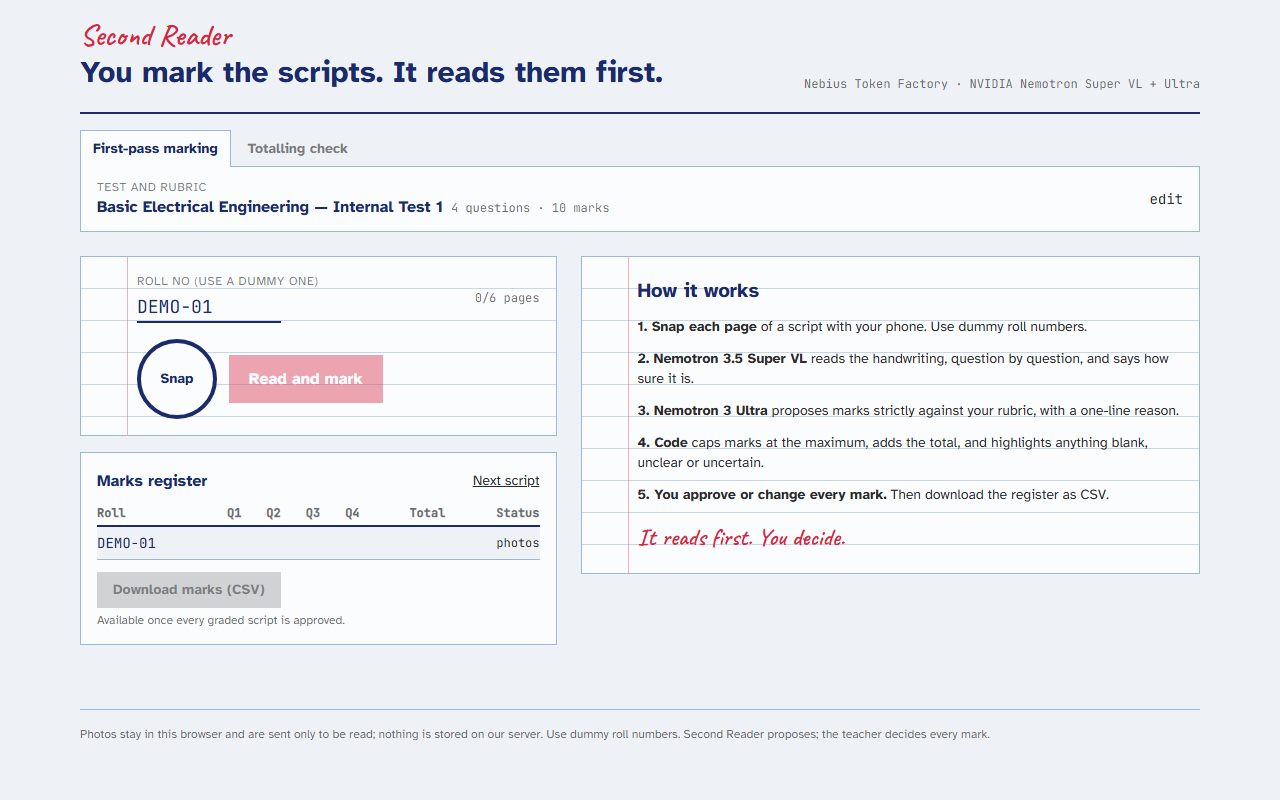
The home page: first-pass marking and the totalling check
-
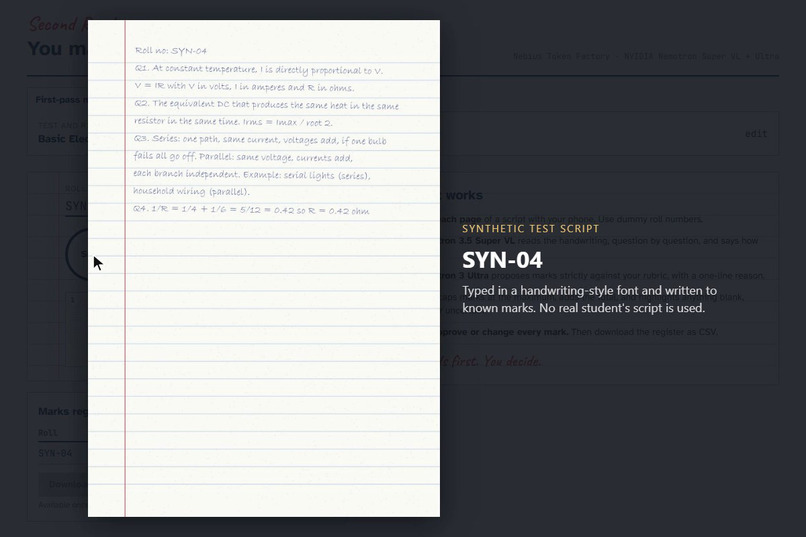
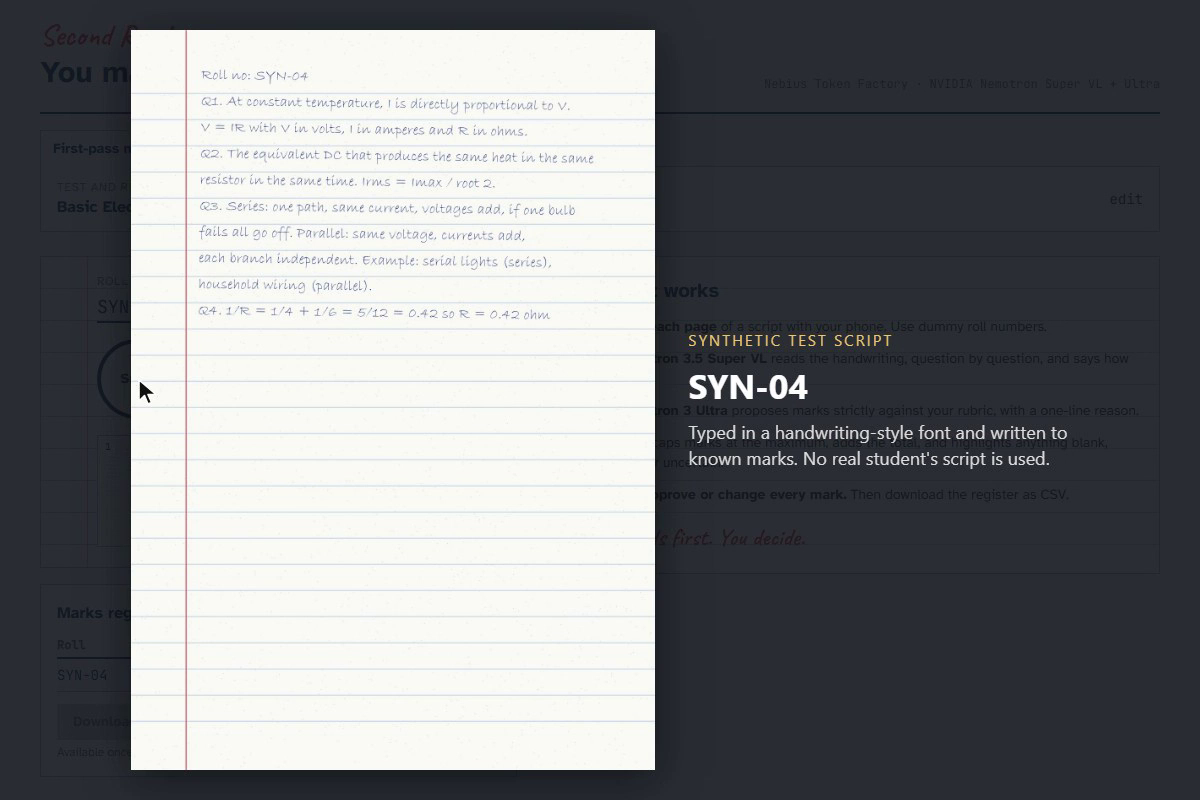
SYN-04: a synthetic page in a handwriting-style font, written to earn known marks
-
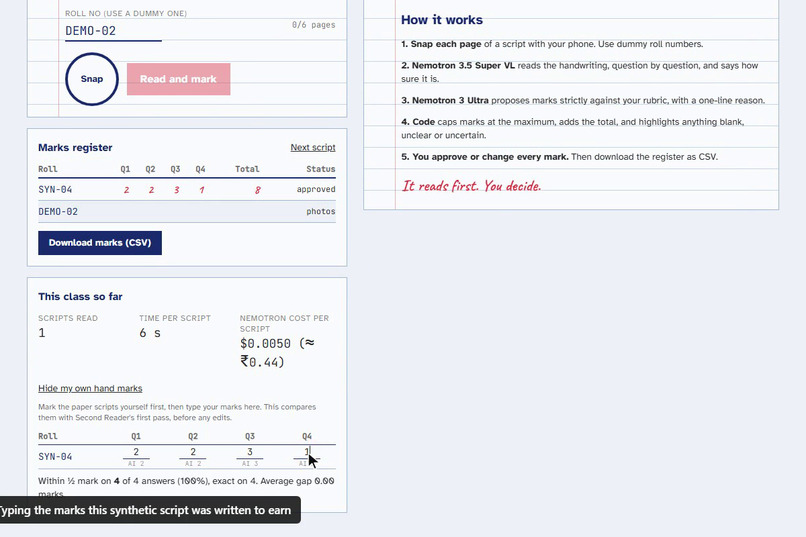
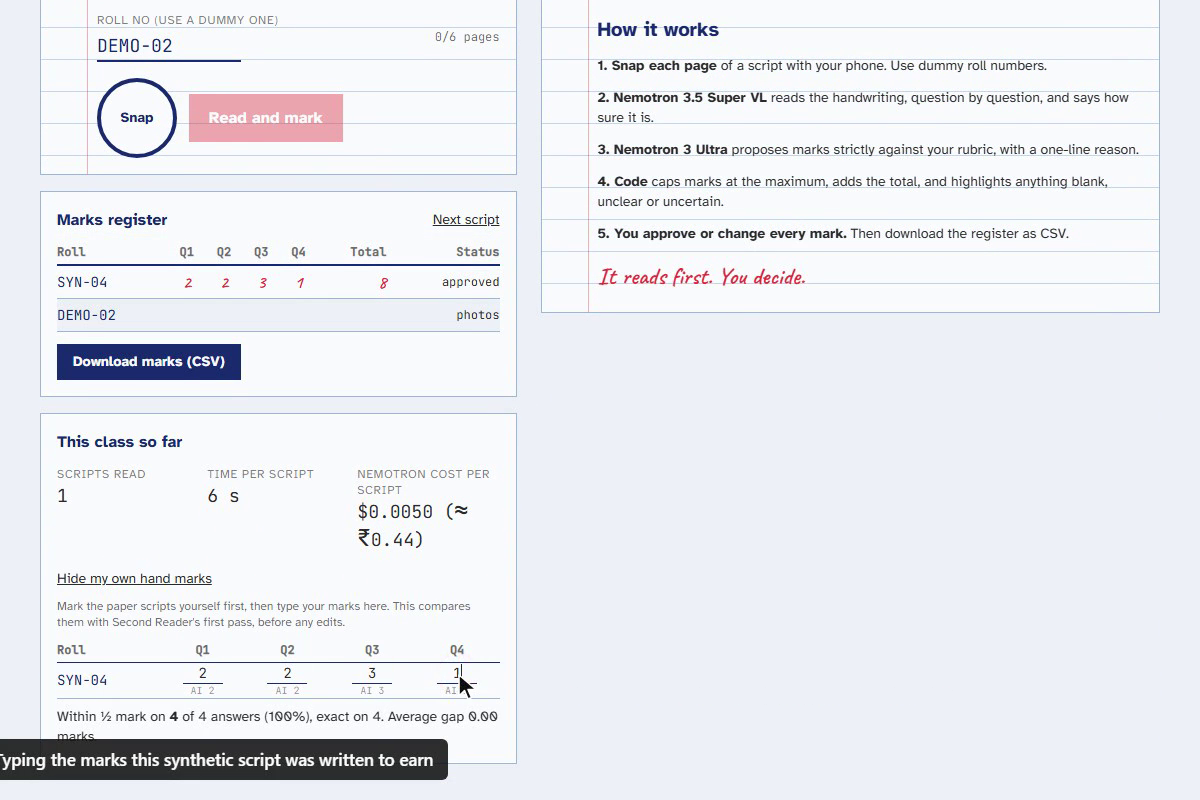
Checking the first pass against the marks the script was written to earn: within ½ on 4 of 4
-
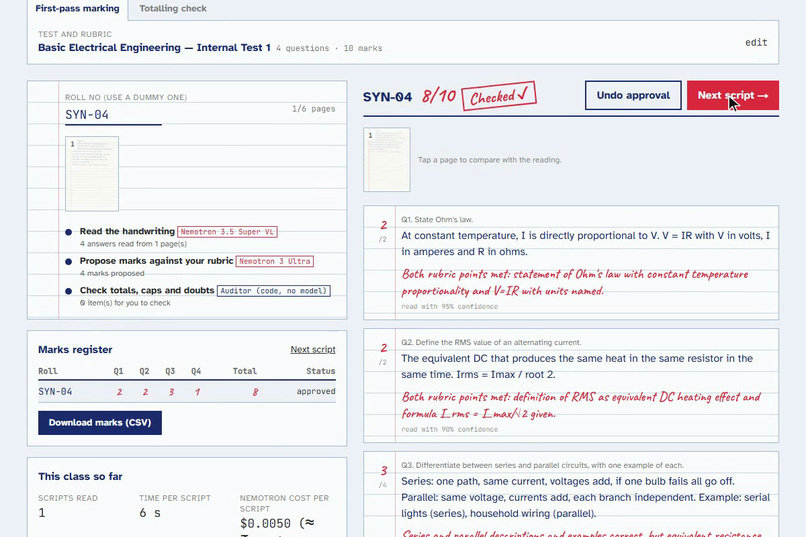
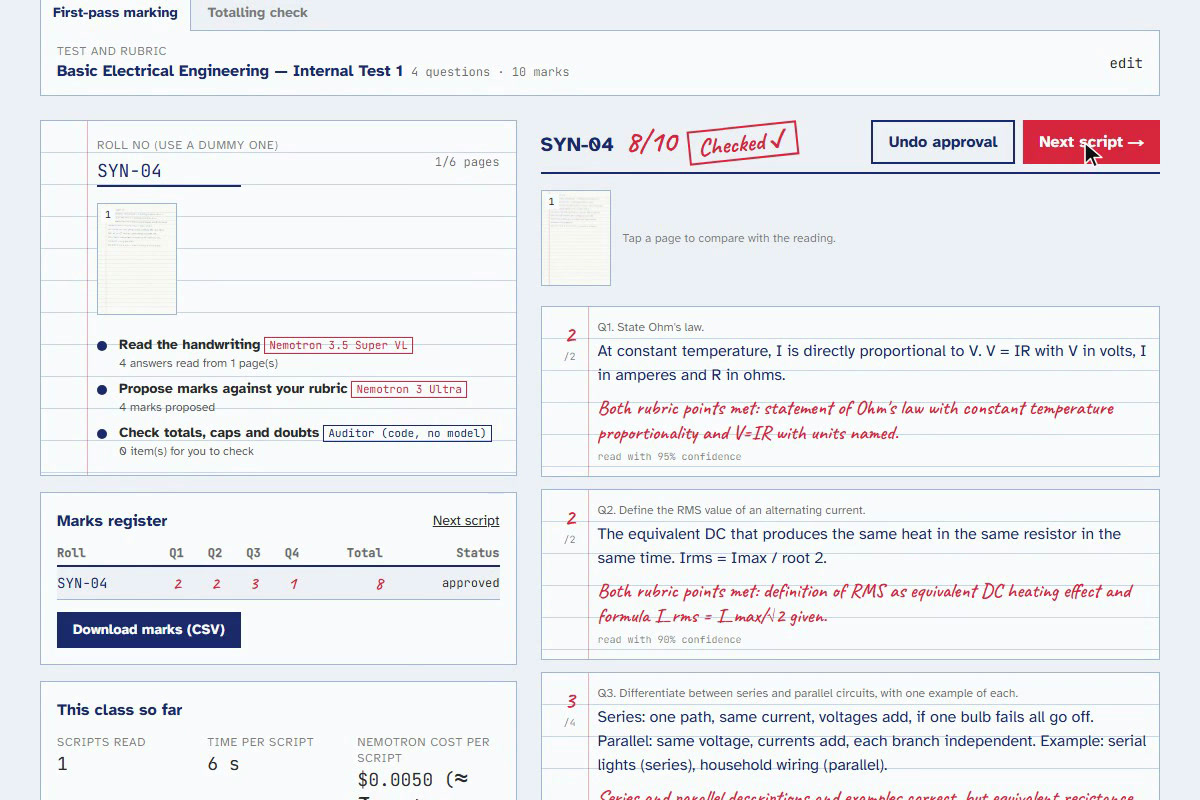
A synthetic test script (SYN-04) approved: each mark with a one-line reason against the rubric
Inspiration
Faculty mark internal-test scripts by hand, a stack at a time, and mistakes happen at scale: Bangalore University blacklisted 50 evaluators for erroneous marking (Deccan Herald, 9 Jan 2025), and universities run re-totalling as its own process because marks get added up wrong. Reading the handwriting and checking it against the scheme of valuation is slow; the judgement is the teacher's. We wanted a first reader, not a grader.
What it does
Snap each page; Nemotron 3.5 Super VL reads every answer; Nemotron 3 Ultra proposes a mark and a reason against the teacher's own rubric; code caps, rounds, totals and flags anything blank, unclear or uncertain. The teacher reviews flagged answers first, adjusts with −½/+½, approves, and moves to the next script. A totalling-check mode catches addition mistakes on scripts already marked by hand, and the rubric can be filled from a photo of the answer key.
How we built it
Next.js on Vercel. Super VL with thinking off reads pages, answer keys and margin marks (about 5 s a page when the service is quiet); Ultra with thinking on proposes marks; a TypeScript auditor owns every number. Photos are resized on the phone and never stored. Unit tests cover the auditor, the agreement score, the class insight, the totalling check and parsing marks like "1½".
Challenges
- Models send question numbers as
1rather than"1", and marks as "1½"; untreated, every answer would have been dropped. - Nemotron reasons by default; turning it off for transcription made reading fast and cheap, while marking keeps it on.
- Keeping the teacher in charge: nothing exports until every graded script is approved.
Accomplishments
- A full read → mark → audit in 10 s (10–45 s under load) for about ₹0.5 per script.
- On five synthetic test scripts written to known marks (handwriting-style fonts, not real handwriting): within ½ mark on 20 of 20 answers, exact on 19.
- The totalling check caught a deliberate slip (written 9, marks add to 8.5); a photographed answer key became the rubric exactly.
What we learned
Vision and judgement are different jobs: Super VL transcribes reliably when it doesn't think, Ultra marks better when it does. Rubrics written as marking points ("statement (1), V = IR (1)") make the marker's reasons checkable at a glance.
What's next
Testing on real student handwriting, diagrams, and a scheme-of-valuation import for whole question papers.
Limitations
- Not yet tested on real student handwriting. Every script in the demo and the benchmark is a synthetic page rendered in a handwriting-style font, labelled as such. Low-legibility answers are flagged for the teacher.
- The marker can be strict, which is why every mark is a proposal and there's a built-in check against the teacher's own hand marks.
- Full list in the README.
Built With
- nebius-token-factory
- nemotron-3-ultra
- nemotron-3.5-super-vl
- next.js
- nvidia-nemotron
- typescript
- vercel


Log in or sign up for Devpost to join the conversation.