Inspiration
In the online events, academic panels, online trainings we attend, we often hear a wide array of concepts, algorithms, terms, and formulas. Yet what we often hear might be misrepresented or mixed with the speaker’s personal interpretation. Therefore, I thought that the ability to trace and verify these concepts directly from their original sources in the academic literature provides a solid foundation for reliable knowledge. Having experienced this same issue firsthand, I believe that extracting this information, assessing its accuracy, and linking it to authoritative academic papers (for example, via the Semantic Scholar API) would be beneficial for everyone who interested in the grounding of information.
What it does
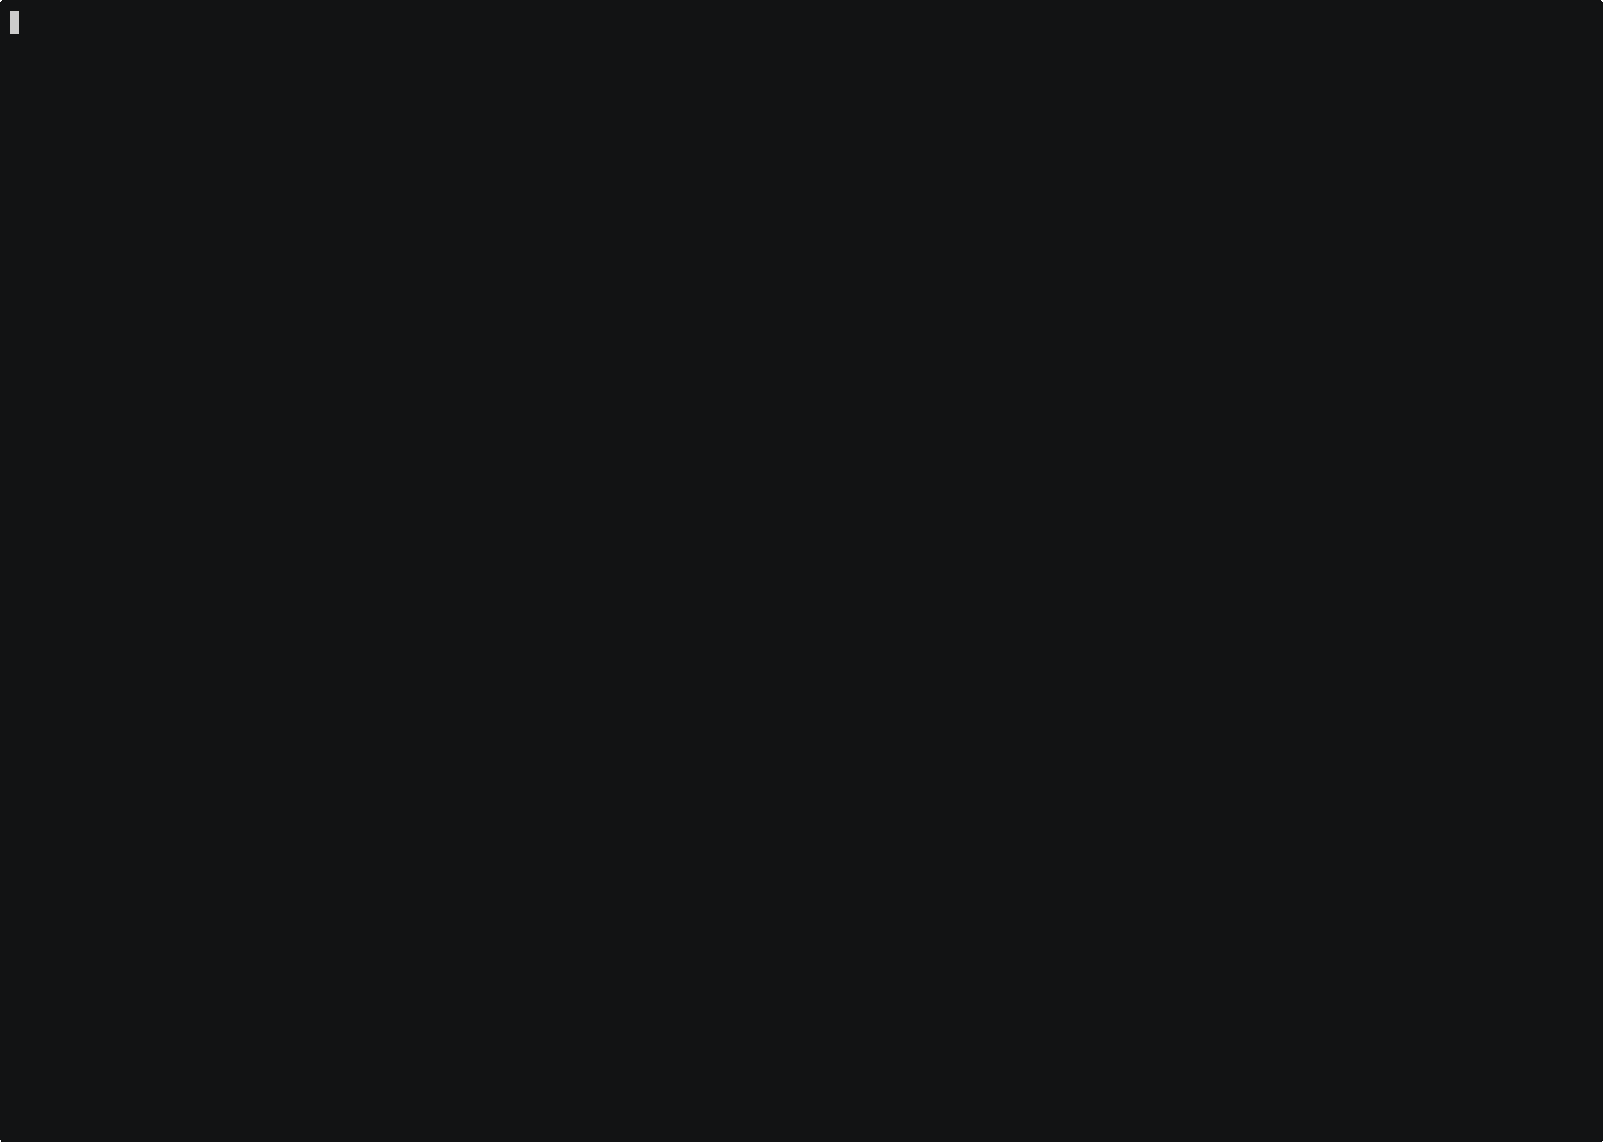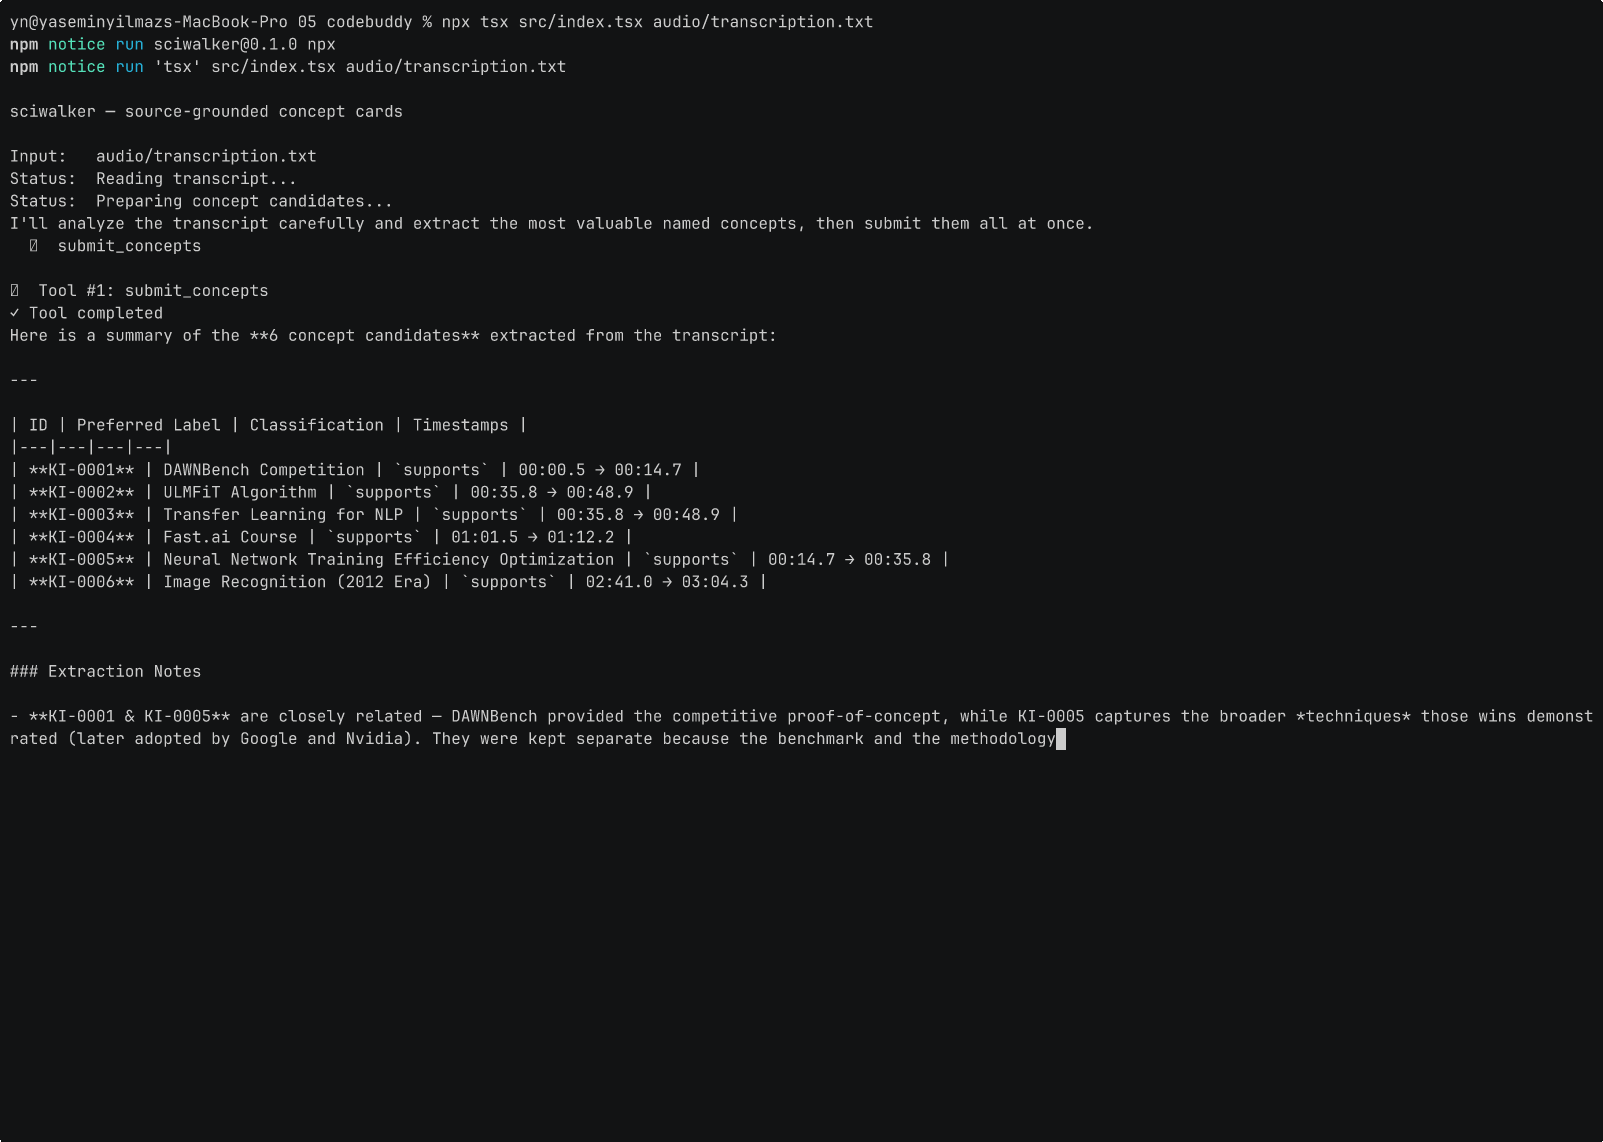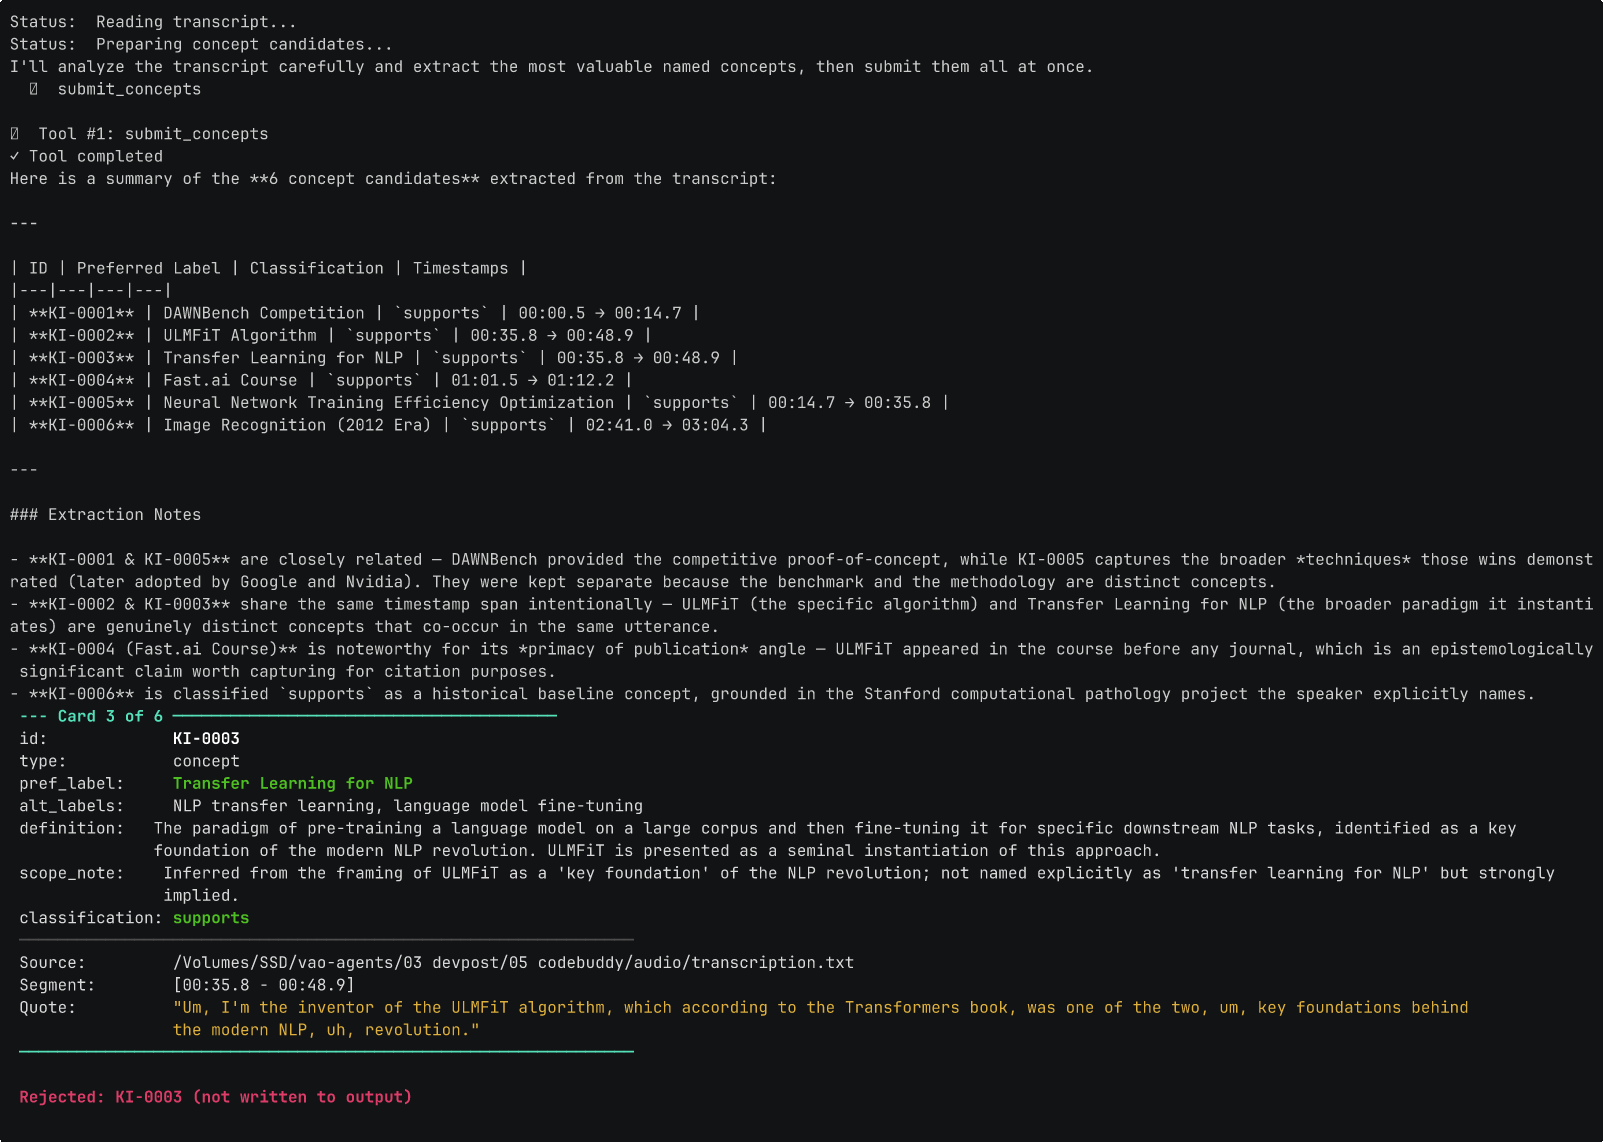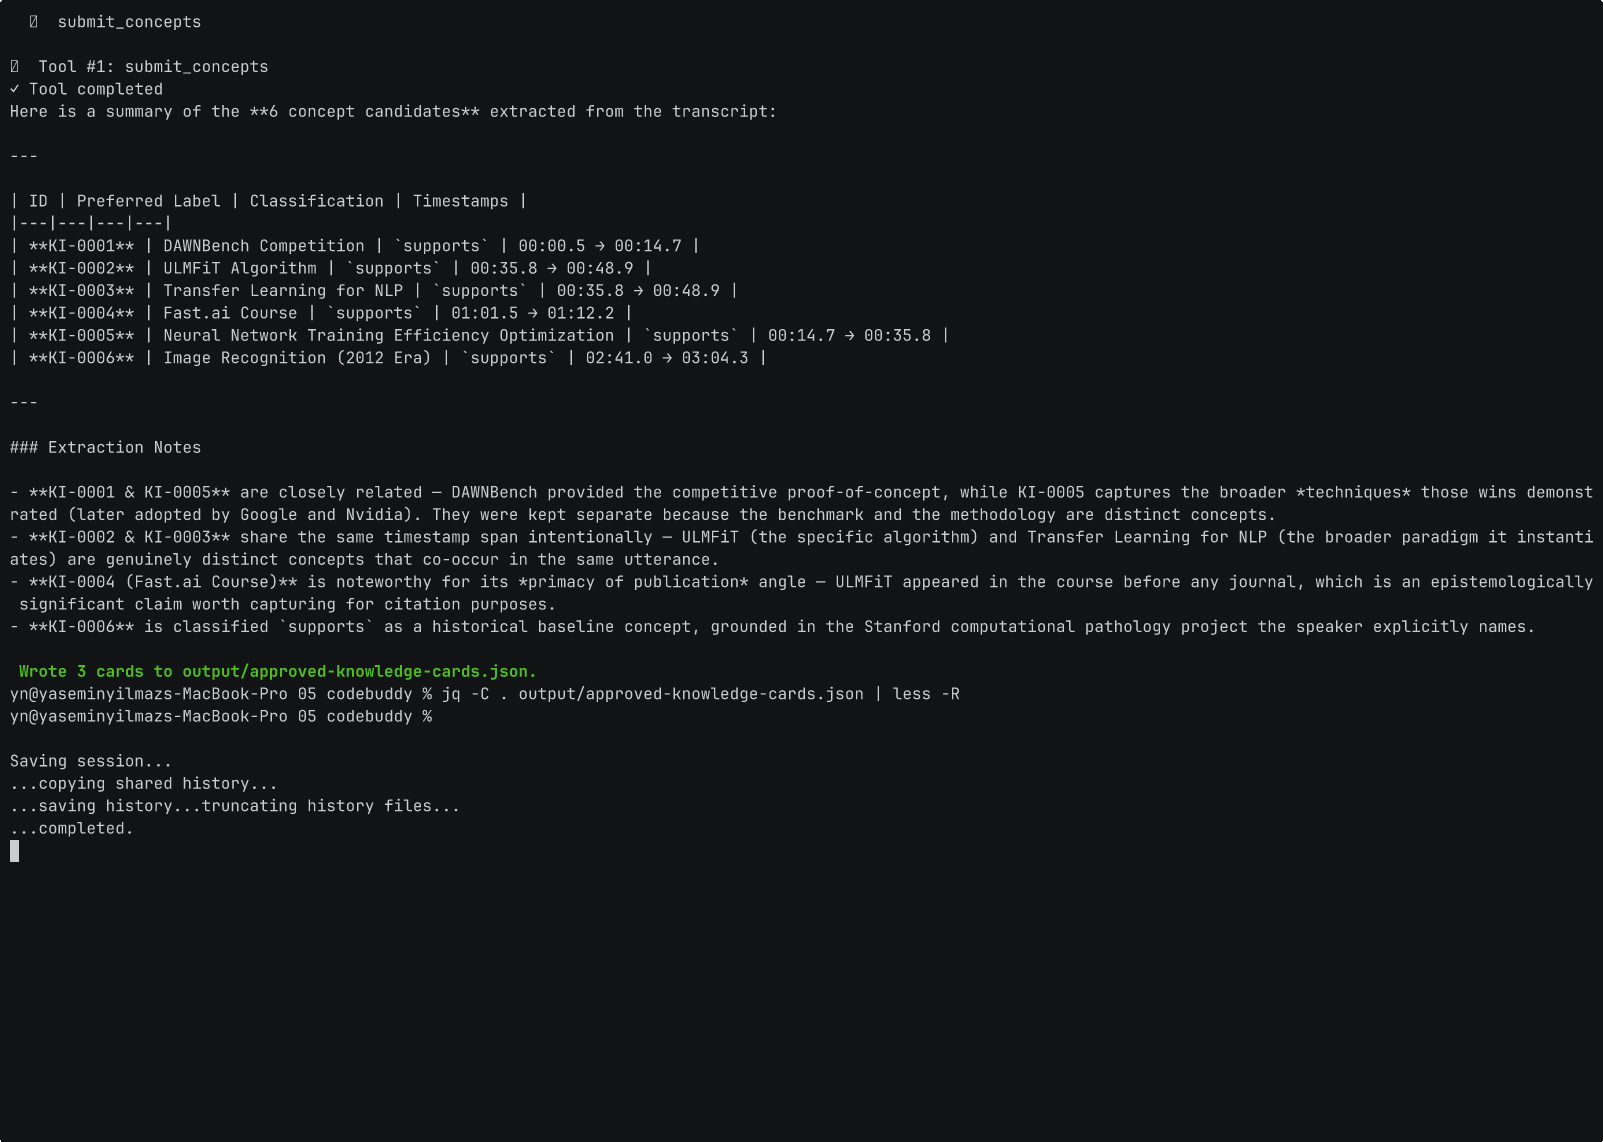
The sciwalker agent reads a timestamped academic transcript, extracts concept KnowledgeItem cards using an AI agent, and lets a research assistant approve or reject each card one at a time in the terminal. Every card is traceable to the exact segment and verbatim quote in the source transcript.
- AI Agent Orchestration: Powered by TypeScript and the
@strands-agents/sdkintegrating with Amazon Bedrock (Anthropic Claude Sonnet 4.6) to extract structured concept definitions, alt-labels, and verbatim quotes from timestamped transcripts. - Timestamp Resolution: Instead of relying on the LLM to calculate timestamps (which is prone to hallucinations and arithmetic drift), the agent extracts verbatim quotes while a deterministic TypeScript segment resolver matches the exact transcript lines and timestamps.
- Schema Validation: Every candidate card is validated against SKOS-compliant Zod schemas (
KnowledgeItem). Malformed candidates are caught and filtered out before reaching the user. - Interactive Terminal UI (TUI): Built using
Ink(React in the terminal) to deliver a streamlined review experience where researchers review AI confidence flags and approve ([a]) or reject ([r]) cards via keyboard shortcuts. - Clean Persistence: Approved cards are formatted and saved into
output/approved-knowledge-cards.jsonwith complete source provenance (timestamps, quotes, and transcript path).
How we built it
We built sciwalker following the structured, spec-driven methodology from the Learn AI Basics Skill Pack, executing each phase sequentially:
/2-scope— Scoping & Core Loop: Defined the exact user problem for research assistants and established the core loop: transcript input → LLM concept extraction → interactive human review → validated JSON output. Minimized the scope by cutting non-essential features (audio decoding, speaker diarization) to guarantee source-grounded precision./3-prd— Product Requirements Document: Specified the complete lifecycle across three terminal modes:- Mode 1 (Startup): File parsing, CLI argument validation, and Bedrock model invocation.
- Mode 2 (Review): Interactive card-by-card terminal review with evidence-based classification flags (
supports,insufficient,potential_contradiction). - Mode 3 (Close): Persistence and session wrap-up.
/4-spec— Technical Specification & Architecture: Designed SKOS-compliant Zod data contracts (KnowledgeItem) and formulated our core architectural rule: "LLM for semantics, deterministic code for structure." We designed a custom TypeScript segment resolver to match verbatim quotes to exact transcript timestamps rather than trusting LLM-generated times./5-build— Incremental Vertical Build Slices: Implemented the application across 5 strictly isolated and verified slices:- Slice 1: CLI entry point, argument validation, and error exit handling.
- Slice 2: Zod schema definitions (
CandidateKnowledgeItemandApprovedKnowledgeItem). - Slice 3: Strands Agent integration calling Amazon Bedrock (Anthropic Claude Sonnet 4.6) via a structured
submit_conceptstool. - Slice 4: Interactive React-based Terminal UI (
Ink) featuring live review controls ([a]approve /[r]reject). - Slice 5: Persistence layer writing validated cards to
output/approved-knowledge-cards.json. Conducted end-to-end integration tests. Generated the interactive architecture map (app-map.html)
/6-ship— Verification & Showcase: Prepared public GitHub repo. Written README.md file. Produced the narrated demonstration video and walkthrough.
Challenges we ran into
- LLM Timestamp Hallucinations: LLMs frequently drift or approximate timestamps when processing long transcript files. We solved this by treating the LLM as a semantic extractor and delegating timestamp calculation to deterministic program.
- Schema Validation Failure: We started to execute the 5‑build stage without having properly evaluated the results of Zod schema validation. At that point we realized that we had omitted the information that should be presented to the researcher when a schema check fails. For instance, the sciwalker might have extracted a crucial piece of knowledge, but the researcher could never notice it because of a Zod validation failure. To solve this problem we introduced a Failure mode in addition to the three sequential modes—Startup, Review, and Close—so that the researcher is kept informed.
Accomplishments that we're proud of
- Minimizing-Hallucination Provenance: Built a dual-engine pipeline ("LLM for semantics, deterministic code for structure") that guarantees verbatim quotes and exact transcript timestamp boundaries, making every citation auditable against the original transcript.
- First AI Agent Implementation: Successfully designed and integrated an agentic workflow using the
@strands-agents/sdkand Amazon Bedrock (Anthropic Claude Sonnet 4.6) with structured tool calls and error boundaries. - Distraction-Free Terminal Experience: Developed an interactive, keyboard-driven Terminal UI (TUI) using
Ink(React for CLI) that puts researcher agency front and center with single-keystroke reviews ([a]approve /[r]reject). - Strict Data Integrity: Enforced SKOS-compliant Zod schema validation at runtime, ensuring every persisted card in
output/approved-knowledge-cards.jsonis citable, structured, and ready for downstream research tools. - Disciplined Spec-Driven Engineering: Completed the entire development lifecycle following the Learn AI Basics Skill Pack—moving from learner profile and scoping to vertical build slices, automated type checking, and demo production.
What we learned
Throughout this process, thanks to Learn AI Basics — skills repository contributors, I realized how essential it is to properly structure the layers of context and domain knowledge that an AI coding agent receives. More importantly, I learned to pinpoint which parts of a software must remain deterministic code rather than being handed over to an LLM, and how much this architectural decision influences overall system reliability and the accuracy of its outputs.
What's next for sciwalker
- Semantic Scholar API Integration: Connect extracted concepts to academic literature databases to fetch relevant peer-reviewed papers, author information, and official citations automatically.
- Multi-Type Knowledge Extraction: Expand beyond
conceptcards to support additional structured academic items such asclaim,equation,method, andalgorithm. - In-CLI Inline Card Editing: Allow researchers to edit definitions, preferred labels, or scope notes directly in the terminal before approving cards.
- Extended Export Formats: Support exporting approved knowledge cards into
JSON-LD,YAML, and Obsidian/Notion-compatible Markdown.
Built With
- amazon-web-services
- bedrock
- codebuddy
- ink
- json
- kiro
- node.js
- strands
- typescript
- zod

Log in or sign up for Devpost to join the conversation.